

The DOI matches its Crossref record; 56 of the 56 references it cites were found in a registry or an index.
Matching patients to clinical trials with large language models
Open accessAbstract
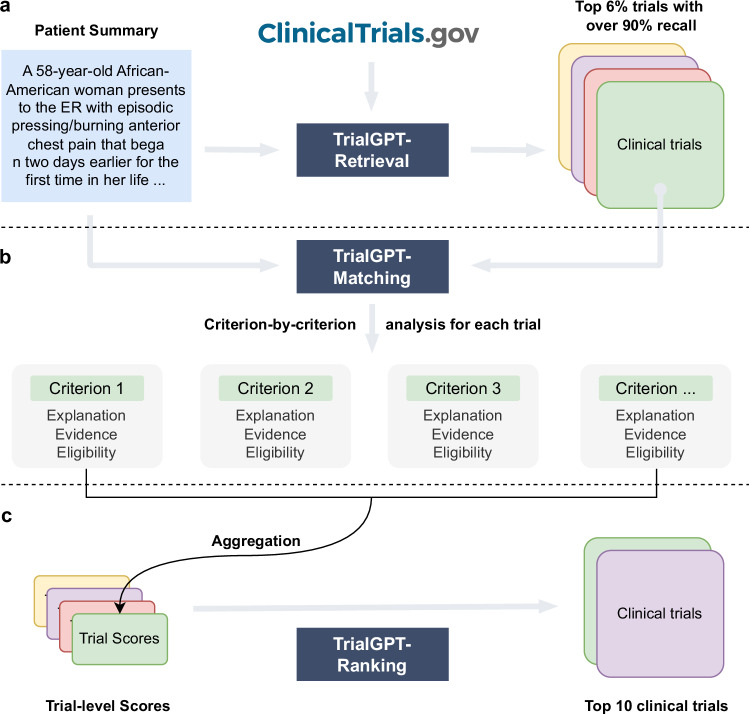
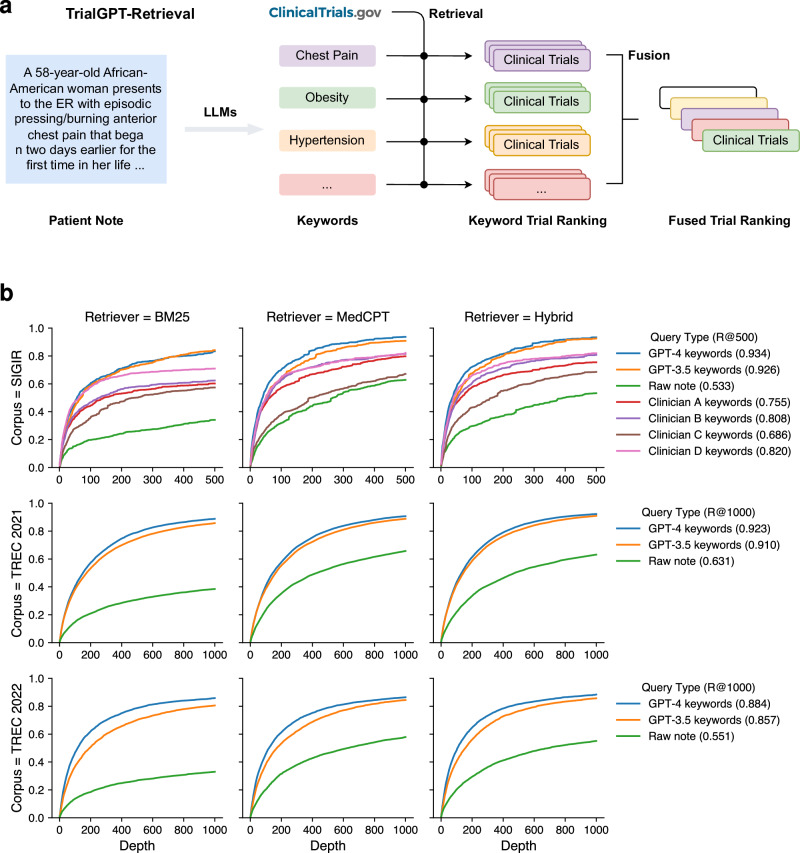
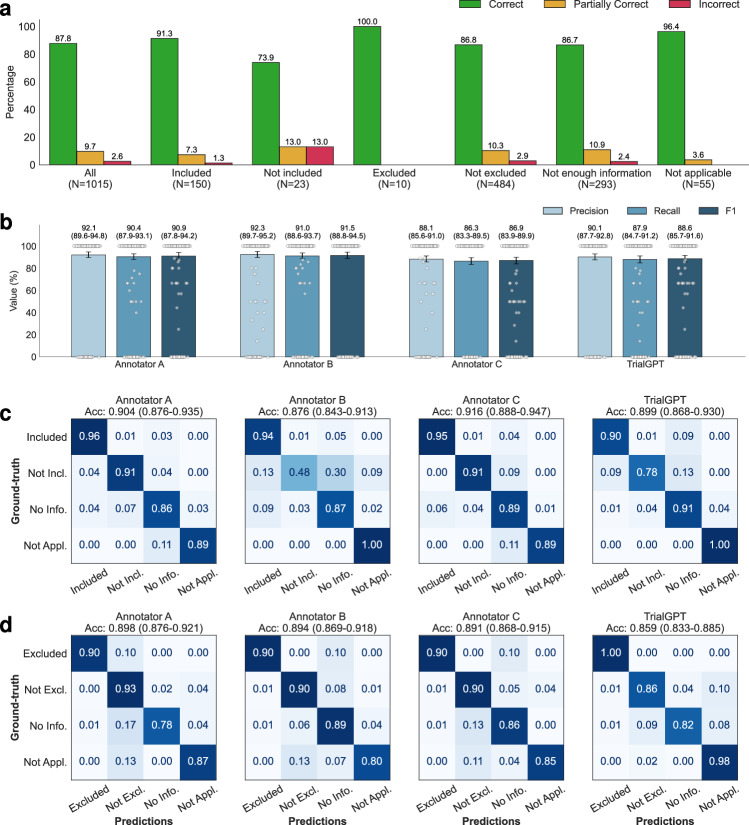
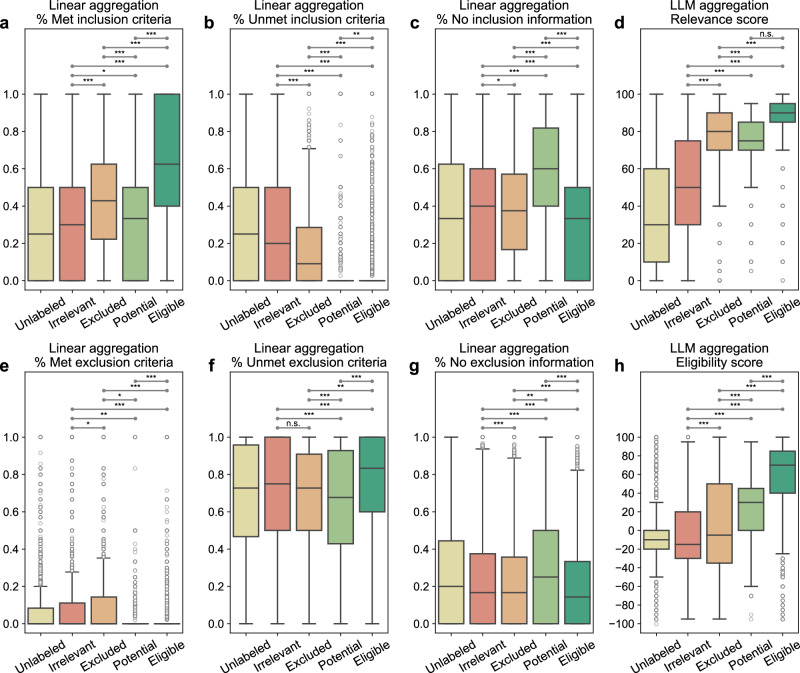
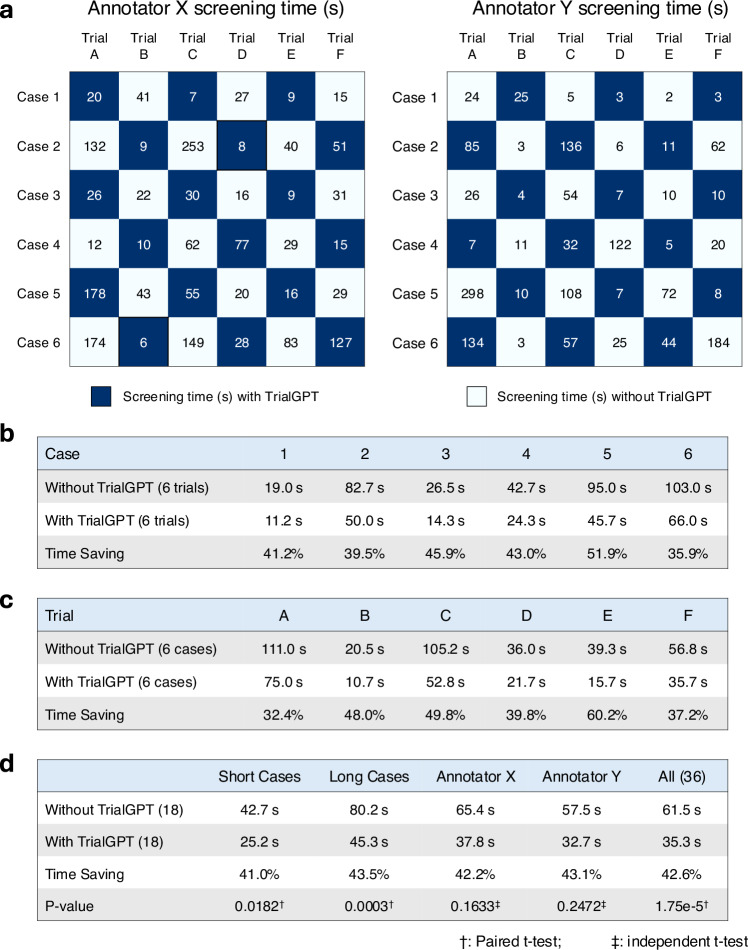
Patient recruitment is challenging for clinical trials. We introduce TrialGPT, an end-to-end framework for zero-shot patient-to-trial matching with large language models. TrialGPT comprises three modules: it first performs large-scale filtering to retrieve candidate trials (TrialGPT-Retrieval); then predicts criterion-level patient eligibility (TrialGPT-Matching); and finally generates trial-level scores (TrialGPT-Ranking). We evaluate TrialGPT on three cohorts of 183 synthetic patients with over 75,000 trial annotations. TrialGPT-Retrieval can recall over 90% of relevant trials using less than 6% of the initial collection. Manual evaluations on 1015 patient-criterion pairs show that TrialGPT-Matching achieves an accuracy of 87.3% with faithful explanations, close to the expert performance. The TrialGPT-Ranking scores are highly correlated with human judgments and outperform the best-competing models by 43.8% in ranking and excluding trials. Furthermore, our user study reveals that TrialGPT can reduce the screening time by 42.6% in patient recruitment. Overall, these results have demonstrated promising opportunities for patient-to-trial matching with TrialGPT.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“many published approaches remain retrospective, disease-limited, or optimized for text similarity and retrieval rather than auditable patient–trial execution over longitudinal records.”
From Transforming oncology clinical trial matching through neuro-symbolic, multi-agent AI and an oncology-specific knowledge graph: a prospective evaluation in 3804 patients (2026) · cites this paper as [4]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“A pioneering system in this realm is TrialGPT, which uses a trio of agents to match patients to clinical trials [36].”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“clinicians assisted by TrialGPT were able to complete trial screening tasks 42.6% faster than those working without AI assistance (35.3 s vs. 61.5 s; p < 0.001)”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“the high correlation between TrialGPT’s ranking scores and human judgment suggests that MAS has the potential to serve as a reliable cognitive assistant for complex, zero-shot patient-to-trial matching”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“representing a 43.8% improvement over state-of-the-art baselines like the cross-encoder BioLinkBERT (AUROC: 0.6176)”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
Experimental — accuracy not yet measured
The cited source says what the claim attributes to it.
In the citing paper
“TrialGPT-Retrieval, first conducts a large-scale search to retrieve candidate trials from databases based on a patient’s profile”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
The cited source says what the claim attributes to it.
In the citing paper
“the system achieved a precision of 90.1% and a recall of 87.9% in locating relevant supporting sentences in clinical notes”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
The cited source says what the claim attributes to it.
In the citing paper
“TrialGPT-Ranking, assigns scores to rank the trials by suitability”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
The cited source says what the claim attributes to it.
In the citing paper
“the system achieved a precision of 90.1% and a recall of 87.9% in locating relevant supporting sentences in clinical notes”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
The cited source says what the claim attributes to it.
In the citing paper
“In the trial exclusion task, TrialGPT attained an AUROC of 0.7979”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
The cited source says what the claim attributes to it.
In the citing paper
“as these evaluations were conducted on synthetic patient records”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
The cited source says what the claim attributes to it.
In the citing paper
“manual evaluations of 1015 patient-criterion pairs demonstrated that the matching agent achieved an accuracy of 87.3%”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
The cited source says what the claim attributes to it.
In the citing paper
“TrialGPT-Retrieval successfully recalled over 90% of relevant trials while filtering out most irrelevant ones, requiring less than 6% of the total collection to maintain this high recall”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
The cited source says what the claim attributes to it.
In the citing paper
“TrialGPT-Matching, then evaluates the patient’s eligibility against each trial’s criteria using LLM-based reading and annotation of inclusion/exclusion criteria”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
The cited source says what the claim attributes to it.
In the citing paper
“The system was then evaluated on three cohorts comprising 183 synthetic patients with over 75,000 trial eligibility annotations.”
From A Review of Multi-Agent AI Systems for Biological and Clinical Data Analysis (2026) · cites this paper as [36]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q. V., & Zhou, D. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1800 · Cited by 4,505
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q., & Zhou, D. (2022) · arXiv · doi:10.48550/arxiv.2201.11903 · Cited by 4,263
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
A large annotated corpus for learning natural language inference
Bowman, S. R., Angeli, G., Potts, C., & Manning, C. D. (2015) · Proceedings of the 2015 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d15-1075 · Cited by 3,377
The probabilistic relevance framework: BM25 and beyond
Robertson, S., & Zaragoza, H. (2009) · Foundations and Trends® in Information Retrieval · doi:10.1561/1500000019 · Cited by 3,374
A Broad-Coverage Challenge Corpus for Sentence Understanding through Inference
Williams, A., Nangia, N., & Bowman, S. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1101 · Cited by 3,342
Research works printed but not linked: 2
- Roberts, K., Demner-Fushman, D., Voorhees, E. M., Bedrick, S. & Hersh, W. R. Overview of the TREC 2021 Clinical Trials Track. In Proc. Thirtieth Text REtrieval Conference (TREC 2021) (2021). · DOI
- Roberts, K., Simpson, M. S., Voorhees, E. M. & Hersh, W. R. Overview of the TREC 2015 Clinical Decision Support Track. In Proc. Twenty-Fourth Text REtrieval Conference (TREC 2015) (2015). · DOI
Cited by
Sorted by citations
Opportunities and Challenges for ChatGPT and Large Language Models in Biomedicine and Health
Tian, S., Jin, Q., Yeganova, L., Lai, P.-T., Zhu, Q., Chen, X., Yang, Y., Chen, Q., Kim, W., Comeau, D. C., et al. (2023) · Briefings in Bioinformatics · doi:10.1093/bib/bbad493 · Cited by 359
Self-citationRetrieval augmented generation for large language models in healthcare: A systematic review
Amugongo, L. M., Mascheroni, P., Brooks, S., Doering, S., & Seidel, J. (2025) · PLOS Digital Health · doi:10.1371/journal.pdig.0000877 · Cited by 267
Moulaei, K., Yadegari, A., Baharestani, M., Farzanbakhsh, S., Sabet, B., & Reza Afrash, M. (2024) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2024.105474 · Cited by 244
Ocaña, A., Pandiella, A., Privat, C., Bravo, I., Luengo-Oroz, M. A., Amir, E., & Győrffy, B. (2025) · Biomarker Research · doi:10.1186/s40364-025-00758-2 · Cited by 248
Mirakhori, F., & Niazi, S. K. (2025) · Pharmaceuticals · doi:10.3390/ph18010047 · Cited by 176
Hidden flaws behind expert-level accuracy of multimodal GPT-4 vision in medicine
Jin, Q., Chen, F., Zhou, Y., Xu, Z., Cheung, J. M., Chen, R., Summers, R. M., Rousseau, J. F., Ni, P., Landsman, M. J., et al. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01185-7 · Cited by 146
Self-citationPubMed and beyond: biomedical literature search in the age of artificial intelligence
Jin, Q., Leaman, R., & Lu, Z. (2024) · EBioMedicine · doi:10.1016/j.ebiom.2024.104988 · Cited by 152
Self-citationRetrieval-Augmented Generation–Enabled GPT-4 for Clinical Trial Screening
Ünlü, O., Shin, J., Mailly, C. J., Oates, M., Tucci, M. R., Varugheese, M., Wagholikar, K. B., Wang, F., Scirica, B. M., Blood, A. J., et al. (2024) · NEJM AI · doi:10.1056/aioa2400181 · Cited by 128
Unmasking and quantifying racial bias of large language models in medical report generation
Yang, Y., Liu, X., Jin, Q., Huang, F., & Lu, Z. (2024) · Communications Medicine · doi:10.1038/s43856-024-00601-z · Cited by 105
Self-citationApplication of large language models in medicine
Liu, F., Zhou, H., Gu, B., Zou, X., Huang, J., Wu, J., Li, Y., Chen, S. S., Hua, Y., Zhou, P., et al. (2025) · Nature Reviews Bioengineering · doi:10.1038/s44222-025-00279-5 · Cited by 94
Large language models for drug discovery and development
Zheng, Y., Koh, H. Y., Ju, J., Yang, M., May, L. T., Webb, G. I., Li, L., Pan, S., & Church, G. M. (2025) · Patterns · doi:10.1016/j.patter.2025.101346 · Cited by 121
Yuan, M., Bao, P., Yuan, J., Shen, Y., Chen, Z., Xie, Y., Zhao, J., Li, Q., Chen, Y., Zhang, L., et al. (2024) · Medicine Plus · doi:10.1016/j.medp.2024.100030 · Cited by 93
(2024) · ACM eBooks · doi:10.1145/3674127 · Cited by 86
Hallmarks of artificial intelligence contributions to precision oncology
Chang, T., Park, S., Schäffer, A. A., Jiang, P., & Ruppin, E. (2025) · Nature Cancer · doi:10.1038/s43018-025-00917-2 · Cited by 83
A survey on retrieval-augmentation generation (RAG) models for healthcare applications
El-Enen, M. A. A., Saad, S., & Nazmy, T. M. (2025) · Neural Computing and Applications · doi:10.1007/s00521-025-11666-9 · Cited by 88
Zero-Shot Clinical Trial Patient Matching with LLMs
Wornow, M., Lozano, A., Dash, D., Jindal, J., Mahaffey, K. W., & Shah, N. H. (2025) · NEJM AI · doi:10.1056/aics2400360 · Cited by 59
Artificial intelligence to revolutionize IBD clinical trials: a comprehensive review
Sedaño, R., Solitano, V., Vuyyuru, S. K., Yuan, Y., Hanžel, J., Ma, C., Nardone, O. M., & Jairath, V. (2025) · Therapeutic Advances in Gastroenterology · doi:10.1177/17562848251321915 · Cited by 59
Gupta, S., Basu, A., Nievas, M., Thomas, J., Wolfrath, N., Ramamurthi, A., Taylor, B., Kothari, A. N., Schwind, R., Miller, T. M., et al. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01274-7 · Cited by 52
Red teaming ChatGPT in medicine to yield real-world insights on model behavior
Chang, C. T., Farah, H., Gui, H., Rezaei, S. J., Bou-Khalil, C., Park, Y., Swaminathan, A., Omiye, J. A., Kolluri, A., Chaurasia, A., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01542-0 · Cited by 52
Verlingue, L., Boyer, C., Olgiati, L., Brutti-Mairesse, C., Morel, D., & Blay, J. (2024) · The Lancet Regional Health - Europe · doi:10.1016/j.lanepe.2024.101064 · Cited by 50
Riaz, I. B., Harmon, S. A., Chen, Z., Naqvi, S. A. A., & Liang Cheng, C. (2024) · American Society of Clinical Oncology Educational Book · doi:10.1200/edbk_438516 · Cited by 49
AI-Driven Drug Discovery for Rare Diseases
Gangwal, A., & Lavecchia, A. (2024) · Journal of Chemical Information and Modeling · doi:10.1021/acs.jcim.4c01966 · Cited by 49
ESMO guidance on the use of Large Language Models in Clinical Practice (ELCAP)
Wong, E. Y. T., Verlingue, L., Aldea, M., Franzoi, M. A., Umeton, R., Halabi, S., Harbeck, N., Indini, A., Prelaj, A., Romano, E., et al. (2025) · Annals of Oncology · doi:10.1016/j.annonc.2025.09.001 · Cited by 44
Self-citationPark, J., Fang, Y., Ta, C., Zhang, G., Idnay, B., Chen, F., Feng, D. D., Shyu, R., Gordon, E. R., Spotnitz, M., et al. (2024) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2024.104649 · Cited by 42
Self-citationMitigating the risk of health inequity exacerbated by large language models
Ji, Y., Ma, W., Sivarajkumar, S., Zhang, H., Sadhu, E. M., Li, Z., Wu, X., Visweswaran, S., & Wang, Y. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01576-4 · Cited by 62
Landschaft, A., Antweiler, D., Mackay, S., Kugler, S., Rüping, S., Wrobel, S., Höres, T., & Allende-Cid, H. (2024) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2024.105531 · Cited by 41
Large language models in clinical trials: applications, technical advances, and future directions
Lin, A., Wang, Z., Jiang, A., Chen, L., Qi, C., Zhu, L., Mou, W., Gan, W., Zeng, D., Xiao, M., et al. (2025) · BMC Medicine · doi:10.1186/s12916-025-04348-9 · Cited by 39
Self-citationLarge language models vs human for classifying clinical documents
Mustafa, A., Naseem, U., & Azghadi, M. R. (2025) · International Journal of Medical Informatics · doi:10.1016/j.ijmedinf.2025.105800 · Cited by 34
Generative Artificial Intelligence in Medicine
Shanmugam, D., Agrawal, M., Movva, R., Chen, I. Y., Ghassemi, M., Jacobs, M. L., & Pierson, E. (2025) · Annual Review of Biomedical Data Science · doi:10.1146/annurev-biodatasci-103123-095332 · Cited by 40
From RAGs to riches: utilizing large language models to write documents for clinical trials
Markey, N., El-Mansouri, I., Rensonnet, G., van Langen, C., & Meier, C. (2025) · Clinical Trials · doi:10.1177/17407745251320806 · Cited by 33
Azenkot, T., Rivera, D. R. R., Stewart, M. D., & Patel, S. P. (2025) · American Society of Clinical Oncology Educational Book · doi:10.1200/edbk-25-473590 · Cited by 31
Adversarial prompt and fine-tuning attacks threaten medical large language models
Yang, Y., Jin, Q., Huang, F., & Lu, Z. (2025) · Nature Communications · doi:10.1038/s41467-025-64062-1 · Cited by 38
Self-citationDesigning Clinical Trials for Patients With Rare Cancers: Connecting the Zebras
Subbiah, V., Othus, M. K. D., Palma, J., Cuglievan, B., & Kurzrock, R. (2025) · American Society of Clinical Oncology Educational Book · doi:10.1200/edbk-25-100051 · Cited by 28
AI meets informed consent: a new era for clinical trial communication
Waters, M. R. (2025) · JNCI Cancer Spectrum · doi:10.1093/jncics/pkaf028 · Cited by 26
Learning to match patients to clinical trials using large language models
Rybinski, M., Kusa, W., Karimi, S., & Hanbury, A. (2024) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2024.104734 · Cited by 25
A perspective for adapting generalist AI to specialized medical AI applications and their challenges
Wang, Z., Wang, H., Danek, B. P., Li, Y., Mack, C. D., Arbuckle, L., Biswal, D., Poon, H., Wang, Y., Rajpurkar, P., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01789-7 · Cited by 35
Self-citationProbiotic‐Based Materials as Living Therapeutics
Sabio, L., Day, G. J., & Salmerón‐Sánchez, M. (2025) · Advanced Materials · doi:10.1002/adma.202508500 · Cited by 25
Hung, T. K. W., Kuperman, G. J., Sherman, E. J., Ho, A. L., Weng, C., Pfister, D. G., & Mao, J. J. J. (2024) · Journal of Medical Internet Research · doi:10.2196/60695 · Cited by 24
A survey on biomedical automatic text summarization with large language models
Huang, Z., Chen, X., Wang, Y., Huang, J., & Zhao, X. (2025) · Information Processing & Management · doi:10.1016/j.ipm.2025.104216 · Cited by 24
Deep Learning in Digital Breast Tomosynthesis: Current Status, Challenges, and Future Trends
Wang, R., Chen, F., Chen, H., Lin, C. X., Shuai, J., Wu, Y., Ma, L., Hu, X., Wu, M. H., Wang, J., et al. (2025) · MedComm · doi:10.1002/mco2.70247 · Cited by 22
Self-citationBiomedical Natural Language Processing in the Era of Large Language Models
Usuyama, N., Wong, C., Zhang, S., Naumann, T., & Poon, H. (2025) · Annual Review of Biomedical Data Science · doi:10.1146/annurev-biodatasci-103123-095406 · Cited by 22
Vatsal, S., Dubey, H., & Singh, A. (2026) · IEEE Access · doi:10.1109/access.2026.3651218 · Cited by 27
Lozano, A., Sun, M., Burgess, J., Chen, L., Nirschl, J., Gu, J., López, I., Aklilu, J. G., Rau, A., Katzer, A. W., et al. (2025) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52734.2025.01837 · Cited by 20
Niazi, S. K. (2026) · Journal of Chemistry · doi:10.1155/joch/5202999 · Cited by 19
Patients’ selection and trial matching in early-phase oncology clinical trials
Corbaux, P., Bayle, A., Besle, S., Vinceneux, A., Vanacker, H., Ouali, K., Hanvic, B., Baldini, C., Cassier, P. A., Terret, C., et al. (2024) · Critical Reviews in Oncology/Hematology · doi:10.1016/j.critrevonc.2024.104307 · Cited by 19
Artificial intelligence in clinical trials of lung cancer: Current and future prospects
Zhang, Y., You, P., Liu, R., Lu, Y., Li, J., Lei, Y., Wu, S., & Zhou, H. (2024) · Intelligent Oncology · doi:10.1016/j.intonc.2024.11.003 · Cited by 18
The use of large language models to enhance cancer clinical trial educational materials
Gao, M., Varshney, A., Chen, S., Goddla, V., Gallifant, J., Doyle, P., Novack, C., Dillon-Martin, M., Perkins, T. A., Correia, X., et al. (2025) · JNCI Cancer Spectrum · doi:10.1093/jncics/pkaf021 · Cited by 18
A Survey on Unifying Large Language Models and Knowledge Graphs for Biomedicine and Healthcare
Xu, R., Jiang, P., Luo, L., Xiao, C., Cross, A., Pan, S., Sun, J., & Yang, C. (2025) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3711896.3736556 · Cited by 20
Self-citationFrom Transformers to ChatGPT: An Analysis of Large Language Models Research
Cotfas, L., Sandu, A., Delcea, C., Diaconu, P., Frăsineanu, C., & Stănescu, A. (2025) · IEEE Access · doi:10.1109/access.2025.3600739 · Cited by 21
Yang, Y., Jin, Q., Zhu, Q., Wang, Z., Álvarez, F. E., Wan, N., Hou, B., & Lu, Z. (2025) · Annual Review of Biomedical Data Science · doi:10.1146/annurev-biodatasci-103123-094851 · Cited by 20
Self-citationPan, J., Zhong, R., Xia, F., Huang, J., Zhu, L., Yang, Y., & Lin, T. (2025) · Plant Phenomics · doi:10.1016/j.plaphe.2025.100094 · Cited by 19
Self-citationA prospective pragmatic evaluation of automatic trial matching tools in a molecular tumor board
Gueguen, L., Olgiati, L., Brutti-Mairesse, C., Sans, A., Texier, V. L., & Verlingue, L. (2025) · npj Precision Oncology · doi:10.1038/s41698-025-00806-y · Cited by 14
Synthetic data distillation enables the extraction of clinical information at scale
Woo, E. G., Burkhart, M. C., Alsentzer, E., & Beaulieu‐Jones, B. K. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01681-4 · Cited by 18
Chen, H., Li, X., He, X., Chen, A., McGill, J. M., Webber, E. C., Xu, H., Liu, M., & Bian, J. (2025) · JCO Clinical Cancer Informatics · doi:10.1200/cci-25-00071 · Cited by 14
Huang, N., Wei, Y., & Li, J. (2025) · Journal of Biological Engineering · doi:10.1186/s13036-025-00562-4 · Cited by 14
Convergence of machine learning and genomics for precision oncology
Reardon, B. M., Culhane, A. C., & Allen, E. M. V. (2026) · Nature reviews. Cancer · doi:10.1038/s41568-025-00897-6 · Cited by 14
Use of AI as a Research Recruitment Tool: Ethical Elements, Considerations, and Recommendations
Rentzepis, P. J., Snyder, D. L., Baker, T. J., & Bierer, B. E. (2026) · The American Journal of Bioethics · doi:10.1080/15265161.2026.2649234 · Cited by 14
Deep Learning in Hematology: From Molecules to Patients
Wang, J. (2024) · Clinical Hematology International · doi:10.46989/001c.124131 · Cited by 15
Patient-Centered Research Through Artificial Intelligence to Identify Priorities in Cancer Care
Kim, J., Chen, M. L., Rezaei, S. J., Ramírez‐Posada, M., Caswell-Jin, J. L., Kurian, A. W., Riaz, F., Sarin, K. Y., Tang, J. Y., Asch, S. M., et al. (2025) · JAMA Oncology · doi:10.1001/jamaoncol.2025.0694 · Cited by 14
Panacea: A foundation model for clinical trial search, summarization, design, and recruitmentPreprint
Lin, J., Xu, H., Wang, Z., Wang, S., & Sun, J. (2024) · medRxiv · doi:10.1101/2024.06.26.24309548 · Cited by 15
Self-citationHuang, K. (2025) · Progress in IS · doi:10.1007/978-3-031-90026-6_10 · Cited by 13
Lee, K., Mai, Y., Liu, Z., Raja, K., Higashi, M. K., Jun, T., Ma, M., Wang, T., Ai, L., Calay, E., et al. (2024) · Scientific Reports · doi:10.1038/s41598-024-77447-x · Cited by 14
Why is it hard to assess thought disorder? Clarifying the third domain of psychosis
Palaniyappan, L. K., Sreeraj, V. S., Venkatasubramanian, G., & Voppel, A. (2026) · Schizophrenia Research · doi:10.1016/j.schres.2026.02.018 · Cited by 12
TRIALSCOPE — A Framework for Clinical Trial Simulation from Real-World Data
Hernández, J. G., Ueno, R., Wong, C., Gero, Z., Bagga, J., Chien, I., Oravkin, E., Kıcıman, E., Nori, A. V., Weerasinghe, R. K., et al. (2025) · NEJM AI · doi:10.1056/aioa2400859 · Cited by 12
Gichoya, J. W., Mwavu, R., Minja, F. J., Kaonga, N., Purkayastha, S., & Newsome, J. M. (2025) · The Lancet Digital Health · doi:10.1016/j.landig.2025.100937 · Cited by 13
Making large language models reliable data science programming copilots for biomedical research
Wang, Z., Danek, B. P., Yang, Z., Chen, Z., & Sun, J. (2026) · Nature Biomedical Engineering · doi:10.1038/s41551-025-01587-2 · Cited by 11
Self-citationGong, E. J., Bang, C. S., & Shin, Y. S. (2026) · Bioengineering · doi:10.3390/bioengineering13030365 · Cited by 14
AI in Biomedicine—A Forward-Looking Perspective on Health Equity
Kumar, D., Malin, B., Vishwanatha, J. K., Wu, L., & Hedges, J. R. (2024) · International Journal of Environmental Research and Public Health · doi:10.3390/ijerph21121642 · Cited by 11
Jia, X., Rong, Y., Wu, Q. J., Cárdenas, C., Court, L. E., Hrinivich, W. T., Kang, H., Kovalchuk, N., Whitaker, T. J., Xiao, Y., et al. (2025) · International Journal of Radiation Oncology*Biology*Physics · doi:10.1016/j.ijrobp.2025.03.045 · Cited by 11
The DRAGON benchmark for clinical NLP
Bosma, J. S., Dercksen, K., Builtjes, L., André, R., Roest, C., Fransen, S. J., Noordman, C. R., Navarro-Padilla, M., Lefkes, J., Alves, N., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01626-x · Cited by 15
Dennstädt, F., Windisch, P. Y., Filchenko, I., Zink, J., Putora, P. M., Shaheen, A., Gaio, R., Čihorić, N., Wosny, M., Aeppli, S., et al. (2025) · Oncology · doi:10.1159/000546946 · Cited by 11
Long-Term Follow-Up Care After Treatment for Primary Breast Cancer: Strategies and Considerations
Franzoi, M. A., Janni, W. J., Erdmann-Sager, J., Kline‐Quiroz, C. M., Schäffler, H., Pfister, K., Fazzalari, A., & Vaz-Luís, I. (2025) · American Society of Clinical Oncology Educational Book · doi:10.1200/edbk-25-473472 · Cited by 10
Preparing Allergists to Practice in 2050 Using Artificial Intelligence
Khoury, P., Oppenheimer, J., Bunyavanich, S., Ciaccio, C. E., & Portnoy, J. M. (2025) · The Journal of Allergy and Clinical Immunology In Practice · doi:10.1016/j.jaip.2025.09.012 · Cited by 10
Enhanced LLM-supported instructions for medication use through retrieval-augmented generation
de Jesus, D., Júnior, A. P. D. S., de Albergaria, E. T., Pagano, A. S., de Oliveira, I. J. R., Dias, C. D. S., Lage, E. M., de Oliveira, F. R., Oliveira, J. A., Gomes, I. D. C., et al. (2025) · Computers in Biology and Medicine · doi:10.1016/j.compbiomed.2025.111135 · Cited by 10
Parikh, R. B., Kolla, L., Beothy, E. A., Ferrell, W. J., Laventure, B., Guido, M., Girard, A., Li, Y., Dosoky, K. E. M., Tarabishy, K., et al. (2026) · Nature Communications · doi:10.1038/s41467-026-68873-8 · Cited by 10
Castells, P., & Jannach, D. (2024) · ACM eBooks · doi:10.1145/3674127.3674131 · Cited by 10
Compliance and factuality of large language models for clinical research document generation
Wang, Z., Gao, J., Danek, B. P., Theodorou, B., Shaik, R., Thati, S., Won, S., & Sun, J. (2025) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocaf174 · Cited by 9
Self-citationLeveraging artificial intelligence for equitable women’s health outcomes through imaging
Ndirangu, B., Newsome, J. M., Chavoshi, M., Trivedi, H., & Gichoya, J. W. (2026) · British Journal of Radiology · doi:10.1093/bjr/tqag035 · Cited by 10
Tutorial: guidance on the use of large language models for medical research
Jin, Q., Wan, N., Leaman, R., Tian, S., Wang, Z., Yang, Y., Wang, Z., Xiong, G., Lai, P.-T., Zhu, Q. L., et al. (2026) · Nature Protocols · doi:10.1038/s41596-026-01408-z · Cited by 15
Self-citationLoaiza-Bonilla, A., Yost, C., Kurnaz, S., Tuysuz, E., Thaker, N. G., Giritlioglu, D., & Noel Meza, J. P. (2026) · ESMO Real World Data and Digital Oncology · doi:10.1016/j.esmorw.2026.100706 · Cited by 12
“Prior systems have demonstrated that LLMs, retrieval, and ontology alignment can help identify candidate trials, 3,4,11-13 but many published approaches remain retrospective, disease-limited, or optimized for text similarity and retrieval rather than auditable patient — trial execution over…”
Armoundas, A. A., & Singh, J. P. (2026) · European Heart Journal - Digital Health · doi:10.1093/ehjdh/ztag019 · Cited by 8
Bi, K., Zhao, Y., Lu, S., Xu, K., & Zhang, Y. (2024) · Infectious Microbes & Diseases · doi:10.1097/im9.0000000000000169 · Cited by 8
Use of Large Language Models in Clinical Cancer Research
Kehl, K. L. (2025) · JCO Clinical Cancer Informatics · doi:10.1200/cci-25-00027 · Cited by 9
Gao, H., Wang, K., Yuan, Y., Wang, Y., Liu, Q., Wang, Y., Sun, J. Q., Wang, W., Wang, H., Zhou, S., et al. (2025) · Scientific Reports · doi:10.1038/s41598-025-07649-4 · Cited by 9
Self-citationConstructing the cure: engineering the next wave of antibody and cellular immune therapies
Bailey, S. R., Bartee, E., Daniels, K. G., Heery, C. R., Kaumaya, P. T. P., Lesinski, G. B., Lowinger, T. B., Nelson, M. H., Rubinstein, M. P., Wittling, M. C., et al. (2025) · Journal for ImmunoTherapy of Cancer · doi:10.1136/jitc-2025-011761 · Cited by 8
Review of Large Language Models for Patient and Caregiver Support in Cancer Care Delivery
Kouzy, R., Cha, E. E., Rosen, A., & Bitterman, D. S. (2025) · JCO Clinical Cancer Informatics · doi:10.1200/cci-25-00044 · Cited by 10
Yan, D., Zheng, Q., Chang, K., Hua, R., Liu, Y., Xue, J., Shu, Z., Hu, Y., Yang, P., Wei, Y., et al. (2025) · Chinese Journal of Natural Medicines · doi:10.1016/s1875-5364(25)60983-6 · Cited by 8
Application and Prospects of Large Language Models in Small-Molecule Drug Discovery
Ma, J., Liu, J., Xu, D., Song, X., & Zhang, Z. (2025) · Analytical Chemistry · doi:10.1021/acs.analchem.5c04083 · Cited by 9
Large Language Models in Cardiovascular Prevention: A Narrative Review and Governance Framework
Santos, J. F., & Dores, H. (2026) · Diagnostics · doi:10.3390/diagnostics16030390 · Cited by 8
Hamamoto, R., Koyama, T., Takahashi, S., Yasuda, T., Kobayashi, K., Akagi, Y., Kouno, N., Sudo, K., Hirata, M., Sunami, K., et al. (2026) · Journal of Hematology & Oncology · doi:10.1186/s13045-026-01781-y · Cited by 8
Artificial Intelligence and the Transformation of Cell and Gene Therapy Development
Auclair, J. R., Joung, J., Singh, M. A., Debauve, G., & Singh, R. (2026) · Pharmaceutics · doi:10.3390/pharmaceutics18030356 · Cited by 8
Current advancement in AI-integrated drug discovery: Methods and applications
Mathur, Y., Choudhury, A., Prabha, S., Saeed, M. U., Sulaimani, M. N., Mohammad, T., & Hassan, M. I. (2025) · Biotechnology Advances · doi:10.1016/j.biotechadv.2025.108642 · Cited by 8
Shi, H., Zhang, J., & Zhang, K. (2026) · IEEE International Conference on Healthcare Informatics (ICHI) · doi:10.1109/ichi69079.2026.00111 · Cited by 9
Gui, X., Lv, H., Wang, X., Lv, L., Xiao, Y., & Wang, L. (2025) · BioData Mining · doi:10.1186/s13040-025-00458-5 · Cited by 10
“…(e.g., Pathway A - Majority Vote) delivered high precision (typical around 0.92, which compares favorably to reported manual annotation performance [30]) and also demonstrated good recall (e.g., typically > 0.85 for these tasks, as shown in Supplemental Table S3), contributing to both accuracy and…”
InfluentialPatient2Trial: From patient to participant in clinical trials using large language models
Datta, S., Lee, K., Huang, L., Paek, H., Gildersleeve, R., Gold, J., Pillai, D., Wang, J., Higashi, M. K., Shi, L., et al. (2025) · Informatics in Medicine Unlocked · doi:10.1016/j.imu.2025.101615 · Cited by 7
Pharmacogenomics Meets Generative AI: Transforming Clinical Trial Design with Large Language Models
Fatharani, A., & Alsayegh, A. (2025) · Journal of Pharmacology and Pharmacotherapeutics · doi:10.1177/0976500x251321885 · Cited by 8
Large Language Models in Randomized Controlled Trials Design: Observational Study
Jin, L., Ong, J. C. L., Elangovan, K., Ke, Y., Pyle, A., Ting, D. S. W., & Liu, N. (2025) · Journal of Medical Internet Research · doi:10.2196/67469 · Cited by 7
Wang, Z., Zhang, R., Ji, C., Zhang, J., Yue, B., & Wang, F. (2025) · World Journal of Gastrointestinal Oncology · doi:10.4251/wjgo.v17.i10.111339 · Cited by 7
Self-citationCallies, A., Bodinier, Q., Ravaud, P., & Davarpanah, K. (2025) · Communications Medicine · doi:10.1038/s43856-025-01256-0 · Cited by 7
A context-augmented large language model for accurate precision oncology medicine recommendations
Jun, H., Tanaka, Y., Johri, S., Camp, S. Y., Bao, E. L., Carvalho, F. L. F., Gui, D. Y., Jordan, A. C., Labaki, C., Martin, S. D., et al. (2026) · Cancer Cell · doi:10.1016/j.ccell.2025.12.017 · Cited by 8
Metadata
- Authors
- Jin, Q., Wang, Z., Floudas, C. S., Chen, F., Gong, C., Bracken-Clarke, D., Xue, E., Yang, Y., Sun, J., & Lu, Z.
- Affiliations
- National Institutes of Health (US)
- University of Illinois Urbana-Champaign (US)
- University of Pittsburgh (US)
- Albert Einstein College of Medicine (US)
- Corresponding author
- Lu, Zhiyong
- ORCID
- Venue
- Nature Communications
- Published
- 2024-11-18
- Volume
- 15
- Issue
- 1
- Pages
- 9074-9074
- ISSN
- 2041-1723 (ISSN-L)
- PMC
- PMC11574183
- OpenAlex
- W4404486407
- Cited by
- 287
- References
- 43
- Citations by year
- 2026: 119 · 2025: 117 · 2024: 50
- FWCI
- 26.74
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- Nature Communications (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by)
- PubMed Central (submittedVersion, cc-by)
- RePEc: Research Papers in Economics (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University) (cc-by)
- Funders
- U.S. Department of Health & Human Services | National Institutes of Health
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Physical Sciences › Computer Science › Information Systems › Information Retrieval and Search Behavior
- Keywords
- clinical trial recruitment, large language models, explainable AI, synthetic patient data, user study
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
