

The DOI matches its Crossref record; 96 of the 96 references it cites were found in a registry or an index; 1 of the 11 sources its claims cite were checked for support.
When combinations of humans and AI are useful: A systematic review and meta-analysis
Open accessPublished version of a preprint
Abstract
Inspired by the increasing use of artificial intelligence (AI) to augment humans, researchers have studied human–AI systems involving different tasks, systems and populations. Despite such a large body of work, we lack a broad conceptual understanding of when combinations of humans and AI are better than either alone. Here we addressed this question by conducting a preregistered systematic review and meta-analysis of 106 experimental studies reporting 370 effect sizes. We searched an interdisciplinary set of databases (the Association for Computing Machinery Digital Library, the Web of Science and the Association for Information Systems eLibrary) for studies published between 1 January 2020 and 30 June 2023. Each study was required to include an original human-participants experiment that evaluated the performance of humans alone, AI alone and human–AI combinations. First, we found that, on average, human–AI combinations performed significantly worse than the best of humans or AI alone (Hedges’ g = −0.23; 95% confidence interval, −0.39 to −0.07). Second, we found performance losses in tasks that involved making decisions and significantly greater gains in tasks that involved creating content. Finally, when humans outperformed AI alone, we found performance gains in the combination, but when AI outperformed humans alone, we found losses. Limitations of the evidence assessed here include possible publication bias and variations in the study designs analysed. Overall, these findings highlight the heterogeneity of the effects of human–AI collaboration and point to promising avenues for improving human–AI systems.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
This preregistered systematic review and meta-analysis of 106 experiments (370 effect sizes) finds that, on average, human–AI combinations perform worse than the best of humans or AI alone, though they do outperform humans alone. Effects vary by task type and by whether humans or AI perform better alone.
Key findings
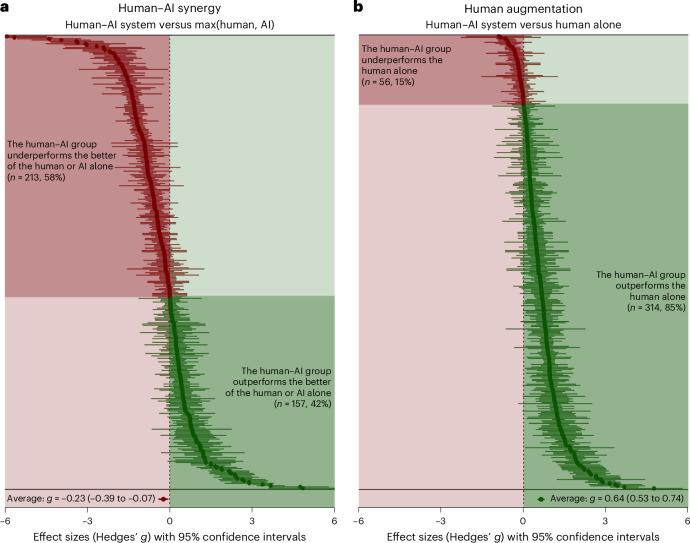
- Human–AI combinations showed negative overall synergy versus the better of human alone or AI alone: Hedges’ g = −0.23 (95% CI, −0.39 to −0.07; P = 0.005).
- Human–AI combinations did show human augmentation versus humans alone: g = 0.64 (95% CI, 0.53 to 0.74; P = 0.000).
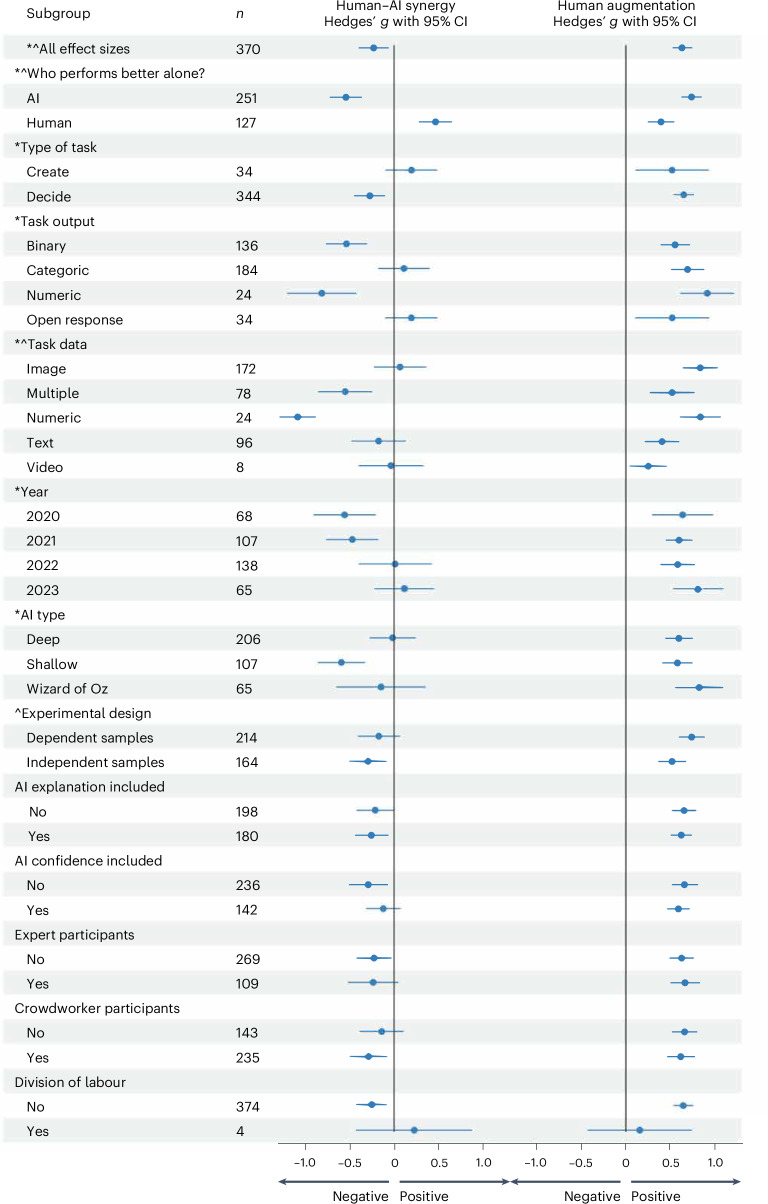
- Task type moderated synergy: decision tasks had losses (g = −0.27; 95% CI, −0.44 to −0.10; P = 0.002), while creation tasks had positive but non-significant gains (g = 0.19; 95% CI, −0.09 to 0.48; P = 0.180), with a significant difference between task types.
- Relative human/AI performance moderated synergy: when humans alone outperformed AI alone, synergy was positive (g = 0.46; 95% CI, 0.28 to 0.66); when AI alone outperformed humans alone, synergy was negative (g = −0.54; 95% CI, −0.71 to −0.37). Explanation, confidence, participant type, and division of labour were not statistically significant moderators.
Methods
- Preregistered systematic review and meta-analysis following Kitchenham and PRISMA guidelines; searched ACM Digital Library, Web of Science, and AIS eLibrary for studies published 1 January 2020–30 June 2023.
- From 5,126 initial papers, 74 met inclusion criteria, yielding 106 experiments and 370 unique effect sizes; included studies had to report performance for human alone, AI alone, and human–AI combination.
- Used Hedges’ g and a three-level random-effects meta-analytic model with robust variance estimation, Knapp–Hartung adjustment, and separate meta-regressions for moderators; sensitivity analyses clustered at paper level, excluded outliers, and used leave-one-out checks.
Limitations
- The paper states that results apply only to studies reporting all three conditions, so tasks that neither humans nor AI can perform alone are excluded; samples and outcome measures varied across studies, limiting comparability, and measurement error was not fully modelled.
- The paper states possible publication bias remains possible, though tests did not indicate it for synergy; tests did indicate potential publication bias for human augmentation. It also notes possible research topic selection bias, variation in study rigour, and high unexplained heterogeneity.
- Evident from the text: most effect sizes concerned decision tasks (~85%) and most human–AI systems had humans making final decisions after AI input (>95%), so findings may not generalize to other human–AI configurations.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
36 Own result · 14 Own interpretation · 7 Own method · 6 No full text of the sources · 6 No basis given · 1 Supported so far · 1 Sources not found · 1 Not checked yet
The sources with a verdict support this claim; the rest weren’t checked yet, have no full text we could read, or their verdicts aren’t rated yet.
In the paper
“We thus adopted a three-level meta-analytic model in which effect sizes are nested within experiments, so we explicitly took the dependencies in our data into account in the model63,64.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Methods > Data analysis
What the sources say
- Supportedcites [63] Van den Noortgate, W., López-López, J. A., Marín-Martínez, F. & Sánchez-Meca, J. Meta-analysis of multiple outcomes: a multilevel approach. Behav. Res. Methods 47, 1274–1294 (2015). source
The Abstract describes a three-level meta-analytic model for dependence among multiple effect sizes from the same study. The Conclusions likewise state that the approach accounts for dependence between effect sizes within studies. The citing authors’ adoption of the model is their own methodological choice, not a finding attributed to this source. (LLM, conf=0.92)
- Not checked — no full text of the sourcecites [64] Cheung, M. W.-L. Modeling dependent effect sizes with three-level meta-analyses: a structural equation modeling approach. Psychol. Methods 19, 211–229 (2014). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We also found that the type of AI involved in the experiment (F2,103 = 3.77, two-tailed P = 0.026) and the year of publication (F3,102 = 3.65, two-tailed P = 0.015) moderated human–AI synergy, and the experimental design moderated human augmentation (F1,104 = 4.90, two-tailed P = 0.029).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Even though the average performance gains for creation tasks were not significantly different from 0 (presumably because of the relatively small sample size of n = 34), the difference between losses for decision tasks and gains for creation tasks was statistically significant.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Only 3 of the 100+ experiments in our analysis explore such processes with a predetermined delegation of separate subtasks to humans and AI.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Moderating effect of task type
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We also found that the type of AI involved in the experiment (F2,103 = 3.77, two-tailed P = 0.026) and the year of publication (F3,102 = 3.65, two-tailed P = 0.015) moderated human–AI synergy, and the experimental design moderated human augmentation (F1,104 = 4.90, two-tailed P = 0.029).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“First, we found that the type of task significantly moderated human–AI synergy (F1,104 = 7.84, two-tailed P = 0.006).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, when we compared the performance of the human–AI systems to a different baseline—the humans alone—we found substantial evidence of human augmentation. The human–AI systems performed significantly better than humans alone, and this pooled effect size was positive (g = 0.64; t98 = 11.87; two-tailed P = 0.000; 95% CI, 0.53 to 0.74) and medium to large21.”
- Also stated in: § Main · plain
“On average, we found evidence of human augmentation, meaning that the average human–AI systems performed better than the human alone.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Overall levels of human–AI synergy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Main · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Among decision tasks—those in which participants decided between a finite set of options—the pooled effect size for human–AI synergy was significantly negative (g = −0.27; t104 = −3.20; two-tailed P = 0.002; 95% CI, −0.44 to −0.10), which indicates performance losses from combining humans and AI.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“But when the AI alone outperformed the human alone, performance losses occurred in the combined system relative to the AI alone, with a negative effect size for human–AI synergy of g = −0.54 (t104 = −6.20; two-tailed P = 0.000; 95% CI, −0.71 to −0.37), a medium-sized effect21.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Here we addressed this question by conducting a preregistered systematic review and meta-analysis of 106 experimental studies reporting 370 effect sizes.”
- Also stated in: § Results · plain
“These papers reported the results of 106 unique experiments, and many of the experiments had multiple conditions, so we collected a total of 370 unique effect sizes measuring the impact of human–AI collaboration on task performance.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Results · plain
- It may state two separate claims as one. 23
- Probably not a substantial claim. 16
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We also found evidence for substantial heterogeneity of effect sizes in our estimations of human–AI synergy (I2 = 97.7%) and human augmentation (I2 = 93.8%) (see Supplementary Tables 5 and 6 for more details).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“With the four effect sizes from these 3 experiments, we found that, on average, human–AI synergy (g = 0.22, t104 = 0.69; two-tailed P = 0.494; 95% CI, −0.42 to 0.87) occurred, but the result was not statistically significant (see Supplementary Information section 2.6 for a more detailed discussion of these experiments).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Moderating effect of task type
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The remaining moderators we investigated were not statistically significant for human–AI synergy or human augmentation (explanation, confidence, participant type and division of labour).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Second, we found that the performance of the human and AI relative to each other impacted both human–AI synergy (F1,104 = 81.79, two-tailed P = 0.000) and human augmentation (F1,104 = 24.35, two-tailed P = 0.000).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Relatedly, we found that the type of data involved in the task significantly moderated both human–AI synergy (F4,101 = 15.24, two-tailed P = 0.000) and human augmentation (F4,101 = 6.52, two-tailed P = 0.000).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As shown in Fig. 2, when the human alone outperformed the AI alone, the combined human–AI system outperformed both alone with an average pooled effect size for human–AI synergy of g = 0.46 (t104 = 5.06; two-tailed P = 0.000; 95% CI, 0.28 to 0.66), a medium-sized effect21.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“When the AI outperformed the human alone, greater performance gains tended to occur in the human–AI systems relative to the human alone, and the pooled effect size for human augmentation was positive and medium to large in magnitude (g = 0.74; t104 = 13.50; two-tailed P = 0.000; 95% CI, 0.63 to 0.85) (see Supplementary Figs. 4–7 for a more detailed visualization of this result for decision tasks).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“The measurement error can also vary across experiments.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Limitations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In contrast, among creation tasks—those in which participants created some sort of open-response content—the pooled effect size for human–AI synergy was positive (g = 0.19; t104 = 1.35; two-tailed P = 0.180; 95% CI, −0.09 to 0.48), pointing to synergy between humans and AI.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
hedgedn = 34- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“We find this assumption plausible because the experiments recruited different sets of participants and entailed different tasks or interventions.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Methods > Sensitivity analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Supplementary Fig. 9 displays the funnel plot of the included effect sizes, and we did not observe significant asymmetry or regions of missing data in the plot for our primary outcome, human–AI synergy.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Methods > Bias tests
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Many of the experiments in our analysis evaluate performance according to a single measure of overall accuracy, but this measure corresponds to different things depending on the situation, and it omits other important criteria for human–AI systems.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > A roadmap for future work: finding human–AI synergy
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“For example, studies used different attention check mechanisms and performance incentive structures, which can both affect the quality of responses and thus introduce another source of noise into our data.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Limitations
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“For example, researchers mostly used their own experimental platforms and stimuli, which naturally introduce sources of variation between their studies.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Limitations
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Using this approach, we identified 11 outliers for human–AI synergy and 9 outliers for human augmentation.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Methods > Sensitivity analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our initial literature search yielded 5,126 papers, and, per the review process described in the Methods (see ‘Literature review’), we identified 74 that met our inclusion criteria (Supplementary Fig. 1).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We searched an interdisciplinary set of databases (the Association for Computing Machinery Digital Library, the Web of Science and the Association for Information Systems eLibrary) for studies published between 1 January 2020 and 30 June 2023.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Each study was required to include an original human-participants experiment that evaluated the performance of humans alone, AI alone and human–AI combinations.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Here we addressed this question by conducting a preregistered systematic review and meta-analysis of 106 experimental studies reporting 370 effect sizes.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“We conducted this meta-analysis in accord with the guidelines from Kitchenham55 on systematic reviews, and we followed the standards set forth by the Preferred Reporting Items for Systematic Reviews and Meta-Analyses56.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Methods
What the sources say
- Not matchedcites Kitchenham55
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not checked — no full text of the sourcecites [56] Moher, D., Liberati, A., Tetzlaff, J., Altman, D. G. & PRISMA Group Preferred reporting items for systematic reviews and meta-analyses: the PRISMA statement. Ann. Intern. Med. 151, 264–269 (2009). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Not matched
In the paper
“We chose Hedges’ g as our measure of effect size because it is unitless, so it allows us to compare human–AI performance across different metrics, and it corrects for upward bias in the raw standardized mean difference (Cohen’s d)61.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Methods > Data analysis
What the sources say
- Not checked — no full text of the sourcecites [61] Hedges, L. V. Distribution theory for Glass’s estimator of effect size and related estimators. J. Educ. Stat. 6, 107–128 (1981). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We synthesized these data in a three-level meta-analytic model (see ‘Data analysis’ in Methods).”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Third, although we did not find evidence of publication biases, it remains possible that they exist, which would impact our literature base and, by extension, our meta-analytic results.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Limitations
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Fourth, our results only apply to the tasks, processes and participant pools that researchers have chosen to study, and these configurations may not be representative of the ways human–AI systems are configured in practical uses of AI outside the laboratory.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Limitations
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, we expect that if there were a publication bias operating here, it would be a bias to publish studies that showed significant gains from combining humans and AI. And since our overall results showed the opposite, it seems unlikely that they are a result of publication bias.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Limitations
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“As is typical for meta-analyses43, in our three-level model, we weighted effect sizes as a function of their variance across participants, so we did not account for this other source of variation in measurement.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Limitations
What the sources say
- Not checked — no full text of the sourcecites [43] Borenstein, M., Hedges, L. V., Higgins, J. P. & Rothstein, H. R. Introduction to Meta-analysis (John Wiley & Sons, 2021). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In other words, the human–AI systems we analysed were, on average, better than humans alone but not better than both humans alone and AI alone.”
- Also stated in: § Main · plain
“On average, we found evidence of human augmentation, meaning that the average human–AI systems performed better than the human alone. But we did not find human–AI synergy on average, meaning that the average human–AI systems performed worse than at least one of the human alone or the AI alone.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Overall levels of human–AI synergy
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Main · plain
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We have made the materials required to reproduce our results publicly accessible through an Open Science Framework repository.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Fifth, the quality of our analysis depends on the quality of the studies we synthesized.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Limitations
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The moderators we investigated account for some of this heterogeneity, but much remains unexplained.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Limitations
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The discrepancy between the symmetry in the funnel plot for human–AI synergy versus asymmetry in the funnel plot for human augmentation may reflect how many researchers and journals implicitly assume an interest in human augmentation, comparing the human–AI system to the human alone.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Methods > Bias tests
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it.
In the paper
“Additionally, as discussed in ref. 33, human–AI synergy requires that humans be better at some parts of a task, AI be better at other parts of the task and the system as a whole be good at appropriately allocating subtasks to whichever partner is best for that subtask.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > A roadmap for future work: finding human–AI synergy
What the sources say
- Not checked — no full text of the sourcecites [33] Donahue, K., Chouldechova, A. & Kenthapadi, K. Human–algorithm collaboration: achieving complementarity and avoiding unfairness. In Proc. 2022 ACM Conference on Fairness, Accountability, and Transparency 1639–1656 (Association for Computing Machinery, 2022); https://doi.org/10.1145/3531146.3533221 source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“To further ensure comprehensive coverage, we also conducted a forward and backward search on all studies we found that met our inclusion criteria.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Methods > Literature review
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper relies on this without support.
There is a lack of broad conceptual understanding of when combinations of humans and AI are better than either alone.
“Despite such a large body of work, we lack a broad conceptual understanding of when combinations of humans and AI are better than either alone.”
The authors state this as an assumption.
The experiments in the analysis are independent from each other even if they come from the same paper.
“It does, however, consider the experiments in our analysis as independent from each other, even if they come from the same paper. We find this assumption plausible because the experiments recruited different sets of participants and entailed different tasks or interventions.”
The paper relies on this without support.
The participant samples overlapped only on the level of the experiment.
“because the participant samples overlapped only on the level of the experiment.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“While Gen-AI as an MKO can improve learning process, whereas over-reliance on these tools leads to logical complacency and selective cognitive atrophy (Vaccaro, , Almaatouq, & Malone, 2024).”
From The Double-Edged Sword of Automation: Impact of Generative AI Adoption on Student's Critical Thinking Skills in Higher Education Considering Cognitive Offloading as a Mediator (2026) · cites this paper as Vaccaro, , Almaatouq, & Malone, 2024
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Vaccaro et al. (2024) showed that human-AI combinations often outperform either alone in creative tasks.”
From Metadiscourse Patterns in Human-Written vs. Generative AI-Authored Research Abstracts: A Comparative Corpus-Based Analysis (2026) · cites this paper as Vaccaro et al. (2024)
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“To support the introduction of AI in clinical practice in intensive care, we propose starting with the concept of human-AI augmentation, which is more inclusive and better established according to medical literature [34].”
From Implementing Artificial Intelligence in Critical Care Medicine: a consensus of 22. (2025) · cites this paper as [34]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Recent meta-analyses of human-AI collaboration show that combinations sometimes underperform either party in isolation (Vaccaro et al., 2024)”
From Indie at Scale: How Large Language Models Make Community-Centered Game Development Economically Viable (2026) · cites this paper as Vaccaro et al., 2024
The cited source says what the claim attributes to it.
In the citing paper
“This collaboration has been described in two forms: human-AI augmentation (when human–AI interface enhances clinical performance compared to human alone) and human-AI synergy (where the combined performance exceeds that of both the human and the AI individually) [34].”
From Implementing Artificial Intelligence in Critical Care Medicine: a consensus of 22. (2025) · cites this paper as [34]
The cited source says what the claim attributes to it.
In the citing paper
“Vaccaro et al .'s meta-analysis of 106 experimental studies found that human-AI combinations performed worse than the best individual decision-maker on average for decision tasks 34 .”
From AI-induced never-skilling in medical education (2026) · cites this paper as [34]
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Such tasks may have been part of the training data in GenAI models, which is a known issue in GenAI research [61]”
From Generative AI and Creativity: A Systematic Literature Review and Meta-Analysis (2025) · cites this paper as [61]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated major: it would touch a result — a value a result rests on, reported and recomputed p-values on opposite sides of the significance level, two passages that conflict with no sign which is right, or a cited work retracted before this paper was published.
In the paper
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Discussion > Surprisingly insignificant moderators
“the significant and less researched moderators we identified: the baseline performance of the human and AI alone, the type of task they perform, and the division of labour between them.”
§ When combinations of humans and AI are useful: A systematic review and meta-analysis > Results > Heterogeneity of human–AI synergy
“The remaining moderators we investigated were not statistically significant for human–AI synergy or human augmentation (explanation, confidence, participant type and division of labour).”
Citations
Cites
Bias in meta-analysis detected by a simple, graphical test
Egger, M., Smith, G. D., Schneider, M., & Minder, C. (1997) · BMJ · doi:10.1136/bmj.315.7109.629 · Cited by 56,722 · cited 1×
“We visually inspected the plots and performed Egger’s regression test 70 as well as the rank correlation test 71 to evaluate the results in the funnel plots.”
Preferred reporting items for systematic reviews and meta-analyses: the PRISMA Statement.
(2009) · PubMed Central · Cited by 44,859
Preferred reporting items for systematic reviews and meta-analyses: The PRISMA statement
Moher, D., Liberati, A., Tetzlaff, J., Altman, D. G., & the PRISMA Group* (2009) · Annals of Internal Medicine · doi:10.7326/0003-4819-151-4-200908180-00135 · Cited by 37,554
Quantifying heterogeneity in a meta‐analysis
Higgins, J. P. T., & Thompson, S. G. (2002) · Statistics in Medicine · doi:10.1002/sim.1186 · Cited by 36,763
Statistical Power Analysis for the Behavioral Sciences
Cohen, J. (2013) · doi:10.4324/9780203771587 · Cited by 25,373
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Conducting Meta-Analyses in R with the metafor Package
Viechtbauer, W. (2010) · Journal of Statistical Software · doi:10.18637/jss.v036.i03 · Cited by 20,464
Operating characteristics of a rank correlation test for publication bias
Begg, C. B., & Mazumdar, M. (1994) · Biometrics · doi:10.2307/2533446 · Cited by 16,955 · cited 1×
“We visually inspected the plots and performed Egger’s regression test 70 as well as the rank correlation test 71 to evaluate the results in the funnel plots.”
Mastering the game of Go with deep neural networks and tree search
Silver, D., Huang, A., Maddison, C. J., Guez, A., Sifre, L., van den Driessche, G., Schrittwieser, J., Antonoglou, I., Panneershelvam, V., Lanctot, M., et al. (2016) · Nature · doi:10.1038/nature16961 · Cited by 15,612
Borenstein, M., Hedges, L. V., Higgins, J. P. T., & Rothstein, H. R. (2021) · doi:10.1002/9781119558378 · Cited by 9,799
Research works printed but not linked: 2
- Wilson, H. J. & Daugherty, P. R. Collaborative intelligence: humans and AI are joining forces. Harv. Bus. Rev. 96, 114–123 (2018).
- Hedges, L. V. & Olkin, I. Statistical Methods for Meta-analysis (Academic Press, 2014).
Cited by
Sorted by citations
Items 201–300 of 578
Chen, Q., Wang, H., Ma, C., & Ru, P. (2025) · Social Science & Medicine · doi:10.1016/j.socscimed.2025.118626 · Cited by 3
Is Consent-GPT valid? Public attitudes to generative AI use in surgical consent
Allen, J. W., Hannikainen, I. R., Savulescu, J., Wilkinson, D. J. C., & Earp, B. D. (2025) · AI & Society · doi:10.1007/s00146-025-02644-9 · Cited by 4
Human-in-the-Loop Bayesian Optimization for Artificial Intelligence-Guided Design
Jetton, C., Campbell, M. I., & Hoyle, C. (2025) · Journal of Mechanical Design · doi:10.1115/1.4070429 · Cited by 2
Confidence-weighted integration of human and machine judgments for superior decision-making
Yáñez, F., Luo, X., Minero, O. V., & Love, B. C. (2025) · Patterns · doi:10.1016/j.patter.2025.101423 · Cited by 3
Augmenting Human Cognition Through Generative AI
Rogers, Y., Reicherts, L., Zhang, Z. T., & Hassib, M. (2026) · Springer eBooks · doi:10.1007/978-3-031-61050-9_10-1 · Cited by 1
Human-AI collaboration versus expert intuition: a head-to-head comparison in patient classification
Manca, M. L., Migliorini, P., & Boraschi, D. (2025) · The Innovation Medicine · doi:10.59717/j.xinn-med.2026.100182 · Cited by 1
When noise mitigates bias in human–algorithm decision-making: An agent-based model
Parsons, S. P., & Torenvlied, R. (2025) · PLoS ONE · doi:10.1371/journal.pone.0339273 · Cited by 1
Banh, L., Stangl, F. J., Strobel, G., & Riedl, R. (2025) · Lecture notes in information systems and organisation · doi:10.1007/978-3-032-00815-2_2 · Cited by 1
Measuring trust in artificial intelligence with the N2pc component
Wiese, E., & Feldmann‐Wüstefeld, T. (2026) · NeuroImage · doi:10.1016/j.neuroimage.2026.121720 · Cited by 1
The Generative AI Challenge to Highway QA Integrity
Copeland, M. (2026) · Transportation Research Record · doi:10.1177/03611981251411238 · Cited by 1
Hines, B. D., Talbert, D. A., & Anton, S. R. (2026) · International Journal of Artificial Intelligence Tools · doi:10.1142/s0218213026400026 · Cited by 1
Beyond Qualifications Frameworks: Large Language Models and the Future of Global Skills Recognition
Keevy, J., Bateman, A., Manoharan, H. E., Molokwane, P., Lastra, R., Mlotshwa, H. F., Paterson, A., Ramchurun, R., Ravaioli, S., Shiohira, K., et al. (2026) · European Journal of Open Distance and E-Learning · doi:10.65043/eurodl.162 · Cited by 3
Gindullina, D., Lazutov, M., Stolyarov, K., Danilenko, D., & Leonenko, V. N. (2026) · Expert Systems with Applications · doi:10.1016/j.eswa.2026.131730 · Cited by 1
CLARA: AI-Mediated Facilitation for Enhancing Group Cognition and Cohesion in Remote Collaboration
Gunasekaran, T. S., Doosti, M. S., Gupta, K., Bai, H., Pai, Y. S., & Billinghurst, M. (2026) · ACM Transactions on Computer-Human Interaction · doi:10.1145/3786325 · Cited by 4
Who listens to ChatGPT and when should they? A two-study examination of AI-assisted decision making
Grawitch, M. J., Winton, S. L., & Mudigonda, S. P. (2026) · Computers in Human Behavior Artificial Humans · doi:10.1016/j.chbah.2026.100283 · Cited by 3
Tang, H., Li, L., & Chen, L. (2026) · International Journal of Human-Computer Interaction · doi:10.1080/10447318.2026.2621990 · Cited by 2
The Beauty of Dismantling Everything: Team Processes as a Multimodal Puzzle
Lehmann‐Willenbrock, N. (2026) · Small Group Research · doi:10.1177/10464964261427799 · Cited by 1
Forero, D. A. (2026) · Current Genomics · doi:10.2174/0113892029403403260112075225 · Cited by 1
Smart simulations, safer systems: agentic AI and cybercrime in E-government
Mushtaq, S., & Önkal, D. (2026) · SIMULATION · doi:10.1177/00375497261429524 · Cited by 2
Metacognition of ChatGPT in confidence judgements
YOSHIZAWA, S., Onzo, A., Nozawa, S., Takano, T., Ishikawa, T., & Mogi, K. (2026) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2026.1694192 · Cited by 1
Zhong, S., & Xu, X. (2026) · Risk Analysis · doi:10.1111/risa.70249 · Cited by 1
Four Aspirations for Evaluating AI-Infused Technologies: A Narrative Review
Morey, D. A., Jalaeian, M., Reynolds, M. E., McGeorge, N., Oldham, H. K., & Rayo, M. F. (2026) · Journal of Cognitive Engineering and Decision Making · doi:10.1177/15553434261443032 · Cited by 1
Wang, Z.-H., Xu, X., & Zhao, C. (2026) · IEEE Transactions on Systems Man and Cybernetics Systems · doi:10.1109/tsmc.2026.3681214 · Cited by 2
Crowdsourced versus large language models forecasting: evidence for the accuracy–correlation effect
Jeddi, Y., Segovia‐Martín, J., & Servan-Schreiber, E. (2026) · Philosophical Transactions of the Royal Society B Biological Sciences · doi:10.1098/rstb.2024.0456 · Cited by 1
Wochele‐Thoma, T., Ijinu, T. P., Sasidharan, S. P., Manakkadan, A., Shine, L. S., Krishnakumar, N. M., Aruna, S. I., Pasupuleti, N., Aswany, T., Deepthi, D. C., et al. (2026) · Frontiers in Digital Health · doi:10.3389/fdgth.2026.1795488 · Cited by 1
Linking AI agent architectures to trust antecedents in human-autonomous teams: a scoping review
Zamecnik, A., Febriantoro, W., Cukurova, M., Joksimovíc, S., Großmann, G., & Siemens, G. (2026) · Artificial Intelligence Review · doi:10.1007/s10462-026-11572-z · Cited by 5
Seitchik, A. E., & Hardway, C. L. (2026) · Discover Education · doi:10.1007/s44217-026-01548-0 · Cited by 1
AI-Enhanced Science Literacy: Science Literacy Plus
Liu, X., & Tripp, J. N. (2026) · Springer eBooks · doi:10.1007/978-3-032-16871-9_4 · Cited by 1
Integrating artificial intelligence tools in health research
Postill, G., Sedláková, J., Tancredi, S., Smit, F., Ekongefeyin, S. N. N., Baumer, A. M., Chioléro, A., Bernard, J., Rosella, L. C., & von Wyl, V. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02739-7 · Cited by 1
Lutz, C., Newlands, G., & Jarrahi, M. H. (2026) · Springer eBooks · doi:10.1007/978-981-95-3658-0_87 · Cited by 1
Artificial intelligence exposure and labor market transformations in Latin America
Egana-delSol, P. A., & Bravo‐Ortega, C. (2026) · Technological Forecasting and Social Change · doi:10.1016/j.techfore.2026.124758 · Cited by 6
AI Could Undermine Qualitative Research. Luckily, We Have a Plan
Matta, C., Nordmark, S., & Masiello, I. (2026) · International Journal of Qualitative Methods · doi:10.1177/16094069261456950 · Cited by 1
Configuring human and AI investments: Synergy and its impact on operational efficiency
Xu, J., Zhang, B., & Lu, J. (2026) · Decision Support Systems · doi:10.1016/j.dss.2026.114702 · Cited by 1
Papale, A., Lopiano, G., Campagner, A., & Cabitza, F. (2026) · Technologies · doi:10.3390/technologies14060366 · Cited by 2
Knowledge Co‐Creation by Human–Machine Social Interaction: Based on Decision Field Theory
Ren, Z., Shen, X., & Xia, S. (2026) · Systems Research and Behavioral Science · doi:10.1002/sres.70103 · Cited by 2
For Factors of AI Integration in Research: Case Study of Russian Laboratories
Sazonov, A., Popova, E. V., & Matsepuro, D. M. (2026) · Высшее образование в России · doi:10.31992/0869-3617-2026-35-6-149-168 · Cited by 1
From Individual Prompts to Collective Intelligence: Mainstreaming Generative AI in the Classroom
Qadir, J., & Khan, M. S. (2026) · IEEE Global Engineering Education Conference (EDUCON) · doi:10.1109/educon67543.2026.11574210 · Cited by 1
Operationalizing and Optimizing Human–Agent Teaming for Knowledge Work
Kane, A. A., Diep, M. M., Porter, A., & Paletz, S. B. F. (2026) · Emerald Group Publishing Limited eBooks · doi:10.1108/s1534-085620260000021018 · Cited by 2
Drobniak, S. M., Cendrowska-Pek, M., Gudowska, A., Janas, K., Podkowa, P., Skorb, K., Gronowska, M., Oleś, W., Bikmurzina, F., Boroń, N., et al. (2026) · Research Integrity and Peer Review · doi:10.1186/s41073-026-00230-1 · Cited by 4
Srinivas, R., & Chetan, S. S. (2026) · Group Decision and Negotiation · doi:10.1007/s10726-026-10016-x · Cited by 5
The norm architects: How AI delegation norms form before anyone designs them
Shabad, V. (2026) · Organizational Dynamics · doi:10.1016/j.orgdyn.2026.101258 · Cited by 2
Metricized Scaffolds: AI-Enabled Simulation Training and Transfer in Human Resource Development
Xie, N., Liu, Y., Wang, Y., & Wang, Y. (2026) · Administrative Sciences · doi:10.3390/admsci16080372 · Cited by 1
Subramanya, S., Krishnan, S., & Azad, N. (2026) · Information Systems Frontiers · doi:10.1007/s10796-026-10804-5 · Cited by 2
From the First Public ChatGPT to Astra in Scientific Collaboration
Shapovalov, V. (2026) · Conceptual Future · doi:10.53933/c75rcf79 · Cited by 2
Human learning is an understudied but promising lever for boosting human–AI synergy
Berger, J., Burton, J. W., Hertwig, R., Kosch, T., Kurvers, R. H. J. M., Kurzenberger, B., Lazik, C. K., Onnasch, L., Rieger, T., Thoma, A. I., et al. (2026) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2536100123 · Cited by 7
Le, H., Choube, A., Mishra, V., & Intille, S. S. (2026) · Proceedings of the ACM on Interactive Mobile Wearable and Ubiquitous Technologies · doi:10.1145/3831653 · Cited by 3
Augmentation or Erosion? Regulating Cognitive Offloading in Generative AI-Supported STEM Learning
Nakamura, D. (2026) · Educational Psychology Review · doi:10.1007/s10648-026-10224-6 · Cited by 3
Lane, J. N., Boussioux, L., Ayoubi, C., Chen, Y. H., Lin, C., Spens, R., Wagh, P., & Wang, P.-H. (2024) · SSRN Electronic Journal · doi:10.2139/ssrn.4914367 · Cited by 2
León-Domínguez, U., Flores-Flores, E. D., García-Jasso, A. J., Gómez-Cuéllar, M. K., Torres-Sanchez, D., & Marimon, B. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5227056 · Cited by 1
Prosenz, J., Bernhofer, S., Duller, C., Venturi, D., & Maieron, A. (2025) · The American Journal of Gastroenterology · doi:10.14309/ajg.0000000000003648 · Cited by 1
Buechsenschuss, R., Koch‐Bayram, I., Biemann, T., & Puranam, P. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.6028034 · Cited by 1
Liang, H., Zhang, D., An, X., & Xu, J. (2026) · Research Square · doi:10.21203/rs.3.rs-8774138/v1 · Cited by 1
Rawshan, L. B., Wang, Z., & Lim, B. Y. (2026) · ACM International Conference on Intelligent User Interfaces (IUI) · doi:10.1145/3742413.3789147
Integrating Complementary Feature Sets for Human-AI Decision-Making
Lage, I., & Wintersteen, B. (2026) · ACM International Conference on Intelligent User Interfaces (IUI) · doi:10.1145/3742413.3789096
Takahashi, K. (2026) · Zenodo (CERN European Organization for Nuclear Research) · doi:10.5281/zenodo.18973272 · Cited by 1
Kleinman, E., Kim, S., Kim, S., Lee, H., Kim, J., Kang, D., Park, S., Harteveld, C., & Lee, B. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3791065
Zhang, Z., Yi, X., Dai, Z., Yu, X., Zhang, S., Liu, B., Cao, J., & Zhao, H. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3791926 · Cited by 2
Gautam, K., Bhatia, P., & Chilana, P. K. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3791124
Improving Abductive ReasoningPreprint
He, V. F., & Puranam, P. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.6594299 · Cited by 1
Sadigzade, Z. (2026) · Acta Globalis Humanitatis et Linguarum · doi:10.69760/aghel.026001005 · Cited by 1
A metacognitive approach to learning and performance in human-AI interaction
Fan, Y., Yan, L., Molenaar, I., Greiff, S., & Gašević, D. (2026) · Communications Psychology · doi:10.1038/s44271-026-00548-y · Cited by 1
Alcaraz, J. M. L., Moran, X. L., Zaragoza, E. D., Händel, C., Koebe, R., Haverkamp, W., & Strodthoff, N. (2026) · arXiv · doi:10.48550/arxiv.2601.06645
“If substantiated in larger user studies this would be an example of the most desirable augmentation scenario, where the augmented clinicians’ performance exceeds the model performance [22].”
Jaffar, Z. F., Alvi, A., Rahim, A., Ambreen, S., & Jaffar, M. M. (2026) · Journal of Language, Literature & Social Affairs · doi:10.63056/jllsa.2.5.2026.253
“(Wang & Fan, 2025) While Gen-AI as an MKO can improve learning process, whereas over-reliance on these tools leads to logical complacency and selective cognitive atrophy (Vaccaro, , Almaatouq, & Malone, 2024).”
Qarkaxhija, J. (2026) · doi:10.31235/osf.io/m75hn_v1
“A meta-analysis of human-AI collaboration shows that combinations sometimes underperform either party in isolation [8], and benchmarks of end-to-end issue resolution show that agents remain well short of human rates on real repositories [9].”
InfluentialBeyond Human-Likeness: Mapping the Scientific Critique Profiles of LLMs and Human Reviewers
Yang, Y., Thelwall, M., & He, G. (2026) · arXiv · doi:10.48550/arxiv.2609.01895
“…knowledge spaces, where progress depends on connecting dispersed ideas, methods, and evidence (Bianchini et al., 2026), and with human-AI collaboration research showing that complementarity depends on matching task structure to the distinctive contributions of each side (Vaccaro et al., 2024).”
Gu, H., Schreyer, M., Moffitt, K. C., & Vasarhelyi, M. A. (2024) · SSRN Electronic Journal · doi:10.2139/ssrn.4881256 · Cited by 3
Designing Human-Automation Redundancy: Overreliance, Automation Shirking, and the Operator’s Dilemma
Cohen, D., Roth, Y., Rieskamp, J., & Schöbel, M. (2025) · doi:10.2139/ssrn.5098488
Krause, T. A. (2025) · dms – der moderne staat – Zeitschrift für Public Policy Recht und Management · doi:10.3224/dms.vxix.403989
Human AI Collaboration for Trust Management
Akiyoshi, M. (2025) · Proceedings of the AAAI Symposium Series · doi:10.1609/aaaiss.v5i1.35551
Vicente, L., & Cabitza, F. (2025) · Lecture notes in computer science · doi:10.1007/978-3-031-93838-2_5 · Cited by 1
Philosophy of the Machines - A Manifesto for Humans in the Age of Artificial AgentsPreprint
Immediato, G. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5295231
The Role of Artificial Intelligence in Backing Up Human Insight: A Powerful Partnership
Kim, H., & Lee, H. S. (2025) · MechEcology · doi:10.23104/me.e7
Human–Robot Collaboration in Surgery at The Nexus of Knowledge, Agency, and OwnershipPreprint
Merdin‐Uygur, E., Öztürkcan, S., Özbilgin, M. F., et al. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5336774
Working with AI: An analysis for rational integration
Lagziel, D., & Tsodikovich, Y. (2025) · Games and Economic Behavior · doi:10.1016/j.geb.2025.06.009
Yang, D., Zhang, Y., Hoel, T., & Yuan, L. Y. (2025) · Communications in computer and information science · doi:10.1007/978-3-031-99261-2_23
The Impact of Artificial Intelligence on Virtual Teams
Gündoğan, A., & Runco, M. A. (2025) · IGI Global eBooks · doi:10.4018/979-8-3373-6102-4.ch001
Understanding the Role of Computer‐Aided Diagnosis in Colonoscopy
Halvorsen, N., & Mori, Y. (2025) · Digestive Endoscopy · doi:10.1111/den.70007
AI-based research mentors: Plausible scenarios and ethical issues
Crean, D., Wieczorek, M., Gordijn, B., & Kearns, A. J. (2025) · Accountability in Research · doi:10.1080/08989621.2025.2551890
Yang, Y., Fan, L., Wang, T., & Yan, R. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5472396
Dilemma between bias interaction and trustworthy AI in human–AI collaborated judgments
Shirasuna, M., Honda, H., & Kagawa, R. (2026) · Computers in Human Behavior Artificial Humans · doi:10.1016/j.chbah.2026.100314
Cabitza, F., Fregosi, C., & Vicente, L. (2025) · Communications in computer and information science · doi:10.1007/978-3-032-08317-3_11
HUMAN-AI COLLABORATION IN SCIENCE EDUCATION: CHALLENGES AND STEPS FORWARD
Yang, D. (2025) · Journal of Baltic Science Education · doi:10.33225/jbse/25.24.800
Chen, Q., & Zhang, X.-A. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5626645
Vocabulary at the Living–Machine Interface: A Narrative Review of Shared Lexicon for Hybrid AI
Prahl, A., & Li, Y. (2025) · Biomimetics · doi:10.3390/biomimetics10110723
A New Paradigm of Business Computing Driven by Domain-specific Foundation Models
Yang, S., Jin, J., & Pan, Y. (2025) · 中国科学基金 · doi:10.3724/bnsfc-2025.06.12.0004
Human–AI Interaction for Visualization and Visual Analytics
Zeng, W., Fu, H., Zhao, N., et al. (2025) · IEEE Computer Graphics and Applications · doi:10.1109/mcg.2025.3606311
MAGIX: A Unified Framework for the Use of XAI in Enterprises
Sovrano, F., & Miller, T. (2025) · Springer eBooks · doi:10.1007/978-3-032-01940-0_6 · Cited by 1
Editorial: Reimagining roles and identity in the era of human - AI collaboration
Chen, X., Wen, I., Qu, Q., et al. (2025) · Frontiers in Psychology · doi:10.3389/fpsyg.2025.1736730
Learning to Prompt: Human Adaptation in Production with Generative AIPreprint
Lin, S. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5788402
Augmented human intelligence goes beyond the AGI mirage
Lissack, M. R., & Meagher, B. (2025) · Discover Artificial Intelligence · doi:10.1007/s44163-025-00683-1 · Cited by 1
MICA: Trust-Driven Design Refinements for Camouflaged Object Detection Applications
Hogue, D., Elliott, D. S., Schley, L., et al. (2025) · doi:10.1109/dasc66011.2025.11257236
Ferehat, F. Z., & Eddakir, A. (2025) · International Symposium on Multidisciplinary Studies and Innovative Technologies (ISMSIT) · doi:10.1109/ismsit67332.2025.11268130
Individual bounded rationality destabilizes cooperative dynamics in human–AI groupsPreprint
Tsutsui, K., Mizuguchi, N., Goto, Y., Onagawa, R., Kano, F., Kudo, K., Isaka, T., & Fujii, K. (2025) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.64898/2025.11.30.691459
Li, Z., Sun, B., Li, X., et al. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5648735
Human-Centered and Contextual Assessment of Human-AI Decision-Making Interventions
Nasr, S., & Johnson, D. S. (2025) · Contextualizing Explanations · doi:10.64136/mznt1005
A Framework for Context-aware XAI in Human-AI Collaboration
Knoblach, J., Finzel, B., & Schmid, U. (2025) · doi:10.64136/deef2831
Human-AI Proximity: Unveiling the Detrimental Effects on Idea Selection and ImplementationPreprint
Mascareño, J., Wortler, B., Przegalinska, A., & Ciechanowskie, L. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5885745
Human-AI Proximity: Unveiling the Detrimental Effects on Idea Selection and ImplementationPreprint
Mascareño, J., Wortler, B., Przegalinska, A., & Ciechanowskie, L. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5885744
Human-AI Proximity: Unveiling the Detrimental Effects on Idea Selection and ImplementationPreprint
Mascareño, J., Wortler, B., Przegalinska, A., & Ciechanowskie, L. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5893131
Automatisierte Workflows im Wissensmanagement
Offergelt, F., Hofreiter, S., & Steiner, T. (2025) · Essentials · doi:10.1007/978-3-662-72565-8_5
Metadata
- Authors
- Vaccaro, M., Almaatouq, A., & Malone, T.
- Affiliations
- Massachusetts Institute of Technology (US)
- Venue
- Nature Human Behaviour
- Published
- 2024-10-28
- Volume
- 8
- Issue
- 12
- Pages
- 2293-2303
- ISSN
- 2397-3374 (ISSN-L)
- PMC
- PMC11659167
- OpenAlex
- W4403839497
- Semantic Scholar
- 02aec976011a7d595d61db9639209968f4b93177
- Cited by
- 570
- References
- 95
- Citations by year
- 2026: 404 · 2025: 156 · 2024: 9
- FWCI
- 51.29
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Locations
- Nature Human Behaviour (publishedVersion, cc-by)
- Research Square (acceptedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by)
- PubMed Central (submittedVersion, cc-by)
- RePEc: Research Papers in Economics (submittedVersion)
- arXiv (Cornell University) (cc-by)
- Funders
- Accenture Technology Convergence Fellowship
- Toyota Research Institute; MIT Quest for Intelligence; National Research Foundation, Prime Minister's Office, Singapore
- Topics
- Social Sciences › Human Factors and Ergonomics › Human-Automation Interaction and Safety
- Social Sciences › Psychology › Social Psychology › Social Robot Interaction and HRI
- Physical Sciences › Computer Science › Artificial Intelligence › Artificial Intelligence Applications
- Keywords
- human-AI collaboration, human-AI comparison, decision-making, content creation, performance outcomes, AI augmentation, task type effects, human-AI systems
- MeSH terms
- Artificial Intelligence, Decision Making, Humans
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-20, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-20 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
