

The DOI matches its Crossref record; 57 of the 60 references it cites were found in a registry or an index; 14 of the 21 sources its claims cite were checked for support.
Detecting hallucinations in large language models using semantic entropy
Open accessAbstract
Abstract Large language model (LLM) systems, such as ChatGPT 1 or Gemini 2 , can show impressive reasoning and question-answering capabilities but often ‘hallucinate’ false outputs and unsubstantiated answers 3,4 . Answering unreliably or without the necessary information prevents adoption in diverse fields, with problems including fabrication of legal precedents 5 or untrue facts in news articles 6 and even posing a risk to human life in medical domains such as radiology 7 . Encouraging truthfulness through supervision or reinforcement has been only partially successful 8 . Researchers need a general method for detecting hallucinations in LLMs that works even with new and unseen questions to which humans might not know the answer. Here we develop new methods grounded in statistics, proposing entropy-based uncertainty estimators for LLMs to detect a subset of hallucinations—confabulations—which are arbitrary and incorrect generations. Our method addresses the fact that one idea can be expressed in many ways by computing uncertainty at the level of meaning rather than specific sequences of words. Our method works across datasets and tasks without a priori knowledge of the task, requires no task-specific data and robustly generalizes to new tasks not seen before. By detecting when a prompt is likely to produce a confabulation, our method helps users understand when they must take extra care with LLMs and opens up new possibilities for using LLMs that are otherwise prevented by their unreliability.
Overview
CoChat Summary
TL;DR
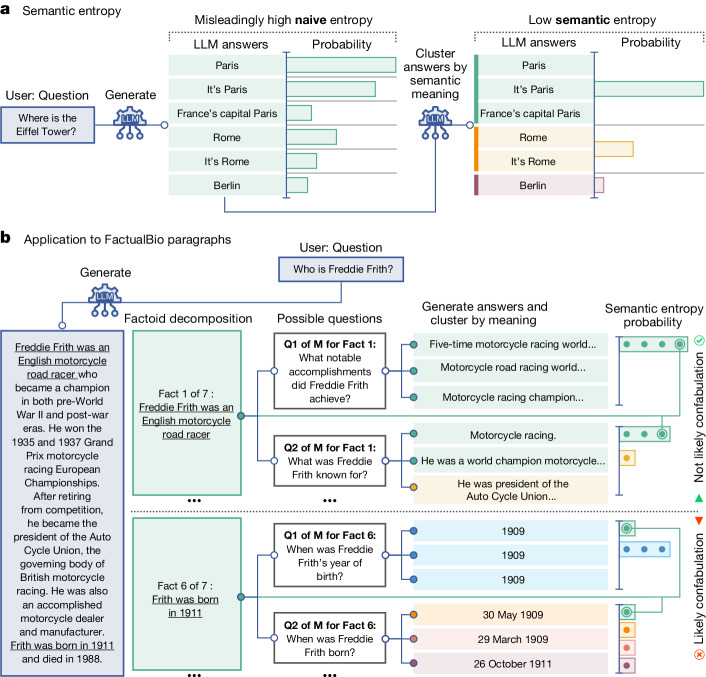
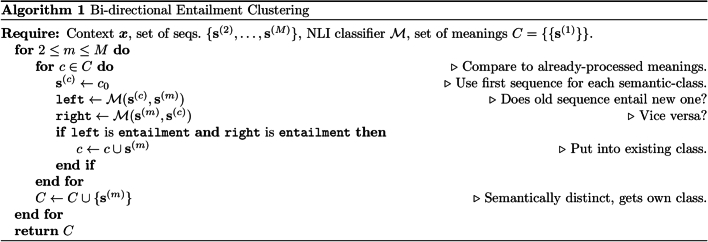
The paper introduces semantic entropy, an uncertainty estimator that clusters LLM generations by meaning via bidirectional entailment and computes entropy over those semantic clusters to detect confabulations. Across question-answering, math, and biography-generation tasks, semantic entropy outperforms naive entropy and supervised baselines without task-specific training data.
Key findings
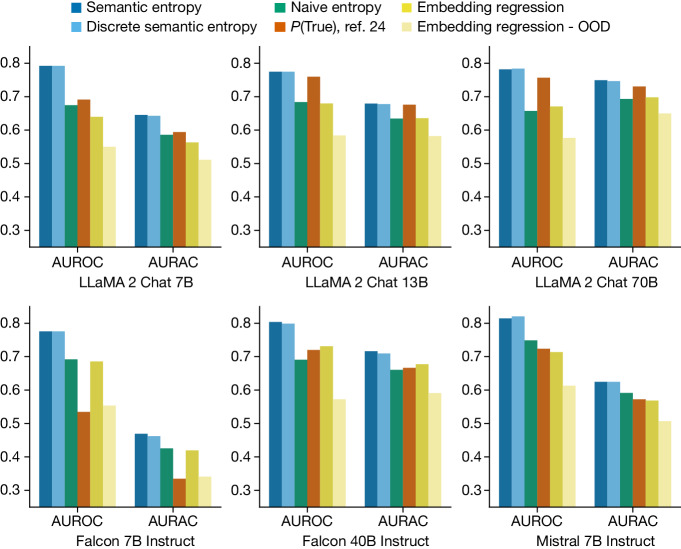
- Averaged across 30 task–model combinations, semantic entropy achieved the best AUROC of 0.790, compared with naive entropy (0.691), P(True) (0.698), and embedding regression (0.687); performance was stable between 0.78 and 0.81 across LLaMA, Falcon, and Mistral model families and scales from 7B to 70B parameters.
- Semantic entropy detects confabulations in sentence-length QA and math across TriviaQA, SQuAD 1.1, BioASQ, NQ-Open, and SVAMP, and its discrete variant performs similarly without requiring exact output probabilities.
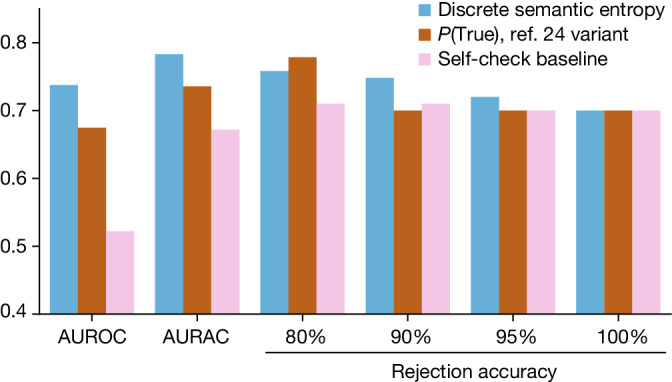
- On the GPT-4 biography dataset FactualBio—21 individuals, 150 factual claims, of which 45 were incorrect—the discrete semantic entropy variant outperformed a self-check baseline and an adapted P(True) baseline on AUROC and AURAC; P(True) had a narrow edge only after the top 20% of answers judged most likely to be confabulations were rejected.
- The method targets confabulations—arbitrary and incorrect generations sensitive to irrelevant details such as random seed—rather than all hallucinations, and it does not address systematically bad outputs.
Methods
- For each question, the method samples multiple generations from the LLM, clusters them by semantic equivalence using bidirectional entailment, and estimates semantic entropy over the meaning clusters; a discrete variant approximates cluster probabilities from generation frequencies when token probabilities are unavailable.
- Sentence-length experiments used LLaMA 2 Chat (7B, 13B, 70B), Falcon Instruct (7B, 40B), and Mistral Instruct (7B) on BioASQ, SQuAD 1.1, TriviaQA, SVAMP, and NQ-Open, with 400 train and 400 test examples per dataset; GPT-4 (v.0613) was used for FactualBio.
- Evaluation metrics were AUROC, rejection accuracy, and AURAC; sentence-length correctness was assessed automatically with GPT-4 against reference answers, validated against human judgement in the Supplementary Information.
Limitations
- The paper states that semantic entropy does not guarantee factuality and does not help when LLM outputs are systematically bad, including confident errors from training objectives, systematic reasoning failures, or misleading behaviour.
- The paper notes that semantic clustering can be overly sensitive to context: in one example, it distinguished a precise date from a year and treated the model as uncertain, even though the distinction was probably irrelevant in context.
- For FactualBio, the paper states that automatically generated questions are the main source of errors, and that GPT-4 did not expose output probabilities at the time, preventing computation of naive entropy, standard semantic entropy, and the embedding regression baseline for GPT-4.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
8 Valid · 6 Not valid · 5 Not checked · 60 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Large language model (LLM) systems, such as ChatGPT1 or Gemini2, can show impressive reasoning and question-answering capabilities but often ‘hallucinate’ false outputs and unsubstantiated answers3,4.”
§ Detecting hallucinations in large language models using semantic entropy > Abstract
What the sources say
- Partly supportedcites [3] Xiao, Y. & Wang, W. Y. On hallucination and predictive uncertainty in conditional language generation. In Proc. 16th Conference of the European Chapter of the Association for Computational Linguistics 2734–2744 (Association for Computational Linguistics, 2021). sourceExperimental — accuracy not yet measured
The Introduction (p. 1) says neural generation models can produce content unsupported by their inputs, and §2.1 (p. 2) defines hallucination as false information unsupported by the input. The paper studies conditional generation, including image captioning and data-to-text, rather than establishing how often LLM systems such as ChatGPT or Gemini give unsubstantiated answers. (LLM, conf=0.84)
- Partly supportedcites [4] Rohrbach, A., Hendricks, L. A., Burns, K., Darrell, T. & Saenko, K. Object hallucination in image captioning. In Proc. 2018 Conference on Empirical Methods in Natural Language Processing (eds Riloff, E., Chiang, D., Hockenmaier, J. & Tsujii, J.) 4035–4045 (Association for Computational Linguistics, 2018). sourceExperimental — accuracy not yet measured
The Introduction describes image-captioning models generating objects absent from an image, and Section 3.2 reports hallucinated objects in 7.4%–17.7% of tested captions. This supports the general point that generated outputs can be false, but the paper does not establish how often LLM systems such as ChatGPT or Gemini produce unsubstantiated answers. Page numbers were not available in our copy. (LLM, conf=0.86)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“High entropy corresponds to high uncertainty23–25—so semantic entropy is one way to estimate semantic uncertainties.”
§ Detecting hallucinations in large language models using semantic entropy > Main
What the sources say
- Not checked — no full text of the sourcecites [23] MacKay, D. J. C. Information-based objective functions for active data selection. Neural Comput. 4, 590–604 (1992). source
- Partly supportedcites [24] Kadavath, S. et al. Language models (mostly) know what they know. Preprint at https://arxiv.org/abs/2207.05221 (2022). sourceExperimental — accuracy not yet measured
Section B.2 (p. 29) hypothesizes that an unsure model produces a high-entropy answer distribution, and reports that entropy has some predictive power. But it also finds that larger models can give diverse correct answers and concludes that answer-distribution entropy is not a robust measure of whether a model knows the answer. The unqualified correspondence in the claim overstates the paper's finding. (LLM, conf=0.87)
- Supportedcites [25] Lindley, D. V. On a measure of the information provided by an experiment. Ann. Math. Stat. 27, 986–1005 (1956). source
The discussion on p. 4 explains that the measure uses Shannon’s function with the sign reversed: information is greatest when the distribution is concentrated on one value and falls as it spreads. This supports the cited background point that higher Shannon entropy corresponds to greater uncertainty; the later claim about semantic entropy is not attributed to this source. (LLM, conf=0.88)
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper states — it cites no source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Nevertheless, we significantly improve question-answering accuracy for state-of-the-art LLMs, revealing that confabulations are a great source of error at present.”
§ Detecting hallucinations in large language models using semantic entropy > Main
boostedstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We further show that semantic uncertainty can be used to improve model accuracy by refusing to answer questions when semantic uncertainty is high.”
§ Detecting hallucinations in large language models using semantic entropy > Methods > Detecting confabulations in QA and math
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In our experiments, we use semantic uncertainty to predict model accuracy, demonstrating that confabulations make up a notable fraction of model mistakes.”
§ Detecting hallucinations in large language models using semantic entropy > Methods > Detecting confabulations in QA and math
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
36 more claims
Create a free account to see all 79 claims and every source verdict.
- Probably not a substantial claim. 30
- It may state two separate claims as one. 20
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“However, LLMs exhibit hallucination and fabrication errors that are unacceptable for quantitative modeling [19, 20, 21].”
From Structured Schemas for Provenance‐Rich, LLM ‐Assisted QSP Model Calibration (2026) · cites this paper as [19]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Studies on hallucination, calibration, sycophancy, and cognitive bias indicate that failures often result not from a lack of capability but from unstable behavioral dispositions under uncertainty or pressure [8, 9, 10, 12, 15].”
From Machine Psychometrics: A Mathematical Psychology of Artificial Intelligence (2026) · cites this paper as [8]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“AI-generated patient summaries also frequently contain errors that can be hard to detect12.”
From Multi-model assurance analysis showing large language models are highly vulnerable to adversarial hallucination attacks during clinical decision support (2025) · cites this paper as [12]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“LLMs remain limited by the static knowledge encoded in their parameters.They are prone to hallucinations, factual inaccuracies, and out-of-date internal knowledge (Farquhar et al., 2024;Lewis et al., 2020).”
From Improving Amharic Information Retrieval with Translative and Multi-Agent Debate Retrieval Augmented Generation (2026) · cites this paper as Farquhar et al., 2024
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“This limitation can result in responses that lack coherence, contextual relevance, and even lead to hallucinations in extended dialogues or complex tasks [1], [2].”
From Memory-Augmented Architecture for Long-Term Context Handling in Large Language Models (2026) · cites this paper as [1]
Experimental — accuracy not yet measured
11 more claims about this paper
Create a free account to see every claim other papers make about this one.
Citations
Cites
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
SQuAD: 100,000+ Questions for Machine Comprehension of Text
Rajpurkar, P., Zhang, J., Lopyrev, K., & Liang, P. (2016) · Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d16-1264 · Cited by 6,208
Survey of Hallucination in Natural Language Generation
Ji, Z., Lee, N., Frieske, R., Yu, T., Su, D., Xu, Y., Ishii, E., Bang, Y. J., Madotto, A., & Fung, P. (2023) · ACM Computing Surveys · doi:10.1145/3571730 · Cited by 5,025 · cited 2×
“Hallucinations are often defined as LLMs generating “content that is nonsensical or unfaithful to the provided source content” 9–11 but they have come to include a vast array of failures of faithfulness and factuality.”
A Broad-Coverage Challenge Corpus for Sentence Understanding through Inference
Williams, A., Nangia, N., & Bowman, S. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1101 · Cited by 3,342 · cited 2×
“We rely on language models to predict entailment, such as DeBERTa-Large-MNLI 56 , which has been trained to predict entailment, or general-purpose LLMs such as GPT-3.”
Llama 2: Open Foundation and Fine-Tuned Chat Models
Touvron, H., Martin, L., Stone, K., Albert, P., Almahairi, A., Babaei, Y., Bashlykov, N., Batra, S., Bhargava, P., Bhosale, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2307.09288 · Cited by 2,604 · cited 1×
“Our results for TriviaQA, SQuAD, BioASQ, NQ-Open and SVAMP are all evaluated context-free and involve sentence-length answers (96 ± 70 characters, mean ± s.d.) and use LLaMA 2 Chat (7B, 13B and 70B parameters) 38 , Falcon Instruct (7B and 40B) 39 and Mistral Instruct (7B) 40 .”
Aleatory or epistemic? Does it matter?
Kiureghian, A. D., & Ditlevsen, O. (2009) · Structural Safety · doi:10.1016/j.strusafe.2008.06.020 · Cited by 2,454 · cited 1×
“Researchers some-times separate aleatoric uncertainty (uncertainty in the underlying data distribution) from epistemic uncertainty (caused by having only limited information) 46 .”
Natural Questions: A benchmark for question answering research
Kwiatkowski, T., Palomaki, J., Redfield, O., Collins, M., Parikh, A., Alberti, C., Epstein, D., Polosukhin, I., Devlin, J., Lee, K., et al. (2019) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00276 · Cited by 2,069 · cited 2×
“33), life sciences (BioASQ 34 ) and open-domain natural questions (NQ-Open 35 ) derived from actual queries to Google Search 36 .”
TriviaQA: A Large Scale Distantly Supervised Challenge Dataset for Reading Comprehension
Joshi, M., Choi, E., Weld, D., & Zettlemoyer, L. (2017) · Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p17-1147 · Cited by 1,690 · cited 5×
“TriviaQA is a trivia question-answering dataset.”
InfluentialTriviaQA: A Large Scale Distantly Supervised Challenge Dataset for Reading Comprehension
Joshi, M., Choi, E., Weld, D. S., & Zettlemoyer, L. (2017) · arXiv · doi:10.48550/arxiv.1705.03551 · Cited by 1,650
On a measure of the information provided by an experiment
Lindley, D. V. (1956) · The Annals of Mathematical Statistics · doi:10.1214/aoms/1177728069 · Cited by 1,509 · cited 2×
“High entropy corresponds to high uncertainty 23–25 —so semantic entropy is one way to estimate semantic uncertainties.”
Research works printed but not linked: 8
- Xiao, T. Z., Gomez, A. N. & Gal, Y. Wat zei je? Detecting out-of-distribution translations with variational transformers. In Workshop on Bayesian Deep Learning at the Conference on Neural Information Processing Systems (NeurIPS, Vancouver, 2019).
- Negri, M., Bentivogli, L., Mehdad, Y., Giampiccolo, D. & Marchetti, A. Divide and conquer: crowdsourcing the creation of cross-lingual textual entailment corpora. In Proc. 2011 Conference on Empirical Methods in Natural Language Processing 670–679 (Association for Computational Linguistics, 2011).
- Malinin, A. & Gales, M. Uncertainty estimation in autoregressive structured prediction. In Proceedings of the International Conference on Learning Representations https://openreview.net/forum?id=jN5y-zb5Q7m (2021).
- Holtzman, A., Buys, J., Du, L., Forbes, M. & Choi, Y. The curious case of neural text degeneration. In Proceedings of the International Conference on Learning Representations https://openreview.net/forum?id=rygGQyrFvH (2020).
- Culicover, P. W. Paraphrase generation and information retrieval from stored text. Mech. Transl. Comput. Linguist. 11, 78–88 (1968).
- He, P., Liu, X., Gao, J. & Chen, W. Deberta: decoding-enhanced BERT with disentangled attention. In International Conference on Learning Representations https://openreview.net/forum?id=XPZIaotutsD (2021).
- Socher, R., Huang, E., Pennin, J., Manning, C. D. & Ng, A. Dynamic pooling and unfolding recursive autoencoders for paraphrase detection. In Proceedings of the 24th Conference on Neural Information Processing Systems (eds Shawe-Taylor, J. et al.) (2011)
- Kane, H., Kocyigit, Y., Abdalla, A., Ajanoh, P. & Coulibali, M. Towards neural similarity evaluators. In Workshop on Document Intelligence at the 32nd conference on Neural Information Processing (2019).
Cited by
A framework to assess clinical safety and hallucination rates of LLMs for medical text summarisation
Asgari, E., Montaña-Brown, N., Dubois, M., Khalil, S., Balloch, J., Yeung, J. A., & Pimenta, D. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01670-7 · Cited by 423
What large language models know and what people think they know
Steyvers, M., Tejeda, H., Kumar, A., Belem, C., Karny, S., Hu, X., Mayer, L. W., & Smyth, P. (2025) · Nature Machine Intelligence · doi:10.1038/s42256-024-00976-7 · Cited by 209
“13,17).”
InfluentialMedical large language models are vulnerable to data-poisoning attacks
Alber, D. A., Yang, Z., Alyakin, A., Yang, E., Rai, S., Valliani, A. A., Zhang, J., Rosenbaum, G. R., Amend-Thomas, A. K., Kurland, D. B., et al. (2025) · Nature Medicine · doi:10.1038/s41591-024-03445-1 · Cited by 242
“There exist many approaches to detecting misinformation generated by LLMs 60 .”
The clinicians’ guide to large language models: a general perspective with a focus on hallucinations
Roustan, D., & Bastardot, F. (2025) · Interactive Journal of Medical Research · doi:10.2196/59823 · Cited by 191
“Measurement of semantic entropy [22], algorithmic approaches to address root causes of hallucinations [23], and more classical methods such as Retrieval-Augmented Generation [24] are some of the many techniques that have been proposed to identify and reduce hallucinations.”
Omar, M., Sorin, V., Collins, J. D., Reich, D., Freeman, R., Gavin, N., Charney, A., Stump, L., Bragazzi, N. L., Nadkarni, G. N., et al. (2025) · Communications Medicine · doi:10.1038/s43856-025-01021-3 · Cited by 204
Metadata
- Authors
- Farquhar, S., Kossen, J., Kuhn, L., & Gal, Y.
- Affiliations
- University of Oxford (GB)
- Corresponding author
- Farquhar, Sebastian
- Venue
- Nature
- Published
- 2024-06-19
- Volume
- 630
- Issue
- 8017
- Pages
- 625-630
- ISSN
- 0028-0836 (ISSN-L)
- 1476-4687
- PMC
- PMC11186750
- OpenAlex
- W4399803256
- Semantic Scholar
- f82f49c20c6acc69f884f05e3a9f1ceea91061ce
- Cited by
- 934
- References
- 60
- Citations by year
- 2026: 540 · 2025: 349 · 2024: 44
- FWCI
- 137.11
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- creativecommons.org/licenses/by/4.0 (tdm)
- creativecommons.org/licenses/by/4.0 (vor)
- Locations
- Nature (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- RePEc: Research Papers in Economics (submittedVersion)
- Funders
- Government of the United Kingdom
- UK Research and Innovation
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Adversarial Robustness in Machine Learning
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- hallucination detection, large language models, semantic entropy, uncertainty estimation, confabulation, LLM reliability, generalization to unseen tasks, honesty
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Detecting hallucinations in large language models using semantic entropy. https://app.cochat.ai/papers/10.1038/s41586-024-07421-0
- The paper
- Farquhar, S., Kossen, J., Kuhn, L., & Gal, Y. (2024). Detecting hallucinations in large language models using semantic entropy. Nature. https://doi.org/10.1038/s41586-024-07421-0
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
