

The DOI matches its DataCite record; 47 of the 47 references it cites were found in a registry or an index; 7 of the 13 sources its claims cite were checked for support.
Humanity's Last Exam
Open accessPublished version of a preprint
Abstract
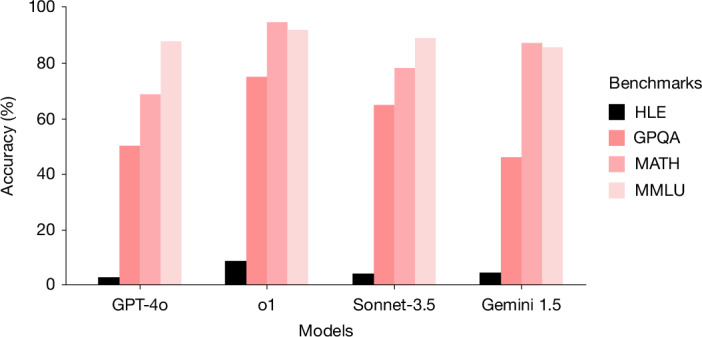
Benchmarks are important tools for tracking the rapid advancements in large language model (LLM) capabilities. However, benchmarks are not keeping pace in difficulty: LLMs now achieve over 90\% accuracy on popular benchmarks like MMLU, limiting informed measurement of state-of-the-art LLM capabilities. In response, we introduce Humanity's Last Exam (HLE), a multi-modal benchmark at the frontier of human knowledge, designed to be the final closed-ended academic benchmark of its kind with broad subject coverage. HLE consists of 2,500 questions across dozens of subjects, including mathematics, humanities, and the natural sciences. HLE is developed globally by subject-matter experts and consists of multiple-choice and short-answer questions suitable for automated grading. Each question has a known solution that is unambiguous and easily verifiable, but cannot be quickly answered via internet retrieval. State-of-the-art LLMs demonstrate low accuracy and calibration on HLE, highlighting a significant gap between current LLM capabilities and the expert human frontier on closed-ended academic questions. To inform research and policymaking upon a clear understanding of model capabilities, we publicly release HLE at https://lastexam.ai.
Overview
Integrity signals
Registry
Cites
Statistics
Figures


Verification
Claims the paper makes
2 Valid · 5 Not valid · 0 Not checked · 33 Own results and interpretations
Some cited sources support this claim and some don’t — read each source’s verdict below.
In the paper
“LLMs now achieve more than 90% accuracy on popular benchmarks such as Measuring Massive Multitask Language Understanding1”
- Also stated in: another passage · plain
“state-of-the-art LLMs2–6 now achieve more than 90% accuracy on popular benchmarks such as Measuring Massive Multitask Language Understanding (MMLU)1”
§ A benchmark of expert-level academic questions to assess AI capabilities > Abstract
What the sources say
- Not matchedcites [1] Hendrycks, D. et al. Measuring massive multitask language understanding. In Proc. International Conference on Learning Representations (ICLR) https://openreview.net/forum?id=d7KBjmI3GmQ (ICLR, 2021).
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Supportedcites [2] Gemini Team Google. Gemini 1.5: unlocking multimodal understanding across millions of tokens of context. Preprint at https://arxiv.org/abs/2403.05530 (2024). source
The Math and Science results (section 6.1.1) report 91.7% on MMLU for Gemini 1.5 Pro, supporting the claim that a leading LLM exceeds 90%. That figure uses majority voting over 32 responses (maj@32); its listed 5-shot score is 85.9%. (LLM, conf=0.88)
- Disputedcites [3] OpenAI et al. GPT-4 technical report. Preprint at https://arxiv.org/abs/2303.08774 (2024). sourceExperimental — accuracy not yet measured
The 4 Capabilities table (p. 7) reports GPT-4 at 86.4% on MMLU, not more than 90%. It reports scores above 90% on other benchmarks, but those do not support the claim's MMLU example. (LLM, conf=0.91)
Checked by a reasoning model — may be wrong.
- Not matchedcites [4] The Claude 3 Model Family: Opus, Sonnet, Haiku (Anthropic, 2024).
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Not matchedcites [5] OpenAI o1 System Card (OpenAI, 2024).
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Supportedcites [6] Guo, D. et al. DeepSeek-R1 incentivizes reasoning in LLMs through reinforcement learning. Nature 645, 633–638 (2025). 40962978 PMC12443585 source
Table 2 (DeepSeek-R1 section) reports 90.8% for DeepSeek-R1 and 91.2% for an intermediate model on MMLU. These results support the claim that LLMs can exceed 90% on that benchmark. (LLM, conf=0.92)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: another passage · plain
At least one cited source doesn’t support this claim or points to a different paper, and none confirmed it — see the verdicts below.
In the paper
“recent history shows benchmarks are quickly saturated—with models markedly progressing from near-zero to near-perfect performance in a short timeframe9,10.”
§ A benchmark of expert-level academic questions to assess AI capabilities > Discussion > Limitations
What the sources say
- Not matchedcites [9] Rein, D. et al. GPQA: A graduate-level Google-proof Q&A benchmark. In Proc. First Conference on Language Modeling (COLM) https://openreview.net/forum?id=Ti67584b98 (COLM, 2024).
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
- Disputedcites [10] Chollet, F., Knoop, M., Kamradt, G. & Landers, B. ARC prize 2024: technical report. Preprint at https://arxiv.org/abs/2412.04604 (2024). sourceExperimental — accuracy not yet measured
Our copy of the ARC Prize 2024 report says the opposite of quick saturation for the benchmark it documents: the Abstract states ARC-AGI 'is five years old and remains unbeaten' and is 'the most important unsolved AI benchmark in the world', and Section 1.2 (Pre-2024 Progress) records that the 2020 top score of 20% 'had only increased to 33%' four years later, with no deep-learning approach above 1% and GPT-3 at 0% in 2020. The 2024 gain reported (33% to 55.5%, Abstract and Section 3/Conclusion) is substantial but far from near-perfect, and the Conclusion (Section 5) insists ARC-AGI 'remains undefeated - still by a considerable margin'. No passage in our copy (searched: benchmark saturation, solved/defeated benchmarks, near-zero to near-perfect progress) states the general claim that benchmarks are quickly saturated. (LLM, conf=0.70)
Checked by a reasoning model — may be wrong.
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Not matched
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“but it would not alone suggest autonomous research capabilities or artificial general intelligence11.”
§ A benchmark of expert-level academic questions to assess AI capabilities > Discussion > Limitations
What the sources say
- Partly supportedcites [11] Hendrycks, D. et al. A definition of AGI. Preprint at https://arxiv.org/abs/2510.18212 (2025). sourceExperimental — accuracy not yet measured
On p. 2, the paper says impressive performance on complex benchmarks can coexist with missing capabilities essential to AGI. The Discussion (p. 15) separately defines Recursive AI as independently conducting the entire AI R&D lifecycle. These passages support the caution, but the paper does not specifically assess whether high accuracy on HLE indicates autonomous research capability. (LLM, conf=0.84)
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“State-of-the-art LLMs demonstrate low accuracy and calibration on HLE”
- Also stated in: another passage · plain
“Models also provide incorrect answers with high confidence rather than acknowledging uncertainty on these challenging questions, with most models exhibiting root mean square (RMS) calibration errors above 70%.”
- Also stated in: another passage · plain
“Table 1 shows poor calibration across all models, reflected in high RMS calibration error scores.”
§ A benchmark of expert-level academic questions to assess AI capabilities > Abstract
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: another passage · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Gemini 2.5 Pro | 21.6 ± 1.6 | 72”
§ A benchmark of expert-level academic questions to assess AI capabilities > Evaluation > Quantitative results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
14 more claims
Create a free account to see all 40 claims and every source verdict.
- Probably not a substantial claim. 18
- It may state two separate claims as one. 12
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source doesn’t support the claim as written.
In the citing paper
“breakthroughs on MMLU, HLE, and mathematical olympiads have been achieved through scaling rather than novel reasoning mechanisms [Phan et al. 2025]”
From The ARC of Progress towards AGI: A Living Survey of Abstraction and Reasoning (2026) · cites this paper as Phan et al. 2025
Checked by a reasoning model — may be wrong.
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Second, benchmarks are often adversarially selected for tasks that current models struggle with compared to humans, 1 biasing the comparison to human performance.”
From Measuring AI Ability to Complete Long Software Tasks (2025) · cites this paper as [5]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Some deep research benchmarks focus on challenging but closed-ended tasks whose solutions can be checked by a deterministic algorithm against the ground truth (e.g., Mialon et al. [2023], Phan et al. [2025], Wei et al. [2025], Krishna et al. [2024], Gupta et al. [2026]).”
From DRACO: a Cross-Domain Benchmark for Deep Research Accuracy, Completeness, and Objectivity (2026) · cites this paper as Phan et al. [2025]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Among these works, some utilize QA datasets [21, 16, 30] as evaluation metrics; however, this approach neither aligns with real-world DRA applications nor comprehensively assesses their broader capabilities.”
From DeepResearch Bench: A Comprehensive Benchmark for Deep Research Agents (2025) · cites this paper as [21]
The cited source says what the claim attributes to it.
In the citing paper
“This problem is exacerbated by search-time data contamination, where challenging benchmarks such as Humanity's Last Exam (Phan et al., 2025) leaked 3% of their answers on HuggingFace alone (Han et al., 2025).”
From BrowseComp-Plus: A Fair and Disentangled Evaluation Benchmark for Deep Search Agents (2026) · cites this paper as Phan et al., 2025
2 more claims about this paper
Create a free account to see every claim other papers make about this one.
Citations
Cites
DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning
DeepSeek-AI, Guo, D., Yang, D., Zhang, H., Song, J., Wang, P., Zhu, Q., Xu, R., Zhang, R., Ma, S., et al. (2025) · arXiv · doi:10.48550/arxiv.2501.12948 · Cited by 18,918
Self-citationSQuAD: 100,000+ Questions for Machine Comprehension of Text
Rajpurkar, P., Zhang, J., Lopyrev, K., & Liang, P. (2016) · Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d16-1264 · Cited by 6,208 · cited 2×
“The benchmark is developed by subject-matter experts globally.”
VQA: Visual Question Answering
Antol, S., Agrawal, A., Lu, J., Mitchell, M., Batra, D., Zitnick, C. L., & Parikh, D. (2015) · 2015 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2015.279 · Cited by 4,487
Self-citationGLUE: A Multi-Task Benchmark and Analysis Platform for Natural Language Understanding
Wang, A., Singh, A., Michael, J., Hill, F., Levy, O., & Bowman, S. (2018) · Proceedings of the 2018 EMNLP Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP · doi:10.18653/v1/w18-5446 · Cited by 4,222 · cited 1×
“Each question undergoes rigorous multi-stage review by graduate-level and expert reviewers to ensure high difficulty, precision, and relevance.”
Self-citationLarge language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
A large annotated corpus for learning natural language inference
Bowman, S. R., Angeli, G., Potts, C., & Manning, C. D. (2015) · Proceedings of the 2015 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d15-1075 · Cited by 3,377 · cited 1×
“This level of expert disa-greement is in line with what is observed in other well-known machine learning benchmarks 59–62 .”
MS MARCO: A Human Generated MAchine Reading COmprehension Dataset
Bajaj, P., Campos, D., Craswell, N., Deng, L., Gao, J., Liu, X., Majumder, R., McNamara, A., Mitra, B., Nguyen, T., et al. (2016) · arXiv · doi:10.48550/arxiv.1611.09268 · Cited by 2,473 · cited 1×
“The benchmark is developed by subject-matter experts globally.”
Self-citationKnow What You Don't Know: Unanswerable Questions for SQuAD
Rajpurkar, P., Jia, R., & Liang, P. (2018) · arXiv · doi:10.48550/arxiv.1806.03822 · Cited by 2,242 · cited 2×
“The framing of the benchmark as "humanity's last exam" feels a bit strong to me.”
Know What You Don’t Know: Unanswerable Questions for SQuAD
Rajpurkar, P., Jia, R., & Liang, P. (2018) · Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 2: Short Papers) · doi:10.18653/v1/p18-2124 · Cited by 2,240 · cited 2×
“The framing of the benchmark as "humanity's last exam" feels a bit strong to me.”
Research works printed but not linked: 16
- [1]Hendrycks, D. et al. Measuring massive multitask language understanding. In Proc. International Conference on Learning Representations (ICLR) https://openreview.net/forum?id=d7KBjmI3GmQ (ICLR, 2021).
- [9]Rein, D. et al. GPQA: A graduate-level Google-proof Q&A benchmark. In Proc. First Conference on Language Modeling (COLM) https://openreview.net/forum?id=Ti67584b98 (COLM, 2024).
- [12]Li, N. et al. The WMDP benchmark: measuring and reducing malicious use with unlearning. In Proc. 41st International Conference on Machine Learning (ICML), 28713–28738 (PMLR, 2024).
- [14]Srivastava, A. et al. Beyond the imitation game: Quantifying and extrapolating the capabilities of language models. Trans. Mach. Learn. Res. https://openreview.net/forum?id=uyTL5Bvosj (2023).
- [16]Hendrycks, D. et al. Measuring mathematical problem solving with the MATH dataset. In Proc. 35th Conference on Neural Information Processing Systems (NeurIPS) Datasets and Benchmarks Track https://openreview.net/forum?id=7Bywt2mQsCe (NeurIPS, 2021).
- [17]Lu, P. et al. MathVista: Evaluating mathematical reasoning of foundation models in visual contexts. In Proc. International Conference on Learning Representations (ICLR) https://openreview.net/forum?id=KUNzEQMWU7 (ICLR, 2024).
- [21]Gao, B. et al. Omni-MATH: A universal Olympiad level mathematic benchmark for large language models. In Proc. International Conference on Learning Representations (ICLR) https://openreview.net/forum?id=yaqPf0KAlN (ICLR, 2025).
- [22]Chan, J. S. et al. MLE-bench: Evaluating machine learning agents on machine learning engineering. In Proc. International Conference on Learning Representations (ICLR) https://openreview.net/forum?id=6s5uXNWGIh (ICLR, 2025).
- [23]Zhang, A. K. et al. Cybench: A framework for evaluating cybersecurity capabilities and risks of language models. In Proc. International Conference on Learning Representations (ICLR) https://openreview.net/forum?id=tc90LV0yRL (ICLR, 2025).
- [24]Jimenez, C. E. et al. SWE-bench: Can language models resolve real-world Github issues? In Proc. International Conference on Learning Representations (ICLR) https://openreview.net/forum?id=VTF8yNQM66 (ICLR, 2024).
- [30]Perez, E. et al. Discovering language model behaviors with model-written evaluations. In Findings of the Association for Computational Linguistics: ACL 2023, 13387–13434 (ACL, 2023).
- [34]Hendrycks, D. et al. What would Jiminy Cricket do? Towards agents that behave morally. In Proc. 35th Conference on Neural Information Processing Systems (NeurIPS) Datasets and Benchmarks Track https://openreview.net/forum?id=G1muTb5zuO7 (NeurIPS, 2021).
- [37]Wang, A. et al. SuperGLUE: A stickier benchmark for general-purpose language understanding systems. In Proc. Advances in Neural Information Processing Systems (NeurIPS), Vol. 32, 3261–3275 (NeurIPS, 2019).
- [46]Yao, S. et al. τ-bench: A benchmark for tool-agent-user interaction in real-world domains. In Proc. International Conference on Learning Representations (ICLR) https://openreview.net/forum?id=roNSXZpUDN (ICLR, 2025).
- [47]Andriushchenko, M. et al. AgentHarm: A benchmark for measuring harmfulness of LLM agents. In Proc. International Conference on Learning Representations (ICLR) https://openreview.net/forum?id=AC5n7xHuR1 (ICLR, 2025).
- [50]Srinivasan, V. K. et al. NexusRaven: a commercially-permissive language model for function calling. In NeurIPS 2023 Foundation Models for Decision Making Workshop (NeurIPS, 2023).
Cited by
A Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Dong, Z., Hou, Y., Zhang, B., Min, Y., Zhang, J., Liu, P., et al. (2026) · Frontiers of Computer Science · doi:10.1007/s11704-026-60308-3 · Cited by 2,093
Self-citationEvaluating large language models for accuracy incentivizes hallucinations
Kalai, A. T., Nachum, O., Vempala, S., & Zhang, E. (2026) · Nature · doi:10.1038/s41586-026-10549-w · Cited by 788
MiniMax-M1: Scaling Test-Time Compute Efficiently with Lightning AttentionPreprint
MiniMax, :, Chen, A., Li, A., Gong, B., Jiang, B., Fei, B., Yang, B., Shan, B., Yu, C.-Q., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.13585 · Cited by 347
“• Reasoning & Knowledge: We assess domain knowledge and reasoning capabilities through GPQA-Diamond (Rein et al., 2024), MMLU-Pro (Wang et al., 2024), and the challenging HLE benchmark (Phan et al., 2025).”
Self-citationA Survey on Test-Time Scaling in Large Language Models: What, How, Where, and How Well?Preprint
Zhang, Q., Lyu, F., Sun, Z., Wang, L., Zhang, W., Hua, W., Wu, H., Guo, Z., Wang, Y.-F., Muennighoff, N., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2503.24235 · Cited by 362
Self-citationTongyi DeepResearch Technical ReportPreprint
Tongyi DeepResearch Team, Li, B., Zhang, B., Zhang, D., Huang, F., Li, G., Chen, G., Yin, H., Wu, J., Zhou, J., et al. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2510.24701 · Cited by 299
Self-citation
Metadata
- Authors
- Phan, L., Gatti, A., Han, Z., Li, N., Hu, J., Zhang, H., Zhang, C. B. C., Shaaban, M., Ling, J., Shi, S., Choi, M., Agrawal, A., Chopra, A., Khoja, A., Kim, R., Ren, R., Hausenloy, J., Zhang, O., Mazeika, M., Dodonov, D., Nguyen, T., Lee, J., Anderson, D., Doroshenko, M., Stokes, A. C., Mahmood, M., Pokutnyi, O., Iskra, O., Wang, J. P., Levin, J.-C., Kazakov, M., Feng, F., Feng, S. Y., Zhao, H., Yu, M., Gangal, V., Zou, C., Wang, Z., Popov, S., Gerbicz, R., Galgon, G., Schmitt, J., Yeadon, W., Lee, Y., Sauers, S., Sanchez, A., Giska, F., Roth, M., Riis, S., Utpala, S., Burns, N., Goshu, G. M., Naiya, M. M., Agu, C., Giboney, Z., Cheatom, A., Fournier-Facio, F., Crowson, S.-J., Finke, L., Cheng, Z., Zampese, J., Hoerr, R. G., Nandor, M., Park, H., Gehrunger, T., Cai, J., McCarty, B., Garretson, A. C., Taylor, E., Sileo, D., Ren, Q., Qazi, U., Li, L., Nam, J., Wydallis, J. B., Arkhipov, P., Shi, J. W. L., Bacho, A., Willcocks, C. G., Cao, H., Motwani, S., Santos, E. D. O., Veith, J., Vendrow, E., Cojoc, D., Zenitani, K., Robinson, J., Tang, L., Li, Y., Vendrow, J., Fraga, N. W., Kuchkin, V., Maksimov, A. P., Marion, P., Efremov, D., Lynch, J., Liang, K., Mikov, A., Gritsevskiy, A., Guillod, J., Demir, G., Martinez, D., Pageler, B., Zhou, K., Soori, S., Press, O., Tang, H., Rissone, P., Green, S. R., Brüssel, L., Twayana, M., Dieuleveut, A., Imperial, J. M., Prabhu, A., Yang, J., Crispino, N., Rao, A., Zvonkine, D., Loiseau, G., Kalinin, M., Lukas, M., Manolescu, C., Stambaugh, N., Mishra, S., Hogg, T., Bosio, C., Coppola, B. P., Salazar, J., Jin, J., Sayous, R., Ivanov, S., Schwaller, P., Senthilkuma, S., Bran, A. M., Algaba, A., Houte, K. V. D., Van Der Sypt, L., Verbeken, B. F., Noever, D., Kopylov, A., Myklebust, B., Li, B., Schut, L., Zheltonozhskii, E., Yuan, Q., Lim, D., Stanley, R., Yang, T., Maar, J., Wykowski, J., Oller, M., Sahu, A., Ardito, C. G., Hu, Y., Kamdoum, A. G. K., Jin, A., Vilchis, T. G., Zu, Y., Lackner, M., Koppel, J., Sun, G., Antonenko, D. S., Chern, S., Zhao, B., Arsene, P., Cavanagh, J. M., Li, D., Shen, J., Crisostomi, D., Zhang, W., Dehghan, A., Ivanov, S., Perrella, D., Kaparov, N., Zang, A., Sucholutsky, I., Kharlamova, A., Orel, D., Poritski, V., Ben-David, S., Berger, Z., Whitfill, P., Foster, M., Munro, D., Ho, L., Sivarajan, S., Hava, D. B., Kuchkin, A., Holmes, D., Rodriguez-Romero, A., Sommerhage, F., Zhang, A., Moat, R., Schneider, K., Kazibwe, Z., Clarke, D., Kim, D. H., Dias, F. M., Fish, S., Elser, V., Kreiman, T., Vilchis, V. E. G., Klose, I., Anantheswaran, U., Zweiger, A., Rawal, K., Li, J., Nguyen, J., Daans, N., Heidinger, H., Radionov, M., Rozhoň, V., Ginis, V., Stump, C., Cohen, N., Poświata, R., Tkadlec, J., Goldfarb, A., Wang, C., Padlewski, P., Barzowski, S., Montgomery, K., Stendall, R., Tucker-Foltz, J., Stade, J., Rogers, T. R., Goertzen, T., Grabb, D., Shukla, A., Givré, A., Ambay, J. A., Sen, A., Aziz, M. F., Inlow, M. H., He, H., Zhang, L., Kaddar, Y., Ängquist, I., Chen, Y., Wang, H. K., Ramakrishnan, K., Thornley, E., Terpin, A., Schoelkopf, H., Zheng, E., Carmi, A., Brown, E. D. L., Zhu, K., Bartolo, M., Wheeler, R., Stehberger, M., Bradshaw, P., Heimonen, J., Sridhar, K., Akov, I., Sandlin, J., Makarychev, Y., Tam, J., Hoang, H., Cunningham, D. M., Goryachev, V., Patramanis, D., Krause, M., Redenti, A., Aldous, D., Lai, J., Coleman, S., Xu, J., Lee, S., Magoulas, I., Zhao, S., Tang, N., Cohen, M. K., Paradise, O., Kirchner, J. H., Ovchynnikov, M., Matos, J. O., Shenoy, A., Wang, M., Nie, Y., Sztyber-Betley, A., Faraboschi, P., Riblet, R., Crozier, J., Halasyamani, S., Verma, S., Joshi, P., Meril, E., Ma, Z., Andréoletti, J., Singhal, R., Platnick, J., Nevirkovets, V., Basler, L., Ivanov, A., Khoury, S., Gustafsson, N., Piccardo, M., Mostaghimi, H., Chen, Q., Singh, V., Khánh, T. Q., Rosu, P., Szlyk, H., Brown, Z., Narayan, H., Menezes, A., Roberts, J., Alley, W., Sun, K., Patel, A., Lamparth, M., Reuel, A., Xin, L., Xu, H., Loader, J., Martin, F., Wang, Z., Achilleos, A., Preu, T., Korbak, T., Bosio, I., Kazemi, F., Chen, Z., Bálint, B., Lo, E. J. Y., Wang, J., Nunes, M. I. S., Milbauer, J., Bari, M. S., Wang, Z., Ansarinejad, B., Sun, Y., Durand, S., Elgnainy, H., Douville, G., Tordera, D., Balabanian, G., Wolff, H., Kvistad, L., Milliron, H., Sakor, A., Eron, M., O., A. F. D., Shah, S., Zhou, X., Kamalov, F., Abdoli, S., Santens, T., Barkan, S., Tee, A., Zhang, R., Tomasiello, A., De Luca, G. B., Looi, S.-Z., Le, V.-K., Kolt, N., Pan, J., Rodman, E., Drori, J., Fossum, C. J., Muennighoff, N., Jagota, M., Pradeep, R., Fan, H., Eicher, J., Chen, M., Thaman, K., Merrill, W., Firsching, M., Harris, C., Ciobâcă, S., Gross, J., Pandey, R., Gusev, I., Jones, A., Agnihotri, S., Zhelnov, P., Mofayezi, M., Piperski, A., Zhang, D. K., Dobarskyi, K., Leventov, R., Soroko, I., Duersch, J., Taamazyan, V., Ho, A., Ma, W., Held, W., Xian, R., Zebaze, A. R., Mohamed, M., Leser, J. N., Yuan, M. X., Yacar, L., Lengler, J., Olszewska, K., Di Fratta, C., Oliveira, E., Jackson, J. W., Zou, A., Chidambaram, M., Manik, T., Haffenden, H., Stander, D., Dasouqi, A., Shen, A., Golshani, B., Stap, D., Kretov, E., Uzhou, M., Zhidkovskaya, A. B., Winter, N., Rodriguez, M. O., Lauff, R., Wehr, D., Tang, C., Hossain, Z., Phillips, S., Samuele, F., Ekström, F., Hammon, A., Patel, O., Farhidi, F., Medley, G., Mohammadzadeh, F., Peñaflor, M., Kassahun, H., Friedrich, A., Perez, R. H., Pyda, D., Sakal, T., Dhamane, O., Mirabadi, A. K., Hallman, E., Okutsu, K., Battaglia, M., Maghsoudimehrabani, M., Amit, A., Hulbert, D., Pereira, R., Weber, S., Handoko, Peristyy, A., Malina, S., Mehkary, M., Aly, R., Reidegeld, F., Dick, A.-K., Friday, C., Singh, M., Shapourian, H., Kim, W., Costa, M., Gurdogan, H., Kumar, H., Ceconello, C., Zhuang, C., Park, H., Carroll, M., Tawfeek, A. R., Steinerberger, S., Aggarwal, D., Kirchhof, M., Dai, L., Kim, E., Ferret, J., Shah, J., Wang, Y., Yan, M., Burdzy, K., Zhang, L., Franca, A., Pham, D. T., Loh, K. Y., Robinson, J., Jackson, A., Giordano, P., Petersen, P., Cosma, A., Colino, J., White, C., Votava, J., Vinnikov, V., Delaney, E., Spelda, P., Stritecky, V., Shahid, S. M., Mourrat, J.-C., Vetoshkin, L., Sponselee, K., Bacho, R., Yong, Z.-X., de la Rosa, F., Cho, N., Li, X., Malod, G., Weller, O., Albani, G., Lang, L., Laurendeau, J., Kazakov, D., Adesanya, F., Portier, J., Hollom, L., Souza, V., Zhou, Y. A., Degorre, J., Yalın, Y., Obikoya, G. D., Rai, Bigi, F., Boscá, M. C., Shumar, O., Bacho, K., Recchia, G., Popescu, M., Shulga, N., Tanwie, N. M., Lux, T. C. H., Rank, B., Ni, C., Brooks, M., Yakimchyk, A., Huanxu, Liu, Cavalleri, S., Häggström, O., Verkama, E., Newbould, J., Gundlach, H., Brito-Santana, L., Amaro, B., Vajipey, V., Grover, R., Wang, T., Kratish, Y., Li, W.-D., Gopi, S., Caciolai, A., de Witt, C. S., Hernández-Cámara, P., Rodolà, E., Robins, J., Williamson, D., Cheng, V., Raynor, B., Qi, H., Segev, B., Fan, J., Martinson, S., Wang, E. Y., Hausknecht, K., Brenner, M. P., Mao, M., Demian, C., Kassani, P., Zhang, X., Avagian, D., Scipio, E. J., Ragoler, A., Tan, J., Sims, B., Plecnik, R., Kirtland, A., Bodur, O. F., Shinde, D. P., Labrador, Y. C. L., Adoul, Z., Zekry, M., Karakoc, A., Santos, T. C. B., Shamseldeen, S., Karim, L., Liakhovitskaia, A., Resman, N., Farina, N., Gonzalez, J. C., Maayan, G., Anderson, E., Pena, R. D. O., Kelley, E., Mariji, H., Pouriamanesh, R., Wu, W., Finocchio, R., Alarab, I., Cole, J., Ferreira, D., Johnson, B., Safdari, M., Dai, L., Arthornthurasuk, S., McAlister, I. C., Moyano, A. J., Pronin, A., Fan, J., Ramirez-Trinidad, A., Malysheva, Y., Pottmaier, D., Taheri, O., Stepanic, S., Perry, S., Askew, L., Rodríguez, R. A. H., Minissi, A. M. R., Lorena, R., Iyer, K., Fasiludeen, A. A., Clark, R., Ducey, J., Piza, M., Somrak, M., Vergo, E., Qin, J., Borbás, B., Chu, E., Lindsey, J., Jallon, A., McInnis, I. M. J., Chen, E., Semler, A., Gloor, L., Shah, T., Carauleanu, M., Lauer, P., Huy, T. Đ., Shahrtash, H., Duc, E., Lewark, L., Brown, A., Albanie, S., Weber, B., Vaz, W. S., Clavier, P., Fan, Y., Silva, G. P. R. E., Long, Lian, Abramovitch, M., Jiang, X., Mendoza, S., Islam, M., Gonzalez, J., Mavroudis, V., Xu, J., Kumar, P., Goswami, L. P., Bugas, D., Heydari, N., Jeanplong, F., Jansen, T., Pinto, A., Apronti, A., Galal, A., Ze-An, N., Singh, A., Jiang, T., Xavier, J. O. A., Agarwal, K. P., Berkani, M., Zhang, G., Du, Z., Junior, B. A. D. O., Malishev, D., Remy, N., Hartman, T. D., Tarver, T., Mensah, S., Loume, G. A., Morak, W., Habibi, F., Hoback, S., Cai, W., Gimenez, J., Montecillo, R. G., Łucki, J., Campbell, R., Sharma, A., Meer, K., Gul, S., Gonzalez, D. E., Alapont, X., Hoover, A., Chhablani, G., Vargus, F., Agarwal, A., Jiang, Y., Patil, D., Outevsky, D., Scaria, K. J., Maheshwari, R., Dendane, A., Shukla, P., Cartwright, A., Bogdanov, S., Mündler, N., Möller, S., Arnaboldi, L., Thaman, K., Siddiqi, M. R., Saxena, P., Gupta, H., Fruhauff, T., Sherman, G., Vincze, M., Usawasutsakorn, S., Ler, D., Radhakrishnan, A., Enyekwe, I., Salauddin, S. M., Muzhen, J., Maksapetyan, A., Rossbach, V., Harjadi, C., Bahaloohoreh, M., Sparrow, C., Sidhu, J., Ali, S., Bian, S., Lai, J., Singer, E., Uro, J. L., Bateman, G., Sayed, M., Menshawy, A., Duclosel, D., Bezzi, D., Jain, Y., Aaron, A., Tiryakioglu, M., Siddh, S., Krenek, K., Shah, I. A., Jin, J., Creighton, S., Peskoff, D., EL-Wasif, Z., P, R., Richmond, M., McGowan, J., Patwardhan, T., Sun, H.-Y., Sun, T., Zubić, N., Sala, S., Ebert, S., Kaddour, J., Schottdorf, M., Wang, D., Petruzella, G., Meiburg, A., Medved, T., ElSheikh, A., Hebbar, S. A., Vaquero, L., Yang, X., Poulos, J., Zouhar, V., Bogdanik, S., Zhang, M., Sanz-Ros, J., Anugraha, D., Dai, Y., Nhu, A. N., Wang, X., Demircali, A. A., Jia, Z., Zhou, Y., Wu, J., He, M., Chandok, N., Sinha, A., Luo, G., Le, L., Noyé, M., Perełkiewicz, M., Pantidis, I., Qi, T., Purohit, S. S., Parcalabescu, L., Nguyen, T.-H., Winata, G. I., Ponti, E. M., Li, H., Dhole, K., Park, J., Abbondanza, D., Wang, Y., Nayak, A., Caetano, D. M., Wong, A. A. W. L., del Rio-Chanona, M., Kondor, D., Francois, P., Chalstrey, E., Zsambok, J., Hoyer, D., Reddish, J., Hauser, J., Rodrigo-Ginés, F.-J., Datta, S., Shepherd, M., Kamphuis, T., Zhang, Q., Kim, H., Sun, R., Yao, J., Dernoncourt, F., Krishna, S., Rismanchian, S., Pu, B., Pinto, F., Wang, Y., Shridhar, K., Overholt, K. J., Briia, G., Nguyen, H., David, Bartomeu, S., Pang, T. C., Wecker, A., Xiong, Y., Li, F., Huber, L. S., Jaeger, J., De Maddalena, R., Lù, X. H., Zhang, Y., Beger, C., Kon, P. T. J., Li, S., Sanker, V., Yin, M., Liang, Y., Zhang, X., Agrawal, A., Yifei, L. S., Zhang, Z., Cai, M., Sonmez, Y., Cozianu, C., Li, C., Slen, A., Yu, S., Park, H. K., Sarti, G., Briański, M., Stolfo, A., Nguyen, T. A., Zhang, M., Perlitz, Y., Hernandez-Orallo, J., Li, R., Shabani, A., Juefei-Xu, F., Dhingra, S., Zohar, O., Nguyen, M. C., Pondaven, A., Yilmaz, A., Zhao, X., Jin, C., Jiang, M., Todoran, S., Han, X., Kreuer, J., Rabern, B., Plassart, A., Maggetti, M., Yap, L., Geirhos, R., Kean, J., Wang, D., Mollaei, S., Sun, C., Yin, Y., Wang, S., Li, R., Chang, Y., Wei, A., Bizeul, A., Wang, X., Arrais, A. O., Mukherjee, K., Chamorro-Padial, J., Liu, J., Qu, X., Guan, J., Bouyamourn, A., Wu, S., Plomecka, M., Chen, J., Tang, M., Deng, J., Subramanian, S., Xi, H., Chen, H., Zhang, W., Ren, Y., Tu, H., Kim, S., Chen, Y., Marjanović, S. V., Ha, J., Luczyna, G., Ma, J. J., Shen, Z., Song, D., Zhang, C. E., Wang, Z., Gendron, G., Xiao, Y., Smucker, L., Weng, E., Lee, K. H., Ye, Z., Ermon, S., Lopez-Miguel, I. D., Knights, T., Gitter, A., Park, N., Wei, B., Chen, H., Pai, K., Elkhanany, A., Lin, H., Siedler, P. D., Fang, J., Mishra, R., Zsolnai-Fehér, K., Jiang, X., Khan, S., Yuan, J., Jain, R. K., Lin, X., Peterson, M., Wang, Z., Malusare, A., Tang, M., Gupta, I., Fosin, I., Kang, T., Dworakowska, B., Matsumoto, K., Zheng, G., Sewuster, G., Villanueva, J. P., Rannev, I., Chernyavsky, I., Chen, J., Banik, D., Racz, B., Dong, W., Wang, J., Bashmal, L., Gonçalves, D. V., Hu, W., Bar, K., Bohdal, O., Patlan, A. S., Dhuliawala, S., Geirhos, C., Wist, J., Kansal, Y., Chen, B., Tire, K., Yücel, A. T., Christof, B., Singla, V., Song, Z., Chen, S., Ge, J., Ponkshe, K., Park, I., Shi, T., Ma, M. Q., Mak, J., Lai, S., Moulin, A., Cheng, Z., Zhu, Z., Zhang, Z., Patil, V., Jha, K., Men, Q., Wu, J., Zhang, T., Vieira, B. H., Aji, A. F., Chung, J.-W., Mahfoud, M., Hoang, H. T., Sperzel, M., Hao, W., Meding, K., Xu, S., Kostakos, V., Manini, D., Liu, Y., Toukmaji, C., Paek, J., Yu, E., Demircali, A. E., Sun, Z., Dewerpe, I., Qin, H., Pflugfelder, R., Bailey, J., Morris, J., Heilala, V., Rosset, S., Yu, Z., Chen, P. E., Yeo, W., Jain, E., Yang, R., Chigurupati, S., Chernyavsky, J., Reddy, S. P., Venugopalan, S., Batra, H., Park, C. F., Tran, H., Maximiano, G., Zhang, G., Liang, Y., Shiyu, H., Xu, R., Pan, R., Suresh, S., Liu, Z., Gulati, S., Zhang, S., Turchin, P., Bartlett, C. W., Scotese, C. R., Cao, P. M., Wu, B., Karwowski, J., Scaramuzza, D., Nattanmai, A., McKellips, G., Cheraku, A., Suhail, A., Luo, E., Deng, M., Luo, J., Zhang, A., Jindel, K., Paek, J., Halevy, K., Baranov, A., Liu, M., Avadhanam, A., Zhang, D., Cheng, V., Ma, B., Fu, E., Do, L., Lass, J., Yang, H., Sunkari, S., Bharath, V., Ai, V., Leung, J., Agrawal, R., Zhou, A., Chen, K., Kalpathi, T., Xu, Z., Wang, G., Xiao, T., Maung, E., Lee, S., Yang, R., Yue, R., Zhao, B., Yoon, J., Sun, S., Singh, A., Luo, E., Peng, C., Osbey, T., Wang, T., Echeazu, D., Yang, H., Wu, T., Patel, S., Kulkarni, V., Sundarapandiyan, V., Zhang, A., Le, A., Nasim, Z., Yalam, S., Kasamsetty, R., Samal, S., Yang, H., Sun, D., Shah, N., Saha, A., Zhang, A., Nguyen, L., Nagumalli, L., Wang, K., Zhou, A., Wu, A., Luo, J., Telluri, A., Dillmann, S., Wang, Z., Luo, J., Lunn, H., Gazizov, A., Borde, H. S. D. O., Trus, I., Hervault, M., Zhang, Z., Chen, B., Wu, Y., Cordier, C. J., Kaynar, G., Ayvaz, C., Avdiunina, P., Brust, J., Diao, X., Meaney, K. D., Gu, Y., Wang, C., Dong, C., Wright, W., Brave, S., Root, O., Liu, J., Lok, C. C., Li, T., Du, S., He, D., Liu, L., Jamalzadegan, S., Ramakrishna, A., Xu, X., Qing, X., Luo, X., Li, W., Bo, S., Gusev, F., Skandalis, M., Ma, D., Zhang, C., Qiu, H., Hart, A. G., Gabrielsson, R. B., Akov, I., Lukoianov, A., Hu, P., Li, S., Lyu, W., Zhao, X., Yang, T., Wu, W., Lei, D., Baber, R. W., Yuan, X., Wang, L., Cui, Y., David, J.-R., Potlapelly, S., Kalfus, J., Xu, H., Bendahi, A., Bao, Q., Jia, Y., Gui, J., Hu, J., Liu, Z., Şık, F., Handoko, B., Yue, S., Wang, A., & Hendrycks, D.
- Affiliations
- Michael Pokorny
- Massachusetts Institute of Technology (US)
- George Mason University (US)
- Brown University (US)
- McGill University (CA)
- Carnegie Mellon University (US)
- University of Washington (US)
- University of Cambridge (GB)
- Queen's University (CA)
- Stanford University (US)
- Novo Nordisk (Denmark) (DK)
- Universidade do Porto (PT)
- Eötvös Loránd University (HU)
- ETH Zurich (CH)
- Durham University (GB)
- University of Minnesota (US)
- Queen Mary University of London (GB)
- Microsoft (United States) (US)
- Auckland University of Technology (NZ)
- Alberta Health Services (CA)
- University of Illinois Chicago (US)
- MAGNET: Machine Learning in Information Networks (FR)
- Princeton University (US)
- University of Canterbury (NZ)
- Metropolitan State University of Denver (US)
- Seoul National University (KR)
- Accenture (United States) (US)
- Tufts University (US)
- Institut national de recherche en sciences et technologies du numérique (FR)
- University of California, Berkeley (US)
- University of British Columbia (CA)
- École Polytechnique Fédérale de Lausanne (CH)
- Concordia University (CA)
- Institute of Science and Technology Austria (AT)
- National University of Singapore (SG)
- California Institute of Technology (US)
- University of Oxford (GB)
- Humboldt-Universität zu Berlin (DE)
- Columbia University (US)
- Stony Brook University (US)
- University of Luxembourg (LU)
- Universidade Federal de Juiz de Fora (BR)
- Rockwell Automation (United States) (US)
- École Normale Supérieure - PSL (FR)
- University of Toronto (CA)
- University of Tübingen (DE)
- Sapienza University of Rome (IT)
- École Normale Supérieure Paris-Saclay (FR)
- University of North Texas (US)
- Institut Polytechnique de Paris (FR)
- National University (PH)
- Maastricht University (NL)
- Washington University in St. Louis (US)
- University of California, Los Angeles (US)
- Centre National de la Recherche Scientifique (FR)
- Martin Luther University Halle-Wittenberg (DE)
- Leibniz University Hannover (DE)
- Indian Institute of Technology Bombay (IN)
- Institute for Molecular Manufacturing (US)
- University of Michigan (US)
- Université Paris-Saclay (FR)
- Vrije Universiteit Brussel (BE)
- PeopleTec (United States) (US)
- University of Chicago (US)
- Technion – Israel Institute of Technology (IL)
- University of Miami (US)
- Technische Universität Berlin (DE)
- University of Manchester (GB)
- University of Illinois Urbana-Champaign (US)
- University of Calgary (CA)
- Universidad Iberoamericana (MX)
- TU Wien (AT)
- University of Wisconsin–Madison (US)
- Yale University (US)
- University of Edinburgh (GB)
- The University of Western Australia (AU)
- New York University (US)
- Mohamed bin Zayed University of Artificial Intelligence (AE)
- University of Waterloo (CA)
- University of California San Diego (US)
- University of Maryland, College Park (US)
- Manhattan School of Music (US)
- Leiden University (NL)
- The Open University (GB)
- Corteva (United States) (US)
- Sanford Burnham Prebys Medical Discovery Institute (US)
- Yonsei University (KR)
- Universidade de São Paulo (BR)
- Harvard University (US)
- Cornell University (US)
- University of Leeds (GB)
- Arizona State University (US)
- Swinburne University of Technology (AU)
- KU Leuven (BE)
- Universidad Nacional Agraria La Molina (PE)
- Brandenburg University of Technology Cottbus-Senftenberg (DE)
- Ruhr University Bochum (DE)
- National Information Processing Institute (PL)
- Charles University (CZ)
- Cranfield University (GB)
- University of Copenhagen (DK)
- The University of Sydney (AU)
- Indian Institute of Technology Delhi (IN)
- Universidad de Buenos Aires (AR)
- University of Technology Sydney (AU)
- Indiana State University (US)
- Australian National University (AU)
- KTH Royal Institute of Technology (SE)
- DELL (United States) (US)
- Ben-Gurion University of the Negev (IL)
- Donald & Barbara Zucker School of Medicine at Hofstra/Northwell (US)
- Cohere (Canada) (US)
- University of Pennsylvania (US)
- Toyota Technological Institute at Chicago (US)
- Northeastern University (US)
- Case Western Reserve University (US)
- University of Windsor (CA)
- St. Jude Children's Research Hospital (US)
- Rochester Institute of Technology (US)
- Emory University (US)
- Anthropic (United States) (US)
- European Organization for Nuclear Research (CH)
- University of California, Santa Barbara (US)
- Hewlett Packard Enterprise (United States) (US)
- North Carolina State University (US)
- All India Institute of Medical Sciences (IN)
- Tel Aviv University (IL)
- Georgia Institute of Technology (US)
- Northwestern University (US)
- University of Arizona (US)
- University of Lisbon (PT)
- Indian Institute of Technology Kharagpur (IN)
- Posts and Telecommunications Institute of Technology (VN)
- Duke University (US)
- Mila - Quebec Artificial Intelligence Institute (CA)
- University College London (GB)
- University of Zurich (CH)
- University of Padua (IT)
- Boston University (US)
- Royal Veterinary College (GB)
- Instituto Superior Técnico (PT)
- The Ohio State University (US)
- Cairo University (EG)
- Universitat de València (ES)
- Monash University (AU)
- The University of Texas at Dallas (US)
- Canadian University of Dubai (AE)
- Hebrew University of Jerusalem (IL)
- University of Milano-Bicocca (IT)
- University of Massachusetts Lowell (US)
- Virginia Tech (US)
- University of Geneva (CH)
- Laboratoire d'Informatique, de Robotique et de Microélectronique de Montpellier (FR)
- Google (United States) (US)
- California Polytechnic State University (US)
- University of Mannheim (DE)
- Stockholm University (SE)
- Eastern Idaho Technical College (US)
- University of Tennessee at Knoxville (US)
- Johns Hopkins University (US)
- University of Amsterdam (NL)
- Fraunhofer-Einrichtung für Individualisierte Medizintechnik (DE)
- University of Pisa (IT)
- Georgia State University (US)
- Polytechnic University of the Philippines (PH)
- University of Oregon (US)
- Drexel University (US)
- University of Mumbai (IN)
- Gakushuin University (JP)
- University of Guelph (CA)
- Intuit (United States) (US)
- Centre Tecnologic de Telecomunicacions de Catalunya (ES)
- Temple University (US)
- École Normale Supérieure de Lyon (FR)
- Cisco Systems (United States) (US)
- Indian Institute of Technology BHU (IN)
- Google DeepMind (United Kingdom) (GB)
- The University of Texas at Arlington (US)
- University of Vienna (AT)
- Universitatea Națională de Știință și Tehnologie Politehnica București (RO)
- Ollscoil na Gaillimhe – University of Galway (IE)
- Eastern Institute of Technology (NZ)
- Czech Technical University in Prague (CZ)
- Universität Hamburg (DE)
- Helmholtz Center for Information Security (DE)
- Universidad de Morón (AR)
- Université Paris Cité (FR)
- Politecnico di Milano (IT)
- The New School (US)
- Universidad de Granada (ES)
- Quinn
- Heidelberg University (DE)
- La Trobe University (AU)
- Université de Yaoundé I (CM)
- Universität Innsbruck (AT)
- Tony
- Chalmers University of Technology (SE)
- Children's Hospital of Orange County (US)
- Centro de Investigación Científica y de Educación Superior de Ensenada (MX)
- University of Bradford (GB)
- Beni-Suef University (EG)
- Boğaziçi University (TR)
- Mansoura University (EG)
- Hospital for Sick Children (CA)
- University of Bristol (GB)
- University of Oklahoma (US)
- University of Arkansas at Fayetteville (US)
- Florida Atlantic University (US)
- Bournemouth University (GB)
- University of Warwick (GB)
- University of Alabama in Huntsville (US)
- University of Hertfordshire (GB)
- OncoPrecision (United States) (US)
- Central College (US)
- Nottingham Trent University (GB)
- Max Planck Institute for Intelligent Systems (DE)
- University of Virginia (US)
- Dartmouth College (US)
- Instituto de Engenharia de Sistemas e Computadores Microsistemas e Nanotecnologias (PT)
- James Madison University (US)
- Instituto Gonçalo Moniz (BR)
- Rice University (US)
- Rutgers, The State University of New Jersey (US)
- École Polytechnique (FR)
- Quod
- National Technological University (AR)
- John Crane (United States) (US)
- The Alan Turing Institute (GB)
- Puducherry Technological University (IN)
- Leibniz Institute for Science and Mathematics Education (DE)
- Royal Holloway University of London (GB)
- Tanta University (EG)
- University of Malaya (MY)
- Hemwati Nandan Bahuguna Garhwal University (IN)
- Mohamed I University (MA)
- Northern Illinois University (US)
- Bethune-Cookman University (US)
- University of California, Irvine (US)
- Central Mindanao University (PH)
- University of the Fraser Valley (CA)
- Missouri University of Science and Technology (US)
- CSMSS Chh. Shahu College of Engineering (IN)
- Sheffield Teaching Hospitals NHS Foundation Trust (GB)
- RMIT University (AU)
- German Research Centre for Artificial Intelligence (DE)
- University of Trento (IT)
- Chulalongkorn University (TH)
- Aligarh Muslim University (IN)
- University of Southern California (US)
- Menoufia University (EG)
- Instituto Politécnico Nacional (MX)
- University of Bologna (IT)
- Manipal University Jaipur (IN)
- OpenAI (United States) (US)
- The University of Texas at Austin (US)
- Murdoch University (AU)
- University of Delaware (US)
- Williams College (US)
- University of Maribor (SI)
- Fondazione Bruno Kessler (IT)
- Brigham and Women's Hospital (US)
- The University of Tokyo (JP)
- Vellore Institute of Technology University (IN)
- Centre Hospitalier Régional et Universitaire de Nancy (FR)
- Delft University of Technology (NL)
- Scripps Research Institute (US)
- Atilim University (TR)
- Leonardo (Italy) (IT)
- Complexity Science Hub (AT)
- Universidad Nacional de Educación a Distancia (ES)
- Saxion (NL)
- Korea Advanced Institute of Science and Technology (KR)
- Adobe Systems (United States) (US)
- National Aerospace University – Kharkiv Aviation Institute (UA)
- University of Bern (CH)
- University of North Carolina at Chapel Hill (US)
- University of Groningen (NL)
- Jagiellonian University (PL)
- Universitat Politècnica de València (ES)
- Royal Bank of Canada (CA)
- Mayo Clinic (US)
- Imperial College London (GB)
- University of Lausanne (CH)
- Dalhousie University (CA)
- Universitat de Lleida (ES)
- Amazon (United States) (US)
- University of California, Santa Cruz (US)
- University of Seoul (KR)
- University of Auckland (NZ)
- Korea University of Technology and Education (KR)
- University of California, Davis (US)
- Baylor College of Medicine (US)
- Indraprastha Institute of Information Technology Delhi (IN)
- New Jersey Institute of Technology (US)
- Purdue University West Lafayette (US)
- Utrecht University (NL)
- University of Klagenfurt (AT)
- Max Planck Institute for Security and Privacy (DE)
- Goethe University Frankfurt (DE)
- Universidad del Valle (CO)
- Bilkent University (TR)
- Universitat Pompeu Fabra (ES)
- The University of Melbourne (AU)
- Ankara University (TR)
- AIT Austrian Institute of Technology GmbH (AT)
- Providence College (US)
- University of Jyväskylä (FI)
- Weizmann Institute of Science (IL)
- Indiana University Bloomington (US)
- Nanyang Technological University (SG)
- University of Sheffield (GB)
- Centre Inria de l'Université de Lille (FR)
- Corresponding author
- Phan, Long
- Hendrycks, Dan
- ORCID
- Gatti, Alice
- Zhang, Hugh
- Zhang, Chen Bo Calvin
- Ren, Richard
- Zhang, Oliver
- Nguyen, Tung
- Anderson, Daron
- Mahmood, Mobeen
- Iskra, Oleg
- Zhao, Haoran
- Yu, Michael
- Wang, Zihan
- Popov, Serguei
- Schmitt, Johannes
- Yeadon, Will
- Roth, Marc
- Riis, Søren
- Burns, Noah
- Goshu, Gashaw M.
- Naiya, Mohinder Maheshbhai
- Fournier-Facio, Francesco
- Cheng, Zerui
- Park, Hyunwoo
- Gehrunger, Tim
- Garretson, Alexis C
- Sileo, Damien
- Li, Lianghui
- Nam, Jungbae
- Shi, Jack Wei Lun
- Bacho, Aras
- Willcocks, Chris G.
- Cao, Hangrui
- Veith, Johannes
- Vendrow, Edward
- Zenitani, Kengo
- Li, Yuqi
- Vendrow, Joshua
- Kuchkin, Vladyslav
- Efremov, Denis
- Lynch, Jayson
- Gritsevskiy, Andrew
- Guillod, Julien
- Martinez, Dakotah
- Zhou, Kevin
- Tang, Henry
- Rissone, Paolo
- Twayana, Moon
- Dieuleveut, Aymeric
- Imperial, Joseph Marvin
- Yang, Jinzhou
- Zvonkine, Dimitri
- Loiseau, Gabriel
- Manolescu, Ciprian
- Hogg, Tad
- Jin, Jaehyeok
- Sayous, Rafael
- Schwaller, Philippe
- Bran, Andres M
- Algaba, Andres
- Houte, Kelsey Van den
- Verbeken, Brecht F.
- Schut, Lisa
- Zheltonozhskii, Evgenii
- Lim, Derek
- Stanley, Richard
- Yang, Tong
- Maar, John
- Wykowski, Julian
- Ardito, Cesare Giulio
- Hu, Yuzheng
- Lackner, Martin
- Koppel, James
- Antonenko, Daniil S.
- Li, Daofeng
- Crisostomi, Donato
- Zhang, Wenjin
- Perrella, David
- Zang, Allen
- Sucholutsky, Ilia
- Kharlamova, Arina
- Orel, Daniil
- Ben-David, Shalev
- Munro, Daniel
- Sivarajan, Shankar
- Holmes, David
- Sommerhage, Frank
- Zhang, Anji
- Moat, Richard
- Kim, Dae Hyun
- Dias, Felipe Meneguitti
- Elser, Veit
- Kreiman, Tobias
- Rawal, Kaivalya
- Nguyen, Jeremy
- Daans, Nicolas
- Heidinger, Haline
- Rozhoň, Václav
- Ginis, Vincent
- Stump, Christian
- Cohen, Niv
- Poświata, Rafał
- Tkadlec, Josef
- Wang, Chenguang
- Padlewski, Piotr
- Stendall, Ryan
- Tucker-Foltz, Jamie
- Stade, Jack
- Rogers, T. Ryan
- Goertzen, Tom
- Grabb, Declan
- Givré, Alan
- Inlow, Mark H
- Zhang, Ling
- Kaddar, Younesse
- Chen, Yanxu
- Wang, Harrison K
- Thornley, Elliott
- Terpin, Antonio
- Carmi, Avishy
- Brown, Ethan D. L.
- Bartolo, Max
- Wheeler, Richard
- Stehberger, Martin
- Bradshaw, Peter
- Sridhar, Kaustubh
- Sandlin, Jennifer
- Makarychev, Yury
- Redenti, Andrew
- Aldous, David
- Lai, Jesyin
- Xu, Jiangnan
- Magoulas, Ilias
- Cohen, Michael K.
- Paradise, Orr
- Kirchner, Jan Hendrik
- Ovchynnikov, Maksym
- Matos, Jason O.
- Faraboschi, Paolo
- Crozier, Jonathan
- Andréoletti, Jérémy
- Khoury, Seri
- Piccardo, Marco
- Mostaghimi, Hamid
- Chen, Qijia
- Szlyk, Hannah
- Narayan, Himanshu
- Lamparth, Max
- Reuel, Anka
- Xin, Linwei
- Xu, Hanmeng
- Wang, Zixuan
- Achilleos, Andrea
- Bosio, Ida
- Lo, Eve J. Y.
- Wang, Jiaqi
- Milbauer, Jeremiah
- Wang, Zihao
- Ansarinejad, Behzad
- Tordera, Daniel
- Sakor, Ahmad
- Zhou, Xiaoxiang
- Kamalov, Firuz
- Abdoli, Sherwin
- Santens, Tim
- Zhang, Robin
- Tomasiello, Alessandro
- Kolt, Noam
- Pan, Jiayi
- Rodman, Emma
- Fossum, Carl J
- Muennighoff, Niklas
- Jagota, Milind
- Pradeep, Ronak
- Gross, Jason
- Pandey, Rohan
- Gusev, Ilya
- Agnihotri, Shashank
- Zhelnov, Pavel
- Zhang, David K.
- Soroko, Ignat
- Taamazyan, Vage
- Ma, Wenjie
- Lengler, Johannes
- Jackson, Joseph W.
- Kretov, Egor
- Farhidi, Faraz
- Pyda, Daniel
- Sakal, Taom
- Dhamane, Omkar
- Mirabadi, Ali Khajegili
- Maghsoudimehrabani, Mohammad
- Pereira, Roberto
- Weber, Simon
- Peristyy, Anton
- Malina, Stephen
- Mehkary, Mustafa
- Friday, Cary
- Singh, Mukhwinder
- Shapourian, Hassan
- Costa, Mariana
- Ceconello, Chiara
- Park, Haon
- Carroll, Micah
- Tawfeek, Andrew R.
- Steinerberger, Stefan
- Aggarwal, Daattavya
- Kirchhof, Michael
- Kim, Evan
- Shah, Jainam
- Yan, Minghao
- Pham, Diana T.
- Loh, Kang Yong
- Giordano, Paolo
- Petersen, Philipp
- Cosma, Adrian
- Votava, Jacob
- Delaney, Ethan
- Shahid, Syed M.
- Mourrat, Jean-Christophe
- Vetoshkin, Lavr
- Sponselee, Koen
- Bacho, Renas
- Yong, Zheng-Xin
- de la Rosa, Florencia
- Li, Xiuyu
- Malod, Guillaume
- Weller, Orion
- Albani, Guglielmo
- Laurendeau, Julien
- Kazakov, Dmitry
- Adesanya, Fatimah
- Hollom, Lawrence
- Obikoya, Gbenga Daniel
- Bigi, Filippo
- Recchia, Gabriel
- Shulga, Nikita
- Amaro, Brian
- Wang, Ting
- Kratish, Yosi
- Gopi, Sivakanth
- Caciolai, Andrea
- de Witt, Christian Schroeder
- Hernández-Cámara, Pablo
- Rodolà, Emanuele
- Williamson, Dominic
- Fan, Jingxuan
- Martinson, Sarah
- Hausknecht, Kaylie
- Brenner, Michael P.
- Mao, Mao
- Demian, Christoph
- Kassani, Peyman
- Zhang, Xinyu
- Tan, Justin
- Maayan, Gabe
- Mariji, Hodjat
- Wu, Wentao
- Alarab, Ismail
- Johnson, Bryan
- Moyano, Alejandro José
- Malysheva, Yana
- Pottmaier, Daphiny
- Lorena, Ricardo
- Iyer, Krishnamurthy
- Qin, Juehang
- Lindsey, Jack
- Jallon, Antoine
- Chen, Evan
- Lewark, Lukas
- Albanie, Samuel
- Clavier, Pierre
- Jiang, Xi
- Gonzalez, Juan
- Mavroudis, Vasilios
- Xu, Justin
- Goswami, Laxman Prasad
- Bugas, Daniel
- Jansen, Thorben
- Singh, Ankit
- Berkani, Mohammed
- Zhang, Gang
- Habibi, Farzad
- Łucki, Jakub
- Hoover, Alex
- Chhablani, Gunjan
- Jiang, Yibo
- Maheshwari, Rajat
- Mündler, Niels
- Arnaboldi, Luca
- Siddiqi, Muhammad Rehan
- Radhakrishnan, Anil
- Enyekwe, Innocent
- Rossbach, Vivien
- Sparrow, Claire
- Singer, Eric
- Duclosel, Darling
- Bezzi, Dario
- Shah, Imad Ali
- Jin, Jun
- EL-Wasif, Zienab
- McGowan, Joseph
- Sun, Hao-Yu
- Zubić, Nikola
- Sala, Samuele
- Ebert, Stephen
- Schottdorf, Manuel
- Medved, Tilen
- Hebbar, S Ashwin
- Vaquero, Lorenzo
- Zouhar, Vilém
- Zhang, Mingfang
- Dai, Yinwei
- Nhu, Anh N.
- Jia, Zhibai
- Zhou, Yuyin
- He, Mike
- Luo, Gaoxiang
- Noyé, Mickaël
- Perełkiewicz, Michał
- Purohit, Soham Sachin
- Li, Hanchen
- Dhole, Kaustubh
- Park, Jongee
- Abbondanza, Dario
- Caetano, Diogo M.
- Wong, Antonio A. W. L.
- Kondor, Dániel
- Chalstrey, Ed
- Reddish, Jenny
- Rodrigo-Ginés, Francisco-Javier
- Zhang, Qizheng
- Kim, Hyunjun
- Sun, Ruiji
- Dernoncourt, Franck
- Krishna, Satyapriya
- Rismanchian, Sina
- Pu, Bonan
- Overholt, Kalon J.
- Pang, Tony CY
- Huber, Lukas S.
- Jaeger, Joshua
- Lù, Xing Han
- Zhang, Yuhui
- Kon, Patrick Tser Jern
- Li, Sean
- Sanker, Vivek
- Yin, Ming
- Zhang, Xinlu
- Agrawal, Ankit
- Cai, Mu
- Sonmez, Yasin
- Li, Changhao
- Yu, Shoubin
- Sarti, Gabriele
- Briański, Marcin
- Zhang, Mike
- Juefei-Xu, Felix
- Zohar, Orr
- Jiang, Muyan
- Kreuer, Jules
- Rabern, Brian
- Plassart, Anna
- Maggetti, Martino
- Yap, Luther
- Geirhos, Robert
- Wang, Dingsu
- Yin, Yifan
- Wei, Anjiang
- Wang, Xiaohan
- Arrais, Alexandre Oliveira
- Mukherjee, Kushin
- Chamorro-Padial, Jorge
- Liu, Jiachen
- Guan, Junyi
- Bouyamourn, Adam
- Chen, Haoxuan
- Ren, Yinuo
- Tu, Haoqin
- Marjanović, Sara Vera
- Ha, Junwoo
- Ma, Jeff J.
- Shen, Zewen
- Wang, Zhun
- Lee, Kwok Hao
- Ye, Zhe
- Ermon, Stefano
- Lopez-Miguel, Ignacio D.
- Gitter, Anthony
- Chen, Hongzheng
- Mishra, Ritwik
- Zsolnai-Fehér, Károly
- Jiang, Xilin
- Malusare, Aditya
- Tang, Maosen
- Dworakowska, Barbara
- Chernyavsky, Igor
- Banik, Deepayan
- Dong, Wenchao
- Hu, Wei
- Bar, Kaushik
- Dhuliawala, Shehzaad
- Wist, Julien
- Kansal, Yuval
- Yücel, Atak Talay
- Singla, Veerupaksh
- Song, Zijian
- Chen, Sanxing
- Ge, Jiaxin
- Cheng, Zhuo
- Zhu, Zhanda
- Zhang, Ziyi
- Wu, Jiaxuan
- Zhang, Tianchi
- Vieira, Bruno Hebling
- Aji, Alham Fikri
- Chung, Jae-Won
- Hao, Wei
- Meding, Kristof
- Xu, Sihan
- Kostakos, Vassilis
- Yu, Eunmi
- Bailey, James
- Heilala, Ville
- Chen, Peter E.
- Venugopalan, Subhashini
- Batra, Hunar
- Zhang, Genghan
- Liang, Yizhuo
- Bartlett, Christopher W.
- Scotese, Christopher R.
- Cao, Phuong M.
- Karwowski, Jacek
- Scaramuzza, Davide
- Agrawal, Rishit
- Singh, Aryan
- Zhang, Alex
- Nguyen, Leon
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2025
- Volume
- 649
- Issue
- 8099
- Pages
- 1139-1146
- ISSN
- 0028-0836 (ISSN-L)
- arXiv
- 2501.14249
- PMC
- PMC12851929
- OpenAlex
- W4406840771
- Semantic Scholar
- a5524d085ac586d531021dcb1ec156eaf942b109
- Cited by
- 65
- References
- 14
- Citations by year
- 2026: 51 · 2025: 14
- FWCI
- 174.28
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Nature (publishedVersion, cc-by-nc-nd)
- Research Square (acceptedVersion, cc-by)
- Europe PMC (PubMed Central) (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- RiuNet (Universitat Politècnica de València) (publishedVersion, cc-by-nc-nd)
- Repository for Publications and Research Data (ETH Zurich) (publishedVersion, cc-by-nc-nd)
- SHURA (Sheffield Hallam University Research Archive) (Sheffield Hallam University) (acceptedVersion)
- Open Research Online (The Open University) (acceptedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by)
- HAL (submittedVersion, other-oa)
- CERN Document Server (European Organization for Nuclear Research) (submittedVersion, cc-by-nc-nd)
- Jyväskylä University Digital Archive (University of Jyväskylä) (submittedVersion, cc-by-nc-nd)
- Lirias (KU Leuven) (submittedVersion, cc-by-nc-nd)
- Tuwhera (Auckland University of Technology) (submittedVersion, cc-by-nc-nd)
- Open Repository and Bibliography (University of Luxembourg) (submittedVersion, other-oa)
- Research Explorer (The University of Manchester) (submittedVersion)
- VUBIR (Vrije Universiteit Brussel) (submittedVersion, cc-by)
- KTH Publication Database DiVA (KTH Royal Institute of Technology) (submittedVersion, other-oa)
- Infoscience (Ecole Polytechnique Fédérale de Lausanne) (submittedVersion)
- Publication Server of Goethe University Frankfurt am Main (Goethe University Frankfurt) (submittedVersion, cc-by)
- Research Explorer (The University of Manchester) (submittedVersion, cc-by-nc-nd)
- Edinburgh Research Explorer (University of Edinburgh) (submittedVersion, other-oa)
- Virtual Community of Pathological Anatomy (University of Castilla La Mancha) (submittedVersion)
- Repositori digital de la UPF (Universitat Pompeu Fabra) (submittedVersion, cc-by-nc-nd)
- VUBIR (Vrije Universiteit Brussel) (submittedVersion)
- arXiv (Cornell University) (cc-by)
- Funders
- Office of Science (DE-AC02-06CH11357)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- large language models, benchmarking, automated grading, question difficulty
- MeSH terms
- Artificial Intelligence, Educational Measurement, Humans, Language, Benchmarking
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol and qwen3.8-omni-flash).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Humanity's Last Exam. https://app.cochat.ai/papers/10.48550/arxiv.2501.14249
- The paper
- Phan, L., Gatti, A., Han, Z., Li, N., Hu, J., Zhang, H., Zhang, C. B. C., Shaaban, M., Ling, J., Shi, S., Choi, M., Agrawal, A., Chopra, A., Khoja, A., Kim, R., Ren, R., Hausenloy, J., Zhang, O., Mazeika, M., . . . Hendrycks, D. (2025). Humanity's Last Exam. arXiv. https://doi.org/10.48550/arxiv.2501.14249
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
