

The DOI matches its Crossref record; 15 of the 15 references it cites were found in a registry or an index; none of the 1 sources its claims cite is checked for support yet.
ChatGPT outperforms crowd workers for text-annotation tasks
Open accessAbstract
Many NLP applications require manual text annotations for a variety of tasks, notably to train classifiers or evaluate the performance of unsupervised models. Depending on the size and degree of complexity, the tasks may be conducted by crowd workers on platforms such as MTurk as well as trained annotators, such as research assistants. Using four samples of tweets and news articles ( n = 6,183), we show that ChatGPT outperforms crowd workers for several annotation tasks, including relevance, stance, topics, and frame detection. Across the four datasets, the zero-shot accuracy of ChatGPT exceeds that of crowd workers by about 25 percentage points on average, while ChatGPT’s intercoder agreement exceeds that of both crowd workers and trained annotators for all tasks. Moreover, the per-annotation cost of ChatGPT is less than $0.003—about thirty times cheaper than MTurk. These results demonstrate the potential of large language models to drastically increase the efficiency of text classification.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
Using four datasets of tweets and news articles (n = 6,183), the paper finds that zero-shot ChatGPT annotations outperform MTurk crowd workers on several text-annotation tasks and achieve higher intercoder agreement than both crowd workers and trained annotators. ChatGPT is also far cheaper, at less than $0.003 per annotation, about thirty times cheaper than MTurk.
Key findings
- Across four datasets, ChatGPT’s zero-shot accuracy exceeds MTurk’s by about 25 percentage points on average, and it outperforms MTurk for most tasks.
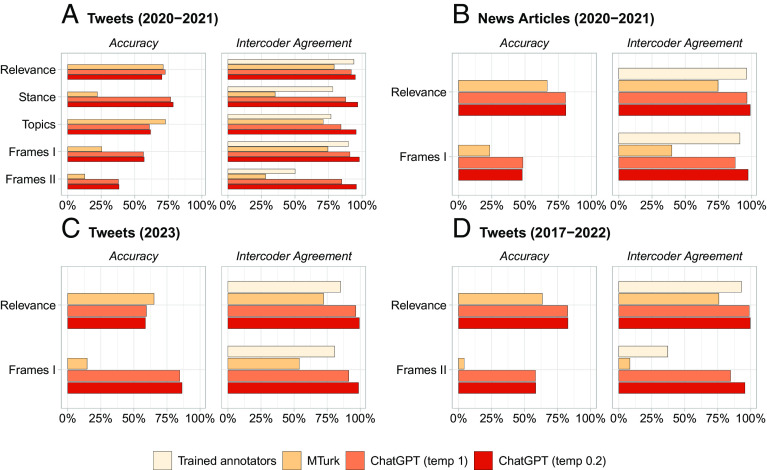
- ChatGPT’s intercoder agreement averages 91% at temperature = 1 and 97% at temperature = 0.2, compared with about 56% for MTurk and 79% for trained annotators.
- Relevance-task accuracy rates were 70% for content moderation tweets, 81% for content moderation news articles, 83% for US Congress tweets, and 59% for 2023 content moderation tweets.
- Per-annotation cost for ChatGPT is less than $0.003, about thirty times cheaper than MTurk. Correlations reported: intercoder agreement and accuracy r = 0.36; ChatGPT accuracy and trained-annotator intercoder agreement r = 0.46; ChatGPT overperformance vs. MTurk and trained-annotator intercoder agreement r = −0.37.
Methods
- Design: compare zero-shot ChatGPT annotations against MTurk crowd workers and trained annotators on the same codebooks and tasks, using trained annotators as the gold standard.
- Data: four datasets totaling n = 6,183, including a random sample of 2,382 content-moderation tweets from 2020–2021; 1,856 US Congress tweets from 2017–2022; 1,606 newspaper articles on content moderation from 2020–2021; and 500 tweets from January 2023, of which 339 were in English.
- Analysis: tasks included relevance, topic detection, stance, general frame detection, and policy frame detection. ChatGPT used the “gpt-3.5-turbo” API with temperature 1 and 0.2, two responses per temperature per tweet, and a new chat session for every tweet. MTurk workers were restricted to “MTurk Masters,” >90% HIT approval rate with at least 50 approved HITs, and US location. Metrics were accuracy against trained annotators and intercoder agreement.
Limitations
- The paper states that further research is needed to understand how ChatGPT and other LLMs perform in a broader range of contexts, and it lists future questions including multiple languages, few-shot learning, semiautomated labeling, chain-of-thought prompting, and comparison across LLM types.
- The paper states that in the 2023 sample, ChatGPT struggled with misclassifying tweets about specific user suspensions in the relevance task due to a lack of examples in the prompt, underscoring the importance of high-quality prompts.
- Evident from the text: the evaluation uses one ChatGPT model version (“gpt-3.5-turbo”) and does not report testing in languages other than English; the paper itself lists performance across multiple languages as a future question.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
10 Own result · 8 Own method · 7 Own interpretation · 2 No basis given · 1 Not checked yet
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Regarding accuracy, Fig. 1 shows that ChatGPT outperforms MTurk for most tasks across the four datasets.”
- Also stated in: § Abstract · plain
“We find that across the four datasets, ChatGPT’s zero-shot accuracy is higher than that of MTurk for most tasks.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Abstract · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“ChatGPT’s intercoder agreement exceeds that of both crowd workers and trained annotators for all tasks.”
- Also stated in: § Abstract · plain
“For all tasks, ChatGPT’s intercoder agreement exceeds that of both MTurk and trained annotators.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Abstract
plaincorrelationaln = 4- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Abstract · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“ChatGPT’s accuracy is positively correlated with the intercoder agreement of trained annotators (Pearson’s r = 0.46), suggesting better performance for easier tasks.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Conversely, ChatGPT’s outperformance of MTurk is negatively correlated with the intercoder agreement of trained annotators (Pearson’s r = -0.37), potentially indicating stronger overperformance for more complex tasks.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Across the four datasets, the zero-shot accuracy of ChatGPT exceeds that of crowd workers by about 25 percentage points on average”
- Also stated in: § Results · plain
“On average, ChatGPT’s accuracy exceeds that of MTurk by about 25 percentage points.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Abstract
plaincorrelationaln = 4- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Results · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The correlation between intercoder agreement and accuracy is positive (Pearson’s r = 0.36).”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This paper demonstrates the potential of LLMs to transform text-annotation procedures for a variety of tasks common to many research projects.”
- Also stated in: § Abstract · boosted
“These results demonstrate the potential of large language models to drastically increase the efficiency of text classification.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Discussion
boostedconditionaln = 4- Asserted: passes — The authors put it forward as true.
- Checkable: unclear — It is unclear whether it could be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Abstract · boosted
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“While these findings do not suggest that memorization is a major issue, they underscore the importance of high-quality prompts.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption: The 2023 tweets were not included in ChatGPT's training data.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Conversely, ChatGPT’s outperformance of MTurk is negatively correlated with the intercoder agreement of trained annotators (Pearson’s r = -0.37), potentially indicating stronger overperformance for more complex tasks.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“ChatGPT’s accuracy is positively correlated with the intercoder agreement of trained annotators (Pearson’s r = 0.46), suggesting better performance for easier tasks.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- It may state two separate claims as one. 8
- Probably not a substantial claim. 10
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“In the 2023 sample, ChatGPT performed much better than MTurk in the second task but struggled with misclassifying tweets about specific user suspensions in the relevance task due to a lack of examples in the prompt.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“On average, intercoder agreement is about 56% for MTurk, 79% for trained annotators, 91% for ChatGPT with temperature = 1, and 97% for ChatGPT with temperature = 0.2.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Accuracy rates for relevance tasks, with two classes (relevant/irrelevant) are 70% for content moderation tweets, 81% for content moderation news articles, 83% for US Congress tweets, and 59% for 2023 content moderation tweets.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Using four samples of tweets and news articles (n = 6,183), we show that ChatGPT outperforms crowd workers for several annotation tasks, including relevance, stance, topics, and frame detection.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Abstract
plainn = 4- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Moreover, the per-annotation cost of ChatGPT is less than $0.003—about thirty times cheaper than MTurk.”
- Also stated in: § Abstract · plain
“ChatGPT’s per-annotation cost is about $0.003 or a third of a cent—about thirty times cheaper than MTurk, with higher quality.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Abstract
plainn = 6,183- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Abstract · plain
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“The evidence is consistent across different types of texts and time periods.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The sample size was determined by the number of texts needed to build a training set for a machine learning classifier.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Materials and Methods > Datasets.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This suggests that a lower temperature value may be preferable for annotation tasks, as it seems to increase consistency without decreasing accuracy.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Moreover, we ensured that no worker could annotate more than 20% of the tweets for a given task.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Materials and Methods > Crowd Workers.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We intentionally avoided adding any ChatGPT-specific prompts to ensure comparability between ChatGPT and MTurk crowd workers.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Materials and Methods > ChatGPT.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“Moreover, some of the tasks involve a large number of classes and exhibit lower levels of intercoder agreement, which indicates a higher degree of annotation difficulty (11).”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Results
What the sources say
- Not checked yetcites [11] P. S. Bayerl, K. I. Paul, What determines inter-coder agreement in manual annotations? A meta-analytic investigation Comput. Linguist. 37, 699– 725 (2011).
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“As with the trained human annotators, each tweet was annotated by two different crowd workers.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Materials and Methods > Crowd Workers.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The coders annotated the tweets independently task by task.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Materials and Methods > Trained Annotators.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“First, we computed average accuracy (i.e., percentage of correct predictions), that is, the number of correctly classified instances over the total number of cases to be classified, using trained human annotations as our gold standard and considering only texts that both annotators agreed upon.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Materials and Methods > Evaluation Metrics.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“To ensure annotation quality, we restricted access to the tasks to workers who are classified as “MTurk Masters” by Amazon, who have an HIT (Human Intelligence Task) approval rate greater than 90% with at least 50 approved HITs, and who are located in the United States.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Materials and Methods > Crowd Workers.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We created a new chat session for every tweet to ensure that the ChatGPT results are not influenced by the history of annotations.”
§ ChatGPT outperforms crowd workers for text-annotation tasks > Materials and Methods > ChatGPT.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper relies on this without support.
The trained annotators' annotations constitute a valid gold standard for correctness.
“using trained human annotations as our gold standard”
“using our trained annotators as a benchmark”
The paper relies on this without support.
The 2023 tweets were not included in ChatGPT's training data.
“a new sample of tweets posted in 2023 to address the concern that ChatGPT might be relying on memorization for texts potentially included in the model’s training dataset.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“LLMs have been shown to perform well on diverse text-analysis tasks 36 , often matching or exceeding state-of-the-art models and crowd workers 37,38 , even with zero-shot prompts 39 .”
From Quantifying the prevalence and impact of overreaching causal claims in social science (2026) · cites this paper as [38]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“we employ GPT-4 for automated evaluation, where both the generated hypotheses and the provided background are evaluated across these aspects.”
From Large Language Models as Biomedical Hypothesis Generators: A Comprehensive Evaluation (2024) · cites this paper as Gilardi et al., 2023
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“These models mitigate many of the above mentioned limitations associated with human coders by leveraging their computational efficiency, consistency, and scalability [34–36].”
From The quantum technology job market: data driven analysis of 3641 job posts (2026) · cites this paper as [34]
The cited source says what the claim attributes to it.
In the citing paper
“LLM-assisted annotation shows a similar tension: LLMs can match or outperform crowd workers on some text-classification tasks, yet may introduce systematic bias in qualitative coding (Ashwin et al., 2025;Gilardi et al., 2023).”
From Beyond Human-Likeness: Mapping the Scientific Critique Profiles of LLMs and Human Reviewers (2026) · cites this paper as Gilardi et al., 2023
The cited source says what the claim attributes to it.
In the citing paper
“Prior studies have also reported that LLM evaluations can be competitive with crowdworker annotations (Gilardi et al., 2023).”
From MAPLE: Multi-Aspect Panels of LLM Evaluators for Open-Ended Questions (2026) · cites this paper as Gilardi et al., 2023
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“LLM-assisted annotation shows a similar tension: LLMs can match or outperform crowd workers on some text-classification tasks, yet may introduce systematic bias in qualitative coding (Ashwin et al., 2025;Gilardi et al., 2023).”
From Beyond Human-Likeness: Mapping the Scientific Critique Profiles of LLMs and Human Reviewers (2026) · cites this paper as Gilardi et al., 2023
Experimental — accuracy not yet measuredIn the citing paper
“They find this model performs better than human workers trained with such materials on Amazon Mechanical Turk—though such coders are known to be less accurate than those trained directly by researchers in small group settings.”
From Can Generative AI improve social science? (2024) · cites this paper as [51]
In the citing paper
“Gilardi et al. argue GPT 3.5-turbo can accurately measure the topic of tweets, the stance or opinions of their authors, and the “frames” used to organize the message in a narrative manner (51).”
From Can Generative AI improve social science? (2024) · cites this paper as [51]
In the citing paper
“Some LLMs have been found as good as human annotators [41] in some tasks.”
From Harnessing the power of llms in practice: a survey on chatGPT and beyond (2024) · cites this paper as [41]
Citations
Cites
Large Language Models are Zero-Shot Reasoners
Kojima, T., Gu, S. S., Reid, M., Matsuo, Y., & Iwasawa, Y. (2022) · arXiv · doi:10.48550/arxiv.2205.11916 · Cited by 2,013
An MTurk Crisis? Shifts in Data Quality and the Impact on Study Results
Chmielewski, M., & Kucker, S. C. (2020) · Social Psychological and Personality Science · doi:10.1177/1948550619875149 · Cited by 1,027
Out of One, Many: Using Language Models to Simulate Human Samples
Argyle, L. P., Busby, E. C., Fulda, N., Gubler, J. R., Rytting, C., & Wingate, D. (2023) · Political Analysis · doi:10.1017/pan.2023.2 · Cited by 783
Using cognitive psychology to understand GPT-3
Binz, M., & Schulz, E. (2023) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2218523120 · Cited by 559 · cited 2×
“…very well for a wide range of purposes, including ideological scaling (Wu et al., 2023), the classification of legislative proposals (Nay, 2023), the resolution of cognitive psychology tasks, (Binz and Schulz, 2023), and the simulation of human samples for survey research (Argyle et al., 2023).”
BackgroundCrowd-sourced Text Analysis: Reproducible and Agile Production of Political Data
Benoit, K. R., Conway, D., Lauderdale, B. E., Laver, M., & Mikhaylov, S. (2016) · American Political Science Review · doi:10.1017/s0003055416000058 · Cited by 296
Huang, F., Kwak, H., & An, J. (2023) · International World Wide Web Conference (WWW) · doi:10.1145/3543873.3587368 · Cited by 247
Huang, F., Kwak, H., & An, J. (2023) · arXiv · doi:10.48550/arxiv.2302.07736 · Cited by 231
The Media Frames Corpus: Annotations of Frames Across Issues
Card, D., Boydstun, A. E., Gross, J. H., Resnik, P., & Smith, N. A. (2015) · doi:10.3115/v1/p15-2072 · Cited by 224
Kuzman, T., Mozetič, I., & Ljubešić, N. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2303.03953 · Cited by 137
What Determines Inter-Coder Agreement in Manual Annotations? A Meta-Analytic Investigation
Bayerl, P. S., & Paul, K. I. (2011) · Computational Linguistics · doi:10.1162/coli_a_00074 · Cited by 126
Research works printed but not linked: 1
- M. Desmond, E. Duesterwald, K. Brimijoin, M. Brachman, Q. Pan, Semi-automateddatalabeling, in NeurIPS 2020 Competition and Demonstration Track, (PMLR, 2021), pp. 156–169.
Cited by
Sorted by citations
Items 1,001–1,025 of 1,025
New Topic Discovery Using LLM Analysis and Entropy Based Clustering of Short Texts
Detmer, A., Bhatnagar, R., & Aurisano, J. (2025) · IEEE ... International Conference on Data Mining workshops · doi:10.1109/icdmw69685.2025.00139
Chen, J., Chersoni, E., Marelli, M., & Huang, C. (2026) · Cognitive Science · doi:10.1111/cogs.70194
Efficient segmentation of fish in aquaculture with self-developed low-light adaptive camera
Zhao, K., Shen, Y., Chai, R., & Yuan, G. (2026) · Smart Agricultural Technology · doi:10.1016/j.atech.2026.102029
How Information Retrieval Systems Construct and Amplify Immigration Narratives
Masud, Z., Paul, A., Ahmed, S. I., & Ebrahim Bagheri, A. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-21324-2_36
BeigeSage: sentiment classification in economic texts utilizing LLMs and fine-tuned BERT models
Smith, C., & Lambert, J. (2026) · Applied Economics · doi:10.1080/00036846.2026.2647124
Fang, Q., Liu, H., & Zhou, S. (2026) · Electronic Commerce Research · doi:10.1007/s10660-026-10121-8
The Fearless Premium: Workplace Psychological Safety and Stock ReturnsPreprint
Boustanifar, H., & Sheykhi, S. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.6391618
Sio, L. D., Legnante, G., Tuorto, D., Vezzoni, C., Boldrini, M., Bordignon, M., Colombo, A., Angelis, A. D., Leofreddi, A., Maggini, N., et al. (2026) · Frontiers in Political Science · doi:10.3389/fpos.2026.1720542
Peez, A., & Scherzinger, J. (2026) · The Review of International Organizations · doi:10.1007/s11558-026-09620-y
Kolmogorov-Arnold Networkのマーケティング解析への応用可能性の検討 : 従来的な深層学習手法との理論的比較と実データによる購買予測への応用
新美, 潤. (n.d.) · Institutional Repositories DataBase (IRDB)
Wilson, M. C., Martin-Morales, K., & Nelson, G. (2026) · doi:10.33774/apsa-2026-hgrxk
Deep Research on a Loop: Using AI Agents to Construct Economic DatasetsPreprint
Galiani, S., Afonso, S., Gálvez, R. H., & Sosa, R. A. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.6502499
Are Transition and Physical Climate Risks Priced? Evidence from Directional News-Based MeasuresPreprint
Toussaint, C. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.6431199
Professional Brokerage of Limited Legality under AuthoritarianismPreprint
Zu, Z. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.6448958
Wang, Z., Zhang, G., Chen, X., Hao, S., Li, Y., Xiong, G., Yang, Z., Yang, K., Sim, M. Y., & Xu, K. (2026) · Synthesis lectures on human language technologies · doi:10.1007/978-3-032-06264-2_11
Ovádek, M. (2026) · Cambridge University Press eBooks · doi:10.1017/9781009672580.013
Methodology for Design and Analysis of Machine Learning Competitions
Pavão, A. (2023) · theses.fr (ABES) · doi:10.70675/9234d2f0zebc5z4c1czaf3bzb0ad7a481e04
The politics of newswriting : three essays on how journalists cover politics
Shen, R. (2024) · theses.fr (ABES) · doi:10.70675/01d0eae8z52b1z4d10z97d8z8a40763bb73a
Temporal Disorientation of Metro Travellers
Perroy, B. (2024) · theses.fr (ABES) · doi:10.70675/6ff9160ez64e0z4becz86dbze5888d440e69
Using Knowledge Graph To Detect And Explain Misinformation Spread On The Web
Peskine, Y. (2025) · theses.fr (ABES) · doi:10.70675/efad38dcza422z419dz865ez1bc0e700ce2c
Lobbying dynamics and influence
Logeart, R. (2024) · theses.fr (ABES) · doi:10.70675/28096b72z90abz40d0zb55dz42deaf9d0c90
Towards operationalizing nature’s value in Minnesota’s decision-making
Dampha, N. K., Heyn, M., Grant, S. L., & Darboe, K. (2026) · Frontiers in Sustainability · doi:10.3389/frsus.2026.1804253
Dutta, S., Doherty, E. J., & Hirshfield, L. (2026) · CHI Conference Extended Abstracts on Human Factors in Computing Systems (CHI EA) · doi:10.1145/3772363.3799244
DALL: Data Labeling via Data Programming and Active Learning Enhanced by Large Language Models
Li, G., Wang, A., Wang, S., Zhang, Y., Cao, P., Bai, Y., & Liu, C. H. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3791356
Metadata
- Authors
- Gilardi, F., Alizadeh, M., & Kubli, M.
- Affiliations
- Harvard University (US)
- Corresponding author
- Gilardi, Fabrizio
- Venue
- Proceedings of the National Academy of Sciences
- Publisher
- National Academy of Sciences
- Published
- 2023-07-18
- Volume
- 120
- Issue
- 30
- Pages
- e2305016120-e2305016120
- ISSN
- 0027-8424 (ISSN-L)
- 1091-6490
- PMC
- PMC10372638
- OpenAlex
- W4384662964
- Cited by
- 1,197
- References
- 12
- Citations by year
- 2026: 440 · 2025: 356 · 2024: 274 · 2023: 125
- FWCI
- 554.15
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Proceedings of the National Academy of Sciences (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Zurich Open Repository and Archive (University of Zurich) (acceptedVersion, cc-by-nc-nd)
- arXiv (Cornell University) (submittedVersion, cc-by)
- Zurich Open Repository and Archive (University of Zurich) (submittedVersion, other-oa)
- arXiv (Cornell University) (cc-by)
- Zurich Open Repository and Archive (University of Zurich)
- Funders
- EC | European Research Council (883121)
- Topics
- Social Sciences › General Social Sciences › Computational and Text Analysis Methods
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Sentiment Analysis and Opinion Mining
- Keywords
- ChatGPT, large language models, textual annotation, crowd workers, Amazon Mechanical Turk, automatic annotation, inter-coder agreement, annotation cost, stance detection, topic extraction, frame detection, tweets, news articles, text classification
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-09, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-09 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
