

Using AI-generated suggestions from ChatGPT to optimize clinical decision support
Open accessThe DOI matches its Crossref record; 39 of the 39 references it cites were found in a registry or an index.
Abstract
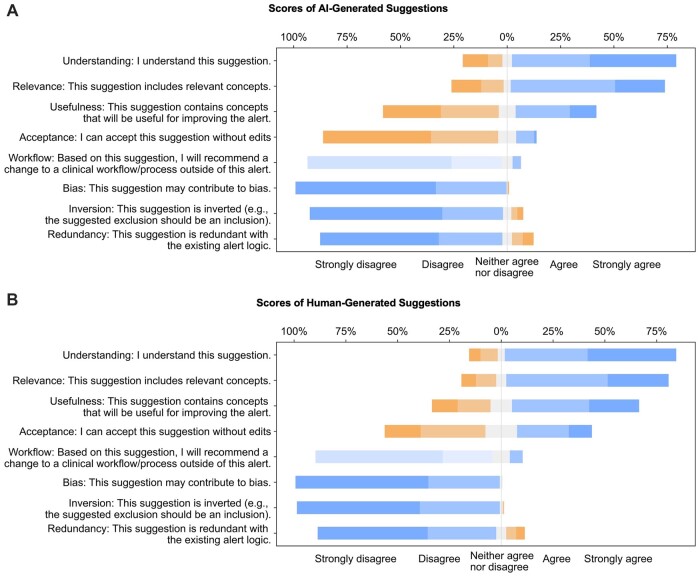
Objective: To determine if ChatGPT can generate useful suggestions for improving clinical decision support (CDS) logic and to assess noninferiority compared to human-generated suggestions. Methods: We supplied summaries of CDS logic to ChatGPT, an artificial intelligence (AI) tool for question answering that uses a large language model, and asked it to generate suggestions. We asked human clinician reviewers to review the AI-generated suggestions as well as human-generated suggestions for improving the same CDS alerts, and rate the suggestions for their usefulness, acceptance, relevance, understanding, workflow, bias, inversion, and redundancy. Results: Five clinicians analyzed 36 AI-generated suggestions and 29 human-generated suggestions for 7 alerts. Of the 20 suggestions that scored highest in the survey, 9 were generated by ChatGPT. The suggestions generated by AI were found to offer unique perspectives and were evaluated as highly understandable and relevant, with moderate usefulness, low acceptance, bias, inversion, redundancy. Conclusion: AI-generated suggestions could be an important complementary part of optimizing CDS alerts, can identify potential improvements to alert logic and support their implementation, and may even be able to assist experts in formulating their own suggestions for CDS improvement. ChatGPT shows great potential for using large language models and reinforcement learning from human feedback to improve CDS alert logic and potentially other medical areas involving complex, clinical logic, a key step in the development of an advanced learning health system.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures


Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“The integration of AI-powered tools into clinical pharmacy practices could bolster efficiency, decision-making, and patient outcomes.9”
From ChatGPT and Clinical Training: Perception, Concerns, and Practice of Pharm-D Students (2023) · cites this paper as [9]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
A guideline of selecting and reporting intraclass correlation coefficients for reliability research
Koo, T. K., & Li, M. Y. (2016) · Journal of Chiropractic Medicine · doi:10.1016/j.jcm.2016.02.012 · Cited by 31,709
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
A General Inductive Approach for Analyzing Qualitative Evaluation Data
Thomas, D. R. (2006) · American Journal of Evaluation · doi:10.1177/1098214005283748 · Cited by 10,858
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Kung, T. H., Cheatham, M., ChatGPT, Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., et al. (2022) · doi:10.1101/2022.12.19.22283643 · Cited by 4,115
Kung, T. H., Cheatham, M., Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., Maningo, J., et al. (2023) · PLOS Digital Health · doi:10.1371/journal.pdig.0000198 · Cited by 4,115
Kawamoto, K., Houlihan, C. A., Balas, E. A., & Lobach, D. F. (2005) · BMJ · doi:10.1136/bmj.38398.500764.8f · Cited by 2,703
Effect of Clinical Decision-Support Systems: A Systematic Review
Bright, T. J., Wong, A., Dhurjati, R., Bristow, E., Bastian, L., Coeytaux, R. R., Samsa, G., Hasselblad, V., Williams, J. W., Musty, M. D., et al. (2012) · Annals of Internal Medicine · doi:10.7326/0003-4819-157-1-201207030-00450 · Cited by 1,200
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.173 · Cited by 1,185
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · arXiv · doi:10.48550/arxiv.2005.00661 · Cited by 1,185
Research works printed but not linked: 1
- de Winter, 2010, Five-point Likert items: t test versus Mann-Whitney-Wilcoxon, Pract Assess Res Eval, 15, 11
Cited by
Items 201–300 of 542
ChatGPT in Oncology Diagnosis and Treatment: Applications, Legal and Ethical Challenges
Zhou, Z., Qin, P., Cheng, X., Shao, M., Ren, Z., Zhao, Y., Li, Q., & Liu, L. (2025) · Current Oncology Reports · doi:10.1007/s11912-025-01649-3 · Cited by 18
Analysis of Privacy Leakage in Federated Large Language ModelsPreprint
Vu, M. N., Nguyen, T., Jeter, T. R., & Thai, M. T. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2403.04784 · Cited by 18
Can Large Language Models Safely Address Patient Questions Following Cataract Surgery?
Chowdhury, M., Lim, E., Higham, A., McKinnon, R., Ventoura, N., He, Y., & De Pennington, N. (2023) · Proceedings of the 5th Clinical Natural Language Processing Workshop · doi:10.18653/v1/2023.clinicalnlp-1.17 · Cited by 17
The AI Genie in the Bottle: Charting AI Evolution and Aversion in Advertising
Feng, Y. (2025) · Journal of Interactive Advertising · doi:10.1080/15252019.2025.2537019 · Cited by 17
Idan, D., Shitrit, I. B., Volevich, M., Binyamin, Y., Nassar, R., Nassar, M., Abelson, N., Zlotnik, A. A., & Einav, S. (2025) · Scientific Reports · doi:10.1038/s41598-025-21689-w · Cited by 17
Clinical application potential of large language model: a study based on thyroid nodules
Xia, S., Hua, Q., Mei, Z., Xu, W., Lai, L., Wei, M., Yu, Q., Luo, L., Wang, C., Huo, S., et al. (2024) · Endocrine · doi:10.1007/s12020-024-03981-3 · Cited by 17
Large Language Model Architectures in Health Care: Scoping Review of Research Perspectives
Leiser, F., Guse, R., & Sunyaev, A. (2025) · Journal of Medical Internet Research · doi:10.2196/70315 · Cited by 17
Sezer, B., & Okutan, A. E. (2025) · BMC Oral Health · doi:10.1186/s12903-025-06791-9 · Cited by 16
Kufel, W. D., Hanrahan, K. D., Seabury, R. W., Parsels, K. A., Gallagher, J. C., MacDougall, C., Covington, E. W., Chahine, E. B., Britt, R. S., & Steele, J. M. (2024) · Open Forum Infectious Diseases · doi:10.1093/ofid/ofae641 · Cited by 16
Zeng, J., Zou, X., Li, S., Tang, Y., Teng, S., Li, H., Wang, C., Wu, Y., Zhang, L., Zhong, Y., et al. (2024) · Journal of Medical Internet Research · doi:10.2196/51095 · Cited by 16
Self-citationNGUYEN, D. L., Kim, G. H. J., & Bedayat, A. (2025) · Clinical Imaging · doi:10.1016/j.clinimag.2025.110551 · Cited by 16
Tutorial: guidance on the use of large language models for medical research
Jin, Q., Wan, N., Leaman, R., Tian, S., Wang, Z., Yang, Y., Wang, Z., Xiong, G., Lai, P.-T., Zhu, Q. L., et al. (2026) · Nature Protocols · doi:10.1038/s41596-026-01408-z · Cited by 16
Large Language Models in Healthcare: A Review
Zou, S., & He, J. (2023) · International Symposium on Computer Science and Intelligent Control (ISCSIC) · doi:10.1109/iscsic60498.2023.00038 · Cited by 15
Ethical considerations for large language models in ophthalmology
Kalaw, F. G. P., & Baxter, S. L. (2024) · Current Opinion in Ophthalmology · doi:10.1097/icu.0000000000001083 · Cited by 15
Chiu, E. K.-Y., & Chung, T. W. (2025) · PLoS ONE · doi:10.1371/journal.pone.0300487 · Cited by 15
Liu, J., Segal, K. R., Daher, M., Ozolin, J., Binder, W. D., Bergen, M. A., McDonald, C. L., Owens, B. D., & Antoci, V. (2025) · Injury · doi:10.1016/j.injury.2025.112297 · Cited by 15
Nurses’ assessment of artificial ıntelligence chatbots for health literacy education
Aşıksoy, G. (2025) · Journal of Education and Health Promotion · doi:10.4103/jehp.jehp_1195_24 · Cited by 15
A Review of the Role of ChatGPT for Clinical Decision Support Systems
Fawzi, S. A. (2023) · Novel Intelligent and Leading Emerging Sciences Conference (NILES) · doi:10.1109/niles59815.2023.10296668 · Cited by 15
ChatGPT-CARE: a Superior Decision Support Tool Enhancing ChatGPT with Clinical Practice GuidelinesPreprint
Wang, Y., Visweswaran, S., Kapoor, S., Kooragayalu, S., & Wu, X. (2023) · medRxiv · doi:10.1101/2023.08.09.23293890 · Cited by 15
Šuto, J., Marušić, A., & Buljan, I. (2025) · JMIR Cancer · doi:10.2196/63347 · Cited by 14
Kim, D., Kang, S., & Hong, A. (2025) · Technovation · doi:10.1016/j.technovation.2025.103374 · Cited by 14
Özbek, İ. C., & Özduran, E. (2026) · Phlebology The Journal of Venous Disease · doi:10.1177/02683555261460252 · Cited by 14
A FOUR-STAGE MODEL OF CHATGPT ADOPTION: APPLICATION IN TOURISM, HEALTHCARE, AND EDUCATION INDUSTRY
(2023) · Issues in Information Systems · doi:10.48009/3_iis_2023_121 · Cited by 14
Ong, J., Hariprasad, S. M., & Chhablani, J. K. (2023) · Ophthalmic surgery, lasers & imaging retina · doi:10.3928/23258160-20230926-01 · Cited by 15
Braun, E.-M., Juhasz‐Böss, I., Solomayer, E., Truhn, D., Keller, C., Heinrich, V., & Braun, B. J. (2023) · Archives of Gynecology and Obstetrics · doi:10.1007/s00404-023-07272-6 · Cited by 14
Razi, A., Bouzoubaa, L. A., Pessianzadeh, A., Seberger, J. S., & Rezapour, R. (2025) · Research Square · doi:10.21203/rs.3.rs-5686084/v1 · Cited by 14
Shi, X., Jiang, Z., Xiong, L., Siu, K.-C., & Chen, Z. (2026) · JMIR Human Factors · doi:10.2196/81652 · Cited by 13
“These differences directly reflect the distinct curricular focus, professional requirements, and learning objectives characterizing each discipline [7,20,36].”
Jairoun, A. A., Al‐Hemyari, S. S., Shahwan, M. J., Alnuaimi, G. R. H., Ibrahim, N. A., & Jaber, A. A. S. (2024) · Exploratory Research in Clinical and Social Pharmacy · doi:10.1016/j.rcsop.2024.100518 · Cited by 13
Abhari, S., Afshari, Y., Fatehi, F., Salmani, H., Garavand, A., Chumachenko, D., Zakerabasali, S., & Morita, P. P. (2024) · Annals of Medicine and Surgery · doi:10.1097/ms9.0000000000002716 · Cited by 13
Artificial intelligence in forensic pathology: an Australian and New Zealand perspective
Garland, J., Tse, R. D., Stables, S. R., Broi, U. D., & Ondruschka, B. (2025) · Rechtsmedizin · doi:10.1007/s00194-025-00741-z · Cited by 13
The early wave of ChatGPT research: A review and future agenda
Busch, P. A., Hausvik, G. I., & Nielsen, J. A. (2025) · Computers in Human Behavior Artificial Humans · doi:10.1016/j.chbah.2025.100213 · Cited by 13
AI's deep dive into complex pediatric inguinal hernia issues: a challenge to traditional guidelines?
Wang, G., Liu, Q., Chen, G., Xia, B., Zeng, D., Chen, G., & Guo, C. (2023) · Hernia · doi:10.1007/s10029-023-02900-1 · Cited by 13
Revolutionizing Patient Care: The Impact of ChatGPT and Generative AI in Healthcare
Jain, N. (2024) · International Journal of Scientific and Research Publications · doi:10.29322/ijsrp.14.11.2024.p15506 · Cited by 13
Leveraging Large Language Models for Hybrid Workplace Decision SupportPreprint
Kim, Y., & Hsu, C.-C. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2402.03616 · Cited by 13
Sen, C. K., & DeMazumder, D. (2025) · Advances in Wound Care · doi:10.1177/21621918251380217 · Cited by 13
Prompting Frameworks for Large Language Models: A Survey
Liu, X., Wang, J., Yuan, X., Sun, J., Dong, G., Di, P., Wang, W., & Wang, D. (2026) · ACM Computing Surveys · doi:10.1145/3789253 · Cited by 12
Zhang, X., Liu, Z., Cheng, Y., Wang, X., & Wang, Z. (2023) · IEEE ... International Conference on Data Mining workshops · doi:10.1109/icdmw60847.2023.00187 · Cited by 12
Shemtob, L., Nouri, A. G., Harvey-Sullivan, A., Qiu, C. S., Martin, J., Martin, M., Noden, S., Rob, T., Neves, A. L., Majeed, A., et al. (2025) · JAMIA Open · doi:10.1093/jamiaopen/ooaf082 · Cited by 12
Leveraging ChatGPT and explainable AI for enhancing clinical decision support
Shawi, R. E., & Jamel, L. (2025) · Scientific Reports · doi:10.1038/s41598-025-22784-8 · Cited by 12
Pugliese, G., Maccari, A., Felisati, E., Felisati, G., Giudici, L., Rapolla, C., Pisani, A., & Saibene, A. M. (2023) · Clinical Case Reports · doi:10.1002/ccr3.7933 · Cited by 12
Using a Natural Language Processing Approach to Support Rapid Knowledge Acquisition
Koonce, T. Y., Giuse, D. A., Williams, A. M., Blasingame, M. N., Krump, P. A., Su, J., & Giuse, N. B. (2024) · JMIR Medical Informatics · doi:10.2196/53516 · Cited by 12
Mackey, B. P., Garabet, R., Maule, L., Tadesse, A., Cross, J., & Weingarten, M. (2024) · Discover Artificial Intelligence · doi:10.1007/s44163-024-00135-2 · Cited by 11
Applications and Challenges of Human Computer Interaction and AI Interfaces for Health Care
Hutch, M. R., & Luo, Y. (2024) · Cognitive informatics in biomedicine and healthcare · doi:10.1007/978-3-031-69947-4_4 · Cited by 11
Evaluating AI Chatbot Responses to Postkidney Transplant Inquiries
Zhan, Y., Chen, X., Ye, F., Wu, Z., Usman, M., Yuan, Z., Wu, H., Huang, J., & Yu, H. (2025) · Transplantation Proceedings · doi:10.1016/j.transproceed.2024.12.028 · Cited by 11
Neary, M., Fulton, E. A., Rogers, V., Wilson, J., Griffiths, Z., Chuttani, R., & Sacher, P. M. (2025) · Frontiers in Digital Health · doi:10.3389/fdgth.2025.1460236 · Cited by 11
Fındık, M. (2026) · Scandinavian Journal of Trauma Resuscitation and Emergency Medicine · doi:10.1186/s13049-025-01540-x · Cited by 11
Large language models and conditional rules in clinical decision support systems
Sivasothy, S., Bingham, A., Logothetis, I., Barnett, S., Abdelrazek, M., Lückhoff, C., Mathew, J., Vasa, R., & Mouzakis, K. (2026) · Health Information Science and Systems · doi:10.1007/s13755-026-00428-z · Cited by 11
Demirkol, M., & Malkoç, N. (2023) · Educational Process International Journal · doi:10.22521/edupij.2023.124.3 · Cited by 11
GPT-based chatbot tools are still unreliable in the management of prosthetic joint infections
Bortoli, M., Fiore, M., Tedeschi, S., Oliveira, V. C. C., de Sousa, R. J. G., Bruschi, A., Campanacci, D. A., Viale, P., PAOLIS, M. D., & Sambri, A. (2024) · MUSCULOSKELETAL SURGERY · doi:10.1007/s12306-024-00846-w · Cited by 11
Yuan, X., Shao, C.-Y., Zhang, Z.-Z., & Qian, D. (2025) · Digital Health · doi:10.1177/20552076251315511 · Cited by 11
Er-Rays, Y., M’dioud, M., & Lemqeddem, H. A. (2025) · AI and Ethics · doi:10.1007/s43681-025-00672-1 · Cited by 11
Li, Z., Yan, C., Cao, Y., Gong, A., Li, F., & Zeng, R. (2025) · Scientific Reports · doi:10.1038/s41598-025-04309-5 · Cited by 11
Kim, H., Park, H., Kang, S., Kim, J., Kim, J., Jung, J., & Taira, R. K. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae070 · Cited by 11
Huang, Y., Gomaa, A., Semrau, S., Haderlein, M., Lettmaier, S., Weißmann, T., Grigo, J., Tkhayat, H. B., Frey, B., Gaipl, U. S., et al. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2304.11957 · Cited by 11
Kaliyadan, F., & Seetharam, K. (2023) · Indian Dermatology Online Journal · doi:10.4103/idoj.idoj_344_23 · Cited by 11
TURAN, E. İ., BAYDEMIR, A. E., ŞAHIN, A. S., & ÖZCAN, F. G. (2025) · Minerva Anestesiologica · doi:10.23736/s0375-9393.24.18587-2 · Cited by 10
Perception of ChatGPT by Nursing Undergraduates
Liu, J., Wu, S., & Liu, S. (2024) · Studies in health technology and informatics · doi:10.3233/shti240271 · Cited by 10
Self-citationWhen One Size Does not Fit All—Artificial Intelligence in Australian Rural Health
Hains, L. R., Kovoor, J. G., Stretton, B., Gupta, A. K., Zaka, A., Carmichael, G. J., Kefalianos, J. M., Sin, W. L. S., Leslie, A., Booth, A. E. C., et al. (2025) · Australian Journal of Rural Health · doi:10.1111/ajr.70037 · Cited by 10
Agent-in-the-loop to distill expert knowledge into artificial intelligence models: a survey
Gao, J., Zhang, Y., Chen, Y., Dong, Y., Chen, Y., Song, S., Tang, B., & Gu, Y. (2025) · Artificial Intelligence Review · doi:10.1007/s10462-025-11255-1 · Cited by 10
Aalam, A. (2025) · Journal of Emergency Medicine · doi:10.1016/j.jemermed.2025.08.014 · Cited by 10
Luo, S., Canavese, F., Aroojis, A. J., Andreacchio, A., Antičević, D., Bouchard, M. L., Castañeda, P. G., Rosa, V. D., Fiogbe, M. A., Frick, S. L., et al. (2024) · Journal of Pediatric Orthopaedics · doi:10.1097/bpo.0000000000002682 · Cited by 10
Malhotra, K., Wiesenfeld, B. M., Major, V. J., Grover, H., Aphinyanaphongs, Y., Testa, P. A., & Austrian, J. S. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae285 · Cited by 10
Ahmed, A. E., Fatani, D. R., Vargas, J. M., AlMutlak, M., Helayel, H. B., Fairaq, R., & Alabdulhadi, H. (2025) · Cureus · doi:10.7759/cureus.78069 · Cited by 10
Tran, H., Wang, J., Ting, Y., Yu, H., Huang, W., & Chen, T. (2025) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2025.emnlp-industry.23 · Cited by 10
ChatGPT and other artificial intelligence chatbots and biomedical writing
Gurha, P., Ishaq, N., & Marian, A. J. (2023) · The Journal of Cardiovascular Aging · doi:10.20517/jca.2023.13 · Cited by 10
Morita, P. P., Abhari, S., & Kaur, J. (2023) · International Journal of Health Policy and Management · doi:10.34172/ijhpm.2023.8131 · Cited by 10
Large language models for generating rules, yay or nay?Preprint
Sivasothy, S., Barnett, S., Logothetis, R., Abdelrazek, M., Rasool, Z., Thudumu, S., & Brannelly, Z. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2406.06835 · Cited by 10
Can Gen-AI promote community group buying? A tripartite evolutionary game analysis
Zhou, F., Zhang, C., Tiwari, S., Huang, X., & Basu, P. (2025) · International Journal of Production Economics · doi:10.1016/j.ijpe.2025.109721 · Cited by 9
Liu, X., Chen, Y., Guan, W., Jiang, P., Yan, L., Fan, M., & Zhou, Q. (2025) · Journal of Advanced Nursing · doi:10.1111/jan.70250 · Cited by 9
Sheen, F., Mullarkey, B., Witcomb, G. L., Opitz, M., Maloney, E., Baldoza, S. M., & White, H. J. (2025) · Child and Adolescent Mental Health · doi:10.1111/camh.70047 · Cited by 9
Umehara, K., Ota, J., Nishii, T., Kishimoto, R., & Ishida, T. (2025) · European Journal of Radiology Artificial Intelligence · doi:10.1016/j.ejrai.2025.100064 · Cited by 9
Dullabh, P., Zott, C., Gauthreaux, N. A., Peterson, C., Aronoff, A., Monkhouse, K., & Sittig, D. F. (2026) · Journal of Medical Internet Research · doi:10.2196/81628 · Cited by 9
Self-citationThe new frontier: utilizing ChatGPT to expand craniofacial research
Zhang, A., Dimock, E., Gupta, R., & Chen, K. (2024) · Archives of Craniofacial Surgery · doi:10.7181/acfs.2024.00115 · Cited by 9
Mashagbeh, M. A., Dardas, L. A., Alzaben, H., & Al‐Khayat, A. (2024) · Frontiers in Education · doi:10.3389/feduc.2024.1429324 · Cited by 9
Frodl, A., Fuchs, A., Yilmaz, T., Izadpanah, K., Schmal, H., & Siegel, M. (2024) · Clinics and Practice · doi:10.3390/clinpract14060186 · Cited by 9
Hamilton, Z., Aseem, A., Chen, Z., Naffakh, N., Reizine, N. M., Weinberg, F. D., Jain, S., Kessler, L. G., Gadi, V. K., Bun, C., et al. (2024) · JCO Clinical Cancer Informatics · doi:10.1200/cci.24.00123 · Cited by 9
Balasanjeevi, G., & Surapaneni, K. M. (2024) · Respiratory Medicine and Research · doi:10.1016/j.resmer.2024.101091 · Cited by 9
Lin, S., Zhou, S., Jiao, H., Wang, M., Yan, H., Dou, P., & Chen, J. (2024) · Complex & Intelligent Systems · doi:10.1007/s40747-024-01697-5 · Cited by 9
MD Student Perceptions of ChatGPT for Reflective Writing Feedback in Undergraduate Medical Education
Haider, N., Morjaria, L., Sheth, U., Al-Jabouri, N., & Sibbald, M. (2025) · International Medical Education · doi:10.3390/ime4030027 · Cited by 8
Comparative analysis of AI and expert evaluations in engineering design pedagogy
Coşkun, T. K., & Altan, E. B. (2025) · PLoS ONE · doi:10.1371/journal.pone.0332715 · Cited by 8
Kot, S., Engineer, M., Gilman, E., Flathmann, C., Pradhan, A., & Dixon, E. (2026) · ACM Transactions on Computer-Human Interaction · doi:10.1145/3773029 · Cited by 8
Multimodal large language models for IOL power calculation in cataract surgery: A feasibility study
Jun, H. W., Ryu, S. Y., & Yoo, T. K. (2025) · AJO International · doi:10.1016/j.ajoint.2025.100205 · Cited by 8
Benchmarking GPT-5 in radiation oncology: measurable gains, but persistent need for expert oversight
Dinç, U., Sarkar, J., Schubert, P., Semrau, S., Weißmann, T., Karius, A., Brand, J., Axer, B., Gomaa, A., Stephan, P., et al. (2025) · Frontiers in Oncology · doi:10.3389/fonc.2025.1695468 · Cited by 8
Liu, Y., Wang, F., Wang, P., Zhou, Z., Wang, H., Li, J., Qiu, Y., Wang, H., & Miao, S. (2026) · Journal of Cancer Research and Clinical Oncology · doi:10.1007/s00432-025-06413-5 · Cited by 8
Hang, Y.-Q., wu, J., Bai, L., Wu, M., Yu, J., Li, L., & Piao, X. L. (2026) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-026-03371-x · Cited by 8
Passing the Buck to AI: How Individuals’ Decision-Making Patterns Affect Reliance on AI
Mei, K. X., Pang, R. Y., Lyford, A., Wang, L. L., & Reinecke, K. (2026) · ACM Transactions on Computer-Human Interaction · doi:10.1145/3786326 · Cited by 8
Generative IoT: advancing IoT with generative AI and large language models
Firouzi, F., Ray, A., Farahani, B., Daneshmand, M., Song, J., Wu, S., & Chakrabarty, K. (2026) · Digital Communications and Networks · doi:10.1016/j.dcan.2026.03.010 · Cited by 8
Who Does What? Archetypes of Roles Assigned to LLMs During Human-AI Decision-Making
Chappidi, S., Singh, J., & Krauze, A. V. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3791428 · Cited by 8
Youth Perspectives on Generative AI and Its Use in Health Care
Schaaff, C., Bains, M., Davis, S., Amalraj, T., Frank, A., Waselewski, M. E., Chang, T., & Wong, A. H. (2025) · Journal of Medical Internet Research · doi:10.2196/72197 · Cited by 8
Gadde, P., Poornima, U. L. S., Akkaloori, A., & Bharathi, V. (2024) · Journal of Nature and Science of Medicine · doi:10.4103/jnsm.jnsm_208_23 · Cited by 8
Assessing the research landscape and clinical utility of large language models: A scoping reviewPreprint
Park, Y., Pillai, A., Deng, J., Guo, E., Gupta, M., Paget, M., & Naugler, C. T. (2023) · Research Square · doi:10.21203/rs.3.rs-3472000/v1 · Cited by 8
Evaluating the performance of ChatGPT in clinical multidisciplinary treatment: a retrospective study
Wang, X., Guo, J., Zhang, T., Lu, H., Zhou, D., Zhang, H., & Wang, X. (2025) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-025-03181-7 · Cited by 7
Nguyen, D., Bronson, I., Chen, R., & Kim, Y. H. (2025) · Frontiers in Radiology · doi:10.3389/fradi.2025.1670517 · Cited by 7
he, S., Zhang, Y., & li, J. (2026) · JMIR Formative Research · doi:10.2196/71541 · Cited by 7
Ge, J., Buenaventura, A., Berrean, B., Purvis, J., Fontil, V., Lai, J. C., & Pletcher, M. J. (2024) · Hepatology Communications · doi:10.1097/hc9.0000000000000394 · Cited by 7
Expertise or Hallucination? A Comprehensive Evaluation of ChatGPT's Aptitude in Clinical Genetics
Zhang, Y., Ren, S., Wang, J., Zhan, C., He, M., Liu, X., Wu, R., Zhao, J., Wu, C., Fan, C., et al. (2025) · IEEE Transactions on Big Data · doi:10.1109/tbdata.2025.3536939 · Cited by 7
Generative artificial intelligence policies: information governance
Wang, X., Liu, B., & Bao, L. (2025) · Management Decision · doi:10.1108/md-06-2024-1422 · Cited by 7
Zhou, S., & Yu, S. (2025) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-025-03204-3 · Cited by 7
Segal, S., Saha, A. K., & Khanna, A. K. (2024) · Anesthesiology · doi:10.1097/aln.0000000000004824 · Cited by 7
ChatGPT Is Trending: Trust but Verify
Harrington, L. (2023) · AACN Advanced Critical Care · doi:10.4037/aacnacc2023129 · Cited by 7
Metadata
- Authors
- Liu, S., Wright, A. P., Patterson, B. L., Wanderer, J. P., Turer, R. W., Nelson, S. D., McCoy, A. B., Sittig, D. F., & Wright, A.
- Affiliations
- Vanderbilt University Medical Center (US)
- The University of Texas Southwestern Medical Center (US)
- The University of Texas Health Science Center at Houston (US)
- Corresponding author
- Liu, Siru
- ORCID
- Venue
- Journal of the American Medical Informatics Association
- Publisher
- Oxford University Press (OUP)
- Published
- 2023-04-22
- Volume
- 30
- Issue
- 7
- Pages
- 1237-1245
- ISSN
- 1067-5027 (ISSN-L)
- 1527-974X
- PMC
- PMC10280357
- OpenAlex
- W4366769280
- Cited by
- 397
- References
- 34
- Citations by year
- 2026: 64 · 2025: 126 · 2024: 144 · 2023: 61
- FWCI
- 15.73
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Journal of the American Medical Informatics Association (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Digital Commons-TMC (Texas Medical Center) (submittedVersion)
- Funders
- NIH (K99LM014097-01, R01AG062499-01, R01LM013995-01)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Health Professions › Health Information Management › Electronic Health Records Systems
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- ChatGPT, clinical decision support, large language models, non-inferiority, reinforcement learning from human feedback, learning health systems
- MeSH terms
- Learning Health System, Artificial Intelligence, Humans, Language, Decision Support Systems, Clinical, Workflow
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
