

Using AI-generated suggestions from ChatGPT to optimize clinical decision support
Open accessThe DOI matches its Crossref record; 39 of the 39 references it cites were found in a registry or an index.
Abstract
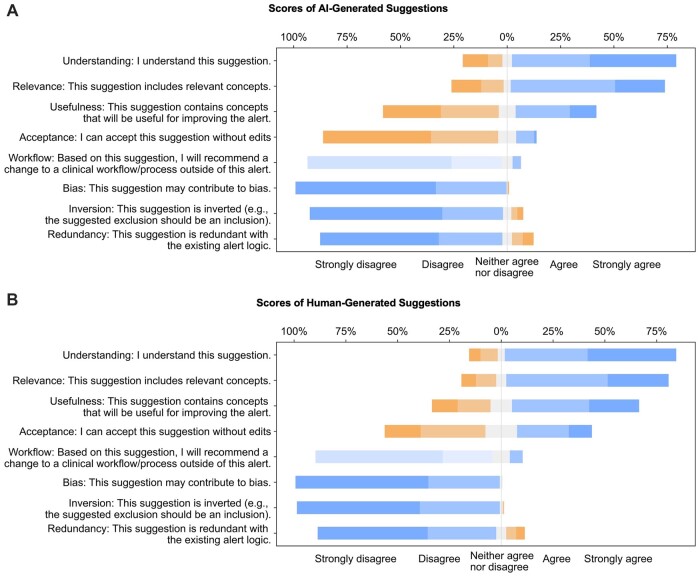
Objective: To determine if ChatGPT can generate useful suggestions for improving clinical decision support (CDS) logic and to assess noninferiority compared to human-generated suggestions. Methods: We supplied summaries of CDS logic to ChatGPT, an artificial intelligence (AI) tool for question answering that uses a large language model, and asked it to generate suggestions. We asked human clinician reviewers to review the AI-generated suggestions as well as human-generated suggestions for improving the same CDS alerts, and rate the suggestions for their usefulness, acceptance, relevance, understanding, workflow, bias, inversion, and redundancy. Results: Five clinicians analyzed 36 AI-generated suggestions and 29 human-generated suggestions for 7 alerts. Of the 20 suggestions that scored highest in the survey, 9 were generated by ChatGPT. The suggestions generated by AI were found to offer unique perspectives and were evaluated as highly understandable and relevant, with moderate usefulness, low acceptance, bias, inversion, redundancy. Conclusion: AI-generated suggestions could be an important complementary part of optimizing CDS alerts, can identify potential improvements to alert logic and support their implementation, and may even be able to assist experts in formulating their own suggestions for CDS improvement. ChatGPT shows great potential for using large language models and reinforcement learning from human feedback to improve CDS alert logic and potentially other medical areas involving complex, clinical logic, a key step in the development of an advanced learning health system.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures


Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“The integration of AI-powered tools into clinical pharmacy practices could bolster efficiency, decision-making, and patient outcomes.9”
From ChatGPT and Clinical Training: Perception, Concerns, and Practice of Pharm-D Students (2023) · cites this paper as [9]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
A guideline of selecting and reporting intraclass correlation coefficients for reliability research
Koo, T. K., & Li, M. Y. (2016) · Journal of Chiropractic Medicine · doi:10.1016/j.jcm.2016.02.012 · Cited by 31,709
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
A General Inductive Approach for Analyzing Qualitative Evaluation Data
Thomas, D. R. (2006) · American Journal of Evaluation · doi:10.1177/1098214005283748 · Cited by 10,858
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Kung, T. H., Cheatham, M., ChatGPT, Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., et al. (2022) · doi:10.1101/2022.12.19.22283643 · Cited by 4,115
Kung, T. H., Cheatham, M., Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., Maningo, J., et al. (2023) · PLOS Digital Health · doi:10.1371/journal.pdig.0000198 · Cited by 4,115
Kawamoto, K., Houlihan, C. A., Balas, E. A., & Lobach, D. F. (2005) · BMJ · doi:10.1136/bmj.38398.500764.8f · Cited by 2,703
Effect of Clinical Decision-Support Systems: A Systematic Review
Bright, T. J., Wong, A., Dhurjati, R., Bristow, E., Bastian, L., Coeytaux, R. R., Samsa, G., Hasselblad, V., Williams, J. W., Musty, M. D., et al. (2012) · Annals of Internal Medicine · doi:10.7326/0003-4819-157-1-201207030-00450 · Cited by 1,200
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.173 · Cited by 1,185
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · arXiv · doi:10.48550/arxiv.2005.00661 · Cited by 1,185
Research works printed but not linked: 1
- de Winter, 2010, Five-point Likert items: t test versus Mann-Whitney-Wilcoxon, Pract Assess Res Eval, 15, 11
Cited by
Items 401–500 of 542
Wang, X., Wang, S., Wang, D., & Sima, X. (2025) · Health & Social Care in the Community · doi:10.1155/hsc/3585981 · Cited by 1
Artificial intelligence methods in science of Human Habitat: a systematic review
An, Y., Peng, X., & Liu, L. (2025) · Journal of Asian Architecture and Building Engineering · doi:10.1080/13467581.2025.2554964 · Cited by 1
From Evidence to Recommendations With Large Language Models: A Feasibility Study
Zhao, W., Xia, D., Ye, Z., Lai, H., Sun, M., Huang, J., Liu, J., Liu, J., & Ge, L. (2025) · Journal of Evidence-Based Medicine · doi:10.1111/jebm.70067 · Cited by 1
Measuring the User Experience Toward ChatGPT for Sustainable Tourism Purposes
Hakim, I. N., Antariksa, B., Hamidah, S., Rusata, T., & Faisyal, F. (2025) · Springer eBooks · doi:10.1007/978-981-96-3379-1_43 · Cited by 1
Tığlı, A., Deniz, R., Üstebay, S., Bektaş, M. H., Çöllüoğlu, Ç., & Baykuş, Y. (2026) · Hippocrates Medical Journal · doi:10.58961/hmj.1916158 · Cited by 1
Huang, R., Cecil, J., Freedman, M., & Chattopadhyay, S. (2026) · Journal of Medical Internet Research · doi:10.2196/88126 · Cited by 1
Yang, Y., Liu, X., Domínguez, J. L. C., Fang, Y., Xie, W., Shen, B., & Siau, K. L. (2026) · Journal of Organizational and End User Computing · doi:10.4018/joeuc.400122 · Cited by 1
Urooj, S., & Faheem, M. (2026) · Hospital Pharmacy · doi:10.1177/00185787251405374 · Cited by 1
Trends in ChatGPT Publications in Health Sciences: A Bibliometric Analysis
Avcı, Y. D., Yapar, D., Sonuvar, E. T., & Bilge, U. (2026) · Turkish Journal of Family Medicine & Primary Care · doi:10.21763/tjfmpc.1746582 · Cited by 1
Generative artificial intelligence in healthcare: a bibliometric analysis
Tian, X., Meng, F., Guo, H., Li, Z., Jia, S., Wang, Z., & Cheng, P. (2026) · International Journal of Surgery · doi:10.1097/js9.0000000000004041 · Cited by 1
ŞAHİN, F. T., & İşlek, Ö. (2026) · İnönü Üniversitesi Sağlık Hizmetleri Meslek Yüksek Okulu Dergisi · doi:10.33715/inonusaglik.1686265 · Cited by 1
Li, Y., Zhu, Y., & Xu, Q. (2025) · Pinnacle Academic Press Proceedings Series · doi:10.71222/qev02377 · Cited by 1
Борисов, А. А., Burtsev, T., Kosov, P., Bobrovskaya, T. V., Vasilev, Y. A., Vladzymyrskyy, A. V., Omelyanskaya, O. V., Pamova, A. P., & Arzamasov, K. M. (2026) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2026.1768005 · Cited by 1
Design of a RAG framework for cardiology EHR analysis
Defilippo, A., Canino, G., Procopio, N., Trapuzzano, M. D. A., Sorrentino, S., Indolfi, M. D. C., Vizza, P., Veltri, P., & Guzzi, P. H. (2026) · Discover Artificial Intelligence · doi:10.1007/s44163-026-01128-z · Cited by 1
Design and Optimization of AI Decision Support Systems Centered on Human Experience
Jin, J. (2025) · International Conference on Computing, Robotics and System Sciences (ICRSS) · doi:10.1109/icrss67786.2025.00050 · Cited by 1
Nelson, S. D., & Wright, A. T. (2026) · Journal of Medical Internet Research · doi:10.2196/95004 · Cited by 1
Self-citationEvaluation Methods for AI in Public Health
Wu, M. (2026) · Springer eBooks · doi:10.1007/978-3-032-15872-7_4 · Cited by 1
Shen, Y., Wu, Y., Qiu, Y., & Wu, J. (2026) · Frontiers in Medicine · doi:10.3389/fmed.2026.1818061 · Cited by 1
Raipal, S., & Penkova, A. (2026) · Knowledge-Based Systems · doi:10.1016/j.knosys.2026.116241 · Cited by 1
Liu, Q., & Ren, H. (2026) · International Conference on Big Data and Informatization Education (ICBDIE) · doi:10.1145/3806980.3807111 · Cited by 1
Use of ChatGPT among Student Nurses in Baguio City, Philippines: A Cross-sectional Study
Lacanlale, R. C. A. T., Dalilis, C., Gayagay, R. B. S. S., Da-o, R. S. M. D., Bilog, R. T. M., Bacsa, R. F. A. D., Lauzon, R. D. A. P., Mariano, A., Rabara, R. S. T., Reyes, R. R. A. A., et al. (2026) · Acta Medica Philippina · doi:10.47895/amp.vi0.11158 · Cited by 1
Perioperative Risk Stratification with AI-Powered Chatbots: A Systematic Review and Meta-Analysis
Bellini, V., Panizzi, M., Delrio, S., Berdini, M., Sapountzakis, V., Diego, L. A. D. S., & Bignami, E. G. (2026) · Journal of Clinical Medicine · doi:10.3390/jcm15124670 · Cited by 1
A Real-World Evaluation of Large Language Model–Generated Hospital Courses in Pediatrics
Kim, J. E., Hron, J. D., Kats, D. J., Wong, K., Kutz, L., & Parsons, C. R. (2026) · Hospital Pediatrics · doi:10.1542/hpeds.2026-009216 · Cited by 1
Jaber, A. A. S., Anssari, J. H. A., & Jairoun, A. A. (2026) · Pharmacy Practice · doi:10.18549/pharmpract.2026.4.3282 · Cited by 1
Zhou, Y., Gao, J., & Yang, K. (2023) · International Conference on Electronics and Devices, Computational Science (ICEDCS) · doi:10.1109/icedcs60513.2023.00106 · Cited by 1
Integrating Machine Learning in Clinical Decision Support Systems
Subramanian, T. (2024) · Health Informatics - An International Journal · doi:10.5121/hiij.2024.13101 · Cited by 1
Situational Data Integration in Question Answering systems: a survey over two decades
Franciscatto, M. H., Bona, L. C. E., Trois, C., Fabro, M. D. D., & Lima, J. C. D. (2024) · Knowledge and Information Systems · doi:10.1007/s10115-024-02136-0 · Cited by 1
Yang, H., Xiao, L., Zhu, R., Liu, Z., & Chen, J. (2024) · IEEE Annual International Computer Software and Applications Conference (COMPSAC) · doi:10.1109/compsac61105.2024.00165 · Cited by 1
APLICACIÓN DE LA INTELIGENCIA ARTIFICIAL EN LA INVESTIGACIÓN EN CIENCIAS DE LA SALUD
Chauca, L. E., Lázaro, A. R. F., Hijar, E. P. M., Huamaní, M. M. L. C., & Huamaní, A. V. C. (2024) · Editora Científica Digital eBooks · doi:10.37885/978-65-5360-724-8 · Cited by 1
Evaluating the Accuracy of ChatGPT in the Japanese Board-Certified Physiatrist Examination
Kato, Y., Ushida, K., & Momosaki, R. (2024) · Cureus · doi:10.7759/cureus.76214 · Cited by 1
Chirino, A., Cabral, G., Cavallazzi, R., Prado, J., Chandler, T. R., Furmanek, S. P., Mattingly, W. A., Wiemken, T. L., Carrico, R., Song, M., et al. (2024) · Norton Healthcare Medical Journal · doi:10.59541/001c.127927 · Cited by 1
Chouikh, A., Khechine, H., Ammari, M. L., & Mellouli, S. (2025) · Hawaii International Conference on System Sciences (HICSS) · doi:10.24251/hicss.2025.860 · Cited by 1
Edison, E., Awaiz, A. D., Sehr, S., Afzal, A., Tahir, H., Aslam, M., & Khan, M. W. (2025) · Insights-Journal of Health and Rehabilitation · doi:10.71000/zhqww010 · Cited by 1
DSouza, H., Mohammed, A., Almuntashiri, A. A. A., Kumar, V., Mulla, M., Khader, A. A., Bhowmick, S., & Gupta, P. (2025) · Journal of Education and Health Promotion · doi:10.4103/jehp.jehp_1699_24 · Cited by 1
Cao, Y., Yuan, H., Qiao, Y., Guo, Y., Wang, X., Li, B., Wang, X., Li, Y., & Jiao, W. (2026) · Archivos Españoles de Urología · doi:10.56434/j.arch.esp.urol.20267906.111 · Cited by 1
Temporal Signal Intelligence for Pervasive ICU Sensing and Continuous Patient Monitoring
Nakamura, H., Kato, Y., & El-Kholy, A. (2024) · Journal of Artificial Intelligence for Healthcare Systems · doi:10.68159/t351403748 · Cited by 1
On-site controls for urban stormwater pollution
Prey, J. (1994) · OSTI OAI (U.S. Department of Energy Office of Scientific and Technical Information) · Cited by 1
Yang, H., Li, J., Liu, S., Liu, L., Liu, X., Huang, Y., Shi, Q., & liu, J. (2023) · doi:10.2196/preprints.50911 · Cited by 1
Self-citationA LITERATURE REVIEW: CHATGPT, WHAT WILL THE FUTURE OF PHARMACY PRACTICE BRING—A THREAT OR A BENEFIT?
Noviani, L., Rachmawati, P., & Irawan, A. (2023) · doi:10.53555//jptcp.v30i18.3016 · Cited by 1
Lin, Y., Wang, Y., Deng, Y., Xu, D., & Wang, M. (2024) · doi:10.2196/preprints.60412 · Cited by 1
Alkalbani, A. M., Alrawahi, A. S., Salah, A., Haghighi, V., Zhang, Y., Alkindi, S. S. A., & Sheng, Q. Z. (2024) · Research Square · doi:10.21203/rs.3.rs-5128451/v1 · Cited by 1
Falvo, D. J., Weidener, L., & Karlsson, M. (2025) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2025.01.08.631843 · Cited by 1
The Fault in Our Sets: A Mixed Methods Analysis of Clinical Value Set ErrorsPreprint
Zahn, L. M., Ahmad, H., Sittig, D. F., Russo, E. M., Koh, B., Nimocks, A., & Wright, A. T. (2025) · medRxiv · doi:10.1101/2025.02.27.25323054 · Cited by 1
Self-citationLLMartini: Seamless and Interactive Leveraging of Multiple LLMs through Comparison and CompositionPreprint
Shi, Y., Yang, J., Wang, Y., Yin, Y., Li, H., Gao, K., & Yu, C. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2510.19252 · Cited by 1
Diffusion-driven SpatioTemporal Graph KANsformer for Medical Examination RecommendationPreprint
Li, J., Zhou, Y., Zhao, Z., Huang, Q., Qi, J., He, X., Chu, H., & Li, F. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.07431 · Cited by 1
Alkhalaf, M. (2024) · Research Online (University of Wollongong) · Cited by 1
Xian, R. P., Lee, A. J., Lolla, S., Wang, V., Cui, Q., Ro, R., & Abbasi-Asl, R. (2024) · arXiv · doi:10.48550/arxiv.2402.10527
Языковая репрезентация характера человека во фразеологической картине мира в английском языке
Александровна, В. А. (2013) · Bulletin of Chelyabinsk State University
Huang, J., Liu, J., Hu, D., Zheng, Y., Duan, Y., & Wu, X. (2023) · doi:10.2196/preprints.50179
Unleashing the Potential of ChatGPT: A Personal Perspective
(2023) · Advances in educational technologies and instructional design book series · doi:10.4018/978-1-6684-9300-7.ch008
Breeding, T., Patel, H. S., Nasef, H., & Elkbuli, A. (2023) · The American Surgeon · doi:10.1177/00031348231204913
21. Yüzyıl’da Sağlık Bilimleri: Yöntem, Kuram ve Vaka
Yıldız, E. K., & Tur, K. (2023) · Özgür Yayınları eBooks · doi:10.58830/ozgur.pub282
TBHEB 2023-4 Vol 80 Full Printed Journal
ERCÖMERT, U. (2023) · Turkish Bulletin of Hygiene and Experimental Biology · doi:10.5505/turkhijyen.2023.97572
A commentary on can ChatGPT assist urologists manage overactive bladder?
Mao, C., & Zhang, T. (2024) · International Journal of Surgery · doi:10.1097/js9.0000000000001261
Xu, S., Chen, S., & Chen, M. (2024) · Communications in computer and information science · doi:10.1007/978-981-97-1280-9_9
Deng, Q.-F., Bao, Y.-Y., Yang, Y., & Mao, C. (2024) · European Urology · doi:10.1016/j.eururo.2024.02.031
Daungsupawong, H., & Wiwanitkit, V. (2024) · Mustansiriya Medical Journal · doi:10.4103/mj.mj_70_23
Promises and Perils of Generative AI in the Healthcare Sector
Garg, P. (2024) · Advances in medical technologies and clinical practice book series · doi:10.4018/979-8-3693-3731-8.ch015
Surapaneni, K. M., & Bakthavasan, E. (2024) · Indian Journal of Orthopaedics Surgery · doi:10.18231/j.ijos.2024.047
Evaluation of Biostatistics Contents in ChatGPT: A Descriptive Study
Eden, A. B., Kayı, A. B., & Veznikli, M. (2024) · Proceedings of the International Conference on Statistics, Theory and Applications (ICSTA ...) · doi:10.11159/icsta24.108
(2024) · JACC. Cardiovascular imaging · doi:10.1016/s1936-878x(24)00411-x
Is ChatGPT worthy enough for provisioning clinical decision support?
Ray, P. P. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae282
Exploring GPT ‐4.0's efficiency in handling paediatric appendicitis questions
Zeng, D., Chen, G., Wang, G., Zhou, H., & Guo, C. (2024) · Surgical Practice · doi:10.1111/1744-1633.12733
GYNs at the REI gates: unsolvable conundrum or unambiguous opportunity?
Letterie, G. S. (2024) · Journal of Assisted Reproduction and Genetics · doi:10.1007/s10815-024-03344-x
Eliminating Risk Involved in Using ChatGPT for Clinical Decision Support System
D’Costa, K., & Kanabar, V. (2025) · Lecture notes of the Institute for Computer Sciences, Social Informatics and Telecommunications Engineering · doi:10.1007/978-3-031-84312-9_14
Phillipi, M., Shu, C., Merax, J., Cho, H., Zhang, Y., Sun, S. H., Glavis‐Bloom, J., & Houshyar, R. (2025) · doi:10.2196/preprints.77072
How to Write Professional Notes in the EMR
Nolan-Kelley, L. (2025) · Springer eBooks · doi:10.1007/978-3-031-85546-7_13
Halim, M. S., Khowaja, A. H., Fazal, Z. Z., Jain, T., Janjua, K., Khan, A. A., Tran, A. N. T., & Sepah, Y. J. (2025) · medRxiv · doi:10.1101/2025.07.05.25330926
Vranješ, D., Perković, T., Braović, M., & Ćupurdija, A. (2025) · International Conference on Smart and Sustainable Technologies (SpliTech) · doi:10.23919/splitech65624.2025.11091635
UTSA-NLP at ArchEHR-QA 2025: Improving EHR Question Answering via Self-Consistency Prompting
Shields‐Menard, S. A., Reimers, Z., Gardner, J., Perry, D., & Rios, A. (2025) · Workshop on Biomedical Language Processing (BioNLP) · doi:10.18653/v1/2025.bionlp-share.10
Добрева, A. (2025) · Communications in computer and information science · doi:10.1007/978-3-031-93601-2_7
Kamran, A., Iqra, Suf, Y., Ali, A. M., Arham, K., & Shaukat, F. (2025) · National Journal of Health Sciences · doi:10.21089/njhs.10s1.0s21
Santamaria, T. (2025) · Primary Care Clinics in Office Practice · doi:10.1016/j.pop.2025.07.006
Khababa, G., Khababa, A., Harun, N. H., & Amrani, S. (2025) · International Conference on Emerging Smart Technologies and Applications (eSmarTA) · doi:10.1109/esmarta66764.2025.11132265
Chen, R., Wang, G., & Nie, S. (2025) · JNCI Journal of the National Cancer Institute · doi:10.1093/jnci/djaf262
A Review of Transformers in Medical Research and Health Care
Lin, C.-H., & Kuo, C. (2025) · Hand Clinics · doi:10.1016/j.hcl.2025.08.007
(2025) · Revista Internacional de Andrología · doi:10.22514/j.androl.2025.030
Li, J., Shi, B., Shi, F., Sun, A., Huang, J., Wu, X., Yao, Z., Wu, C., Chen, L., Yuan, J., et al. (2025) · Langenbeck s Archives of Surgery · doi:10.1007/s00423-025-03844-z
Treatment, evidence, imitation, and chatPreprint
Weisenthal, S. J. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.23040
EXPLAINABLE DEEP LEARNING MODELS FOR MEDICAL IMAGE DIAGNOSIS BRIDGING ACCURACY AND INTERPRETABILITY
Nguyen, S. (2025) · International Journal of Apllied Mathematics · doi:10.12732/ijam.v38i7s.531
EXPLAINABLE DEEP LEARNING MODELS FOR MEDICAL IMAGE DIAGNOSISBRIDGING ACCURACY AND INTERPRETABILITY
Nguyen, S. (2025) · International Journal of Apllied Mathematics · doi:10.12732/ijam.v38i8s.582
Wang, L., You, Z., Zhang, Q., Wen, J., Shi, J., Chen, Y., Wang, Y., Ding, F., Feng, Z., & Li, L. (2025) · AAAI Publications (The Association for the Advancement of Artificial Intelligence (AAAI)) · doi:10.48550/arxiv.2511.07127
Generative artificial intelligence in postgraduate medical education
Akbarnezhad, N. (2025) · International Journal of Clinical Medical Research · doi:10.61466/ijcmr3060004
Najmuddin, M. (2025) · Dentomaxillofacial Radiology · doi:10.1093/dmfr/twaf085
Benchmarking large language models for identifying transcription factor regulatory interactions
Noel, L., Hsiao, Y.-W., He, Y., Hung, A. J., Cui, X., Ray, E., Moore, J. H., Peng, P.-C., & Huang, X. (2025) · Bioinformatics · doi:10.1093/bioinformatics/btaf653
Computational Analysis of Health Text
He, L. (2023) · eScholarship (California Digital Library)
Health according to ChattGPT, a new health discourse
Söderlind, H. (2023) · DiVA (Digitala Vetenskapliga Arkivet)
Kuivanen, M. (2024) · Theseus (Ammattikorkeakoulujen)
Automating the Annotation of Data through Machine Learning and Semantic Technologies
Pigott-Dix, L. A. K. (2023) · UEA Digital Repository (University of East Anglia)
Decoding Health: Large Language Models Transforming Healthcare
Liang, J. (2025) · Applied and Computational Engineering · doi:10.54254/2755-2721/2025.bj27258
Altan, Y. C. R., & Nacir, B. (2026) · Fiziksel Tıp ve Rehabilitasyon Bilimleri Dergisi · doi:10.31609/jpmrs.2025-112944
Namdev, S., Tiwari, N., Dwivedi, P., Madaria, A., Latiyar, S., & Pyasi, A. (2025) · IEEE International Conference on ICT in Business Industry & Government (ICTBIG) · doi:10.1109/ictbig68706.2025.11323720
The Impact of Large Language Models in Healthcare: A Systematic Review of AI Applications
Maurya, A. K., Saritha, S. K., & Bharti, J. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-15404-0_5
Hargoosee, R. D. M., Mageed, F. A. R., Hameed, J. R., Ashour, K. J. Q., & Hasan, P. Q. (2025) · Bright Sky Publications eBooks · doi:10.62906/bs.book.487
SLM With Swarm Intelligence for Efficient Representation of Medical Claims
El-Enen, M. A. A., Sharma, R., AbdulRazek, M., Nazir, A., Muhammad, R., & Sahlol, A. T. (2026) · IEEE Access · doi:10.1109/access.2026.3666108
Leveraging Large Language Models for Hybrid Workplace Recommendation
Kim, Y., & Hsu, C.-C. (2025) · International Conference on Foundation and Large Language Models (FLLM) · doi:10.1109/fllm67465.2025.11390885
Consensus Building in AI Risk Management: Approaches to Global Cooperation
Qu, S., Zhou, Q., Lin, J., Cao, Y., Song, Y., Ben, Y., Lei, L., Zhang, F., & Huang, Q. G. H. (2026) · Frontiers of artificial intelligence, ethics and multidisciplinary applications. · doi:10.1007/978-3-032-05588-0_8
Küçülmez, Ö. (2026) · International Journal of Advances in Signal and Image Sciences · doi:10.29284/n50b4s27
Benchmarking Clinical Reasoning in Large Language Models: A Comparative Assessment StudyPreprint
Prade, T., & Samwald, M. (2026) · medRxiv · doi:10.64898/2026.03.13.26347597
Metadata
- Authors
- Liu, S., Wright, A. P., Patterson, B. L., Wanderer, J. P., Turer, R. W., Nelson, S. D., McCoy, A. B., Sittig, D. F., & Wright, A.
- Affiliations
- Vanderbilt University Medical Center (US)
- The University of Texas Southwestern Medical Center (US)
- The University of Texas Health Science Center at Houston (US)
- Corresponding author
- Liu, Siru
- ORCID
- Venue
- Journal of the American Medical Informatics Association
- Publisher
- Oxford University Press (OUP)
- Published
- 2023-04-22
- Volume
- 30
- Issue
- 7
- Pages
- 1237-1245
- ISSN
- 1067-5027 (ISSN-L)
- 1527-974X
- PMC
- PMC10280357
- OpenAlex
- W4366769280
- Cited by
- 397
- References
- 34
- Citations by year
- 2026: 64 · 2025: 126 · 2024: 144 · 2023: 61
- FWCI
- 15.73
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Journal of the American Medical Informatics Association (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Digital Commons-TMC (Texas Medical Center) (submittedVersion)
- Funders
- NIH (K99LM014097-01, R01AG062499-01, R01LM013995-01)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Health Professions › Health Information Management › Electronic Health Records Systems
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- ChatGPT, clinical decision support, large language models, non-inferiority, reinforcement learning from human feedback, learning health systems
- MeSH terms
- Learning Health System, Artificial Intelligence, Humans, Language, Decision Support Systems, Clinical, Workflow
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
