

Multimodal Attention Network for Continuous-Time Emotion Recognition Using Video and EEG Signals
Open accessThe DOI matches its Crossref record; 59 of the 59 references it cites were found in a registry or an index.
Abstract
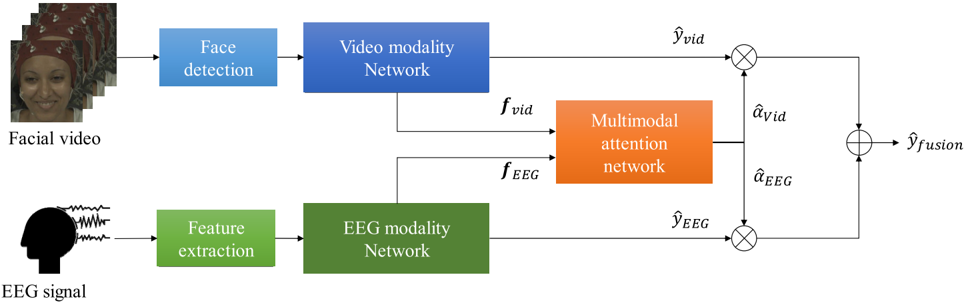
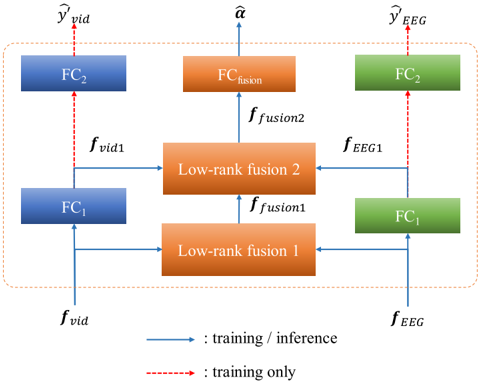
Emotion recognition is a very important technique for ultimate interactions between human beings and artificial intelligence systems. For effective emotion recognition in a continuous-time domain, this article presents a multimodal fusion network which integrates video modality and electroencephalogram (EEG) modality networks. To calculate the attention weights of facial video features and the corresponding EEG features in fusion, a multimodal attention network, that is utilizing bilinear pooling based on low-rank decomposition, is proposed. Finally, continuous domain valence values are computed by using two modality network outputs and attention weights. Experimental results show that the proposed fusion network provides an improved performance of about 6.9% over the video modality network for the MAHNOB human computer interface (MAHNOB-HCI) dataset. Also, we achieved the performance improvement even for our proprietary dataset.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures


Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Hochreiter, S., & Schmidhuber, J. (1997) · Neural Computation · doi:10.1162/neco.1997.9.8.1735 · Cited by 102,318 · cited 1×
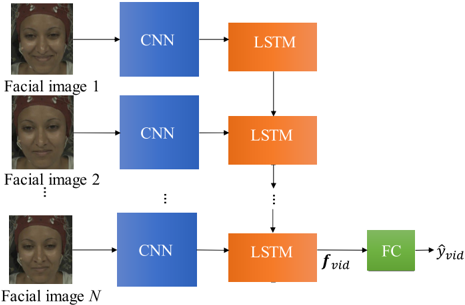
“Next, CNN extracts the features from each facial image, and the CNN features pass through LSTM [25] to generate a video feature f vid whose length is 2048.”
MethodImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333 · cited 2×
“Therefore, the deep convolutional encoder is pre-trained with a well-known ImageNet [27], which is a huge–scale image classification dataset with 1000 classes, and the pre-trained network is fine-tuned with the FER2013 dataset [28], which consists of 32,298 images with 7 emotional classes.”
BackgroundMethodDensely Connected Convolutional Networks
Huang, G., Liu, Z., Van Der Maaten, L., & Weinberger, K. Q. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.243 · Cited by 48,566
DEAP: A Database for Emotion Analysis ;Using Physiological Signals
Koelstra, S., Muhl, C., Soleymani, M., Lee, J.-S., Yazdani, A., Ebrahimi, T., Pun, T., Nijholt, A., & Patras, I. (2012) · IEEE Transactions on Affective Computing · doi:10.1109/t-affc.2011.15 · Cited by 5,093 · cited 1×
“TheDatabase for Emotion Analysis using Physiological signals (DEAP) dataset [17] and the MAHNOB-HCI dataset [18], which sensed EEG signals with facial videos when humans feel emotions, were released in 2012.”
MethodLucey, P., Cohn, J. F., Kanade, T., Saragih, J., Ambadar, Z., & Matthews, I. (2010) · 2010 IEEE Computer Society Conference on Computer Vision and Pattern Recognition - Workshops · doi:10.1109/cvprw.2010.5543262 · Cited by 4,303 · cited 2×
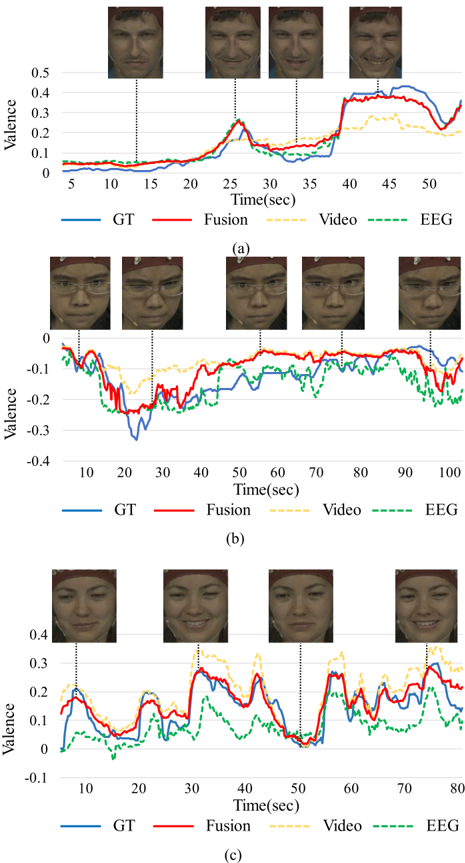
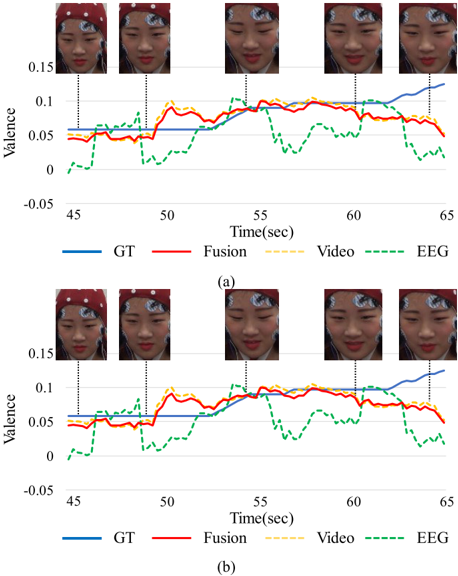
“Also, in interval [15], [35] of Fig.”
Method(2011) · Cited by 2,752
Opensmile: the munich versatile and fast open-source audio feature extractor
Eyben, F., Wöllmer, M., & Schuller, B. (2010) · Proceedings of the 18th ACM international conference on Multimedia · doi:10.1145/1873951.1874246 · Cited by 2,642
Challenges in Representation Learning: A Report on Three Machine Learning Contests
Goodfellow, I. J., Erhan, D., Carrier, P. L., Courville, A., Mirza, M., Hamner, B., Cukierski, W., Tang, Y., Thaler, D., Lee, D.-H., et al. (2013) · Lecture Notes in Computer Science · doi:10.1007/978-3-642-42051-1_16 · Cited by 1,719
A Multimodal Database for Affect Recognition and Implicit Tagging
Soleymani, M., Lichtenauer, J., Pun, T., & Pantic, M. (2012) · IEEE Transactions on Affective Computing · doi:10.1109/t-affc.2011.25 · Cited by 1,664 · cited 3×
“Since two modality networks are trained independently and fusion is done through the multimodal attention network at the output stage, the proposed method is easier to learn than the conventional method [14], which conducts end-to-end learning with pre-fused multimodal input.”
BackgroundMethodInfluentialEEG Emotion Recognition Using Dynamical Graph Convolutional Neural Networks
Song, T., Zheng, W., Song, P., & Cui, Z. (2020) · IEEE Transactions on Affective Computing · doi:10.1109/taffc.2018.2817622 · Cited by 1,597 · cited 5×
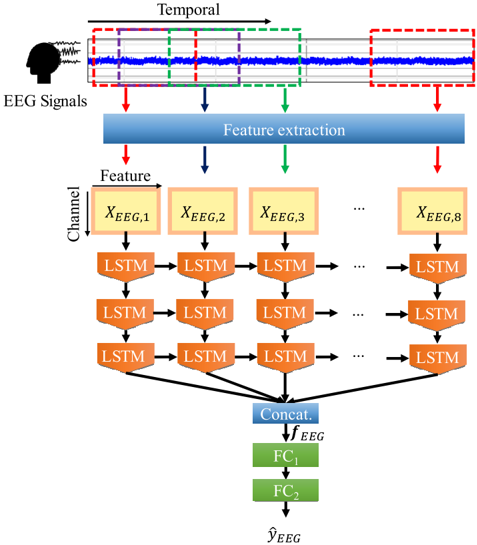
“Since then, many EEG-based emotion recognition algorithms have been developed [6]–[8], [52], [53].”
BackgroundMethodInfluentialMultimodal Compact Bilinear Pooling for Visual Question Answering and Visual Grounding
Fukui, A., Park, D. H., Yang, D., Rohrbach, A., Darrell, T., & Rohrbach, M. (2016) · Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d16-1044 · Cited by 1,582 · cited 1×
“Fukui et al. achieved the compacter operation by applying fast Fourier transform (FFT) to the outer product process of the features of each modality [41].”
MethodEfficient Low-rank Multimodal Fusion With Modality-Specific Factors
Liu, Z., Shen, Y., Lakshminarasimhan, V. B., Liang, P. P., Bagher Zadeh, A., & Morency, L.-P. (2018) · Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p18-1209 · Cited by 1,170 · cited 3×
“To solve this problem, we propose a new multimodal attention network using low-rank decomposition [39], [42].”
BackgroundMethodUsing the International 10-20 EEG System for Positioning of Transcranial Magnetic Stimulation
Herwig, U., Satrapi, P., & Schönfeldt-Lecuona, C. (2003) · Brain Topography · doi:10.1023/b:brat.0000006333.93597.9d · Cited by 1,098
Feature Extraction and Selection for Emotion Recognition from EEG
Jenke, R., Peer, A., & Buss, M. (2014) · IEEE Transactions on Affective Computing · doi:10.1109/taffc.2014.2339834 · Cited by 1,081
Gated Fusion Network for Single Image Dehazing
Ren, W., Ma, L., Zhang, J., Pan, J., Cao, X., Liu, W., & Yang, M.-H. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00343 · Cited by 973
EEG-Based Emotion Recognition Using Regularized Graph Neural Networks
Zhong, P., Wang, D., & Miao, C. (2022) · IEEE Transactions on Affective Computing · doi:10.1109/taffc.2020.2994159 · Cited by 910 · cited 3×
“Since then, many EEG-based emotion recognition algorithms have been developed [6]–[8], [52], [53].”
BackgroundAnalysis of emotion recognition using facial expressions, speech and multimodal information
Busso, C., Deng, Z., Yildirim, S., Bulut, M., Lee, C. M., Kazemzadeh, A., Lee, S., Neumann, U., & Narayanan, S. (2004) · Proceedings of the 6th international conference on Multimodal interfaces · doi:10.1145/1027933.1027968 · Cited by 840 · cited 1×
“proposed an emotion recognition mechanism based on multimodal signals where two or more signals among video, voice, and bio-signals are employed for emotion recognition [10].”
BackgroundSeparating Style and Content with Bilinear Models
Tenenbaum, J. B., & Freeman, W. T. (2000) · Neural Computation · doi:10.1162/089976600300015349 · Cited by 840 · cited 3×
“Firstly, three different fusion methods were evaluated: feature concatenation & FC layer, bilinear pooling [51], and low-rank decomposition.”
BackgroundMethodJoint Fine-Tuning in Deep Neural Networks for Facial Expression Recognition
Jung, H., Lee, S., Yim, J., Park, S., & Kim, J. (2015) · 2015 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2015.341 · Cited by 781 · cited 2×
“Recently, various emotion recognition mechanisms based on convolutional neural network (CNN) which are trained in an end-to-end manner have been developed and showed reliable performance [3], [4].”
BackgroundMethodMulti-modal Factorized Bilinear Pooling with Co-attention Learning for Visual Question Answering
Yu, Z., Yu, J., Fan, J., & Tao, D. (2017) · 2017 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2017.202 · Cited by 758
AMIGOS: A Dataset for Affect, Personality and Mood Research on Individuals and Groups
Miranda-Correa, J. A., Abadi, M. K., Sebe, N., & Patras, I. (2021) · IEEE Transactions on Affective Computing · doi:10.1109/taffc.2018.2884461 · Cited by 709
Challenges in representation learning: A report on three machine learning contests
Goodfellow, I. J., Erhan, D., Luc Carrier, P., Courville, A., Mirza, M., Hamner, B., Cukierski, W., Tang, Y., Thaler, D., Lee, D.-H., et al. (2015) · Neural Networks · doi:10.1016/j.neunet.2014.09.005 · Cited by 697
S^3FD: Single Shot Scale-Invariant Face Detector
Zhang, S., Zhu, X., Lei, Z., Shi, H., Wang, X., & Li, S. Z. (2017) · 2017 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2017.30 · Cited by 653
Analysis of EEG Signals and Facial Expressions for Continuous Emotion Detection
Soleymani, M., Asghari-Esfeden, S., Fu, Y., & Pantic, M. (2016) · IEEE Transactions on Affective Computing · doi:10.1109/taffc.2015.2436926 · Cited by 552 · cited 10×
“In [6], PSD features were extracted from EEG signals, and the emotion states were estimated by applying a continuous-time conditional random field (CRF) and LSTM to PSD features.”
BackgroundMethodInfluentialFEELTRACE: an instrument for recording perceived emotion in real time
Cowie, R., Douglas‐Cowie, E., Savvidou, S. M., & McMahon, E. R. (2000) · Research Portal (Queen's University Belfast) · Cited by 539
ASCERTAIN: Emotion and Personality Recognition Using Commercial Sensors
Subramanian, R., Wache, J., Abadi, M. K., Vieriu, R. L., Winkler, S., & Sebe, N. (2018) · IEEE Transactions on Affective Computing · doi:10.1109/taffc.2016.2625250 · Cited by 535 · cited 1×
“For example, Subramanian et al. built a multimodal dataset to recognize personality as well as emotion [56].”
BackgroundKetkar, N. (2017) · Deep Learning with Python · doi:10.1007/978-1-4842-2766-4_12 · Cited by 443 · cited 1×
“The proposed method was implemented using Pytorch [31], and the computing environments for learning were a Xeon E5-2560 and a GTX1080Ti.”
MethodFacial Expression Recognition by De-expression Residue Learning
Yang, H., Ciftci, U., & Yin, L. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00231 · Cited by 439 · cited 2×
“Recently, various emotion recognition mechanisms based on convolutional neural network (CNN) which are trained in an end-to-end manner have been developed and showed reliable performance [3], [4].”
BackgroundMethodRecognition of emotions using multimodal physiological signals and an ensemble deep learning model
Yin, Z., Zhao, M., Wang, Y., Yang, J., & Zhang, J. (2017) · Computer Methods and Programs in Biomedicine · doi:10.1016/j.cmpb.2016.12.005 · Cited by 416
Attention-Based Multimodal Fusion for Video Description
Hori, C., Hori, T., Lee, T.-Y., Zhang, Z., Harsham, B., Hershey, J. R., Marks, T. K., & Sumi, K. (2017) · 2017 IEEE International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2017.450 · Cited by 401 · cited 1×
“The attention-based method [36], [50] and the gated fusion method [20]–[22] are the representative hard-thresholding approaches.”
MethodMultimodal Compact Bilinear Pooling for Visual Question Answering and Visual GroundingPreprint
Fukui, A., Park, D. H., Yang, D., et al. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1606.01847 · Cited by 388 · cited 1×
“Fukui et al. achieved the compacter operation by applying fast Fourier transform (FFT) to the outer product process of the features of each modality [41].”
MethodJiang, Y.-G., Wu, Z., Wang, J., Xue, X., & Chang, S.-F. (2018) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2017.2670560 · Cited by 381 · cited 1×
“the speech processing field [19] and recently in the field of emotion recognition [45].”
BackgroundFacial Action Unit Recognition by Exploiting Their Dynamic and Semantic Relationships
Tong, Y., Liao, W., & Ji, Q. (2007) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2007.1094 · Cited by 378 · cited 2×
“Tong et al. [1] detected activated areas in the face, and defined action units (AU) according to their positions and shapes, and then classified facial expressions according to AU types or AU combinations.”
BackgroundDeep Affect Prediction in-the-Wild: Aff-Wild Database and Challenge, Deep Architectures, and Beyond
Kollias, D., Tzirakis, P., Nicolaou, M. A., Papaioannou, A., Zhao, G., Schuller, B., Kotsia, I., & Zafeiriou, S. (2019) · International Journal of Computer Vision · doi:10.1007/s11263-019-01158-4 · Cited by 377 · cited 4×
“For example, three-dimensional CNNs [13] and CNN-LSTM–based networks [46] were proposed for FER on the AFEW dataset.”
BackgroundMethodInfluentialGhimire, D., & Lee, J. (2013) · Sensors · doi:10.3390/s130607714 · Cited by 291 · cited 2×
“With rapid development of algorithms to extract landmarks, i.e., locations of facial key points, many facial expression recognition (FER) algorithms using landmark information have been proposed [2].”
BackgroundMethodA Novel EEG Feature Extraction Method Using Hjorth Parameter
Oh, S.-H., Lee, Y.-R., & Kim, H.-N. (2014) · International Journal of Electronics and Electrical Engineering · doi:10.12720/ijeee.2.2.106-110 · Cited by 260 · cited 1×
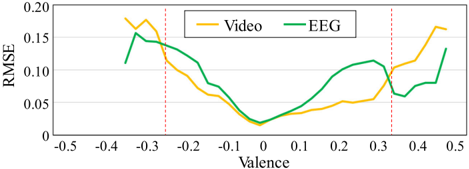
“On the other hand, in interval [30], [43] and interval [53], [80] of Fig.”
BackgroundAccurate EEG-Based Emotion Recognition on Combined Features Using Deep Convolutional Neural Networks
Chen, J. X., Zhang, P. W., Mao, Z. J., Huang, Y. F., Jiang, D. M., & Zhang, Y. N. (2019) · IEEE Access · doi:10.1109/access.2019.2908285 · Cited by 248 · cited 2×
“Chen et al. combined temporal and frequency features extracted from EEG signals, and applied CNN to the combined features [52].”
BackgroundMethodAFEW-VA database for valence and arousal estimation in-the-wild
Kossaifi, J., Tzimiropoulos, G., Todorovic, S., & Pantic, M. (2017) · Image and Vision Computing · doi:10.1016/j.imavis.2017.02.001 · Cited by 236 · cited 1×
“One is the AFEW valence arousal (AFEW-VA) dataset [47] that reconfigures discrete labels of the AFEW dataset, and the other is the Affect-in-theWild (Aff-wild) dataset, which annotates human emotional responses for YouTube contents [46].”
BackgroundLocality-Sensitive Deconvolution Networks with Gated Fusion for RGB-D Indoor Semantic Segmentation
Cheng, Y., Cai, R., Li, Z., Zhao, X., & Huang, K. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.161 · Cited by 229 · cited 1×
“The attention-based method [36], [50] and the gated fusion method [20]–[22] are the representative hardthresholding approaches.”
MethodBLOCK: Bilinear Superdiagonal Fusion for Visual Question Answering and Visual Relationship Detection
Ben-younes, H., Cadene, R., Thome, N., & Cord, M. (2019) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v33i01.33018102 · Cited by 219
From individual to group-level emotion recognition: EmotiW 5.0
Dhall, A., Goecke, R., Ghosh, S., Joshi, J., Hoey, J., & Gedeon, T. (2017) · Proceedings of the 19th ACM International Conference on Multimodal Interaction · doi:10.1145/3136755.3143004 · Cited by 218 · cited 2×
“On the other hand, a world-wide emotion recognition challenge called Emotion Recognition in the Wild (EmotiW) [11] ranks competing algorithms [12], [13] through performance evaluation for Acted Facial Expressions in the Wild (AFEW) dataset that is composed of wild audio-visual data excerpted from…”
BackgroundMFAS: Multimodal Fusion Architecture Search
Perez-Rua, J.-M., Vielzeuf, V., Pateux, S., Baccouche, M., & Jurie, F. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00713 · Cited by 193 · cited 3×
“Vielzeuf et al. [35] and Pérez-Rúa et al. [38] proposed to fuse multi-modal features through multiple layers and refine the fused features.”
BackgroundMethodCentralNet: A Multilayer Approach for Multimodal Fusion
Vielzeuf, V., Lechervy, A., Pateux, S., & Jurie, F. (2019) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-11024-6_44 · Cited by 166
Learning supervised scoring ensemble for emotion recognition in the wild
Hu, P., Cai, D., Wang, S., Yao, A., & Chen, Y. (2017) · Proceedings of the 19th ACM International Conference on Multimodal Interaction · doi:10.1145/3136755.3143009 · Cited by 162 · cited 1×
“On the other hand, a world-wide emotion recognition challenge called Emotion Recognition in the Wild (EmotiW) [11] ranks competing algorithms [12], [13] through performance evaluation for Acted Facial Expressions in the Wild (AFEW) dataset that is composed of wild audio-visual data excerpted from sitcoms and movies.”
BackgroundHadamard Product for Low-rank Bilinear Pooling
Kim, J.-H., On, K.-W., Lim, W., Kim, J., Ha, J.-W., & Zhang, B. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1610.04325 · Cited by 154
Analysis of EEG signals by combining eigenvector methods and multiclass support vector machines
Übeylı, E. D. (2007) · Computers in Biology and Medicine · doi:10.1016/j.compbiomed.2007.06.002 · Cited by 140 · cited 1×
“the speech processing field [19] and recently in the field of emotion recognition [45].”
BackgroundČukić, M., Stokić, M., Simić, S., & Pokrajac, D. (2020) · Cognitive Neurodynamics · doi:10.1007/s11571-020-09581-x · Cited by 130
Deep Physiological Affect Network for the Recognition of Human Emotions
Kim, B. H., & Jo, S. (2018) · IEEE Transactions on Affective Computing · doi:10.1109/taffc.2018.2790939 · Cited by 114 · cited 2×
“Kim and Jo explored that the channels on which EEG signals are activated differ depending on the emotional state [7].”
BackgroundMethodLook, Listen and Learn — A Multimodal LSTM for Speaker Identification
Ren, J., Hu, Y., Tai, Y.-W., Wang, C., Xu, L., Sun, W., & Yan, Q. (2016) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v30i1.10471 · Cited by 91 · cited 1×
“, a multimodal LSTM [54].”
Mavratzakis, A., Herbert, C., & Walla, P. (2016) · NeuroImage · doi:10.1016/j.neuroimage.2015.09.065 · Cited by 89 · cited 1×
“In order to compensate for this, emotion recognition technology using additional biosignals, such as the electromyogram (EMG) and galvanic skin response (GSR), has recently been studied [8], [32].”
BackgroundMulti-modal Conditional Attention Fusion for Dimensional Emotion Prediction
Chen, S., & Jin, Q. (2016) · Proceedings of the 24th ACM international conference on Multimedia · doi:10.1145/2964284.2967286 · Cited by 86 · cited 3×
“As an example of an application to emotion recognition using video and audio modalities, Chen and Jin concatenated each modality input and interim features, and then adjusted the output weights of the video and audio modalities by calculating the attention weight using the FC layer [36].”
BackgroundMethodEfficient Low-rank Multimodal Fusion with Modality-Specific FactorsPreprint
Liu, Z., Shen, Y., Lakshminarasimhan, V., Liang, P. P., Zadeh, A., & Morency, L. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1806.00064 · Cited by 80 · cited 3×
“To solve this problem, we propose a new multimodal attention network using low-rank decomposition [39], [42].”
BackgroundMethodGated Fusion Network for Joint Image Deblurring and Super-ResolutionPreprint
Zhang, X., Dong, H., Hu, Z., Lai, W., Wang, F., & Yang, M. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1807.10806 · Cited by 78 · cited 1×
“The attention-based method [36], [50] and the gated fusion method [20]–[22] are the representative hard-thresholding approaches.”
MethodEmotion recognition from audio signals using Support Vector Machine
Sinith, M. S., Aswathi, E., Deepa, T., Shameema, C. P., & Rajan, S. (2015) · IEEE Recent Advances in Intelligent Computational Systems · doi:10.1109/raics.2015.7488403 · Cited by 67 · cited 1×
“On the other hand, there were many attempts to recognize human emotions from tone information of voice signals [5].”
BackgroundJointly Learning Energy Expenditures and Activities Using Egocentric Multimodal Signals
Nakamura, K., Yeung, S., Alahi, A., & Fei-Fei, L. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.721 · Cited by 67 · cited 2×
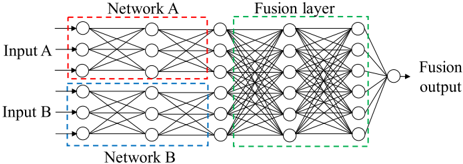
“1, recent multimodal deep learning networks are based on a fully-connected (FC) layer structure, adopting an approach of concatenating input modalities or intermediate features for delivery to the next layer [18].”
BackgroundMethodLook, Listen and Learn - A Multimodal LSTM for Speaker IdentificationPreprint
Ren, J., Hu, Y., Tai, Y., et al. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1602.04364 · Cited by 53 · cited 1×
“, a multimodal LSTM [54].”
Kim, D. H., Lee, M. K., Choi, D. Y., & Song, B. C. (2017) · INTERNATIONAL CONFERENCE ON MULTIMODAL INTERACTION · doi:10.1145/3136755.3143005 · Cited by 50 · cited 2×
“For example, three-dimensional CNNs [13] and CNN-LSTM–based networks [46] were proposed for FER on the AFEW dataset.”
BackgroundMethodSelf-citationClerico, A., Gupta, R., & Falk, T. H. (2015) · International IEEE/EMBS Conference on Neural Engineering · doi:10.1109/ner.2015.7146774 · Cited by 27 · cited 1×
“On the other hand, in interval [30], [43] and interval [53], [80] of Fig.”
BackgroundEstimation of Affective Level in the Wild with Multiple Memory Networks
Li, J., Chen, Y., Xiao, S., Zhao, J. C., Roy, S., Feng, J., Yan, S., & Sim, T. (2017) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw.2017.244 · Cited by 19 · cited 1×
“To do this, CNN-LSTM– based networks are widely used [46], [48].”
Method
Research works printed but not linked: 3
- zhang, 2017, S3FD: Single shot scale-invariant face detector, Proc IEEE Int Conf Comput Vis, 192
- valstar, 2010, Induced disgust, happiness and surprise: An addition to the MMI facial expression database, Proc Third Int'l Workshop EMOTION (satellite of LREC) Corpora for Research on Emotion and Affect, 65
- cukic, 2018, EEG machine learning with Higuchi fractal dimension and sample entropy as features for successful detection of depression, arXiv 1803 05985
Cited by
A review on EEG-based multimodal learning for emotion recognition
Pillalamarri, R., & Shanmugam, U. (2025) · Artificial Intelligence Review · doi:10.1007/s10462-025-11126-9 · Cited by 183
Multimodal Emotion Recognition From EEG Signals and Facial Expressions
Wang, S., Qu, J., Zhang, Y., & Zhang, Y. (2023) · IEEE Access · doi:10.1109/access.2023.3263670 · Cited by 124
“For example, Choi et al. [21] proposed a multimodal fusion network integrating video and EEG modalities.”
BackgroundMultimodal Emotion Recognition Using a Hierarchical Fusion Convolutional Neural Network
Zhang, Y., Cheng, C., & Zhang, Y. (2021) · IEEE Access · doi:10.1109/access.2021.3049516 · Cited by 84
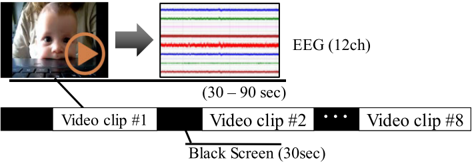
“Each video clip was about 34 to 117 seconds [30].”
BackgroundMultimodal emotion recognition: A comprehensive review, trends, and challenges
Ramaswamy, M. P. A., & Palaniswamy, S. (2024) · WIREs Data Mining and Knowledge Discovery · doi:10.1002/widm.1563 · Cited by 70
Ding, Z., Ji, Y., Gan, Y., Wang, Y., & Xia, Y. (2024) · Multimedia Tools and Applications · doi:10.1007/s11042-023-18096-6 · Cited by 64
“In line with the multimodal nature of emotion recognition models, existing frameworks like CNN and Gated Recurrent Units (GRU) are also being used to extract emotional features from videos, actions, and even brain activity, aiming to enhance multi-dimensional recognition accuracy [87, 138].”
Metadata
- Authors
- Choi, D. Y., Kim, D.-H., & Song, B. C.
- Affiliations
- Inha University (KR)
- Venue
- IEEE Access
- Published
- 2020
- Volume
- 8
- Pages
- 203814-203826
- ISSN
- 2169-3536 (ISSN-L)
- OpenAlex
- W3101150053
- Cited by
- 39
- References
- 58
- Citations by year
- 2026: 5 · 2025: 14 · 2024: 7 · 2023: 6 · 2022: 2 · 2021: 5
- FWCI
- 3.14
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- IEEE Access (publishedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- Korea Evaluation Institute of Industrial Technology (10073154)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Emotion and Mood Recognition
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Face and Expression Recognition
- Life Sciences › Neuroscience › Cognitive Neuroscience › EEG and Brain-Computer Interfaces
- Keywords
- multimodal fusion, bilinear pooling, low-rank decomposition, EEG features, human-computer interaction
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
