

Learning With Sharing: An Edge-Optimized Incremental Learning Method for Deep Neural Networks
Open accessThe DOI matches its Crossref record; 39 of the 40 references it cites were found in a registry or an index.
Abstract
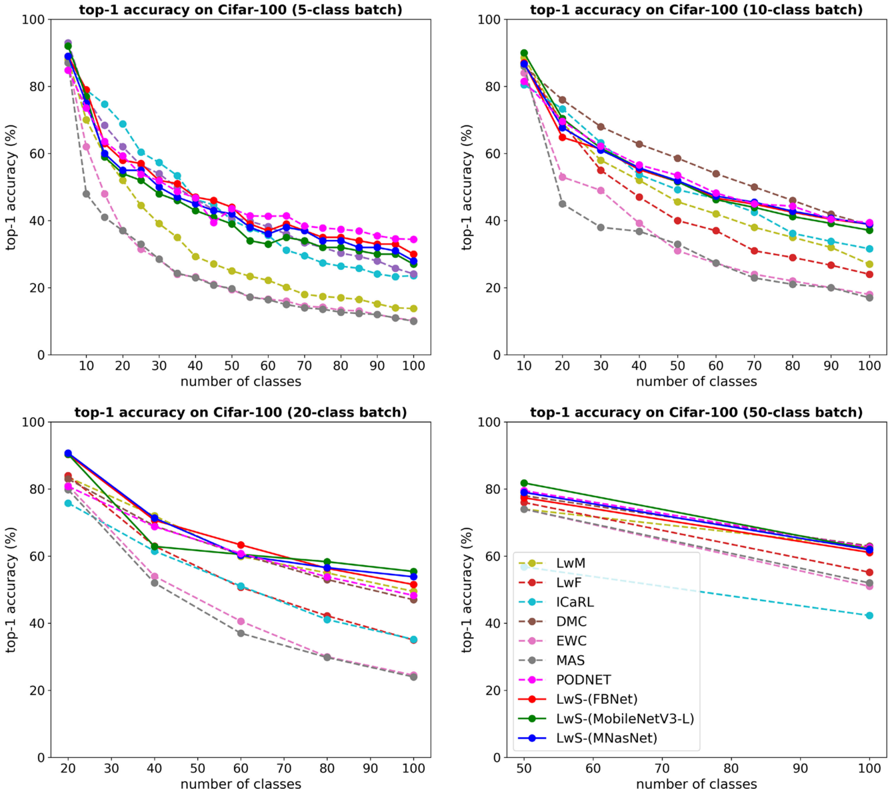
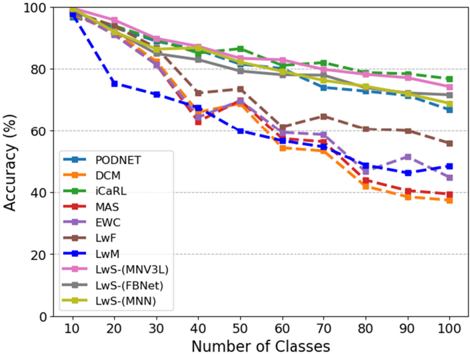
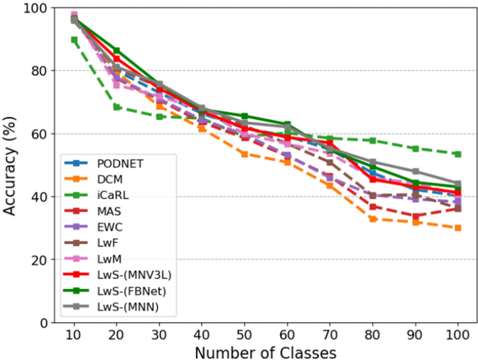
Incremental learning techniques aim to increase the capability of Deep Neural Network (DNN) model to add new classes in the pre-trained model. However, DNNs suffer from catastrophic forgetting during the incremental learning process. Existing incremental learning techniques try to reduce the effect of catastrophic forgetting by either using previous samples of data while adding new classes in the model or designing complex model architectures. This leads to high design complexity and memory requirements which make incremental learning impossible to implement on edge devices that have limited memory and computation resources. So, we propose a new incremental learning technique Learning with Sharing (LwS) based on the concept of transfer learning. The main aims of LwS are reduction in training complexity and storage memory requirements while achieving high accuracy during the incremental learning process. We perform cloning and sharing of full connected (FC) layers to add new classes in the model incrementally. Our proposed technique can preserve the knowledge of existing classes and add new classes without storing data from the previous classes. We show that our proposed technique outperforms the state-of-the-art techniques in accuracy comparison for Cifar-100, Caltech-101, and UCSD Birds datasets.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474 · cited 2×
“DNNs have automated many tasks, such as face recognition [1], object detection [2] and classi fi cation [3] that were not possible with such high accuracy a few years ago.”
BackgroundMethodMobileNetV2: Inverted Residuals and Linear Bottlenecks
Sandler, M., Howard, A., Zhu, M., Zhmoginov, A., & Chen, L.-C. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00474 · Cited by 28,755 · cited 1×
“As compared to previous models of MobileNets [18], [36], MobileNetV3 [33] makes use of hard swish (HS) activation function in convolution layers due to low computation complexity as compared to swish function.”
MethodMobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications
Howard, A. G., Zhu, M., Chen, B., Kalenichenko, D., Wang, W., Weyand, T., Andreetto, M., & Adam, H. (2017) · arXiv · doi:10.48550/arxiv.1704.04861 · Cited by 19,015 · cited 2×
“As compared to previous models of MobileNets [18], [36], MobileNetV3 [33] makes use of hard swish (HS) activation function in convolution layers due to low computation complexity as compared to swish function.”
MethodHoward, A., Sandler, M., Chen, B., Wang, W., Chen, L.-C., Tan, M., Chu, G., Vasudevan, V., Zhu, Y., Pang, R., et al. (2019) · 2019 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00140 · Cited by 9,708 · cited 3×
“As compared to previous models of MobileNets [18], [36], MobileNetV3 [33] makes use of hard swish (HS) activation function in convolution layers due to low computation complexity as compared to swish function.”
BackgroundMethodOvercoming catastrophic forgetting in neural networks
Kirkpatrick, J., Pascanu, R., Rabinowitz, N., Veness, J., Desjardins, G., Rusu, A. A., Milan, K., Quan, J., Ramalho, T., Grabska-Barwinska, A., et al. (2017) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.1611835114 · Cited by 7,899 · cited 6×
“The selection of the training process in [30], [31], [20], and [29] depends upon the incremental task settings.”
BackgroundMethodInfluentialLi, Z., & Hoiem, D. (2018) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2017.2773081 · Cited by 4,202
iCaRL: Incremental Classifier and Representation Learning
Rebuffi, S.-A., Kolesnikov, A., Sperl, G., & Lampert, C. H. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.587 · Cited by 3,988 · cited 9×
“The training phase of incremental learning methods has large computation requirements [8], [10] – [13], so it is dif fi cult to perform training of such algorithms at the edge devices due to constraints of computation power, storage memory, and power consumption.”
BackgroundMethodResultInfluentialCatastrophic Interference in Connectionist Networks: The Sequential Learning Problem
McCloskey, M., & Cohen, N. J. (1989) · Psychology of Learning and Motivation · doi:10.1016/s0079-7421(08)60536-8 · Cited by 3,770 · cited 1×
“One can perform training of DNN model with only new data, but this leads to deterioration of classi fi - cation accuracy which is also known as catastrophic forgetting [9].”
MnasNet: Platform-Aware Neural Architecture Search for Mobile
Tan, M., Chen, B., Pang, R., Vasudevan, V., Sandler, M., Howard, A., & Le, Q. V. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00293 · Cited by 3,416 · cited 2×
“MNasNet [35] focuses on the reduction of the inference delay which can be helpful for LwS to speed up data processing in the inference stage.”
MethodFei-Fei, L., Fergus, R., & Perona, P. (2005) · 2004 Conference on Computer Vision and Pattern Recognition Workshop · doi:10.1109/cvpr.2004.383 · Cited by 2,502
Memory Aware Synapses: Learning What (not) to Forget
Aljundi, R., Babiloni, F., Elhoseiny, M., Rohrbach, M., & Tuytelaars, T. (2018) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-01219-9_9 · Cited by 1,590
Gradient Episodic Memory for Continual Learning
Lopez-Paz, D., & Ranzato, M. (2017) · arXiv · doi:10.48550/arxiv.1706.08840 · Cited by 1,403 · cited 3×
“Inthedomain of incremental learning, [26] – [28] are also notable works.”
BackgroundMethodInfluentialLarge Scale Incremental Learning
Wu, Y., Chen, Y., Wang, L., Ye, Y., Liu, Z., Guo, Y., & Fu, Y. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00046 · Cited by 1,313 · cited 2×
“FC þ 2D Conv layers C: Only FC layers LwM [12], LwF [10], DMC [24], LSIL [21], GEM [26], PODNET [25], DCM [27], PNN [23], iCaRL [8] 2x A ST [28] 2x B PNS [11] 1.3-1.6x B PackNet [40] 1.05-1.6x A, B (Task dependent) MAS [30], EWC [29], DAN [20], FTDNN [31] 1.05-1.6x B, C (Task dependent) LwS…”
BackgroundMethodInfluentialRusu, A. A., Rabinowitz, N. C., Desjardins, G., Soyer, H., Kirkpatrick, J., Kavukcuoglu, K., Pascanu, R., & Hadsell, R. (2016) · arXiv · doi:10.48550/arxiv.1606.04671 · Cited by 1,307 · cited 2×
“FC þ 2D Conv layers C: Only FC layers LwM [12], LwF [10], DMC [24], LSIL [21], GEM [26], PODNET [25], DCM [27], PNN [23], iCaRL [8] 2x A ST [28] 2x B PNS [11] 1.3-1.6x B PackNet [40] 1.05-1.6x A, B (Task dependent) MAS [30], EWC [29], DAN [20], FTDNN [31] 1.05-1.6x B, C (Task dependent) LwS…”
BackgroundInfluentialFBNet: Hardware-Aware Efficient ConvNet Design via Differentiable Neural Architecture Search
Wu, B., Keutzer, K., Dai, X., Zhang, P., Wang, Y., Sun, F., Wu, Y., Tian, Y., Vajda, P., & Jia, Y. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.01099 · Cited by 1,261 · cited 2×
“FBNet [34] has been also developed for low-latency inference, hence it is also helpful for our proposed technique due to the utilization of network sharing scheme.”
MethodPackNet: Adding Multiple Tasks to a Single Network by Iterative Pruning
Mallya, A., & Lazebnik, S. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00810 · Cited by 1,258
End-to-End Incremental Learning
Castro, F. M., Marín-Jiménez, M. J., Guil, N., Schmid, C., & Alahari, K. (2018) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-01258-8_15 · Cited by 1,184
Fastai: A Layered API for Deep Learning
Howard, J., & Gugger, S. (2020) · Information · doi:10.3390/info11020108 · Cited by 971 · cited 1×
“Fastai v1 [32] library is used to perform all experiments on base models and incremental learning models.”
MethodTransferable Representation Learning with Deep Adaptation Networks
Long, M., Cao, Y., Cao, Z., Wang, J., & Jordan, M. I. (2019) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2018.2868685 · Cited by 676 · cited 2×
“This problem is solved by using transfer learning technique [5].”
MethodPODNet: Pooled Outputs Distillation for Small-Tasks Incremental Learning
Douillard, A., Cord, M., Ollion, C., Robert, T., & Valle, E. (2020) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-58565-5_6 · Cited by 638 · cited 9×
“Both DMC [24] and POD-NET [25] have a similar accuracy performance as LwS.”
BackgroundMethodResultInfluentialMulti-view Face Detection Using Deep Convolutional Neural Networks
Farfade, S. S., Saberian, M. J., & Li, L.-J. (2015) · Proceedings of the 5th ACM on International Conference on Multimedia Retrieval · doi:10.1145/2671188.2749408 · Cited by 572 · cited 1×
“DNNs have automated many tasks, such as face recognition [1], object detection [2] and classi fi cation [3] that were not possible with such high accuracy a few years ago.”
MethodDhar, P., Singh, R. V., Peng, K.-C., Wu, Z., & Chellappa, R. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00528 · Cited by 516 · cited 9×
“However, in terms of memory requirements and training methodology, there are some major differences between LwS, DMC [24], and LwM [12].”
BackgroundMethodInfluentialClass-incremental Learning via Deep Model Consolidation
Zhang, J., Zhang, J., Ghosh, S., Li, D., Tasci, S., Heck, L., Zhang, H., & Jay Kuo, C.-C. (2020) · 2020 IEEE Winter Conference on Applications of Computer Vision (WACV) · doi:10.1109/wacv45572.2020.9093365 · Cited by 328 · cited 10×
“However, in terms of memory requirements and training methodology, there are some major differences between LwS, DMC [24], and LwM [12].”
BackgroundMethodResultInfluentialTree-CNN: A hierarchical Deep Convolutional Neural Network for incremental learning
Roy, D., Panda, P., & Roy, K. (2020) · Neural Networks · doi:10.1016/j.neunet.2019.09.010 · Cited by 257 · cited 1×
“Tree-CNN was proposed by Roy et al. [16] which uses a tree-like architecture to grow the network with the arrival of new classes.”
MethodIncremental Learning Through Deep Adaptation
Rosenfeld, A., & Tsotsos, J. K. (2020) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2018.2884462 · Cited by 244 · cited 3×
“‘ Deep Adaptation Network (DAN) ’ [20] adds the new classes incrementally by increasing the number of fi lters in the base model.”
BackgroundInfluentialXiao, T., Zhang, J., Yang, K., Peng, Y., & Zhang, Z. (2014) · Proceedings of the 22nd ACM international conference on Multimedia · doi:10.1145/2647868.2654926 · Cited by 234 · cited 1×
“The work done by Xiao et al. [22] presents a tree-structured model to learn new classes.”
Side-Tuning: A Baseline for Network Adaptation via Additive Side Networks
Zhang, J. O., Sax, A., Zamir, A., Guibas, L., & Malik, J. (2020) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-58580-8_41 · Cited by 184 · cited 3×
“Inthedomain of incremental learning, [26] – [28] are also notable works.”
BackgroundMethodInfluentialFine-Tuning Deep Neural Networks in Continuous Learning Scenarios
Käding, C., Rodner, E., Freytag, A., & Denzler, J. (2017) · Lecture notes in computer science · doi:10.1007/978-3-319-54526-4_43 · Cited by 156 · cited 4×
“[30], [31], etc., either 2D convolution layers and fully connected layers are trained or only 2D convolutional layers or fully connected layers are trained.”
BackgroundInfluentialLatent Replay for Real-Time Continual Learning
Pellegrini, L., Graffieti, G., Lomonaco, V., & Maltoni, D. (2020) · 2020 IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) · doi:10.1109/iros45743.2020.9341460 · Cited by 137 · cited 1×
“Lorenzo et al. [17] proposed a latent replay for real-time continual learning.”
BackgroundLearning to Learn, from Transfer Learning to Domain Adaptation: A Unifying Perspective
Patricia, N., & Caputo, B. (2014) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2014.187 · Cited by 135 · cited 1×
“So, our approach to designing the incremental learning algorithm is based on transfer learning and domain adaptation [14].”
MethodCORe50: a New Dataset and Benchmark for Continuous Object Recognition
Lomonaco, V., & Maltoni, D. (2017) · arXiv · doi:10.48550/arxiv.1705.03550 · Cited by 135 · cited 1×
“The authors have added a latent replay layer in MobileNetV1 model [18] which grows to the size of 48MB for CORe50 dataset [19]. iCaRL [8] utilized a decoupled classi fi er and representation learning technique to perform incremental learning.”
MethodIncremental Learning in Deep Convolutional Neural Networks Using Partial Network Sharing
Sarwar, S. S., Ankit, A., & Roy, K. (2020) · IEEE Access · doi:10.1109/access.2019.2963056 · Cited by 120 · cited 8×
“In this experiment setting, PNS [11] can achieve an accuracy of 55.43% for Mobile-NetV3-L while sharing 60% of DNN model for each incremental group (T0, T1, T2, and T3) of Cifar-100 dataset.”
BackgroundMethodResultInfluentialHardware for machine learning: Challenges and opportunities
Sze, V., Chen, Y.-H., Emer, J., Suleiman, A., & Zhang, Z. (2018) · 2018 IEEE Custom Integrated Circuits Conference (CICC) · doi:10.1109/cicc.2018.8357072 · Cited by 97
Object detection and robotic sorting system in complex industrial environment
Liang, B., YanBo, W., ZhiHong, C., Liu, J., & Lin, J. (2017) · Chinese Automation Congress · doi:10.1109/cac.2017.8244092 · Cited by 23 · cited 1×
“Sorting robots are one example where the robots can perform the sorting of different objects using computer vision techniques [6].”
BackgroundReal-time video object recognition using convolutional neural network
Ahn, B. (2015) · doi:10.1109/ijcnn.2015.7280718 · Cited by 20 · cited 1×
“DNNs have automated many tasks, such as face recognition [1], object detection [2] and classi fi cation [3] that were not possible with such high accuracy a few years ago.”
MethodOn the use of XML for port communications
Englert, B., & Lam, S. (2009) · IFAC Proceedings Volumes · doi:10.3182/20090902-3-us-2007.0059 · Cited by 8
Class-Incremental Learning of Convolutional Neural Networks Based on Double Consolidation Mechanism
Jin, L., Liang, H., & Yang, C. (2020) · IEEE Access · doi:10.1109/access.2020.3025558 · Cited by 5 · cited 1×
“FC þ 2D Conv layers C: Only FC layers LwM [12], LwF [10], DMC [24], LSIL [21], GEM [26], PODNET [25], DCM [27], PNN [23], iCaRL [8] 2x A ST [28] 2x B PNS [11] 1.3-1.6x B PackNet [40] 1.05-1.6x A, B (Task dependent) MAS [30], EWC [29], DAN [20], FTDNN [31] 1.05-1.6x B, C (Task dependent) LwS…”
BackgroundInfluentialIncremental learning with deep neural networks using a test-time oracle.
Gepperth, A., & Gondal, S. A. (2018) · The European Symposium on Artificial Neural Networks · Cited by 4
Large Scale Incremental LearningPreprint
Wu, Y., Chen, Y., Wang, L., et al. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1905.13260 · Cited by 2 · cited 2×
“FC þ 2D Conv layers C: Only FC layers LwM [12], LwF [10], DMC [24], LSIL [21], GEM [26], PODNET [25], DCM [27], PNN [23], iCaRL [8] 2x A ST [28] 2x B PNS [11] 1.3-1.6x B PackNet [40] 1.05-1.6x A, B (Task dependent) MAS [30], EWC [29], DAN [20], FTDNN [31] 1.05-1.6x B, C (Task dependent) LwS…”
BackgroundMethodInfluential
Research works printed but not linked: 1
- TSUNG-HAN TSAI (Senior Member, IEEE) received the BS, MS, and PhD degrees in electrical engineering from the National Taiwan University, Taipei, Taiwan, in 1990, 1994, and 1998 respectively. From 1999 to 2000, he was an associate professor in electronic engi- neering with Fu Jen University. He joined National Central University in 2000. Since 2008 he was a full professor with the Department of Electrical Engineer- ing, National Central University. Currently he is also the director of Intelligent Chip and System Center, National Central University, and also serves as the Prin- cipal Investigator of the National Program for Intelligent Electronics. His research interests include VLSI signal processing, video/audio coding algorithms, DSP architecture design, wireless communication and system-on-chip design.
Cited by
You, L., Guo, Z., Zuo, B.-R., Chang, Y., & Yuen, C. (2024) · IEEE Internet of Things Journal · doi:10.1109/jiot.2024.3353793 · Cited by 23
A Survey of Incremental Deep Learning for Defect Detection in Manufacturing
Mohandas, R., Southern, M., O’Connell, E., & Hayes, M. J. (2024) · Big Data and Cognitive Computing · doi:10.3390/bdcc8010007 · Cited by 31
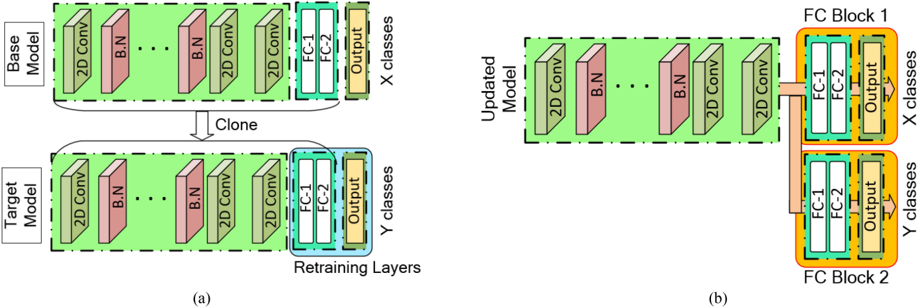
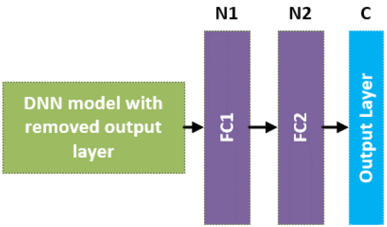
“Hussain et al. [108] proposed learning with sharing (LwS) as a method for incremental learning in deep learning framework optimised for Edge devices, which involves cloning of the initial DNN framework except the output layer and freezing all those layers excluding fully connected (FC) layers.”
MethodLi, X., Li, H., Sun, C., Fan, Q., Han, Z., & Leung, V. C. M. (2025) · IEEE Communications Surveys & Tutorials · doi:10.1109/comst.2025.3587225 · Cited by 21
“This approach allows the model to be locally updated based on newly obtained data [163], [164], [165], [166].”
Wu, J., Cheng, Z., Meng, J., Wang, L., & Lin, M. (2024) · IEEE Transactions on Energy Conversion · doi:10.1109/tec.2024.3410704 · Cited by 10
“Hussain et al. [19] proposed a new incremental learning technique, learning with sharing (LwS), which combines the concept of transfer learning.”
Guo, Z., You, L., Liu, S., He, J., & Zuo, B.-R. (2023) · Mathematics · doi:10.3390/math11081867 · Cited by 14
Metadata
- Authors
- Hussain, M. A., Huang, S.-A., & Tsai, T.-H.
- Affiliations
- National Central University (TW)
- National Central University, Taoyuan, Taiwan
- Venue
- IEEE Transactions on Emerging Topics in Computing
- Published
- 2023-04-01
- Volume
- 11
- Issue
- 2
- Pages
- 461-473
- ISSN
- 2168-6750 (ISSN-L)
- 2376-4562
- OpenAlex
- W4312935497
- Cited by
- 11
- References
- 40
- Citations by year
- 2025: 7 · 2024: 3 · 2023: 1
- FWCI
- 0.90
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Locations
- IEEE Transactions on Emerging Topics in Computing (publishedVersion, cc-by)
- Funders
- Industrial Technology Research Institute
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Data Stream Mining Techniques
- Keywords
- incremental learning, catastrophic forgetting, edge devices, transfer learning, memory-efficient training, deep neural network
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
