

The DOI matches its Crossref record; 81 of the 85 references it cites were found in a registry or an index.
Image Super-Resolution Via Iterative Refinement
Open accessAbstract
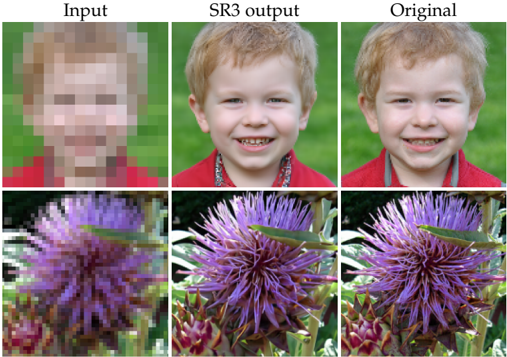
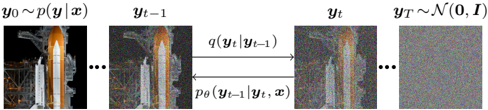
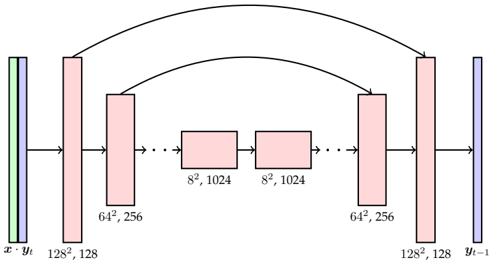
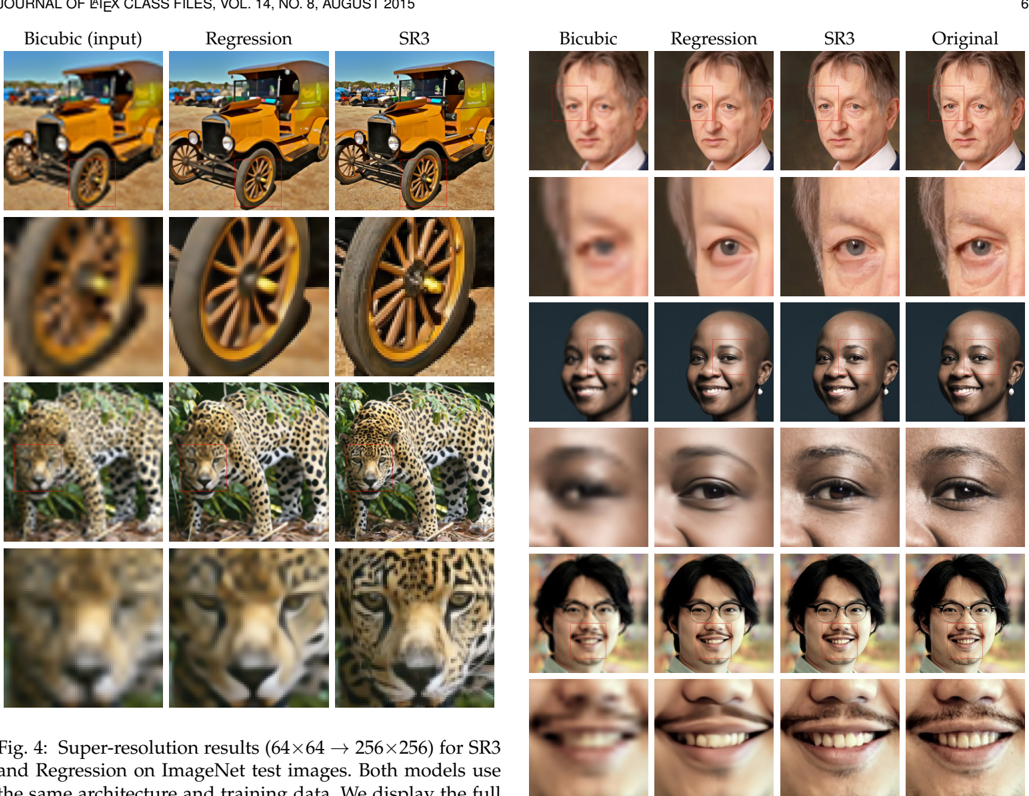
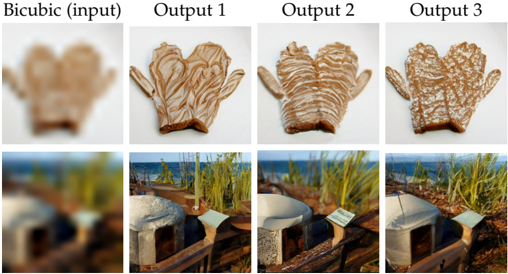
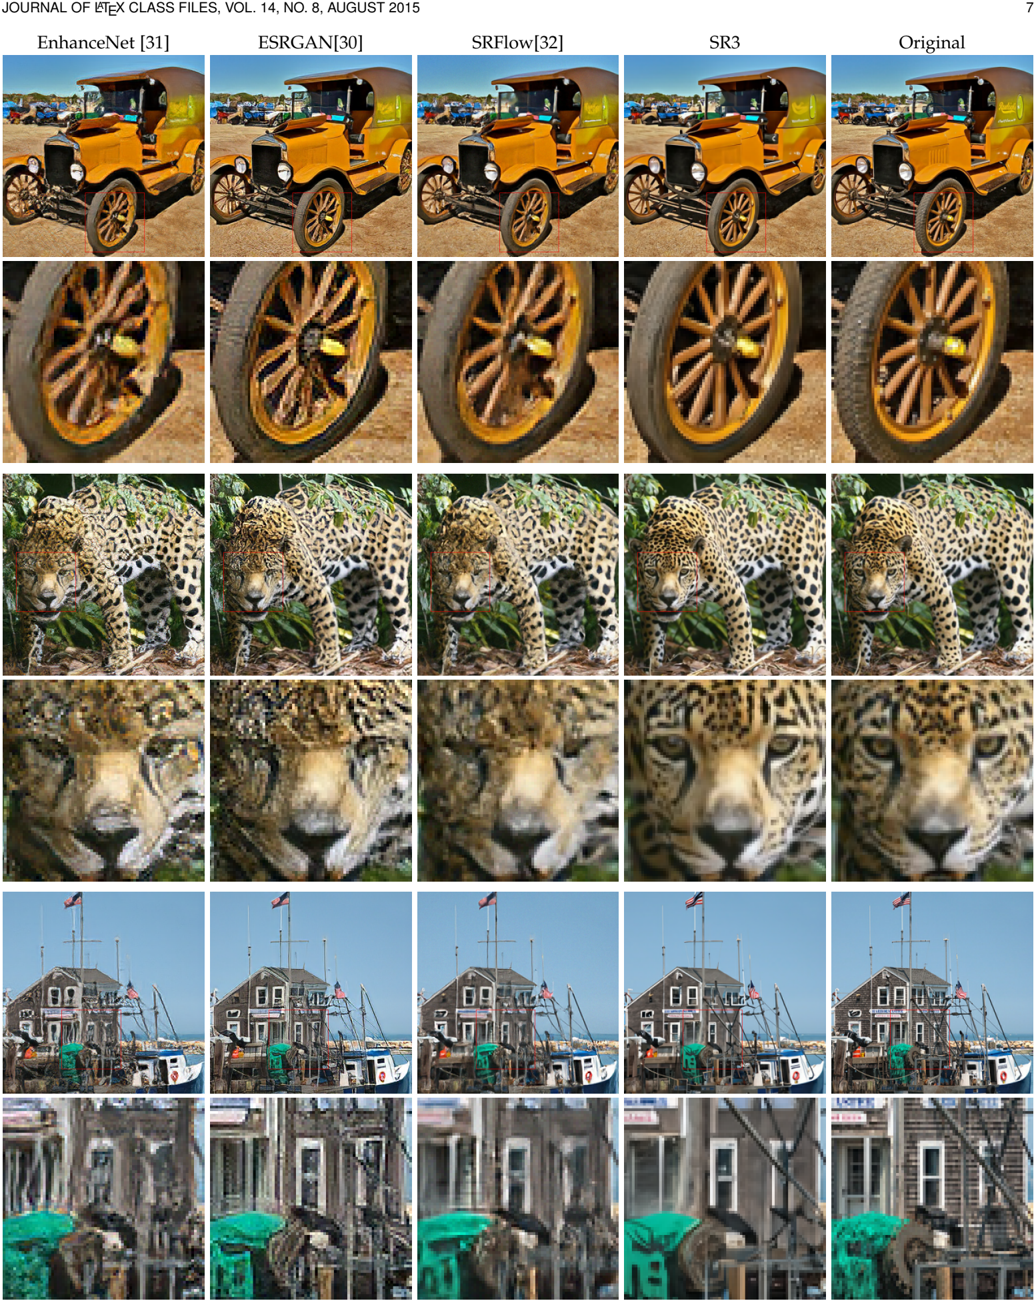
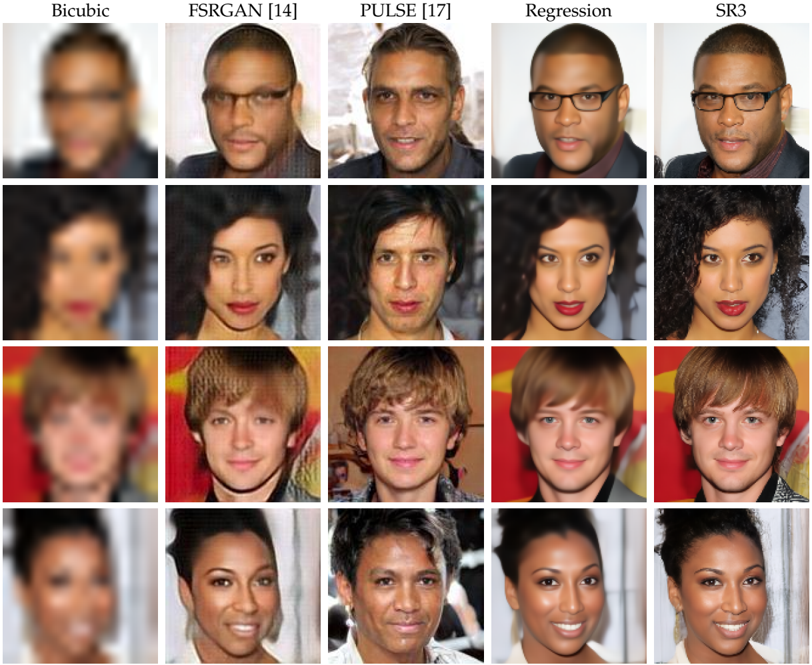
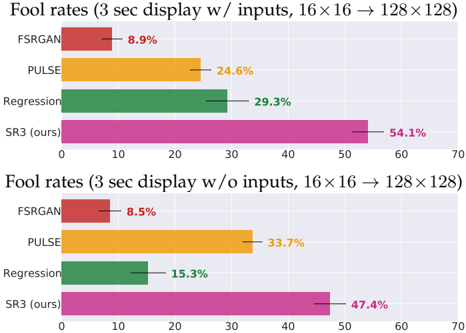
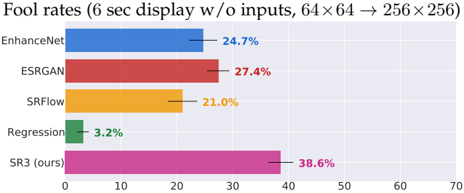
We present SR3, an approach to image Super-Resolution via Repeated Refinement. SR3 adapts denoising diffusion probabilistic models (Ho et al. 2020), (Sohl-Dickstein et al. 2015) to image-to-image translation, and performs super-resolution through a stochastic iterative denoising process. Output images are initialized with pure Gaussian noise and iteratively refined using a U-Net architecture that is trained on denoising at various noise levels, conditioned on a low-resolution input image. SR3 exhibits strong performance on super-resolution tasks at different magnification factors, on faces and natural images. We conduct human evaluation on a standard 8× face super-resolution task on CelebA-HQ for which SR3 achieves a fool rate close to 50%, suggesting photo-realistic outputs, while GAN baselines do not exceed a fool rate of 34%. We evaluate SR3 on a 4× super-resolution task on ImageNet, where SR3 outperforms baselines in human evaluation and classification accuracy of a ResNet-50 classifier trained on high-resolution images. We further show the effectiveness of SR3 in cascaded image generation, where a generative model is chained with super-resolution models to synthesize high-resolution images with competitive FID scores on the class-conditional 256×256 ImageNet generation challenge.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures





Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Both the SR3 and CDM directly apply the diffusion process to input images, which leads to larger evaluation steps.”
From Diffusion Models: A Comprehensive Survey of Methods and Applications (2024) · cites this paper as [200]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Low-light face videos suffer from severe noise and detail loss, limiting their use in surveillance and photography applications.”
From Temporally consistent low-light face video enhancement via video-to-video conditional diffusion (2026) · cites this paper as [5]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“This greatly improves FID on ImageNet 256×256, but does not reach the same performance as state-of-the-art models like BigGAN-deep [43, 53], as seen in Table 5.”
From Diffusion Models Beat GANs on Image Synthesis (2021) · cites this paper as [53]
Experimental — accuracy not yet measuredIn the citing paper
“Super-Resolution via Repeated Refinement (SR3) [200] uses DDPM to enable conditional image generation.”
From Diffusion Models: A Comprehensive Survey of Methods and Applications (2024) · cites this paper as [200]
In the citing paper
“SR3 conducts super-resolution through a stochastic, iterative denoising process.”
From Diffusion Models: A Comprehensive Survey of Methods and Applications (2024) · cites this paper as [200]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474 · cited 1×
“Then, we report classification accuracy of a pre-trained ResNet50 [65] model.”
MethodVaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
U-Net: Convolutional Networks for Biomedical Image Segmentation
Ronneberger, O., Fischer, P., & Brox, T. (2015) · Lecture notes in computer science · doi:10.1007/978-3-319-24574-4_28 · Cited by 99,404
Exploiting Generative AI to Scale up Intelligent Tutoring Systems
Jakubův, J., Chvalovský, K., Goertzel, Z., Kaliszyk, C., Olšák, M., Piotrowski, B., Schulz, S., Suda, M., & Urban, J. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,658
Image quality assessment: from error visibility to structural similarity
Wang, Z., Bovik, A. C., Sheikh, H. R., & Simoncelli, E. P. (2004) · IEEE Transactions on Image Processing · doi:10.1109/tip.2003.819861 · Cited by 57,892 · cited 10×
“Table 2 shows the PSNR, SSIM [63] and Consistency scores for 16 16 !”
BackgroundInfluentialImageNet Large Scale Visual Recognition Challenge
Russakovsky, O., Deng, J., Su, H., Krause, J., Satheesh, S., Ma, S., Huang, Z., Karpathy, A., Khosla, A., Bernstein, M., et al. (2015) · International Journal of Computer Vision · doi:10.1007/s11263-015-0816-y · Cited by 39,380 · cited 2×
“on ImageNet 1K [62] and use the dev split for evaluation.”
BackgroundMethodAuto-Encoding Variational Bayes
Kingma, D. P., & Welling, M. (2013) · arXiv · doi:10.48550/arxiv.1312.6114 · Cited by 20,067 · cited 2×
“VAEs [7], [46] offer fast sampling, but tend to underperform GANs”
BackgroundGenerative adversarial networks
Goodfellow, I., Pouget-Abadie, J., Mirza, M., Xu, B., Warde-Farley, D., Ozair, S., Courville, A., & Bengio, Y. (2020) · Communications of the ACM · doi:10.1145/3422622 · Cited by 18,384
Sequence to Sequence Learning with Neural Networks
Sutskever, I., Vinyals, O., & Le, Q. V. (2014) · arXiv · doi:10.48550/arxiv.1409.3215 · Cited by 17,766
Photo-Realistic Single Image Super-Resolution Using a Generative Adversarial Network
Ledig, C., Theis, L., Huszar, F., Caballero, J., Cunningham, A., Acosta, A., Aitken, A., Tejani, A., Totz, J., Wang, Z., et al. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.19 · Cited by 12,696
Cited by
High-Resolution Image Synthesis with Latent Diffusion Models
Rombach, R., Blattmann, A., Lorenz, D., Esser, P., & Ommer, B. (2022) · 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52688.2022.01042 · Cited by 20,302
“In the context of image synthesis, however, combining the generative power of DMs with other types of conditionings beyond class-labels [15] or blurred variants of the input image [70] is so far an under-explored area of research.”
InfluentialDiffusion Models Beat GANs on Image Synthesis
Dhariwal, P., & Nichol, A. (2021) · arXiv · doi:10.48550/arxiv.2105.05233 · Cited by 3,362
“In this section, we demonstrate that we can achieve results better than StyleGAN2 and BigGAN-deep with the same or lower compute budget.”
BackgroundMethodInfluentialPhotorealistic Text-to-Image Diffusion Models with Deep Language Understanding
Saharia, C., Chan, W., Saxena, S., Li, L., Whang, J., Denton, E., Ghasemipour, S. K. S., Ayan, B. K., Mahdavi, S. S., Lopes, R. G., et al. (2022) · arXiv · doi:10.48550/arxiv.2205.11487 · Cited by 2,528
“Diffusion models have seen wide success in image generation [28, 42, 62, 16, 29, 61], outperforming GANs in fidelity and diversity, without training instability and mode collapse issues [6, 16, 29].”
BackgroundSelf-citationHierarchical Text-Conditional Image Generation with CLIP Latents
Ramesh, A., Dhariwal, P., Nichol, A., Chu, C., & Chen, M. (2022) · arXiv · doi:10.48550/arxiv.2204.06125 · Cited by 2,511
“For the first upsampling stage, we use gaussian blur [43], and for the second, we use a more diverse BSR degradation [42,”
MethodDreamBooth: Fine Tuning Text-to-Image Diffusion Models for Subject-Driven Generation
Ruiz, N., Li, Y., Jampani, V., Pritch, Y., Rubinstein, M., & Aberman, K. (2022) · arXiv · doi:10.48550/arxiv.2208.12242 · Cited by 2,442
“[62] Chitwan Saharia, Jonathan Ho, William Chan, Tim Salimans, David J Fleet, and Mohammad Norouzi.”
Background
Metadata
- Authors
- Saharia, C., Ho, J., Chan, W., Salimans, T., Fleet, D. J., & Norouzi, M.
- Affiliations
- Google (United States) (US)
- Venue
- IEEE Transactions on Pattern Analysis and Machine Intelligence
- Published
- 2022
- Volume
- 45
- Issue
- 4
- Pages
- 1-14
- ISSN
- 0162-8828 (ISSN-L)
- 2160-9292
- 1939-3539
- OpenAlex
- W3155072588
- Cited by
- 1,829
- References
- 85
- Citations by year
- 2026: 234 · 2025: 580 · 2024: 662 · 2023: 301 · 2022: 40
- FWCI
- 129.48
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Locations
- IEEE Transactions on Pattern Analysis and Machine Intelligence (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Image Processing Techniques
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Generative Adversarial Networks and Image Synthesis
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Image and Signal Denoising Methods
- Keywords
- image super-resolution, iterative refinement, denoising diffusion probabilistic models, image-to-image translation, U-Net, face super-resolution, high-resolution image generation, human evaluation, image classification accuracy
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Image Super-Resolution Via Iterative Refinement. https://app.cochat.ai/papers/10.1109/tpami.2022.3204461
- The paper
- Saharia, C., Ho, J., Chan, W., Salimans, T., Fleet, D. J., & Norouzi, M. (2022). Image Super-Resolution Via Iterative Refinement. IEEE Transactions on Pattern Analysis and Machine Intelligence. https://doi.org/10.1109/tpami.2022.3204461
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
