

mixOmics: An R package for ‘omics feature selection and multiple data integration
Open accessPublished version of a preprint
The DOI matches its Crossref record; 58 of the 58 references it cites were found in a registry or an index.
Abstract
The advent of high throughput technologies has led to a wealth of publicly available 'omics data coming from different sources, such as transcriptomics, proteomics, metabolomics. Combining such large-scale biological data sets can lead to the discovery of important biological insights, provided that relevant information can be extracted in a holistic manner. Current statistical approaches have been focusing on identifying small subsets of molecules (a 'molecular signature') to explain or predict biological conditions, but mainly for a single type of 'omics. In addition, commonly used methods are univariate and consider each biological feature independently. We introduce mixOmics, an R package dedicated to the multivariate analysis of biological data sets with a specific focus on data exploration, dimension reduction and visualisation. By adopting a systems biology approach, the toolkit provides a wide range of methods that statistically integrate several data sets at once to probe relationships between heterogeneous 'omics data sets. Our recent methods extend Projection to Latent Structure (PLS) models for discriminant analysis, for data integration across multiple 'omics data or across independent studies, and for the identification of molecular signatures. We illustrate our latest mixOmics integrative frameworks for the multivariate analyses of 'omics data available from the package.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures



Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
R: A Language and Environment for Statistical Computing
R Core Team (2025) · doi:10.32614/r.manuals · Cited by 352,181
Regression shrinkage and selection via the lasso
Tibshirani, R. (1996) · Journal of the Royal Statistical Society Series B: Statistical Methodology · doi:10.1111/j.2517-6161.1996.tb02080.x · Cited by 51,482 · cited 1×
“Feature selection is performed via l1 regularisation (LASSO, [27]), which is implemented into each method’s statistical criterion to be optimised.”
MethodRegularization Paths for Generalized Linear Models via Coordinate Descent
Friedman, J., Hastie, T., & Tibshirani, R. (2010) · Journal of Statistical Software · doi:10.18637/jss.v033.i01 · Cited by 19,927 · cited 1×
“glmnet, [38], PMA, [39]), mixOmics uses soft-thresholding to improve usability by replacing the l(1) parameter by the number keepX of features to select on each dimension.”
MethodEnterotypes of the human gut microbiome
MetaHIT Consortium (additional members), Arumugam, M., Raes, J., Pelletier, E., Le Paslier, D., Yamada, T., Mende, D. R., Fernandes, G. R., Tap, J., Bruls, T., et al. (2011) · Nature · doi:10.1038/nature09944 · Cited by 7,548
Partial least squares for discrimination
Barker, M., & Rayens, W. (2003) · Journal of Chemometrics · doi:10.1002/cem.785 · Cited by 2,841
Khan, J., Wei, J. S., Ringnér, M., Saal, L. H., Ladanyi, M., Westermann, F., Berthold, F., Schwab, M., Antonescu, C. R., Peterson, C., et al. (2001) · Nature Medicine · doi:10.1038/89044 · Cited by 2,644 · cited 2×
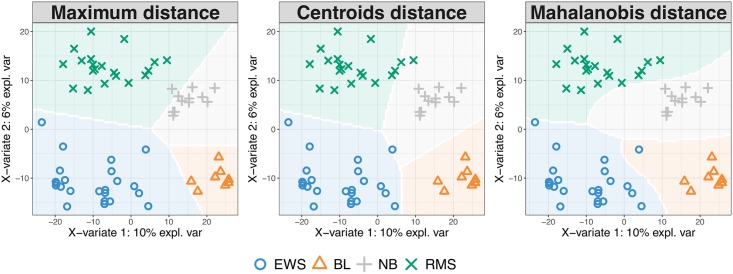
“The study investigates Small Round Blue Cell Tumors (SRBCT, [35]) of 63 tumour samples with the expression levels of 2,308 genes.”
BackgroundMethodLê Cao, K.-A., Boitard, S., & Besse, P. (2011) · BMC Bioinformatics · doi:10.1186/1471-2105-12-253 · Cited by 1,007 · cited 3×
“In single ‘omics analyses this distance achieves best accuracy when the predicted values are close to 0 or 1 [10].”
BackgroundMethodInfluentialPlankton networks driving carbon export in the oligotrophic ocean
Guidi, L., Chaffron, S., Bittner, L., Eveillard, D., Larhlimi, A., Roux, S., Darzi, Y., Audic, S., Berline, L., Brum, J. R., et al. (2016) · Nature · doi:10.1038/nature16942 · Cited by 870 · cited 1×
“(2016), Table 3 and factomineR Husson et al. (2017)). However, very few methods propose feature selection, including sparse CCA (pma package Witten et al. (2013)), sparse PLS (spls package, Chung et al.”
MethodTumor classification by partial least squares using microarray gene expression data
Nguyen, D. V., & Rocke, D. M. (2002) · Bioinformatics · doi:10.1093/bioinformatics/18.1.39 · Cited by 816 · cited 1×
“The assessment is data-driven and similar to the process detailed in Rohart et al. (2016), where one-sided t-tests assess whether there is a gain in performance when adding components to the model.”
MethodPath Models with Latent Variables: The NIPALS Approach
WOLD, H. (1975) · Quantitative Sociology · doi:10.1016/b978-0-12-103950-9.50017-4 · Cited by 802 · cited 1×
“Unsupervised analyses methods include Principal Component Analysis—based on NonLinear Iterative Partial Least Squares for missing values [18], Independent Component Analysis [19], Partial Least Squares regression—PLS, also known as Projection to Latent Structures [20], multi-group PLS [21], regularised Canonical Corre…”
MethodPartial least squares: a versatile tool for the analysis of high-dimensional genomic data
Boulesteix, A.-L., & Strimmer, K. (2006) · Briefings in Bioinformatics · doi:10.1093/bib/bbl016 · Cited by 802
A Sparse PLS for Variable Selection when Integrating Omics Data
Lê Cao, K.-A., Rossouw, D., Robert-Granié, C., & Besse, P. (2008) · Statistical Applications in Genetics and Molecular Biology · doi:10.2202/1544-6115.1390 · Cited by 564
Zhang, L. S., & Davies, S. S. (2016) · Genome Medicine · doi:10.1186/s13073-016-0296-x · Cited by 500
integrOmics: an R package to unravel relationships between two omics datasets
Lê Cao, K.-A., González, I., & Déjean, S. (2009) · Bioinformatics · doi:10.1093/bioinformatics/btp515 · Cited by 460
mixOmics : an R package for ‘omics feature selection and multiple data integrationPreprint
Rohart, F., Gautier, B., Singh, A., et al. (2017) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/108597 · Cited by 442
Self-citationHelminth infection promotes colonization resistance via type 2 immunity
Ramanan, D., Bowcutt, R., Lee, S. C., Tang, M. S., Kurtz, Z. D., Ding, Y., Honda, K., Gause, W. C., Blaser, M. J., Bonneau, R. A., et al. (2016) · Science · doi:10.1126/science.aaf3229 · Cited by 408
Dimension reduction techniques for the integrative analysis of multi-omics data
Meng, C., Zeleznik, O. A., Thallinger, G. G., Kuster, B., Gholami, A. M., & Culhane, A. C. (2016) · Briefings in Bioinformatics · doi:10.1093/bib/bbv108 · Cited by 383
CCA: An R Package to Extend Canonical Correlation Analysis
Gonzalez, I., Déjean, S., Martin, P., & Baccini, A. (2008) · Journal of Statistical Software · doi:10.18637/jss.v023.i12 · Cited by 377 · cited 1×
“Unsupervised analyses methods include Principal Component Analysis—based on NonLinear Iterative Partial Least Squares for missing values [18], Independent Component Analysis [19], Partial Least Squares regression—PLS, also known as Projection to Latent Structures [20], multi-group PLS [21], regularised Canonical Corre…”
MethodRegularized Generalized Canonical Correlation Analysis
Tenenhaus, A., & Tenenhaus, M. (2011) · Psychometrika · doi:10.1007/s11336-011-9206-8 · Cited by 368
Greninger, A. L., Messacar, K., Dunnebacke, T., Naccache, S. N., Federman, S., Bouquet, J., Mirsky, D., Nomura, Y., Yagi, S., Glaser, C., et al. (2016) · Genome Medicine · doi:10.1186/s13073-015-0257-9 · Cited by 333
Visualising associations between paired ‘omics’ data sets
González, I., Cao, K.-A. L., Davis, M. J., & Déjean, S. (2012) · BioData Mining · doi:10.1186/1756-0381-5-19 · Cited by 313
Sparse canonical methods for biological data integration: application to a cross-platform study
Lê Cao, K.-A., Martin, P. G., Robert-Granié, C., & Besse, P. (2009) · BMC Bioinformatics · doi:10.1186/1471-2105-10-34 · Cited by 283
Multi-class cancer classification via partial least squares with gene expression profiles
Nguyen, D. V., & Rocke, D. M. (2002) · Bioinformatics · doi:10.1093/bioinformatics/18.9.1216 · Cited by 246 · cited 1×
“We introduce here a supervised version, called PLS-Discriminant Analysis (PLS-DA, (Nguyen and Rocke, 2002a; Barker and Rayens, 2003), a natural extension that substitutes one of the data set for a dummy matrix Y.”
MethodVariable selection for generalized canonical correlation analysis
Tenenhaus, A., Philippe, C., Guillemot, V., Le Cao, K.-A., Grill, J., & Frouin, V. (2014) · Biostatistics · doi:10.1093/biostatistics/kxu001 · Cited by 234
PLS Dimension Reduction for Classification with Microarray Data
Boulesteix, A.-L. (2004) · Statistical Applications in Genetics and Molecular Biology · doi:10.2202/1544-6115.1075 · Cited by 210
New Perspectives in Partial Least Squares and Related Methods
(2013) · Springer Proceedings in Mathematics & Statistics · doi:10.1007/978-1-4614-8283-3 · Cited by 208
A multiblock partial least squares algorithm for investigating complex chemical systems
Wangen, L. E., & Kowalski, B. R. (1989) · Journal of Chemometrics · doi:10.1002/cem.1180030104 · Cited by 191
Presentato, A., Piacenza, E., Anikovskiy, M., Cappelletti, M., Zannoni, D., & Turner, R. J. (2016) · Microbial Cell Factories · doi:10.1186/s12934-016-0602-8 · Cited by 191
Mahana, D., Trent, C. M., Kurtz, Z. D., Bokulich, N. A., Battaglia, T., Chung, J., Müller, C. L., Li, H., Bonneau, R. A., & Blaser, M. J. (2016) · Genome Medicine · doi:10.1186/s13073-016-0297-9 · Cited by 190
A benchmark for RNA-seq quantification pipelines
Teng, M., Love, M. I., Davis, C. A., Djebali, S., Dobin, A., Graveley, B. R., Li, S., Mason, C. E., Olson, S., Pervouchine, D., et al. (2016) · Genome Biology · doi:10.1186/s13059-016-0940-1 · Cited by 189
MixMC: A Multivariate Statistical Framework to Gain Insight into Microbial Communities
Lê Cao, K.-A., Costello, M.-E., Lakis, V. A., Bartolo, F., Chua, X.-Y., Brazeilles, R., & Rondeau, P. (2016) · PLOS ONE · doi:10.1371/journal.pone.0160169 · Cited by 183
Yao, F., Coquery, J., & Lê Cao, K.-A. (2012) · BMC Bioinformatics · doi:10.1186/1471-2105-13-24 · Cited by 179 · cited 2×
“Unsupervised analyses methods includes Principal Component Analysis – based on NonLinear Iterative Partial Least Squares for missing values Wold (1975), Independent Component Analysis Yao et al. (2012), Partial Least Squares regression – PLS, also known as Projection to Latent Structures Wold (1966), multi-group PLS E…”
MethodTenenhaus, M., Tenenhaus, A., & Groenen, P. J. F. (2017) · Psychometrika · doi:10.1007/s11336-017-9573-x · Cited by 175
Liquet, B., Cao, K. L., Hocini, H., & Thiébaut, R. (2012) · BMC Bioinformatics · doi:10.1186/1471-2105-13-325 · Cited by 140
Plankton networks driving carbon export in the oligotrophic ocean
Guidi, L., Chaffron, S., Bittner, L., et al. (2016) · Flanders Marine Institute (Flanders Marine Institute) · Cited by 136
Rohart, F., Eslami, A., Matigian, N., Bougeard, S., & Cao, K. L. (2017) · BMC Bioinformatics · doi:10.1186/s12859-017-1553-8 · Cited by 126 · cited 2×
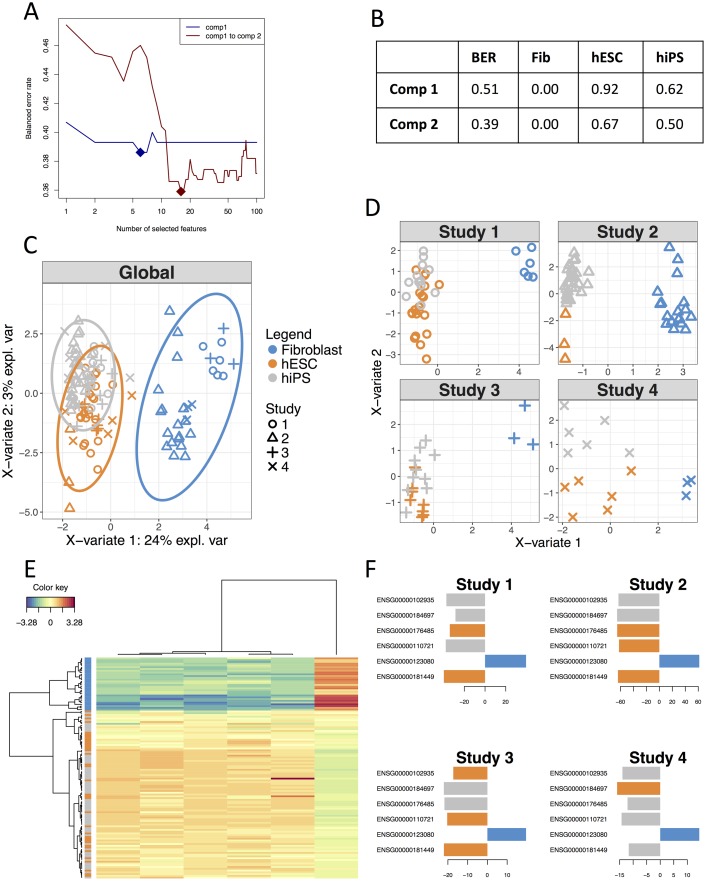
“Our own applications of the method to full data sets have showed strong potential of the method to identify reliable and robust biomarkers across independent transcriptomics studies Rohart et al. (2016, 2017).”
MethodSelf-citationThe Degrees of Freedom of Partial Least Squares Regression
Krämer, N., & Sugiyama, M. (2011) · Journal of the American Statistical Association · doi:10.1198/jasa.2011.tm10107 · Cited by 119 · cited 1×
“Components between different data sets however are not linearly dependent as we maximise the covariance between them [46].”
BackgroundWesterhuis, J. A., & Smilde, A. K. (2001) · Journal of Chemometrics · doi:10.1002/cem.652 · Cited by 91
Nonlinear Partial Least Squares An Overview
Rosipal, R. (2010) · IGI Global eBooks · doi:10.4018/978-1-61520-911-8.ch009 · Cited by 89
Multilevel omic data integration in cancer cell lines: advanced annotation and emergent properties
Liu, Y., Devescovi, V., Chen, S., & Nardini, C. (2013) · BMC Systems Biology · doi:10.1186/1752-0509-7-14 · Cited by 84
Labus, J. S., Horn, J. D. V., Gupta, A., Alaverdyan, M., Torgerson, C. M., Ashe-McNalley, C., Andrei Irimia, A., Hong, J., Naliboff, B. D., Tillisch, K., et al. (2015) · Pain · doi:10.1097/j.pain.0000000000000196 · Cited by 75
DIABLO: from multi-omics assays to biomarker discovery, an integrative approachPreprint
Singh, A., Shannon, C. P., Gautier, B., Rohart, F., Vacher, M. A., Tebbutt, S. J., & Cao, K. L. (2016) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/067611 · Cited by 61
Self-citationThree-Way Component Analysis Using theRPackageThreeWay
Giordani, P., Kiers, H. A. L., & Ferraro, M. A. D. (2014) · Journal of Statistical Software · doi:10.18637/jss.v057.i07 · Cited by 53
Key role of lipid management in nitrogen and aroma metabolism in an evolved wine yeast strain
Rollero, S., Mouret, J., Sanchez, I., Camarasa, C., Ortiz-Julien, A., Sablayrolles, J.-M., & Dequin, S. (2016) · Microbial Cell Factories · doi:10.1186/s12934-016-0434-6 · Cited by 47
A molecular classification of human mesenchymal stromal cells
Rohart, F., Mason, E. A., Matigian, N., Mosbergen, R., Korn, O., Chen, T., Butcher, S., Patel, J., Atkinson, K., Khosrotehrani, K., et al. (2016) · PeerJ · doi:10.7717/peerj.1845 · Cited by 47
Self-citationGünther, O. P., Chen, V., Freue, G. C., Balshaw, R. F., Tebbutt, S. J., Hollander, Z., Takhar, M., McMaster, W. R., McManus, B. M., Keown, P. A., et al. (2012) · BMC Bioinformatics · doi:10.1186/1471-2105-13-326 · Cited by 46 · cited 1×
“The other common type of N -integration is to combine the molecular signatures identified from separate analyses of each ‘omics Günther et al. (2012), which disregards the relationships between the different ‘omics functional levels.”
BackgroundLeibovici, D. (2010) · Journal of Statistical Software · doi:10.18637/jss.v034.i10 · Cited by 42
Karaman, İ., Nørskov, N. P., Yde, C. C., Hedemann, M. S., Knudsen, K. E. B., & Köhler, A. (2014) · Metabolomics · doi:10.1007/s11306-014-0698-y · Cited by 39
spls: Sparse Partial Least Squares (SPLS) Regression and Classification
Chung, D., Chun, H., & Keles, S. (2008) · doi:10.32614/cran.package.spls · Cited by 33
PMA: Penalized Multivariate Analysis
Witten, D., Tibshirani, R. J., Gross, S., & Narasimhan, B. (2009) · doi:10.32614/cran.package.pma · Cited by 21
Cook, J. A., Chandramouli, G. V. R., Anver, M. R., Sowers, A. L., Thetford, A., Krausz, K. W., Gonzalez, F. J., Mitchell, J. B., & Patterson, A. D. (2016) · Cancer Research · doi:10.1158/0008-5472.can-15-2416 · Cited by 18 · cited 1×
“Lastly, they are highly flexible to answer various biological questions (Boulesteix and Strimmer, 2007): mixOmics multivariate methods have been successfully applied in several recent studies to identify biomarkers in ‘omics studies ranging from metabolomics, brain imaging to microbiome and statistically integrate dat…”
MethodKawaguchi, A., & Yamashita, F. (2017) · Biostatistics · doi:10.1093/biostatistics/kxx011 · Cited by 17
Algorithms for multi‐group PLS
Eslami, A., Qannari, E. M., Köhler, A., & Bougeard, S. (2014) · Journal of Chemometrics · doi:10.1002/cem.2593 · Cited by 15
RGCCA: Regularized and Sparse Generalized Canonical Correlation Analysis for Multiblock Data
Girka, F., Camenen, E., Peltier, C., Gloaguen, A., Guillemot, V., & Tenenhaus, A. (2012) · doi:10.32614/cran.package.rgcca · Cited by 10
Multi-group PLS Regression: Application to Epidemiology
Eslami, A., Qannari, E. M., Köhler, A., & Bougeard, S. (2013) · Springer proceedings in mathematics & statistics · doi:10.1007/978-1-4614-8283-3_17 · Cited by 9 · cited 6×
“(2012), Partial Least Squares regression – PLS, also known as Projection to Latent Structures Wold (1966), multi-group PLS Eslami et al. (2013), regularised Canonical Correlation Analysis – rCCA González et al. (2008)) and regularised Generalised Canonical Correlation Analysis – RGCCA based on a PLS algorithm Tenenhau…”
MethodInfluentialShah, A. K., Cao, K. L., Choi, E., Chen, D., Gautier, B., Nancarrow, D. J., Whiteman, D. C., Baker, P. R., Clauser, K. R., Chalkley, R. J., et al. (2016) · Data in Brief · doi:10.1016/j.dib.2016.03.081 · Cited by 6 · cited 2×
“The methods has been applied and validated in several biological and biomedical studies, including ours in proteomics and microbiome Shah et al. (2016); Lê Cao et al. (2016).”
MethodSelf-citationThreeWay: Three-Way Component Analysis
Ferraro, M. A. D., Giordani, P., & Kiers, H. A. L. (2012) · doi:10.32614/cran.package.threeway · Cited by 3
PTAk: Principal Tensor Analysis on k Modes
<doi:10.18637/jss.v034.i10>, D. G. L. (. (2001) · doi:10.32614/cran.package.ptak · Cited by 2
Research works printed but not linked: 3
- A Singh, 2016, DIABLO-an integrative, multi-omics, multivariate method for multi-group classification, bioRxiv, 067611
- F Rohart, 2017, MINT: A multivariate integrative approach to identify a reproducible biomarker signature across multiple experiments and platforms, BMC Bioinformatics, 18
- H Wold, 1966, Estimation of principal components and related models by iterative least squares, J Multivar Anal, 391
Cited by
Multi-omics Data Integration, Interpretation, and Its Application
Subramanian, I., Verma, S., Kumar, S., Jere, A., & Anamika, K. (2020) · Bioinformatics and Biology Insights · doi:10.1177/1177932219899051 · Cited by 1,609
“…to identify multi-omics signatures (putative biomarkers) that could distinguish the breast cancer subtypes, namely, Basal, HER2, and Luminal A. 51 Thus, mix-Omics can address both disease subtyping and biomarker prediction. moCluster. moCluster uses multi-table multivariate analysis approach…”
BackgroundEleven grand challenges in single-cell data science
Lähnemann, D., Köster, J., Szczurek, E., McCarthy, D. J., Hicks, S. C., Robinson, M. D., Vallejos, C. A., Campbell, K. R., Beerenwinkel, N., Mahfouz, A., et al. (2020) · Genome Biology · doi:10.1186/s13059-020-1926-6 · Cited by 1,327
DIABLO: an integrative approach for identifying key molecular drivers from multi-omics assays
Singh, A., Shannon, C. P., Gautier, B., Rohart, F., Vacher, M., Tebbutt, S. J., & Lê Cao, K.-A. (2019) · Bioinformatics · doi:10.1093/bioinformatics/bty1054 · Cited by 1,072
“Note that the design matrix is not restricted to 0 and 1 values only and a compromise between correlation and discrimination can also be modeled as described in Rohart et al. (2017).”
BackgroundSelf-citationThe vaginal microbiome and preterm birth
Fettweis, J. M., Serrano, M. G., Brooks, J. P., Edwards, D. J., Girerd, P. H., Parikh, H. I., Huang, B., Arodz, T. J., Edupuganti, L., Glascock, A. L., et al. (2019) · Nature Medicine · doi:10.1038/s41591-019-0450-2 · Cited by 983
Orchestrating single-cell analysis with Bioconductor
Amezquita, R. A., Lun, A. T. L., Becht, E., Carey, V. J., Carpp, L. N., Geistlinger, L., Marini, F., Rue-Albrecht, K., Risso, D., Soneson, C., et al. (2020) · Nature Methods · doi:10.1038/s41592-019-0654-x · Cited by 945
“Finally, several data integration methods developed for bulk assays are available in themixOmics [79] package and have shown good performance on single-cell data [80].”
Method
Metadata
- Authors
- Rohart, F., Gautier, B., Singh, A., & Lê Cao, K.-A.
- Affiliations
- Translational Research Institute (AU)
- University of British Columbia (CA)
- Venue
- PLOS Computational Biology
- Publisher
- Public Library of Science (PLoS)
- Published
- 2017-11-03
- Volume
- 13
- Issue
- 11
- Pages
- e1005752
- ISSN
- 1553-734X (ISSN-L)
- 1553-7358
- PMC
- PMC5687754
- OpenAlex
- W2950985821
- Cited by
- 4,056
- References
- 57
- Citations by year
- 2026: 629 · 2025: 612 · 2024: 600 · 2023: 523 · 2022: 496 · 2021: 489 · 2020: 350 · 2019: 241 · 2018: 95 · 2017: 14
- FWCI
- 78.13
- Type
- journal article
- Language
- en
- Update notices
- new_version (2017-11-15)
- Open access
- gold
- doi.org
- Licence
- Locations
- PLoS Computational Biology (publishedVersion, cc-by)
- bioRxiv (Cold Spring Harbor Laboratory) (acceptedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Minerva Access (University of Melbourne) (submittedVersion, cc-by)
- RePEc: Research Papers in Economics (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Figshare (submittedVersion, cc-by)
- Funders
- National Health and Medical Research Council (APP1087415)
- Australian Cancer Research Foundation (ACRF) for the Diamantina Individualised Oncology Care Centre
- Topics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Bioinformatics and Genomic Networks
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Metabolomics and Mass Spectrometry Studies
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Gene expression and cancer classification
- Keywords
- R package, multi-omics integration, feature selection, multivariate analysis, dimensionality reduction, partial least squares regression, discriminant analysis, molecular signatures, systems biology, transcriptomics, proteomics, metabolomics, exploratory data analysis
- MeSH terms
- Data Interpretation, Statistical, Humans, Neoplasms, Software, Computational Biology, Genomics, Systems Biology, Metabolomics
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
