

The DOI matches its Crossref record; 88 of the 88 references it cites were found in a registry or an index.
SqueezeBERT: What can computer vision teach NLP about efficient neural networks?
Open accessAbstract
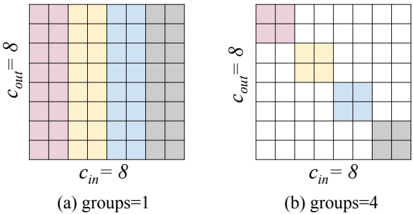
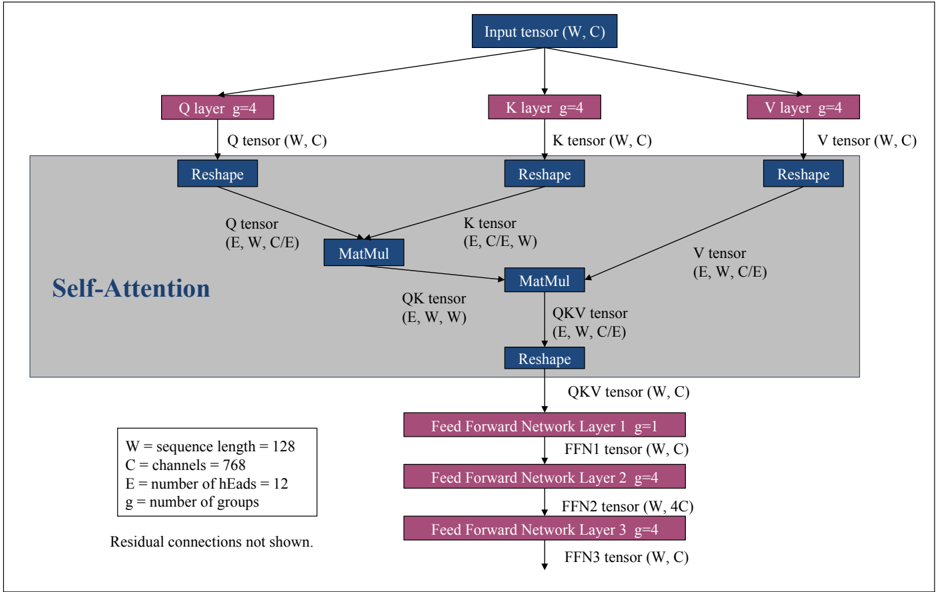
Humans read and write hundreds of billions of messages every day.Further, due to the availability of large datasets, large computing systems, and better neural network models, natural language processing (NLP) technology has made significant strides in understanding, proofreading, and organizing these messages.Thus, there is a significant opportunity to deploy NLP in myriad applications to help web users, social networks, and businesses.Toward this end, we consider smartphones and other mobile devices as crucial platforms for deploying NLP models at scale.However, today's highly-accurate NLP neural network models such as BERT and RoBERTa are extremely computationally expensive, with BERT-base taking 1.7 seconds to classify a text snippet on a Pixel 3 smartphone.To begin to address this problem, we draw inspiration from the computer vision community, where work such as MobileNet has demonstrated that grouped convolutions (e.g., depthwise convolutions) can enable speedups without sacrificing accuracy.We demonstrate how to replace several operations in self-attention layers with grouped convolutions and use this technique in a novel network architecture called Squeeze-BERT, which runs 4.3x faster than BERT-base on the Pixel 3 while achieving competitive accuracy on the GLUE test set.A PyTorch-based implementation of Squeeze-BERT is available as part of the Hugging Face Transformers library: https:// huggingface.co/squeezebert
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Moreover, models such as MobileBERT and SqueezeBERT employ bottleneck layers and grouped convolutions, leading to a 3× to 4× reduction in latency while maintaining >90% of the original model’s accuracy.”
From Tiny Language Models for Automation and Control: Overview, Potential Applications, and Future Research Directions (2025) · cites this paper as [103]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Very Deep Convolutional Networks for Large-Scale Image Recognition
Simonyan, K., & Zisserman, A. (2014) · arXiv · doi:10.48550/arxiv.1409.1556 · Cited by 114,148
ImageNet classification with deep convolutional neural networks
Krizhevsky, A., Sutskever, I., & Hinton, G. E. (2017) · Communications of the ACM · doi:10.1145/3065386 · Cited by 112,155
U-Net: Convolutional Networks for Biomedical Image Segmentation
Ronneberger, O., Fischer, P., & Brox, T. (2015) · Lecture notes in computer science · doi:10.1007/978-3-319-24574-4_28 · Cited by 99,404
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Densely Connected Convolutional Networks
Huang, G., Liu, Z., Van Der Maaten, L., & Weinberger, K. Q. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.243 · Cited by 48,566
Microsoft COCO: Common Objects in Context
Lin, T.-Y., Maire, M., Belongie, S., Hays, J., Perona, P., Ramanan, D., Dollár, P., & Zitnick, C. L. (2014) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-10602-1_48 · Cited by 45,460
ImageNet Large Scale Visual Recognition Challenge
Russakovsky, O., Deng, J., Su, H., Krause, J., Satheesh, S., Ma, S., Huang, Z., Karpathy, A., Khosla, A., Bernstein, M., et al. (2015) · International Journal of Computer Vision · doi:10.1007/s11263-015-0816-y · Cited by 39,380
Research works printed but not linked: 3
- William B. Dolan and Chris Brockett. 2005. Auto- matically constructing a corpus of sentential para- phrases. In Proceedings of the International Work- shop on Paraphrasing.
- Zhanghao Wu, Zhijian Liu, Ji Lin, Yujun Lin, and Song Han. 2020. Lite transformer with long short term attention. In ICLR.
- Ji Xin, Raphael Tang, Jaejun Lee, Yaoliang Yu, and Jimmy Lin. 2020. Deebert: Dynamic early exiting for accelerating bert inference. In ACL.
Cited by
Sorted by citations
Trends in AI inference energy consumption: Beyond the performance-vs-parameter laws of deep learning
Desislavov, R., Martínez-Plumed, F., & Hernández-Orallo, J. (2023) · Sustainable Computing: Informatics and Systems · doi:10.1016/j.suscom.2023.100857 · Cited by 269
“There are many models that focus on being efficient instead of reaching high score, and this is reflected in their names too (e.g., MobileBERT [Sun et al., 2020] and SqueezeBERT [Iandola et al., 2020]).”
BackgroundBERT applications in natural language processing: a review
Gardazi, N. M., Daud, A. Y., Malik, M. K., Bukhari, A. A., Alsahfi, T., & Alshemaimri, B. K. (2025) · Artificial Intelligence Review · doi:10.1007/s10462-025-11162-5 · Cited by 354
ADAHESSIAN: An Adaptive Second Order Optimizer for Machine Learning
Yao, Z., Gholami, A., Shen, S., Mustafa, M., Keutzer, K., & Mahoney, M. W. (2021) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v35i12.17275 · Cited by 257
Self-citationEnd-to-End Transformer-Based Models in Textual-Based NLP
Rahali, A., & Akhloufi, M. A. (2023) · AI · doi:10.3390/ai4010004 · Cited by 209
Zhang, H., & Shafiq, M. O. (2024) · Journal Of Big Data · doi:10.1186/s40537-023-00842-0 · Cited by 180
Learned Token Pruning for Transformers
Kim, S., Shen, S., Thorsley, D., Gholami, A., Kwon, W., Hassoun, J., & Keutzer, K. (2022) · Proceedings of the 28th ACM SIGKDD Conference on Knowledge Discovery and Data Mining · doi:10.1145/3534678.3539260 · Cited by 139
Self-citationEdgeBERT: Sentence-Level Energy Optimizations for Latency-Aware Multi-Task NLP Inference
Tambe, T., Hooper, C. R. C., Pentecost, L., Jia, T., Yang, E.-Y., Donato, M., Sanh, V., Whatmough, P. N., Rush, A. M., Brooks, D. M., et al. (2021) · IEEE/ACM International Symposium on Microarchitecture (MICRO) · doi:10.1145/3466752.3480095 · Cited by 145
Garrido-Muñoz, I., Montejo-Ráez, A., Martínez-Santiago, F., & Ureña-López, L. A. (2021) · Applied Sciences · doi:10.3390/app11073184 · Cited by 123
Efficient Methods for Natural Language Processing: A Survey
Treviso, M., Lee, J.-U., Ji, T., van Aken, B., Cao, Q., Ciosici, M. R., Hassid, M., Heafield, K., Hooker, S., Raffel, C., et al. (2023) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00577 · Cited by 156
Compression of Deep Learning Models for Text: A Survey
Gupta, M., & Agrawal, P. (2022) · ACM Transactions on Knowledge Discovery from Data · doi:10.1145/3487045 · Cited by 128
Performance Study on Extractive Text Summarization Using BERT Models
Abdel-Salam, S., & Rafea, A. (2022) · Information · doi:10.3390/info13020067 · Cited by 106
WhiteningBERT: An Easy Unsupervised Sentence Embedding Approach
Huang, J., Tang, D., Zhong, W., Lu, S., Shou, L., Gong, M., Jiang, D., & Duan, N. (2021) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2021.findings-emnlp.23 · Cited by 99
Understanding and Overcoming the Challenges of Efficient Transformer Quantization
Bondarenko, Y., Nagel, M., & Blankevoort, T. (2021) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2021.emnlp-main.627 · Cited by 172
Bokolo, B. G., & Liu, Q. (2023) · Electronics · doi:10.3390/electronics12214396 · Cited by 116
Pre-trained Summarization DistillationPreprint
Shleifer, S., & Rush, A. M. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2010.13002 · Cited by 121
Lamaakal, I., Maleh, Y., El Makkaoui, K., Ouahbi, I., Pławiak, P., Alfarraj, O., Almousa, M., & Abd El-Latif, A. A. (2025) · Sensors · doi:10.3390/s25051318 · Cited by 60
Survey of BERT (Bidirectional Encoder Representation Transformer) types
Mohammed, A. H., & Ali, A. H. (2021) · Journal of Physics Conference Series · doi:10.1088/1742-6596/1963/1/012173 · Cited by 62
Hussain, S., Afzal, H., Saeed, R., Iltaf, N., & Umair, M. Y. (2021) · Computational and Mathematical Methods in Medicine · doi:10.1155/2021/5589829 · Cited by 40
Towards Reliable Misinformation Mitigation: Generalization, Uncertainty, and GPT-4
Pelrine, K., Imouza, A., Thibault, C., Reksoprodjo, M., Gupta, C., Christoph, J. N., Godbout, J., & Rabbany, R. (2023) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2023.emnlp-main.395 · Cited by 83
DCT-Former: Efficient Self-Attention with Discrete Cosine Transform
Scribano, C., Franchini, G., Prato, M., & Bertogna, M. (2023) · Journal of Scientific Computing · doi:10.1007/s10915-023-02125-5 · Cited by 41
Your fairness may vary: Pretrained language model fairness in toxic text classification
Baldini, I., Wei, D., Ramamurthy, K. N., Singh, M., & Yurochkin, M. (2022) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2022.findings-acl.176 · Cited by 51
Automatic Construction of Educational Knowledge Graphs: A Word Embedding-Based Approach
Ain, Q. U., Chatti, M. A., Bakar, K. G. C., Joarder, S., & Alatrash, R. (2023) · Information · doi:10.3390/info14100526 · Cited by 43
Meta-KD: A Meta Knowledge Distillation Framework for Language Model Compression across Domains
Fang, T., Wang, C., Qiu, M., Zhang, Y., Li, Y., & Huang, J. (2021) · doi:10.18653/v1/2021.acl-long.236 · Cited by 51
Guesmi, M., Chatti, M. A., Joarder, S., Ain, Q. U., Alatrash, R., Siepmann, C., & Vahidi, T. (2023) · International Journal of Human-Computer Interaction · doi:10.1080/10447318.2023.2262797 · Cited by 31
AutoBERT-Zero: Evolving BERT Backbone from Scratch
Gao, J., Xu, H., Han, S., Ren, X., Yu, P. L. H., Liang, X., Jiang, X., & Li, Z. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i10.21311 · Cited by 32
GhostBERT: Generate More Features with Cheap Operations for BERT
Huang, Z., Hou, L., Shang, L., Jiang, X., Chen, X. D., & Liu, Q. (2021) · doi:10.18653/v1/2021.acl-long.509 · Cited by 23
Emotion Recognition on Edge Devices: Training and Deployment
Pandelea, V., Ragusa, E., Apicella, T., Gastaldo, P., & Cambria, E. (2021) · Sensors · doi:10.3390/s21134496 · Cited by 21
EfficientBERT: Progressively Searching Multilayer Perceptron via Warm-up Knowledge Distillation
Dong, C., Wang, G., Xu, H., Peng, J., Ren, X., & Liang, X. (2021) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2021.findings-emnlp.123 · Cited by 22
Machine learning-based approaches for ubiquitination site prediction in human proteins
Pourmirzaei, M., Ramazi, S., Esmaili, F., Shojaeilangari, S., & Allahvardi, A. (2023) · BMC Bioinformatics · doi:10.1186/s12859-023-05581-w · Cited by 20
SkipBERT: Efficient Inference with Shallow Layer Skipping
Wang, J., Chen, K., Chen, G., Shou, L., & McAuley, J. (2022) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2022.acl-long.503 · Cited by 20
ILDAE: Instance-Level Difficulty Analysis of Evaluation Data
Varshney, N., Mishra, S. R., & Baral, C. R. (2022) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2022.acl-long.240 · Cited by 19
Eye Gaze and Self-attention: How Humans and Transformers Attend Words in Sentences
Bensemann, J., Peng, A. Y., Benavides‐Prado, D., Chen, Y., Tan, N. Ö., Corballis, P. M., Riddle, P., & Witbrock, M. (2022) · Workshop on Cognitive Modeling and Computational Linguistics (CMCL) · doi:10.18653/v1/2022.cmcl-1.9 · Cited by 17
Aggarwal, S., & Vishwakarma, D. K. (2024) · Expert Systems with Applications · doi:10.1016/j.eswa.2024.124278 · Cited by 17
Liapis, C. M., & Kotsiantis, S. B. (2023) · Information · doi:10.3390/info14110596 · Cited by 19
A survey on moral foundation theory and pre-trained language models: current advances and challenges
Zangari, L., Greco, C. M., Picca, D., & Tagarelli, A. (2025) · AI & Society · doi:10.1007/s00146-025-02225-w · Cited by 21
PipeBERT: High-throughput BERT Inference for ARM Big.LITTLE Multi-core Processors
Chang, H.-Y., Mozafari, S. H., Chen, C., Clark, J. J., Meyer, B. H., & Gross, W. J. (2023) · Journal of Signal Processing Systems · doi:10.1007/s11265-022-01814-y · Cited by 14
SKDBERT: Compressing BERT via Stochastic Knowledge Distillation
Ding, Z., Guoqing, J., Zhang, S., Guo, L., & Lin, W. T. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i6.25902 · Cited by 14
Multi-modal spatial relational attention networks for visual question answering
Yao, H., Wang, L., Cai, C., Sun, Y., Zhang, Z., & Luo, Y. (2023) · Image and Vision Computing · doi:10.1016/j.imavis.2023.104840 · Cited by 14
Debiasing pretrained text encoders by paying attention to paying attention
Gaci, Y., Benatallah, B., Casati, F., & Benabdeslem, K. (2022) · Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2022.emnlp-main.651 · Cited by 14
Distilling Wisdom: A Review on Optimizing Learning From Massive Language Models
Zhang, D., Listiyani, D., Singh, P., & Mohanty, M. (2025) · IEEE Access · doi:10.1109/access.2025.3554586 · Cited by 18
NLP based Deep Learning Approach for Plagiarism Detection
Rosu, R., Stoica, A. Ş., Popescu, P. Ș., & Mihăescu, M. C. (2020) · International Joural of User-System Interaction · doi:10.37789/ijusi.2020.13.1.4 · Cited by 12
KPLLM-STE: Knowledge-enhanced and prompt-aware large language models for short-text expansion
Zhong, H., Zhang, Q., Li, W., Lin, R., & Tang, Y. Z. (2024) · World Wide Web · doi:10.1007/s11280-024-01322-y · Cited by 11
Liu, P., Gao, Z.-F., Zhao, W. X., Xie, Z. Y., Lu, Z.-Y., & Wen, J.-R. (2021) · doi:10.18653/v1/2021.acl-long.418 · Cited by 27
Song, W., & Zheng, J. (2024) · Quality Engineering · doi:10.1080/08982112.2024.2304815 · Cited by 11
Pushing the Accuracy of Thai Food Image Classification with Transfer Learning
Ittisoponpisan, S., Kaipan, C., Ruang-on, S., Thaiphan, R., & Songsri-in, K. (2022) · Engineering Journal · doi:10.4186/ej.2022.26.10.57 · Cited by 10
Adaptive Filters and Aggregator Fusion for Efficient Graph Convolutions.Preprint
Tailor, S. A., Opolka, F. L., Lió, P., & Lane, N. D. (2021) · arXiv (Cornell University) · Cited by 10
EdgeTran: Device-Aware Co-Search of Transformers for Efficient Inference on Mobile Edge Platforms
Tuli, S., & Jha, N. K. (2023) · IEEE Transactions on Mobile Computing · doi:10.1109/tmc.2023.3328287 · Cited by 16
CS-BERT: a pretrained model for customer service dialogues
Wang, P., Fang, J., & Reinspach, J. (2021) · Workshop on NLP for Conversational AI (NLP4ConvAI) · doi:10.18653/v1/2021.nlp4convai-1.13 · Cited by 9
A flaw in using pretrained protein language models in protein–protein interaction inference models
Szymborski, J., & Emad, A. (2026) · Nature Machine Intelligence · doi:10.1038/s42256-025-01176-7 · Cited by 13
The Framework Tax: Disparities Between Inference Efficiency in NLP Research and Deployment
Fernandez, J., Kahn, J., Na, C., Bisk, Y., & Strubell, E. (2023) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2023.emnlp-main.98 · Cited by 11
Are Rotten Apples Edible? Challenging Commonsense Inference Ability with Exceptions
Do, N., & Pavlick, E. (2021) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2021.findings-acl.181 · Cited by 8
Word embedding factor based multi-head attention
Li, Z., Zhao, Y., Zhang, X., Han, H., & Huang, C. F. (2025) · Artificial Intelligence Review · doi:10.1007/s10462-025-11115-y · Cited by 7
Towards SLO-Compliant and Cost-Effective Serverless Computing on Emerging GPU Architectures
Bhasi, V. M., Sharma, A., Jain, R., Gunasekaran, J. R., Pattnaik, A., Kandemir, M., & Das, C. R. (2024) · International Middleware Conference · doi:10.1145/3652892.3700760 · Cited by 10
On the Role of Corpus Ordering in Language Modeling
Agrawal, A., Singh, S., Schneider, L. R., & Samuels, M. (2021) · Workshop on Simple and Efficient Natural Language Processing (SustaiNLP) · doi:10.18653/v1/2021.sustainlp-1.15 · Cited by 7
High Performance Natural Language Processing
Ilharco, G., Magalhaes, C. I., Turc, I., Dettmers, T., Ferreira, F., & Lee, K. (2020) · Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2020.emnlp-tutorials.4 · Cited by 7
On convex decision regions in deep network representations
Tětková, L., Brüsch, T., Dorszewski, T., Mager, F. M., Aagaard, R. Ø., Foldager, J., Alstrøm, T. S., & Hansen, L. K. (2025) · Nature Communications · doi:10.1038/s41467-025-60809-y · Cited by 10
Guesmi, M., Chatti, M. A., Kadhim, L., Joarder, S., & Ain, Q. U. (2023) · Multimodal Technologies and Interaction · doi:10.3390/mti7090091 · Cited by 6
Efficient Transformers for on-robot Natural Language Understanding
Greco, A., Roberto, A., Saggese, A., & Vento, M. (2022) · IEEE-RAS International Conference on Humanoid Robots (Humanoids) · doi:10.1109/humanoids53995.2022.10000085 · Cited by 6
Optimal Condition Training for Target Source Separation
Tzinis, E., Wichern, G., Smaragdis, P., & Roux, J. L. (2023) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49357.2023.10095128 · Cited by 6
GHOST at SemEval-2021 Task 5: Is explanation all you need?
Pluciński, K., & Klimczak, H. (2021) · International Workshop on Semantic Evaluation (SemEval) · doi:10.18653/v1/2021.semeval-1.114 · Cited by 6
MLPruning: A Multilevel Structured Pruning Framework for Transformer-based ModelsPreprint
Yao, Z., Ma, L., Shen, S., Keutzer, K., & Mahoney, M. W. (2021) · arXiv (Cornell University) · Cited by 6
Self-citationStereotype and Categorical Bias Evaluation via Differential Cosine Bias Measure
Sayenju, S., Aygün, R. S., Franks, B., Johnston, S., Lee, G., & Modgil, G. (2022) · IEEE International Conference on Big Data (BigData) · doi:10.1109/bigdata55660.2022.10020924 · Cited by 5
Detection of Morality in Tweets Based on the Moral Foundation Theory
Bulla, L., Giorgis, S. D., Aldo Gangemi, A., Marinucci, L., & Mongiovı̀, M. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-25599-1_1 · Cited by 5
Zhou, X., Fu, Q., Chen, J., Liu, L., Wang, Y., Lu, Y., & Wu, H. (2023) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2023.104445 · Cited by 5
EPAM: A Predictive Energy Model for Mobile AI
Mallik, A., Wang, H., Xie, J. L., Chen, D., & Han, K. (2023) · International Conference on Communications · doi:10.1109/icc45041.2023.10279417 · Cited by 5
E-LANG: Energy-Based Joint Inferencing of Super and Swift Language Models
Akbari, M., Banitalebi-Dehkordi, A., & Zhang, Y. (2022) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2022.acl-long.359 · Cited by 8
Guesmi, M., Siepmann, C., Chatti, M. A., Joarder, S., Ain, Q. U., & Alatrash, R. (2023) · ACM Conference on User Modeling, Adaptation and Personalization (UMAP) · doi:10.1145/3563359.3597379 · Cited by 5
NoiER: An Approach for Training More Reliable Fine-Tuned Downstream Task Models
Jang, M., & Lukasiewicz, T. (2022) · IEEE/ACM Transactions on Audio Speech and Language Processing · doi:10.1109/taslp.2022.3193292 · Cited by 4
Explainable AI Discloses Gender Bias in Sexism Detection Algorithm
Muntasir, F., & Noor, J. (2024) · International Conference on Networking, Systems and Security (NSysS) · doi:10.1145/3704522.3704524 · Cited by 5
Revisiting Text Guide, a Truncation Method for Long Text Classification
Fiok, K., Karwowski, W., Gutiérrez-Franco, E., Davahli, M. R., Wilamowski, M., & Ahram, T. (2021) · Applied Sciences · doi:10.3390/app11188554 · Cited by 4
Enhancing Natural Language Representation with Large-Scale Out-of-Domain Commonsense
Cui, W., & Chen, X. (2022) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2022.findings-acl.138 · Cited by 4
Embarrassingly Simple Performance Prediction for Abductive Natural Language Inference
Kadiķis, E., Srivastav, V., & Klinger, R. (2022) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2022.naacl-main.441 · Cited by 4
Textual Pre-Trained Models for Age Screening Across Community Question-Answering
Figueroa, A., & Timilsina, M. (2024) · IEEE Access · doi:10.1109/access.2024.3368929 · Cited by 3
Villate-Castillo, G., Ser, J. D., & Sanz, B. (2026) · Artificial Intelligence Review · doi:10.1007/s10462-026-11548-z · Cited by 7
Memory-Assistant Collaborative Language Understanding for Artificial Intelligence of Things
Yan, M., Chen, C., Du, J., Peng, X., Zhou, J. T., & Zeng, Z. (2021) · IEEE Transactions on Industrial Informatics · doi:10.1109/tii.2021.3100397 · Cited by 3
A data generation pipeline for cardiac vessel segmentation and motion artifact grading
Sushmit, A. S., Xu, Y., Mariani, O., Lyu, Q., Li, Y., Cao, X., Wiedeman, C., Ma, H., Maltz, J. S., Yu, H., et al. (2022) · Developments in X-Ray Tomography · doi:10.1117/12.2642869 · Cited by 3
Meta-KD: A Meta Knowledge Distillation Framework for Language Model Compression across DomainsPreprint
Fang, T., Wang, C., Qiu, M., Zhang, Y., Li, Y., & Huang, J. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2012.01266 · Cited by 3
Tiwari, G., Saini, S., & Minaxi (2025) · Neural Computing and Applications · doi:10.1007/s00521-024-10847-2 · Cited by 2
Comparative Analysis of Deep Learning Algorithms in Fire Detection
Göçmen, R., Çıbuk, M., & Akin, E. (2024) · Balkan Journal of Electrical and Computer Engineering · doi:10.17694/bajece.1533966 · Cited by 2
Architectures for Machine Learning
Yang, Y., Chen, C., & Wang, Z. (2024) · Springer eBooks · doi:10.1007/978-981-97-9314-3_12 · Cited by 2
GroupBERT: Enhanced Transformer Architecture with Efficient Grouped StructuresPreprint
Chelombiev, I., Justus, D., Orr, D., Dietrich, A., Gressmann, F., Koliousis, A., & Luschi, C. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2106.05822 · Cited by 6
Multi-Label Emotion Classification Using Physically Explicated Dataset
Sowndarya Spoorthi, B., Harshitha, V., Nagasandesh, N., Pramod, K. S., & Shashank, N. (2023) · Soft Computing Research Society eBooks · doi:10.52458/978-81-955020-5-9-71 · Cited by 1
SAFE Natural Language Processing
Babaei, G., Giudice, O., Giudici, P., & Maggi, A. (2025) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn64981.2025.11228343 · Cited by 1
Driss, M., Atitallah, S. B., Benjdira, B., AlHalawani, S., Ali, A. M., & Boulila, W. (2026) · Internet of Things · doi:10.1016/j.iot.2026.102020 · Cited by 2
Srinivasan, S., Begoli, E., Mahbub, M., & Knight, K. (2021) · IEEE Security and Privacy Workshops (SPW) · doi:10.1109/spw53761.2021.00049 · Cited by 2
Deshmukh, S. A., Vaidya, R., Kamuni, V. D., & Gaikwad, S. V. (2023) · Theoretical Issues in Ergonomics Science · doi:10.1080/1463922x.2023.2214792 · Cited by 1
Mozafari, S. H., Clark, J. J., Gross, W. J., & Meyer, B. H. (2023) · IEEE International Conference on Application-specific Systems, Architectures and Processors (ASAP) · doi:10.1109/asap57973.2023.00024 · Cited by 1
Zhang, Z., Yun, W., Jia, X., Lv, Q., Ni, H., Wang, X., & Wu, G. (2023) · Communications in computer and information science · doi:10.1007/978-981-99-8138-0_12 · Cited by 1
Zhang, J., Wang, J., Li, H., Shou, L., Chen, K., Chen, G., Xie, Q., Xie, G., & Gong, X. (2025) · The VLDB Journal · doi:10.1007/s00778-025-00919-7 · Cited by 1
A Follow-the-Leader Strategy Using Hierarchical Deep Neural Networks with Grouped Convolutions
Solomon, J. E., & Charette, F. (2021) · SN Computer Science · doi:10.1007/s42979-021-00572-1 · Cited by 1
On The Connection of Benford's Law and Neural Networks.Preprint
Sahu, S. K., Java, A., & Shaikh, A. (2021) · arXiv (Cornell University) · Cited by 1
Liu, P., Gao, Z.-F., Zhao, W. X., Xie, Z. Y., Lu, Z.-Y., & Wen, J.-R. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2106.02205 · Cited by 1
Your fairness may vary: Group fairness of pretrained language models in toxic text classification.Preprint
Baldini, I., Wei, D., Ramamurthy, K. N., Yurochkin, M., & Singh, M. (2021) · arXiv (Cornell University) · Cited by 1
Data Mining Tool To Help The Scientific Community Develop Answers To Covid-19 Queries
Rajath, S., Kumar, A., Agarwal, M., shekar, S. N. C., & Prasad, V. B. (2021) · International Conference on Intelligent Computing in Data Sciences (ICDS) · doi:10.1109/icds53782.2021.9626771 · Cited by 1
Architectures for Machine Learning
Yang, Y., Chen, C., & Wang, Z. (2022) · Springer eBooks · doi:10.1007/978-981-15-6401-7_12-1
High-Throughput Edge Inference for BERT Models via Neural Architecture Search and Pipeline
Chang, H.-Y., Mozafari, S. H., Clark, J. J., Meyer, B. H., & Gross, W. J. (2023) · ACM Great Lakes Symposium on VLSI (GLSVLSI) · doi:10.1145/3583781.3590302
Hybrid Model Compression for BERT-Based Polyphone Disambiguation in Mandarin ChinesePreprint
Zhao, W., wang, Z., & xu, L. (2023) · doi:10.36227/techrxiv.23983191
Hybrid Model Compression for BERT-Based Polyphone Disambiguation in Mandarin ChinesePreprint
Zhao, W., wang, Z., & xu, L. (2023) · doi:10.36227/techrxiv.23983191.v1
Metadata
- Authors
- Iandola, F., Shaw, A., Krishna, R., & Keutzer, K.
- Affiliations
- University of California, Berkeley (US)
- Venue
- Proceedings of SustaiNLP: Workshop on Simple and Efficient Natural Language Processing
- Published
- 2020
- Pages
- 124-135
- OpenAlex
- W3036463250
- Cited by
- 114
- References
- 77
- Citations by year
- 2026: 6 · 2025: 15 · 2024: 10 · 2023: 30 · 2022: 21 · 2021: 27 · 2020: 5
- FWCI
- 6.40
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Workshop on Simple and Efficient Natural Language Processing (SustaiNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Samsung
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- efficient neural networks, group convolution, depthwise convolution, self-attention, BERT, RoBERTa, mobile deployment, computational efficiency, GLUE benchmark
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
