

The DOI matches its Crossref record; 88 of the 88 references it cites were found in a registry or an index.
SqueezeBERT: What can computer vision teach NLP about efficient neural networks?
Open accessAbstract
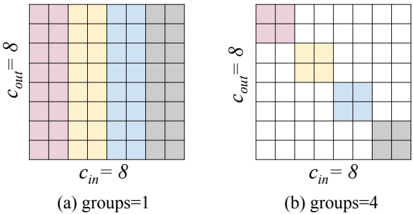
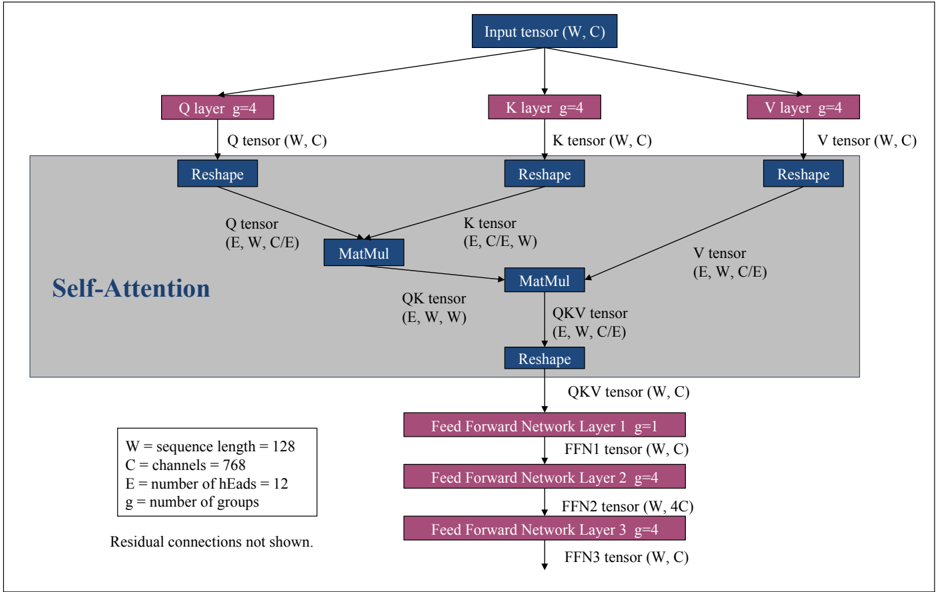
Humans read and write hundreds of billions of messages every day.Further, due to the availability of large datasets, large computing systems, and better neural network models, natural language processing (NLP) technology has made significant strides in understanding, proofreading, and organizing these messages.Thus, there is a significant opportunity to deploy NLP in myriad applications to help web users, social networks, and businesses.Toward this end, we consider smartphones and other mobile devices as crucial platforms for deploying NLP models at scale.However, today's highly-accurate NLP neural network models such as BERT and RoBERTa are extremely computationally expensive, with BERT-base taking 1.7 seconds to classify a text snippet on a Pixel 3 smartphone.To begin to address this problem, we draw inspiration from the computer vision community, where work such as MobileNet has demonstrated that grouped convolutions (e.g., depthwise convolutions) can enable speedups without sacrificing accuracy.We demonstrate how to replace several operations in self-attention layers with grouped convolutions and use this technique in a novel network architecture called Squeeze-BERT, which runs 4.3x faster than BERT-base on the Pixel 3 while achieving competitive accuracy on the GLUE test set.A PyTorch-based implementation of Squeeze-BERT is available as part of the Hugging Face Transformers library: https:// huggingface.co/squeezebert
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Moreover, models such as MobileBERT and SqueezeBERT employ bottleneck layers and grouped convolutions, leading to a 3× to 4× reduction in latency while maintaining >90% of the original model’s accuracy.”
From Tiny Language Models for Automation and Control: Overview, Potential Applications, and Future Research Directions (2025) · cites this paper as [103]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Very Deep Convolutional Networks for Large-Scale Image Recognition
Simonyan, K., & Zisserman, A. (2014) · arXiv · doi:10.48550/arxiv.1409.1556 · Cited by 114,148
ImageNet classification with deep convolutional neural networks
Krizhevsky, A., Sutskever, I., & Hinton, G. E. (2017) · Communications of the ACM · doi:10.1145/3065386 · Cited by 112,155
U-Net: Convolutional Networks for Biomedical Image Segmentation
Ronneberger, O., Fischer, P., & Brox, T. (2015) · Lecture notes in computer science · doi:10.1007/978-3-319-24574-4_28 · Cited by 99,404
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Densely Connected Convolutional Networks
Huang, G., Liu, Z., Van Der Maaten, L., & Weinberger, K. Q. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.243 · Cited by 48,566
Microsoft COCO: Common Objects in Context
Lin, T.-Y., Maire, M., Belongie, S., Hays, J., Perona, P., Ramanan, D., Dollár, P., & Zitnick, C. L. (2014) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-10602-1_48 · Cited by 45,460
ImageNet Large Scale Visual Recognition Challenge
Russakovsky, O., Deng, J., Su, H., Krause, J., Satheesh, S., Ma, S., Huang, Z., Karpathy, A., Khosla, A., Bernstein, M., et al. (2015) · International Journal of Computer Vision · doi:10.1007/s11263-015-0816-y · Cited by 39,380
Research works printed but not linked: 3
- William B. Dolan and Chris Brockett. 2005. Auto- matically constructing a corpus of sentential para- phrases. In Proceedings of the International Work- shop on Paraphrasing.
- Zhanghao Wu, Zhijian Liu, Ji Lin, Yujun Lin, and Song Han. 2020. Lite transformer with long short term attention. In ICLR.
- Ji Xin, Raphael Tang, Jaejun Lee, Yaoliang Yu, and Jimmy Lin. 2020. Deebert: Dynamic early exiting for accelerating bert inference. In ACL.
Cited by
Sorted by citations
Items 101–114 of 114
Yokoyama, T., Natter, J., & Godet, J. (2023) · medRxiv · doi:10.1101/2023.12.09.23299754 · Cited by 1
A Novel Information Theoretic Objective to Disentangle Representations for Fair Classification
Colombo, P., Noiry, N., Staerman, G., & Piantanida, P. (2023) · doi:10.18653/v1/2023.findings-ijcnlp.17 · Cited by 1
Towards resource-aware dialogue systems and sentiment analysis
Pandelea, V. (2024) · DR-NTU (Nanyang Technological University) · doi:10.32657/10356/173846
Battlefield Ground Target Detection Based on Improved Yolov10
Liu, P., Wang, J., Yang, H., Sun, T., Bo, Y., & Yang, L. (2025) · IEEE International Conference on Human-Machine Systems (ICHMS) · doi:10.1109/ichms65439.2025.11153978
Enhancing depression detection in social media through BERT model pruning
Yang, Y., Daud, S. N., & Peng, Z. (2025) · AIP conference proceedings · doi:10.1063/5.0291688
HEADoC: Highly Efficient and Accurate Document Classifier Optimized Using Semantic Distances
Khan, M. U., Tariq, M. A., & Siddique, M. S. (2025) · Progress in Artificial Intelligence · doi:10.1007/s13748-025-00411-x
Sector-Wise Backpropagation for Low-Resource Text Classification in Deep Models
Noguera, J. L. V., Valdez, C. U., Agüero-Torales, M. M., Mello-Román, J. C., Colbes, J. D., & Grillo, S. A. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-07959-6_18
Energy-Aware Deep Learning on GPUs through Parameter Sharing and Mixed Precision Training
Tchakoute, R. N., & Tadonki, C. (2025) · International Symposium on Computer Architecture and High Performance Computing Workshops (SBAC-PADW) · doi:10.1109/sbac-padw69789.2025.00024
Wang, Z., Li, Y., Fu, J., & Zhang, G. (2026) · Synthesis lectures on human language technologies · doi:10.1007/978-3-032-06264-2_4
On Subjectivity, Bias and Fairness in Language Model Learning
Gaci, Y. (2023) · theses.fr (ABES) · doi:10.70675/dca82074za0c4z46d1z8a6bz96ce30bea3b6
Naithani, A., & Jain, V. (2026) · International Symposium on Digital Forensics and Security (ISDFS) · doi:10.1109/isdfs69419.2026.11458952
Comparison of Transformer-based Deep Learning Methods for the Paraphrase Identification Task
Vrublevskyi, V., & Marchenko, O. O. (2022) · International Scientific Conference Information Technology and Implementation (IT&I) · doi:10.55056/ceur-ws.org/vol-3624/short_5.pdf
Drone Flight Log Forensics with BERT-based Entity Recognition
Syahputro, B., & Studiawan, H. (2025) · Asian Conference on Communication and Networks (ASIANComNet) · doi:10.1109/asiancomnet68615.2025.11579570
Sani, M. S., Iranmanesh, S., & Raad, R. (2026) · Sensors · doi:10.3390/s26185862
Metadata
- Authors
- Iandola, F., Shaw, A., Krishna, R., & Keutzer, K.
- Affiliations
- University of California, Berkeley (US)
- Venue
- Proceedings of SustaiNLP: Workshop on Simple and Efficient Natural Language Processing
- Published
- 2020
- Pages
- 124-135
- OpenAlex
- W3036463250
- Cited by
- 114
- References
- 77
- Citations by year
- 2026: 6 · 2025: 15 · 2024: 10 · 2023: 30 · 2022: 21 · 2021: 27 · 2020: 5
- FWCI
- 6.40
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Workshop on Simple and Efficient Natural Language Processing (SustaiNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Samsung
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Advanced Neural Network Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- efficient neural networks, group convolution, depthwise convolution, self-attention, BERT, RoBERTa, mobile deployment, computational efficiency, GLUE benchmark
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
