

The DOI matches its Crossref record; 62 of the 63 references it cites were found in a registry or an index, and 1 are not checked yet.
Multimodal Language Analysis in the Wild: CMU-MOSEI Dataset and Interpretable Dynamic Fusion Graph
Open accessAbstract
AmirAli Bagher Zadeh, Paul Pu Liang, Soujanya Poria, Erik Cambria, Louis-Philippe Morency. Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). 2018.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“This dataset encompasses 3837 videos collected from over 1000 distinctive YouTube speakers, with a reasonably balanced gender distribution of 57% male and 43% female speakers, highlighting the dataset’s focus on inclusivity.”
From A Survey of Deep Learning-Based Multimodal Emotion Recognition: Speech, Text, and Face (2023) · cites this paper as [30]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“The thematic diversity of the CMU-MOSEI dataset is notable, with a spread across 250 different themes. The three predominant themes are comments (16.2%), debates (2.9%), and consultations (1.8%), while the rest of the themes are nearly evenly distributed.”
From A Survey of Deep Learning-Based Multimodal Emotion Recognition: Speech, Text, and Face (2023) · cites this paper as [30]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“One of CMU-MOSEI’s unique characteristics is its annotations at the utterance level, with 23,259 samples annotated in this manner.”
From A Survey of Deep Learning-Based Multimodal Emotion Recognition: Speech, Text, and Face (2023) · cites this paper as [30]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“The CMU Multimodal Opinion Sentiment and Emotion Intensity (CMU-MOSEI) dataset [30] is a crucial resource in multimodal sentiment analysis and emotion recognition, distinguished by its scale, which is unmatched in the field.”
From A Survey of Deep Learning-Based Multimodal Emotion Recognition: Speech, Text, and Face (2023) · cites this paper as [30]
The cited source says what the claim attributes to it.
In the citing paper
“We generate open-ended AQAs about speech using the four commonly used datasets IEMOCAP [23], MOSEI [24], LibriTTS [25], and Vox-Celeb2 [26,27].”
From Joint Audio and Speech Understanding (2023) · cites this paper as [24]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Breiman, L. (2001) · Machine Learning · doi:10.1023/a:1010933404324 · Cited by 133,538
Hochreiter, S., & Schmidhuber, J. (1997) · Neural Computation · doi:10.1162/neco.1997.9.8.1735 · Cited by 102,318
Cortes, C., & Vapnik, V. (1995) · Machine Learning · doi:10.1007/bf00994018 · Cited by 59,421
Cortes, C., & Vapnik, V. N. (1995) · Machine Learning · doi:10.1023/a:1022627411411 · Cited by 34,565
Glove: Global Vectors for Word Representation
Pennington, J., Socher, R., & Manning, C. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1162 · Cited by 34,071
FaceNet: A unified embedding for face recognition and clustering
Schroff, F., Kalenichenko, D., & Philbin, J. (2015) · 2015 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2015.7298682 · Cited by 15,267
Bidirectional recurrent neural networks
Schuster, M., & Paliwal, K. K. (1997) · IEEE Transactions on Signal Processing · doi:10.1109/78.650093 · Cited by 10,172
Speech recognition with deep recurrent neural networks
Graves, A., Mohamed, A.-R., & Hinton, G. (2013) · 2013 IEEE International Conference on Acoustics, Speech and Signal Processing · doi:10.1109/icassp.2013.6638947 · Cited by 8,893
The Stanford CoreNLP Natural Language Processing Toolkit
Manning, C. D., Surdeanu, M., Bauer, J., Finkel, J. R., Bethard, S. J., & McClosky, D. (2014) · Annual Meeting of the Association for Computational Linguistics: System Demonstrations (ACL Demo) · doi:10.3115/v1/p14-5010 · Cited by 7,252
Thumbs up?: sentiment classification using machine learning techniques
Pang, B., Lee, L., & Vaithyanathan, S. (2002) · Proceedings of the ACL-02 conference on Empirical methods in natural language processing - EMNLP '02 · doi:10.3115/1118693.1118704 · Cited by 7,024
Recursive Deep Models for Semantic Compositionality Over a Sentiment Treebank
Socher, R., Perelygin, A., Wu, J., Chuang, J., Manning, C. D., Ng, A., & Potts, C. (2013) · Proceedings of the 2013 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d13-1170 · Cited by 6,878
DeepFace: Closing the Gap to Human-Level Performance in Face Verification
Taigman, Y., Yang, M., Ranzato, M., & Wolf, L. (2014) · 2014 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2014.220 · Cited by 6,542
3D Convolutional Neural Networks for Human Action Recognition
Ji, S., Xu, W., Yang, M., & Yu, K. (2012) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2012.59 · Cited by 6,313
Joint Face Detection and Alignment Using Multitask Cascaded Convolutional Networks
Zhang, K., Zhang, Z., Li, Z., & Qiao, Y. (2016) · IEEE Signal Processing Letters · doi:10.1109/lsp.2016.2603342 · Cited by 6,214
Multimodal Machine Learning: A Survey and Taxonomy
Baltrusaitis, T., Ahuja, C., & Morency, L.-P. (2019) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2018.2798607 · Cited by 5,018
Self-citationIEMOCAP: Interactive emotional dyadic motion capture database
Busso, C., Bulut, M., Lee, C.-C., Kazemzadeh, A., Mower, E., Kim, S., Chang, J. N., Lee, S., & Narayanan, S. S. (2008) · Language Resources and Evaluation · doi:10.1007/s10579-008-9076-6 · Cited by 3,869
Learning Word Vectors for Sentiment Analysis
Maas, A. L., Daly, R. E., Pham, P. T., Huang, D., Ng, A. Y., & Potts, C. (2011) · Cited by 3,710
A Convolutional Neural Network for Modelling Sentences
Kalchbrenner, N., Grefenstette, E., & Blunsom, P. (2014) · Proceedings of the 52nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.3115/v1/p14-1062 · Cited by 3,601
SphereFace: Deep Hypersphere Embedding for Face Recognition
Liu, W., Wen, Y., Yu, Z., Li, M., Raj, B., & Song, L. (2017) · 2017 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2017.713 · Cited by 2,280
Thumbs up? Sentiment Classification using Machine Learning TechniquesPreprint
Pang, B., Lee, L., & Vaithyanathan, S. (2002) · arXiv (Cornell University) · doi:10.48550/arxiv.cs/0205070 · Cited by 2,211
Tensor Fusion Network for Multimodal Sentiment Analysis
Zadeh, A., Chen, M., Poria, S., Cambria, E., & Morency, L.-P. (2017) · Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d17-1115 · Cited by 2,102
Self-citationOpenFace: An open source facial behavior analysis toolkit
Baltrušaitis, T., Robinson, P., & Morency, L. (2016) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv.2016.7477553 · Cited by 1,794
Self-citationTraining Very Deep NetworksPreprint
Srivastava, R. K., Greff, K., & Schmidhuber, J. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1507.06228 · Cited by 1,504
Context-Dependent Sentiment Analysis in User-Generated Videos
Poria, S., Cambria, E., Hazarika, D., Majumder, N., Zadeh, A., & Morency, L.-P. (2017) · Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p17-1081 · Cited by 939
Self-citationFacial signs of emotional experience.
Ekman, P., Freisen, W. V., & Ancoli, S. (1980) · Journal of Personality and Social Psychology · doi:10.1037/h0077722 · Cited by 915
Adieu features? End-to-end speech emotion recognition using a deep convolutional recurrent network
Trigeorgis, G., Ringeval, F., Brueckner, R., Marchi, E., Nicolaou, M. A., Schuller, B., & Zafeiriou, S. (2016) · 2016 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp.2016.7472669 · Cited by 904
A C-LSTM Neural Network for Text ClassificationPreprint
Zhou, C., Sun, C., Liu, Z., & Lau, F. C. M. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1511.08630 · Cited by 882
Memory Fusion Network for Multi-view Sequential Learning
Zadeh, A., Liang, P. P., Mazumder, N., Poria, S., Cambria, E., & Morency, L.-P. (2018) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v32i1.12021 · Cited by 855
Self-citationMultimodal Sentiment Intensity Analysis in Videos: Facial Gestures and Verbal Messages
Zadeh, A., Zellers, R., Pincus, E., & Morency, L.-P. (2016) · IEEE Intelligent Systems · doi:10.1109/mis.2016.94 · Cited by 852
Self-citationIntroducing the RECOLA multimodal corpus of remote collaborative and affective interactions
Ringeval, F., Sonderegger, A., Sauer, J., & Lalanne, D. (2013) · 2013 10th IEEE International Conference and Workshops on Automatic Face and Gesture Recognition (FG) · doi:10.1109/fg.2013.6553805 · Cited by 771
Deep Unordered Composition Rivals Syntactic Methods for Text Classification
Iyyer, M., Manjunatha, V., Boyd-Graber, J. L., & Daumé, H. (2015) · doi:10.3115/v1/p15-1162 · Cited by 729
COVAREP — A collaborative voice analysis repository for speech technologies
Degottex, G., Kane, J., Drugman, T., Raitio, T., & Scherer, S. (2014) · 2014 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp.2014.6853739 · Cited by 695
Collecting Large, Richly Annotated Facial-Expression Databases from Movies
Dhall, A., Goecke, R., Lucey, S., & Gedeon, T. (2012) · IEEE Multimedia · doi:10.1109/mmul.2012.26 · Cited by 658
Convolutional MKL Based Multimodal Emotion Recognition and Sentiment Analysis
Poria, S., Chaturvedi, I., Cambria, E., & Hussain, A. (2016) · Proceedings · doi:10.1109/icdm.2016.0055 · Cited by 624
Self-citationSpeaker identification on the SCOTUS corpus
Yuan, J., & Liberman, M. (2008) · The Journal of the Acoustical Society of America · doi:10.1121/1.2935783 · Cited by 610
Grossberg, S. (2013) · Scholarpedia · doi:10.4249/scholarpedia.1888 · Cited by 602
Towards multimodal sentiment analysis: harvesting opinions from the web
Morency, L.-P., Mihalcea, R., & Doshi, P. (2011) · Proceedings of the 13th international conference on multimodal interfaces · doi:10.1145/2070481.2070509 · Cited by 470
Self-citationSpeech emotion recognition using convolutional and Recurrent Neural Networks
Lım, W., Jang, D., & Lee, T. (2016) · Asia-Pacific Signal and Information Processing Association Annual Summit and Conference (APSIPA ASC) · doi:10.1109/apsipa.2016.7820699 · Cited by 433
The Vera am Mittag German audio-visual emotional speech database
Grimm, M., Kroschel, K., & Narayanan, S. S. (2008) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme.2008.4607572 · Cited by 413
Tian, Y., Takeo Kanade, A., & Cohn, J. F. (2005) · Springer eBooks · doi:10.1007/0-387-27257-7_12 · Cited by 407
Youtube movie reviews: Sentiment analysis in an audio-visual context
Wollmer, M., Weninger, F., Knaup, T., Schuller, B., Sun, C., Sagae, K., & Morency, L.-P. (2013) · IEEE Intelligent Systems · doi:10.1109/mis.2013.34 · Cited by 403
Self-citationMOSI: Multimodal Corpus of Sentiment Intensity and Subjectivity Analysis in Online Opinion Videos
Zadeh, A., Zellers, R., Pincus, E., & Morency, L.-P. (2016) · arXiv · doi:10.48550/arxiv.1606.06259 · Cited by 350
Self-citationMultimodal sentiment analysis with word-level fusion and reinforcement learning
Chen, M., Wang, S., Liang, P. P., Baltrušaitis, T., Zadeh, A., & Morency, L.-P. (2017) · Proceedings of the 19th ACM International Conference on Multimodal Interaction · doi:10.1145/3136755.3136801 · Cited by 334
Self-citationRecurrent Highway NetworksPreprint
Zilly, J., Srivastava, R., Koutník, J., & Schmidhuber, J. (2016) · arXiv (Cornell University) · doi:10.3929/ethz-b-000233981 · Cited by 314
Video and Image based Emotion Recognition Challenges in the Wild: EmotiW 2015
Dhall, A., Ramana Murthy, O. V., Goecke, R., Joshi, J., & Gedeon, T. (2015) · Proceedings of the 2015 ACM on International Conference on Multimodal Interaction · doi:10.1145/2818346.2829994 · Cited by 305
Normalized amplitude quotient for parametrization of the glottal flow.
Alku, P., Bäckström, T., & Vilkman, E. (2002) · The Journal of the Acoustical Society of America · doi:10.1121/1.1490365 · Cited by 287
(2009) · Springer eBooks · doi:10.1007/978-0-387-73003-5_2171 · Cited by 269
Deep multimodal fusion for persuasiveness prediction
Nojavanasghari, B., Gopinath, D., Koushik, J., Baltrušaitis, T., & Morency, L. (2016) · INTERNATIONAL CONFERENCE ON MULTIMODAL INTERACTION · doi:10.1145/2993148.2993176 · Cited by 247
Self-citationDetection of Glottal Closure Instants From Speech Signals: A Quantitative Review
Thomas Drugman, A., Thomas, M. R., Guðnason, J., Naylor, P. A., & Dutoit, T. (2011) · IEEE Transactions on Audio Speech and Language Processing · doi:10.1109/tasl.2011.2170835 · Cited by 236
(2013) · Cited by 236
Joint robust voicing detection and pitch estimation based on residual harmonics
Drugman, T., & Alwan, A. A. (2011) · Interspeech (USB) · doi:10.21437/interspeech.2011-519 · Cited by 228
Matsumoto, Y., & Mihalcea, R. F. (2011) · Cited by 175
Extending Long Short-Term Memory for Multi-View Structured Learning
Rajagopalan, S. S., Morency, L., Baltrušaitis, T., & Goecke, R. (2016) · Lecture notes in computer science · doi:10.1007/978-3-319-46478-7_21 · Cited by 139
Self-citationComputational Analysis of Persuasiveness in Social Multimedia
Park, S., Shim, H. S., Chatterjee, M., Sagae, K., & Morency, L. (2014) · INTERNATIONAL CONFERENCE ON MULTIMODAL INTERACTION · doi:10.1145/2663204.2663260 · Cited by 127
Self-citationMemory Fusion Network for Multi-view Sequential LearningPreprint
Zadeh, A., Liang, P. P., Mazumder, N., Poria, S., Cambria, E., & Morency, L. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1802.00927 · Cited by 117
Self-citationWavelet Maxima Dispersion for Breathy to Tense Voice Discrimination
Kane, J., & Gobl, C. (2013) · IEEE Transactions on Audio Speech and Language Processing · doi:10.1109/tasl.2013.2245653 · Cited by 85
Combating Human Trafficking with Multimodal Deep Models
Tong, E., Zadeh, A., Jones, C., & Morency, L. (2017) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p17-1142 · Cited by 83
Self-citationParabolic spectral parameter — A new method for quantification of the glottal flow
Alku, P., Strik, H., & Vilkman, E. A. (1997) · Speech Communication · doi:10.1016/s0167-6393(97)00020-4 · Cited by 73
The MAHNOB Mimicry Database: A database of naturalistic human interactions
Bilakhia, S., Petridis, S., Nijholt, A., & Pantić, M. (2015) · Pattern Recognition Letters · doi:10.1016/j.patrec.2015.03.005 · Cited by 61
Müller, F. M. (2001) · Cited by 52
Multi-attention Recurrent Network for Human Communication Comprehension
Zadeh, A., Liang, P. P., Poria, S., Vij, P., Cambria, E., & Morency, L. (2018) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v32i1.12024 · Cited by 49
Self-citationWang, H., Meghawat, A., Morency, L., & Xing, E. P. (2016) · arXiv (Cornell University) · Cited by 29
Self-citationDynamic Wordclouds and Vennclouds for Exploratory Data Analysis
Coppersmith, G., & Kelly, E. (2014) · doi:10.3115/v1/w14-3103 · Cited by 20
Research works printed but not linked: 3
- Gilles Degottex, John Kane, Thomas Drugman, Tuomo Raitio, and Stefan Scherer. 2014. Covarep-a col- laborative voice analysis repository for speech tech- nologies. In Acoustics, Speech and Signal Process- ing (ICASSP), 2014 IEEE International Conference on. IEEE, pages 960-964.
- Devamanyu Hazarika, Soujanya Poria, Amir Zadeh, Erik Cambria, Louis-Philippe Morency, and Roger Zimmerman. 2018. Memn: Multimodal emotional memory network for emotion recognition in dyadic conversational videos. In NAACL.
- Julian Georg Zilly, Rupesh Kumar Srivastava, Jan Koutník, and Jürgen Schmidhuber. 2016. Re- current Highway Networks. arXiv preprint arXiv:1607.03474 . · arXiv
Cited by
Sorted by citations
Multimodal Transformer for Unaligned Multimodal Language Sequences
Tsai, Y.-H. H., Bai, S., Liang, P. P., Kolter, J. Z., Morency, L.-P., & Salakhutdinov, R. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1656 · Cited by 2,259
“Both tasks are frequently used to benchmark models’ ability to fuse multimodal (sentiment) information (Poria et al., 2017; Zadeh et al., 2018a; Liang et al., 2018; Tsai et al., 2019; Pham et al., 2019; Wang et al., 2019).”
BackgroundMethodInfluentialSelf-citationMELD: A Multimodal Multi-Party Dataset for Emotion Recognition in Conversations
Poria, S., Hazarika, D., Majumder, N., Naik, G., Cambria, E., & Mihalcea, R. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1050 · Cited by 1,416
“The other publicly available multimodal emotion and sentiment recognition datasets are MOSEI (Zadeh et al., 2018b), MOSI (Zadeh et al., 2016b), and MOUD (P´erez-Rosas et al., 2013), however none of these datasets is conversational.”
BackgroundSelf-citationMISA: Modality-Invariant and -Specific Representations for Multimodal Sentiment Analysis
Hazarika, D., Zimmermann, R., & Poria, S. (2020) · Proceedings of the 28th ACM International Conference on Multimedia · doi:10.1145/3394171.3413678 · Cited by 1,073
“com/platform/ 4Please refer to [19, 60] and their respective SDKs (https://github.”
BackgroundMethodInfluentialSelf-citationDynamic Neural Networks: A Survey
Han, Y., Huang, G., Song, S., Yang, L., Wang, H., & Wang, Y. (2022) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2021.3117837 · Cited by 848
Gandhi, A., Adhvaryu, K., Poria, S., Cambria, E., & Hussain, A. (2023) · Information Fusion · doi:10.1016/j.inffus.2022.09.025 · Cited by 783
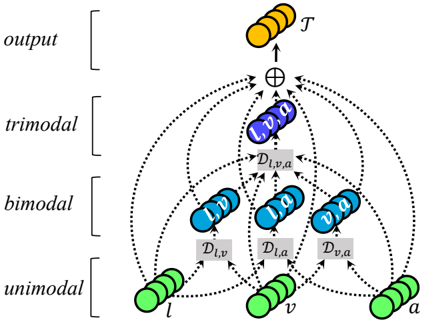
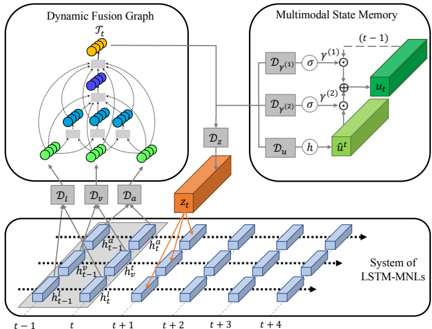
“[47] DFG 2018 Word-level Fusion MFN+DFG CMU-MOSEI Multi-view sequential learning that consists of three main components System of LSTMs consists of multiple Longshort Term Memory (LSTM) networks, Deltamemory Attention Network 85.”
BackgroundSelf-citation
Metadata
- Authors
- Bagher Zadeh, A., Liang, P. P., Poria, S., Cambria, E., & Morency, L.-P.
- Affiliations
- California Miramar University (US)
- Nanyang Technological University (SG)
- Agency for Science, Technology and Research (SG)
- Venue
- Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
- Published
- 2018
- Pages
- 2236-2246
- ISSN
- 0736-587X (ISSN-L)
- OpenAlex
- W2883409523
- Cited by
- 1,433
- References
- 62
- Citations by year
- 2026: 281 · 2025: 300 · 2024: 266 · 2023: 202 · 2022: 153 · 2021: 113 · 2020: 73 · 2019: 39 · 2018: 6
- FWCI
- 17.41
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Proceedings of the conference - Association for Computational Linguistics. Meeting (publishedVersion, cc-by)
- Funders
- National Science Foundation
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Sentiment Analysis and Opinion Mining
- Physical Sciences › Computer Science › Artificial Intelligence › Speech and dialogue systems
- Keywords
- CMU-MOSEI, multimodal fusion, emotion recognition
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
