

Is Attention Interpretable?
Open accessThe DOI matches its Crossref record; 43 of the 43 references it cites were found in a registry or an index.
Abstract
Attention mechanisms have recently boosted performance on a range of NLP tasks.Because attention layers explicitly weight input components' representations, it is also often assumed that attention can be used to identify information that models found important (e.g., specific contextualized word tokens).We test whether that assumption holds by manipulating attention weights in already-trained text classification models and analyzing the resulting differences in their predictions.While we observe some ways in which higher attention weights correlate with greater impact on model predictions, we also find many ways in which this does not hold, i.e., where gradient-based rankings of attention weights better predict their effects than their magnitudes.We conclude that while attention noisily predicts input components' overall importance to a model, it is by no means a fail-safe indicator.1
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures


Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Besides using Incremental Deletion/Addition to evaluate correctness and output-completeness, compactness can be evaluated by counting how many features of the explanation need to be removed, perturbed or added to change the decision of the predictive model [7,34,70,123,165,221].”
From From Anecdotal Evidence to Quantitative Evaluation Methods: A Systematic Review on Evaluating Explainable AI (2023) · cites this paper as [221]
Experimental — accuracy not yet measuredIn the citing paper
“In [85], the attention mechanism weights were seen as at best noisy predictors of the relative importance of specific regions of the input sequence, and they should not be treated as justifications for the model’s decisions.”
From Survey of Explainable AI Techniques in Healthcare (2023) · cites this paper as [85]
In the citing paper
“Although this is typically the case for softmax scores [221], there might be cases where this assumption is invalid.”
From From Anecdotal Evidence to Quantitative Evaluation Methods: A Systematic Review on Evaluating Explainable AI (2023) · cites this paper as [221]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Adam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946 · cited 1×
“Unless otherwise noted, to train each model, we used Adam (Kingma and Ba, 2014) with gradient clipping of 10.0 and a patience value of 5, so we would stop training a model if five epochs elapsed without any improvement in validation set accuracy.”
MethodInfluential"Why Should I Trust You?": Explaining the Predictions of Any Classifier
Ribeiro, M. T., Singh, S., & Guestrin, C. (2016) · Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining · doi:10.1145/2939672.2939778 · Cited by 17,555 · cited 4×
“Note, however, that we still do not take either as a gold-standard indicator of importance to the model, as with the gradient in Ross et al. (2017) and Melis and Jaakkola (2018), but merely as an alternative ordering method.”
BackgroundMethodInfluentialNeural Machine Translation by Jointly Learning to Align and Translate
Bahdanau, D., Cho, K., & Bengio, Y. (2014) · arXiv · doi:10.48550/arxiv.1409.0473 · Cited by 16,213 · cited 2×
“Specifically, we use the additive formulation originally defined in Bahdanau et al. (2015).”
BackgroundMethodConvolutional Neural Networks for Sentence Classification
Kim, Y. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1181 · Cited by 14,831 · cited 2×
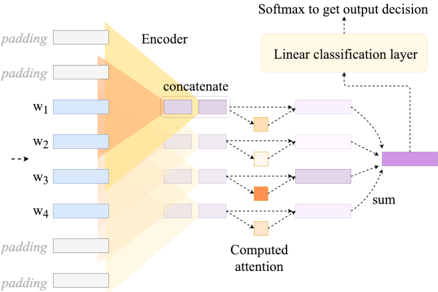
“Aside from biRNNs, we also experiment with models that instead contextualize word vectors by convolutions on only a token’s close neighbors, inspired by Kim (2014). See Figure 2 for a diagram of the FLAN architecture using a convolutional encoder.”
MethodEffective Approaches to Attention-based Neural Machine Translation
Luong, T., Pham, H., & Manning, C. D. (2015) · Proceedings of the 2015 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d15-1166 · Cited by 8,382 · cited 1×
“For many different problems — to name a few, machine translation (Luong et al., 2015), syntactic parsing (Vinyals et al., 2015), reading comprehension (Hermann et al., 2015), and language modeling (Liu and Lapata, 2018) — incorporating attention mechanisms into models has proven beneficial for…”
BackgroundLipton, Z. C. (2018) · Queue · doi:10.1145/3236386.3241340 · Cited by 5,427 · cited 1×
“Lipton (2016) describes a model as “transparent” if “a person can contemplate the entire model at once.””
BackgroundHierarchical Attention Networks for Document Classification
Yang, Z., Yang, D., Dyer, C., He, X., Smola, A., & Hovy, E. (2016) · Proceedings of the 2016 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies · doi:10.18653/v1/n16-1174 · Cited by 4,712 · cited 6×
“Our model architectures are inspired by the hierarchical attention network (HAN; Yang et al., 2016), a text classification model with two layers of attention, first to the word tokens in each sentence and then to the resulting sentence representations.”
BackgroundMethodResultInfluentialCharacter-level Convolutional Networks for Text Classification
Zhang, X., Zhao, J., & LeCun, Y. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1509.01626 · Cited by 3,205 · cited 3×
“We investigate four model architectures on a topic classification dataset (Yahoo Answers; Zhang et al., 2015) and on three review ratings datasets: IMDB (Diao et al.”
MethodTeaching Machines to Read and Comprehend
Hermann, K. M., Kočiský, T., Grefenstette, E., Espeholt, L., Kay, W., Suleyman, M., & Blunsom, P. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1506.03340 · Cited by 2,521 · cited 1×
“For many different problems—to name a few, machine translation (Luong et al., 2015), syntactic parsing (Vinyals et al., 2015), reading comprehension (Hermann et al., 2015), and language modeling (Liu and Lapata, 2018)—incorporating attention mechanisms into models has proven benefi-cial for…”
Background
Research works printed but not linked: 4
- Philipp Koehn and Rebecca Knowles. 2017. Six chal- lenges for neural machine translation. In Pro- ceedings of the First Workshop on Neural Machine Translation.
- Zachary C Lipton. 2016. The mythos of model inter- pretability. arXiv preprint arXiv:1606.03490. · arXiv
- Yang Liu and Mirella Lapata. 2018. Learning struc- tured text representations. Transactions of the Asso- ciation of Computational Linguistics, 6:63-75.
- Oriol Vinyals, Łukasz Kaiser, Terry Koo, Slav Petrov, Ilya Sutskever, and Geoffrey Hinton. 2015. Gram- mar as a foreign language. In Advances in Neural Information Processing Systems.
Cited by
Han (2023) · doi:10.1109/tpami.2022.3152247 · Cited by 4,682
“Transformer is originally applied on natural language processing (NLP) tasks and brings in significant improvement [123, 29, 10].”
BackgroundInfluentialA review on the attention mechanism of deep learning
Niu, Z., Zhong, G., & Yu, H. (2021) · Neurocomputing · doi:10.1016/j.neucom.2021.03.091 · Cited by 3,379
Pre-trained models for natural language processing: A survey
Qiu, X., Sun, T., Xu, Y., Shao, Y., Dai, N., & Huang, X. (2020) · Science China Technological Sciences · doi:10.1007/s11431-020-1647-3 · Cited by 1,591
“However, much work on model analysis depends on the attention mechanism, and the effectiveness of attention for interpretability is still controversial [71, 155].”
BackgroundA primer in BERTology: What we know about how BERT works
Rogers, A., Kovaleva, O., & Rumshisky, A. (2020) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00349 · Cited by 1,552
“However, there is ongoing debate on the merits of attention as a tool for interpreting deep learning models (Jain and Wallace, 2019; Serrano and Smith, 2019; Wiegreffe and Pinter, 2019; Brunner et al., 2020).”
MethodAn Attentive Survey of Attention Models
Chaudhari, S., Mithal, V., Polatkan, G., & Ramanath, R. (2021) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3465055 · Cited by 689
Metadata
- Authors
- Serrano, S., & Smith, N. A.
- Affiliations
- University of Washington (US)
- Venue
- Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics
- Published
- 2019
- Pages
- 2931-2951
- ISSN
- 0736-587X (ISSN-L)
- OpenAlex
- W2948140294
- Cited by
- 690
- References
- 39
- Citations by year
- 2026: 63 · 2025: 85 · 2024: 82 · 2023: 102 · 2022: 119 · 2021: 143 · 2020: 80 · 2019: 15
- FWCI
- 34.15
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Proceedings of the conference - Association for Computational Linguistics. Meeting (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Explainable Artificial Intelligence (XAI)
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- attention mechanism, interpretability, text classification, model interpretability, feature importance, explainable AI
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: Is Attention Interpretable? https://app.cochat.ai/papers/10.18653/v1/p19-1282
- The paper
- Serrano, S., & Smith, N. A. (2019). Is Attention Interpretable? Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics. https://doi.org/10.18653/v1/p19-1282
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
