

Virtual Patients Using Large Language Models: Scalable, Contextualized Simulation of Clinician-Patient Dialogue With Feedback
Open accessPublished version of a preprint
The DOI matches its Crossref record; 66 of the 66 references it cites were found in a registry or an index.
Abstract
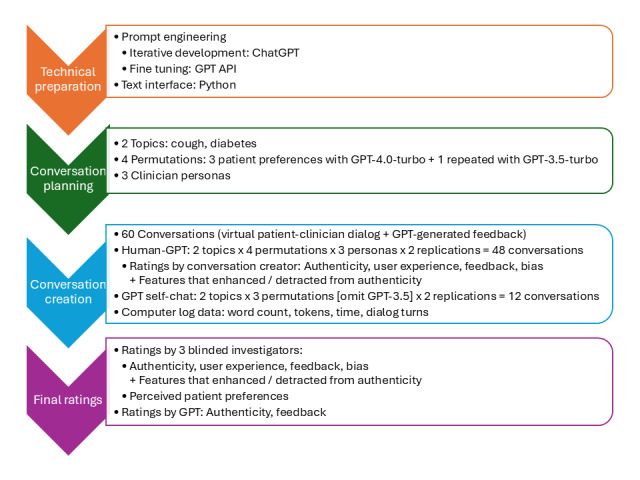
Background: Virtual patients (VPs) are computer screen–based simulations of patient-clinician encounters. VP use is limited by cost and low scalability. Objective: We aimed to show that VPs powered by large language models (LLMs) can generate authentic dialogues, accurately represent patient preferences, and provide personalized feedback on clinical performance. We also explored using LLMs to rate the quality of dialogues and feedback. Methods: We conducted an intrinsic evaluation study rating 60 VP-clinician conversations. We used carefully engineered prompts to direct OpenAI’s generative pretrained transformer (GPT) to emulate a patient and provide feedback. Using 2 outpatient medicine topics (chronic cough diagnosis and diabetes management), each with permutations representing different patient preferences, we created 60 conversations (dialogues plus feedback): 48 with a human clinician and 12 “self-chat” dialogues with GPT role-playing both the VP and clinician. Primary outcomes were dialogue authenticity and feedback quality, rated using novel instruments for which we conducted a validation study collecting evidence of content, internal structure (reproducibility), relations with other variables, and response process. Each conversation was rated by 3 physicians and by GPT. Secondary outcomes included user experience, bias, patient preferences represented in the dialogues, and conversation features that influenced authenticity. Results: The average cost per conversation was US $0.51 for GPT-4.0-Turbo and US $0.02 for GPT-3.5-Turbo. Mean (SD) conversation ratings, maximum 6, were overall dialogue authenticity 4.7 (0.7), overall user experience 4.9 (0.7), and average feedback quality 4.7 (0.6). For dialogues created using GPT-4.0-Turbo, physician ratings of patient preferences aligned with intended preferences in 20 to 47 of 48 dialogues (42%-98%). Subgroup comparisons revealed higher ratings for dialogues using GPT-4.0-Turbo versus GPT-3.5-Turbo and for human-generated versus self-chat dialogues. Feedback ratings were similar for human-generated versus GPT-generated ratings, whereas authenticity ratings were lower. We did not perceive bias in any conversation. Dialogue features that detracted from authenticity included that GPT was verbose or used atypical vocabulary (93/180, 51.7% of conversations), was overly agreeable (n=56, 31%), repeated the question as part of the response (n=47, 26%), was easily convinced by clinician suggestions (n=35, 19%), or was not disaffected by poor clinician performance (n=32, 18%). For feedback, detractors included excessively positive feedback (n=42, 23%), failure to mention important weaknesses or strengths (n=41, 23%), or factual inaccuracies (n=39, 22%). Regarding validation of dialogue and feedback scores, items were meticulously developed (content evidence), and we confirmed expected relations with other variables (higher ratings for advanced LLMs and human-generated dialogues). Reproducibility was suboptimal, due largely to variation in LLM performance rather than rater idiosyncrasies. Conclusions: LLM-powered VPs can simulate patient-clinician dialogues, demonstrably represent patient preferences, and provide personalized performance feedback. This approach is scalable, globally accessible, and inexpensive. LLM-generated ratings of feedback quality are similar to human ratings.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“LLM-generated simulations demonstrate clinically relevant psychiatric exchanges [23-25] and generate automated feedback aligned with expert judgment [26], offering a cost-efficient and scalable alternative to real patients for clinical training.”
From Enhancing Psychiatry Training Using an Agentic AI Simulated Consultation Tool: Prospective Cohort Study (2026) · cites this paper as [23]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Prior studies have demonstrated the technical feasibility of text-based VSPs and AI-assisted automated scoring systems.”
In the citing paper
“These findings, echoed by Cook et al [23], who observed that LLM-powered virtual patients generated personalized, high-quality performance feedback rated comparably to human evaluators, substantiate the potential of AI-assisted formative assessment in clinical education.”
From Enhancing Psychiatry Training Using an Agentic AI Simulated Consultation Tool: Prospective Cohort Study (2026) · cites this paper as [23]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The Measurement of Observer Agreement for Categorical Data
Landis, J. R., & Koch, G. G. (1977) · Biometrics · doi:10.2307/2529310 · Cited by 81,148 · cited 1×
“To appraise rating reproducibility, we estimated variance components and calculated a single-rating intraclass correlation coefficient (ICC), which was interpreted using criteria from Landis and Koch [66] (ie, 0-0.2=slight; 0.21-0.4=fair; 0.41-0.6=moderate; and 0.61-0.8=substantial).”
InfluentialThe FAIR Guiding Principles for scientific data management and stewardship
Wilkinson, M. D., Dumontier, M., Aalbersberg, I. J., Appleton, G., Axton, M., Baak, A., Blomberg, N., Boiten, J.-W., da Silva Santos, L. B., Bourne, P. E., et al. (2016) · Scientific Data · doi:10.1038/sdata.2016.18 · Cited by 18,423 · cited 1×
“LLMs represent a disruptive technology [31], offering an unprecedented opportunity to transform VP production and use, enabling scalable, accessible (ie, inexpensive and low expertise), interoperable, and reusable [32] simulations of patient-clinician encounters.”
An overview of clinical decision support systems: Benefits, risks, and strategies for success
Sutton, R. T., Pincock, D., Baumgart, D. C., Sadowski, D. C., Fedorak, R. N., & Kroeker, K. I. (2020) · npj Digital Medicine · doi:10.1038/s41746-020-0221-y · Cited by 3,019 · cited 1×
“VPs—computer screen–based simulations of patient-clinician encounters [7]—have demonstrated efficacy in teaching, assessing, and studying clinical reasoning [8] and could also support validation of decision-support tools before clinical implementation [9,10].”
The Experience of Presence: Factor Analytic Insights
Schubert, T., Friedmann, F., & Regenbrecht, H. (2001) · Presence: Teleoperators and Virtual Environments · doi:10.1162/105474601300343603 · Cited by 2,303 · cited 1×
“We added a third empirically derived framework for evaluating “presence” in virtual reality (ie, realness, involvement, and spatial “physical” presence) [54,55].”
Current Concepts in Validity and Reliability for Psychometric Instruments: Theory and Application
Cook, D. A., & Beckman, T. J. (2006) · The American Journal of Medicine · doi:10.1016/j.amjmed.2005.10.036 · Cited by 1,745 · cited 1×
“For the 3 novel instruments, we conducted a validation study collecting validity evidence from 4 of 5 potential sources [39,40]: content (ie, grounding of the instruments in theory and prior empirical work); internal structure (ie, rating reproducibility); relations with other variables (ie,…”
Self-citationFeedback in Clinical Medical Education
Ende, J. (1983) · JAMA: The Journal of the American Medical Association · doi:10.1001/jama.1983.03340060055026 · Cited by 1,329 · cited 1×
“Providing performance feedback to clinicians is also essential in clinical skill development [23], yet it is commonly of low quality or simply absent [24-27].”
Liu, C.-W., Lowe, R., Serban, I., Noseworthy, M., Charlin, L., & Pineau, J. (2016) · Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d16-1230 · Cited by 1,228
Language (Technology) is Power: A Critical Survey of “Bias” in NLP
Blodgett, S. L., Barocas, S., Daumé III, H., & Wallach, H. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.485 · Cited by 1,050 · cited 1×
“Bias—“skew that produces a type of harm toward different social groups” [62]—is a well-known risk in AI generally and natural language generation specifically [62-65].”
A three-talk model for shared decision making: multistage consultation process
Elwyn, G., Durand, M. A., Song, J., Aarts, J., Barr, P. J., Berger, Z., Cochran, N., Frosch, D., Galasiński, D., Gulbrandsen, P., et al. (2017) · BMJ · doi:10.1136/bmj.j4891 · Cited by 1,018
What every teacher needs to know about clinical reasoning
Eva, K. W. (2005) · Medical Education · doi:10.1111/j.1365-2929.2004.01972.x · Cited by 930 · cited 1×
“As we seek to prevent errors in clinical practice [1,2] and promote high-value care [3,4], we need to better understand clinical reasoning and how to support its development and application [2,5].”
The Mini-CEX: A Method for Assessing Clinical Skills
Norcini, J. J., Blank, L. L., Duffy, F. D., & Fortna, G. S. (2003) · Annals of Internal Medicine · doi:10.7326/0003-4819-138-6-200303180-00012 · Cited by 730
Virtual patients: a critical literature review and proposed next steps
Cook, D. A., & Triola, M. M. (2009) · Medical Education · doi:10.1111/j.1365-2923.2008.03286.x · Cited by 624 · cited 1×
“VPs—computer screen–based simulations of patient-clinician encounters [7]—have demonstrated efficacy in teaching, assessing, and studying clinical reasoning [8] and could also support validation of decision-support tools before clinical implementation [9,10].”
Self-citationNorman, G. R., Monteiro, S. D., Sherbino, J., Ilgen, J. S., Schmidt, H. G., & Mamede, S. (2017) · Academic Medicine · doi:10.1097/acm.0000000000001421 · Cited by 594
Computerized Virtual Patients in Health Professions Education: A Systematic Review and Meta-Analysis
Cook, D. A., Erwin, P. J., & Triola, M. M. (2010) · Academic Medicine · doi:10.1097/acm.0b013e3181edfe13 · Cited by 570 · cited 2×
“Hence, VP implementations typically comprise few cases and lack case-to-case variability in salient features (eg, diagnosis, illness severity, preferences, and ethnic diversity) [8,21,22].”
Self-citationKey components of shared decision making models: a systematic review
Bomhof-Roordink, H., Gärtner, F. R., Stiggelbout, A. M., & Pieterse, A. H. (2019) · BMJ Open · doi:10.1136/bmjopen-2019-031763 · Cited by 532
Diagnostic error and clinical reasoning
Norman, G. R., & Eva, K. W. (2010) · Medical Education · doi:10.1111/j.1365-2923.2009.03507.x · Cited by 498 · cited 1×
“Because clinical reasoning is case specific [6] and educationally opportune encounters with real patients are finite, education and research in this field require a scalable approach to emulating authentic patient-clinician interactions.”
Bower, J. L., & Christensen, C. M. (1996) · Journal of Product Innovation Management · doi:10.1016/0737-6782(96)81091-5 · Cited by 455
Diagnostic Errors—The Next Frontier for Patient Safety
Newman-Toker, D. E. (2009) · JAMA · doi:10.1001/jama.2009.249 · Cited by 433 · cited 1×
“As we seek to prevent errors in clinical practice [1,2] and promote high-value care [3,4], we need to better understand clinical reasoning and how to support its development and application [2,5].”
Biases in Large Language Models: Origins, Inventory, and Discussion
Navigli, R., Conia, S., & Ross, B. (2023) · Journal of Data and Information Quality · doi:10.1145/3597307 · Cited by 364 · cited 1×
“These groups can be defined by demographics such as gender, age, gender orientation, physical appearance, disability, nationality, ethnicity, race, socioeconomic status, religion, and culture [64].”
Owens, D. K., Qaseem, A., Chou, R., Shekelle, P., & for the Clinical Guidelines Committee of the American College of Physicians* (2011) · Annals of Internal Medicine · doi:10.7326/0003-4819-154-3-201102010-00007 · Cited by 329
Howcroft, D. M., Belz, A., Clinciu, M., Gkatzia, D., Hasan, S. A., Mahamood, S., Mille, S., van Miltenburg, E., Santhanam, S., & Rieser, V. (2020) · International Conference on Natural Language Generation · doi:10.18653/v1/2020.inlg-1.23 · Cited by 319 · cited 1×
“To generate items to rate dialogue authenticity, we drew on the literature on dialogue systems and natural language generation [41-51] from which we distilled 5 repeatedly emphasized constructs: responses are humanlike (ie, sensible, natural, and avoiding bias), coherent (ie, contextually…”
Five sources of bias in natural language processing
Hovy, D., & Prabhumoye, S. (2021) · Language and Linguistics Compass · doi:10.1111/lnc3.12432 · Cited by 298 · cited 1×
“Bias can arise from the input (ie, training) data, annotation process, input representations, models, or research design [63], resulting in harms of stereotyping, disparagement, dehumanization, erasure, and inequitable performance [62] to nondominant groups.”
All That’s ‘Human’ Is Not Gold: Evaluating Human Evaluation of Generated Text
Clark, E., August, T., Serrano, S., Haduong, N., Gururangan, S., & Smith, N. A. (2021) · Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers) · doi:10.18653/v1/2021.acl-long.565 · Cited by 290 · cited 1×
“We considered but omitted a domain for fluency because recent literature suggests that fluency can be presumed for contemporary AI models [42,44,46].”
All That's 'Human' Is Not Gold: Evaluating Human Evaluation of Generated Text
Clark, E., August, T., Serrano, S., Haduong, N., Gururangan, S., & Smith, N. A. (2021) · arXiv · doi:10.48550/arxiv.2107.00061 · Cited by 290 · cited 1×
“We considered but omitted a domain for fluency because recent literature suggests that fluency can be presumed for contemporary AI models [42,44,46].”
Virtual Patient Simulation at U.S. and Canadian Medical Schools
Huang, G., Reynolds, R., & Candler, C. (2007) · Academic Medicine · doi:10.1097/acm.0b013e31803e8a0a · Cited by 233
Survey on evaluation methods for dialogue systems
Deriu, J., Rodrigo, A., Otegi, A., Echegoyen, G., Rosset, S., Agirre, E., & Cieliebak, M. (2021) · Artificial Intelligence Review · doi:10.1007/s10462-020-09866-x · Cited by 215
Contextual Errors and Failures in Individualizing Patient Care
Weiner, S. J., Schwartz, A., Weaver, F., Goldberg, J., Yudkowsky, R., Sharma, G., Binns-Calvey, A., Preyss, B., M. Schapira, M., Persell, S. D., et al. (2010) · Annals of Internal Medicine · doi:10.7326/0003-4819-153-2-201007200-00002 · Cited by 214
Providing High-Value, Cost-Conscious Care: A Critical Seventh General Competency for Physicians
Weinberger, S. E. (2011) · Annals of Internal Medicine · doi:10.7326/0003-4819-155-6-201109200-00007 · Cited by 212 · cited 1×
“As we seek to prevent errors in clinical practice [1,2] and promote high-value care [3,4], we need to better understand clinical reasoning and how to support its development and application [2,5].”
Patient-Centered Decision Making and Health Care Outcomes: An Observational Study
Weiner, S. J., Schwartz, A., Sharma, G., Binns-Calvey, A., Ashley, N., Kelly, B., Dayal, A., Patel, S., Weaver, F. M., & Harris, I. (2013) · Annals of Internal Medicine · doi:10.7326/0003-4819-158-8-201304160-00001 · Cited by 212
Best practices for the human evaluation of automatically generated text
van der Lee, C., Gatt, A., van Miltenburg, E., Wubben, S., & Krahmer, E. (2019) · Proceedings of the 12th International Conference on Natural Language Generation · doi:10.18653/v1/w19-8643 · Cited by 205
Management Reasoning: Beyond the Diagnosis
Cook, D. A., Sherbino, J., & Durning, S. J. (2018) · JAMA · doi:10.1001/jama.2018.4385 · Cited by 170
Self-citationFeedback and the mini clinical evaluation exercise
Holmboe, E. S., Yepes, M., Williams, F., & Huot, S. J. (2004) · Journal of General Internal Medicine · doi:10.1111/j.1525-1497.2004.30134.x · Cited by 168
A Comprehensive Assessment of Dialog Evaluation Metrics
Yeh, Y.-T., Eskénazi, M., & Mehri, S. (2021) · doi:10.18653/v1/2021.eancs-1.3 · Cited by 138
Contextual Errors in Medical Decision Making: Overlooked and Understudied
Weiner, S. J., & Schwartz, A. (2015) · Academic Medicine · doi:10.1097/acm.0000000000001017 · Cited by 113 · cited 2×
“Such permutations (ie, preferences, comorbidities, social determinants of health, and system constraints) will prove invaluable in training and assessing contextualized care [17-19].”
Exploring Patient Values in Medical Decision Making: A Qualitative Study
Lee, Y. K., Low, W. Y., & Ng, C. J. (2013) · PLoS ONE · doi:10.1371/journal.pone.0080051 · Cited by 111
Towards Unified Dialogue System Evaluation: A Comprehensive Analysis of Current Evaluation Protocols
Finch, S. E., & Choi, J. D. (2020) · Annual Meeting of the Special Interest Group on Discourse and Dialogue · doi:10.18653/v1/2020.sigdial-1.29 · Cited by 108
Peddle, M., Bearman, M., & Nestel, D. (2016) · Clinical Simulation in Nursing · doi:10.1016/j.ecns.2016.04.004 · Cited by 104 · cited 2×
“To generate items to rate user experience, we merged 2 conceptual frameworks for measuring authenticity in VPs—one emphasizing decision-making and cognitive strategies [52] and the other highlighting realism, empathy, and variability [22,53].”
Management Reasoning: Implications for Health Professions Educators and a Research Agenda
Cook, D. A., Durning, S. J., Sherbino, J., & Gruppen, L. D. (2019) · Academic Medicine · doi:10.1097/acm.0000000000002768 · Cited by 94 · cited 2×
“Such authenticity will facilitate training, assessment, and research on shared decision-making [13-16] and other management reasoning processes [11,12,20].”
Self-citationFernando, N., Cleland, J., McKenzie, H., & Cassar, K. (2007) · Medical Education · doi:10.1111/j.1365-2923.2007.02939.x · Cited by 87 · cited 2×
“This fills an important, long-recognized gap in clinical training [24-27].”
Using Machine Learning to Assess Physician Competence: A Systematic Review
DIAS, R. D., Gupta, A., & Yule, S. (2018) · Academic Medicine · doi:10.1097/acm.0000000000002414 · Cited by 85 · cited 1×
“Artificial intelligence (AI) has long been used to rate narrative text [33-37], but this typically requires supervised machine learning—using human-graded texts to train the AI system.”
The Quality of Written Feedback by Attendings of Internal Medicine Residents
Jackson, J. L., Kay, C., Jackson, W., & Frank, M. (2015) · Journal of General Internal Medicine · doi:10.1007/s11606-015-3237-2 · Cited by 74 · cited 2×
“To generate items to rate feedback, we integrated findings from focus group studies [24,28], published instruments [30,56,57], and other empirical and conceptual studies [29,58-61] and identified 4 recurrent constructs: evidence-based (ie, behavior-focused) observations; specific, actionable…”
Creating virtual patients using large language models: scalable, global, and low cost
Cook, D. A. (2025) · Medical Teacher · doi:10.1080/0142159x.2024.2376879 · Cited by 73 · cited 1×
“We used Python to create a text VP interface, as previously described [38], that accesses GPT through the OpenAI application programming interface (API).”
Self-citationAssessing the quality of supervisors’ completed clinical evaluation reports
Dudek, N. L., Marks, M. B., Wood, T. J., & Lee, A. C. (2008) · Medical Education · doi:10.1111/j.1365-2923.2008.03105.x · Cited by 71 · cited 3×
“To generate items to rate feedback, we integrated findings from focus group studies [24,28], published instruments [30,56,57], and other empirical and conceptual studies [29,58-61] and identified 4 recurrent constructs: evidence-based (ie, behavior-focused) observations; specific, actionable…”
Chan, T. M., Sebok‐Syer, S. S., Sampson, C. S., & Monteiro, S. (2020) · Teaching and Learning in Medicine · doi:10.1080/10401334.2019.1708365 · Cited by 70 · cited 2×
“To generate items to rate feedback, we integrated findings from focus group studies [24,28], published instruments [30,56,57], and other empirical and conceptual studies [29,58-61] and identified 4 recurrent constructs: evidence-based (ie, behavior-focused) observations; specific, actionable…”
Estándares para Pruebas Educativas y Psicológicas
(2018) · doi:10.2307/j.ctvr43hg2 · Cited by 70
Demystifying AI: Current State and Future Role in Medical Education Assessment
Turner, L., Hashimoto, D. A., Vasisht, S., & Schaye, V. (2024) · Academic Medicine · doi:10.1097/acm.0000000000005598 · Cited by 70
Hargraves, I. G., Fournier, A. K., Montori, V. M., & Bierman, A. S. (2020) · Patient Education and Counseling · doi:10.1016/j.pec.2020.06.022 · Cited by 63
Marcotte, L., Egan, R. G., Soleas, E., Dalgarno, N., Norris, M., & Smith, C. A. (2019) · Canadian Medical Education Journal · doi:10.36834/cmej.57323 · Cited by 53
Peddle, M., Bearman, M., McKenna, L., & Nestel, D. (2019) · Advances in Simulation · doi:10.1186/s41077-019-0088-7 · Cited by 49 · cited 1×
“To generate items to rate user experience, we merged 2 conceptual frameworks for measuring authenticity in VPs—one emphasizing decision-making and cognitive strategies [52] and the other highlighting realism, empathy, and variability [22,53].”
Spadafore, M., Yılmaz, Y., Rally, V., Chan, T. M., Russell, M., Thoma, B., Singh, S., Monteiro, S., Pardhan, A., Martin, L. J., et al. (2024) · Academic Medicine · doi:10.1097/acm.0000000000005634 · Cited by 46 · cited 1×
“…feedback, we integrated findings from focus group studies [24,28], published instruments [30,56,57], and other empirical and conceptual studies [29,58-61] and identified 4 recurrent constructs: evidence-based (ie, behavior-focused) observations; specific, actionable suggestions; observations…”
Fink, M. C., Reitmeier, V., Stadler, M. J., Siebeck, M., Fischer, F., & Fischer, M. R. (2020) · Journal of Medical Internet Research · doi:10.2196/21196 · Cited by 44 · cited 1×
“We added a third empirically derived framework for evaluating “presence” in virtual reality (ie, realness, involvement, and spatial “physical” presence) [54,55].”
TuringAdvice: A Generative and Dynamic Evaluation of Language Use
Zellers, R., Holtzman, A., Clark, E., Qin, L., Farhadi, A., & Choi, Y. (2021) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2021.naacl-main.386 · Cited by 41
Huwendiek, S., de Leng, B. A., Kononowicz, A. A., Kunzmann, R., Muijtjens, A. M. M., van der Vleuten, C. P. M., Hoffmann, G. F., Tönshoff, B., & Dolmans, D. H. J. M. (2014) · Medical Teacher · doi:10.3109/0142159x.2014.970622 · Cited by 40 · cited 1×
“To generate items to rate user experience, we merged 2 conceptual frameworks for measuring authenticity in VPs—one emphasizing decision-making and cognitive strategies [52] and the other highlighting realism, empathy, and variability [22,53].”
Management Reasoning: Empirical Determination of Key Features and a Conceptual Model
Cook, D. A., Stephenson, C. R., Gruppen, L. D., & Durning, S. J. (2022) · Academic Medicine · doi:10.1097/acm.0000000000004810 · Cited by 40 · cited 2×
“Such authenticity will facilitate training, assessment, and research on shared decision-making [13-16] and other management reasoning processes [11,12,20].”
Self-citationSmith, E., Hsu, O., Qian, R., Roller, S., Boureau, Y.-L., & Weston, J. (2022) · Proceedings of the 4th Workshop on NLP for Conversational AI · doi:10.18653/v1/2022.nlp4convai-1.8 · Cited by 40
Exploring how feedback reflects entrustment decisions using artificial intelligence
Gin, B. C., ten Cate, O., O'Sullivan, P. S., Hauer, K. E., & Boscardin, C. (2022) · Medical Education · doi:10.1111/medu.14696 · Cited by 37
On Measures of Biases and Harms in NLP
Dev, S., Sheng, E., Zhao, J., Amstutz, A., Sun, J., Hou, Y., Sanseverino, M., Kim, J., Nishi, A., Peng, N., et al. (2022) · Findings of the Association for Computational Linguistics: AACL-IJCNLP 2022 · doi:10.18653/v1/2022.findings-aacl.24 · Cited by 32 · cited 2×
“Bias—“skew that produces a type of harm toward different social groups” [62]—is a well-known risk in AI generally and natural language generation specifically [62-65].”
Automatic scoring of medical students’ clinical notes to monitor learning in the workplace
Spickard, A., Ridinger, H. A., Wrenn, J. O., O’brien, N., Shpigel, A., Wolf, M. S., Stein, G., & Denny, J. C. (2013) · Medical Teacher · doi:10.3109/0142159x.2013.849801 · Cited by 30
Machine Scoring of Medical Students’ Written Clinical Reasoning: Initial Validity Evidence
Cianciolo, A. T., LaVoie, N., & Parker, J. (2021) · Academic Medicine · doi:10.1097/acm.0000000000004010 · Cited by 28
Clement, E., Oswald, A., Ghosh, S., & Hamza, D. M. (2024) · Journal of Graduate Medical Education · doi:10.4300/jgme-d-23-00210.1 · Cited by 26 · cited 1×
“To generate items to rate feedback, we integrated findings from focus group studies [24,28], published instruments [30,56,57], and other empirical and conceptual studies [29,58-61] and identified 4 recurrent constructs: evidence-based (ie, behavior-focused) observations; specific, actionable…”
Marcotte, L., Egan, R. G., Soleas, E., Dalgarno, N., Norris, M., & Smith, C. (2019) · PubMed Central · Cited by 23
Automated Patient Note Grading: Examining Scoring Reliability and Feasibility
Bond, W. F., Zhou, J., Bhat, S., Park, Y. S., Ebert-Allen, R. A., Ruger, R. L., & Yudkowsky, R. (2023) · Academic Medicine · doi:10.1097/acm.0000000000005357 · Cited by 19 · cited 1×
“Artificial intelligence (AI) has long been used to rate narrative text [33-37], but this typically requires supervised machine learning—using human-graded texts to train the AI system.”
Beyond “Read More”: An Intervention to Improve Faculty Written Feedback to Learners
Zelenski, A. B., Tischendorf, J. S., Kessler, M. A., Saunders, S., MacDonald, M. M., Vogelman, B., & Zakowski, L. J. (2019) · Journal of Graduate Medical Education · doi:10.4300/jgme-d-19-00058.1 · Cited by 15 · cited 1×
“…feedback, we integrated findings from focus group studies [24,28], published instruments [30,56,57], and other empirical and conceptual studies [29,58-61] and identified 4 recurrent constructs: evidence-based (ie, behavior-focused) observations; specific, actionable suggestions; observations…”
Cook, D. A., Hargraves, I. G., Stephenson, C. R., & Durning, S. J. (2023) · Medical Teacher · doi:10.1080/0142159x.2023.2170776 · Cited by 15 · cited 2×
“Such authenticity will facilitate training, assessment, and research on shared decision-making [13-16] and other management reasoning processes [11,12,20].”
Self-citationThe McMaster Narrative Comment Rating Tool: Development and Initial Validity Evidence
McGuire, A., Acai, A., & Sonnadara, R. (2023) · Teaching and Learning in Medicine · doi:10.1080/10401334.2023.2276799 · Cited by 9 · cited 1×
“To generate items to rate feedback, we integrated findings from focus group studies [24,28], published instruments [30,56,57], and other empirical and conceptual studies [29,58-61] and identified 4 recurrent constructs: evidence-based (ie, behavior-focused) observations; specific, actionable…”
Van Ostaeyen, S., Embo, M., Rotsaert, T., De Clercq, O., Schellens, T., & Valcke, M. (2023) · Perspectives on Medical Education · doi:10.5334/pme.1050 · Cited by 6
Research works printed but not linked: 3
- Tong, Y, 2014, The standards for educational and psychological testing, 11
- Roller, S, arXiv, 2006.12442 · arXiv
- Adiwardana, D, arXiv
Cited by
Zeng, J., Qi, W., Shen, S., Liu, X., Li, S., Wang, B., Dong, C., Zhu, X., Shi, Y., Lou, X., et al. (2025) · Journal of Medical Internet Research · doi:10.2196/79091 · Cited by 76
“Among studies using ChatGPT, only 2 mentioned setting the “temperature” hyperparameter [49,51], with one of them exploring whether the temperature affects LLM-based virtual patients’performance.”
InfluentialA large language model digital patient system enhances ophthalmology history taking skills
Luo, M.-J., Bi, S., Pang, J., Liu, L., Tsui, C.-K., Lai, Y., Chen, W., Yang, Y., Xu, K., Zhao, L., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01841-6 · Cited by 39
Gin, B. C., LaForge, K., Burk-Rafel, J., & Boscardin, C. K. (2025) · Academic Medicine · doi:10.1097/acm.0000000000006117 · Cited by 36
Li, D., & Lutfi, S. L. (2025) · JMIR Medical Informatics · doi:10.2196/79039 · Cited by 45
The feasibility of using generative artificial intelligence for history taking in virtual patients
Yi, Y., & Kim, K.-J. (2025) · BMC Research Notes · doi:10.1186/s13104-025-07157-8 · Cited by 28
“In particular, further studies are warranted to inform the effective use of prompts and behavioral components of the chatbot that optimizes its performance across various clinical contexts [8, 9, 10].”
Metadata
- Authors
- Cook, D. A., Overgaard, J., Pankratz, V. S., Del Fiol, G., & Aakre, C. A.
- Affiliations
- Mayo Clinic (US)
- University of New Mexico (US)
- Corresponding author
- Cook, David A
- Venue
- Journal of Medical Internet Research
- Publisher
- JMIR Publications Inc.
- Published
- 2025-04-04
- Volume
- 27
- Pages
- e68486
- ISSN
- 1438-8871 (ISSN-L)
- PMC
- PMC12008702
- OpenAlex
- W4406327404
- Cited by
- 96
- References
- 65
- Citations by year
- 2026: 72 · 2025: 24
- FWCI
- 23.11
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- cc-by
- Locations
- Journal of Medical Internet Research (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- Edinburgh Napier University
- Gentofte Hospital
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Social Sciences › Education › Simulation-Based Education in Healthcare
- Social Sciences › Education › Innovations in Medical Education
- Keywords
- virtual patients, large language models, GPT, personalized feedback, patient preferences, GPT-3.5-turbo, diabetes management, simulation scalability, user experience, prompt engineering
- MeSH terms
- Large Language Models, Communication, Diabetes Mellitus, Feedback, Humans, Language, Physician-Patient Relations, User-Computer Interface, Patient Simulation, Patient Preference
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
