

The DOI matches its DataCite record; 57 of the 59 references it cites were found in a registry or an index, and 2 are not checked yet.
Large Language Models Can Self-Improve
Open accessAbstract
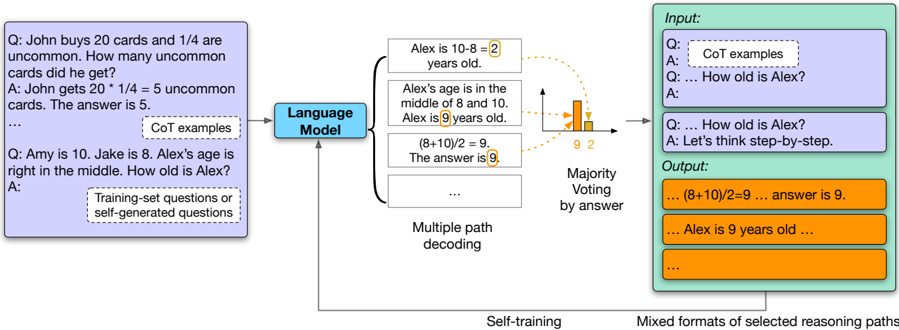
Large Language Models (LLMs) have achieved excellent performances in various tasks. However, fine-tuning an LLM requires extensive supervision. Human, on the other hand, may improve their reasoning abilities by self-thinking without external inputs. In this work, we demonstrate that an LLM is also capable of self-improving with only unlabeled datasets. We use a pre-trained LLM to generate "high-confidence" rationale-augmented answers for unlabeled questions using Chain-of-Thought prompting and self-consistency, and fine-tune the LLM using those self-generated solutions as target outputs. We show that our approach improves the general reasoning ability of a 540B-parameter LLM (74.4%->82.1% on GSM8K, 78.2%->83.0% on DROP, 90.0%->94.4% on OpenBookQA, and 63.4%->67.9% on ANLI-A3) and achieves state-of-the-art-level performance, without any ground truth label. We conduct ablation studies and show that fine-tuning on reasoning is critical for self-improvement.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Researchers are starting to apply discrete optimization and RL to find effective prompts, generally for a single logical LM call (Guo et al., 2023; Pryzant et al., 2023; Huang et al., 2022; Yang et al., 2023).”
From DSPy: Compiling Declarative Language Model Calls into Self-Improving Pipelines (2023) · cites this paper as Huang et al., 2022
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Distilling the Knowledge in a Neural Network
Hinton, G., Vinyals, O., & Dean, J. (2015) · arXiv · doi:10.48550/arxiv.1503.02531 · Cited by 14,204
SQuAD: 100,000+ Questions for Machine Comprehension of Text
Rajpurkar, P., Zhang, J., Lopyrev, K., & Liang, P. (2016) · Proceedings of the 2016 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d16-1264 · Cited by 6,208
Chain-of-Thought Prompting Elicits Reasoning in Large Language Models
Wei, J., Wang, X., Schuurmans, D., Bosma, M., Ichter, B., Xia, F., Chi, E., Le, Q., & Zhou, D. (2022) · arXiv · doi:10.48550/arxiv.2201.11903 · Cited by 4,263
Self-citationGLUE: A Multi-Task Benchmark and Analysis Platform for Natural Language Understanding
Wang, A., Singh, A., Michael, J., Hill, F., Levy, O., & Bowman, S. (2018) · Proceedings of the 2018 EMNLP Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP · doi:10.18653/v1/w18-5446 · Cited by 4,222
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
A Broad-Coverage Challenge Corpus for Sentence Understanding through Inference
Williams, A., Nangia, N., & Bowman, S. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1101 · Cited by 3,342
PaLM: Scaling Language Modeling with Pathways
Chowdhery, A., Narang, S., Devlin, J., Bosma, M., Mishra, G., Roberts, A., Barham, P., Chung, H. W., Sutton, C., Gehrmann, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2204.02311 · Cited by 2,590
Self-citationSelf-Training With Noisy Student Improves ImageNet Classification
Xie, Q., Luong, M.-T., Hovy, E., & Le, Q. V. (2020) · 2020 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr42600.2020.01070 · Cited by 2,393
Large language models are zero-shot reasoners
Kojima, T., Gu, S. (., Reid, M., Matsuo, Y., & Iwasawa, Y. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1613 · Cited by 2,013
Self-citation
Research works printed but not linked: 7
- Xiaokang Chen, Yuhui Yuan, Gang Zeng, and Jingdong Wang. 2021. Semi-supervised semantic segmenta- tion with cross pseudo supervision. In IEEE Confer- ence on Computer Vision and Pattern Recognition (CVPR).
- Anoop Korattikara Balan, Vivek Rathod, Kevin P Mur- phy, and Max Welling. 2015. Bayesian dark knowl- edge. Advances in neural information processing systems, 28.
- Aitor Lewkowycz, Anders Andreassen, David Dohan, Ethan Dyer, Henryk Michalewski, Vinay Venkatesh Ramasesh, Ambrose Slone, Cem Anil, Imanol Schlag, Theo Gutman-Solo, Yuhuai Wu, Behnam Neyshabur, Guy Gur-Ari, and Vedant Misra. 2022. Solving quantitative reasoning problems with lan- guage models. ArXiv, abs/2206.14858. · arXiv
- Yifei Li, Zeqi Lin, Shizhuo Zhang, Qiang Fu, Bei Chen, Jian-Guang Lou, and Weizhu Chen. 2022b. On the advance of making language models better reasoners. ArXiv, abs/2206.02336. · arXiv
- Wang Ling, Dani Yogatama, Chris Dyer, and Phil Blun- som. 2017b. Program induction by rationale gener- ation: Learning to solve and explain algebraic word problems. In ACL.
- Timo Schick and Hinrich Schütze. 2020a. Exploiting cloze-questions for few-shot text classification and natural language inference. In Conference of the Eu- ropean Chapter of the Association for Computational Linguistics.
- Jason Wei, Yi Tay, Rishi Bommasani, Colin Raffel, Barret Zoph, Sebastian Borgeaud, Dani Yogatama, Maarten Bosma, Denny Zhou, Donald Metzler, et al. 2022b. Emergent abilities of large language models. arXiv preprint arXiv:2206.07682. · arXiv
Cited by
Sorted by citations
Large language models in medicine
Thirunavukarasu, A. J., Ting, D. S. J., Elangovan, K., Gutierrez, L., Tan, T. F., & Ting, D. S. W. (2023) · Nature Medicine · doi:10.1038/s41591-023-02448-8 · Cited by 3,944
Self-Instruct: Aligning Language Models with Self-Generated Instructions
Wang, Y., Kordi, Y., Mishra, S., Liu, A., Smith, N. A., Khashabi, D., & Hajishirzi, H. (2023) · Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2023.acl-long.754 · Cited by 1,243
Unleashing the potential of prompt engineering for large language models
CHEN, B. ‐., Zhang, Z., Langrené, N., & Zhu, S. (2025) · Patterns · doi:10.1016/j.patter.2025.101260 · Cited by 1,097
Towards Reasoning in Large Language Models: A Survey
Huang, J., & Chang, K. C.-C. (2023) · Findings of the Association for Computational Linguistics: ACL 2023 · doi:10.18653/v1/2023.findings-acl.67 · Cited by 428
Self-citationBai, Y., Kadavath, S., Kundu, S., Askell, A., Kernion, J., Jones, A., Chen, A., Goldie, A., Mirhoseini, A., & Kaplan, J. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2212.08073 · Cited by 326
“Some other recent works on self-supervision include [Shi et al., 2022, Huang et al., 2022].”
Background
Metadata
- Authors
- Huang, J., Gu, S. S., Hou, L., Wu, Y., Wang, X., Yu, H., & Han, J.
- Affiliations
- University of Illinois Urbana-Champaign (US)
- Google (United States) (US)
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2022
- Pages
- 1051-1068
- arXiv
- 2210.11610
- OpenAlex
- W4389523706
- Cited by
- 230
- References
- 59
- Citations by year
- 2026: 36 · 2025: 77 · 2024: 63 · 2023: 53 · 2022: 1
- FWCI
- 40.57
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- large language models, human development, self-supervised fine-tuning, unlabeled data, chain-of-thought prompting, self-consistency, reasoning skills, low-resource languages, Arecaceae, GSM8K, OpenBookQA
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
