

The DOI matches its Crossref record; 47 of the 47 references it cites were found in a registry or an index; none of the 39 sources its claims cite is checked for support yet.
Challenges of developing a digital scribe to reduce clinical documentation burden
Open accessAbstract
Clinicians spend a large amount of time on clinical documentation of patient encounters, often impacting quality of care and clinician satisfaction, and causing physician burnout. Advances in artificial intelligence (AI) and machine learning (ML) open the possibility of automating clinical documentation with digital scribes, using speech recognition to eliminate manual documentation by clinicians or medical scribes. However, developing a digital scribe is fraught with problems due to the complex nature of clinical environments and clinical conversations. This paper identifies and discusses major challenges associated with developing automated speech-based documentation in clinical settings: recording high-quality audio, converting audio to transcripts using speech recognition, inducing topic structure from conversation data, extracting medical concepts, generating clinically meaningful summaries of conversations, and obtaining clinical data for AI and ML algorithms.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
This perspective paper identifies and discusses the major technical and data-related challenges to developing a "digital scribe" that automatically documents clinician–patient conversations using speech recognition and NLP. It argues that progress is best achieved by solving each pipeline challenge individually rather than pursuing a holistic solution.
Key findings
The paper is a challenge-identification piece rather than an empirical study, so it reports no primary outcomes of its own; its claims are framed around cited evidence and the authors' analysis.
- A cited study found word error rates of 35% or higher for simulated medical conversations using commercial ASR engines, and the authors note these were best-case results from controlled, near-ideal acoustic conditions.
- The authors enumerate challenges across five pipeline stages: audio recording/ASR, topic structuring, medical concept extraction, summarization, and data collection (summarized in Table 1).
- Existing tools such as MetaMap and cTAKES map text to UMLS concepts but were designed for written text; with default settings, "I am feeling fine" maps "I" to "blood group antibody I," "feeling" to "emotions," and "fine" to "qualitative concept" or "legal fine."
- One cited effort developed its own corpus of 3000 conversations annotated by medical scribes because no public corpus was available, described as a costly investment.
Methods
This is a conceptual/perspective review, not an empirical study; it identifies and discusses challenges via narrative synthesis of prior literature and a summary table (Table 1) mapping tasks to challenges. No dataset, sample, or statistical analysis is reported. The paper draws on cited prior work (e.g., ASR engine comparisons, diarization research, UMLS mapping tools) to illustrate each challenge.
Limitations
The paper does not present a formal limitations section; as a perspective piece it offers no empirical validation of the challenges it describes. The text makes evident that the challenges are largely illustrated through cited studies and hypothetical examples rather than systematic evidence, and the authors note that evaluation of digital scribes in clinical environments (quality of care, patient satisfaction, clinician efficiency, documentation time, organizational dynamics) remains to be conducted. The authors also state that collecting sufficient data at the scale needed for AI/ML could alone take years, and that the closed data-sharing environment slows progress.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
22 Not checked yet · 16 Own interpretation · 2 No basis given
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“However, UMLS was designed for written text, not for spoken medical conversations.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 3: information extraction in clinical conversations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“ASR produces a transcript of the clinician–patient conversation that lacks clear boundaries and structure due to the unconstrained nature of conversations.22”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 2: structuring clinician–patient conversations
What the sources say
- Not checked yetcites [22] Lacson, R. C., Barzilay, R. & Long, W. J. Automatic analysis of medical dialogue in the home hemodialysis domain: structure induction and summarization. J. Biomed. Inform. 39, 541–555 (2006). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“Spontaneous, conversational speech is not linguistically well-formed.21”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 1: audio recording and speech recognition
What the sources say
- Not checked yetcites [21] Xiong, W. et al. Toward human parity in conversational speech recognition. IEEE/ACM Trans. Audio Speech Lang. Proc. 25, 2410–2423 (2017). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“A recent study found that the word error rate of simulated medical conversations with commercial ASR engines was 35% or higher.17”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 1: audio recording and speech recognition
What the sources say
- Not checked yetcites [17] Kodish-Wachs, J., Agassi, E., Kenny, P. & Overhage, J. M. A systematic comparison of contemporary automatic speech recognition engines for conversational clinical speech. AMIA Annu. Symp. Proc. 2018, 683–689 (2018).
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“Tools like MetaMap must also have their parameters tuned, as using them with default settings may result in the extraction of irrelevant terms.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 3: information extraction in clinical conversations
What the sources say
- Not checked yetcites [29] Reátegui, R. & Ratté, S. Comparison of MetaMap and cTAKES for entity extraction in clinical notes. BMC Med. Inform. Decis. Mak. 18, 74 (2018). source
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“The position of the recording device also has a strong impact on the captured audio.18,20”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 1: audio recording and speech recognition
What the sources say
- Not checked yetcites [18] Vogel, A. P. & Morgan, A. T. Factors affecting the quality of sound recording for speech and voice analysis. Int. J. Speech-Lang. Pathol. 11, 431–437 (2009). source
- Not checked yetcites [20] Shafey, L. E., Soltau, H. & Shafran, I. Joint speech recognition and speaker diarization via sequence transduction. In Interspeech 2019, 396–400 (International Speech Communication Association, 2019). source
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“Having multiple speakers participating in the conversation and differentiating them in the audio (speaker diarization) also adds a level of complexity and potential errors to ASR.7”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 1: audio recording and speech recognition
What the sources say
- Not checked yetcites [7] Finley, G. et al. An automated medical scribe for documenting clinical encounters. In Proc. 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Demonstrations, 11–15 (Association for Computational Linguistics, 2018). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“After conversion from speech to text, NLP techniques that perform well on grammatically correct sentences break down with conversational speech because of the lack of punctuation and sentence boundaries, grammatical differences between spoken and written language, and lack of structure.7,24,25”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 1: audio recording and speech recognition
What the sources say
- Not checked yetcites [7] Finley, G. et al. An automated medical scribe for documenting clinical encounters. In Proc. 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Demonstrations, 11–15 (Association for Computational Linguistics, 2018). source
- Not checked yetcites [24] Kahn, J. G., Lease, M., Charniak, E., Johnson, M. & Ostendorf, M. Effective use of prosody in parsing conversational speech. In Proc. Human Language Technology Conference and Conference on Empirical Methods in Natural Language Processing, 233–240 (Association for Computational Linguistics, 2005). source
- Not checked yetcites [25] Jamshid Lou, P., Wang, Y. & Johnson, M. Neural constituency parsing of speech transcripts. In Proc. 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Vol. 1 (Long and Short Papers), 2756–2765 (Association for Computational Linguistics, 2019). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“Research on machine comprehension of written passages cannot be directly transferred to spoken conversations due to common phenomena in spontaneous speech, such as zero anaphora (using an expression whose interpretation depends upon a prior expression), thinking aloud, and topic drift.14”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 3: information extraction in clinical conversations
What the sources say
- Not checked yetcites [14] Liu, Z. et al. Fast prototyping a dialogue comprehension system for nurse-patient conversations on symptom monitoring. In Proc. 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Vol. 2 (Industry Papers), 24–31 (Association for Computational Linguistics, 2019).
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Knowing the current topic or medical activity during a consultation reduces the complexity of information extraction and summarization.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 2: structuring clinician–patient conversations
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
In the paper
“The differences in (1) spoken vs. written language and (2) lay vs. expert terminology, cause inaccuracies and word mismatching when using existing tools for medical language processing from medical conversations.30”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 3: information extraction in clinical conversations
What the sources say
- Not checked yetcites [30] Lacson, R. & Barzilay, R. Automatic processing of spoken dialogue in the home hemodialysis domain. AMIA Annu. Symp. Proc. 2005, 420–424 (2005).
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“A recording made in a real clinical setting is likely to include noise and other environmental conditions that negatively affect ASR.18,19”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 1: audio recording and speech recognition
What the sources say
- Not checked yetcites [18] Vogel, A. P. & Morgan, A. T. Factors affecting the quality of sound recording for speech and voice analysis. Int. J. Speech-Lang. Pathol. 11, 431–437 (2009). source
- Not checked yetcites [19] Ram, A. et al. Conversational AI: the science behind the Alexa prize. Preprint at arXiv:1801.03604 [cs] (2018).
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Even with ideal recording equipment, ASR of conversational speech is more vulnerable to errors.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 1: audio recording and speech recognition
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“Even if unsupervised learning is used to generate a summary, not requiring labels for the training data,37,38 a set of gold standard summaries would still be needed to evaluate the quality of the summarization.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 4: conversation summarization
What the sources say
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This will be difficult to differentiate by an automatic summarization model, as it would require sophisticated natural language understanding.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 4: conversation summarization
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“Generating a medical summary from a clinician–patient conversation can be cast as a supervised learning task,32 where an ML algorithm is trained with a large set of past medical conversation transcripts along with the gold standard summary associated with each conversation.7,33”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 4: conversation summarization
What the sources say
- Not checked yetcites [32] LeCun, Y., Bengio, Y. & Hinton, G. Deep learning. Nature 521, 436–444 (2015). source
- Not checked yetcites [7] Finley, G. et al. An automated medical scribe for documenting clinical encounters. In Proc. 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Demonstrations, 11–15 (Association for Computational Linguistics, 2018). source
- Not checked yetcites [33] Liang, J. & Tsou, C.-H. A novel system for extractive clinical note summarization using EHR data. In Proc. 2nd Clinical Natural Language Processing Workshop, 46–54 (Association for Computational Linguistics, 2019). source
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“However, obtaining and sharing medical data presents a major obstacle due to privacy issues and the sensitive nature of the data.13,14,39”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 5: lack of clinical data
What the sources say
- Not checked yetcites [13] Du, N. et al. Extracting symptoms and their status from clinical conversations. In Proc. of the 57th Annual Meeting of the Association of Computational Linguistics, 915–925 (Association for Computational Linguistics, 2019). source
- Not checked yetcites [14] Liu, Z. et al. Fast prototyping a dialogue comprehension system for nurse-patient conversations on symptom monitoring. In Proc. 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Vol. 2 (Industry Papers), 24–31 (Association for Computational Linguistics, 2019).
- Not checked yetcites [39] Cios, K. J. & William Moore, G. Uniqueness of medical data mining. Artif. Intell. Med. 26, 1–24 (2002). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 17
- It may state two separate claims as one. 11
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
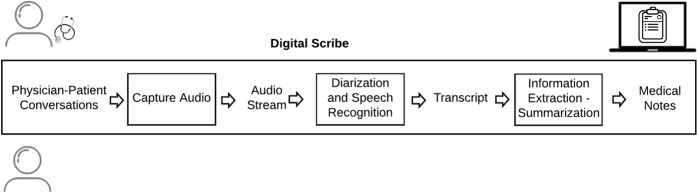
“To generate medical notes for the clinician–patient encounter, a digital scribe must be able to: (1) record the clinician–patient conversation, (2) convert the audio to text, and (3) extract salient information from the text and summarize the information (Fig. 1).”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Introduction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Recently, advances in AI, machine learning (ML), NLP, natural language understanding, and automatic speech recognition (ASR), have raised the prospect of deploying effective and reliable digital scribes in clinical practice.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Introduction
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“However, clinical encounters do not necessarily follow a linear order of their components,27,28 which exacerbates summarization or information extraction.22”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 2: structuring clinician–patient conversations
What the sources say
- Not checked yetcites [27] Waitzkin, H. A critical theory of medical discourse: ideology, social control, and the processing of social context in medical encounters. J. Health Soc. Behav. 30, 220–239 (1989). source
- Not checked yetcites [28] Kocaballi, A. B. et al. A network model of activities in primary care consultations. J. Am. Med. Inform. Assoc. 26, 1074–1082 (2019). source
- Not checked yetcites [22] Lacson, R. C., Barzilay, R. & Long, W. J. Automatic analysis of medical dialogue in the home hemodialysis domain: structure induction and summarization. J. Biomed. Inform. 39, 541–555 (2006). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Medical conversations have different statistical properties than medical dictations, meaning that ASR trained with dictations is likely to underperform with medical conversations.7”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 1: audio recording and speech recognition
What the sources say
- Not checked yetcites [7] Finley, G. et al. An automated medical scribe for documenting clinical encounters. In Proc. 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Demonstrations, 11–15 (Association for Computational Linguistics, 2018). source
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“High-quality audio minimizes errors across the processing pipeline of the digital scribe.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 1: audio recording and speech recognition
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“Clinical documentation is found to be associated with clinician burnout,1 increased cognitive load,2 information loss,3 and distractions.4”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Introduction
What the sources say
- Not checked yetcites [1] Friedberg, M. W. et al. Factors affecting physician professional satisfaction and their implications for patient care, health systems, and health policy. RAND Health Q. 3, 1 (2014).
- Not checked yetcites [2] Wachter, R. & Goldsmith, J. To combat physician burnout and improve care, fix the electronic health record. Harvard Bus. Rev. (2018) https://hbr.org/2018/03/to-combat-physician-burnout-and-improve-care-fix-the-electronic-health-record#comment-section.
- Not checked yetcites [3] Shachak, A., Hadas-Dayagi, M., Ziv, A. & Reis, S. Primary care physicians’ use of an electronic medical record system: a cognitive task analysis. J. Gen. Intern. Med. 24, 341–348 (2009). source
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, developing a digital scribe is fraught with problems due to the complex nature of clinical environments and clinical conversations.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Abstract
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Any digital scribe solution that requires ongoing input and supervision throughout the consultation will (1) distract clinicians from patients and (2) replace the distractions and disruptions of using an EHR with those of a digital scribe.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Discussion: clinical practice implications
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“To generate effective medical notes, the summarization may need to draw on medical knowledge and capture nonverbal information during a consultation.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 4: conversation summarization
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. It may state two separate claims as one.
In the paper
“The main concern raised is that manual documentation allows clinicians to structure their thoughts, think critically, reflect, and practice medicine effectively, such that removing it would adversely affect the way clinicians practice medicine.9”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Discussion: clinical practice implications
What the sources say
- Not checked yetcites [9] Willis, M. & Jarrahi, M. H. Automating documentation: a critical perspective into the role of artificial intelligence in clinical documentation. In Information in Contemporary Society (eds Taylor, N. G., Christian-Lamb, C., Martin, M. H. & Nardi, B.) 200–209 (Springer International Publishing, 2019). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“In general, digital scribe research is hindered by (1) limited well-annotated large-scale data for modeling human–human spoken dialogs and (2) even scarcer conversation data in healthcare due to privacy issues.14”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 5: lack of clinical data
What the sources say
- Not checked yetcites [14] Liu, Z. et al. Fast prototyping a dialogue comprehension system for nurse-patient conversations on symptom monitoring. In Proc. 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Vol. 2 (Industry Papers), 24–31 (Association for Computational Linguistics, 2019).
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“However, obtaining the gold standard summary of each conversation is costly because of the medical expertize required to complete the task14 and the high variability in clinician notes’ content, style, organization, and quality.36”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 4: conversation summarization
What the sources say
- Not checked yetcites [14] Liu, Z. et al. Fast prototyping a dialogue comprehension system for nurse-patient conversations on symptom monitoring. In Proc. 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Vol. 2 (Industry Papers), 24–31 (Association for Computational Linguistics, 2019).
- Not checked yetcites [36] Edwards, S. T., Neri, P. M., Volk, L. A., Schiff, G. D. & Bates, D. W. Association of note quality and quality of care: a cross-sectional study. BMJ Qual. Saf. 23, 406–413 (2014). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A dataset of medical conversations along with the corresponding summaries would allow far-reaching advances in the digital scribe and clinical documentation space.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 5: lack of clinical data
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
None of the sources cited for this claim have been checked yet.
In the paper
“In addition, conversations do not fit a command-like structure, which makes it difficult to perform intent recognition—identifying a user’s intent from an utterance31—and to apply NLP techniques.19”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 3: information extraction in clinical conversations
What the sources say
- Not checked yetcites [31] Bhargava, A., Celikyilmaz, A., Hakkani-Tur, D. & Sarikaya, R. Easy contextual intent prediction and slot detection. In 2013 IEEE International Conference on Acoustics, Speech and Signal Processing, 8337–8341 (IEEE, 2013). source
- Not checked yetcites [19] Ram, A. et al. Conversational AI: the science behind the Alexa prize. Preprint at arXiv:1801.03604 [cs] (2018).
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The currently closed environment for sharing sensitive data means that the few research teams with access to data are the only ones that can make advances, further slowing progress by impeding open science.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Conclusion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds. It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“Rather than replacement of clinicians as depicted in many dystopic AI futures, the goal of digital scribes is the formation of a “human–AI symbiosis” that augments the clinician–patient experience and improves quality of care.6,8,9”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Discussion: clinical practice implications
What the sources say
- Not checked yetcites [6] Lin, S. Y., Shanafelt, T. D. & Asch, S. M. Reimagining clinical documentation with artificial intelligence. Mayo Clin. Proc. 93, 563–565 (2018). source
- Not checked yetcites [8] Coiera, E., Kocaballi, B., Halamka, J. & Laranjo, L. The digital scribe. npj Digit. Med. 1, 58 (2018). source
- Not checked yetcites [9] Willis, M. & Jarrahi, M. H. Automating documentation: a critical perspective into the role of artificial intelligence in clinical documentation. In Information in Contemporary Society (eds Taylor, N. G., Christian-Lamb, C., Martin, M. H. & Nardi, B.) 200–209 (Springer International Publishing, 2019). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Due to the complexity of each task, we posit that research may reap the greatest benefits by focusing on solving the challenges individually, as opposed to seeking to build a holistic solution.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Conclusion
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As a result, rich and accurate clinical data has become one of the most valuable intellectual property assets for industry and academia.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 5: lack of clinical data
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Nevertheless, clinicians will only be convinced of embracing digital scribes if they believe that any reviewing and revising of summaries will be less time consuming than writing a summary from scratch.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 4: conversation summarization
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
In the paper
“Current advocates of replacing the entire documentation process with AI also tend to overlook the complexities of healthcare sociotechnical systems.9”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Discussion: clinical practice implications
What the sources say
- Not checked yetcites [9] Willis, M. & Jarrahi, M. H. Automating documentation: a critical perspective into the role of artificial intelligence in clinical documentation. In Information in Contemporary Society (eds Taylor, N. G., Christian-Lamb, C., Martin, M. H. & Nardi, B.) 200–209 (Springer International Publishing, 2019). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In particular, conversational clinical data, transcripts, and summaries are needed to apply the recent advances in ML and AI to digital scribe development.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Conclusion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Collecting sufficient data at the scale needed for AI and ML algorithms could alone take years to complete.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Conclusion
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“During a clinical encounter, it is common for a clinician to change their assessments or revise some observations.”
§ Challenges of developing a digital scribe to reduce clinical documentation burden > Challenge 4: conversation summarization
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Unfortunately as clinic encounter conversations are not routinely recorded and are difficult to ethically share due to patient confidentiality, there are no sufficiently large clinic dialogue-note datasets to benchmark this task.”
From Aci-bench: a Novel Ambient Clinical Intelligence Dataset for Benchmarking Automatic Visit Note Generation (2023) · cites this paper as [12]
Citations
Cites
LeCun, Y., Bengio, Y., & Hinton, G. (2015) · Nature · doi:10.1038/nature14539 · Cited by 84,126
Sudlow, C., Gallacher, J., Allen, N., Beral, V., Burton, P., Danesh, J., Downey, P., Elliott, P., Green, J., Landray, M., et al. (2015) · PLOS Medicine · doi:10.1371/journal.pmed.1001779 · Cited by 12,728
MIMIC-III, a freely accessible critical care database
Johnson, A. E. W., Pollard, T. J., Shen, L., Lehman, L.-W. H., Feng, M., Ghassemi, M., Moody, B., Szolovits, P., Anthony Celi, L., & Mark, R. G. (2016) · Scientific Data · doi:10.1038/sdata.2016.35 · Cited by 8,141
A guide to deep learning in healthcare
Esteva, A., Robicquet, A., Ramsundar, B., Kuleshov, V., DePristo, M., Chou, K., Cui, C., Corrado, G., Thrun, S., & Dean, J. (2019) · Nature Medicine · doi:10.1038/s41591-018-0316-z · Cited by 5,312
Artificial intelligence in healthcare
Yu, K.-H., Beam, A. L., & Kohane, I. S. (2018) · Nature Biomedical Engineering · doi:10.1038/s41551-018-0305-z · Cited by 2,817
Deep Learning for Health Informatics
Ravì, D., Wong, C., Deligianni, F., Berthelot, M., Andreu-Perez, J., Lo, B., & Yang, G.-Z. (2017) · IEEE Journal of Biomedical and Health Informatics · doi:10.1109/jbhi.2016.2636665 · Cited by 2,000
Serving the enterprise and beyond with informatics for integrating biology and the bedside (i2b2)
Murphy, S. N., Weber, G. M., Mendis, M., Gainer, V. S., Chueh, H. C., Churchill, S. E., & Kohane, I. S. (2010) · Journal of the American Medical Informatics Association · doi:10.1136/jamia.2009.000893 · Cited by 926
Types of Unintended Consequences Related to Computerized Provider Order Entry
Campbell, E. M., Sittig, D. F., Ash, J. S., Guappone, K. P., & Dykstra, R. H. (2006) · Journal of the American Medical Informatics Association · doi:10.1197/jamia.m2042 · Cited by 823
Recent automatic text summarization techniques: a survey
Gambhir, M., & Gupta, V. (2016) · Artificial Intelligence Review · doi:10.1007/s10462-016-9475-9 · Cited by 769
Friedberg, M., Chen, P., Van Busum, K., Aunon, F., Pham, C., Caloyeras, J., Mattke, S., Pitchforth, E., Quigley, D., Brook, R., et al. (2014) · RAND Health Quarterly · doi:10.7249/rhq-03-04-01 · Cited by 707
Cited by
Sorted by citations
Perceptions and Needs of Artificial Intelligence in Health Care to Increase Adoption: Scoping Review
Chew, H. S. J., & Achananuparp, P. (2022) · Journal of Medical Internet Research · doi:10.2196/32939 · Cited by 243
The impact of nuance DAX ambient listening AI documentation: a cohort study.
Haberle, T., Cleveland, C., Snow, G. L., Barber, C., Stookey, N., Thornock, C., Younger, L., Mullahkhel, B., & Ize-Ludlow, D. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae022 · Cited by 171
The digital scribe in clinical practice: a scoping review and research agenda
van Buchem, M. M., Boosman, H., Bauer, M. P., Kant, I. M. J., Cammel, S. A., & Steyerberg, E. W. (2021) · npj Digital Medicine · doi:10.1038/s41746-021-00432-5 · Cited by 152
Pavuluri, S., Sangal, R., Sather, J., & Taylor, R. A. (2024) · BMJ Health & Care Informatics · doi:10.1136/bmjhci-2024-101120 · Cited by 129
Thomas Craig, K. J., Willis, V. C., Gruen, D., Rhee, K., & Jackson, G. P. (2021) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocaa301 · Cited by 123
Metadata
- Authors
- Quiroz, J. C., Laranjo, L., Kocaballi, A. B., Berkovsky, S., Rezazadegan, D., & Coiera, E.
- Affiliations
- Macquarie University (AU)
- Corresponding author
- Quiroz, Juan C.
- ORCID
- Venue
- npj Digital Medicine
- Published
- 2019-11-22
- Volume
- 2
- Issue
- 1
- Pages
- 114-114
- ISSN
- 2398-6352 (ISSN-L)
- PMC
- PMC6874666
- OpenAlex
- W2989925457
- Semantic Scholar
- bfcfdf78801e224e88016c04e973130e5944ee8f
- Cited by
- 162
- References
- 47
- Citations by year
- 2026: 26 · 2025: 37 · 2024: 26 · 2023: 24 · 2022: 18 · 2021: 16 · 2020: 12 · 2019: 1
- FWCI
- 2.21
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- npj Digital Medicine (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion)
- UTS ePRESS (University of Technology Sydney) (submittedVersion, other-oa)
- Swinburne figshare (Swinburne University of Technology) (submittedVersion, cc-by)
- Funders
- Department of Health | National Health and Medical Research Council (APP1134919)
- Topics
- Health Sciences › Health Professions › Health Information Management › Electronic Health Records Systems
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Nursing › Research and Theory › Nursing Diagnosis and Documentation
- Keywords
- clinical documentation burden, speech recognition, medical scribes, speech-to-text, topic modeling, medical concept extraction, physician burnout
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-06, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-06 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
