

The DOI matches its Crossref record; 134 of the 143 references it cites were found in a registry or an index; 1 of the 58 sources its claims cite were checked for support.
Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI
Open accessAbstract
Generative Artificial Intelligence is set to revolutionize healthcare delivery by transforming traditional patient care into a more personalized, efficient, and proactive process. Chatbots, serving as interactive conversational models, will probably drive this patient-centered transformation in healthcare. Through the provision of various services, including diagnosis, personalized lifestyle recommendations, dynamic scheduling of follow-ups, and mental health support, the objective is to substantially augment patient health outcomes, all the while mitigating the workload burden on healthcare providers. The life-critical nature of healthcare applications necessitates establishing a unified and comprehensive set of evaluation metrics for conversational models. Existing evaluation metrics proposed for various generic large language models (LLMs) demonstrate a lack of comprehension regarding medical and health concepts and their significance in promoting patients’ well-being. Moreover, these metrics neglect pivotal user-centered aspects, including trust-building, ethics, personalization, empathy, user comprehension, and emotional support. The purpose of this paper is to explore state-of-the-art LLM-based evaluation metrics that are specifically applicable to the assessment of interactive conversational models in healthcare. Subsequently, we present a comprehensive set of evaluation metrics designed to thoroughly assess the performance of healthcare chatbots from an end-user perspective. These metrics encompass an evaluation of language processing abilities, impact on real-world clinical tasks, and effectiveness in user-interactive conversations. Finally, we engage in a discussion concerning the challenges associated with defining and implementing these metrics, with particular emphasis on confounding factors such as the target audience, evaluation methods, and prompt techniques involved in the evaluation process.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
This perspective paper argues that existing LLM evaluation metrics are inadequate for healthcare chatbots because they miss medical semantics and user-centered concerns such as trust, empathy, ethics, personalization, and hallucination. It proposes a comprehensive set of foundation metrics grouped into accuracy, trustworthiness, empathy, and performance, along with an evaluation framework and discussion of implementation challenges.
Key findings
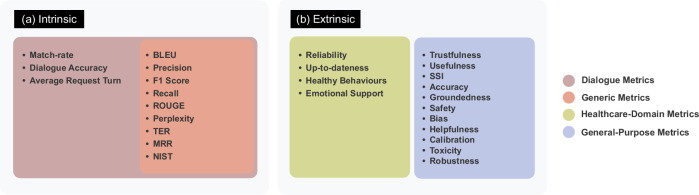
- Existing intrinsic metrics such as BLEU and ROUGE rely on surface-form similarity and fail to capture medical concepts, semantics, context, and human-centered aspects; the paper illustrates this with two semantically similar health sentences that scored only 0.39 BLEU and 0.13 ROUGE on a 0–1 scale.
- Existing extrinsic and multi-metric evaluations remain incomplete for healthcare chatbots, often neglecting empathy, reasoning, up-to-dateness, hallucinations, personalization, relevance, and latency.
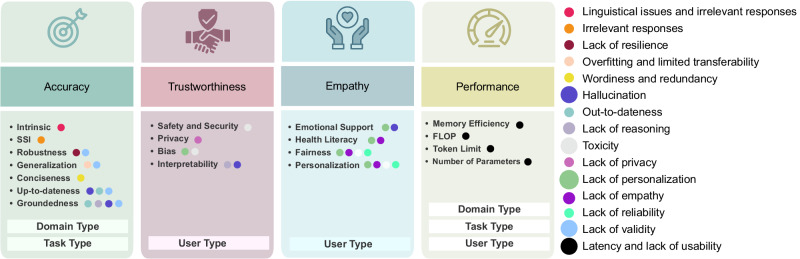
- The paper proposes four user-centered metric groups—accuracy, trustworthiness, empathy, and performance—with submetrics such as groundedness, privacy, bias, emotional support, health literacy, fairness, personalization, memory efficiency, FLOP, token limit, and number of parameters.
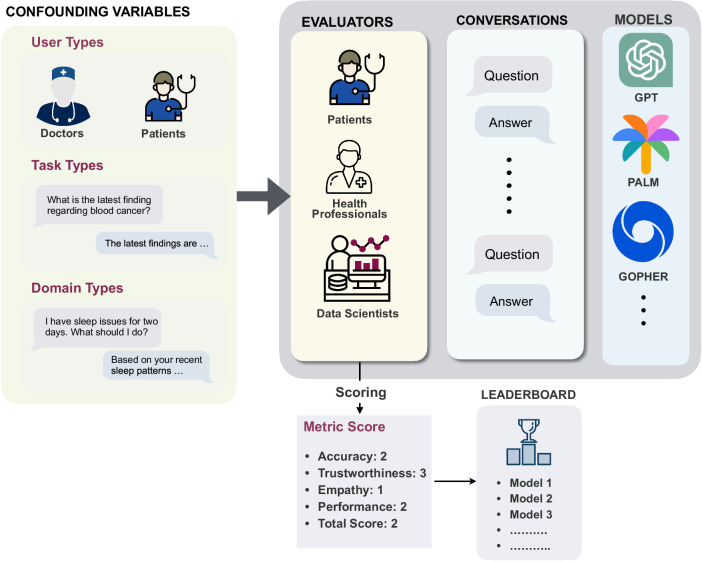
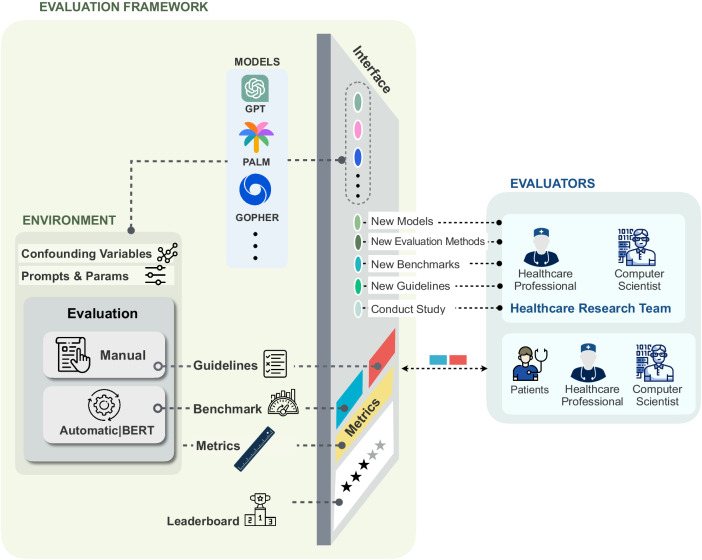
- It identifies three confounding variables for evaluation—user type, domain type, and task type—and presents a framework with models, environment, interface, interacting users, and leaderboard components.
Methods
- Narrative review and position paper: reviews intrinsic and extrinsic evaluation metrics for LLMs, including general-purpose, health-specific, and multi-metric approaches.
- Synthesizes a proposed set of healthcare chatbot metrics from the literature, categorizes them into four groups, and maps each metric to healthcare problems and existing benchmarks in Table 2.
- No empirical data collection, model training, or experimental evaluation is reported; the paper proposes an evaluation framework and discusses challenges and future implementation.
Limitations
- The paper states that future work is needed to implement the proposed evaluation framework, conduct extensive metric assessment using benchmarks and case studies, and establish unified benchmarks tailored to healthcare chatbots.
- It discusses challenges including metric associations and correlations, selection of evaluation methods, subjectivity and need for diverse expert annotators, and effects of prompt techniques and model parameters.
- Evident from the text: the proposed metrics and framework are not empirically validated in this paper, and no sample, dataset, or model evaluation results are reported beyond the illustrative BLEU/ROUGE example.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
32 Own interpretation · 24 Not checked yet · 6 No basis given · 1 Supported · 1 Own method
In the paper
“Despite the contextual similarity between the two sentences, the obtained BLEU and ROUGE scores are 0.39 and 0.13, respectively, on a scale of 0 to 1, reflecting low alignment.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Intrinsic evaluation metrics
What the sources say
- Not checked yetcites HuggingFace24
plainSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“Notably, Laing et al.5 have presented a multi-metric approach, as part of the HELM benchmark, to scrutinize LLMs concerning their accuracy, calibration (proficiency in assigning meaningful probabilities for generated text), robustness, fairness, bias, toxicity, and efficiency.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Multi-metric measurements
What the sources say
- Not checked yetcites [5] Liang, P. et al. Holistic evaluation of language models. Trans. Machine Learn. Res. https://openreview.net/forum?id=iO4LZibEqW (2023).
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“However, they solely rely on surface-form similarity and language-specific perspectives, rendering them inadequate for healthcare chatbots.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Intrinsic evaluation metrics
What the sources say
- Not checked yetcites [19] Sai, A. B., Mohankumar, A. K. & Khapra, M. M. A survey of evaluation metrics used for NLG systems. ACM Comput. Surv. (CSUR) 55, 1–39 (2022). source
- Not checked yetcites [20] Zhang*, T., Kishore*, V., Wu*, F., Weinberger, K. Q. & Artzi, Y. Bertscore: evaluating text generation with bert. In International Conference on Learning Representations. (International Conference on Learning Representations (ICLR), 2020).
- Not checked yetcites [21] Khurana, D., Koli, A., Khatter, K. & Singh, S. Natural language processing: state of the art, current trends and challenges. Multimedia Tools Appl. 82, 3713–3744 (2023). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Therefore, if we solely use these metrics to evaluate a healthcare chatbot, an inaccurate answer may receive a high score compared with the reference answer.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Intrinsic evaluation metrics
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“However, these methods have merely concentrated on specific aspects, such as the robustness of the generated answers within a particular medical domain.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Introduction
What the sources say
- Not checked yetcites [7] Thoppilan, R. et al. LaMDA: language models for dialog applications. Preprint at https://arxiv.org/abs/2201.08239 (2022).
- Not checked yetcites [9] Adiwardana, D. et al. Towards a human-like open-domain chatbot. Preprint at https://arxiv.org/abs/2001.09977 (2020).
- Not checked yetcites [12] Peng, B. et al. GODEL: large-scale pre-training for goal-directed dialog. Preprint at https://arxiv.org/abs/2206.11309 (2022).
- Not checked yetcites [13] Touvron, H. et al. LLaMA: open and efficient foundation language models. Preprint at https://arxiv.org/abs/2302.13971 (2023).
- Not checked yetcites [14] Wang, P. et al. Large language models are not fair evaluators. Preprint at https://arxiv.org/abs/2305.17926 (2023).
- Not checked yetcites [15] Resnik, P. et al. Using intrinsic and extrinsic metrics to evaluate accuracy and facilitation in computer-assisted coding. In Perspectives in Health Information Management Computer Assisted Coding Conference Proceedings (The American Health Information Management Association (AHIMA), 2006).
- Not checked yetcites [16] Liu, P. et al. Pre-train, prompt, and predict: a systematic survey of prompting methods in natural language processing. ACM Comput. Surv. 55, 1–35 (2023).
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“For example, these studies unable to assess chatbots in terms of empathy, reasoning, up-to-dateness, hallucinations, personalization, relevance, and latency.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Multi-metric measurements
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
In the paper
“Although these metrics are model-based, they lack an understanding of medical concepts (e.g., symptoms, diagnostic tests, diagnoses, and treatments), their interplay, and the priority for the well-being of the patient, all of which are crucial for medical decision-making10.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Introduction
What the sources say
- Not checked yetcites [10] Silfen, E. Documentation and coding of ED patient encounters: an evaluation of the accuracy of an electronic medical record. Am J Emerg Med. 24, 664–678 (2006). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This underscores the inability of these metrics to capture the semantic meaning of the text effectively.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Intrinsic evaluation metrics
plaindirectSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Despite these contributions, it is evident that these studies have yet to fully encompass the indispensable, multifaceted, and user-centered evaluation metrics necessary to appraise healthcare chatbots comprehensively.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Multi-metric measurements
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“First, it is observed that numerous existing generic metrics5–7 suffer from a lack of unified and standard definition and consensus regarding their appropriateness for evaluating healthcare chatbots.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Introduction
What the sources say
- Not checked yetcites [5] Liang, P. et al. Holistic evaluation of language models. Trans. Machine Learn. Res. https://openreview.net/forum?id=iO4LZibEqW (2023).
- Not checked yetcites [6] Wang, B. et al. Decodingtrust: a comprehensive assessment of trustworthiness in GPT models. Preprint at https://arxiv.org/abs/2306.11698 (2023).
- Not checked yetcites [7] Thoppilan, R. et al. LaMDA: language models for dialog applications. Preprint at https://arxiv.org/abs/2201.08239 (2022).
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 41
- It may state two separate claims as one. 11
Every source the paper cites for this claim was checked and supports it.
In the paper
“temperature67, which can influence specific metric scores.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Model prompt techniques and parameters
What the sources say
- Supportedcites [67] Chung, J., Kamar, E. & Amershi, S. Increasing diversity while maintaining accuracy: Text data generation with large language models and human interventions. In Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 575–593 (Association for Computational Linguistics, Toronto, 2023). source
Section 4.3 reports that higher temperature increased diversity and decreased label accuracy, while also affecting model accuracy under some conditions. The Ethics Statement notes that the patterns varied by task, supporting the claim that temperature can influence specific metric scores. (LLM, conf=0.93)
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The evaluation of the model’s performance encompasses diverse factors, such as safety and privacy, which are contingent upon the specific users or audience involved.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“For this reason, they inadequately capture vital aspects like semantic nuances, contextual relevance, long-range dependencies, changes in critical semantic ordering, and human-centric perspectives11, thereby limiting their effectiveness in evaluating healthcare chatbots.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Introduction
What the sources say
- Not checked yetcites [11] Novikova, J., Dušek, O., Cercas Curry, A. & Rieser, V. Why we need new evaluation metrics for NLG. In Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing, 2241–2252 (Association for Computational Linguistics, Copenhagen, Denmark, 2017). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“To address this, groundedness leverages relevant factual information, promoting sound reasoning and staying up-to-date ensuring validity.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Accuracy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. It may state two separate claims as one.
- Rests on an assumption: In the healthcare domain, safety and currentness of information are paramount.
None of the sources cited for this claim have been checked yet.
In the paper
“The definition of these accuracy metrics is contingent upon the domain and task types involved5,25.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Accuracy
What the sources say
- Not checked yetcites [5] Liang, P. et al. Holistic evaluation of language models. Trans. Machine Learn. Res. https://openreview.net/forum?id=iO4LZibEqW (2023).
- Not checked yetcites [25] AI Risk Management Framework—nist.gov. https://www.nist.gov/itl/ai-risk-management-framework (2023).
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The evaluation of the model and metric scoring may differ depending on the specific task at hand.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“In addition, Chang et al.8 have presented organized evaluation methodologies for LLMs through three essential dimensions: “what to evaluate,” “where to evaluate,” and “how to evaluate.””
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Multi-metric measurements
What the sources say
- Not checked yetcites [8] Chang, Y. et al. A survey on evaluation of large language models. ACM ransactions on Intelligent Systems and Technology. https://doi.org/10.1145/3641289 (2024). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Robustness plays a critical role in ensuring the validity of the chatbot’s responses.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Accuracy
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
- Rests on an assumption: Human inquiries may not precisely align with their underlying issues or intent.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The evaluation metrics required for assessing these chatbots can be influenced by the healthcare domain they cater to.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“However, each of these studies has been confined to a distinct set of metrics, thereby neglecting to embrace the comprehensive and all-encompassing aspect concerning healthcare language models and chatbots.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Extrinsic evaluation metrics
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As outlined below, the metrics are categorized into four distinct groups: accuracy, trustworthiness, empathy, and performance, based on their dependencies on the confounding variables.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“In this evaluation process, three confounding variables are taken into account: user type, domain type, and task type.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“Likewise, Wang et al.6 have assessed the trustworthiness of GPT-3.5 and GPT-4 from eight discerning aspects encompassing toxicity, bias, robustness, privacy, machine ethics, and fairness.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Multi-metric measurements
What the sources say
- Not checked yetcites [6] Wang, B. et al. Decodingtrust: a comprehensive assessment of trustworthiness in GPT models. Preprint at https://arxiv.org/abs/2306.11698 (2023).
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“These metrics lack the capability to capture essential elements such as semantics19,20, context19,21, distant dependencies22,23, semantically critical ordering change21, and human perspectives, particularly in real-world scenarios.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Review of existing evaluation metrics for LLMs > Intrinsic evaluation metrics
What the sources say
- Not checked yetcites [19] Sai, A. B., Mohankumar, A. K. & Khapra, M. M. A survey of evaluation metrics used for NLG systems. ACM Comput. Surv. (CSUR) 55, 1–39 (2022). source
- Not checked yetcites [20] Zhang*, T., Kishore*, V., Wu*, F., Weinberger, K. Q. & Artzi, Y. Bertscore: evaluating text generation with bert. In International Conference on Learning Representations. (International Conference on Learning Representations (ICLR), 2020).
- Not checked yetcites [21] Khurana, D., Koli, A., Khatter, K. & Singh, S. Natural language processing: state of the art, current trends and challenges. Multimedia Tools Appl. 82, 3713–3744 (2023). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Moreover, existing evaluations overlook performance aspects of models, such as computational efficiency and model size, which are crucial for practical implementation.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Introduction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Second, it is evident that the existing evaluation metrics overlook a wide range of crucial user-centered aspects that indicate the extent to which a chatbot establishes a connection and conveys support and emotion to the patient.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Introduction
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
- Rests on an assumption: Emotional bonds play a vital role in physician–patient communications.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A chatbot’s ability to generalize enhances its validity in effectively addressing a wide range of medical scenarios.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Accuracy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
- Rests on an assumption: There is scarcity of data and information across various medical domains and categories.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Up-to-dateness significantly enhances the validity of a chatbot by ensuring that its information aligns with the latest evidence and guidelines.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Accuracy
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
- Rests on an assumption: In the healthcare domain, safety and currentness of information are paramount.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“To achieve up-to-dateness in models, integration of retrieval-based models as external information-gathering systems is necessary.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Accuracy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Furthermore, the current methods fail to address the issue of hallucination, wherein chatbots generate misleading or inaccurate information.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Introduction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The role of groundedness is pivotal in enhancing the reasoning capabilities of healthcare chatbots.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Accuracy
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
- Rests on an assumption: In the healthcare domain, safety and currentness of information are paramount.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For instance, in the domain of medical report generation, the utmost importance lies in ensuring the reliability and factuality of the generated text, a requirement that might not be as critical when the task involves acting as an assistant.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it. The paper may give no reason why it holds. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“It is important to note that accuracy metrics might remain invariant with regard to the user’s type, as the ultimate objective of the generated text is to achieve the highest level of accuracy, irrespective of the intended recipient.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Accuracy
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For instance, metrics in trustworthiness and empathy may be correlated.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Metrics association
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A significant relationship exists between performance metrics and the other three categories.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Metrics association
boostedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The integration of the aforementioned requirements should result in the desired scores, treating the evaluation component as a black box.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Toward an effective evaluation framework
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, a notable concern arises when employing existing benchmarks (see Table 2) to automatically evaluate relevant metrics. These benchmarks may lack comprehensive assessments of the chatbot model’s robustness concerning confounding variables specific to the target user type, domain type, and task type.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Evaluation methods
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Human-based methods involve providing questions or guidelines to human annotators who score the chatbot’s generated answers based on given criteria. This approach presents two main challenges: subjectivity and the need for a variety of domain expert annotators.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Evaluation methods
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Enhancing fairness within a healthcare chatbot’s responses contributes to increased reliability by ensuring that the chatbot consistently provides equitable and unbiased answers.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Empathy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“An increase in parameters may introduce complexity, potentially affecting these metrics positively or negatively.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Metrics association
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Empathy often necessitates personalization, which can potentially compromise privacy and lead to biased responses.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Metrics association
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it. The paper may give no reason why it holds. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For instance, a model trained on an imbalanced dataset, with dominant samples from white males and limited samples from Hispanic females, might exhibit bias due to the imbalanced training dataset. Consequently, it may provide unfair responses to Hispanic females, as their patterns were not accurately learned during the training process.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Empathy
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The ability to adjust these variables in the evaluation framework ensures alignment among all stakeholders evaluating the target healthcare chatbot model, fostering a consistent and uniform evaluation perspective.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Toward an effective evaluation framework
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Reducing the number of parameters, which often leads to decreased memory usage and FLOPs, is likely to improve usability and latency, making the model more efficient and effective in practical applications.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Performance
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Modifying these parameters can influence the chatbot’s behavior when responding to queries.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Model prompt techniques and parameters
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Personalization enhances the reliability of a chatbot by tailoring its interactions and healthcare recommendations to individual users, ensuring that responses align closely with their preferences and health-related data.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Empathy
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“Popular LLMs, such as GPT-4, Llama, and BERT, often require large memory capacity13,58–61, making it challenging to run them on devices with limited memory, such as embedded systems, laptops, and mobile phones62.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Performance
What the sources say
- Not checked yetcites [13] Touvron, H. et al. LLaMA: open and efficient foundation language models. Preprint at https://arxiv.org/abs/2302.13971 (2023).
- Not checked yetcites [58] Brown, T. et al. Language models are few-shot learners. Adv. Neural Inf. Process. Syst. 33, 1877–1901 (2020).
- Not checked yetcites [59] Achiam, J. et al. GPT-4 technical report. arXiv preprint arXiv:2303.08774 (2023).
- Not checked yetcites [60] Devlin, J., Chang, M.-W., Lee, K. & Toutanova, K. BERT: pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers), 4171–4186 (Association for Computational Linguistics, Minneapolis, 2019).
- Not checked yetcites [61] Lee, J. et al. BioBERT: a pre-trained biomedical language representation model for biomedical text mining. Bioinformatics 36, 1234–1240 (2019). source
- Not checked yetcites [62] Zhuang, B. et al. A survey on efficient training of transformers. In Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence, IJCAI-23 (ed. Elkind, E.) 6823–6831 (International Joint Conferences on Artificial Intelligence Organization, 2023). source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“Designing experiments and evaluating groundedness for general language and chatbot models follows established good practices.7,30,34–37”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Accuracy
What the sources say
- Not checked yetcites [7] Thoppilan, R. et al. LaMDA: language models for dialog applications. Preprint at https://arxiv.org/abs/2201.08239 (2022).
- Not checked yetcites [30] Jin, Z. et al. Can large language models infer causation from correlation? Preprint at https://arxiv.org/abs/2306.05836 (2023).
- Not checked yetcites [34] Glaese, A. et al. Improving alignment of dialogue agents via targeted human judgements. Preprint at https://arxiv.org/abs/2209.14375 (2022).
- Not checked yetcites [35] Gekhman, Z., Herzig, J., Aharoni, R., Elkind, C. & Szpektor, I. Trueteacher: Learning factual consistency evaluation with large language models. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, 2053–2070 (Association for Computational Linguistics, 2023). source
- Not checked yetcites [36] Manakul, P., Liusie, A. & Gales, M. Selfcheckgpt: Zero-resource black-box hallucination detection for generative large language models. In Proceedings of the 2023 Conference on Empirical Methods in Natural Language Processing, 9004–9017 (Association for Computational Linguistics, 2023). source
- Not checked yetcites [37] Laban, P. et al. LLMs as factual reasoners: insights from existing benchmarks and beyond. Preprint at https://arxiv.org/abs/2305.14540 (2023).
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“This assessment requires examining the presence of true-causal relations among generated words30, which must be supported by evidence from reliable reference sources7,12.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Accuracy
What the sources say
- Not checked yetcites [30] Jin, Z. et al. Can large language models infer causation from correlation? Preprint at https://arxiv.org/abs/2306.05836 (2023).
- Not checked yetcites [7] Thoppilan, R. et al. LaMDA: language models for dialog applications. Preprint at https://arxiv.org/abs/2201.08239 (2022).
- Not checked yetcites [12] Peng, B. et al. GODEL: large-scale pre-training for goal-directed dialog. Preprint at https://arxiv.org/abs/2206.11309 (2022).
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The proposed metrics demonstrate both within-category and between-category associations, with the potential for negative or positive correlations among them.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Metrics association
boostedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For instance, the number of parameters in a language model can impact accuracy, trustworthiness, and empathy metrics.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Metrics association
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
In the paper
“As the number of tokens increases, the memory and computation needed also increase63, leading to higher latency and reduced usability.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Performance
What the sources say
- Not checked yetcites [63] Hoffmann, J. et al. An empirical analysis of compute-optimal large language model training. In Advances in Neural Information Processing Systems (eds Oh, A. H. et al.) (Neural Information Processing Systems Foundation, Inc. (NeurIPS), 2022).
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For instance, within the accuracy metrics category, up-to-dateness and groundedness show a positive correlation, as ensuring the chatbot utilizes the most recent and valid information enhances the factual accuracy of answers, thereby increasing groundedness.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Metrics association
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Conversely, a low parameter count can limit the model’s knowledge acquisition and influence the values of these metrics.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Metrics association
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Various automatic and human-based evaluation methods can quantify each metric, and the selection of evaluation methods significantly impacts metric scores.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Challenges in evaluating healthcare chatbots > Evaluation methods
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
The paper relies on this without support.
Healthcare applications are life-critical.
“Due to the life-critical nature of healthcare applications, using conversational models necessitates establishing a unified and comprehensive set of foundation metrics1 that enable a meticulous evaluation of the models’ performance, capabilities, identification of potential errors, and implementation of effective feedback mechanisms.”
The paper relies on this without support.
Emotional bonds play a vital role in physician–patient communications.
“Emotional bonds play a vital role in physician–patient communications, but they are often ignored during the development and evaluation of chatbots.”
The paper relies on this without support.
In the healthcare domain, safety and currentness of information are paramount.
“In particular, in the healthcare domain, where safety and currentness of information are paramount, hallucinations pose a significant concern.”
The paper relies on this without support.
There is scarcity of data and information across various medical domains and categories.
“In the context of healthcare, the significance of the generalization metric becomes pronounced due to the scarcity of data and information across various medical domains and categories.”
The paper relies on this without support.
Human inquiries may not precisely align with their underlying issues or intent.
“In healthcare chatbots, where human inquiries may not precisely align with their underlying issues or intent, robustness assumes paramount importance.”
The paper relies on this without support.
The desired level of interpretability for a generated text may vary between a patient and a nurse.
“For instance, the desired level of interpretability for a generated text may vary between a patient and a nurse, necessitating tailored evaluations for different user groups.”
The paper relies on this without support.
Empathy plays a crucial role in building trust between users and chatbots.
“Empathy also plays a crucial role in building trust between users and chatbots.”
The paper relies on this without support.
Unempathetic responses can erode trust and credibility in the system.
“Unempathetic responses can erode trust and credibility in the system, as users may feel unheard, misunderstood, or invalidated.”
The paper relies on this without support.
Low latency ensures prompt and efficient communication, enabling users to obtain timely responses.
“Low latency ensures prompt and efficient communication, enabling users to obtain timely responses.”
The paper relies on this without support.
Performance metrics may remain invariant concerning the three confounding variables (user type, domain type, and task type).
“It is important to note that performance metrics may remain invariant concerning the three confounding variables (user type, domain type, and task type).”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“The application gap is attributed to surface-form similarity and lexicographic analytic restrictions41.”
From Towards a holistic framework for multimodal LLM in 3D brain CT radiology report generation (2025) · cites this paper as [41]
In the citing paper
“Medical image reports assist in differential diagnosis and thus are characterized by complex paraphrasing, high token counts (>100), and numerous negative descriptions, which conflict with common metric evaluation contexts24,41.”
From Towards a holistic framework for multimodal LLM in 3D brain CT radiology report generation (2025) · cites this paper as [41]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots
“OpenAI Evals108”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > References
“108. Aryan, A., Nain, A. K., McMahon, A., Meyer, L. A. & Sahota, H. S. The costly dilemma: are large language models the pay-day loans of machine learning?”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots
“performance metrics are evaluated based on the three confounding variables.”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots > Performance
“It is important to note that performance metrics may remain invariant concerning the three confounding variables (user type, domain type, and task type).”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots
“WinoGender13”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > References
“13. Touvron, H. et al. LLaMA: open and efficient foundation language models.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > Essential metrics for evaluating healthcare chatbots
“BigBench112”
§ Foundation metrics for evaluating effectiveness of healthcare conversations powered by generative AI > References
“112. Ghazal, A. et al. Bigbench: towards an industry standard benchmark for big data analytics.”
Citations
Cites
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Lewis, M., Liu, Y., Goyal, N., Ghazvininejad, M., Mohamed, A., Levy, O., Stoyanov, V., & Zettlemoyer, L. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.703 · Cited by 8,821
BioBERT: a pre-trained biomedical language representation model for biomedical text mining
Lee, J., Yoon, W., Kim, S., Kim, D., Kim, S., So, C. H., & Kang, J. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btz682 · Cited by 7,218 · cited 1×
“…93 TruthfulQA, 94 CivilComments, 95 BOLD, 96 BBQ 97 Trustworthiness Privacy Evaluatingthemodel’suseofsensitiveuserinformation Lackofprivacy DP-SGD 98,99 Bias Lackofpersonzalitionandtoxicity CrowS-Pairs, 100 WinoGender, 13 BBQ, 97 TruthfulQA, 94 RealToxicityPrompts, 101 CivilComments 102”
LLaMA: Open and Efficient Foundation Language Models
Touvron, H., Lavril, T., Izacard, G., Martinet, X., Lachaux, M.-A., Lacroix, T., Rozière, B., Goyal, N., Hambro, E., Azhar, F., et al. (2023) · arXiv · doi:10.48550/arxiv.2302.13971 · Cited by 4,602 · cited 1×
“Popular LLMs, such as GPT-4, Llama, and BERT, often require large memory capacity, 13,24,140–142 making it challenging to run them on devices with limited memory, such as embedded systems, laptops, and mobile phones.”
BackgroundLiu, P., Yuan, W., Fu, J., Jiang, Z., Hayashi, H., & Neubig, G. (2023) · ACM Computing Surveys · doi:10.1145/3560815 · Cited by 4,361 · cited 2×
“In the following, we briefly outline these evaluation methods.”
BackgroundMethodLiu, P., Yuan, W., Fu, J., Jiang, Z., Hayashi, H., & Neubig, G. (2021) · arXiv · doi:10.48550/arxiv.2107.13586 · Cited by 4,352 · cited 2×
“In the following, we briefly outline these evaluation methods.”
BackgroundMethodA Survey on Evaluation of Large Language Models
Chang, Y., Wang, X., Wang, J., Wu, Y., Yang, L., Zhu, K., Chen, H., Yi, X., Wang, C., Wang, Y., et al. (2024) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3641289 · Cited by 4,254 · cited 2×
“Currently, state-of-the-art conversational models are predominantly assessed and compared based on language-specific perspectives 8 and surface-form similarity 8 using intrinsic metrics such as Bilingual Evaluation Understudy (BLEU) 9 and Recall-oriented Understudy for Gisting Evaluation (ROUGE).”
BackgroundSelf-citationGLUE: A Multi-Task Benchmark and Analysis Platform for Natural Language Understanding
Wang, A., Singh, A., Michael, J., Hill, F., Levy, O., & Bowman, S. (2018) · Proceedings of the 2018 EMNLP Workshop BlackboxNLP: Analyzing and Interpreting Neural Networks for NLP · doi:10.18653/v1/w18-5446 · Cited by 4,222
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Research works printed but not linked: 18
- Resnik, P. et al. Using intrinsic and extrinsic metrics to evaluate accuracy and facilitation in computer-assisted coding. In Perspectives in Health Information Management Computer Assisted Coding Conference Proceedings (The American Health Information Management Association (AHIMA), 2006).
- Zhang*, T., Kishore*, V., Wu*, F., Weinberger, K. Q. & Artzi, Y. Bertscore: evaluating text generation with bert. In International Conference on Learning Representations. (International Conference on Learning Representations (ICLR), 2020).
- Napoles, C., Van Durme, B. & Callison-Burch, C. Evaluating sentence compression: Pitfalls and suggested remedies. In Proceedings of the Workshop on Monolingual Text-To-Text Generation, 91–97 (Association for Computational Linguistics, 2011). https://aclanthology.org/volumes/W11-16/.
- Zhou, C. et al. Lima: Less is more for alignment. Advances in Neural Information Processing Systems 36 (Neural Information Processing Systems Foundation, Inc. (NeurIPS), 2024).
- Devlin, J., Chang, M.-W., Lee, K. & Toutanova, K. BERT: pre-training of deep bidirectional transformers for language understanding. In Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers), 4171–4186 (Association for Computational Linguistics, Minneapolis, 2019).
- Hoffmann, J. et al. An empirical analysis of compute-optimal large language model training. In Advances in Neural Information Processing Systems (eds Oh, A. H. et al.) (Neural Information Processing Systems Foundation, Inc. (NeurIPS), 2022).
- Text REtrieval Conference (TREC) Home Page — trec.nist.gov. https://trec.nist.gov/. [Accessed 28-07-2023]
- Ge, Y. et al. Openagi: When llm meets domain experts. Advances in Neural Information Processing Systems 36 (Neural Information Processing Systems Foundation, Inc. (NeurIPS), 2024).
- Wei, J. et al. Finetuned language models are zero-shot learners. In International Conference on Learning Representations (ICLR, 2022).
- Radford, A. et al. Language models are unsupervised multitask learners. OpenAI Blog 1, 9 (2019).
- Zhang, K. et al. BiomedGPT: a unified and generalist biomedical generative pre-trained transformer for vision, language, and multimodal tasks. Preprint at https://arxiv.org/abs/2305.17100 (2023). · arXiv
- Banerjee, S. & Lavie, A. Meteor: an automatic metric for mt evaluation with improved correlation with human judgments. In Proceedings of the ACL Workshop on Intrinsic and Extrinsic Evaluation Measures for Machine Translation and/or Summarization, 65–72 (Association for Computational Linguistics, 2005).
- Peng, Y.-S., Tang, K.-F., Lin, H.-T. & Chang, E. Refuel: exploring sparse features in deep reinforcement learning for fast disease diagnosis. Adv. Neural Inf. Process. Syst. 31, (2018).
- Hermann, K. M. et al. Teaching machines to read and comprehend. In Proceedings of the 28th International Conference on Neural Information Processing Systems - Volume 1, NIPS’15, 1693–1701 (MIT Press, Cambridge, 2015).
- Aryan, A., Nain, A. K., McMahon, A., Meyer, L. A. & Sahota, H. S. The costly dilemma: are large language models the pay-day loans of machine learning? https://abiaryan.com/assets/EMNLP%20Submission_Non-Anon.pdf. (2023).
- Yuan, L. et al. Revisiting out-of-distribution robustness in nlp: Benchmarks, analysis, and LLMs evaluations. Advances in Neural Information Processing Systems 36 (Neural Information Processing Systems Foundation, Inc. (NeurIPS), 2024).
- Hendrycks, D. et al. Measuring coding challenge competence with APPS. In Thirty-fifth Conference on Neural Information Processing Systems Datasets and Benchmarks Track (Round 2) (Neural Information Processing Systems Foundation, Inc. (NeurIPS), 2021).
- Maas, A. et al. Learning word vectors for sentiment analysis. In Proceedings of the 49th Annual Meeting of the Association for Computational Linguistics: Human Language Technologies, 142–150 (Association for Computational Linguistics, 2011).
Cited by
Sorted by citations
Generative artificial intelligence in medicine
Teo, Z. L., Thirunavukarasu, A. J., Elangovan, K., Cheng, H., Moova, P., Soetikno, B., Nielsen, C., Pollreisz, A., Ting, D. S. J., Morris, R. J. T., et al. (2025) · Nature Medicine · doi:10.1038/s41591-025-03983-2 · Cited by 119
“For a comprehensive overview of foundational metrics for clinical GAI assessment, Abbasian et al. have provided a summary grouped under the headings of accuracy, trustworthiness, empathy and performance 150 .”
Use of Generative AI for Mental Health Advice Among US Adolescents and Young Adults
McBain, R., Bozick, R., Diliberti, M., Zhang, L.-A., Zhang, F., Burnett, A., Kofner, A., Rader, B., Breslau, J., Stein, B. D., et al. (2025) · JAMA Network Open · doi:10.1001/jamanetworkopen.2025.42281 · Cited by 128
Jacob, C., Brasier, N., Laurenzi, E., Heuss, S., Mougiakakou, S. G., Çöltekin, A., & Peter, M. K. (2024) · Journal of Medical Internet Research · doi:10.2196/67485 · Cited by 125
“Trust is built through factors such as validation, transparency, safety, privacy, and interpretability of the AI tool [62].”
InfluentialTwo Tales of Persona in LLMs: A Survey of Role-Playing and Personalization
Tseng, Y.-M., Huang, Y.-C., Hsiao, T.-Y., Chen, W.-L., Huang, C.-W., Meng, Y., & Chen, Y.-N. (2024) · Findings of the Association for Computational Linguistics: EMNLP 2024 · doi:10.18653/v1/2024.findings-emnlp.969 · Cited by 87
Prompt Engineering in Education: A Systematic Review of Approaches and Educational Applications
Qian, Y. (2025) · Journal of Educational Computing Research · doi:10.1177/07356331251365189 · Cited by 134
Metadata
- Authors
- Abbasian, M., Khatibi, E., Azimi, I., Oniani, D., Shakeri Hossein Abad, Z., Thieme, A., Sriram, R., Yang, Z., Wang, Y., Lin, B., Gevaert, O., Li, L.-J., Jain, R., & Rahmani, A. M.
- Affiliations
- University of California, Irvine (US)
- University of Pittsburgh (US)
- Stanford University (US)
- National Institute of Standards and Technology (US)
- Corresponding author
- Abbasian, Mahyar
- Khatibi, Elahe
- ORCID
- Venue
- npj Digital Medicine
- Published
- 2024-03-29
- Volume
- 7
- Issue
- 1
- Pages
- 82-82
- ISSN
- 2398-6352 (ISSN-L)
- PMC
- PMC10980701
- OpenAlex
- W4393335480
- Semantic Scholar
- 8d1211cbbdf161feaae2c87832ede063346e76dd
- Cited by
- 213
- References
- 143
- Citations by year
- 2026: 92 · 2025: 83 · 2024: 38
- FWCI
- 4.81
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Locations
- npj Digital Medicine (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by)
- eScholarship (California Digital Library) (submittedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion)
- arXiv (Cornell University) (cc-by)
- Funders
- National Institute of Standards and Technology
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Social Sciences › Business, Management and Accounting › Marketing › AI in Service Interactions
- Keywords
- generative AI in healthcare, healthcare chatbots, evaluation metrics, large language models, chatbots, patient-centered care, user trust, empathy, emotional support, personalized health recommendations, confounding factors
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-09, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-09 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
