

The DOI matches its Crossref record; 29 of the 29 references it cites were found in a registry or an index; 18 of the 18 sources its claims cite were checked for support.
AlphaFold Protein Structure Database in 2024: providing structure coverage for over 214 million protein sequences
Open accessAbstract
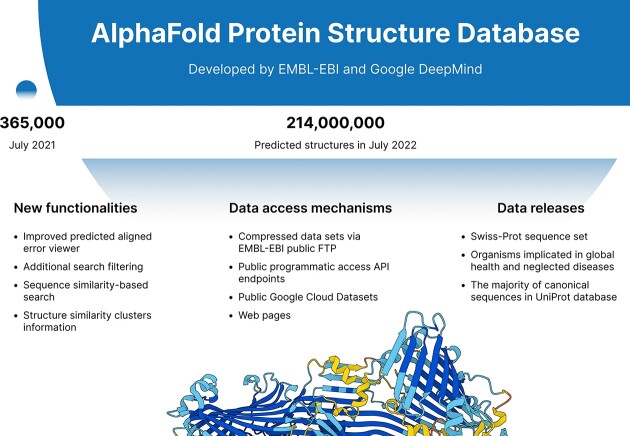
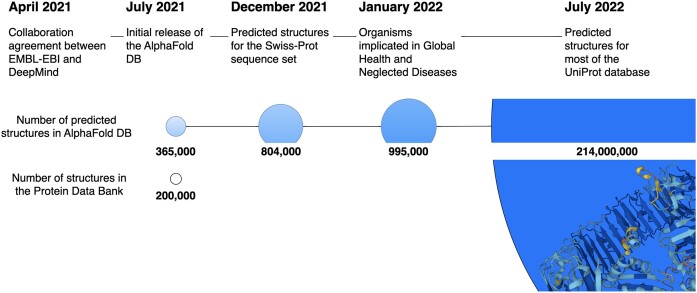
The AlphaFold Database Protein Structure Database (AlphaFold DB, https://alphafold.ebi.ac.uk) has significantly impacted structural biology by amassing over 214 million predicted protein structures, expanding from the initial 300k structures released in 2021. Enabled by the groundbreaking AlphaFold2 artificial intelligence (AI) system, the predictions archived in AlphaFold DB have been integrated into primary data resources such as PDB, UniProt, Ensembl, InterPro and MobiDB. Our manuscript details subsequent enhancements in data archiving, covering successive releases encompassing model organisms, global health proteomes, Swiss-Prot integration, and a host of curated protein datasets. We detail the data access mechanisms of AlphaFold DB, from direct file access via FTP to advanced queries using Google Cloud Public Datasets and the programmatic access endpoints of the database. We also discuss the improvements and services added since its initial release, including enhancements to the Predicted Aligned Error viewer, customisation options for the 3D viewer, and improvements in the search engine of AlphaFold DB.
Overview
CoChat Summary
TL;DR
AlphaFold DB has grown from ~300k to over 214 million predicted protein structures as of September 2023, with expanded access, search, and visualization features. This 2024 update describes data archiving, access mechanisms, integration with core resources, and new clustering/BLAST/PAE viewer capabilities.
Key findings
- AlphaFold DB expanded from approximately 300k structures in 2021 to over 214 million predicted protein structures as of September 2023; the initial July 2021 release housed over 360,000 structures for 20 model organism proteomes.
- Predictions are integrated into resources including PDB, UniProt, Ensembl, InterPro and MobiDB, and are accessible via FTP, Google Cloud Public Datasets (~23 TiB), API, and the website; PAE data is unavailable from EMBL-EBI public FTP.
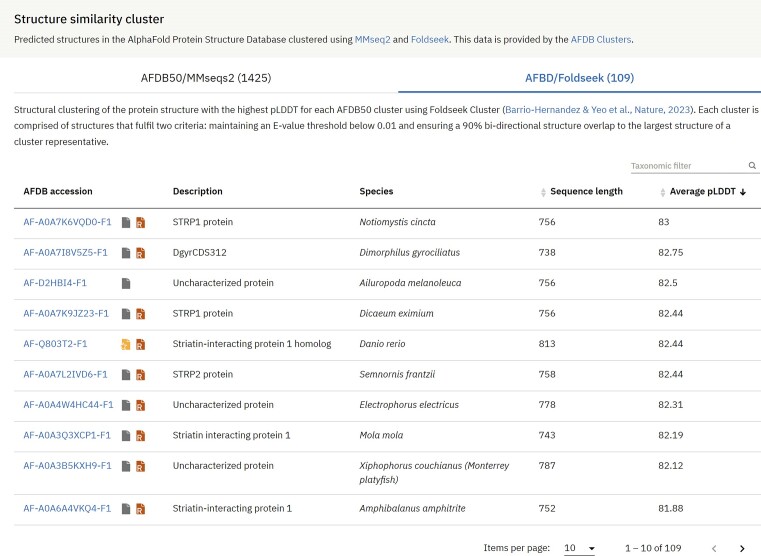
- Structure similarity clustering used MMseqs2 to cluster 214 million UniProtKB sequences into 52 million clusters, then Foldseek secondary clustering yielded 18.8 million clusters, finalizing 2.30 million robust clusters each with at least a pair of structures.
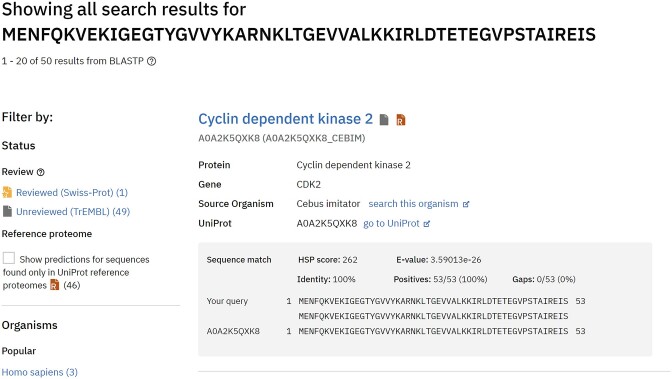
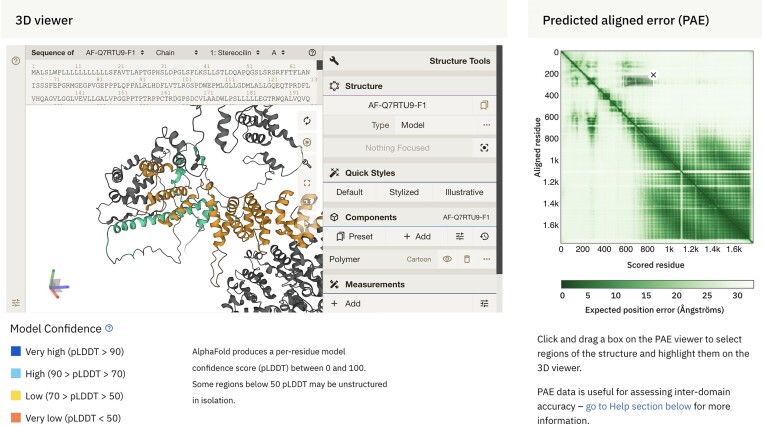
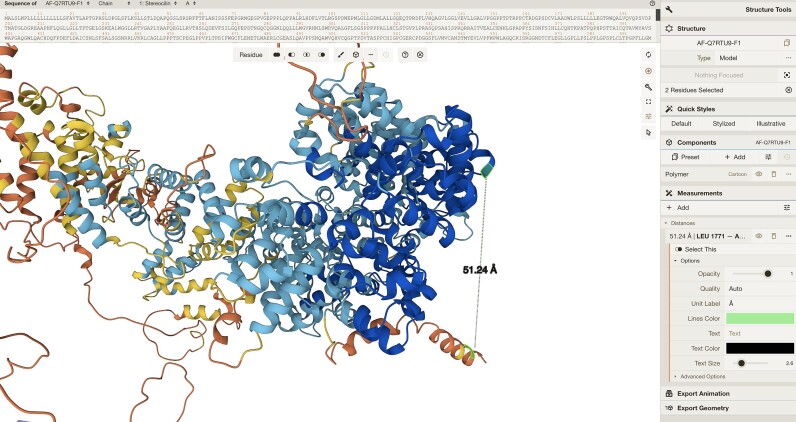
- New features include BLAST sequence similarity search, improved search filters for reviewed/unreviewed and reference proteome status, enhanced PAE viewer–Mol* interactivity, and a November 2022 update fixing a numerical bug that affected ~4% of total structure predictions.
Methods
- Descriptive database update/report with no primary experimental design; data generation is carried out by Google DeepMind, with predictions stored in PDB, mmCIF (modelCIF), and binaryCIF formats plus JSON metadata and confidence metrics pLDDT and PAE.
- Archiving uses successive releases from UniProt reference proteomes (e.g., 2021_02, 2021_04), Swiss-Prot, WHO global health proteomes, and MANE select; as of September 2023, EMBL-EBI FTP hosts TAR files for proteomes of 48 organisms.
- Access and analysis infrastructure includes FTP, Google Cloud Public Datasets, an API keyed on UniProt accessions, Apache-Solr search, BLAST on Google Cloud Platform, and Foldseek/MMseqs2 clustering.
Limitations
- Stated: sequences are not covered if they are less than 16 amino acids; >2700 aa for Swiss-Prot/proteome sequences or >1280 aa for other UniProt sequences; contain non-standard amino acids; are not in the UniProt ‘one sequence per gene’ FASTA file; or are viral proteins; these limitations are under discussion.
- Stated: some sequences may be outdated compared to UniProt due to less frequent AlphaFold DB releases; PAE data is unavailable from EMBL-EBI public FTP; full Google Cloud dataset download requires a Google account and can take roughly 2.5 days at 1 Gbps.
- Evident from the text: all archived structures are predicted models rather than experimental structures, and users must interpret pLDDT/PAE cautiously (e.g., pLDDT <50 likely disordered, 50–70 lower confidence); the database also currently lacks isoform and multimeric predicted structures, which are listed as future work.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures

Verification
Claims the paper makes
11 Valid · 1 Not valid · 0 Not checked · 28 Own results and interpretations
Every source the paper cites for this claim was checked and supports it.
In the paper
“The new generation of predicted protein structure models has demonstrated remarkable accuracy, which could mitigate the continually widening gap between known protein sequences and experimentally determined protein structures (7).”
§ AlphaFold Protein Structure Database in 2024: providing structure coverage for over 214 million protein sequences > Introduction
What the sources say
- Supportedcites [7] Varadi, 2023, The opportunities and challenges posed by the new generation of deep learning-based protein structure predictors, Curr. Opin. Struct. Biol. source
The Introduction says prediction models made a major advance in accuracy and can match or sometimes surpass experimentally determined structures. It also describes a growing gap between known protein sequences and determined structures; the section on new challenges says predicted structures have greatly increased coverage of protein sequence space. These passages support both the accuracy claim and the proposed potential to narrow that gap (page numbers unavailable). (LLM, conf=0.93)
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“In response to frequent requests from the user community since the AlphaFold DB launch, we have made significant strides to implement a sequence-based similarity search feature. We have incorporated the Basic Local Alignment Search Tool (BLAST) (21) into our Google Cloud Platform infrastructure to achieve this.”
§ AlphaFold Protein Structure Database in 2024: providing structure coverage for over 214 million protein sequences > Implementation > Data access
What the sources say
- Supportedcites [21] Camacho, 2009, BLAST+: architecture and applications, BMC Bioinf. source
The Background identifies BLAST as a sequence similarity search program that matches a query sequence against a database. In the citing sentence, the citation identifies the tool incorporated; the AlphaFold DB implementation is the citing authors’ own report, not a claim attributed to this source. (LLM, conf=0.91)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“The impact of the predicted structures is further enhanced by their seamless integration into several core data resources, including PDBe-KB (17), UniProt (6), Ensembl (16), InterPro (15), Genecards (24) and MobiDB (25), among others.”
§ AlphaFold Protein Structure Database in 2024: providing structure coverage for over 214 million protein sequences > Conclusions and outlook
What the sources say
- Supportedcites [17] consortium, 2022, PDBe-KB: collaboratively defining the biological context of structural data, Nucleic Acids Res. source
Citation (17) is attached specifically to PDBe-KB, rather than to the other resources in the sentence. The Introduction identifies PDBe-KB as a resource that integrates structural and functional annotations, supporting its identification here. (LLM, conf=0.90)
- Supportedcites [6] U.P. Consortium, 2023, UniProt: the Universal Protein Knowledgebase in 2023, Nucleic Acids Res. source
The citation is attached to UniProt in a list of resources, and the cited paper is a description of UniProt. Its Data integration and Interactive visualisations in entry pages sections state that UniProt incorporates AlphaFold-predicted structures into protein entries alongside other data; the supplied passages do not give page numbers. (LLM, conf=0.93)
- Supportedcites [16] Cunningham, 2022, Ensembl 2022, Nucleic Acids Res. source
The citation identifies Ensembl as one of the resources in the list. In “Developing a new website” (page not provided), the paper says Ensembl’s Entity Viewer provides access to protein information, including 3D structures from PDBe. (LLM, conf=0.86)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“Tackling this challenge, Steinegger et al. recently unveiled the Foldseek Cluster, a state-of-the-art structural-alignment-based clustering algorithm designed for vast datasets (22). They applied this novel method to the AlphaFold DB archive, making the derived structure similarity clusters available to the research community.”
§ AlphaFold Protein Structure Database in 2024: providing structure coverage for over 214 million protein sequences > Implementation > Data access
What the sources say
- Supportedcites [22] Barrio-Hernandez, 2023, Clustering-predicted structures at the scale of the known protein universe, Nature source
The Abstract says the authors used Foldseek cluster to cluster the AlphaFold database. The Methods section (“Web server”) says they developed a server for users to explore the clusters, their members and related clusters, supporting the claim that the results were made available to researchers. (LLM, conf=0.93)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
- Probably not a substantial claim. 30
- It may state two separate claims as one. 15
- The quote only partly states this claim. 1
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“houses over 200 million pre-run AF2 predictions”
From The power and pitfalls of AlphaFold2 for structure prediction beyond rigid globular proteins (2024) · cites this paper as [7]
Citations
Cites
Highly accurate protein structure prediction with AlphaFold
Jumper, J., Evans, R., Pritzel, A., Green, T., Figurnov, M., Ronneberger, O., Tunyasuvunakool, K., Bates, R., Žídek, A., Potapenko, A., et al. (2021) · Nature · doi:10.1038/s41586-021-03819-2 · Cited by 43,764
Self-citationBLAST+: architecture and applications
Camacho, C., Coulouris, G., Avagyan, V., Ma, N., Papadopoulos, J., Bealer, K., & Madden, T. L. (2009) · BMC Bioinformatics · doi:10.1186/1471-2105-10-421 · Cited by 22,074
UniProt: the Universal Protein Knowledgebase in 2023
The UniProt Consortium, Bateman, A., Martin, M.-J., Orchard, S., Magrane, M., Ahmad, S., Alpi, E., Bowler-Barnett, E. H., Britto, R., Bye-A-Jee, H., et al. (2023) · Nucleic Acids Research · doi:10.1093/nar/gkac1052 · Cited by 7,210
Evolutionary-scale prediction of atomic level protein structure with a language model
Lin, Z., Akin, H., Rao, R., Hie, B., Zhu, Z., Lu, W., Smetanin, N., Verkuil, R., Kabeli, O., Shmueli, Y., et al. (2022) · doi:10.1101/2022.07.20.500902 · Cited by 5,990 · cited 1×
“In the wake of the latest breakthroughs in prediction software, new databases such as the AlphaFold Protein Structure Database and the ESM Atlas ( 14 ) have emerged.”
MethodThe GeneCards suite: from gene data mining to disease genome sequence analyses
Stelzer, G., Rosen, N., Plaschkes, I., Zimmerman, S., Twik, M., Fishilevich, S., Stein, T. I., Nudel, R., Lieder, I., Mazor, Y., et al. (2016) · Current Protocols in Bioinformatics · doi:10.1002/cpbi.5 · Cited by 5,550 · cited 1×
“The impact of the predicted structures is further enhanced by their seamless integration into several core data resources, including PDBe-KB ( 17 ), UniProt ( 6 ), Ensembl ( 16 ), InterPro ( 15 ), Genecards ( 24 ) and MobiDB ( 25 ), among others.”
BackgroundAccurate prediction of protein structures and interactions using a 3-track network
Baek, M., DiMaio, F., Anishchenko, I., Dauparas, J., Ovchinnikov, S., Lee, G. R., Wang, J., Cong, Q., Kinch, L. N., Schaeffer, R. D., et al. (2021) · doi:10.1101/2021.06.14.448402 · Cited by 5,549
Paysan-Lafosse, T., Blum, M., Chuguransky, S., Grego, T., Pinto, B. L., Salazar, G. A., Bileschi, M. L., Bork, P., Bridge, A., Colwell, L., et al. (2023) · Nucleic Acids Research · doi:10.1093/nar/gkac993 · Cited by 2,399
Cunningham, F., Allen, J. E., Allen, J., Alvarez-Jarreta, J., Amode, M. R., Armean, I. M., Austine-Orimoloye, O., Azov, A. G., Barnes, I., Bennett, R., et al. (2022) · Nucleic Acids Research · doi:10.1093/nar/gkab1049 · Cited by 1,923
Mol* Viewer: modern web app for 3D visualization and analysis of large biomolecular structures
Sehnal, D., Bittrich, S., Deshpande, M., Svobodová, R., Berka, K., Bazgier, V., Velankar, S., Burley, S. K., Koča, J., & Rose, A. S. (2021) · Nucleic Acids Research · doi:10.1093/nar/gkab314 · Cited by 1,154 · cited 1×
“We improved the visualisation of non-consecutive regions and the interactivity between the PAE viewer and the 3D molecular graphics viewer, Mol* ( 23 ) (Figure 5 ).”
MethodSelf-citationMariani, V., Biasini, M., Barbato, A., & Schwede, T. (2013) · Bioinformatics · doi:10.1093/bioinformatics/btt473 · Cited by 1,138 · cited 1×
“AlphaFold yields a per-residue estimate of its confidence, known as pLDDT, ranging from 0 to 100, indicating the tool’s predicted score on the lDDT-C α metric ( 19 ).”
Method
Cited by
Highly accurate protein structure prediction with AlphaFold
Jumper, J., Evans, R., Pritzel, A., Green, T., Figurnov, M., Ronneberger, O., Tunyasuvunakool, K., Bates, R., Žídek, A., Potapenko, A., et al. (2021) · Nature · doi:10.1038/s41586-021-03819-2 · Cited by 43,764
Self-citationThe PRIDE database at 20 years: 2025 update
Perez-Riverol, Y., Bandla, C., Kundu, D. J., Kamatchinathan, S., Bai, J., Hewapathirana, S., John, N. S., Prakash, A., Walzer, M., Wang, S., et al. (2025) · Nucleic Acids Research · doi:10.1093/nar/gkae1011 · Cited by 1,995
InterPro: the protein sequence classification resource in 2025
Blum, M., Andreeva, A., Florentino, L. C., Chuguransky, S. R., Grego, T., Hobbs, E., Pinto, B. L., Orr, A., Paysan-Lafosse, T., Ponamareva, I., et al. (2025) · Nucleic Acids Research · doi:10.1093/nar/gkae1082 · Cited by 1,062
“…and visualisation of AlphaFold predicted structures in InterPro Over 85% of UniProtKB entries now feature predicted protein structures generated by AlphaFold, an artificial intelligence method developed by Google DeepMind that infers protein structures from their amino acid sequences ( 39 ,40 ).”
Simulating 500 million years of evolution with a language model
Hayes, T., Rao, R., Akin, H., Sofroniew, N. J., Oktay, D., Lin, Z., Verkuil, R., Tran, V. Q., Deaton, J., Wiggert, M., et al. (2025) · Science · doi:10.1126/science.ads0018 · Cited by 937
Burley, S. K., Bhatt, R., Bhikadiya, C., Bi, C., Biester, A., Biswas, P., Bittrich, S., Blaumann, S., Brown, R., Chao, H., et al. (2025) · Nucleic Acids Research · doi:10.1093/nar/gkae1091 · Cited by 329
“…uncharacterized 3D structures to the wealth of 3D biostructure information archived in the PDB, which includes expertly biocurated data and annotations from 50 trusted external resources, alongside > 1 million CSMs coming from AlphaFold DB ( 16 ) and the ModelArchive (modelarchive.org) ( 17 ).”
Metadata
- Authors
- Varadi, M., Bertoni, D., Magana, P., Paramval, U., Pidruchna, I., Radhakrishnan, M., Tsenkov, M., Nair, S., Mirdita, M., Yeo, J., Kovalevskiy, O., Tunyasuvunakool, K., Laydon, A., Žídek, A., Tomlinson, H., Hariharan, D., Abrahamson, J., Green, T., Jumper, J., Birney, E., Steinegger, M., Hassabis, D., & Velankar, S.
- Affiliations
- European Molecular Biology Laboratory, European Bioinformatics Institute , Hinxton, UK
- European Bioinformatics Institute (GB)
- Seoul National University (KR)
- Google DeepMind (United Kingdom) (GB)
- Corresponding author
- Hassabis, Demis
- Velankar, Sameer
- ORCID
- Venue
- Nucleic Acids Research
- Publisher
- Oxford University Press (OUP)
- Published
- 2023-11-02
- Volume
- 52
- Issue
- D1
- Pages
- D368-D375
- ISSN
- 0305-1048 (ISSN-L)
- 1362-4962
- PMC
- PMC10767828
- OpenAlex
- W4388464011
- Cited by
- 2,052
- References
- 29
- Citations by year
- 2026: 724 · 2025: 1015 · 2024: 307 · 2023: 5
- FWCI
- 181.98
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Nucleic Acids Research (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Seoul National University Open Repository (Seoul National University) (submittedVersion)
- Funders
- Google DeepMind
- National Research Foundation of Korea (2019R1A6A1A10073437, 2020M3A9G7103933, 2021R1C1C102065, 2021M3A9I4021220, RS-2023-00250470)
- Samsung DS Research Fund
- Seoul National University
- Topics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Protein Structure and Dynamics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Structural Biology › Enzyme Structure and Function
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Machine Learning in Bioinformatics
- Keywords
- predicted protein structures, AlphaFold2, protein structure prediction, protein sequence coverage, data archiving, database access, search engines
- MeSH terms
- Amino Acid Sequence, Artificial Intelligence, Proteins, Protein Structure, Secondary, Proteome, Databases, Protein, Search Engine
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: AlphaFold Protein Structure Database in 2024: providing structure coverage for over 214 million protein sequences. https://app.cochat.ai/papers/10.1093/nar/gkad1011
- The paper
- Varadi, M., Bertoni, D., Magana, P., Paramval, U., Pidruchna, I., Radhakrishnan, M., Tsenkov, M., Nair, S., Mirdita, M., Yeo, J., Kovalevskiy, O., Tunyasuvunakool, K., Laydon, A., Žídek, A., Tomlinson, H., Hariharan, D., Abrahamson, J., Green, T., Jumper, J., . . . Velankar, S. (2024). AlphaFold Protein Structure Database in 2024: providing structure coverage for over 214 million protein sequences. Nucleic Acids Research. https://doi.org/10.1093/nar/gkad1011
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
