

The DOI matches its Crossref record; 10 of the 10 references it cites were found in a registry or an index.
The European Nucleotide Archive
Open accessAbstract
The European Nucleotide Archive (ENA; http://www.ebi.ac.uk/ena) is Europe's primary nucleotide-sequence repository. The ENA consists of three main databases: the Sequence Read Archive (SRA), the Trace Archive and EMBL-Bank. The objective of ENA is to support and promote the use of nucleotide sequencing as an experimental research platform by providing data submission, archive, search and download services. In this article, we outline these services and describe major changes and improvements introduced during 2010. These include extended EMBL-Bank and SRA-data submission services, extended ENA Browser functionality, support for submitting data to the European Genome-phenome Archive (EGA) through SRA, and the launch of a new sequence similarity search service.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
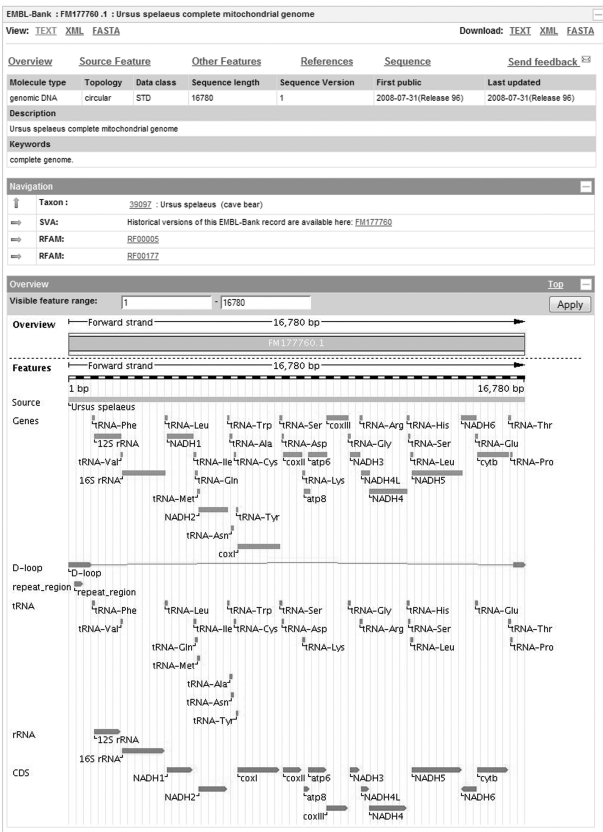
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Tools such as DIGIT and Abysis source their data from the European Nucleotide Archive (ENA) [60] and the National Center for Biotechnology Information (NCBI) [61]; their sequence volumes are of the order of 105 and contain multiple artificially engineered sequences.”
From Computational approaches to therapeutic antibody design: established methods and emerging trends (2020) · cites this paper as [60]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The Sequence Alignment/Map format and SAMtools
Li, H., Handsaker, B., Wysoker, A., Fennell, T., Ruan, J., Homer, N., Marth, G., Abecasis, G., Durbin, R., & 1000 Genome Project Data Processing Subgroup (2009) · Bioinformatics · doi:10.1093/bioinformatics/btp352 · Cited by 62,041
Velvet: Algorithms for de novo short read assembly using de Bruijn graphsPreprint
Zerbino, D. R., & Birney, E. (2008) · Genome Research · doi:10.1101/gr.074492.107 · Cited by 9,587 · cited 1×
“Experimental search support for a limited number of raw reads is provided through De-Bruijn servers based on Velvet (9), using the Exonerate client-server protocol and being fully integrated with our search service.”
MethodAutomated generation of heuristics for biological sequence comparison
Slater, G., & Birney, E. (2005) · BMC Bioinformatics · doi:10.1186/1471-2105-6-31 · Cited by 2,959
The International Nucleotide Sequence Database Collaboration
Karsch‐Mizrachi, I., Nakamura, Y., & Cochrane, G. (2011) · Nucleic Acids Research · doi:10.1093/nar/gkr1006 · Cited by 717
Benson, D. A., Karsch‐Mizrachi, I., Lipman, D. J., Ostell, J., & Sayers, E. W. (2009) · Nucleic Acids Research · doi:10.1093/nar/gkp1024 · Cited by 348
Krause, J., Unger, T., Noçon, A., Malaspinas, A., Kolokotronis, S., Stiller, M., Soibelzon, L. H., Spriggs, H. F., Dear, P. H., Briggs, A. W., et al. (2008) · BMC Evolutionary Biology · doi:10.1186/1471-2148-8-220 · Cited by 288
The International Nucleotide Sequence Database Collaboration
Cochrane, G., Karsch‐Mizrachi, I., & Nakamura, Y. (2010) · Nucleic Acids Research · doi:10.1093/nar/gkq1150 · Cited by 113
DDBJ launches a new archive database with analytical tools for next-generation sequence data
Kaminuma, E., Mashima, J., Kodama, Y., Gojobori, T., Ogasawara, O., Okubo, K., Takagi, T., & Nakamura, Y. (2009) · Nucleic Acids Research · doi:10.1093/nar/gkp847 · Cited by 99 · cited 1×
“The ENA works closely together with NCBI (1) and DDBJ (2) as partners in the International Nucleotide Sequence Database Collaboration (3).”
MethodImprovements to services at the European Nucleotide Archive
Leinonen, R., Akhtar, R. A., Birney, E., Bonfield, J., Bower, L., Corbett, M., Cheng, Y., Demiralp, F., Faruque, N., Goodgame, N., et al. (2009) · Nucleic Acids Research · doi:10.1093/nar/gkp998 · Cited by 66 · cited 1×
“It contains a large diversity of data from patent, expressed sequence tag, whole genome shotgun and other high-throughput sequences, through genomic assemblies and richly annotated sequence fragments to whole replicons (5).”
BackgroundFast and efficient searching of biological data resources--using EB-eye
Valentin, F., Squizzato, S., Goujon, M., McWilliam, H., Paern, J., & López, R. (2010) · Briefings in Bioinformatics · doi:10.1093/bib/bbp065 · Cited by 37 · cited 1×
“Data can be queried using the EB-Eye free text search functionality available in the header section of all EBI web pages (7).”
Method
Cited by
Sorted by citations
Items 201–300 of 698
Seq2science: an end-to-end workflow for functional genomics analysis
van der Sande, M., Frölich, S., Schäfers, T., Smits, J. G. A., Snabel, R. R., Rinzema, S., & van Heeringen, S. J. (2023) · PeerJ · doi:10.7717/peerj.16380 · Cited by 28
“The download-fastq work fl ow can retrieve FASTQ fi les from various databases: the European Nucleotide Archive (ENA) ( Leinonen et al., 2010 ), Gene Expression Omnibus (GEO) ( Barrett et al., 2012 ), the Sequence Read Archive (SRA) ( Leinonen, Sugawara & Shumway, 2010 ), the DNA Data Bank of Japan…”
MethodPrabhakara, S., Khedkar, S., Shambat, S. M., Srinivasan, R., Basu, A., Norrby‐Teglund, A., Seshasayee, A. S. N., & Arakere, G. (2013) · PLoS ONE · doi:10.1371/journal.pone.0060013 · Cited by 28
“html [37], prophage database http:// ispc.”
Menie, M. A. W. O., Younuskunju, S., Balan, B., & Piffer, D. (2017) · Twin Research and Human Genetics · doi:10.1017/thg.2017.37 · Cited by 27
“Data on the ancient Holocene genomes were obtained from the European Nucleotide Archive (Leinonen et al., 2011) in the form of BAM files (accession number PRJEB9021).”
MethodEssential interpretations of bioinformatics in COVID-19 pandemic
Ray, M., Sable, M., Sarkar, S., & Hallur, V. (2020) · Meta Gene · doi:10.1016/j.mgene.2020.100844 · Cited by 28
Janker, L., Schuster, D., Bortel, P., Hagn, G., Meier, S. M., Mohr, T. T., Mader, J. C., Slany, A., Bileck, A., Brunmair, J., et al. (2023) · Journal of Crohn s and Colitis · doi:10.1093/ecco-jcc/jjad052 · Cited by 27
Sibai, M., Parlayan, C., Tuğlu, P., Öztürk, G., & Demircan, T. (2019) · Scientific Reports · doi:10.1038/s41598-019-56829-6 · Cited by 25
“gov/geo/) and the European Nucleotide Archive (ENA) database [51] (https://www.”
BackgroundCheng, L., Jin, J., He, X., Luo, Z., Wang, Z., Yang, J., & Xu, X. (2023) · Frontiers in Plant Science · doi:10.3389/fpls.2023.1164296 · Cited by 27
“, 2017b) were obtained from SRA database (Leinonen et al., 2011).”
HaploCart: Human mtDNA haplogroup classification using a pangenomic reference graph
Rubin, J. D., Vogel, N. A., Gopalakrishnan, S., Sackett, P. W., & Renaud, G. (2023) · PLoS Computational Biology · doi:10.1371/journal.pcbi.1011148 · Cited by 26
Development and Regulatory Application of Microrna Biomarkers
Krauskopf, J., Verheijen, M. C. T., Kleinjans, J. C. S., de Kok, T. M. C. M., & Caiment, F. (2015) · Biomarkers in Medicine · doi:10.2217/bmm.15.50 · Cited by 27
Denton, A. K., Maß, J., Külahoglu, C., Lercher, M. J., Bräutigam, A., & Weber, A. P. M. (2016) · Journal of Experimental Botany · doi:10.1093/jxb/erw463 · Cited by 27
“, 2012) and European nucleotide archives (Leinonen et al., 2010).”
Lactobacillus elicits a 'Marmite effect' on the chicken cecal microbiome
Zou, A., Sharif, S., & Parkinson, J. (2018) · npj Biofilms and Microbiomes · doi:10.1038/s41522-018-0070-5 · Cited by 27
Kazemian, M., Ren, M., Lin, J., Liao, W., Spolski, R. J., & Leonard, W. J. (2015) · Journal of Virology · doi:10.1128/jvi.00822-15 · Cited by 27
“gov/tools/vecscreen /univec/), phage sequences (13), and poly(A/C) sequences], or bacterial rRNA and/or genomic sequences (13).”
BackgroundMethodReid, A. M. A., Wilson, P. W., Caughey, S. D., Dixon, L., D’Eath, R. B., Sandilands, V., Boswell, T., & Dunn, I. (2017) · General and Comparative Endocrinology · doi:10.1016/j.ygcen.2017.07.002 · Cited by 26
Martínez, P. M., Appeldoorn, M. M., Gruppen, H., & Kabel, M. A. (2016) · Biotechnology for Biofuels · doi:10.1186/s13068-016-0519-9 · Cited by 26
Blumenfeld, A. L., & Jose, A. M. (2015) · RNA · doi:10.1261/rna.054551.115 · Cited by 25
“RNA-seq data sets (Supplemental Table S1) were obtained from the European Nucleotide Archive (Leinonen et al. 2011) using the Galaxy platform (Giardine et al. 2005; Blankenberg et al. 2010, 2014; Goecks et al. 2010) for biomedical research.”
Panjabi, P., Yadava, S. K., Kumar, N., Bangkim, R., & Ramchiary, N. (2019) · Springer eBooks · doi:10.1007/978-3-319-93536-2_6 · Cited by 25
Gabruk, M., & Myśliwa‐Kurdziel, B. (2020) · Biochemical Journal · doi:10.1042/bcj20200323 · Cited by 25
elPrep: High-Performance Preparation of Sequence Alignment/Map Files for Variant Calling
Herzeel, C., Costanza, P., Decap, D., Fostier, J., & Reumers, J. (2015) · PLoS ONE · doi:10.1371/journal.pone.0132868 · Cited by 25
Testing for Rare Variant Associations in the Presence of Missing Data
Auer, P. L., Wang, G. T., & Leal, S. M. (2013) · Genetic Epidemiology · doi:10.1002/gepi.21736 · Cited by 22
Identifying Regulatory Elements via Deep Learning
Barshai, M., Tripto, E., & Orenstein, Y. (2020) · Annual Review of Biomedical Data Science · doi:10.1146/annurev-biodatasci-022020-021940 · Cited by 25
“PBM data have been deposited and curated in the UniPROBE database (35), while HT-SELEX data are available through the European Nucleotide Archive (36).”
MethodDraft Genome Sequence of the Virulent Clostridium chauvoei Reference Strain JF4335
Falquet, L., Calderon-Copete, S. P., & Joachim Frey, A. (2013) · Genome Announcements · doi:10.1128/genomea.00593-13 · Cited by 24
“The draft genome sequence was annotated using a pipeline we developed (3) and was deposited at the European Nucleotide Archive (ENA) (4).”
MethodOM-FBA: Integrate Transcriptomics Data with Flux Balance Analysis to Decipher the Cell Metabolism
Guo, W., & Feng, X. (2016) · PLoS ONE · doi:10.1371/journal.pone.0154188 · Cited by 27
“, Gene Expression Omnibus (GEO)[34, 43–45], the European Bioinformatics Institute (EBI)[46, 47], and Many Microbe Microarrays Database (M3D)[48] for collecting gene expression data; and from the Proteomics DB[49] for collecting proteomics data.”
BackgroundBackbone Brackets and Arginine Tweezers delineate Class I and Class II aminoacyl tRNA synthetases
Kaiser, F., Bittrich, S., Salentin, S., Leberecht, C., Haupt, V. J., Krautwurst, S., Schroeder, M., & Labudde, D. (2018) · PLoS Computational Biology · doi:10.1371/journal.pcbi.1006101 · Cited by 23
Somboonna, N., Wilantho, A., Assawamakin, A., Monanunsap, S., Sangsrakru, D., Tangphatsornruang, S., & Tongsima, S. (2014) · BMC Genomics · doi:10.1186/1471-2164-15-607 · Cited by 23
“96.23% of the reliable reads could be identified by BLASTN against NCBI [23], RDP [1,24] and Greengenes [25] for 16S rRNA genes; and NCBI [23], EMBL [26,27] and SILVA [28] for 18S rRNA genes.”
InfluentialAbrudan, M. I., Matimba, A., Nikolic, D., Hughes, D., Argimón, S., Kekre, M., Underwood, A. P., Aanensen, D. M., Abudahab, K., Harste, H., et al. (2021) · Clinical Infectious Diseases · doi:10.1093/cid/ciab770 · Cited by 23
“Teaching Approaches Strategy Description Implementation Examples Challenge and problem-based tasks Problem-solving and decision-making exercises • Use card-based blueprint to order processes and procedures in a typical WGS for AMR surveillance pipeline • Use of fictive case scenarios involving training others in genom…”
Monir, M. M., Hossain, T., Morita, M., Ohnishi, M., Johura, F., Sultana, M., Monira, S., Ahmed, T., Thomson, N. R., Watanabe, H., et al. (2022) · Microbiology Spectrum · doi:10.1128/spectrum.00391-22 · Cited by 23
“In addition, 56 strains from our previous study (16) and 17 genomes from the European Nucleotide Archive (17) were used, which are representative of isolates from Bangladesh between 1991 and 2017 (Table S1).”
MethodThe International Cancer Genome Consortium's evolving data-protection policies
Milius, D., Dove, E. S., Chalmers, D., Dyke, S. O. M., Kato, K., Jiménez, P. N., Ouellette, B. F. F., Ozenberger, B., Rodriguez, L. L., Zeps, N., et al. (2014) · Nature Biotechnology · doi:10.1038/nbt.2926 · Cited by 23
JRC GMO-Amplicons: a collection of nucleic acid sequences related to genetically modified organisms
Petrillo, M., Angers‐Loustau, A., Henriksson, P., Bonfini, L., Patak, A., & Joachim, K. (2015) · Database · doi:10.1093/database/bav101 · Cited by 23
“1 (transgenic section of the ENA database) are identified when using these methods in a simultaneous query.”
BackgroundMethodInfluentialRaising orphans from a metadata morass: A researcher's guide to re-use of public ’omics data
Bhandary, P., Seetharam, A. S., Arendsee, Z. W., Hur, M., & Wurtele, E. S. (2017) · Plant Science · doi:10.1016/j.plantsci.2017.10.014 · Cited by 23
A hierarchy of environmental covariates control the global biogeography of soil bacterial richness
Bickel, S., Chen, X., Papritz, A., & Or, D. (2019) · Scientific Reports · doi:10.1038/s41598-019-48571-w · Cited by 25
Microbial Ecology of Thailand Tsunami and Non-Tsunami Affected Terrestrials
Somboonna, N., Wilantho, A., Jankaew, K., Assawamakin, A., Sangsrakru, D., Tangphatsornruang, S., & Tongsima, S. (2014) · PLoS ONE · doi:10.1371/journal.pone.0094236 · Cited by 23
“against 16S rDNA databases including NCBI non-redundant [28], RDP [29] and Greengenes [30], and for 18S rDNAs the databases included NCBI non-redundant [28], EMBL [31,32] and SILVA [33].”
MethodBogaerts, B., Braekel, J. V., Uffelen, A. V., D’aes, J., Godfroid, M., Delcourt, T., Kelchtermans, M., Milis, K., Goeders, N., Keersmaecker, S. C. J. D., et al. (2025) · BMC Genomics · doi:10.1186/s12864-024-11182-5 · Cited by 21
Patterns of Conservation and Diversification in the Fungal Polarization Network
Diepeveen, E. T., Gehrmann, T., Pourquié, V., Abeel, T., & Laan, L. (2018) · Genome Biology and Evolution · doi:10.1093/gbe/evy121 · Cited by 22
Kaushik, A., Roberts, D. P., Ramaprasad, A., Mfarrej, S., Nair, M. B., Lakshman, D. K., & Pain, A. (2022) · Frontiers in Microbiology · doi:10.3389/fmicb.2022.839524 · Cited by 22
Caprari, S., Metzler, S., Lengauer, T., & Kalinina, O. V. (2015) · Viruses · doi:10.3390/v7102882 · Cited by 22
“The corresponding nucleotide sequences were retrieved from ENA [31], and their GCcontent was analyzed using CodonW [32].”
MethodEmerging pathogens in the fish farming industry and sequencing-based pathogen discovery
Tengs, T., & Rimstad, E. (2017) · Developmental & Comparative Immunology · doi:10.1016/j.dci.2017.01.025 · Cited by 22
Landscape of the long non-coding RNA transcriptome in human heart
Jiang, C., Ding, N., Li, J., Jin, X., Li, X., Pan, T., Huo, C., Li, Y., Xu, J., & Li, X. (2018) · Briefings in Bioinformatics · doi:10.1093/bib/bby052 · Cited by 22
Staley, C. M., & Sadowsky, M. J. (2018) · Journal of Microbiological Methods · doi:10.1016/j.mimet.2018.09.020 · Cited by 22
Dyson, C. J., & Goodisman, M. A. D. (2020) · Molecular Biology and Evolution · doi:10.1093/molbev/msaa088 · Cited by 21
FAIRness and Usability for Open-access Omics Data Systems.
Berrios, D. C., Beheshti, A., & Costes, S. V. (2018) · Europe PMC (PubMed Central) · Cited by 21
Lin, Q., Xavier, B. B., Alako, B., Mitchell, A., Rajakani, S. G., Glupczynski, Y., Finn, R. D., Cochrane, G., & Malhotra‐Kumar, S. (2022) · Communications Biology · doi:10.1038/s42003-022-04187-x · Cited by 21
The use of different 16S rRNA gene variable regions in biogeographical studies
Varliero, G., Lebre, P. H., Stevens, M. I., Czechowski, P., Makhalanyane, T. P., & Cowan, D. A. (2023) · Environmental Microbiology Reports · doi:10.1111/1758-2229.13145 · Cited by 21
V-pipe 3.0: a sustainable pipeline for within-sample viral genetic diversity estimation
Fuhrmann, L., Jablonski, K. P., Topolsky, I., Batavia, A. A., Borgsmüller, N., Baykal, P. I., Carrara, M., Chen, C., Dondi, A., Dragan, M., et al. (2024) · GigaScience · doi:10.1093/gigascience/giae065 · Cited by 20
Biological and Chemical Databases for Research into the Composition of Animal Source Foods
Mińkiewicz, P., Miciński, J., Darewicz, M., & Bucholska, J. (2013) · Food Reviews International · doi:10.1080/87559129.2013.818011 · Cited by 21
“(12,63,64) The European Molecular Biology Laboratory (EMBL) Nucleotide Sequence Database is a part of the European Nucleotide Archive (ENA).(28,29) The database is kept by the European Bioinformatics Institute (EBI) in Hinxton, UK, a member of EMBL.”
BackgroundThe Risa R/Bioconductor package: integrative data analysis from experimental metadata and back again
Gonzalez-Beltran, A. N., Neumann, S., Maguire, E., Sansone, S., & Rocca‐Serra, P. (2014) · BMC Bioinformatics · doi:10.1186/1471-2105-15-s1-s11 · Cited by 21
“ISA supports the move from paper-based laboratory notebooks to a spreadsheet-like tabular format, which can be converted automatically to the formats required by existing public repositories such as ArrayExpress [7], the European Nucleotide Archive (ENA) [8] and the Proteomics Identification Database (PRIDE) [9].”
MethodMorata, J., & Puigdomènech, P. (2017) · BMC Genomics · doi:10.1186/s12864-017-3529-5 · Cited by 21
Zinno, P., Motta, V., Guantario, B., Natella, F., Roselli, M., Bello, C., Comitato, R., Carminati, D., Tidona, F., Meucci, A., et al. (2019) · European Journal of Nutrition · doi:10.1007/s00394-019-01911-y · Cited by 21
Andersen, V. D., Aarestrup, F. M., Munk, P., Jensen, M. S., de Knegt, L., Bortolaia, V., Knudsen, B. E., Lukjančenko, O., Birkegård, A. C., & Vigre, H. (2019) · Preventive Veterinary Medicine · doi:10.1016/j.prevetmed.2019.104853 · Cited by 21
Challenges in Clinicogenetic Correlations: One Phenotype – Many Genes
Gannamani, R., van der Veen, S., van Egmond, M. E., de Koning, T. J., & Tijssen, M. A. J. (2021) · Movement Disorders Clinical Practice · doi:10.1002/mdc3.13163 · Cited by 21
“expression (RNA sequencing) big data.(77) The underlying hypothesis is that genes showing similar expression patterns, that is, “coexpressed” or “coregulated” genes, likely act on similar molecular pathways and have similar biological functions.”
BackgroundLarge-scale labeling and assessment of sex bias in publicly available expression data
Flynn, E., Chang, A., & Altman, R. B. (2021) · BMC Bioinformatics · doi:10.1186/s12859-021-04070-2 · Cited by 21
Gide, T. N., da Silva, I. P., Quek, C. Y. J., Ferguson, P. M., Batten, M., Shang, P., Ahmed, T., Menzies, A. M., Carlino, M. S., Saw, R. P. M., et al. (2021) · Cancers · doi:10.3390/cancers13133186 · Cited by 21
“Data Availability Statement: The targeted RNA sequencing data presented in this study are available in the European Nucleotide Archive (ENA) [42], under accession number PRJEB45846.”
MethodArtificial Intelligence in Infectious Disease Diagnostic Technologies
Dong, C., Liu, Y., Nie, J., Zhang, X., Yu, F., & Zhou, Y.-F. (2025) · Diagnostics · doi:10.3390/diagnostics15202602 · Cited by 27
“Recent enhancements such as the Pathogens Portal and a tagging system further improve data discoverability and facilitate AI-based identification of pathogenic organisms within complex microbial communities [67–69].”
Steward, C. A., González, J. M., Trevanion, S. J., Sheppard, D., Kerry, G., Gilbert, J. G. R., Wicker, L. S., Rogers, J., & Harrow, J. (2013) · Database · doi:10.1093/database/bat032 · Cited by 20
Databases: A Weapon from the Arsenal of Bioinformatics for Plant Abiotic Stress Research
Anamika, A., Mehta, S., Singh, B. P., Patra, A., & Islam, M. A. (2019) · Springer eBooks · doi:10.1007/978-3-030-21687-0_7 · Cited by 20
Balech, B., Sandionigi, A., Marzano, M., Pesole, G., & Santamaría, M. (2022) · Database · doi:10.1093/database/baab084 · Cited by 20
“The most used public resources of animals’ COXI sequences are the Barcode of Life Data System (BOLD) (15) and the primary molecular data resources, such as the European Nucleotide Archive (ENA) (16).”
BackgroundKazemian, M., Ren, M., Lin, J., Liao, W., Spolski, R. J., & Leonard, W. J. (2015) · Molecular Systems Biology · doi:10.15252/msb.156172 · Cited by 20
“…and human ribosomal RNA sequences); abundant sequences (vector sequences [http:// www.ncbi.nlm.nih.gov/tools/vecscreen/univec/]; phage sequences (Leinonen et al, 2011); and polyA/C sequences), bacterial rRNA sequences (Cole et al, 2005), and bacterial and viral genomic sequences (Leinonen et…”
Identification of Small Novel Coding Sequences, a Proteogenomics Endeavor
Olexiouk, V., & Menschaert, G. (2016) · Advances in experimental medicine and biology · doi:10.1007/978-3-319-42316-6_4 · Cited by 19
Eckes-Shephard, A. H., Gubała, T., Nowakowski, P., Szymczyszyn, T., Wells, R., Irwin, J. A., Horro, C., Hancock, J. M., King, G. J. W., Dyer, S. C., et al. (2017) · F1000Research · doi:10.12688/f1000research.11301.1 · Cited by 20
Zhang, Q., Yang, B., Chen, X., Xu, J., Mei, C., & Mao, Z. (2014) · Database · doi:10.1093/database/bau092 · Cited by 20
“For RNA-seq experiments, the raw reads data were retrieved from the European Nucleotide Archive (10).”
MethodElucidating the functional roles of prokaryotic proteins using big data and artificial intelligence
Ardern, Z., Chakraborty, S., Lenk, F., & Kaster, A. (2023) · FEMS Microbiology Reviews · doi:10.1093/femsre/fuad003 · Cited by 22
Price, E., Feyertag, F., Evans, T. G., Miskin, J., Mitrophanous, K. A., & Dikicioǧlu, D. (2024) · Nucleic Acids Research · doi:10.1093/nar/gkae901 · Cited by 21
Ten simple rules for annotating sequencing experiments
Stevens, I., Mukarram, A. K., Hörtenhuber, M., Meehan, T. F., Rung, J., & Daub, C. O. (2020) · PLoS Computational Biology · doi:10.1371/journal.pcbi.1008260 · Cited by 18
“For data that are not personally identifiable, the NCBI SRA [30], the European Nucleotide Archive (ENA) [31], and the DNA Databank of Japan [32] make biological sequence data available to the research community.”
BackgroundMeumann, E. M., Globan, M., Fyfe, J., Leslie, D. E., Porter, J. L., Seemann, T., Denholm, J. T., & Stinear, T. P. (2015) · Microbial Genomics · doi:10.1099/mgen.0.000037 · Cited by 19
The evolution of computational research in a data-centric world
Deshpande, D., Chhugani, K., Ramesh, T., Pellegrini, M. A., Shifman, S., Abedalthagafi, M., Alqahtani, S. A., Ye, C., Liu, X. S., Leek, J. T., et al. (2024) · Cell · doi:10.1016/j.cell.2024.07.045 · Cited by 23
Han, J., Zhang, H., & Ning, K. (2024) · Briefings in Bioinformatics · doi:10.1093/bib/bbaf015 · Cited by 20
“These efforts have led to the deposition of extensive datasets in various databases, such as the European Nucleotide Archive (ENA) [12], EBI Metagenomics [13], and the National Microbiome Data Center [14].”
CistromeFinder for ChIP-seq and DNase-seq data reuse
Sun, H., Qin, B., Liu, T., Wang, Q., Liu, J., Wang, J., Lin, X., Yang, Y., Taing, L., Rao, P. K., et al. (2013) · Bioinformatics · doi:10.1093/bioinformatics/btt135 · Cited by 18
“Genome-wide mapping of transcription factor and chromatin regulator binding, histone modifications and chromatin accessibility is essential for elucidating the regulatory network of various biological processes.”
Mészáros, B., Hatos, A., Palópoli, N., Quaglia, F., Salladini, E., Roey, K. V., Arthanari, H., Dosztányi, Z., Felli, I. C., Fischer, P. D., et al. (2023) · Nature Methods · doi:10.1038/s41592-023-01915-x · Cited by 20
Falquet, L., Liljander, A., Schieck, E., Gluecks, I., Joachim Frey, A., & Jores, J. (2014) · Genome Announcements · doi:10.1128/genomea.01041-14 · Cited by 18
“Sequences were deposited at the European Nucleotide Archive under accession numbers LN515398 and LN515399 for the genomes of F38 and ILRI181, respectively.”
MethodDetection of atypical genes in virus families using a one-class SVM
Metzler, S., & Kalinina, O. V. (2014) · BMC Genomics · doi:10.1186/1471-2164-15-913 · Cited by 18
“We consider all viral genes from ENA, the European Nucleotide Archive [24], downloaded in July 2013.”
MethodDiallo, K., Gamougam, K., Daugla, D. M., Harrison, O. B., Bray, J. E., Caugant, D. A., Lucidarme, J., Trotter, C. L., Hassan-King, M., Stuart, J. M., et al. (2017) · BMC Genomics · doi:10.1186/s12864-017-3789-0 · Cited by 18
Gualandi, N., Iperi, C., Esposito, M., Ansaloni, F., Gustincich, S., & Sanges, R. (2022) · Biology · doi:10.3390/biology11060826 · Cited by 18
“Raw fastq files were downloaded from the ENA-EBI database (accession codes: PRJEB3366, PRJNA420729, and PRJNA599420) and the quality of the reads was assessed using FastQC [38,39].”
MethodXiao, W., Wu, L., Yavaş, G., Simonyan, V. V., Ning, B., & Hong, H. (2016) · Pharmaceutics · doi:10.3390/pharmaceutics8020015 · Cited by 17
“More individual genomes (e.g., NA18507, Korean AK1, and NA12878) were generated and compared to the reference genome and alternative genomes [34–36].”
MethodInfluentialCicerTransDB 1.0: a resource for expression and functional study of chickpea transcription factors
Gayali, S., Acharya, S., Lande, N. V., Pandey, A., Chakraborty, S., & Chakraborty, N. (2016) · BMC Plant Biology · doi:10.1186/s12870-016-0860-y · Cited by 17
“The website also holds many single-click interfaces to connect to other third party webservers that include motif analysis in PlantPAN [21] and PlantCare [22], gene blast at NCBI [14] and ENA [23], as well as localization prediction at Yloc + [24].”
MethodAccessing Cryptosporidium Omic and Isolate Data via CryptoDB.org
On Behalf of the EuPathDB Team, Warrenfeltz, S. W., & Kissinger, J. C. (2019) · Methods in molecular biology · doi:10.1007/978-1-4939-9748-0_10 · Cited by 17
VARUS: sampling complementary RNA reads from the sequence read archive
Stanke, M., Bruhn, W., Becker, F., & Hoff, K. J. (2019) · BMC Bioinformatics · doi:10.1186/s12859-019-3182-x · Cited by 18
The challenges of delivering bioinformatics training in the analysis of high-throughput data
Carvalho, B. S., & Rustici, G. (2013) · Briefings in Bioinformatics · doi:10.1093/bib/bbt018 · Cited by 19
Direct targeting and regulation of RNA polymerase II by cell signaling kinases
Dabas, P., Cutrona, M. B., Rosikiewicz, W., Kempen, R. P., Rodrigues, P., Bowling, J. J., Prater, M. S., Lang, W. H., Danda, A., Zhi, Y., et al. (2025) · Science · doi:10.1126/science.ads7152 · Cited by 18
The on-premise data sharing infrastructure e!DAL: Foster FAIR data for faster data acquisition
Arend, D., König, P., Junker, A., Scholz, U., & Lange, M. (2020) · GigaScience · doi:10.1093/gigascience/giaa107 · Cited by 16
“Most of them evolved over many years, and they are widely accepted by the research community [26]: ENA for genomic data [27], UniProt for protein data [28], PRIDE for proteome data [29], BioModels for systems biology data [30], and many more.”
Molecular and computational approaches to map regulatory elements in 3D chromatin structure
Lee, B. H., & Rhie, S. K. (2021) · Epigenetics & Chromatin · doi:10.1186/s13072-021-00390-y · Cited by 17
Music of metagenomics—a review of its applications, analysis pipeline, and associated tools
Wajid, B., Anwar, F., Wajid, I., Nisar, H., Meraj, S., Zafar, A., AlShawaqfeh, M. K., Ekti, A. R., Khatoon, A., & Suchodolski, J. S. (2021) · Functional & Integrative Genomics · doi:10.1007/s10142-021-00810-y · Cited by 16
Ziemski, M., Adamov, A., Kim, L., Flörl, L., & Bokulich, N. A. (2022) · Bioinformatics · doi:10.1093/bioinformatics/btac639 · Cited by 18
Advances in the field of phage-based therapy with special emphasis on computational resources
Bajiya, N., Dhall, A., Aggarwal, S., & Raghava, G. P. S. (2022) · Briefings in Bioinformatics · doi:10.1093/bib/bbac574 · Cited by 16
Baletaud, F., Lecellier, G. J., Gilbert, A., Mathon, L., Côme, J.-M., Déjean, T., Dumas, M., Fiat, S., & Vigliola, L. (2023) · Biology · doi:10.3390/biology12111446 · Cited by 17
“We used chlorophyll-a, suspended particulate matter, salinity, and current from the Global Ocean Satellite Observations (Copernicus—CMEMS).”
The Annotation-enriched non-redundant patent sequence databases
Li, W., Kondratowicz, B., McWilliam, H., Nauche, S., & López, R. (2013) · Database · doi:10.1093/database/bat005 · Cited by 16
“The patent sequence data deposited to ENA (7), GenBank (8) or the DDBJ (9) are exchanged between these databases through the International Nucleotide Sequence Database Collaboration (Figure 2a).”
MethodK-Means Clustering of Biological Sequences
Chappell, T., Geva, S., & Hogan, J. M. (2017) · Australasian Document Computing Symposium · doi:10.1145/3166072.3166076 · Cited by 16
“For this study we have chosen to use ERR000001 [12], the (lexicographically) first submission package stored in the European Nucleotide Archive [13].”
MethodCao, Y., Xu, X., Kitanovski, S., Song, L., Wang, J., Hao, P., & Hoffmann, D. E. (2021) · Frontiers in Immunology · doi:10.3389/fimmu.2021.656433 · Cited by 17
Systems biology of acidophile biofilms for efficient metal extraction
Buetti‐Dinh, A., Herold, M., Christel, S., Hajjami, M. E., Bellenberg, S., Ilie, O., Wilmes, P., Poetsch, A., Sand, W., Vera, M. A., et al. (2020) · Scientific Data · doi:10.1038/s41597-020-0519-2 · Cited by 16
Yan, Y., Zhao, X., Liang, X., Xue, Y., Niu, Q., Dong, L., Zhou, X., Li, Y., Dong, S., & Gai, Y. (2025) · mSystems · doi:10.1128/msystems.01428-24 · Cited by 15
“Initially, we screened the ENA using specific keywords to identify potential data sets related to wastewater samples, metagenomics, and environmental microbiota.”
Tourab, H., Lopez-Perez, L., Arroyo, P., Georga, E. I., Rujas, M., Ponziani, F. R., Torrego-Ellacuría, M., Barbancho, B. M., Dei, N. N., Ciuti, G., et al. (2025) · IEEE Journal of Biomedical and Health Informatics · doi:10.1109/jbhi.2025.3593198 · Cited by 18
Mou, Z., Spencer, J., McGrath, J. S., & Harries, L. W. (2023) · Human Genomics · doi:10.1186/s40246-023-00545-w · Cited by 15
“The third dataset, generated by Illumina HiSeq 2000, consists of 14 PCa tumour and 14 matched normal samples [25] and was obtained from the European Nucleotide Archive (ENA) [26] using fastq-dl [27] under the accession number PRJEB2449.”
MethodTranscriptomic meta-analysis to identify potential antifungal targets in Candida albicans
Hefny, Z. A., Ji, B., Elsemman, I. E., Nielsen, J., & Dijck, P. V. (2024) · BMC Microbiology · doi:10.1186/s12866-024-03213-8 · Cited by 17
Online Tools for Bioinformatics Analyses in Nutrition Sciences
Malkaram, S. A., Hassan, Y. I., & Zempleni, J. (2012) · Advances in Nutrition · doi:10.3945/an.112.002477 · Cited by 16
“The Protein Data Bank at 40: reflecting on the past to prepare for the future.”
BackgroundInfluentialBacterial Whole-Genome Determination and Applications
He, Y. O. (2014) · Elsevier eBooks · doi:10.1016/b978-0-12-397169-2.00020-2 · Cited by 15
Computational Prediction of RNA-Protein Interactions
Mann, C. M., Muppirala, U. K., & Dobbs, D. L. (2017) · Methods in molecular biology · doi:10.1007/978-1-4939-6716-2_8 · Cited by 15
Nfeature: A platform for computing features of nucleotide sequencesPreprint
Mathur, M., Patiyal, S., Dhall, A., Jain, S., Tomer, R., Arora, A., & Raghava, G. P. S. (2021) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2021.12.14.472723 · Cited by 15
“In recent years, the amount of available biological sequence data has increased exponentially due to the significant increase in genome sequencing projects [1-8].”
BackgroundMartiny, H.-M., Munk, P., Brinch, C., Aarestrup, F. M., Calle, M. L., & Petersen, T. N. (2024) · Microbiology Spectrum · doi:10.1128/spectrum.04108-23 · Cited by 14
Tan, Q. W., & Mutwil, M. (2019) · Biochimica et Biophysica Acta (BBA) - Gene Regulatory Mechanisms · doi:10.1016/j.bbagrm.2019.194429 · Cited by 13
Seeing the forest through the trees: prioritising potentially functional interactions from Hi-C
Liu, N., Low, W. Y., Alinejad‐Rokny, H., Pederson, S., Sadlon, T. J., Barry, S. C., & Breen, J. (2021) · Epigenetics & Chromatin · doi:10.1186/s13072-021-00417-4 · Cited by 16
Diez-Pinel, G., Horder, J. L., King, J. R., McIntyre, A., Mongan, N. P., Goméz-López, G., & Benest, A. V. (2022) · Methods in molecular biology · doi:10.1007/978-1-0716-2059-5_29 · Cited by 14
A practical assembly guideline for genomes with various levels of heterozygosity
Mochizuki, T., Sakamoto, M., Tanizawa, Y., Nakayama, T., Tanifuji, G., Kamikawa, R., & Nakamura, Y. (2023) · Briefings in Bioinformatics · doi:10.1093/bib/bbad337 · Cited by 14
“Their PacBio subreads and Illumina paired-end data of whole-genome sequencing were downloaded from the public archive Sequence Read Archive of European Nucleotide Archive (ENA) [39] (Table 1).”
Method
Metadata
- Authors
- Leinonen, R., Akhtar, R., Birney, E., Bower, L., Cerdeno-Tarraga, A., Cheng, Y., Cleland, I., Faruque, N., Goodgame, N., Gibson, R., Hoad, G., Jang, M., Pakseresht, N., Plaister, S., Radhakrishnan, R., Reddy, K., Sobhany, S., Ten Hoopen, P., Vaughan, R., Zalunin, V., & Cochrane, G.
- Affiliations
- European Bioinformatics Institute (GB)
- Corresponding author
- Leinonen, R.
- ORCID
- Venue
- Nucleic Acids Research
- Publisher
- Oxford University Press (OUP)
- Published
- 2010-10-23
- Volume
- 39
- Issue
- Database
- Pages
- D28-D31
- ISSN
- 0305-1048 (ISSN-L)
- 1362-4962
- PMC
- PMC3013801
- OpenAlex
- W2120358246
- Cited by
- 690
- References
- 10
- Citations by year
- 2026: 37 · 2025: 49 · 2024: 74 · 2023: 52 · 2022: 44 · 2021: 64 · 2020: 37 · 2019: 42 · 2018: 41 · 2017: 47 · 2016: 39 · 2015: 48 · 2014: 33 · 2013: 31 · 2012: 23
- FWCI
- 10.60
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Nucleic Acids Research (publishedVersion, cc-by-nc)
- PubMed Central (publishedVersion, cc-by-nc)
- PubMed (publishedVersion)
- Funders
- Wellcome Trust (085532)
- European Molecular Biology Laboratory
- European Commission
- Topics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Genomics and Phylogenetic Studies
- Physical Sciences › Computer Science › Information Systems › Research Data Management Practices
- Social Sciences › Decision Sciences › Information Systems and Management › Scientific Computing and Data Management
- Keywords
- European Nucleotide Archive, Sequence Read Archive, DNA sequence databases, sequence similarity search, European Genome-phenome Archive
- MeSH terms
- Base Sequence, Europe, Databases, Nucleic Acid, Molecular Sequence Annotation, High-Throughput Nucleotide Sequencing
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
