

The DOI matches its Crossref record; 10 of the 10 references it cites were found in a registry or an index.
The European Nucleotide Archive
Open accessAbstract
The European Nucleotide Archive (ENA; http://www.ebi.ac.uk/ena) is Europe's primary nucleotide-sequence repository. The ENA consists of three main databases: the Sequence Read Archive (SRA), the Trace Archive and EMBL-Bank. The objective of ENA is to support and promote the use of nucleotide sequencing as an experimental research platform by providing data submission, archive, search and download services. In this article, we outline these services and describe major changes and improvements introduced during 2010. These include extended EMBL-Bank and SRA-data submission services, extended ENA Browser functionality, support for submitting data to the European Genome-phenome Archive (EGA) through SRA, and the launch of a new sequence similarity search service.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
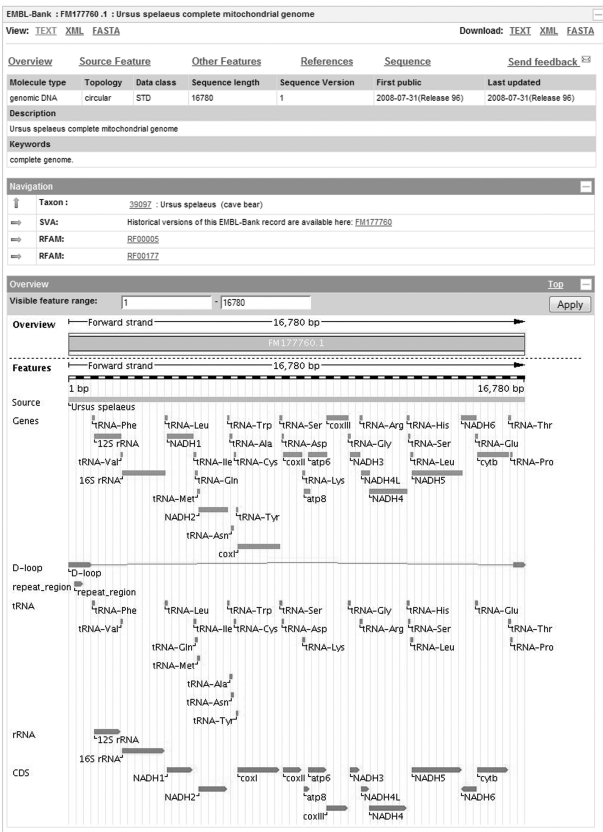
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Tools such as DIGIT and Abysis source their data from the European Nucleotide Archive (ENA) [60] and the National Center for Biotechnology Information (NCBI) [61]; their sequence volumes are of the order of 105 and contain multiple artificially engineered sequences.”
From Computational approaches to therapeutic antibody design: established methods and emerging trends (2020) · cites this paper as [60]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The Sequence Alignment/Map format and SAMtools
Li, H., Handsaker, B., Wysoker, A., Fennell, T., Ruan, J., Homer, N., Marth, G., Abecasis, G., Durbin, R., & 1000 Genome Project Data Processing Subgroup (2009) · Bioinformatics · doi:10.1093/bioinformatics/btp352 · Cited by 62,041
Velvet: Algorithms for de novo short read assembly using de Bruijn graphsPreprint
Zerbino, D. R., & Birney, E. (2008) · Genome Research · doi:10.1101/gr.074492.107 · Cited by 9,587 · cited 1×
“Experimental search support for a limited number of raw reads is provided through De-Bruijn servers based on Velvet (9), using the Exonerate client-server protocol and being fully integrated with our search service.”
MethodAutomated generation of heuristics for biological sequence comparison
Slater, G., & Birney, E. (2005) · BMC Bioinformatics · doi:10.1186/1471-2105-6-31 · Cited by 2,959
The International Nucleotide Sequence Database Collaboration
Karsch‐Mizrachi, I., Nakamura, Y., & Cochrane, G. (2011) · Nucleic Acids Research · doi:10.1093/nar/gkr1006 · Cited by 717
Benson, D. A., Karsch‐Mizrachi, I., Lipman, D. J., Ostell, J., & Sayers, E. W. (2009) · Nucleic Acids Research · doi:10.1093/nar/gkp1024 · Cited by 348
Krause, J., Unger, T., Noçon, A., Malaspinas, A., Kolokotronis, S., Stiller, M., Soibelzon, L. H., Spriggs, H. F., Dear, P. H., Briggs, A. W., et al. (2008) · BMC Evolutionary Biology · doi:10.1186/1471-2148-8-220 · Cited by 288
The International Nucleotide Sequence Database Collaboration
Cochrane, G., Karsch‐Mizrachi, I., & Nakamura, Y. (2010) · Nucleic Acids Research · doi:10.1093/nar/gkq1150 · Cited by 113
DDBJ launches a new archive database with analytical tools for next-generation sequence data
Kaminuma, E., Mashima, J., Kodama, Y., Gojobori, T., Ogasawara, O., Okubo, K., Takagi, T., & Nakamura, Y. (2009) · Nucleic Acids Research · doi:10.1093/nar/gkp847 · Cited by 99 · cited 1×
“The ENA works closely together with NCBI (1) and DDBJ (2) as partners in the International Nucleotide Sequence Database Collaboration (3).”
MethodImprovements to services at the European Nucleotide Archive
Leinonen, R., Akhtar, R. A., Birney, E., Bonfield, J., Bower, L., Corbett, M., Cheng, Y., Demiralp, F., Faruque, N., Goodgame, N., et al. (2009) · Nucleic Acids Research · doi:10.1093/nar/gkp998 · Cited by 66 · cited 1×
“It contains a large diversity of data from patent, expressed sequence tag, whole genome shotgun and other high-throughput sequences, through genomic assemblies and richly annotated sequence fragments to whole replicons (5).”
BackgroundFast and efficient searching of biological data resources--using EB-eye
Valentin, F., Squizzato, S., Goujon, M., McWilliam, H., Paern, J., & López, R. (2010) · Briefings in Bioinformatics · doi:10.1093/bib/bbp065 · Cited by 37 · cited 1×
“Data can be queried using the EB-Eye free text search functionality available in the header section of all EBI web pages (7).”
Method
Cited by
Sorted by citations
Items 301–400 of 698
Addition of soluble fiber to standard purified diets is important for gut morphology in mice
von Süßkind‐Schwendi, M., Dötsch, A., Haberland, V., Ferrario, P. G., Krüger, R., Louis, S., Döring, M., & Gräf, D. (2023) · Scientific Reports · doi:10.1038/s41598-023-46331-5 · Cited by 15
Kim, M., Jung, D.-R., Lee, J.-M., Kim, I., Son, H., Kim, E. S., & Shin, J. (2023) · iScience · doi:10.1016/j.isci.2023.108657 · Cited by 14
A New RNA-Seq Method to Detect the Transcription and Non-coding RNA in Prostate Cancer
Zhang, X., Ma, Z., Wang, Q., Wang, J., Yang, J., Li, X., Li, H., & Men, T. (2013) · Pathology & Oncology Research · doi:10.1007/s12253-013-9618-0 · Cited by 14
“All those data is available on European Nucleotide Archive [13] (ENA; http:// www.”
MethodLi, G., Bankhead, P., Dunne, P. D., O’Reilly, P. G., James, J. A., Salto‐Tellez, M., Hamilton, P. W., & McArt, D. G. (2016) · Briefings in Bioinformatics · doi:10.1093/bib/bbw044 · Cited by 15
Genome-Scale Profiling Reveals Noncoding Loci Carry Higher Proportions of Concordant Data
Literman, R., & Schwartz, R. S. (2021) · Molecular Biology and Evolution · doi:10.1093/molbev/msab026 · Cited by 14
“For each clade, we obtained paired-end Illumina reads from the European Nucleotide Archive (Leinonen et al. 2011) for ten focal taxa and two outgroup taxa (Table S1).”
MethodGhosh, A., & Som, A. (2021) · Stem Cell Research · doi:10.1016/j.scr.2021.102334 · Cited by 14
Introduction to basics of bioinformatics
Pathak, R. K., Singh, D. B., & Singh, R. (2021) · Elsevier eBooks · doi:10.1016/b978-0-323-89775-4.00006-7 · Cited by 14
Fungal genome resources at NCBI
Robbertse, B., & Tatusova, T. A. (2011) · Mycology: An International Journal on Fungal Biology · doi:10.1080/21501203.2011.584576 · Cited by 14
“…which receives data through international collaboration (INSDC: http: // www.insdc.org / ) with the DNA databank of Japan (DDBJ) (Kaminuma et al. 2011) and the European Nucleotide Archive (ENA) (Leinonen et al. 2011a) as well as from large sequencing centers and individual researchers worldwide.”
BackgroundBioinformatics: Concepts, Methods, and Data
Robinson, S. W., Afzal, A. M., & Leader, D. P. (2014) · Elsevier eBooks · doi:10.1016/b978-0-12-386882-4.00013-x · Cited by 19
Singh, R., Dillon, J. R., Demczuk, W., & KUSALIK, A. J. (2019) · BMC Genomics · doi:10.1186/s12864-019-5542-3 · Cited by 14
An α/β-Hydrolase Fold Subfamily Comprising Pseudomonas Quinolone Signal-Cleaving Dioxygenases
Wullich, S. C., Martín, A. A. S., & Fetzner, S. (2020) · Applied and Environmental Microbiology · doi:10.1128/aem.00279-20 · Cited by 13
“aENA IDs (European Nucleotide Archive [63]) of the genes are given.”
BackgroundLSTrAP-Cloud: A User-Friendly Cloud Computing Pipeline to Infer Coexpression Networks
Tan, Q. W., Goh, W., & Mutwil, M. (2020) · Genes · doi:10.3390/genes11040428 · Cited by 14
“The pipeline (Figure 1), Large-Scale Transcriptome Analysis Pipeline in Cloud (LSTrAP-Cloud), takes the CDS of the organism of interest, and streams the list of RNA-seq experiments specified by the user from ENA.”
MethodFilTar: using RNA-Seq data to improve microRNA target prediction accuracy in animals
Bradley, T., & Moxon, S. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btaa007 · Cited by 13
Späth, G. F., & Bussotti, G. (2021) · Nucleic Acids Research · doi:10.1093/nar/gkab1237 · Cited by 15
“WGS reads were downloaded from the Sequence Read Archive (SRA) (33), the European Nucleotide Archive (ENA) (34) repositories and the Encyclopedia of DNA El-ements (ENCODE) dashboard (35) (Supplementary Table S1).”
MethodGenome-wide methylation patterns from canine nanopore assemblies
Schall, P. Z., Winkler, P. A., Petersen‐Jones, S. M., Yuzbasiyan‐Gurkan, V., & Kidd, J. M. (2023) · G3 Genes Genomes Genetics · doi:10.1093/g3journal/jkad203 · Cited by 14
“For comparison of the ONT-based sequencing, the European Nucleotide Archive (RRID:SCR_006515) (Leinonen et al. 2011) was queried for canine methylation sequencing.”
MethodRNA-Rocket: an RNA-Seq analysis resource for infectious disease research
Warren, A. S., Aurrecoechea, C., Brunk, B. P., Desai, P., Emrich, S., Giraldo-Calderón, G. I., Harb, O. S., Hix, D., Lawson, D., Machi, D., et al. (2015) · Bioinformatics · doi:10.1093/bioinformatics/btv002 · Cited by 13
Rules Governing the Mechanism of Epigenetic Reprogramming Memory
Luu, P., Daniela Gerovska, D., Schöler, H. R., & Araúzo-Bravo, M. J. (2018) · Epigenomics · doi:10.2217/epi-2017-0098 · Cited by 13
The effect of non-linear signal in classification problems using gene expression
Heil, B. J., Crawford, J., & Greene, C. S. (2023) · PLoS Computational Biology · doi:10.1371/journal.pcbi.1010984 · Cited by 13
A catalog of hemizygous variation in 127 22q11 deletion patients
Hestand, M. S., Nowakowska, B., Vergaelen, E., Houdt, J. V., Dehaspe, L., Suhl, J. A., Del‐Favero, J., Mortier, G. R., Zackai, E. H., Swillen, A., et al. (2016) · Human Genome Variation · doi:10.1038/hgv.2015.65 · Cited by 13
Integrating Computational Methods to Investigate the Macroecology of Microbiomes
Mascarenhas, R., Ruziska, F. M., Moreira, E. F., Campos, A. B., Loiola, M., Reis, K. W., Silva, A. E. T., Barbosa, F. A. S., Salles, L. D. Q., Menezes, R., et al. (2020) · Frontiers in Genetics · doi:10.3389/fgene.2019.01344 · Cited by 14
“…data are the NCBI short read archive (SRA; Leinonen et al., 2011b), MG-RAST (Meyer et al., 2008) and the European Nucleotide Archive (ENA; Leinonen et al., 2011a), some of which also provide bioinformatics tools for taxonomic annotation and statistical analysis (e.g., MG-RAST and MGnify;…”
MethodMartiny, H.-M., Munk, P., Brinch, C., Aarestrup, F. M., & Petersen, T. N. (2022) · PLoS Biology · doi:10.1371/journal.pbio.3001792 · Cited by 13
“By collecting the sequencing reads from ENA, we could also verify the inherited bias of specific sample types or sources being overrepresented simply due to the availability in the public repository.”
BackgroundMethodInfluentialMicrobial communities in the reef water at Kham Island, lower Gulf of Thailand
Somboonna, N., Wilantho, A., Monanunsap, S., Chavanich, S. A., Tangphatsornruang, S., & Tongsima, S. (2017) · PeerJ · doi:10.7717/peerj.3625 · Cited by 13
“, 2010), EMBL (Leinonen et al., 2011) and SILVA (Pruesse et al.”
MethodREADv2: Advanced and user-friendly detection of biological relatedness in archaeogenomicsPreprint
Alaçamlı, E., Naidoo, T., Aktürk, Ş., Güler, M. N., Mapelli, I., Vural, K. B., Somel, M., Malmström, H., & Günther, T. (2024) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2024.01.23.576660 · Cited by 13
Srikakulam, S. K., Keller, S., Dabbaghie, F., Bals, R., & Kalinina, O. V. (2023) · Bioinform. · doi:10.1093/bioinformatics/btad101 · Cited by 12
Rodríguez-Leal, S., Silva-Acosta, J., Marzialetti, T. G., & Gallardo-Rodríguez, J. J. (2023) · Journal of Applied Phycology · doi:10.1007/s10811-023-02981-6 · Cited by 12
“2008), ENA (Leinonen et al.”
Mathon, L., Baletaud, F., Lebourges‐Dhaussy, A., Lecellier, G. J., Menkès, C., Bachelier, C., Bonneville, C. D., Déjean, T., Dumas, M., Fiat, S., et al. (2024) · Conservation Biology · doi:10.1111/cobi.14368 · Cited by 12
“We used the European Nucleotide Archive (ENA; Leinonen et al., 2011) as a reference database (release 143, March 2020).”
Hung, H. C. H., Kumar, N., Carr, V. R., Yeats, C., Metcalf, B. J., Li, Y., Hawkins, P. A., McGee, L., Bentley, S. D., & Lo, S. W. (2025) · Nature Communications · doi:10.1038/s41467-025-64018-5 · Cited by 16
“While this restricts the versatility of the pipeline, 99.6% ( n =42,291/ 42,452) of pneumococcal raw reads publicly released in 2024 were generated using the Illumina platform, according to records from the European Nucleotide Archive (ENA) 39 , suggesting that this limitation has limited practical impact.”
InfluentialFattahi, M. R., Malekpour, A., Mortazavi, M., Safarpour, A. R., & Naseri, N. (2014) · Europe PMC (PubMed Central) · Cited by 12
Barrantes, I., Leipzig, J. N., & Marwan, W. (2012) · Gene Regulation and Systems Biology · doi:10.4137/grsb.s10224 · Cited by 12
MScDB: A Mass Spectrometry-centric Protein Sequence Database for Proteomics
Marx, H., Lemeer, S., Klaeger, S., Rattei, T., & Küster, B. (2013) · Journal of Proteome Research · doi:10.1021/pr400215r · Cited by 12
INGOT-DR: an interpretable classifier for predicting drug resistance in M. tuberculosis
Zabeti, H., Dexter, N., Safari, A. H., Sedaghat, N., Libbrecht, M. W., & Chindelevitch, L. (2021) · Algorithms for Molecular Biology · doi:10.1186/s13015-021-00198-1 · Cited by 11
“The whole-genome sequencing data for these 8,000 isolates, in the form of paired FASTQ files, are downloaded from the European Nucleotide Archive [50] and the Sequence Read Archive [51].”
MethodGenomePeek—an online tool for prokaryotic genome and metagenome analysis
McNair, K. A., & Edwards, R. A. (2015) · PeerJ · doi:10.7717/peerj.1025 · Cited by 12
“, 2004), and the source nucleic acid sequences from ENA (Leinonen et al., 2010).”
BackgroundSpatial Analyses of Mono, Di and Trinucleotide Trends in Plant Genes
Porceddu, A., & Camiolo, S. (2011) · PLoS ONE · doi:10.1371/journal.pone.0022855 · Cited by 12
“Physcomitrella (30866) and Selaginella (27560) coding sequences were retrieved from the EMBL-Coding sequences database [19].”
MethodJacob, E., Unger, R., & Horovitz, A. (2015) · eLife · doi:10.7554/elife.08932 · Cited by 12
SMusket: Spark-based DNA error correction on distributed-memory systems
Expósito, R. R., González‐Domínguez, J., & Touriño, J. (2019) · Future Generation Computer Systems · doi:10.1016/j.future.2019.10.038 · Cited by 12
A georeferenced rRNA amplicon database of aquatic microbiomes from South America
Metz, S., Huber, P., Mateus‐Barros, E., Junger, P. C., de Melo, M. L., Bagatini, I. L., Izaguirre, I., dos Reis, M. C., Llames, M. E., Accattatis, V., et al. (2022) · Scientific Data · doi:10.1038/s41597-022-01665-z · Cited by 12
Wan, Y., Ganner, M., Mumin, Z., Ready, D. R., Moore, G., Potterill, I., Paranthaman, K., Jauneikaite, E., Patel, B., Harley, A., et al. (2023) · Journal of Infection · doi:10.1016/j.jinf.2023.06.020 · Cited by 11
Jiang, Y., Wang, Y., Che, L., Yang, S., Zhang, X., Lin, Y., Shi, Y., Zou, N., Wang, S., Zhang, Y., et al. (2024) · Nucleic Acids Research · doi:10.1093/nar/gkae1007 · Cited by 11
Silicon Era of Carbon-Based Life: Application of Genomics and Bioinformatics in Crop Stress Research
Li, M., Qi, X., Ni, M., & Lam, H. (2013) · International Journal of Molecular Sciences · doi:10.3390/ijms140611444 · Cited by 11
“uk/ena/ [5] DDBJ http://www.”
Databases and resources for human small non-coding RNAs
Agirre, E., & Eyras, E. (2011) · Human Genomics · doi:10.1186/1479-7364-5-3-192 · Cited by 11
“In order to facilitate access to deep-sequencing data, the Short Read Archive (SRA) of NCBI 54 and the European Nucleotide Archive 55 (ENA) (http://www.ebi.ac. uk/ena/) have been created.”
MethodKerstens, H. H. D., Hehir‐Kwa, J. Y., van de Geer, E., van Run, C., Badloe, S., Janse, A., Baker-Hernandez, J. L., de Vos, S., van der Leest, D. F. M., Verwiel, E. T. P., et al. (2022) · BioMedInformatics · doi:10.3390/biomedinformatics3010001 · Cited by 11
A Bos taurus sequencing methods benchmark for assembly, haplotyping, and variant calling
Eché, C., Iampietro, C., Birbes, C., Dréau, A., Kuchly, C., Franco, A. D., Klopp, C., Faraut, T., Djebali, S., Castinel, A., et al. (2023) · Scientific Data · doi:10.1038/s41597-023-02249-1 · Cited by 10
ARA: a flexible pipeline for automated exploration of NCBI SRA datasets
Maurya, A. K., Szymański, M., & Karlowski, W. M. (2022) · GigaScience · doi:10.1093/gigascience/giad067 · Cited by 10
“Both modes include the same steps (Fig.”
Review of gene expression using microarray and RNA-seq
Villaseñor-Altamirano, A. B., Balderas-Martínez, Y. I., & Medina-Rivera, A. (2024) · Elsevier eBooks · doi:10.1016/b978-0-12-817218-6.00008-5 · Cited by 10
Shukla, R., & Singh, T. R. (2024) · Scientific Reports · doi:10.1038/s41598-024-82208-x · Cited by 12
Transcriptomic profiling of individual bacteria by MATQ-seq
Homberger, C., Imdahl, F., Hayward, R. J., Barquist, L., Saliba, A., & Vogel, J. (2025) · Nature Protocols · doi:10.1038/s41596-025-01157-5 · Cited by 10
Grimm, S. L., Kaufman, J. T., Rice, D. P., Whittaker, C., Bradshaw, W. J., & McLaren, M. R. (2025) · The Lancet Microbe · doi:10.1016/j.lanmic.2025.101187 · Cited by 10
Beier, S., Fiebig, A., Pommier, C., Liyanage, I. U., Lange, M., Kersey, P. J., Weise, S. F., Finkers, R., Koylass, B., Cezard, T., et al. (2022) · F1000Research · doi:10.12688/f1000research.109080.2 · Cited by 10
Karaz, S., Courgeon, M., Lepetit, H., Bruno, E., Pannone, R., Tarallo, A., Thouzé, F., Kerner, P., Vervoort, M., Causeret, F., et al. (2016) · EvoDevo · doi:10.1186/s13227-016-0055-5 · Cited by 10
Fungi.guru: Comparative genomic and transcriptomic resource for the fungi kingdom
Lim, J. J. J., Koh, J., Moo, J. R., Villanueva, E. M. F., Putri, D. A., Lim, Y. S., Seetoh, W. S., Mulupuri, S., Ng, J. W. Z., Nguyen, N. L. U., et al. (2020) · Computational and Structural Biotechnology Journal · doi:10.1016/j.csbj.2020.11.019 · Cited by 10
“RNA-sequencing experiments for all the fungal species were streamed as fastq files from the European Nucleotide Archive (ENA) [32] by using the LSTRaP-Cloud pipeline [33].”
MethodGene co-expression network analysis of Trypanosoma brucei in tsetse fly vector
Mwangi, K. W., Macharia, R. W., & Bargul, J. L. (2021) · Parasites & Vectors · doi:10.1186/s13071-021-04597-6 · Cited by 9
One Health for Dog-mediated Rabies Elimination in Asia
Slack, V., Nadal, D., Yasobant, S., Cliquet, F., Ahmad, W., Nihal, P. D. B., & Ghosh, S. (2023) · CABI eBooks · doi:10.1079/9781800622975.0000 · Cited by 10
Identifying and characterising key alternative splicing events in Drosophila development
Lees, J. G., Ranea, J. A. G., & Orengo, C. A. (2015) · BMC Genomics · doi:10.1186/s12864-015-1674-2 · Cited by 10
“We obtained the paired end sequence data from the fly developmental modENCODE project [22] from the European Nucleotide Archive [52] and calculated expression levels of isoforms from FlyBase 5.45 for all developmental stages.”
MethodInfluentialDual RNA Sequencing Meta-analysis in Plasmodium Infection Identifies Host-Parasite Interactions
Mukherjee, P., Burgio, G., & Heitlinger, E. G. (2021) · mSystems · doi:10.1128/msystems.00182-21 · Cited by 9
“Sequence data generated in biological experiments is submitted to one of the three mirroring databases of the International Nucleotide Sequence Database Collaboration (INSDC): NCBI Sequence Read Archive (SRA) (90), EBI European Nucleotide Archive (ENA) (91), and DDBJ Sequence Read Archive (DRA) (92).”
RFfiller: a robust and fast statistical algorithm for gap filling in draft genomes
Dida, F., & Yi, G. (2022) · PeerJ · doi:10.7717/peerj.14186 · Cited by 9
Mouratidis, I., Baltoumas, F. A., Chantzi, N., Patsakis, M., Chan, C. S. Y., Montgomery, A., Konnaris, M. A., Aplakidou, E., Georgakopoulos, G. C., Das, A., et al. (2023) · bioRxiv · doi:10.1016/j.csbj.2024.04.050 · Cited by 6
“In addition to the above, kmerDB provides links to external genomic and proteomic databases such as the ENA Browser [28], the NCBI Genome Browser [46], the UniProtKB Proteome database [56], and the InterPro protein families and domains database [9].”
Andrea Polanco, F., Rozanski, R., Marques, V., Helmkampf, M., Mouillot, D., Manel, S., Albouy, C. P., Puebla, O., & Pellissier, L. (2025) · Environmental DNA · doi:10.1002/edn3.70077 · Cited by 9
Legesse, D., Bouhouch, Y., Jacquard, C., Sanchez, L., Barka, E. A., & Esmaeel, Q. (2025) · Current Plant Biology · doi:10.1016/j.cpb.2025.100478 · Cited by 9
The Amordad database engine for metagenomics
Behnam, E., & Smith, A. D. (2014) · Bioinformatics · doi:10.1093/bioinformatics/btu405 · Cited by 8
Wani, N., & Raza, K. (2018) · Advances in intelligent systems and computing · doi:10.1007/978-981-13-1822-1_52 · Cited by 9
Named entity linking of geospatial and host metadata in GenBank for advancing biomedical research
Tahsin, T., Weissenbacher, D., Jones-Shargani, D., Magee, D., Vaiente, M., Gonzalez‐Hernandez, G., & Scotch, M. (2017) · Database · doi:10.1093/database/bax093 · Cited by 9
“With its participation in the International Nucleotide Sequence Database Collaboration (INSDC), NCBI exchanges sequences with international institutes such as the European Nucleotide Archive (ENA) (2) and the DNA Data Bank of Japan (DDBJ) (3).”
BackgroundIranzadeh, A., & Mulder, N. (2019) · Springer eBooks · doi:10.1007/978-981-13-8739-5_2 · Cited by 9
Angers‐Loustau, A., Petrillo, M., Paracchini, V., Kagkli, D. M., Rischitor, P. E., Gallardo, A. P., Patak, A., Querci, M., & Joachim, K. (2016) · PLoS ONE · doi:10.1371/journal.pone.0147692 · Cited by 9
“To test the presence of these target regions in other eukaryotes, and in order to enrich the set of reference sequences for barcoding experiments, we mined a local copy of the whole European Nucleotide Archive (ENA) nucleotide database [39] using ecoPCR [40], with each of these primers.”
MethodProtein homeostasis imprinting across evolution
Koutsandreas, T., Felden, B., Chevet, É., & Chatziioannou, A. A. (2024) · NAR Genomics and Bioinformatics · doi:10.1093/nargab/lqae014 · Cited by 9
Guidelines for reproducible analysis of adaptive immune receptor repertoire sequencing data
Peres, A., Klein, V., Frankel, B., Lees, W., Polak, P., Meehan, M., Rocha, A., Lopes, J. C., & Yaari, G. (2024) · Briefings in Bioinformatics · doi:10.1093/bib/bbae221 · Cited by 8
“AIRR-seq data for the analysis pipeline can be obtained either from locally available files, or from public databases like ENA [45], NCBI [46], iReceptor [47], and OAS [48].”
MethodSaha, P., Ravanan, P., & Talwar, P. (2025) · Biology Direct · doi:10.1186/s13062-025-00654-7 · Cited by 8
“The European Nucleotide Archive (ENA), which is overseen by the European Bioinformatics Institute (EBI), serves as an extensive repository for nucleotide sequence data [25].”
Bioinformatics tools for genomic and evolutionary analysis of infectious agents
Gupta, U., Dwivedi, V. D., Bharadwaj, S., & Mohanty, P. S. (2018) · Biomedical and Biotechnology Research Journal (BBRJ) · doi:10.4103/bbrj.bbrj_74_18 · Cited by 8
“BLAST, FASTA, and ENA search are the most popular sequence SSTs.[9,10] Among these three tools, BLAST is a very efficient program which contains many options for the sequence similarity searching.”
MethodCamargo-Forero, N., Orozco-Arias, S., Pérez, J. M., & Guyot, R. (2023) · Archives of Virology · doi:10.1007/s00705-023-05747-0 · Cited by 8
Griffiths, E., Mendes, C. I., Maguire, F., Guthrie, J. L., Wee, B. A., Schmedes, S. E., Holt, K. E., Yadav, C., Cameron, R., Barclay, C., et al. (2024) · Microbial Genomics · doi:10.1099/mgen.0.001260 · Cited by 8
“…user-defined fields in SRA (NCBI; https:// www.ncbi.nlm.nih.gov/sra) or included interactively or programmatically in experiment metadata via the ENA submission system (note: the Webin command line programme does not accept user-defined attributes) ([28]; https://www. ebi.ac.uk/ena/ browser/home).”
MethodVMAP: Vaginal Microbiome Atlas during Pregnancy
Párraga-Leo, A., Oskotsky, T., Oskotsky, B., Wibrand, C., Roldan, A., Tang, A., Ha, C. W. Y., Wong, R. J., Minot, S. S., Andreoletti, G., et al. (2024) · JAMIA Open · doi:10.1093/jamiaopen/ooae099 · Cited by 8
“The dataset was constructed by aggregating and processing vaginal microbiome data from the public domain 12–16 in addition to including newly generated data not yet released to the public.”
Wheat defense response to Fusarium head blight and possibilities of its improvement
Shah, L., Ali, A., Zhu, Y., Wang, S., Si, H., & Ma, C. (2017) · Physiological and Molecular Plant Pathology · doi:10.1016/j.pmpp.2017.01.004 · Cited by 9
Biocuration in the structure–function linkage database: the anatomy of a superfamily
Holliday, G. L., Brown, S. D., Akiva, E., Mischel, D., Hicks, M. A., Morris, J. H., Huang, C. C., Meng, E. C., Pegg, S. C. ‐., Ferrin, T. E., et al. (2017) · Database · doi:10.1093/database/bax006 · Cited by 7
“These data come from The SEED (52), IMG (53) and the European Nucleotide Archive (ENA) (54).”
MethodDon't just dump your data and run
Lima, M. S., & Smith, D. R. (2017) · EMBO Reports · doi:10.15252/embr.201745118 · Cited by 8
“Perhaps this is why members of the INSDC recently went out of their way to remind scientists to submit their raw sequencing reads to the SRA [4].”
Mining for viral fragments in methylation enriched sequencing data
Mensaert, K., Criekinge, W. V., Thas, O., Schuuring, E. M. D., Steenbergen, R. D. M., Wisman, G. B. A., & Meyer, T. D. (2015) · Frontiers in Genetics · doi:10.3389/fgene.2015.00016 · Cited by 8
“These included 2 iso-lates of primary human foreskin keratinocytes (labeled EK), 10 DNA isolates of keratinocytes transfected with full length HPV16 and HPV18 DNA and the plasmid pcDNAIneo (Invitrogen) (different passages of cell lines FK16A, FK16B, FK18A, FK18B; Steenbergen et al., 1996), 2 DNA…”
BackgroundMethodMalleable nature of mRNA-protein compositional complementarity and its functional significance
Hlevnjak, M., & Žagrović, B. (2015) · Nucleic Acids Research · doi:10.1093/nar/gkv166 · Cited by 7
“Where available, the coding sequences (CDS) of their corresponding mRNAs were downloaded from The European Nucleotide Archive (ENA) (14) using the ‘Crossreferences’ section of each UniProtKB entry, while ensuring that ENA-translated mRNAs match the corresponding UniProtKB canonical protein sequences perfectly.”
MethodAguilar‐Bultet, L., Calderon-Copete, S. P., Joachim Frey, A., & Falquet, L. (2013) · Genome Announcements · doi:10.1128/genomea.00592-13 · Cited by 8
“The draft genome was annotated using a pipeline we developed (2) and was deposited at the European Nucleotide Archive (ENA) (3).”
MethodSOPHIE: Generative Neural Networks Separate Common and Specific Transcriptional Responses
Lee, A. J., Mould, D. L., Crawford, J., Hu, D., Powers, R. K., Doing, G., Costello, J. C., Hogan, D. A., & Greene, C. S. (2022) · Genomics Proteomics & Bioinformatics · doi:10.1016/j.gpb.2022.09.011 · Cited by 8
“Such data are readily available through National Center for Biotechnology Information (NCBI) Gene Expression Omnibus (GEO) [9], Short Read Archive (SRA) [10], European Nucleotide Archive (ENA) [11], and other repositories.”
Estimating sequence similarity from read sets for clustering next-generation sequencing data
Ryšavý, P., & Železný, F. (2018) · Data Mining and Knowledge Discovery · doi:10.1007/s10618-018-0584-8 · Cited by 8
Sorbie, A., Jiménez, R. D., & Benakis, C. (2022) · iScience · doi:10.1016/j.isci.2022.103998 · Cited by 7
Large-scale biological meta-database management
Pedersen, E., & Bongo, L. A. (2016) · Future Generation Computer Systems · doi:10.1016/j.future.2016.02.010 · Cited by 7
Arend, D., Beier, S., König, P., Lange, M., Memon, J. A., Oppermann, M., Scholz, U., & Weise, S. F. (2022) · Springer eBooks · doi:10.1007/978-981-16-6795-4_2 · Cited by 7
Shadoff, R., Panoyan, M. A., & Novroski, N. M. M. (2022) · Forensic Genomics · doi:10.1089/forensic.2022.0007 · Cited by 7
“The INDSC actively collaborates with the DNA Databank of Japan, 138 the European Nucleotide Archive, 139 and GenBank.”
Sheng, Y., Ali, R. A., & Heyland, A. (2022) · BMC Bioinformatics · doi:10.1186/s12859-022-04972-9 · Cited by 7
“CoRMAP includes a utility to download datasets of RNA-Seq raw data containing multiple runs from the Sequence Read Archive (SRA) [29, 30] database in batch by the software ascp.”
MethodKumuthini, J., Zass, L. J., Chaouch, M., Fadlelmola, F. M., Mulder, N., Radouani, F., Ras, V., Samtal, C., Tchamga, M. S. S., Sathan, D., et al. (2023) · Elsevier eBooks · doi:10.1016/b978-0-12-819803-2.00003-1 · Cited by 7
Use of a Regression Model to Study Host-Genomic Determinants of Phage Susceptibility in MRSA
Zschach, H., Larsen, M., Hasman, H., Westh, H., Nielsen, M., Międzybrodzki, R., Jończyk‐Matysiak, E., Weber‐Dąbrowska, B., & Górski, A. (2018) · Antibiotics · doi:10.3390/antibiotics7010009 · Cited by 7
“The fasta sequences of the 207 selected strains have been submitted to the European Nucleotide Archive (Hinxton, Cambridgeshire, UK) [24] with the accession numbers ERZ485118–ERZ485325.”
MethodOnline Resources for Genomic Analysis Using High-Throughput SequencingPreprint
Blankenberg, D. J., Taylor, J., & Nekrutenko, A. (2015) · Cold Spring Harbor Protocols · doi:10.1101/pdb.top083667 · Cited by 7
“A typical NGS analysis with Galaxy begins with loading sequencing reads in the FASTQ format into the History, either by uploading or by importing from an external data source such as the ENA Short Read Archive (Leinonen et al. 2011).”
MethodDiversified RACE Sampling on Data Streams Applied to Metagenomic Sequence AnalysisPreprint
Coleman, B., Geordie, B., Chou, L., Elworth, R. A. L., Treangen, T. J., & Shrivastava, A. (2019) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/852889 · Cited by 7
“Large scale genomic repositories such as the European Nucleotide Archive (ENA) [15] and the NCBI Short Read Archive (SRA)[16] are the product of ambitious experimental efforts to sequence as many organisms as possible.”
BackgroundComprehensive benchmarking of metagenomic classification tools for long-read sequencing dataPreprint
Marić, J., Križanović, K., Riondet, S., Nagarajan, N., & Šikić, M. (2020) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2020.11.25.397729 · Cited by 7
“- Datasets ONT1, PB1, and PB4 reflect a community of bacteria without eukaryotic species.”
InfluentialКондратов, К. А., Artamonov, A. A., Nikitin, Y. V., Velmiskina, A., Mikhailovskii, V., Mosenko, S. V., Полковникова, И. А., Asinovskaya, A. Y., Апалько, С. В., Николаевна, С. Н., et al. (2024) · BMC Medical Genomics · doi:10.1186/s12920-024-01982-9 · Cited by 6
“Current version of miR-master used Ensembl [26], RNACentral piRNA [27], NCBI RefSeq [28], ENA [29], GeneCards [30], PirBase [31] databases for analyzing RNAseq FASTQ data.”
BackgroundMethodPerturbAtlas: a comprehensive atlas of public genetic perturbation bulk RNA-seq datasets
Zhang, Y., Zhang, T., Yang, G., Pan, Z., Tang, M., Wen, Y., He, P., Wang, Y., & Zhou, R. (2024) · Nucleic Acids Research · doi:10.1093/nar/gkae851 · Cited by 7
Loganathan, T., & Doss, C. G. P. (2025) · PLoS ONE · doi:10.1371/journal.pone.0324742 · Cited by 6
“The fecal samples of raw FASTQ files were obtained from the European Nucleotide Archive (ENA) [17].”
Colaco, V., Goswami, N., Goel, V. K., Srivastava, S. K., Lalrohlua, P. C., Kumar, N. S., Borah, P., Baruah, R., & Varma, A. K. (2023) · Journal of Cellular Biochemistry · doi:10.1002/jcb.30508 · Cited by 6
The African Human Microbiome Portal: a public web portal of curated metagenomic metadata
Kiran, A. M., Hanachi, M., Alsayed, N., Fassatoui, M., Oduaran, O. H., Allali, I., Maslamoney, S., Meintjes, A., Zass, L. J., Rocha, J. D., et al. (2024) · Database · doi:10.1093/database/baad092 · Cited by 6
scnanoseq: an nf-core pipeline for Oxford Nanopore single-cell RNA-sequencing
Trull, A., community, N.-C., Worthey, E. A., & Ianov, L. (2025) · Bioinformatics · doi:10.1093/bioinformatics/btaf487 · Cited by 6
Rocca‐Serra, P., Walls, R., Parnell, J., Gallery, R. E., Zheng, J., Sansone, S., & Gonzalez-Beltran, A. N. (2015) · Database · doi:10.1093/database/bau132 · Cited by 6
“As comparison, the SRA xml generated by ENA webin tool (13) places the information as ‘sample attributes’.”
MethodWalker, K., Kalra, D., Lowdon, R. F., Chen, G., Molik, D. C., Soto, D. C., Dabbaghie, F., Khleifat, A. A., Mahmoud, M., Paulin, L. F., et al. (2022) · F1000Research · doi:10.12688/f1000research.110194.1 · Cited by 7
The origins of the evolutionary signal used to predict protein-protein interactions
Swapna, L. S., Srinivasan, N., Robertson, D. L., & Lovell, S. C. (2012) · BMC Evolutionary Biology · doi:10.1186/1471-2148-12-238 · Cited by 6
“For every interacting/non-interacting protein pair, 18S rRNA sequences for the set of species whose orthologs are used in the construction of MSA are culled from the ENA database [77].”
MethodGeneSV – an Approach to Help Characterize Possible Variations in Genomic and Protein Sequences
Zemla, A. T., Kostova, T., Gorchakov, R. V., Volkova, E., Beasley, D. W. C., Cardosa, J., Weaver, S. C., Vasilakis, N., & Naraghi‐Arani, P. (2014) · Bioinformatics and Biology Insights · doi:10.4137/bbi.s13076 · Cited by 6
Bioinformatics Database Resources
Khandelwal, I., Sharma, A., Agrawal, P., & Shrivastava, R. (2017) · Advances in library and information science (ALIS) book series · doi:10.4018/978-1-5225-1871-6.ch004 · Cited by 6
Bell, Z., Lovell, P., Mello, C., Yip, P., George, J., & Clayton, D. F. (2019) · Scientific Reports · doi:10.1038/s41598-018-37057-w · Cited by 6
Metadata
- Authors
- Leinonen, R., Akhtar, R., Birney, E., Bower, L., Cerdeno-Tarraga, A., Cheng, Y., Cleland, I., Faruque, N., Goodgame, N., Gibson, R., Hoad, G., Jang, M., Pakseresht, N., Plaister, S., Radhakrishnan, R., Reddy, K., Sobhany, S., Ten Hoopen, P., Vaughan, R., Zalunin, V., & Cochrane, G.
- Affiliations
- European Bioinformatics Institute (GB)
- Corresponding author
- Leinonen, R.
- ORCID
- Venue
- Nucleic Acids Research
- Publisher
- Oxford University Press (OUP)
- Published
- 2010-10-23
- Volume
- 39
- Issue
- Database
- Pages
- D28-D31
- ISSN
- 0305-1048 (ISSN-L)
- 1362-4962
- PMC
- PMC3013801
- OpenAlex
- W2120358246
- Cited by
- 690
- References
- 10
- Citations by year
- 2026: 37 · 2025: 49 · 2024: 74 · 2023: 52 · 2022: 44 · 2021: 64 · 2020: 37 · 2019: 42 · 2018: 41 · 2017: 47 · 2016: 39 · 2015: 48 · 2014: 33 · 2013: 31 · 2012: 23
- FWCI
- 10.60
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Nucleic Acids Research (publishedVersion, cc-by-nc)
- PubMed Central (publishedVersion, cc-by-nc)
- PubMed (publishedVersion)
- Funders
- Wellcome Trust (085532)
- European Molecular Biology Laboratory
- European Commission
- Topics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Genomics and Phylogenetic Studies
- Physical Sciences › Computer Science › Information Systems › Research Data Management Practices
- Social Sciences › Decision Sciences › Information Systems and Management › Scientific Computing and Data Management
- Keywords
- European Nucleotide Archive, Sequence Read Archive, DNA sequence databases, sequence similarity search, European Genome-phenome Archive
- MeSH terms
- Base Sequence, Europe, Databases, Nucleic Acid, Molecular Sequence Annotation, High-Throughput Nucleotide Sequencing
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
