

The DOI matches its Crossref record; 10 of the 10 references it cites were found in a registry or an index.
The European Nucleotide Archive
Open accessAbstract
The European Nucleotide Archive (ENA; http://www.ebi.ac.uk/ena) is Europe's primary nucleotide-sequence repository. The ENA consists of three main databases: the Sequence Read Archive (SRA), the Trace Archive and EMBL-Bank. The objective of ENA is to support and promote the use of nucleotide sequencing as an experimental research platform by providing data submission, archive, search and download services. In this article, we outline these services and describe major changes and improvements introduced during 2010. These include extended EMBL-Bank and SRA-data submission services, extended ENA Browser functionality, support for submitting data to the European Genome-phenome Archive (EGA) through SRA, and the launch of a new sequence similarity search service.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
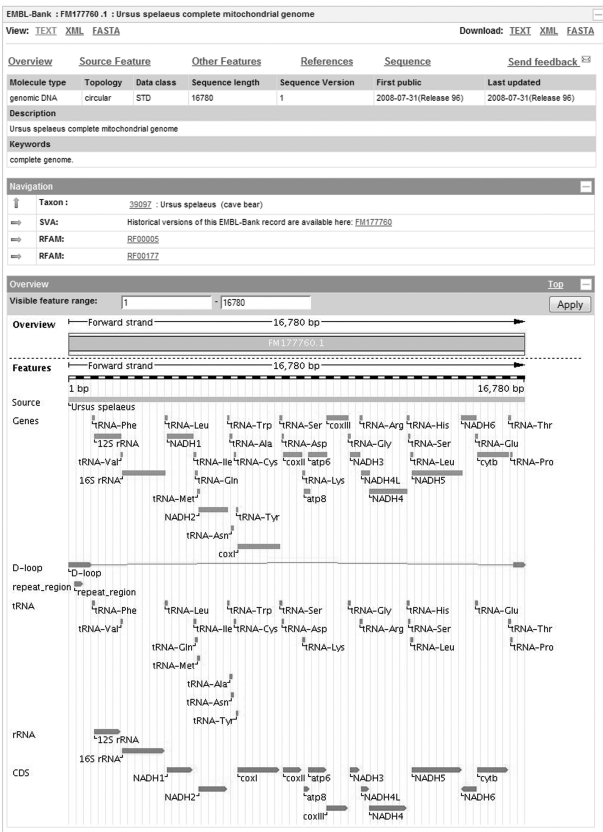
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“Tools such as DIGIT and Abysis source their data from the European Nucleotide Archive (ENA) [60] and the National Center for Biotechnology Information (NCBI) [61]; their sequence volumes are of the order of 105 and contain multiple artificially engineered sequences.”
From Computational approaches to therapeutic antibody design: established methods and emerging trends (2020) · cites this paper as [60]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The Sequence Alignment/Map format and SAMtools
Li, H., Handsaker, B., Wysoker, A., Fennell, T., Ruan, J., Homer, N., Marth, G., Abecasis, G., Durbin, R., & 1000 Genome Project Data Processing Subgroup (2009) · Bioinformatics · doi:10.1093/bioinformatics/btp352 · Cited by 62,041
Velvet: Algorithms for de novo short read assembly using de Bruijn graphsPreprint
Zerbino, D. R., & Birney, E. (2008) · Genome Research · doi:10.1101/gr.074492.107 · Cited by 9,587 · cited 1×
“Experimental search support for a limited number of raw reads is provided through De-Bruijn servers based on Velvet (9), using the Exonerate client-server protocol and being fully integrated with our search service.”
MethodAutomated generation of heuristics for biological sequence comparison
Slater, G., & Birney, E. (2005) · BMC Bioinformatics · doi:10.1186/1471-2105-6-31 · Cited by 2,959
The International Nucleotide Sequence Database Collaboration
Karsch‐Mizrachi, I., Nakamura, Y., & Cochrane, G. (2011) · Nucleic Acids Research · doi:10.1093/nar/gkr1006 · Cited by 717
Benson, D. A., Karsch‐Mizrachi, I., Lipman, D. J., Ostell, J., & Sayers, E. W. (2009) · Nucleic Acids Research · doi:10.1093/nar/gkp1024 · Cited by 348
Krause, J., Unger, T., Noçon, A., Malaspinas, A., Kolokotronis, S., Stiller, M., Soibelzon, L. H., Spriggs, H. F., Dear, P. H., Briggs, A. W., et al. (2008) · BMC Evolutionary Biology · doi:10.1186/1471-2148-8-220 · Cited by 288
The International Nucleotide Sequence Database Collaboration
Cochrane, G., Karsch‐Mizrachi, I., & Nakamura, Y. (2010) · Nucleic Acids Research · doi:10.1093/nar/gkq1150 · Cited by 113
DDBJ launches a new archive database with analytical tools for next-generation sequence data
Kaminuma, E., Mashima, J., Kodama, Y., Gojobori, T., Ogasawara, O., Okubo, K., Takagi, T., & Nakamura, Y. (2009) · Nucleic Acids Research · doi:10.1093/nar/gkp847 · Cited by 99 · cited 1×
“The ENA works closely together with NCBI (1) and DDBJ (2) as partners in the International Nucleotide Sequence Database Collaboration (3).”
MethodImprovements to services at the European Nucleotide Archive
Leinonen, R., Akhtar, R. A., Birney, E., Bonfield, J., Bower, L., Corbett, M., Cheng, Y., Demiralp, F., Faruque, N., Goodgame, N., et al. (2009) · Nucleic Acids Research · doi:10.1093/nar/gkp998 · Cited by 66 · cited 1×
“It contains a large diversity of data from patent, expressed sequence tag, whole genome shotgun and other high-throughput sequences, through genomic assemblies and richly annotated sequence fragments to whole replicons (5).”
BackgroundFast and efficient searching of biological data resources--using EB-eye
Valentin, F., Squizzato, S., Goujon, M., McWilliam, H., Paern, J., & López, R. (2010) · Briefings in Bioinformatics · doi:10.1093/bib/bbp065 · Cited by 37 · cited 1×
“Data can be queried using the EB-Eye free text search functionality available in the header section of all EBI web pages (7).”
Method
Cited by
Sorted by citations
Benson, D. A., Cavanaugh, M., Clark, K., Karsch-Mizrachi, I., Lipman, D. J., Ostell, J., & Sayers, E. W. (2012) · Nucleic Acids Research · doi:10.1093/nar/gks1195 · Cited by 3,261
“Daily data exchange with the European Nucleotide Archive (ENA) and the DNA Data Bank of Japan (DDBJ) ensures worldwide coverage.”
MethodBeghini, F., McIver, L. J., Blanco-Míguez, A., Dubois, L., Asnicar, F., Maharjan, S., Mailyan, A., Manghi, P., Scholz, M., Thomas, A. M., et al. (2021) · eLife · doi:10.7554/elife.65088 · Cited by 2,303
Improvements to PATRIC, the all-bacterial Bioinformatics Database and Analysis Resource Center
Wattam, A. R., Davis, J. J., Assaf, R., Boisvert, S., Brettin, T. S., Bun, C., Conrad, N. R., Dietrich, E. M., Disz, T. L., Gabbard, J. L., et al. (2016) · Nucleic Acids Research · doi:10.1093/nar/gkw1017 · Cited by 1,635
“Since the submission of metadata with a genome is almost entirely voluntary, and many researches have been electing to submit their genomes to SRA (5) or the European Nucleotide Archive (ENA) (42) instead of assembling and annotating them, we have been searching the literature for publications with large-scale AMR stu…”
Landscape of Microsatellite Instability Across 39 Cancer Types
Bonneville, R., Krook, M. A., Kautto, E. A., Miya, J., Wing, M. R., Chen, H., Reeser, J. W., Yu, L., & Roychowdhury, S. (2017) · JCO Precision Oncology · doi:10.1200/po.17.00073 · Cited by 1,505
Gide, T. N., Quek, C., Menzies, A. M., Tasker, A. T., Shang, P., Holst, J., Madore, J., Lim, S. Y., Velickovic, R., Wongchenko, M., et al. (2019) · Cancer Cell · doi:10.1016/j.ccell.2019.01.003 · Cited by 1,047
Pagani, I., Liolios, K., Jansson, J., Chen, I.-M. A., Smirnova, T., Nosrat, B., Markowitz, V. M., & Kyrpides, N. C. (2011) · Nucleic Acids Research · doi:10.1093/nar/gkr1100 · Cited by 1,066
“For all of these projects, the genome sequence is ‘completed’ by depositing the final version of the project in one of the public archival databases such as GenBank (17), European Molecular Biology Laboratory (EMBL) (18) and DNA Data Bank of Japan (DDBJ) (19).”
Background25 years of serving the community with ribosomal RNA gene reference databases and tools
Glöckner, F. O., Yilmaz, P., Quast, C., Gerken, J., Beccati, A., Ciuprina, A., Bruns, G., Yarza, P., Peplies, J., Westram, R., et al. (2017) · Journal of Biotechnology · doi:10.1016/j.jbiotec.2017.06.1198 · Cited by 973
“The models and parameters from the RNAmmer software package (Lagesen et al., 2007) are used to scan all sequences in EMBL-EBI/ENA for the presence of rRNA gene sequences.”
BackgroundMethodInfluentialUsing machine learning approaches for multi-omics data analysis: A review
Reel, P. S., Reel, S., Pearson, E., Trucco, E., & Jefferson, E. (2021) · Biotechnology Advances · doi:10.1016/j.biotechadv.2021.107739 · Cited by 903
RobiNA: a user-friendly, integrated software solution for RNA-Seq-based transcriptomics
Lohse, M., Bolger, A., Nagel, A., Fernie, A. R., Lunn, J. E., Stitt, M., & Usadel, B. (2012) · Nucleic Acids Research · doi:10.1093/nar/gks540 · Cited by 790
Bias, robustness and scalability in single-cell differential expression analysis
Soneson, C., & Robinson, M. D. (2018) · Nature Methods · doi:10.1038/nmeth.4612 · Cited by 770
OptiType: precision HLA typing from next-generation sequencing data
Szolek, A., Schubert, B., Mohr, C., Sturm, M., Feldhahn, M., & Kohlbacher, O. (2014) · Bioinformatics · doi:10.1093/bioinformatics/btu548 · Cited by 774
Cistrome: an integrative platform for transcriptional regulation studies
Liu, T., Ortiz, J. A., Taing, L., Meyer, C. A., Lee, B. T. K., Zhang, Y., Shin, H., Wong, S. S., Ma, J., Lei, Y., et al. (2011) · Genome biology · doi:10.1186/gb-2011-12-8-r83 · Cited by 722
“Currently, databases such as the National Center for Biotechnology Information (NCBI) Gene Expression Omnibus (GEO) [33] and the European Bioinformatics Institute (EBI) ArrayExpress [34] host array data, and databases such as the NCBI Sequence Reads Archive (SRA) [35] and the EBI SRA host sequencing data [36].”
The International Nucleotide Sequence Database Collaboration
Karsch‐Mizrachi, I., Nakamura, Y., & Cochrane, G. (2011) · Nucleic Acids Research · doi:10.1093/nar/gkr1006 · Cited by 717
Massive expansion of human gut bacteriophage diversity
Camarillo-Guerrero, L. F., Almeida, A., Rangel-Pineros, G., Finn, R. D., & Lawley, T. D. (2021) · Cell · doi:10.1016/j.cell.2021.01.029 · Cited by 594
Update on the proposed minimal standards for the use of genome data for the taxonomy of prokaryotes
Riesco, R., & Trujillo, M. E. (2024) · INTERNATIONAL JOURNAL OF SYSTEMATIC AND EVOLUTIONARY MICROBIOLOGY · doi:10.1099/ijsem.0.006300 · Cited by 618
Benson, D. A., Karsch‐Mizrachi, I., Clark, K., Lipman, D. J., Ostell, J., & Sayers, E. W. (2011) · Nucleic Acids Research · doi:10.1093/nar/gkr1202 · Cited by 589
“Daily data exchange with the European Nucleotide Archive (ENA) and the DNA Data Bank of Japan (DDBJ) ensures worldwide coverage.”
MethodScheinin, I., Sie, D., Bengtsson, H. L., van de Wiel, M. A., Olshen, A. B., van Thuijl, H. F., Essen, H. F. H. V., Eijk, P. P., Rustenburg, F., Meijer, G. A., et al. (2014) · Genome Research · doi:10.1101/gr.175141.114 · Cited by 497
Oulas, A., Pavloudi, C., Polymenakou, P., Pavlopoulos, G. A., Papanikolaou, N., Kotoulas, G., Arvanitidis, C., & Iliopoulos, L. (2015) · Bioinformatics and Biology Insights · doi:10.4137/bbi.s12462 · Cited by 453
The Ontology for Biomedical Investigations
Bandrowski, A. E., Brinkman, R. R., Brochhausen, M., Brush, M., Bug, B., Chibucos, M. C., Clancy, K., Courtot, M., Derom, D., Dumontier, M., et al. (2016) · PLoS ONE · doi:10.1371/journal.pone.0154556 · Cited by 387
“The workflow of the ISA system has been validated and is compatible with existing technology centric formats (e.g. MAGE-TAB for ArrayExpress [37] and Sequence Read Archive (SRA) EXtensible Markup Language (XML) for ENA [36], respectively).”
BackgroundA brief history of bioinformatics
Gauthier, J., Vincent, A. T., Charette, S. J., & Derôme, N. (2018) · Briefings in Bioinformatics · doi:10.1093/bib/bby063 · Cited by 425
“In addition, we have also been witnessing the emergence of general genomic databases such as the Sequence Read Archive [121] and The European Nucleotide Archive [122], which were implemented to store raw sequencing data for further reproducibility between studies.”
MethodThe real cost of sequencing: scaling computation to keep pace with data generation
Muir, P., Li, S., Lou, S., Wang, D., Spakowicz, D. J., Salichos, L., Zhang, J., Weinstock, G. M., Isaacs, F. J., Rozowsky, J. S., et al. (2016) · Genome biology · doi:10.1186/s13059-016-0917-0 · Cited by 390
“This necessitated changes in the storage infrastructure; databases such as the European Nucleotide Archive [9] and the Sequence Read Archive (SRA) [10] were created to store and”
MethodReddy, T. B. K., Thomas, A. D., Stamatis, D., Bertsch, J., Isbandi, M., Jansson, J., Mallajosyula, J. K., Pagani, I., Lobos, E. A., & Kyrpides, N. C. (2014) · Nucleic Acids Research · doi:10.1093/nar/gku950 · Cited by 345
“As these data are submitted to various public resources like GenBank (7) and EMBL (8) or analysis platforms like Integrated Microbial Genomes (IMG) (9) and MG-RAST (10), it becomes increasingly important to document the associated metadata in order to facilitate comparative analysis and hypothesis generation.”
MethodTranscriptome analysis of human tissues and cell lines reveals one dominant transcript per gene
Gonzàlez-Porta, M., Frankish, A., Rung, J., Harrow, J., & Brazma, A. (2013) · Genome Biology · doi:10.1186/gb-2013-14-7-r70 · Cited by 266
“Leinonen R, Akhtar R, Birney E, Bower L, Cerdeno-Tárraga A, Cheng Y, Cleland I, Faruque N, Goodgame N, Gibson R, Hoad G, Jang M, Pakseresht N, Plaister S, Radhakrishnan R, Reddy K, Sobhany S, Ten Hoopen P, Vaughan R, Zalunin V, Cochrane G: The European Nucleotide Archive.”
MethodAncient plant DNA in lake sediments
Parducci, L., Bennett, K. D., Ficetola, G. F., Alsos, I. G., Suyama, Y., Wood, J. R., & Pedersen, M. W. (2017) · New Phytologist · doi:10.1111/nph.14470 · Cited by 291
de Klein, N., Tsai, E. A., Vochteloo, M., Baird, D., Huang, Y., Chen, C.-Y., van Dam, S., Oelen, R., Deelen, P., Bakker, O. B., et al. (2023) · Nature Genetics · doi:10.1038/s41588-023-01300-6 · Cited by 272
Comparison of solution-based exome capture methods for next generation sequencing
Sulonen, A.-M., Ellonen, P., Almusa, H., Lepistö, M., Eldfors, S., Hannula, S., Miettinen, T., Tyynismaa, H., Salo, P. P., Heckman, C. A., et al. (2011) · Genome biology · doi:10.1186/gb-2011-12-9-r94 · Cited by 265
Mitotic Transcription and Waves of Gene Reactivation During Mitotic Exit
Palozola, K. C., Donahue, G., Liu, H., Grant, G., Becker, J., Coté, A., Yu, H.-T., Raj, A., & Zaret, K. (2017) · Science · doi:10.1126/science.aal4671 · Cited by 245
Disbiome database: linking the microbiome to disease
Janssens, Y., Nielandt, J., Bronselaer, A., Debunne, N., Verbeke, F., Wynendaele, E., Immerseel, F. V., Vandewynckel, Y., Tré, G. D., & Spiegeleer, B. D. (2018) · BMC Microbiology · doi:10.1186/s12866-018-1197-5 · Cited by 253
“CONSORT: CONsolidated Standards Of Reporting Trials; DDBJ: DNA Data Bank of Japan; DGGE: Denaturating gradient gel electrophoresis; ENA: European Nucleotide Archive; HLGT: Highest level group term; HLT: High level term; ICH: International council for harmonisation of technical requirements for pharmaceuticals for huma…”
BackgroundKovaltsuk, A., Leem, J., Kelm, S., Snowden, J., Deane, C. M., & Krawczyk, K. (2018) · The Journal of Immunology · doi:10.4049/jimmunol.1800708 · Cited by 247
“The majority of raw reads were downloaded from the European Nucleotide Archive (30) and the National Center for Biotechnology Information websites (31).”
MethodThe switches.ELM Resource: A Compendium of Conditional Regulatory Interaction Interfaces
Roey, K. V., Dinkel, H., Weatheritt, R. J., Gibson, T. J., & Davey, N. E. (2013) · Science Signaling · doi:10.1126/scisignal.2003345 · Cited by 247
“PTMs are annotated by the position of the modified residue in the sequence and the type of modification, using the PSI-MOD controlled vocabulary for protein modifications (90), whereas effector molecules are identified by reference to an external resource (66, 70, 71).”
BackgroundMethodInfluentialProtein interaction networks revealed by proteome coevolution
Cong, Q., Anishchenko, I., Ovchinnikov, S., & Baker, D. (2019) · Science · doi:10.1126/science.aaw6718 · Cited by 241
Genenames.org: the HGNC resources in 2013
Gray, K. A., Daugherty, L. C., Gordon, S. M., Seal, R. L., Wright, M. W., & Bruford, E. A. (2012) · Nucleic Acids Research · doi:10.1093/nar/gks1066 · Cited by 240
Architectures of Lipid Transport Systems for the Bacterial Outer Membrane
Ekiert, D. C., Bhabha, G., Isom, G. L., Greenan, G. A., Ovchinnikov, S., Henderson, I. R., Cox, J. S., & Vale, R. D. (2017) · Cell · doi:10.1016/j.cell.2017.03.019 · Cited by 233
GeneDB--an annotation database for pathogens
Logan-Klumpler, F., Silva, N. H. D., Böehme, U., Rogers, M. B., Velarde, G., McQuillan, J. A., Carver, T., Aslett, M. A., Olsen, C., Subramanian, S., et al. (2011) · Nucleic Acids Research · doi:10.1093/nar/gkr1032 · Cited by 228
“We focus on the rapid release and simple, rapid access, to reference genomes, with a depth of annotation and curation that is not found on other databases [such as ENA-EMBL (3) and GenBank (4)].”
MethodComputational approaches to therapeutic antibody design: established methods and emerging trends
Norman, R. A., Ambrosetti, F., Bonvin, A. M. J. J., Colwell, L. J., Kelm, S., Kumar, S., & Krawczyk, K. (2020) · Briefings in Bioinformatics · doi:10.1093/bib/bbz095 · Cited by 219
“Tools such as DIGIT and Abysis source their data from the European Nucleotide Archive (ENA) [60] and the National Center for Biotechnology Information (NCBI) [61]; their sequence volumes are of the order of 105 and contain multiple artificially engineered sequences.”
MethodDesigning a transcriptome next‐generation sequencing project for a nonmodel plant species1
Strickler, S. R., Bombarely, A., & Mueller, L. A. (2012) · American Journal of Botany · doi:10.3732/ajb.1100292 · Cited by 232
CopywriteR: DNA copy number detection from off-target sequence data
Kuilman, T., Velds, A., Kemper, K., Ranzani, M., Bombardelli, L., Hoogstraat, M., Nevedomskaya, E., Xu, G., de Ruiter, J., Lolkema, M. P., et al. (2015) · Genome biology · doi:10.1186/s13059-015-0617-1 · Cited by 212
“Previously unpublished data have been made available through the NCBI Gene Expression Omnibus (GEO) [39] (accession number GSE60259), the European Nucleotide Archive (ENA) [40] (accession number PRJEB6954), and the European Genome-phenome Archive (EGA) [41] (accession number EGAS00001000617).”
MethodHBVdb: a knowledge database for Hepatitis B Virus
Hayer, J., Jadeau, F., Deléage, G., Kay, A., Zoulim, F., & Combet, C. (2012) · Nucleic Acids Research · doi:10.1093/nar/gks1022 · Cited by 212
“Some elements of the ENA-Annotation entry are conserved such as the accession number, the organism name, the creation date, and the references.”
MethodInfluentialChromatin accessibility profiling methods
Minnoye, L., Marinov, G. K., Krausgruber, T., Pan, L., Marand, A. P., Secchia, S., Greenleaf, W. J., Furlong, E. E. M., Zhao, K., Schmitz, R. J., et al. (2021) · Nature Reviews Methods Primers · doi:10.1038/s43586-020-00008-9 · Cited by 206
Lentendu, G., Wubet, T., Chatzinotas, A., Wilhelm, C., Buscot, F., & Schlegel, M. (2014) · Molecular Ecology · doi:10.1111/mec.12819 · Cited by 195
“…either from the PR2 (cer-, chry-, euk- and kin-data sets; Guillou et al. 2012) or UNITE (January 2013 release, its-data set; Abarenkov et al. 2010) databases, or from a self-constructed ENA sequences database (release 116, Leinonen et al. 2010; upa-data set; Appendix S3, Supporting Information).”
BackgroundThe International Human Epigenome Consortium Data Portal
Bujold, D., Morais, D. A. D. L., Gauthier, C., Côté, C., Caron, M., Kwan, T., Chen, K. C., Laperle, J., Nordell-Markovits, A., Pastinen, T., et al. (2016) · Cell Systems · doi:10.1016/j.cels.2016.10.019 · Cited by 186
Temporal and technical variability of human gut metagenomes
Voigt, A. Y., Costea, P. I., Kultima, J. R., Li, S. S., Zeller, G., Sunagawa, S., & Bork, P. (2015) · Genome biology · doi:10.1186/s13059-015-0639-8 · Cited by 182
Lightbody, G., Haberland, V., Browne, F., Taggart, L., Zheng, H., Parkes, E., & Blayney, J. K. (2019) · Briefings in Bioinformatics · doi:10.1093/bib/bby051 · Cited by 173
One Stop Shop for Everything Dictyostelium: dictyBase and the Dicty Stock Center in 2012
Fey, P., Dodson, R. J., Basu, S., & Chisholm, R. L. (2013) · Methods in molecular biology · doi:10.1007/978-1-62703-302-2_4 · Cited by 166
Krishna, A., Biryukov, M., Trefois, C., Antony, P. M. A., Hussong, R., Lin, J., Heinäniemi, M., Glusman, G., Köglsberger, S., Boyd, O., et al. (2014) · BMC Genomics · doi:10.1186/1471-2164-15-1154 · Cited by 174
“The raw reads are available in the European Nucleotide Archive (ENA) database [37] under the study accession PRJEB7313.”
MethodKapushesky, M., Adamusiak, T., Burdett, T., Culhane, A. C., Farne, A., Filippov, A., Holloway, E., Клебанов, А. А., Kryvych, N., Kurbatova, N., et al. (2011) · Nucleic Acids Research · doi:10.1093/nar/gkr913 · Cited by 162
“We also now include data on microRNA expression as well as next-generation sequencing RNA-Seq data from the European Nucleotide Archive [ENA (2)].”
MethodGene regulatory network inference resources: A practical overview
Mercatelli, D., Scalambra, L., Triboli, L., Ray, F., & Giorgi, F. M. (2019) · Biochimica et Biophysica Acta (BBA) - Gene Regulatory Mechanisms · doi:10.1016/j.bbagrm.2019.194430 · Cited by 169
Deelen, P., van Dam, S., Herkert, J. C., Karjalainen, J. M., Brugge, H., Abbott, K. M., van Diemen, C. C., van der Zwaag, P. A., Gerkes, E. H., Zonneveld-Huijssoon, E., et al. (2019) · Nature Communications · doi:10.1038/s41467-019-10649-4 · Cited by 138
“Imr90 (128|16) Huvec (123|22) Hmec (94|7) Lncap (108|21)”
A Guide to Carrying Out a Phylogenomic Target Sequence Capture Project
Andermann, T., Jiménez, M. F. T., Matos‐Maraví, P. F., Batista, R., Blanco‐Pastor, J. L., Gustafsson, A. L. S., Kistler, L., Liberal, I. M., Oxelman, B., Bacon, C. D., et al. (2020) · Frontiers in Genetics · doi:10.3389/fgene.2019.01407 · Cited by 139
“…online database such as the NCBI sequence read archive (Leinonen et al., 2011b, https://www.ncbi.nlm.nih.gov/sra) or the European nucleotide archive (Leinonen et al., 2011a, https://www.ebi.ac.uk/ena), which have an embargo option, preventing others to access the sequence data prior to publication.”
MethodBeginner’s guide to comparative bacterial genome analysis using next-generation sequence data
Edwards, D., & Holt, K. E. (2013) · Microbial Informatics and Experimentation · doi:10.1186/2042-5783-3-2 · Cited by 145
“Sequence reads and assemblies from a number of outbreak strains, generated using different high through-put sequencing platforms (including Illumina, Ion Torrent and 454) are now available for download from the European Nucleotide Archive [11-17].”
MethodESSENTIALS: Software for Rapid Analysis of High Throughput Transposon Insertion Sequencing Data
Zomer, A., Burghout, P., Bootsma, H. J., Hermans, P. W. M., & van Hijum, S. A. F. T. (2012) · PLoS ONE · doi:10.1371/journal.pone.0043012 · Cited by 138
Hellinger, R., Sigurdsson, A., Wu, W., Romanova, E. V., Li, L., Sweedler, J. V., Süßmuth, R. D., & Gruber, C. W. (2023) · Nature Reviews Methods Primers · doi:10.1038/s43586-023-00205-2 · Cited by 142
Reference databases for taxonomic assignment in metagenomics
Santamaría, M., Fosso, B., Consiglio, A., Caro, G. D., Grillo, G., Licciulli, F., Liuni, S., Marzano, M., Alonso-Alemany, D., Valiente, G., et al. (2012) · Briefings in Bioinformatics · doi:10.1093/bib/bbs036 · Cited by 130
“SILVA [44] provides phylogenetic classification for the small and large rRNA subunits for Bacteria, Archaea and Eukarya in the European Nucleotide Archive [54].”
BackgroundMethodWheatExp: an RNA-seq expression database for polyploid wheat
Pearce, S. P., Vasquez-Gross, H. A., Herin, S. Y., Hane, D. L., Wang, Y., Gu, Y., & Dubcovsky, J. (2015) · BMC Plant Biology · doi:10.1186/s12870-015-0692-1 · Cited by 130
“SRA Short Read Archive, NCBI [14], GEO Gene Expression Omnibus, NCBI [15], ENA European Nucleotide Archive [16] Pearce et al.”
BackgroundInfluentialPATRIC as a unique resource for studying antimicrobial resistance
Antonopoulos, D. A., Assaf, R., Aziz, R. K., Brettin, T. S., Bun, C., Conrad, N. R., Davis, J. J., Dietrich, E. M., Disz, T. L., Gerdes, S., et al. (2017) · Briefings in Bioinformatics · doi:10.1093/bib/bbx083 · Cited by 130
Gene co-expression network connectivity is an important determinant of selective constraint
Mähler, N., Wang, J., Terebieniec, B. K., Ingvarsson, P. K., Street, N. R., & Hvidsten, T. R. (2017) · PLoS Genetics · doi:10.1371/journal.pgen.1006402 · Cited by 133
Ten steps to get started in Genome Assembly and Annotation
Angel, V. D. D., Hjerde, E., Sterck, L., Capella-Gutiérrez, S., Notredame, C., Pettersson, O. V., Amselem, J., Bouri, L., Bocs, S., Klopp, C., et al. (2018) · F1000Research · doi:10.12688/f1000research.13598.1 · Cited by 123
Nilsson, R. H., Tedersoo, L., Lindahl, B. D., Kjøller, R., Carlsen, T., Quince, C., Abarenkov, K., Pennanen, T., Stenlid, J., Bruns, T. D., et al. (2011) · New Phytologist · doi:10.1111/j.1469-8137.2011.03755.x · Cited by 120
Biological Databases for Human Research
Zou, D., Ma, L., Yu, J. M., & Zhang, Z. (2015) · Genomics Proteomics & Bioinformatics · doi:10.1016/j.gpb.2015.01.006 · Cited by 118
“…function of human DNA databases includes establishment of the reference genome ( e.g. , NCBI RefSeq [8]), profiling of human genetic variation ( e.g. , dbSNP [13]), association of genotype with phenotype ( e.g. , EGA [14]), and identification of human microbiome metagen-omes ( e.g. , IMG/HMP [15]).”
BackgroundThe diversity and abundance of fungi and bacteria on the healthy and dandruff affected human scalp
Grimshaw, S. G., Smith, A. M., Arnold, D. S., Xu, E., Hoptroff, M., & Murphy, B. (2019) · PLoS ONE · doi:10.1371/journal.pone.0225796 · Cited by 118
“Fungal OTUs were assigned using the same LCA methodology against SILVA, NCBI, UNITE [49], CAMERA, DDBJ, and EMBL databases.”
MethodThe International Nucleotide Sequence Database Collaboration
Cochrane, G., Karsch‐Mizrachi, I., & Nakamura, Y. (2010) · Nucleic Acids Research · doi:10.1093/nar/gkq1150 · Cited by 113
“Assembled sequences and annotations are available from DDBJ (2), the EMBL-Bank component of the European Nucleotide Archive (3) and GenBank from NCBI (4).”
MethodData analysis: Create a cloud commons
Stein, L. D., Knoppers, B. M., Campbell, P. J., Getz, G. A., & Korbel, J. O. (2015) · Nature · doi:10.1038/523149a · Cited by 110
Data integration in biological research: an overview
Lapatas, V., Stefanidakis, M., Jiménez, R. C., Via, A., & Schneider, M. V. (2015) · Journal of Biological Research - Thessaloniki · doi:10.1186/s40709-015-0032-5 · Cited by 104
“This is happening already for nucleotide sequence data where researchers have to submit newly obtained/sequenced entities to one of the three major sequencing databases [91] and refer to it in the paper.”
BackgroundA gene prioritization method based on a swine multi-omics knowledgebase and a deep learning model
Fu, Y., Xu, J., Tang, Z., Wang, L., Yin, D., Fan, Y., Zhang, D., Deng, F., Zhang, Y., Zhang, H., et al. (2020) · Communications Biology · doi:10.1038/s42003-020-01233-4 · Cited by 101
A resource of variant effect predictions of single nucleotide variants in model organisms
Wagih, O., Busby, B. P., Galardini, M., Memon, D., Typas, A., & Beltrão, P. (2018) · Molecular Systems Biology · doi:10.15252/msb.20188430 · Cited by 97
DNA Metabarcoding for the Characterization of Terrestrial Microbiota—Pitfalls and Solutions
Francioli, D., Lentendu, G., Lewin, S. A., & Kolb, S. (2021) · Microorganisms · doi:10.3390/microorganisms9020361 · Cited by 107
Benchmarking bioinformatic tools for fast and accurate eDNA metabarcoding species identification
Mathon, L., Valentini, A., Guérin, P., Normandeau, É., Noël, C., Lionnet, C., Boulanger, E., Thuiller, W., Bernatchez, L., Mouillot, D., et al. (2021) · Molecular Ecology Resources · doi:10.1111/1755-0998.13430 · Cited by 104
“VSEARCH – usearch_global provided a significantly higher mean sensitivity than ecotag (0.97), and significantly lower mean RMSE (0.4).”
BackgroundInfluentialEderveen, T. H. A., Ferwerda, G., Ahout, I. M. L., Vissers, M., de Groot, R., Boekhorst, J., Timmerman, H. M., Huynen, M. A., van Hijum, S. A. F. T., & de Jonge, M. I. (2018) · Microbiome · doi:10.1186/s40168-017-0395-y · Cited by 97
“uk/ena) under study accession number PRJEB20811 [53].”
The 2011 Nucleic Acids Research Database Issue and the online Molecular Biology Database Collection
Galperin, M. Y., & Cochrane, G. (2010) · Nucleic Acids Research · doi:10.1093/nar/gkq1243 · Cited by 91
Use of Bioinformatics Tools in Different Spheres of Life Sciences
Mehmood, M. A. (2014) · Journal of Data Mining in Genomics & Proteomics · doi:10.4172/2153-0602.1000158 · Cited by 90
“[126]”
Derocles, S. A. P., Bohan, D. A., Dumbrell, A. J., Kitson, J. J. N., Massol, F., Pauvert, C., Plantegenest, M., Vacher, C., & Evans, D. M. (2018) · Advances in ecological research/Advances in Ecological Research · doi:10.1016/bs.aecr.2017.12.001 · Cited by 96
Experimental temperatures shape host microbiome diversity and composition
Li, J., Bates, K. A., Hoang, K. L., Hector, T. E., Knowles, S. C. L., & King, K. C. (2022) · Global Change Biology · doi:10.1111/gcb.16429 · Cited by 101
Chinese hamster genome database: An online resource for the CHO community at www.CHOgenome.org
Hammond, S., Kaplarevic, M., Borth, N., Betenbaugh, M. J., & Lee, K. H. (2011) · Biotechnology and Bioengineering · doi:10.1002/bit.24374 · Cited by 87
“Sequence and annotation information for the CHO-K1 WGS assembly (WGS AFTD01000000), currently consisting of 265,786 contigs and 109,151 annotated scaffolds, and the Chinese hamster mitochondrial genome (Partridge et al., 2007) were retrieved from NCBI GenBank (Benson et al., 2011) and EMBL (Leinonen et al., 2011).”
MethodSheflin, A. M., Borresen, E. C., Wdowik, M. J., Rao, S., Brown, R. J., Heuberger, A. L., Broeckling, C. D., Weir, T. L., & Ryan, E. P. (2015) · Nutrients · doi:10.3390/nu7021282 · Cited by 89
Boulanger, E., Loiseau, N., Valentini, A., Arnal, V., Boissery, P., Déjean, T., Déter, J., Guellati, N., Holon, F., Juhel, J., et al. (2021) · Proceedings of the Royal Society B Biological Sciences · doi:10.1098/rspb.2021.0112 · Cited by 91
“(c) Reference database At the onset of our study only 31% of all Mediterranean fish species [80] were referenced in the European Nucleotide Archive (ENA) [81] (release 138) for the 12S rRNA fragment targeted by the teleo primers.”
Maleki‐Ravasan, N., Oshaghi, M. A., Afshar, D., Arandian, M. H., Hajikhani, S., Akhavan, A. A., Yakhchali, B., Shirazi, M. H., Rassi, Y., Jafari, R., et al. (2015) · Parasites & Vectors · doi:10.1186/s13071-014-0517-3 · Cited by 80
Beckert, P., Sánchez-Padilla, E., Merker, M., Dreyer, V., Kohl, T. A., Utpatel, C., Köser, C. U., Barilar, I., Ismail, N. A., Omar, S. V., et al. (2020) · Genome Medicine · doi:10.1186/s13073-020-00793-8 · Cited by 79
Vision, challenges and opportunities for a Plant Cell Atlas
Ahmed, J., Alaba, O., Ameen, G., Arora, V., Arteaga-Vazquez, M. A., Arun, A., Bailey-Serres, J. N., Bartley, L., Bassel, G. W., Bergmann, D. C., et al. (2021) · eLife · doi:10.7554/elife.66877 · Cited by 80
Triticeae Resources in Ensembl Plants
Bolser, D. M., Kerhornou, A., Walts, B., & Kersey, P. J. (2014) · Plant and Cell Physiology · doi:10.1093/pcp/pcu183 · Cited by 78
“In the longer term, we plan to extend the range and scope of RNA sequence alignments to the plant genomes hosted in Ensembl Plants by developing automatic methods to discover the relevant entries in the European Nucleotide Archive (Leinonen et al., 2011) based on their descriptive meta data.”
MethodInfluentialZerbino, D. R., Johnson, N., Juettemann, T., Sheppard, D., Wilder, S. P., Lavidas, I., Nuhn, M., Perry, E. H., Raffaillac-Desfosses, Q., Sobral, D., et al. (2016) · Database · doi:10.1093/database/bav119 · Cited by 76
“Clicking on a peak displays its type (e.g. DNase1 or the specific TF name); the parameters that defined the region from the data including score and peak summit representing the position of highest sequencing read coverage; and a data source such as an ENA accession.”
BackgroundVIDHOP, viral host prediction with deep learning
Mock, F., Viehweger, A., Barth, E., & Marz, M. (2020) · Bioinformatics · doi:10.1093/bioinformatics/btaa705 · Cited by 76
READv2: advanced and user-friendly detection of biological relatedness in archaeogenomics
Alaçamlı, E., Naidoo, T., Güler, M. N., Sağlıcan, E., Aktürk, Ş., Mapelli, I., Vural, K. B., Somel, M., Malmström, H., & Günther, T. (2024) · Genome biology · doi:10.1186/s13059-024-03350-3 · Cited by 89
“We downloaded 1240K SNP capture BAM files for 94 individuals excavated in Gurgy “les Noisats” [22, 59] from the European Nucleotide Archive [60].”
MethodFORK-seq: replication landscape of the Saccharomyces cerevisiae genome by nanopore sequencing
Hennion, M., Arbona, J., Lacroix, L., Cruaud, C., Theulot, B., Tallec, B. L., Proux, F., Wu, X., Novikova, E., Engelen, S., et al. (2020) · Genome biology · doi:10.1186/s13059-020-02013-3 · Cited by 73
Nagasaki, H., Mochizuki, T., Kodama, Y., Saruhashi, S., Morizaki, S., Sugawara, H., Ohyanagi, H., Kurata, N., Okubo, K., Takagi, T., et al. (2013) · DNA Research · doi:10.1093/dnares/dst017 · Cited by 73
“10 Researchers may wish to reuse massive read datasets in DRA; however, their DRA file size tends to be too large to be downloaded to a local computer.”
BackgroundPhytotoxin production in Aspergillus terreus is regulated by independent environmental signals
Gressler, M., Meyer, F., Heine, D., Hortschansky, P., Hertweck, C., & Brock, M. (2015) · eLife · doi:10.7554/elife.07861 · Cited by 73
The microbiome in rheumatology: Where are we and where should we go?
Manasson, J., Blank, R. B., & Scher, J. U. (2020) · Annals of the Rheumatic Diseases · doi:10.1136/annrheumdis-2019-216631 · Cited by 73
RNAcentral: A vision for an international database of RNA sequences
Bateman, A. G., Agrawal, S., Birney, E., Bruford, E. A., Bujnicki, J. M., Cochrane, G., Cole, J. R., Dinger, M. E., Enright, A. J., Gardner, P. P., et al. (2011) · RNA · doi:10.1261/rna.2750811 · Cited by 73
“Participants included representatives from the following databases: EMBL (Leinonen et al. 2011), Ensembl genomes (Kersey et al. 2010), gtRNAdb (Chan and Lowe 2009), HGNC (Seal et al. 2011), lncRNAdb (Amaral et al. 2011), miRBase (Kozomara and Griffiths-Jones 2011), Modomics (Czerwoniec et al.…”
BackgroundInfluentialHigh GC content causes orphan proteins to be intrinsically disordered
Basile, W., Sachenkova, O., Light, S., & Elofsson, A. (2017) · PLoS Computational Biology · doi:10.1371/journal.pcbi.1005375 · Cited by 68
Brown, N., Cambruzzi, J., Cox, P. J., Davies, M., Dunbar, J., Plumbley, D., Sellwood, M. A., Sim, A., Williams-Jones, B. I., Zwierzyna, M., et al. (2018) · Progress in medicinal chemistry · doi:10.1016/bs.pmch.2017.12.003 · Cited by 75
Chermprapai, S., Ederveen, T. H. A., Broere, F., Broens, E. M., Schlotter, Y. M., van Schalkwijk, S., Boekhorst, J., van Hijum, S. A. F. T., & Rutten, V. P. M. G. (2018) · Veterinary Microbiology · doi:10.1016/j.vetmic.2018.12.022 · Cited by 72
“The raw, unprocessed 16S rRNA and ITS marker gene Illumina sequence reads are publicly available for download at the European Nucleotide Archive (ENA) database (Leinonen et al. 2011) under study accession number: PRJEB20808 (http://www.”
MethodGommers, L. M. M., Ederveen, T. H. A., van der Wijst, J., Bos, C., Kortman, G. A. M., Boekhorst, J., Bindels, R. J. M., de Baaij, J. H. F., & Hoenderop, J. G. J. (2019) · The FASEB Journal · doi:10.1096/fj.201900839r · Cited by 71
“The Illumina 16S marker gene sequencing reads, including corresponding metadata for each sample, are publicly available for download at the European Nucleotide Archive (ENA) database (http://www.ebi.ac.uk/ena) under study accession number PRJJEB29058 (20).”
The BioSample Database (BioSD) at the European Bioinformatics Institute
Gostev, M., Faulconbridge, A., Brandizi, M., Fernandez-Banet, J., Sarkans, U., Brāzma, A., & Parkinson, H. (2011) · Nucleic Acids Research · doi:10.1093/nar/gkr937 · Cited by 70
“Many data resources at the European Bioinformatics Institute (EBI), such as the archive of functional genomics data ArrayExpress (1), the European Nucleotide Archive (ENA) (2), the Proteomics Identification Database PRIDE (3) and the European Genome-phenome Archive (EGA) capture and represent information about samples…”
BackgroundMethodInfluentialDNA traces the origin of honey by identifying plants, bacteria and fungi
Wirta, H., Abrego, N., Miller, K. E., Roslin, T. V., & Vesterinen, E. J. (2021) · Scientific Reports · doi:10.1038/s41598-021-84174-0 · Cited by 69
Multi-study inference of regulatory networks for more accurate models of gene regulation
Castro, D. M., Veaux, N. D., Miraldi, E. R., & Bonneau, R. (2019) · PLoS Computational Biology · doi:10.1371/journal.pcbi.1006591 · Cited by 67
“We downloaded chromatin accessibility data for S. cerevisiae from the European Nucleotide Archive (PRJNA276699) [71, 72].”
BackgroundApplications of deep learning in understanding gene regulation
Li, Z., Gao, E., Zhou, J., Han, W., Xu, X., & Gao, X. (2023) · Cell Reports Methods · doi:10.1016/j.crmeth.2022.100384 · Cited by 73
“Concurrently, omics data from individual studies are continuously uploaded to and collected by publicly accessible databases such as the Sequence Read Archive (SRA), 11 the European Nucleotide Archive (ENA), 12 and the UniProt Archive (UniParc).”
MethodSolving the Problem: Genome Annotation Standards before the Data Deluge
Klimke, W. A., O’Donovan, C., White, O. R., Brister, J. R., Clark, K., Fedorov, B., Karsch‐Mizrachi, I., Pruitt, K. D., & Tatusova, T. A. (2011) · Standards in Genomic Sciences · doi:10.4056/sigs.2084864 · Cited by 67
Daptomycin Resistance in Clinical MRSA Strains Is Associated with a High Biological Fitness Cost
Roch, M., Gagetti, P. S., Davis, J. J., Ceriana, P., Errecalde, L., Corso, A. C., & Rosato, A. E. (2017) · Frontiers in Microbiology · doi:10.3389/fmicb.2017.02303 · Cited by 67
“Strains with a BioSample identifier that unambiguously linked to a single run accession were downloaded from the European Nucleotide Archive (Leinonen et al., 2011).”
MethodA vast evolutionarily transient translatome contributes to phenotype and fitness
Wacholder, A. C., Parikh, S. B., Coelho, N. C., Acar, O., Houghton, C. J., Chou, L., & Carvunis, A. (2023) · Cell Systems · doi:10.1016/j.cels.2023.04.002 · Cited by 65
Voigt, O., Adamski, M., Sluzek, K., & Adamska, M. (2014) · BMC Evolutionary Biology · doi:10.1186/s12862-014-0230-z · Cited by 63
Consensus Transcriptional Landscape of Human End‐Stage Heart Failure
Flores, R. O. R., Lanzer, J. D., Holland, C. H., Leuschner, F., Most, P., Schultz, J., Levinson, R. T., & Sáez-Rodríguez, J. (2021) · Journal of the American Heart Association · doi:10.1161/jaha.120.019667 · Cited by 65
Metadata
- Authors
- Leinonen, R., Akhtar, R., Birney, E., Bower, L., Cerdeno-Tarraga, A., Cheng, Y., Cleland, I., Faruque, N., Goodgame, N., Gibson, R., Hoad, G., Jang, M., Pakseresht, N., Plaister, S., Radhakrishnan, R., Reddy, K., Sobhany, S., Ten Hoopen, P., Vaughan, R., Zalunin, V., & Cochrane, G.
- Affiliations
- European Bioinformatics Institute (GB)
- Corresponding author
- Leinonen, R.
- ORCID
- Venue
- Nucleic Acids Research
- Publisher
- Oxford University Press (OUP)
- Published
- 2010-10-23
- Volume
- 39
- Issue
- Database
- Pages
- D28-D31
- ISSN
- 0305-1048 (ISSN-L)
- 1362-4962
- PMC
- PMC3013801
- OpenAlex
- W2120358246
- Cited by
- 690
- References
- 10
- Citations by year
- 2026: 37 · 2025: 49 · 2024: 74 · 2023: 52 · 2022: 44 · 2021: 64 · 2020: 37 · 2019: 42 · 2018: 41 · 2017: 47 · 2016: 39 · 2015: 48 · 2014: 33 · 2013: 31 · 2012: 23
- FWCI
- 10.60
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Nucleic Acids Research (publishedVersion, cc-by-nc)
- PubMed Central (publishedVersion, cc-by-nc)
- PubMed (publishedVersion)
- Funders
- Wellcome Trust (085532)
- European Molecular Biology Laboratory
- European Commission
- Topics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Genomics and Phylogenetic Studies
- Physical Sciences › Computer Science › Information Systems › Research Data Management Practices
- Social Sciences › Decision Sciences › Information Systems and Management › Scientific Computing and Data Management
- Keywords
- European Nucleotide Archive, Sequence Read Archive, DNA sequence databases, sequence similarity search, European Genome-phenome Archive
- MeSH terms
- Base Sequence, Europe, Databases, Nucleic Acid, Molecular Sequence Annotation, High-Throughput Nucleotide Sequencing
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
