

Large Language Models Outperform Expert Coders and Supervised Classifiers at Annotating Political Social Media Messages
Open accessThe DOI matches its Crossref record; 50 of the 50 references it cites were found in a registry or an index; none of the 11 sources its claims cite is checked for support yet.
Abstract
Instruction-tuned Large Language Models (LLMs) have recently emerged as a powerful new tool for text analysis. As these models are capable of zero-shot annotation based on instructions written in natural language, they obviate the need of large sets of training data—and thus bring potential paradigm-shifting implications for using text as data. While the models show substantial promise, their relative performance compared to human coders and supervised models remains poorly understood and subject to significant academic debate. This paper assesses the strengths and weaknesses of popular fine-tuned AI models compared to both conventional supervised classifiers and manual annotation by experts and crowd workers. The task used is to identify the political affiliation of politicians based on a single X/Twitter message, focusing on data from 11 different countries. The paper finds that GPT-4 achieves higher accuracy than both supervised models and human coders across all languages and country contexts. In the US context, it achieves an accuracy of 0.934 and an inter-coder reliability of 0.982. Examining the cases where the models fail, the paper finds that the LLM—unlike the supervised models—correctly annotates messages that require interpretation of implicit or unspoken references, or reasoning on the basis of contextual knowledge—capacities that have traditionally been understood to be distinctly human. The paper thus contributes to our understanding of the revolutionary implications of LLMs for text analysis within the social sciences.
Overview
CoChat Summary
TL;DR
This paper compares zero-shot GPT-4 annotation of politicians’ party affiliation from single X/Twitter messages against supervised classifiers and human coders across 11 countries. GPT-4 achieves the highest accuracy in all countries, including 0.934 accuracy and 0.982 inter-coder reliability in the US, and succeeds on interpretive cases where supervised models fail.
Key findings
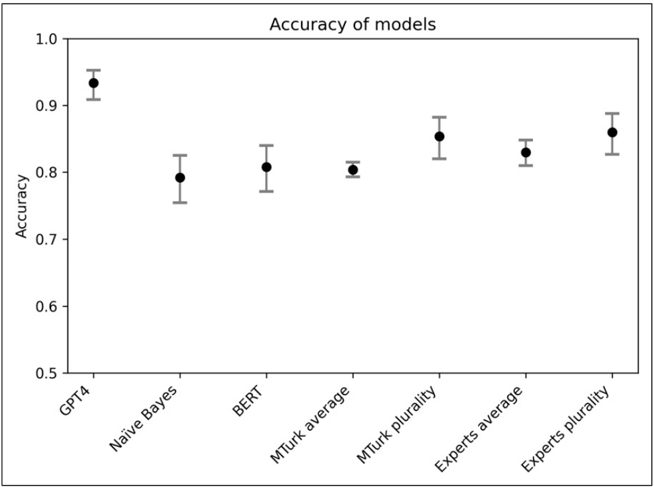
- In the US case, GPT-4 has the highest accuracy and macro F1 of all methods: GPT-4 0.934/0.934, Naïve Bayes 0.792/0.791, BERT 0.808/0.808, MTurk average 0.804/0.803, MTurk plurality 0.854/0.853, experts average 0.830/0.830, experts plurality 0.860/0.860; GPT-4 is statistically significantly better than all other models with 95% confidence.
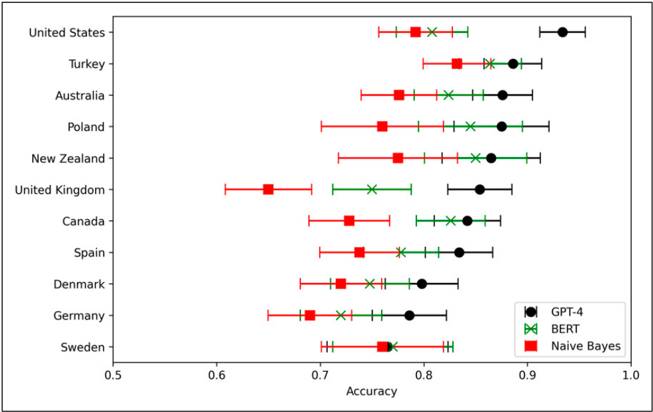
- Across 11 countries and languages, GPT-4 has the highest accuracy of all classifiers for all countries, though accuracy is lower outside the United States; the differences between GPT-4 and supervised models are not significant for all countries.
- Failure analysis shows supervised models fail on messages lacking party-associated words but trivial for humans, while GPT-4 correctly annotated all identified cases where human coders agreed on a correct answer and the LLM was incorrect; GPT-4 also correctly interpreted implicit references, contextual knowledge, and author intentions.
- The model results were found to be stable to variations in instructions (see Figure SI.2).
Methods
- Task: binary, balanced classification of a politician’s party from a single X/Twitter message, using van Vliet et al.’s database across 11 countries; two largest parties per country; random sample of 250 messages per party (500 total) for most countries, and 100 per party for Sweden, New Zealand, and Poland; retweets, replies, URLs, and messages under 100 characters were removed.
- Models: zero-shot GPT-4 (gpt-4-0314) via API with a natural-language prompt; Naïve Bayes bag-of-words baseline; fine-tuned BERT (bert-base-uncased, 3 epochs, batch size 16 training/64 evaluation, AdamW, warmup 500 steps, weight decay 0.01); for the US only, MTurk Master workers (10 independent workers per question, with control questions) and three PhD expert coders.
- Analysis: accuracy and macro F1; Krippendorff’s Alpha for inter-coder reliability; manual examination of all model failures, with follow-up requests for GPT-4 to “motivate your response.”
Limitations
- Paper-stated limitations: the task may be differently challenging across countries due to political differences, and further research is needed to compare LLM capacity across country contexts; the model’s capacity on this specific task may not generalize to other text annotation tasks.
- Evident in the text: human comparison (MTurk and experts) is only available for the US; some country samples are smaller (100 messages per party); LLM motivations are described as potentially post-hoc rationalizations; the GPT-4 version is fixed at gpt-4-0314; and MTurk was run in early March 2023, before LLM use among crowd workers was widespread.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
0 Valid · 1 Not valid · 12 Not checked · 83 Own results and interpretations
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As expected, the Naïve Bayes has the worst performance of all models-but still achieves a respectable 79.2% accuracy”
§ Large Language Models Outperform Expert Coders and Supervised Classifiers at Annotating Political Social Media Messages > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The LLM also correctly interprets messages that require making inferences based on the assumptions of the aims and intentions of the poster.”
§ Large Language Models Outperform Expert Coders and Supervised Classifiers at Annotating Political Social Media Messages > In-Depth Examination of Model Failures
plainSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Finally, there are several examples of the LLM outperforming both MTurkers and experts on tasks involving subjective and contextual interpretation-seemingly as the LLM simply does a better job of scoping the motivations of the poster and making valid inductions.”
§ Large Language Models Outperform Expert Coders and Supervised Classifiers at Annotating Political Social Media Messages > In-Depth Examination of Model Failures
hedgedstates a causeSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The LLM has the highest accuracy in the United States, but the LLM has the highest accuracy of all classifiers across all countries and languages.”
§ Large Language Models Outperform Expert Coders and Supervised Classifiers at Annotating Political Social Media Messages > Discussion
plainSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The examination reveals clearly that the models display different patterns of failure.”
§ Large Language Models Outperform Expert Coders and Supervised Classifiers at Annotating Political Social Media Messages > In-Depth Examination of Model Failures
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
20 more claims
Create a free account to see all 96 claims and to verify the 6 references still open.
- It may state two separate claims as one. 40
- Borderline: one of the tests for a substantial claim is unclear. 1
- The quote only partly states this claim. 1
- Probably not a substantial claim. 49
Citations
Cites
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Advances in Neural Information Processing Systems 19
(2007) · The MIT Press eBooks · doi:10.52202/085713 · Cited by 15,539
Telling more than we can know: Verbal reports on mental processes.
Nisbett, R. E., & Wilson, T. D. (1977) · Psychological Review · doi:10.1037/0033-295x.84.3.231 · Cited by 11,317
Introduction to Information Retrieval
Manning, C. D., Raghavan, P., & Schütze, H. (2008) · doi:10.1017/cbo9780511809071 · Cited by 11,288
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P. J. (2019) · arXiv · doi:10.48550/arxiv.1910.10683 · Cited by 10,929
The Content Analysis Guidebook
Neuendorf, K. A. (2017) · doi:10.4135/9781071802878 · Cited by 9,286 · cited 1×
“However, manual annotation is also not without its own issues (Murthy et al., 2019; Van Atteveldt et al., 2021), as humans can be slow, costly, biased, and prone to fatigue, all of which can undermine data quality and limit the scope of analysis (Grimmer & Stewart, 2013; Neuendorf, 2017).”
Scikit-learn: Machine Learning in Python
(2011) · Journal of Machine Learning Research · doi:10.5555/1953048.2078195 · Cited by 8,539
The Structure of Scientific Revolutions
Hall, M. B., & Kuhn, T. S. (1963) · The American Historical Review · doi:10.2307/1847040 · Cited by 7,479
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Text as Data: The Promise and Pitfalls of Automatic Content Analysis Methods for Political Texts
Grimmer, J., & Stewart, B. M. (2013) · Political Analysis · doi:10.1093/pan/mps028 · Cited by 3,297 · cited 2×
“However, manual annotation is also not without its own issues (Murthy et al., 2019; Van Atteveldt et al., 2021), as humans can be slow, costly, biased, and prone to fatigue, all of which can undermine data quality and limit the scope of analysis (Grimmer & Stewart, 2013; Neuendorf, 2017).”
A comparison of event models for naive bayes text classification
McCallum, A., & Nigam, K. (1998) · Cited by 3,289
Moretti, F. (2013) · Cited by 3,022
Sayer, A. (2000) · doi:10.4135/9781446218730 · Cited by 2,259 · cited 1×
“…interpretation lies at the very heart of the social sciences, it has thus been seen as almost de fi nitionally qualitative; “ meaning has to be understood, it cannot be measured or counted, and hence there is always an interpretive or hermeneutic element in social science ” (Sayer, 2000, p. 17).”
Large language models are zero-shot reasoners
Kojima, T., Gu, S. (., Reid, M., Matsuo, Y., & Iwasawa, Y. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1613 · Cited by 2,013
Large Language Models are Zero-Shot Reasoners
Kojima, T., Gu, S. S., Reid, M., Matsuo, Y., & Iwasawa, Y. (2022) · arXiv · doi:10.48550/arxiv.2205.11916 · Cited by 2,013
Scaling Instruction-Finetuned Language Models
Chung, H. W., Hou, L., Longpre, S., Zoph, B., Tay, Y., Fedus, W., Li, Y., Wang, X., Dehghani, M., Brahma, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2210.11416 · Cited by 1,441
Emergent Abilities of Large Language Models
Wei, J., Tay, Y., Bommasani, R., Raffel, C., Zoph, B., Borgeaud, S., Yogatama, D., Bosma, M., Zhou, D., Metzler, D., et al. (2022) · arXiv · doi:10.48550/arxiv.2206.07682 · Cited by 1,264
ChatGPT Outperforms Crowd-Workers for Text-Annotation Tasks
Gilardi, F., Alizadeh, M., & Kubli, M. (2023) · arXiv · doi:10.48550/arxiv.2303.15056 · Cited by 1,207
ChatGPT outperforms crowd workers for text-annotation tasks
Gilardi, F., Alizadeh, M., & Kubli, M. (2023) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2305016120 · Cited by 1,197 · cited 2×
“…promise, the relative performance of zero-shot learning LLMs in comparison to conventional supervised models and manual coding remains poorly understood and subject to signi fi cant academic debate (Ding et al., 2023; Gilardi et al., 2023; He et al., 2023; Zhu et al., 2023; Ziems et al., 2024).”
An MTurk Crisis? Shifts in Data Quality and the Impact on Study Results
Chmielewski, M., & Kucker, S. C. (2020) · Social Psychological and Personality Science · doi:10.1177/1948550619875149 · Cited by 1,027 · cited 1×
“MTurk classi fi cation however varies signi fi cantly in quality depending on the details of how the tasks are implemented, making it perilous to compare models with MTurk accuracy without additional veri fi cation (Chmielewski & Kucker, 2020).”
Can Large Language Models Transform Computational Social Science?
Ziems, C., Held, W., Shaikh, O., Chen, J., Zhang, Z., & Yang, D. (2023) · arXiv · doi:10.48550/arxiv.2305.03514 · Cited by 839
Reading Machines: Toward an Algorithmic Criticism
Ramsay, S. (2011) · University of Illinois Press eBooks · doi:10.5406/illinois/9780252036415.001.0001 · Cited by 605
Can Large Language Models Transform Computational Social Science?
Ziems, C., Held, W., Shaikh, O., Chen, J., Zhang, Z., & Yang, D. (2024) · Computational Linguistics · doi:10.1162/coli_a_00502 · Cited by 585
GLUE: A Multi-Task Benchmark and Analysis Platform for Natural Language Understanding
Wang, A., Singh, A., Michael, J., Hill, F., Levy, O., & Bowman, S. R. (2018) · arXiv · doi:10.48550/arxiv.1804.07461 · Cited by 562
Fine-Tuning Language Models from Human Preferences
Ziegler, D. M., Stiennon, N., Wu, J., Brown, T. B., Radford, A., Amodei, D., Christiano, P., & Irving, G. (2019) · arXiv · doi:10.48550/arxiv.1909.08593 · Cited by 413
van Atteveldt, W., van der Velden, M. A. C. G., & Boukes, M. (2021) · Communication Methods and Measures · doi:10.1080/19312458.2020.1869198 · Cited by 409
AnnoLLM: Making Large Language Models to Be Better Crowdsourced Annotators
He, X., Lin, Z., Gong, Y., Jin, A.-L., Zhang, H., Chen, L., Jiao, J., Yiu, S., Duan, N., & Chen, W. (2024) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2024.naacl-industry.15 · Cited by 379
Can Generative AI improve social science?
Bail, C. A. (2024) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2314021121 · Cited by 369
Can Generative AI Improve Social Science?
Bail, C. A. (2023) · doi:10.31235/osf.io/rwtzs · Cited by 369
Gender and Representation Bias in GPT-3 Generated Stories
Lucy, L., & Bamman, D. (2021) · Proceedings of the Third Workshop on Narrative Understanding · doi:10.18653/v1/2021.nuse-1.5 · Cited by 287
Best Practices for Text Annotation with Large Language Models
Törnberg, P. (2024) · Sociologica · doi:10.48550/arxiv.2402.05129 · Cited by 230
Self-citationBenchmarking Zero-shot Text Classification: Datasets, Evaluation and Entailment ApproachPreprint
Yin, W., Hay, J., & Roth, D. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1909.00161 · Cited by 223
Introduction to Natural Language Processing
Ami Podrebarac, A. (2019) · Fragmentation of the Photographic Image in the Digital Age · doi:10.4324/9781351027946-15 · Cited by 175
Is GPT-3 a Good Data Annotator?
Ding, B., Qin, C., Liu, L., Chia, Y. K., Li, B., Joty, S., & Bing, L. (2023) · Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2023.acl-long.626 · Cited by 149
The Twitter parliamentarian database: Analyzing Twitter politics across 26 countries
van Vliet, L., Törnberg, P., & Uitermark, J. (2020) · PLoS ONE · doi:10.1371/journal.pone.0237073 · Cited by 129
Self-citationHow to Use Large-Language Models for Text Analysis
Törnberg, P. (2024) · SAGE Publications Ltd eBooks · doi:10.4135/9781529683707 · Cited by 114
Self-citationLiesenfeld, A., Lopez, A., & Dingemanse, M. (2023) · Proceedings of the 5th International Conference on Conversational User Interfaces · doi:10.1145/3571884.3604316 · Cited by 111 · cited 1×
“It also allows the use of models that are more open in terms of their code, training data, model weights, licensing, and documentation (Liesenfeld et al., 2023).”
Can ChatGPT Reproduce Human-Generated Labels? A Study of Social Computing Tasks
Zhu, Y., Zhang, P., Haq, E.-U., Hui, P., & Tyson, G. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2304.10145 · Cited by 63
The dangers of using proprietary LLMs for research
Ollion, É., Shen, R., Macanovic, A., & Chatelain, A. (2024) · Nature Machine Intelligence · doi:10.1038/s42256-023-00783-6 · Cited by 62 · cited 3×
“When dealing with proprietary, secret, con fi dential, or personal data, it can hence be advisable to use a model hosted on your own infrastructure rather than relying on cloud-based APIs (Ollion et al., 2024).”
For a heterodox computational social science
Törnberg, P., & Uitermark, J. (2021) · Big Data & Society · doi:10.1177/20539517211047725 · Cited by 62
Self-citationAre chatbots reliable text annotators? Sometimes
Kristensen‐McLachlan, R. D., Canavan, M., Kardos, M., Jacobsen, M., & Aarøe, L. (2025) · PNAS Nexus · doi:10.1093/pnasnexus/pgaf069 · Cited by 55
AnnoLLM: Making Large Language Models to Be Better Crowdsourced Annotators
He, X., Lin, Z., Gong, Y., Jin, A.-L., Zhang, H., Lin, C., Jiao, J., Yiu, S. M., Duan, N., & Chen, W. (2023) · arXiv · doi:10.48550/arxiv.2303.16854 · Cited by 34
van Vliet, L., Törnberg, P., & Uitermark, J. (2021) · International journal of communication · Cited by 20
Self-citationIs GPT-3 a Good Data Annotator?
Ding, B., Qin, C., Liu, L., Chia, Y. K., Joty, S., Li, B., & Bing, L. (2022) · arXiv · doi:10.48550/arxiv.2212.10450 · Cited by 15
TwitSenti: A Real-Time Twitter Sentiment Analysis and Visualization Framework
Murthy, J. S., Siddesh, G. M., & Srinivasa, K. G. (2019) · Journal of Information & Knowledge Management · doi:10.1142/s0219649219500138 · Cited by 10
OpenAI, Achiam, J., Adler, S., Agarwal, S., Ahmad, L., Akkaya, I., Aleman, F. L., Almeida, D., Altenschmidt, J., Altman, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.08774
(2001)
(1962)
Are Chatbots Reliable Text Annotators? Sometimes
Kristensen-McLachlan, R. D., Canavan, M., Kardos, M., Jacobsen, M., & Aarøe, L. (2023) · arXiv · doi:10.48550/arxiv.2311.05769
Cited by
Best Practices for Text Annotation with Large Language Models
Törnberg, P. (2024) · Sociologica · doi:10.48550/arxiv.2402.05129 · Cited by 230
Self-citationWe Reject the Use of Generative Artificial Intelligence for Reflexive Qualitative Research
Jowsey, T., Braun, V., Clarke, V., Lupton, D. A., & Fine, M. (2025) · Qualitative Inquiry · doi:10.1177/10778004251401851 · Cited by 188
Generative Artificial Intelligence in Qualitative Data Analysis: Analyzing—Or Just Chatting?
Nguyen, D. C., & Welch, C. (2025) · Organizational Research Methods · doi:10.1177/10944281251377154 · Cited by 124
Large Language Model Hacking: Quantifying the Hidden Risks of Using LLMs for Text AnnotationPreprint
Baumann, J., Röttger, P., Urman, A., Wendsjö, A., Plaza-del-Arco, F. M., Gruber, J. B., & Hovy, D. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2509.08825 · Cited by 107
Peykani, P., Ramezanlou, F., Tănăsescu, C. R., & Ghanidel, S. (2025) · Applied Sciences · doi:10.3390/app15148103 · Cited by 84
Metadata
- Authors
- Törnberg, P.
- Affiliations
- University of Neuchâtel (CH)
- Corresponding author
- Törnberg, Petter
- ORCID
- Törnberg, Petter
- Venue
- Social Science Computer Review
- Publisher
- SAGE Publications
- Published
- 2024-09-22
- Volume
- 43
- Issue
- 6
- Pages
- 1181-1195
- ISSN
- 0894-4393 (ISSN-L)
- 1552-8286
- OpenAlex
- W4402740791
- Cited by
- 249
- References
- 43
- Citations by year
- 2026: 166 · 2025: 80 · 2024: 3
- FWCI
- 76.58
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- creativecommons.org/licenses/by/4.0/ (vor)
- journals.sagepub.com/page/policies/text-and-data-mining-license (tdm)
- Locations
- Social Science Computer Review (publishedVersion, cc-by)
- UvA-DARE (University of Amsterdam) (publishedVersion, cc-by)
- Funders
- Sociale en Geesteswetenschappen, NWO (VI.Veni.201S.006)
- Topics
- Social Sciences › General Social Sciences › Computational and Text Analysis Methods
- Physical Sciences › Computer Science › Artificial Intelligence › Sentiment Analysis and Opinion Mining
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Keywords
- large language models, Twitter, GPT-4, intercoder reliability, supervised classifiers, implicit references, contextual reasoning, text-as-data
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-21, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-21 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
