

The DOI matches its Crossref record; 71 of the 71 references it cites were found in a registry or an index.
A neural network multi-task learning approach to biomedical named entity recognition
Open accessAbstract
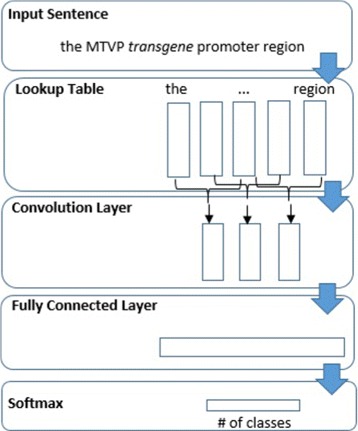
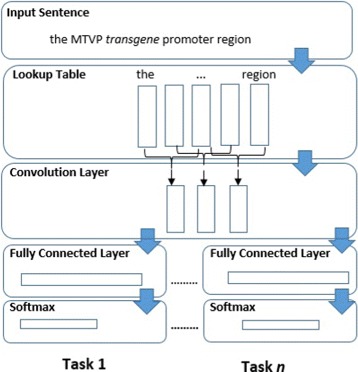
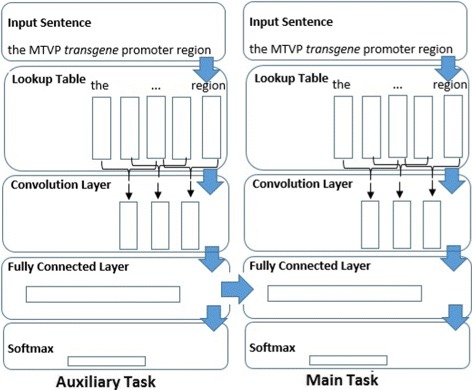
BACKGROUND: Named Entity Recognition (NER) is a key task in biomedical text mining. Accurate NER systems require task-specific, manually-annotated datasets, which are expensive to develop and thus limited in size. Since such datasets contain related but different information, an interesting question is whether it might be possible to use them together to improve NER performance. To investigate this, we develop supervised, multi-task, convolutional neural network models and apply them to a large number of varied existing biomedical named entity datasets. Additionally, we investigated the effect of dataset size on performance in both single- and multi-task settings. RESULTS: We present a single-task model for NER, a Multi-output multi-task model and a Dependent multi-task model. We apply the three models to 15 biomedical datasets containing multiple named entities including Anatomy, Chemical, Disease, Gene/Protein and Species. Each dataset represent a task. The results from the single-task model and the multi-task models are then compared for evidence of benefits from Multi-task Learning. With the Multi-output multi-task model we observed an average F-score improvement of 0.8% when compared to the single-task model from an average baseline of 78.4%. Although there was a significant drop in performance on one dataset, performance improves significantly for five datasets by up to 6.3%. For the Dependent multi-task model we observed an average improvement of 0.4% when compared to the single-task model. There were no significant drops in performance on any dataset, and performance improves significantly for six datasets by up to 1.1%. The dataset size experiments found that as dataset size decreased, the multi-output model's performance increased compared to the single-task model's. Using 50, 25 and 10% of the training data resulted in an average drop of approximately 3.4, 8 and 16.7% respectively for the single-task model but approximately 0.2, 3.0 and 9.8% for the multi-task model. CONCLUSIONS: Our results show that, on average, the multi-task models produced better NER results than the single-task models trained on a single NER dataset. We also found that Multi-task Learning is beneficial for small datasets. Across the various settings the improvements are significant, demonstrating the benefit of Multi-task Learning for this task.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Machine learning methods11–14, particularly deep learning, typically employ neural networks and the first generation of transformer-based large language models (e.g., BERT).”
From A critical assessment of using ChatGPT for extracting structured data from clinical notes (2024) · cites this paper as [11]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Very Deep Convolutional Networks for Large-Scale Image Recognition
Simonyan, K., & Zisserman, A. (2014) · arXiv · doi:10.48550/arxiv.1409.1556 · Cited by 114,148
Adam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946
(2014) · Cited by 33,419
Efficient Estimation of Word Representations in Vector Space
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013) · arXiv · doi:10.48550/arxiv.1301.3781 · Cited by 26,568
Advances in Neural Information Processing Systems 19
(2007) · The MIT Press eBooks · doi:10.52202/085713 · Cited by 16,043
(2010) · International Conference on Machine Learning · Cited by 13,995
Natural Language Processing (almost) from ScratchPreprint
Collobert, R., Weston, J., Bottou, L., Karlen, M., Kavukcuoglu, K., & Kuksa, P. P. (2011) · arXiv (Cornell University) · doi:10.48550/arxiv.1103.0398 · Cited by 6,923
Caruana, R. (1997) · Machine Learning · doi:10.1023/a:1007379606734 · Cited by 6,636
A unified architecture for natural language processing: deep neural networks with multitask learning
Collobert, R., & Weston, J. (2008) · Proceedings of the 25th international conference on Machine learning - ICML '08 · doi:10.1145/1390156.1390177 · Cited by 5,058
Learning deep structured semantic models for web search using clickthrough data
Huang, P.-S., He, X., Gao, J., Deng, L., Acero, A., & Heck, L. P. (2013) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/2505515.2505665 · Cited by 2,120
Research works printed but not linked: 5
- Wei CH, Peng Y, Leaman R, Davis AP, Mattingly CJ, Li J, Wiegers TC, Lu Z. Overview of the Biocreative V chemical disease relation (CDR) task. In: Proceedings of the BioCreative 5 Workshop. Sevilla: The Fifth BioCreative challenge evaluation workshop 2015: 2015. p. 154–66.
- Bakker B, Heskes T. Task clustering and gating for bayesian multitask learning. J Mach Learn Res. 2003; 4:83–99.
- Leaman R, Miller C, Gonzalez G. Enabling recognition of diseases in biomedical text with machine learning: corpus and benchmark. In: Proceedings of the 2009 Symposium on Languages in Biology and Medicine, vol. 82. Jeju Island: The 3rd International Symposium on Languages in Biology and Medicine: 2009.
- Ando RK. Biocreative ii gene mention tagging system at ibm watson. In: Proceedings of the Second BioCreative Challenge Evaluation Workshop, vol. 23. Madrid: Centro Nacional de Investigaciones Oncologicas (CNIO): 2007. p. 101–3.
- Li H, Chen Q, Chen K, Tang B. HITSZ CDR system for disease and chemical named entity recognition and relation extraction. In: Proceedings of the Fifth BioCreative Challenge Evaluation Workshop. Sevilla: The fifth BioCreative challenge evaluation workshop 2015: 2015. p. 196–201.
Cited by
Sorted by citations
Items 201–231 of 231
Disease Named Entity Recognition (D-NER) EvaluationPreprint
Xie, X.-Y. (2021) · Research Square · doi:10.21203/rs.3.rs-911654/v1
Matching Document Pairs using Multi-Feature Semantic Fusion Based on Knowledge GraphPreprint
Chen, Y., Zhang, Z., Huang, X., Xiang, X., He, Z., Chen, Y., & Hu, Q. (2021) · Research Square · doi:10.21203/rs.3.rs-907473/v1
Using Contextualized Representations For Biomedical Entity Recognition
Xiao, Y., Liang, S.-P., Peng, J., Huang, Z., Wang, Y., & Wang, J. (2021) · International Conference on Computer Engineering and Application (ICCEA) · doi:10.1109/iccea53728.2021.00095
Learning Entity-Likeness with Multiple Approximate Matches for Biomedical NER
Le, A. N., Morita, H., & Iwakura, T. (2021) · International conference Recent advances in natural language processing · doi:10.26615/978-954-452-072-4_117
Fast Neural Network Engine for Natural Science Language Processing: A Drug-Search Case.Preprint
Korolev, V., Mitrofanov, A. A., Karpov, K. V., & Tkachenko, V. (2020) · ChemRxiv · doi:10.26434/chemrxiv.12800348
Fast Neural Network Engine for Natural Science Language Processing: A Drug-Search Case.Preprint
Korolev, V., Mitrofanov, A. A., Karpov, K., & Tkachenko, V. (2020) · ChemRxiv · doi:10.26434/chemrxiv.12800348.v2
Fast Neural Network Engine for Natural Science Language Processing: A Drug-Search Case.Preprint
Korolev, V., Mitrofanov, A. A., Karpov, K., & Tkachenko, V. (2020) · ChemRxiv · doi:10.26434/chemrxiv.12800348.v1
A Review on Clinical Named Entity Recognition
Kashtriya, P., Singh, P., & Bansal, P. (2023) · OPJU International Technology Conference on Smart Computing for Innovation and Advancement in Industry (OTCON) · doi:10.1109/otcon56053.2023.10113977
Auxiliary Learning for Named Entity Recognition with Multiple Auxiliary Training Data
Watanabe, T., Ichikawa, T., Tamura, A., Iwakura, T., Ma, C., & Kato, T. (2023) · Journal of Natural Language Processing · doi:10.5715/jnlp.30.507
Comprehensive Review of Deep learning Techniques in Electronic Medical Records
Biruntha, S., Revathy, M., Mahaboob, R., & Meenakshi, V. (2023) · ITM Web of Conferences · doi:10.1051/itmconf/20235603001
A Subword-Centric Character Level Representation for Named Entity Recognition
Gao, F., Liu, C., Pan, Y., Wang, X., & Yin, Y. (2023) · Lecture notes in networks and systems · doi:10.1007/978-3-031-37963-5_79
Biomedical Knowledge Representation Learning
Zeng, Z., Liu, Z., Lin, Y., & Sun, M. (2023) · Springer eBooks · doi:10.1007/978-981-99-1600-9_12
Evaluation on Network Social Media Named Entity Recognition Model Based on Active Learning
He, G., Zhou, Y., & Zheng, Y. (2023) · ACM Transactions on Asian and Low-Resource Language Information Processing · doi:10.1145/3600055
Additional file 2 of Parallel sequence tagging for concept recognition
Furrer, L., Cornelius, J., & Rinaldi, F. (2022) · Figshare · doi:10.6084/m9.figshare.19418422
Additional file 1 of Parallel sequence tagging for concept recognition
Furrer, L., Cornelius, J., & Rinaldi, F. (2022) · Figshare · doi:10.6084/m9.figshare.19418419
An, X. Q., Li, S., Zhang, Y., Shen, M., Wang, Y., & Wu, X. L. (2024) · Research Square · doi:10.21203/rs.3.rs-4494420/v1
Biomedical Named Entity Recognition Model Based on Knowledge Distillation
Han, R., Zheng, D., Feng, Y., Li, Y., & Hu, J. J. (2024) · Smart innovation, systems and technologies · doi:10.1007/978-981-97-3980-6_38
Introduction to intelligent techniques and applications
Jain, P., & Gupta, S. (2024) · Elsevier eBooks · doi:10.1016/b978-0-443-15999-2.00012-8
Partial Annotation Learning for Biomedical Entity Recognition
Ding, L., Colavizza, G., & Zhang, Z. (2024) · IEEE Journal of Biomedical and Health Informatics · doi:10.1109/jbhi.2024.3466294 · Cited by 1
Tsai, C.-T., Upadhyay, S., & Roth, D. (2024) · Synthesis lectures on human language technologies · doi:10.1007/978-3-031-74901-8_4
A Novel Low-Resource Graph Convolutional Neural Network Approach for Entity Recognition
Zhao, Z., & Li, X. (2025) · IEEE Transactions on Computational Biology and Bioinformatics · doi:10.1109/tcbbio.2025.3614139
Raza, S., & Schwartz, B. (2024) · Figshare · doi:10.6084/m9.figshare.26564418
Design and Development of a System for Unveiling Inauthenticity in Audio Content
Kale, S. D., Tipale, J., Sonawane, S., Mulay, K., Patil, G., & Khumkar, N. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-12987-1_23
Tourille, J. (2018) · theses.fr (ABES) · doi:10.70675/02d56023z06bez4e94zac3fz62d58fd755ad · Cited by 5
Alphonse, J., Babu, P., Achutan, S., Kumar, G. B., & Melethadathil, N. (2026) · Scientific Reports · doi:10.1038/s41598-026-48856-x
AI-Powered Medical Report Analyzer and Organ Visualization
Aswani, A. J., Prabha, S. K., Saj, P. S. S., & Veena, G. (2026) · Lecture notes in networks and systems · doi:10.1007/978-3-032-20606-0_43
A Contextual and Sequential Model for Biomedical Named Entity Recognition
Pandey, D. C., & Katarya, R. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-26349-0_35
VILLA: V ersatile I nformation Retrieval from Scientific L iterature Using Large La nguage Models
Antony, B., Dutta, A., Aggarwal, S., Gatne, V., Gökdemir, O., Grimes, S. L., Lauring, A. S., Wasik, B. R., Karpatne, A., & Murali, T. M. (2026) · ACM SIGKDD Conference on Knowledge Discovery and Data Mining (KDD) · doi:10.1145/3770855.3819035
Adapted KoGNER: A Knowledge-Augmented Architecture for Biomedical Named Entity Recognition
Durmaz, A., & Bursa, O. (2026) · IEEE Annual International Computer Software and Applications Conference (COMPSAC) · doi:10.1109/compsac69091.2026.00343
Zhang, Y., & Qing, H. (2026) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2026.115986
BigBIO: A Framework for Data-Centric Biomedical Natural Language Processing
Fries, J. A., Weber, L., Seelam, N., Altay, G., Datta, D., Garda, S., Kang, M., Su, R., Kusa, W., Cahyawijaya, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2206.15076 · Cited by 17
Metadata
- Authors
- Crichton, G., Pyysalo, S., Chiu, B., & Korhonen, A.
- Affiliations
- University of Cambridge (GB)
- Corresponding author
- Crichton, Gamal
- Venue
- BMC Bioinformatics
- Published
- 2017-08-15
- Volume
- 18
- Issue
- 1
- Pages
- 368-368
- ISSN
- 1471-2105 (ISSN-L)
- PMC
- PMC5558737
- OpenAlex
- W2743028754
- Cited by
- 229
- References
- 71
- Citations by year
- 2026: 8 · 2025: 6 · 2024: 23 · 2023: 37 · 2022: 32 · 2021: 44 · 2020: 32 · 2019: 36 · 2018: 9 · 2017: 2
- FWCI
- 8.82
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- cc-by
- Locations
- BMC Bioinformatics (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Apollo (University of Cambridge) (submittedVersion, cc-by)
- Apollo
- Funders
- Medical Research Council (MR/M013049/1)
- Cambridge Commonwealth, European and International Trust
- Topics
- Health Sciences › Medicine › Health Informatics › Biomedical Text Mining and Ontologies
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- biomedical named entity recognition, multi-task learning, convolutional neural networks, multi-output models, dataset size effects, limited training data, biomedical text mining, chemical entity, disease entity
- MeSH terms
- Machine Learning, Models, Theoretical, Databases, Factual, Neural Networks, Computer, Data Mining
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
