

The DOI matches its Crossref record; 61 of the 61 references it cites were found in a registry or an index; 33 of the 56 sources its claims cite were checked for support.
The SAFE procedure: a practical stopping heuristic for active learning-based screening in systematic reviews and meta-analyses
Open accessPublished version of a preprint
Abstract
Active learning has become an increasingly popular method for screening large amounts of data in systematic reviews and meta-analyses. The active learning process continually improves its predictions on the remaining unlabeled records, with the goal of identifying all relevant records as early as possible. However, determining the optimal point at which to stop the active learning process is a challenge. The cost of additional labeling of records by the reviewer must be balanced against the cost of erroneous exclusions. This paper introduces the SAFE procedure, a practical and conservative set of stopping heuristics that offers a clear guideline for determining when to end the active learning process in screening software like ASReview. The eclectic mix of stopping heuristics helps to minimize the risk of missing relevant papers in the screening process. The proposed stopping heuristic balances the costs of continued screening with the risk of missing relevant records, providing a practical solution for reviewers to make informed decisions on when to stop screening. Although active learning can significantly enhance the quality and efficiency of screening, this method may be more applicable to certain types of datasets and problems. Ultimately, the decision to stop the active learning process depends on careful consideration of the trade-off between the costs of additional record labeling against the potential errors of the current model for the specific dataset and context.
Overview
CoChat Summary
TL;DR
The paper introduces the SAFE procedure, a conservative four-phase stopping heuristic for active learning-based screening in systematic reviews and meta-analyses. It combines multiple stopping checks to balance the cost of continued labeling against the risk of missing relevant records.
Key findings
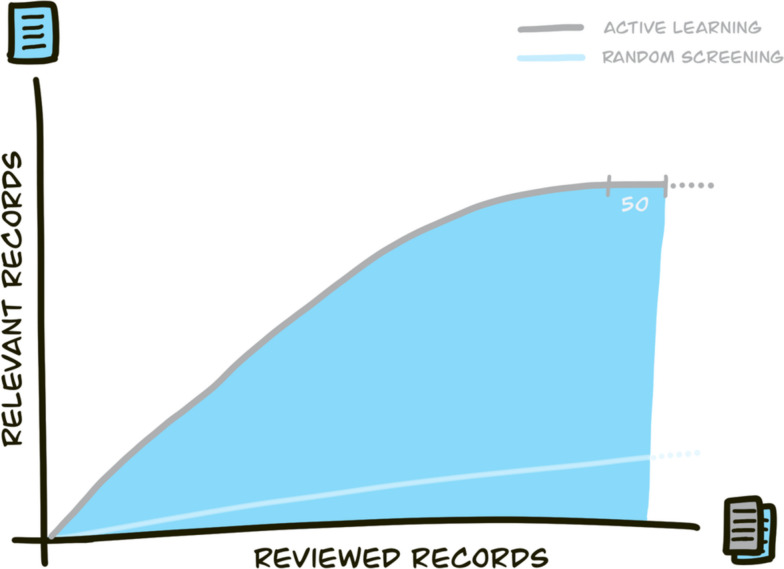
- SAFE consists of four phases: screen a random training set, apply active learning, find more relevant records with a different model, and evaluate quality. In Phase 2, screening stops only when all four conditions are met: all key papers are marked relevant; at least twice the estimated total relevant records (RR_T) have been screened; at least 10% of the total dataset has been screened; and no relevant records have been identified in the last, for example, 50 records.
- An expert meeting with 26 information specialists, data scientists, and active-learning users from the Netherlands and Germany on 12-01-2023 supported a minimum percentage of records screened combined with a threshold of 50 consecutive irrelevant records as “safe and reasonable.” Visual inspection of the recall plot was viewed positively but not precise enough as a stopping rule on its own.
- Experts agreed key papers are useful for validating screening results but may introduce bias if used as prior knowledge in active learning. The paper also notes that humans typically miss around 10% of relevant records.
- Time estimates include Phase 4 taking maybe only 1–2 h, while neural network training in Phase 3 may take up to 6 h on a high-performance cluster; deep learning may be less practical for datasets over 50,000 records due to training times.
Methods
- The stopping heuristic was initially developed in December 2022, inspired by the procedure used by Brouwer et al., and was peer-reviewed on 12-01-2023 by 26 experts. Feedback was collected digitally via Wooclap, discussed by the authors, and used to adapt the heuristic.
- The paper presents the resulting SAFE procedure, its assumptions, four phases, example stopping values, and practical implementation guidance; it does not report an empirical dataset analysis or a direct comparison with existing stopping heuristics.
- The expert feedback focused on use of a minimum percentage to screen, a conservative number of consecutive irrelevant records, visual inspection of the recall plot, and use of key papers as prior knowledge.
Limitations
- The paper states that a direct comparison with existing stopping heuristics has not been presented, and future comparative analysis is needed to validate effectiveness and efficiency in different contexts.
- The paper states that the cut-off values are examples and may not suit small datasets; for a dataset of only 500 records, screening 1% means only 5 records, and the observed fraction may not represent the complete set, potentially leading to over-screening.
- The paper states that the proposed batch size depends on the research question, domain, and desired recall, and that the procedure may not apply to all active learning scenarios or types of data and models; it also notes diminishing returns and training-time concerns in the deep learning phase.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures


Verification
Claims the paper makes
17 Valid · 4 Not valid · 4 Not checked · 48 Own results and interpretations
Every source the paper cites for this claim was checked and supports it.
In the paper
“However, defining a stopping rule is difficult as the cost of labeling additional records must be balanced against the cost of errors made by the model [15].”
§ The SAFE procedure: a practical stopping heuristic for active learning-based screening in systematic reviews and meta-analyses > Introduction
What the sources say
- Supportedcites [15] Cormack, G. v., & Grossman, M. R. (2016). Engineering quality and reliability in technology-assisted review. SIGIR 2016 - Proceedings of the 39th International ACM SIGIR Conference on Research and Development in Information Retrieval, 75–84. https://doi.org/10.1145/2911451.2911510 source
The Background section identifies deciding when to stop as a central problem. Section 6, “Diminishing Loss,” evaluates both relevance loss and review-effort loss, and describes the preferred method as balancing high recall against low effort. That supports the claim’s trade-off between additional labeling and missed relevant records. (LLM, conf=0.88)
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“While finding all relevant records is nearly impossible, even for human screeners [52]”
§ The SAFE procedure: a practical stopping heuristic for active learning-based screening in systematic reviews and meta-analyses > Introduction
What the sources say
- Supportedcites [52] Wang Z, Nayfeh T, Tetzlaff J, O’Blenis P, Murad MH. Error rates of human reviewers during abstract screening in systematic reviews. PLoS ONE. 2020;15(1):1–8. https://doi.org/10.1371/journal.pone.0227742. source
The Discussion > Implications section (page unavailable) says 100% accuracy by human reviewers is unlikely in reality. The paper also reports false exclusions during abstract screening, supporting the claim that human screeners may miss relevant records. (LLM, conf=0.88)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“It is important to note that humans typically miss around 10% of the relevant records [52]”
§ The SAFE procedure: a practical stopping heuristic for active learning-based screening in systematic reviews and meta-analyses > Development > Results
What the sources say
- Partly supportedcites [52] Wang Z, Nayfeh T, Tetzlaff J, O’Blenis P, Murad MH. Error rates of human reviewers during abstract screening in systematic reviews. PLoS ONE. 2020;15(1):1–8. https://doi.org/10.1371/journal.pone.0227742. sourceExperimental — accuracy not yet measured
The Discussion reports a 10.76% error rate during abstract screening, but that figure combines false inclusions and false exclusions across screening decisions; it is not the percentage of relevant records missed. The Limitations section also says that records erroneously excluded by both reviewers could not be assessed, so the paper does not establish the claimed miss rate. (LLM, conf=0.90)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
The cited sources that could be checked couldn’t confirm or dispute this claim.
In the paper
“It might be that some relevant records are not presented to the reviewer because the text used in the abstract is not seen as potentially relevant because of concept ambiguity [11, 17], which can make finding relevant records challenging.”
§ The SAFE procedure: a practical stopping heuristic for active learning-based screening in systematic reviews and meta-analyses > The SAFE procedure > The four phases
What the sources say
- Could not verifycites [11] Chen Y, Mani S, Xu H. Applying active learning to assertion classification of concepts in clinical text. J Biomed Inform. 2012;45(2):265–72. https://doi.org/10.1016/j.jbi.2011.11.003. sourceExperimental — accuracy not yet measured
The Methods (§3.1; page unavailable) describe classifying assertions about medical concepts in clinical notes, and the Discussion (§5; page unavailable) concerns which samples active-learning algorithms select for annotation. Neither addresses relevant records being withheld from a reviewer because ambiguous abstract text appears irrelevant. Searches for reviewer screening, missed records, and concept ambiguity found no supporting passage. (LLM, conf=0.76)
- Could not verifycites [17] Gama J, Žliobaitė I, Bifet A, Pechenizkiy M, Bouchachia A. A survey on concept drift adaptation. ACM Computing Surveys (CSUR). 2014;46(4):1–37. sourceExperimental — accuracy not yet measured
Section 2.1 discusses classifying news as relevant or not relevant, and Section 5 mentions representation bias in adaptive systems. Neither passage says that relevant records may be withheld from a reviewer because ambiguous concepts in their abstracts make them appear irrelevant. Searches for abstract ambiguity and for relevant items not being presented found no passage addressing that mechanism; page numbers were not available in our copy. (LLM, conf=0.72)
hedgedstates a possible cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Could not verify
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“At the same time, using a single heuristic may result in missing potentially relevant records.”
§ The SAFE procedure: a practical stopping heuristic for active learning-based screening in systematic reviews and meta-analyses > Introduction
hedgedstates a possible cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: unclear — It is unclear why the paper says it holds.
2 more claims
Create a free account to see all 73 claims and to verify the 4 references still open.
- It may state two separate claims as one. 28
- Probably not a substantial claim. 59
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Each agent specializes in different tasks, such as other features of the texts (e.g., short versus long abstracts or domain-specific language) or different stopping heuristics.39”
From ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts (2025) · cites this paper as [39]
Experimental — accuracy not yet measuredIn the citing paper
“This work provides a workflow that ensures an evidence-based strategy for determining when to stop screening and switch between models if needed.”
From Large-scale simulation study of active learning models for systematic reviews (2025) · cites this paper as [4]
In the citing paper
“Therefore, we foresee that this model can serve as a model to switch to if enough labels have been gathered,30 as a quality check,39 or if a previously labeled dataset is available, for example, in an update of a systematic review (e.g., van de Schoot et al.2).”
From ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts (2025) · cites this paper as [39]
Citations
Cites
The PRISMA 2020 statement: An updated guideline for reporting systematic reviews
Page, M. J., McKenzie, J. E., Bossuyt, P. M., Boutron, I., Hoffmann, T. C., Mulrow, C. D., Shamseer, L., Tetzlaff, J. M., Akl, E. A., Brennan, S. E., et al. (2021) · BMJ · doi:10.1136/bmj.n71 · Cited by 108,283
Rayyan-a web and mobile app for systematic reviews.
Ouzzani, M., Hammady, H., Fedorowicz, Z., & Elmagarmid, A. (2016) · Systematic Reviews · doi:10.1186/s13643-016-0384-4 · Cited by 26,092 · cited 1×
“Priority screening via active learning has been successfully implemented in various software tools such as Abstrackr [49], ASReview [45], Colandr [12], EPPI-Reviewer [41], FASTREAD [54], Rayyan [28], RobotA-nalyst [32], Research Screener [10], DistillerSR [20], and robotreviewer [25].”
Method(2016) · Cited by 11,679
The PRISMA 2020 statement: an updated guideline for reporting systematic reviews
Page, M. J., McKenzie, J., Bossuyt, P., Boutron, I., Hoffmann, T., mulrow, C., Shamseer, L., Tetzlaff, J., Akl, E., Brennan, S. E., et al. (2020) · doi:10.31222/osf.io/v7gm2 · Cited by 5,177
(2009) · Minds at UW (University of Wisconsin) · Cited by 4,791
A survey on concept drift adaptation
Gama, J., Žliobaitė, I., Bifet, A., Pechenizkiy, M., & Bouchachia, A. (2014) · ACM Computing Surveys · doi:10.1145/2523813 · Cited by 3,735 · cited 1×
“It might be that some relevant records are not presented to the reviewer because the text used in the abstract is not seen as potentially relevant because of concept ambiguity [11, 17], which can make finding relevant records challenging.”
BackgroundAn open source machine learning framework for efficient and transparent systematic reviews
van de Schoot, R., de Bruin, J., Schram, R., Zahedi, P., de Boer, J., Weijdema, F., Kramer, B., Huijts, M., Hoogerwerf, M., Ferdinands, G., et al. (2021) · Nature Machine Intelligence · doi:10.1038/s42256-020-00287-7 · Cited by 1,157
Self-citationA systematic approach to searching: an efficient and complete method to develop literature searches
Bramer, W. M., De Jonge, G. B., Rethlefsen, M. L., Mast, F., & Kleijnen, J. (2018) · Journal of the Medical Library Association · doi:10.5195/jmla.2018.283 · Cited by 863 · cited 2×
“This method is often used for validating the search strategy by ensuring that the search process adequately identifies relevant primary studies [8, 42].”
BackgroundMethodA full systematic review was completed in 2 weeks using automation tools: a case study
Clark, J., Glasziou, P., Del Mar, C., Bannach-Brown, A., Stehlik, P., & Scott, A. M. (2020) · Journal of Clinical Epidemiology · doi:10.1016/j.jclinepi.2020.01.008 · Cited by 687 · cited 1×
“This can be automated, for example, through the use of SR-Accelerator’s Spi-dercite [14], Citation Chaser [19].”
MethodHaddaway, N. R., Grainger, M. J., & Gray, C. T. (2022) · Research Synthesis Methods · doi:10.1002/jrsm.1563 · Cited by 604
Research works printed but not linked: 1
- Qin X, Liu J, Wang Y, Deng K, Ma Y, Zou K, Li L, Sun X. Application of nature language processing in systematic reviews. Chin J Evid Based Med. 2021;21(6):715–20. https://doi.org/10.7507/1672-2531.202012150. · doi:10.7507/1672-2531.202012150
Cited by
Evaluating the effectiveness of large language models in abstract screening: a comparative analysis
Li, M., Sun, J., & Tan, X. M. (2024) · Systematic Reviews · doi:10.1186/s13643-024-02609-x · Cited by 173
The AI risk repository: A meta-review, database, and taxonomy of risks from artificial intelligence
Slattery, P., Saeri, A. K., Grundy, E. A. C., Graham, J., Noetel, M., Uuk, R., Dao, J., Pour, S., Casper, S., & Thompson, N. (2026) · Patterns · doi:10.1016/j.patter.2026.101517 · Cited by 253
“For the first iteration of the active-learning model, the team followed the recommendation of Boetje and van de Schoot 46 to use the Oracle model and the default model setup (TF-IDF as the feature extractor, Naive Bayes as the classifier, maximum as the query strategy, and dynamic resampling…”
InfluentialBrück, C. C., Mooldijk, S. S., Kuiper, L. M., Sambou, M. L., Licher, S., Mattace-Raso, F. U. S., & Wolters, F. J. (2025) · BMJ · doi:10.1136/bmj-2024-080636 · Cited by 60
ASReview LAB v.2: Open-source text screening with multiple agents and a crowd of experts
de Bruin, J., Lombaers, P., Kaandorp, C., Teijema, J., van der Kuil, T., Yazan, B., Dong, A., & van de Schoot, R. (2025) · Patterns · doi:10.1016/j.patter.2025.101318 · Cited by 27
“Therefore, we foresee that this model can serve as a model to switch to if enough labels have been gathered, 30 as a quality check, 39 or if a previously labeled dataset is available, for example, in an update of a systematic review (e.g., van de Schoot et al. 2 ).”
Influentialvan der Veer, A., Madern, T., & van Lenthe, F. J. (2024) · International Journal of Behavioral Nutrition and Physical Activity · doi:10.1186/s12966-024-01576-9 · Cited by 41
“The SAFE-procedure 3 was followed to screen the abstracts, which contains of four steps, with a different heuristic for the number of abstracts to screen in each step [126].”
Method
Metadata
- Authors
- Boetje, J., & van de Schoot, R.
- Affiliations
- University of Applied Sciences Utrecht (NL)
- Corresponding author
- Boetje, Josien
- ORCID
- Boetje, Josien
- Venue
- Systematic Reviews
- Published
- 2024-03-01
- Volume
- 13
- Issue
- 1
- Pages
- 81-81
- ISSN
- 2046-4053 (ISSN-L)
- PMC
- PMC10908130
- OpenAlex
- W4392356867
- Cited by
- 146
- References
- 53
- Citations by year
- 2026: 80 · 2025: 50 · 2024: 15
- FWCI
- 18.22
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- cc-by
- creativecommons.org/licenses/by/4.0 (tdm)
- creativecommons.org/licenses/by/4.0 (vor)
- Locations
- Systematic Reviews (publishedVersion, cc-by)
- Research Square (acceptedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- DSpace (Open University in the Netherlands) (submittedVersion, cc-by)
- Funders
- Nederlandse Organisatie voor Wetenschappelijk Onderzoek (406.22.GO.048, 406.22)
- Topics
- Social Sciences › Decision Sciences › Statistics, Probability and Uncertainty › Meta-analysis and systematic reviews
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning and Algorithms
- Physical Sciences › Computer Science › Information Systems › Information Retrieval and Search Behavior
- Keywords
- active learning (machine learning), systematic review screening, ASReview, cost-benefit trade-off
- MeSH terms
- Heuristics, Systematic Reviews as Topic, Humans, Software, Problem-Based Learning
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-09-29, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-09-29 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: The SAFE procedure: a practical stopping heuristic for active learning-based screening in systematic reviews and meta-analyses. https://app.cochat.ai/papers/10.1186/s13643-024-02502-7
- The paper
- Boetje, J., & van de Schoot, R. (2024). The SAFE procedure: a practical stopping heuristic for active learning-based screening in systematic reviews and meta-analyses. Systematic Reviews. https://doi.org/10.1186/s13643-024-02502-7
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
