

The DOI matches its Crossref record; 33 of the 33 references it cites were found in a registry or an index.
E-BERT: Efficient-Yet-Effective Entity Embeddings for BERT
Open accessAbstract
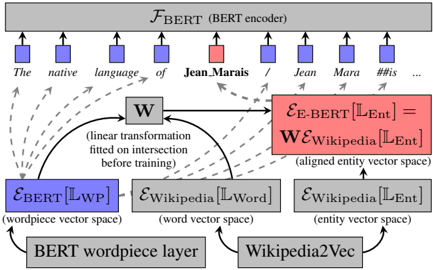
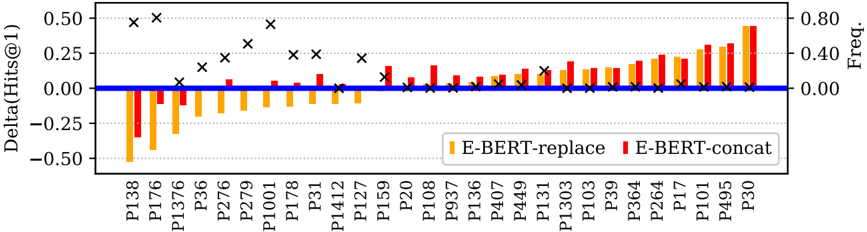
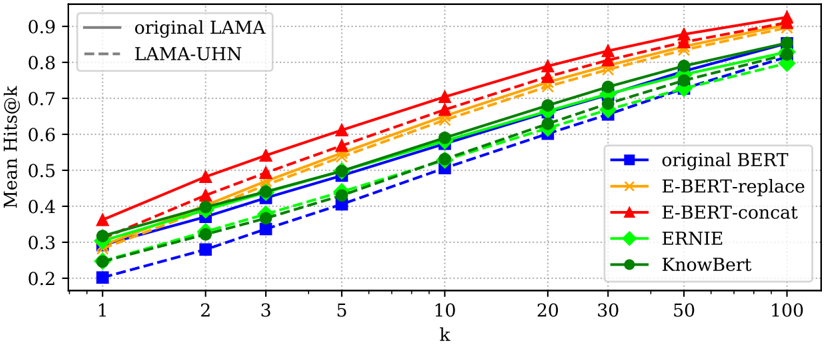
We present a novel way of injecting factual knowledge about entities into the pretrained BERT model ( Devlin et al., 2019): We align Wikipedia2Vec entity vectors (Yamada et al., 2016) with BERT's native wordpiece vector space and use the aligned entity vectors as if they were wordpiece vectors.The resulting entity-enhanced version of BERT (called E-BERT) is similar in spirit to ERNIE (Zhang et al., 2019) and KnowBert (Peters et al., 2019), but it requires no expensive further pretraining of the BERT encoder.We evaluate E-BERT on unsupervised question answering (QA), supervised relation classification (RC) and entity linking (EL).On all three tasks, E-BERT outperforms BERT and other baselines.We also show quantitatively that the original BERT model is overly reliant on the surface form of entity names (e.g., guessing that someone with an Italian-sounding name speaks Italian), and that E-BERT mitigates this problem.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“The ability of Large Language Models to retrieve factual knowledge as explicit knowledge bases [53-56, 56-61] has been stirred discussed, which presents an opportunity to construct more comprehensive knowledge graphs within recommender systems.”
From When large language models meet personalization: perspectives of challenges and opportunities (2024) · cites this paper as [58]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Efficient Estimation of Word Representations in Vector Space
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013) · arXiv · doi:10.48550/arxiv.1301.3781 · Cited by 26,568
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
Introduction to information retrieval
(2009) · Choice Reviews Online · doi:10.5860/choice.46-2715 · Cited by 12,278
Self-citationIntroduction to Information Retrieval
Manning, C. D., Raghavan, P., & Schütze, H. (2008) · doi:10.1017/cbo9780511809071 · Cited by 11,288
Self-citationXLNet: Generalized Autoregressive Pretraining for Language Understanding
Yang, Z., Dai, Z., Yang, Y., Carbonell, J., Salakhutdinov, R., & Le, Q. V. (2019) · arXiv · doi:10.48550/arxiv.1906.08237 · Cited by 6,687
Exploiting Similarities among Languages for Machine TranslationPreprint
Mikolov, T., Le, Q. V., & Sutskever, I. (2013) · arXiv (Cornell University) · doi:10.48550/arxiv.1309.4168 · Cited by 1,728
ERNIE: Enhanced Language Representation with Informative Entities
Zhang, Z., Han, X., Liu, Z., Jiang, X., Sun, M., & Liu, Q. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1139 · Cited by 1,482
Fixing Weight Decay Regularization in Adam
Loshchilov, I., & Hutter, F. (2018) · Cited by 1,297
Research works printed but not linked: 2
- Hady Elsahar, Pavlos Vougiouklis, Arslen Remaci, Christophe Gravier, Jonathon Hare, Frédérique Laforest, and Elena Simperl. 2018. T-REx: A large scale alignment of natural language with knowledge base triples. In LREC, pages 3448-3452, Miyazaki, Japan.
- Diederik P Kingma and Jimmy Ba. 2014. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980. · arXiv
Cited by
Sorted by citations
On the Opportunities and Risks of Foundation Models
Bommasani, R., Hudson, D. A., Adeli, E., Altman, R., Arora, S., von Arx, S., Bernstein, M. S., Bohg, J., Bosselut, A., Brunskill, E., et al. (2021) · arXiv · doi:10.48550/arxiv.2108.07258 · Cited by 2,676
A primer in BERTology: What we know about how BERT works
Rogers, A., Kovaleva, O., & Rumshisky, A. (2020) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00349 · Cited by 1,552
Pre-trained models for natural language processing: A survey
Qiu, X., Sun, T., Xu, Y., Shao, Y., Dai, N., & Huang, X. (2020) · Science China Technological Sciences · doi:10.1007/s11431-020-1647-3 · Cited by 1,591
How Can We Know What Language Models Know?
Jiang, Z., Xu, F. F., Araki, J., & Neubig, G. (2020) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00324 · Cited by 1,002
Pre-trained models: Past, present and future
Han, X., Zhang, Z., Ding, N., Gu, Y., Liu, X., Huo, Y., Qiu, J., Yao, Y., Zhang, A., Zhang, L., et al. (2021) · AI Open · doi:10.1016/j.aiopen.2021.08.002 · Cited by 994
Metadata
- Authors
- Poerner, N., Waltinger, U., & Schütze, H.
- Affiliations
- Siemens (Germany) (DE)
- Ludwig-Maximilians-Universität München (DE)
- Venue
- Findings of the Association for Computational Linguistics: EMNLP 2020
- Published
- 2020
- Pages
- 803-818
- OpenAlex
- W3021191241
- Cited by
- 146
- References
- 33
- Citations by year
- 2026: 5 · 2025: 11 · 2024: 21 · 2023: 24 · 2022: 34 · 2021: 34 · 2020: 15
- FWCI
- 10.21
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Siemens
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Keywords
- entity embeddings, BERT, knowledge injection, relation classification, entity linking
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
