

The DOI matches its Crossref record; 54 of the 57 references it cites were found in a registry or an index.
Dissecting Contextual Word Embeddings: Architecture and Representation
Open accessAbstract
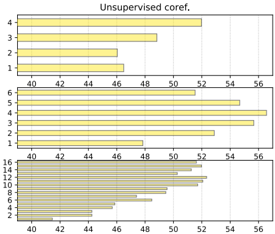
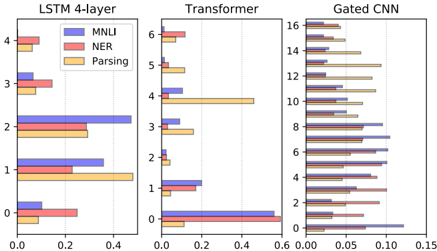
Contextual word representations derived from pre-trained bidirectional language models (biLMs) have recently been shown to provide significant improvements to the state of the art for a wide range of NLP tasks.However, many questions remain as to how and why these models are so effective.In this paper, we present a detailed empirical study of how the choice of neural architecture (e.g.LSTM, CNN, or self attention) influences both end task accuracy and qualitative properties of the representations that are learned.We show there is a tradeoff between speed and accuracy, but all architectures learn high quality contextual representations that outperform word embeddings for four challenging NLP tasks.Additionally, all architectures learn representations that vary with network depth, from exclusively morphological based at the word embedding layer through local syntax based in the lower contextual layers to longer range semantics such coreference at the upper layers.Together, these results suggest that unsupervised biLMs, independent of architecture, are learning much more about the structure of language than previously appreciated.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
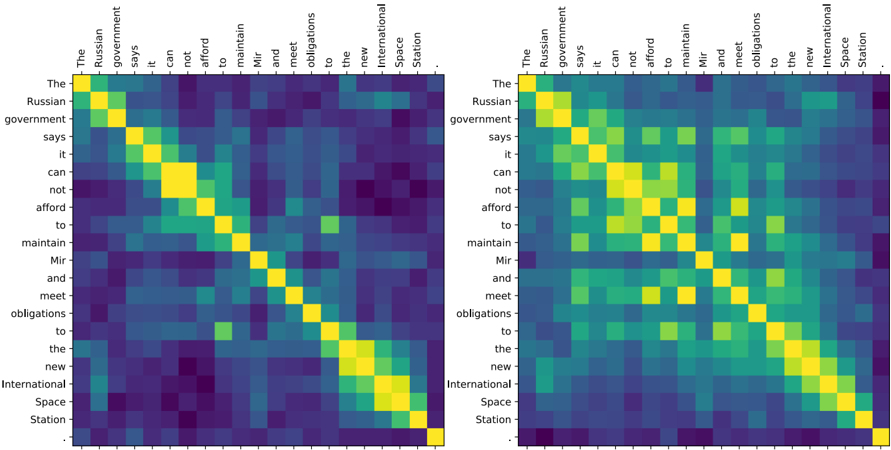
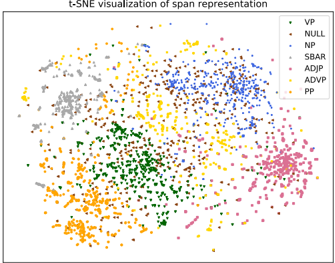
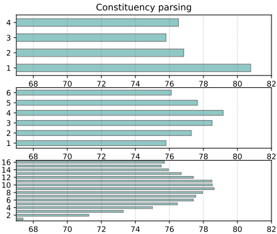
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Following Peters et al. (2018b); Liu et al. (2019a), we observe that the final 2-3 BERT layers provide embeddings that excel at predictive language modeling; as such, Figure 4 uses embeddings from layer 9 of S2ORC-SCIBERT.”
From S2ORC: The Semantic Scholar Open Research Corpus (2020) · cites this paper as Peters et al. (2018b)
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“The study by Peters et al. (2018) suggests that the context vectors of bi-directional language models undergo abrupt changes at syntactic boundaries, allowing them to be utilized for constructing representations of spans or consecutive token sequences.”
From Can "consciousness" be observed from large language model (LLM) internal states? Dissecting LLM representations obtained from Theory of Mind test with Integrated Information Theory and Span Representation analysis (2025) · cites this paper as Peters et al., 2018
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Glove: Global Vectors for Word Representation
Pennington, J., Socher, R., & Manning, C. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1162 · Cited by 34,071
(2008) · Journal of Machine Learning Research · Cited by 33,051
Efficient Estimation of Word Representations in Vector Space
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013) · arXiv · doi:10.48550/arxiv.1301.3781 · Cited by 26,568
Visualizing and understanding convolutional networks
Zeiler, M. D., & Fergus, R. (2014) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-10590-1_53 · Cited by 15,839
Conditional Random Fields: Probabilistic Models for Segmenting and Labeling Sequence Data
Lafferty, J., McCallum, A., & Pereira, F. C. N. (2001) · ScholarlyCommons (University of Pennsylvania) · Cited by 12,935
Deep Contextualized Word Representations
Peters, M., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., & Zettlemoyer, L. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1202 · Cited by 11,983
Self-citationBuilding a Large Annotated Corpus of English: The Penn Treebank
Marcus, M. (1993) · doi:10.21236/ada273556 · Cited by 7,405
ADADELTA: An Adaptive Learning Rate Method
Zeiler, M. D. (2012) · arXiv · doi:10.48550/arxiv.1212.5701 · Cited by 5,322
Research works printed but not linked: 4
- Yonatan Belinkov, Nadir Durrani, Fahim Dalvi, Has- san Sajjad, and James R. Glass. 2017. What do neu- ral machine translation models learn about morphol- ogy? In ACL.
- Guillaume Klein, Yoon Kim, Yuntian Deng, Jean Senellart, and Alexander M. Rush. 2017. Open- NMT: Open-source toolkit for neural machine trans- lation. In ACL.
- Liyuan Liu, Xiang Ren, Jingbo Shang, Jian Peng, and Jiawei Han. 2018. Efficient contextualized represen- tation: Language model pruning for sequence label- ing. In EMNLP.
- Matthew E. Peters, Mark Neumann, Mohit Iyyer, Matt Gardner, Christopher Clark, Kenton Lee, and Luke Zettlemoyer. 2018. Deep contextualized word rep- resentations. In NAACL.
Cited by
Sorted by citations
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Language Models as Knowledge Bases?
Petroni, F., Rocktäschel, T., Riedel, S., Lewis, P., Bakhtin, A., Wu, Y., & Miller, A. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1250 · Cited by 1,834
How Multilingual is Multilingual BERT?
Pires, T., Schlinger, E., & Garrette, D. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1493 · Cited by 1,351
BERT Rediscovers the Classical NLP Pipeline
Tenney, I., Das, D., & Pavlick, E. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1452 · Cited by 1,307
(2019) · doi:10.18653/v1/p19-1356 · Cited by 1,291
Explainability for Large Language Models: A Survey
Zhao, H., Chen, H., Yang, F., Liu, N., Deng, H., Cai, H., Wang, S., Yin, D., & Du, M. (2024) · ACM Transactions on Intelligent Systems and Technology · doi:10.1145/3639372 · Cited by 681
Do Vision Transformers See Like Convolutional Neural Networks?
Raghu, M., Unterthiner, T., Kornblith, S., Zhang, C., & Dosovitskiy, A. (2021) · arXiv · doi:10.48550/arxiv.2108.08810 · Cited by 663
Linguistic Knowledge and Transferability of Contextual Representations
Liu, N. F., Gardner, M., Belinkov, Y., Peters, M. E., & Smith, N. A. (2019) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/n19-1112 · Cited by 757
Self-citationTransfer Learning in Natural Language Processing
Ruder, S., Peters, M. E., Swayamdipta, S., & Wolf, T. (2019) · North American Chapter of the Association for Computational Linguistics · doi:10.18653/v1/n19-5004 · Cited by 712
Self-citation(2019) · doi:10.18653/v1/n19-1419 · Cited by 601
What BERT Is Not: Lessons from a New Suite of Psycholinguistic Diagnostics for Language Models
Ettinger, A. (2020) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00298 · Cited by 511
Analysis Methods in Neural Language Processing: A Survey
Belinkov, Y., & Glass, J. R. (2019) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00254 · Cited by 522
S2ORC: The Semantic Scholar Open Research Corpus
Lo, K., Wang, L. L., Neumann, M., Kinney, R., & Weld, D. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.447 · Cited by 457
Self-citationSentence Encoders on STILTs: Supplementary Training on Intermediate Labeled-data Tasks
Phang, J., Févry, T., & Bowman, S. R. (2018) · arXiv · doi:10.48550/arxiv.1811.01088
Designing and Interpreting Probes with Control Tasks
Hewitt, J., & Liang, P. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1275 · Cited by 393
FLAIR: An Easy-to-Use Framework for State-of-the-Art NLP
Akbik, A., Bergmann, T., Blythe, D. A. J., Rasul, K., Schweter, S., & Vollgraf, R. (2019) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/n19-4010 · Cited by 417
Language Models as Knowledge Bases?Preprint
Petroni, F., Rocktäschel, T., Lewis, P., Bakhtin, A., Wu, Y., Miller, A., & Riedel, S. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1909.01066 · Cited by 714
An Unsupervised Autoregressive Model for Speech Representation Learning
Chung, Y.-A., Hsu, W.-N., Tang, H., & Glass, J. R. (2019) · Interspeech (USB) · doi:10.21437/interspeech.2019-1473 · Cited by 410
Emergent linguistic structure in artificial neural networks trained by self-supervision
Manning, C. D., Clark, K., Hewitt, J., Khandelwal, U., & Levy, O. (2020) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.1907367117 · Cited by 378
BERTology Meets Biology: Interpreting Attention in Protein Language Models
Vig, J., Madani, A., Varshney, L. R., Xiong, C., Socher, R., & Rajani, N. F. (2020) · doi:10.1101/2020.06.26.174417 · Cited by 338
Open Problems in Mechanistic Interpretability
Sharkey, L., Chughtai, B., Batson, J., Lindsey, J., Wu, J., Bushnaq, L., Goldowsky-Dill, N., Heimersheim, S., Ortega, A., Bloom, J., et al. (2025) · arXiv · doi:10.48550/arxiv.2501.16496 · Cited by 291
oLMpics-On What Language Model Pre-training Captures
Talmor, A., Elazar, Y., Goldberg, Y., & Berant, J. (2020) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00342 · Cited by 288
A Gentle Introduction to Reinforcement Learning and its Application in Different Fields
Naeem, M., Rizvi, S. T. H., & Coronato, A. (2020) · IEEE Access · doi:10.1109/access.2020.3038605 · Cited by 290
From Zero to Hero: On the Limitations of Zero-Shot Language Transfer with Multilingual Transformers
Lauscher, A., Ravishankar, V., Vulić, I., & Glavaš, G. (2020) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.363 · Cited by 283
TransPolymer: a Transformer-based language model for polymer property predictions
Xu, C., Wang, Y., & Farimani, A. B. (2023) · npj Computational Materials · doi:10.1038/s41524-023-01016-5 · Cited by 222
A Survey of Reinforcement Learning Informed by Natural Language
Luketina, J., Nardelli, N., Farquhar, G., Foerster, J., Andreas, J., Grefenstette, E., Whiteson, S., & Rocktäschel, T. (2019) · International Joint Conference on Artificial Intelligence · doi:10.24963/ijcai.2019/880 · Cited by 279
Eichstaedt, J. C., Kern, M. L., Yaden, D. B., Schwartz, H. A., Giorgi, S., Park, G., Hagan, C. A., Tobolsky, V. A., Smith, L. K., Buffone, A. E. K., et al. (2021) · Psychological Methods · doi:10.1037/met0000349 · Cited by 210
BERT Rediscovers the Classical NLP PipelinePreprint
Tenney, I., Das, D., & Pavlick, E. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1905.05950 · Cited by 439
Pretrained Encyclopedia: Weakly Supervised Knowledge-Pretrained Language ModelPreprint
Xiong, W., Du, J., Wang, W. Y., & Stoyanov, V. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1912.09637 · Cited by 190
Information-Theoretic Probing for Linguistic Structure
Pimentel, T., Valvoda, J., Hall Maudslay, R., Zmigrod, R., Williams, A., & Cotterell, R. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.420 · Cited by 41
HiT: Hierarchical Transformer with Momentum Contrast for Video-Text Retrieval
Liu, S., Fan, H., Qian, S., Chen, Y., Ding, W., & Wang, Z. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.01170 · Cited by 175
Christian, H., Suhartono, D., Chowanda, A., & Zamli, K. Z. (2021) · Journal Of Big Data · doi:10.1186/s40537-021-00459-1 · Cited by 169
Searching for Effective Neural Extractive Summarization: What Works and What’s Next
Zhong, M., Liu, P., Wang, D., Qiu, X., & Huang, X. (2019) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p19-1100 · Cited by 177
A Survey of Automatic Text Summarization: Progress, Process and Challenges
Mridha, M. F., Lima, A. A., Nur, K. M., Das, S. C., Hasan, M., & Kabir, M. M. (2021) · IEEE Access · doi:10.1109/access.2021.3129786 · Cited by 173
What Happens To BERT Embeddings During Fine-tuning?
Merchant, A., Rahimtoroghi, E., Pavlick, E., & Tenney, I. F. (2020) · BlackboxNLP Workshop on Analyzing and Interpreting Neural Networks for NLP (BlackboxNLP) · doi:10.18653/v1/2020.blackboxnlp-1.4 · Cited by 208
Perturbed Masking: Parameter-free Probing for Analyzing and Interpreting BERT
Wu, Z., Chen, Y., Kao, B., & Liu, Q. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.383 · Cited by 187
SIFRank: A New Baseline for Unsupervised Keyphrase Extraction Based on Pre-Trained Language Model
Sun, Y., Qiu, H., Zheng, Y., Wang, Z., & Zhang, C. (2020) · IEEE Access · doi:10.1109/access.2020.2965087 · Cited by 163
Enhancing Pre-Trained Language Representations with Rich Knowledge for Machine Reading Comprehension
Yang, A., Wang, Q., Liu, J., Liu, K., Lyu, Y., Wu, H., She, Q., & Li, S. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1226 · Cited by 155
Hayes, A. S. (2025) · International Journal of Qualitative Methods · doi:10.1177/16094069251322346 · Cited by 154
What Does BERT with Vision Look At?
Li, L. H., Yatskar, M., Yin, D., Hsieh, C., & Chang, K.-W. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.469 · Cited by 141
On the Explainability of Natural Language Processing Deep Models
Zini, J. E., & Awad, M. (2022) · ACM Computing Surveys · doi:10.1145/3529755 · Cited by 153
Probing Biomedical Embeddings from Language Models
Jin, Q., Dhingra, B., Cohen, W., & Lu, X. (2019) · doi:10.18653/v1/w19-2011 · Cited by 134
On Identifiability in TransformersPreprint
Brunner, G., Liu, Y., Pascual, D., Richter, O., Ciaramita, M., & Wattenhofer, R. P. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1908.04211 · Cited by 151
Dependency-Guided LSTM-CRF for Named Entity Recognition
Jie, Z., & Lu, W. (2019) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d19-1399 · Cited by 111
Ruffo, G., Semeraro, A., Giachanou, A., & Rosso, P. (2022) · Computer Science Review · doi:10.1016/j.cosrev.2022.100531 · Cited by 130
Can You Tell Me How to Get Past Sesame Street? Sentence-Level Pretraining Beyond Language Modeling
Wang, A., Hůla, J., Xia, P., Pappagari, R. R., McCoy, R. T., Patel, R., Kim, N., Tenney, I. F., Huang, Y., Yu, K., et al. (2019) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p19-1439 · Cited by 109
Unsupervised Latent Tree Induction with Deep Inside-Outside Recursive Auto-Encoders
Drozdov, A., Verga, P. W., Yadav, M., Iyyer, M., & McCallum, A. (2019) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/n19-1116 · Cited by 106
Mao, R., & Li, X. (2021) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v35i15.17596 · Cited by 100
Mustapha, K. B. (2024) · Advanced Engineering Informatics · doi:10.1016/j.aei.2024.103066 · Cited by 107
Variational Pretraining for Semi-supervised Text Classification
Gururangan, S., Dang, T., Card, D., & Smith, N. A. (2019) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p19-1590 · Cited by 108
Information flow across the cortical timescale hierarchy during narrative construction
Chang, C. H. C., Nastase, S. A., & Hasson, U. (2022) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2209307119 · Cited by 92
MultiFiT: Efficient Multi-lingual Language Model Fine-tuning
Eisenschlos, J. M., Ruder, S., Czapla, P., Kadras, M., Gugger, S., & Howard, J. (2019) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d19-1572 · Cited by 95
Mixed Dimension Embeddings with Application to Memory-Efficient Recommendation Systems
Ginart, A. A., Naumov, M., Mudigere, D., Yang, J., & Zou, J. (2021) · IEEE International Symposium on Information Theory (ISIT) · doi:10.1109/isit45174.2021.9517710 · Cited by 82
Inductive Entity Representations from Text via Link Prediction
Daza, D., Cochez, M., & Groth, P. (2021) · International World Wide Web Conference (WWW) · doi:10.1145/3442381.3450141 · Cited by 95
What do pre-trained code models know about code?
Karmakar, A., & Robbes, R. (2021) · IEEE/ACM International Conference on Automated Software Engineering (ASE) · doi:10.1109/ase51524.2021.9678927 · Cited by 87
Analysis and Evaluation of Language Models for Word Sense Disambiguation
Loureiro, D., Rezaee, K., Pilehvar, M. T., & Camacho-Collados, J. (2021) · Computational Linguistics · doi:10.1162/coli_a_00405 · Cited by 95
Transformer-Based Named Entity Recognition in Construction Supply Chain Risk Management in Australia
Shishehgarkhaneh, M. B., Moehler, R., Fang, Y., Hijazi, A. A., & Aboutorab, H. (2024) · IEEE Access · doi:10.1109/access.2024.3377232 · Cited by 79
Semantic Structure in Deep Learning
Pavlick, E. (2021) · Annual Review of Linguistics · doi:10.1146/annurev-linguistics-031120-122924 · Cited by 82
BridgeTower: Building Bridges between Encoders in Vision-Language Representation Learning
Xiao, X., Wu, C., Rosenman, S., Lal, V., Che, W., & Duan, N. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i9.26263 · Cited by 91
Chung, S., Moon, S., Kim, J.-H., Kim, J., Lim, S. P., & Chi, S. (2023) · Automation in Construction · doi:10.1016/j.autcon.2023.105020 · Cited by 87
On the Linguistic Representational Power of Neural Machine Translation Models
Belinkov, Y., Durrani, N., Dalvi, F., Sajjad, H., & Glass, J. R. (2020) · Computational Linguistics · doi:10.1162/coli_a_00367 · Cited by 77
Fast changeset-based bug localization with BERT
Ciborowska, A., & Damevski, K. (2022) · ACM/IEEE International Conference on Software Engineering: Companion Proceedings (ICSE-Companion) · doi:10.1145/3510003.3510042 · Cited by 77
Generative AI model privacy: a survey
Liu, Y., Huang, J., Li, Y., Wang, D., & Xiao, B. (2024) · Artificial Intelligence Review · doi:10.1007/s10462-024-11024-6 · Cited by 74
Theoretical Foundations and Limits of Word Embeddings: What Types of Meaning can They Capture?
Arseniev‐Koehler, A. (2022) · Sociological Methods & Research · doi:10.1177/00491241221140142 · Cited by 75
Catelli, R., Casola, V., Pietro, G. D., Fujita, H., & Esposito, M. (2020) · Knowledge-Based Systems · doi:10.1016/j.knosys.2020.106649 · Cited by 64
Specializing Word Embeddings (for Parsing) by Information Bottleneck
Li, X. L., & Eisner, J. M. (2019) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d19-1276 · Cited by 66
On Identifiability in Transformers
Brunner, G., Liu, Y., Pascual, D., Richter, O., Ciaramita, M., & Wattenhofer, R. P. (2020) · International Conference on Learning Representations · Cited by 62
Pilault, J., Elhattami, A., & Pal, C. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2009.09139 · Cited by 75
Analyzing Individual Neurons in Pre-trained Language Models
Durrani, N., Sajjad, H., Dalvi, F., & Belinkov, Y. (2020) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.395 · Cited by 92
Local Interpretations for Explainable Natural Language Processing: A Survey
Luo, S., Ivison, H., Han, S. C., & Poon, J. (2024) · ACM Computing Surveys · doi:10.1145/3649450 · Cited by 73
Assessing Phrasal Representation and Composition in Transformers
Yu, L., & Ettinger, A. (2020) · Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.397 · Cited by 58
BERT is to NLP what AlexNet is to CV: Can Pre-Trained Language Models Identify Analogies?
Ushio, A., Espinosa-Anke, L., Schockaert, S., & Camacho-Collados, J. (2021) · doi:10.18653/v1/2021.acl-long.280 · Cited by 69
Fake news detection using dual BERT deep neural networks
Farokhian, M., Rafe, V., & Veisi, H. (2023) · Multimedia Tools and Applications · doi:10.1007/s11042-023-17115-w · Cited by 58
Similarity Analysis of Contextual Word Representation Models
Wu, J., Belinkov, Y., Sajjad, H., Durrani, N., Dalvi, F., & Glass, J. R. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.422 · Cited by 69
Neural Natural Language Inference Models Partially Embed Theories of Lexical Entailment and Negation
Geiger, A., Richardson, K., & Potts, C. (2020) · BlackboxNLP Workshop on Analyzing and Interpreting Neural Networks for NLP (BlackboxNLP) · doi:10.18653/v1/2020.blackboxnlp-1.16 · Cited by 97
Improving hate speech detection using Cross-Lingual Learning
Firmino, A. A., Baptista, C. D. S., & de Paiva, A. C. (2023) · Expert Systems with Applications · doi:10.1016/j.eswa.2023.121115 · Cited by 53
Leveraging Local and Global Patterns for Self-Attention Networks
Xu, M., Wong, D. F., Yang, B., Zhang, Y., & Chao, L. S. (2019) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p19-1295 · Cited by 52
Dynamic Contextualized Word Embeddings
Hofmann, V., Pierrehumbert, J. B., & Schütze, H. (2021) · doi:10.18653/v1/2021.acl-long.542 · Cited by 55
Cho, Y., Yu, H., & Kang, S. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3340062 · Cited by 56
AVA: A Financial Service Chatbot Based on Deep Bidirectional Transformers
Yu, S., Chen, Y., & Zaidi, H. A. (2021) · Frontiers in Applied Mathematics and Statistics · doi:10.3389/fams.2021.604842 · Cited by 56
Mapping ESG Trends by Distant Supervision of Neural Language Models
Raman, N., Bang, G., & Nourbakhsh, A. (2020) · Machine Learning and Knowledge Extraction · doi:10.3390/make2040025 · Cited by 50
Causal abstractions of neural networks
Geiger, A., Lu, H., Icard, T., & Potts, C. (2021) · arXiv · doi:10.48550/arxiv.2106.02997 · Cited by 45
Interpretability and Analysis in Neural NLP
Belinkov, Y., Gehrmann, S., & Pavlick, E. (2020) · doi:10.18653/v1/2020.acl-tutorials.1 · Cited by 50
From natural language processing to neural databases
Thorne, J. P., Yazdani, M., Saeidi, M., Silvestri, F., Riedel, S., & Halevy, A. Y. (2021) · Proceedings of the VLDB Endowment · doi:10.14778/3447689.3447706 · Cited by 44
Designing and Interpreting Probes with Control Tasks
Hewitt, J., & Liang, P. (2019) · arXiv · doi:10.48550/arxiv.1909.03368 · Cited by 110
Attention Is (not) All You Need for Commonsense Reasoning
Klein, T., & Nabi, M. (2019) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p19-1477 · Cited by 44
Contextual word representations
Smith, N. A. (2020) · Communications of the ACM · doi:10.1145/3347145 · Cited by 46
Leveraging Sentiment Distributions to Distinguish Figurative From Literal Health Reports on Twitter
Biddle, R., Joshi, A., Liu, S., Paris, C. L., & Xu, G. (2020) · International World Wide Web Conference (WWW) · doi:10.1145/3366423.3380198 · Cited by 42
Measuring Systematic Generalization in Neural Proof Generation with TransformersPreprint
Gontier, N., Sinha, K., Reddy, S., & Pal, C. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2009.14786 · Cited by 40
Graph Convolutions over Constituent Trees for Syntax-Aware Semantic Role Labeling
Marcheggiani, D., & Titov, I. (2020) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2020.emnlp-main.322 · Cited by 38
S2ORC: The Semantic Scholar Open Research CorpusPreprint
Lo, K., Wang, L. L., Neumann, M., Kinney, R., & Weld, D. S. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1911.02782 · Cited by 115
Self-citationKeyphrase Extraction from Disaster-related Tweets
Chowdhury, J. R., Caragea, C., & Caragea, D. (2019) · International World Wide Web Conference (WWW) · doi:10.1145/3308558.3313696 · Cited by 37
Yang, J., Wang, Y., & Li, X. (2022) · PeerJ Computer Science · doi:10.7717/peerj-cs.1148 · Cited by 38
ALGAN: Time Series Anomaly Detection with Adjusted-LSTM GAN
Bashar, M. A., & Nayak, R. (2025) · International Journal of Data Science and Analytics · doi:10.1007/s41060-025-00810-2 · Cited by 33
Jiang, M., Sanger, T. M., & Liu, X. (2019) · JMIR Medical Informatics · doi:10.2196/14850 · Cited by 35
Do Neural Language Models Show Preferences for Syntactic Formalisms?
Kulmizev, A., Ravishankar, V., Abdou, M., & Nivre, J. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.375 · Cited by 41
Klafka, J., & Ettinger, A. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.434 · Cited by 40
Zhao, Y., & Bethard, S. J. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.429 · Cited by 36
Metadata
- Authors
- Peters, M., Neumann, M., Zettlemoyer, L., & Yih, W.-T.
- Affiliations
- Allen Institute for Artificial Intelligence (US)
- University of Washington (US)
- Venue
- Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing
- Published
- 2018
- Pages
- 1499-1509
- OpenAlex
- W2888329843
- Cited by
- 434
- References
- 57
- Citations by year
- 2026: 23 · 2025: 27 · 2024: 37 · 2023: 53 · 2022: 55 · 2021: 75 · 2020: 83 · 2019: 77 · 2018: 4
- FWCI
- 24.08
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Sentiment Analysis and Opinion Mining
- Keywords
- contextual word embeddings, bidirectional language models, LSTM, convolutional neural networks, self-attention, representation learning, network depth, morphological representation, syntactic representation, coreference, word embeddings, speed-accuracy trade-off
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
