

The DOI matches its Crossref record; 54 of the 57 references it cites were found in a registry or an index.
Dissecting Contextual Word Embeddings: Architecture and Representation
Open accessAbstract
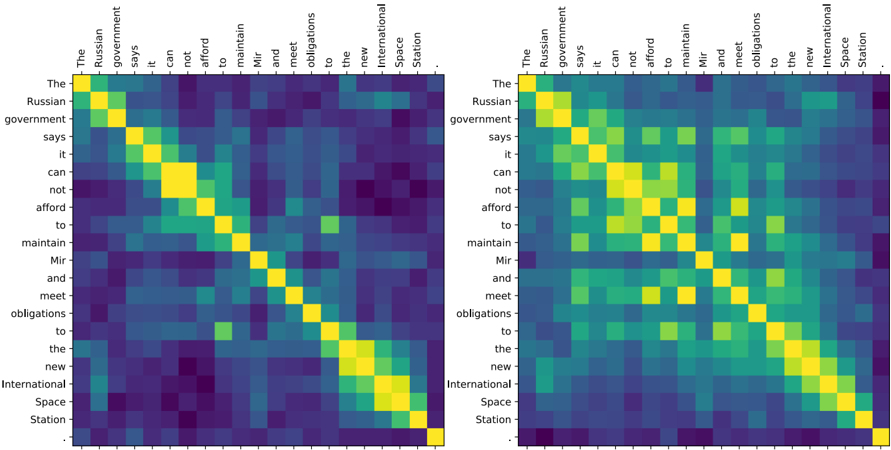
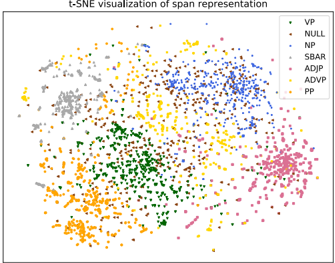
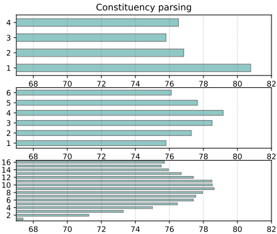
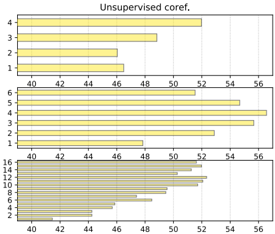
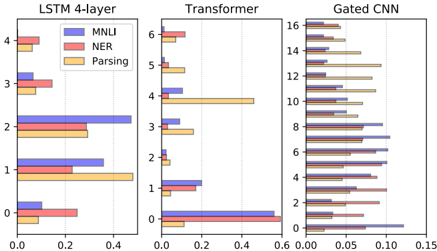
Contextual word representations derived from pre-trained bidirectional language models (biLMs) have recently been shown to provide significant improvements to the state of the art for a wide range of NLP tasks.However, many questions remain as to how and why these models are so effective.In this paper, we present a detailed empirical study of how the choice of neural architecture (e.g.LSTM, CNN, or self attention) influences both end task accuracy and qualitative properties of the representations that are learned.We show there is a tradeoff between speed and accuracy, but all architectures learn high quality contextual representations that outperform word embeddings for four challenging NLP tasks.Additionally, all architectures learn representations that vary with network depth, from exclusively morphological based at the word embedding layer through local syntax based in the lower contextual layers to longer range semantics such coreference at the upper layers.Together, these results suggest that unsupervised biLMs, independent of architecture, are learning much more about the structure of language than previously appreciated.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Following Peters et al. (2018b); Liu et al. (2019a), we observe that the final 2-3 BERT layers provide embeddings that excel at predictive language modeling; as such, Figure 4 uses embeddings from layer 9 of S2ORC-SCIBERT.”
From S2ORC: The Semantic Scholar Open Research Corpus (2020) · cites this paper as Peters et al. (2018b)
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“The study by Peters et al. (2018) suggests that the context vectors of bi-directional language models undergo abrupt changes at syntactic boundaries, allowing them to be utilized for constructing representations of spans or consecutive token sequences.”
From Can "consciousness" be observed from large language model (LLM) internal states? Dissecting LLM representations obtained from Theory of Mind test with Integrated Information Theory and Span Representation analysis (2025) · cites this paper as Peters et al., 2018
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Glove: Global Vectors for Word Representation
Pennington, J., Socher, R., & Manning, C. (2014) · Proceedings of the 2014 Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.3115/v1/d14-1162 · Cited by 34,071
(2008) · Journal of Machine Learning Research · Cited by 33,051
Efficient Estimation of Word Representations in Vector Space
Mikolov, T., Chen, K., Corrado, G., & Dean, J. (2013) · arXiv · doi:10.48550/arxiv.1301.3781 · Cited by 26,568
Visualizing and understanding convolutional networks
Zeiler, M. D., & Fergus, R. (2014) · Lecture Notes in Computer Science · doi:10.1007/978-3-319-10590-1_53 · Cited by 15,839
Conditional Random Fields: Probabilistic Models for Segmenting and Labeling Sequence Data
Lafferty, J., McCallum, A., & Pereira, F. C. N. (2001) · ScholarlyCommons (University of Pennsylvania) · Cited by 12,935
Deep Contextualized Word Representations
Peters, M., Neumann, M., Iyyer, M., Gardner, M., Clark, C., Lee, K., & Zettlemoyer, L. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1202 · Cited by 11,983
Self-citationBuilding a Large Annotated Corpus of English: The Penn Treebank
Marcus, M. (1993) · doi:10.21236/ada273556 · Cited by 7,405
ADADELTA: An Adaptive Learning Rate Method
Zeiler, M. D. (2012) · arXiv · doi:10.48550/arxiv.1212.5701 · Cited by 5,322
WaveNet: a generative model for raw audio
Oord, A. V. D., Dieleman, S., Zen, H., Simonyan, K., Vinyals, O., Graves, A., Kalchbrenner, N., Senior, A., & Kavukcuoglu, K. (2016) · arXiv · doi:10.48550/arxiv.1609.03499 · Cited by 4,911
Universal Language Model Fine-tuning for Text Classification
Howard, J., & Ruder, S. (2018) · Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p18-1031 · Cited by 4,100
Axiomatic attribution for deep networks
Sundararajan, M., Taly, A., & Yan, Q. (2017) · arXiv · doi:10.48550/arxiv.1703.01365 · Cited by 4,087
A Broad-Coverage Challenge Corpus for Sentence Understanding through Inference
Williams, A., Nangia, N., & Bowman, S. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1101 · Cited by 3,342
Long short-term memory recurrent neural network architectures for large scale acoustic modeling
Sak, H., Senior, A., & Beaufays, F. (2014) · Interspeech 2014 · doi:10.21437/interspeech.2014-80 · Cited by 2,973
Convolutional Sequence to Sequence Learning
Gehring, J., Auli, M., Grangier, D., Yarats, D., & Dauphin, Y. N. (2017) · arXiv · doi:10.48550/arxiv.1705.03122 · Cited by 2,850 · cited 1×
“Convolutional architectures have also been shown to provide competitive results for sequence modeling including sequence-to-sequence machine translation (Gehring et al., 2017).”
BackgroundIntroduction to the CoNLL-2003 Shared Task: Language-Independent Named Entity Recognition
Tjong Kim Sang, E. F., & De Meulder, F. (2003) · Proceedings of the seventh conference on Natural language learning at HLT-NAACL 2003 - · doi:10.3115/1119176.1119195 · Cited by 2,788
OpenNMT: Open-Source Toolkit for Neural Machine Translation
Klein, G., Kim, Y., Deng, Y., Sénellart, J., & Rush, A. M. (2017) · Annual Meeting of the Association for Computational Linguistics: System Demonstrations (ACL Demo) · doi:10.18653/v1/p17-4012 · Cited by 1,916
Language Modeling with Gated Convolutional NetworksPreprint
Dauphin, Y., Fan, A., Auli, M., & Grangier, D. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1612.08083 · Cited by 1,765
Introduction to the CoNLL-2002 Shared Task: Language-Independent Named Entity RecognitionPreprint
Sang, E. T. K. (2002) · arXiv (Cornell University) · doi:10.48550/arxiv.cs/0209010 · Cited by 1,677
Character-Aware Neural Language Models
Kim, Y., Jernite, Y., Sontag, D. A., & Rush, A. M. (2016) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v30i1.10362 · Cited by 1,590
Training Very Deep NetworksPreprint
Srivastava, R. K., Greff, K., & Schmidhuber, J. (2015) · arXiv (Cornell University) · doi:10.48550/arxiv.1507.06228 · Cited by 1,504
AllenNLP: A Deep Semantic Natural Language Processing Platform
Gardner, M., Grus, J., Neumann, M., Tafjord, O., Dasigi, P., Liu, N. F., Peters, M. E., Schmitz, M., & Zettlemoyer, L. (2018) · Workshop for NLP Open Source Software (NLP-OSS) · doi:10.18653/v1/w18-2501 · Cited by 1,376
Self-citationEnhanced LSTM for Natural Language Inference
Chen, Q., Zhu, X., Ling, Z.-H., Wei, S., Jiang, H., & Inkpen, D. Z. (2017) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p17-1152 · Cited by 1,315
Exploring the Limits of Language ModelingPreprint
Józefowicz, R., Vinyals, O., Schuster, M., Shazeer, N., & Wu, Y. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1602.02410 · Cited by 1,238
End-to-end Neural Coreference Resolution
Lee, K., He, L., Lewis, M., & Zettlemoyer, L. (2017) · Proceedings of the 2017 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d17-1018 · Cited by 869
Self-citationVisualizing and Understanding Recurrent Networks
Karpathy, A., Johnson, J., & Fei-Fei, L. (2015) · arXiv · doi:10.48550/arxiv.1506.02078 · Cited by 845
Assessing the Ability of LSTMs to Learn Syntax-Sensitive Dependencies
Linzen, T., Emmanuel Dupoux, A., & Goldberg, Y. (2016) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00115 · Cited by 820
(2017) · International Conference on Machine Learning · Cited by 758
Introduction to the CoNLL-2000 shared task
Sang, E. T. K., & Buchholz, S. (2000) · Conference on Computational Natural Language Learning · doi:10.3115/1117601.1117631 · Cited by 713
Regularizing and Optimizing LSTM Language Models
Merity, S., Keskar, N. S., & Socher, R. (2017) · arXiv · doi:10.48550/arxiv.1708.02182 · Cited by 697
Semi-supervised sequence tagging with bidirectional language models
Peters, M., Ammar, W., Bhagavatula, C., & Power, R. (2017) · Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p17-1161 · Cited by 655
Self-citationOne billion word benchmark for measuring progress in statistical language modeling
Chelba, C., Mikolov, T., Schuster, M., Ge, Q., Brants, T., Koehn, P., & Robinson, T. (2014) · Interspeech 2014 · doi:10.21437/interspeech.2014-564 · Cited by 627
Understanding Neural Networks through Representation ErasurePreprint
Li, J., Monroe, W., & Jurafsky, D. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1612.08220 · Cited by 625
(2012) · Cited by 618
Learned in Translation: Contextualized Word Vectors
McCann, B., Bradbury, J., Xiong, C., & Socher, R. (2017) · arXiv · doi:10.48550/arxiv.1708.00107 · Cited by 572 · cited 1×
“In addition to biLM-based representations, McCann et al. (2017) learned contextualized vectors with a neural machine translation system (CoVe).”
MethodConstituency Parsing with a Self-Attentive Encoder
Kitaev, N., & Klein, D. (2018) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p18-1249 · Cited by 531
Deep Semantic Role Labeling: What Works and What’s Next
He, L., Lee, K., Lewis, M., & Zettlemoyer, L. (2017) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p17-1044 · Cited by 432
Self-citationWhat you can cram into a single vector: Probing sentence embeddings for linguistic propertiesPreprint
Conneau, A., Kruszewski, G., Lample, G., Barrault, L., & Baroni, M. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1805.01070 · Cited by 426
On the State of the Art of Evaluation in Neural Language ModelsPreprint
Melis, G., Dyer, C., & Blunsom, P. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1707.05589 · Cited by 397
Introduction to the CoNLL-2000 Shared Task: ChunkingPreprint
Sang, E. F. T. K., & Buchholz, S. (2000) · arXiv (Cornell University) · doi:10.4230/oasics.ldk.2021.20 · Cited by 365
(2013) · Iris (University of Trento) · Cited by 360
Deep Semantic Role Labeling With Self-Attention
Tan, Z., Wang, M., Xie, J., Chen, Y., & Shi, X. (2018) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v32i1.11928 · Cited by 312
What do Neural Machine Translation Models Learn about Morphology?
Belinkov, Y., Durrani, N., Dalvi, F., Sajjad, H., & Glass, J. (2017) · Proceedings of the 55th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p17-1080 · Cited by 307
Sharp nearby, fuzzy far away: How neural language models use context
Khandelwal, U., He, H., Qi, P., & Jurafsky, D. (2018) · Proceedings of the 56th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/p18-1027 · Cited by 303
Natural Language Inference over Interaction SpacePreprint
Gong, Y., Luo, H., & Zhang, J. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1709.04348 · Cited by 252
Beyond Word Importance: Contextual Decomposition to Extract Interactions from LSTMsPreprint
Murdoch, W. J., Liu, P. J., & Yu, B. (2018) · arXiv (Cornell University) · doi:10.48550/arxiv.1801.05453 · Cited by 191
Zhang, K., & Bowman, S. R. (2018) · BlackboxNLP Workshop on Analyzing and Interpreting Neural Networks for NLP (BlackboxNLP) · doi:10.18653/v1/w18-5448 · Cited by 168
Representation of Linguistic Form and Function in Recurrent Neural Networks
Kádár, Á., Chrupała, G., & Alishahi, A. (2017) · Computational Linguistics · doi:10.1162/coli_a_00300 · Cited by 147
What Do Recurrent Neural Network Grammars Learn About Syntax?
Kuncoro, A., Ballesteros, M., Kong, L., Dyer, C., Neubig, G., & Smith, N. A. (2017) · Conference of the European Chapter of the Association for Computational Linguistics · doi:10.18653/v1/e17-1117 · Cited by 131
Deep RNNs Encode Soft Hierarchical Syntax
Blevins, T., Levy, O., & Zettlemoyer, L. (2018) · Annual Meeting of the Association for Computational Linguistics (ACL) · doi:10.18653/v1/p18-2003 · Cited by 117
Self-citationExtending a Parser to Distant Domains Using a Few Dozen Partially Annotated Examples
Joshi, V., Peters, M. E., & Hopkins, M. (2018) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/p18-1110 · Cited by 109
Self-citationWhat’s Going On in Neural Constituency Parsers? An Analysis
Gaddy, D., Stern, M., & Klein, D. (2018) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/n18-1091 · Cited by 72
Efficient Contextualized Representation: Language Model Pruning for Sequence Labeling
Liu, L., Ren, X., Shang, J., Gu, X., Peng, J., & Han, J. (2018) · Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d18-1153 · Cited by 45
Research works printed but not linked: 4
- Yonatan Belinkov, Nadir Durrani, Fahim Dalvi, Has- san Sajjad, and James R. Glass. 2017. What do neu- ral machine translation models learn about morphol- ogy? In ACL.
- Guillaume Klein, Yoon Kim, Yuntian Deng, Jean Senellart, and Alexander M. Rush. 2017. Open- NMT: Open-source toolkit for neural machine trans- lation. In ACL.
- Liyuan Liu, Xiang Ren, Jingbo Shang, Jian Peng, and Jiawei Han. 2018. Efficient contextualized represen- tation: Language model pruning for sequence label- ing. In EMNLP.
- Matthew E. Peters, Mark Neumann, Mohit Iyyer, Matt Gardner, Christopher Clark, Kenton Lee, and Luke Zettlemoyer. 2018. Deep contextualized word rep- resentations. In NAACL.
Cited by
Sorted by citations
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Language Models as Knowledge Bases?
Petroni, F., Rocktäschel, T., Riedel, S., Lewis, P., Bakhtin, A., Wu, Y., & Miller, A. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1250 · Cited by 1,834
How Multilingual is Multilingual BERT?
Pires, T., Schlinger, E., & Garrette, D. (2019) · Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/p19-1493 · Cited by 1,351
Metadata
- Authors
- Peters, M., Neumann, M., Zettlemoyer, L., & Yih, W.-T.
- Affiliations
- Allen Institute for Artificial Intelligence (US)
- University of Washington (US)
- Venue
- Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing
- Published
- 2018
- Pages
- 1499-1509
- OpenAlex
- W2888329843
- Cited by
- 434
- References
- 57
- Citations by year
- 2026: 23 · 2025: 27 · 2024: 37 · 2023: 53 · 2022: 55 · 2021: 75 · 2020: 83 · 2019: 77 · 2018: 4
- FWCI
- 24.08
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Sentiment Analysis and Opinion Mining
- Keywords
- contextual word embeddings, bidirectional language models, LSTM, convolutional neural networks, self-attention, representation learning, network depth, morphological representation, syntactic representation, coreference, word embeddings, speed-accuracy trade-off
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
