

The DOI matches its Crossref record; 32 of the 32 references it cites were found in a registry or an index; none of the 45 sources its claims cite is checked for support yet.
Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes
Open accessAbstract
BACKGROUND: A pilot study can be an important step in the assessment of an intervention by providing information to design the future definitive trial. Pilot studies can be used to estimate the recruitment and retention rates and population variance and to provide preliminary evidence of efficacy potential. However, estimation is poor because pilot studies are small, so sensitivity analyses for the main trial's sample size calculations should be undertaken. METHODS: We demonstrate how to carry out easy-to-perform sensitivity analysis for designing trials based on pilot data using an example. Furthermore, we introduce rules of thumb for the size of the pilot study so that the overall sample size, for both pilot and main trials, is minimized. RESULTS: The example illustrates how sample size estimates for the main trial can alter dramatically by plausibly varying assumptions. Required sample size for 90% power varied from 392 to 692 depending on assumptions. Some scenarios were not feasible based on the pilot study recruitment and retention rates. CONCLUSION: Pilot studies can be used to help design the main trial, but caution should be exercised. We recommend the use of sensitivity analyses to assess the robustness of the design assumptions for a main trial.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
Pilot studies can inform the design of definitive trials with continuous outcomes by estimating recruitment/retention, population variance, and preliminary efficacy potential, but their small size makes estimates imprecise. The paper recommends sensitivity analyses and stepped rules of thumb for pilot sample size, illustrated by an example where required main-trial sample size for 90% power ranged from 392 to 692 depending on assumptions.
Key findings
- In the worked example, main-trial sample size for 90% power varied from 392 to 692 depending on assumptions about the SD and dropout rate; for 80% power, sample sizes ranged from 296 to 518.
- The pilot example had a recruitment rate of 50% of eligible patients, at 25 recruitments per month, and 80% retention (40 of 50 participants completed all three assessments).
- Based on a target standardized effect size of 4/14 = 0.29 for a 90% powered main trial, the stepped rules of thumb indicated 25 patients per arm for the pilot.
- Feasibility assessment showed that recruiting over 1.5 years at 25 participants per month would enroll 450 participants, falling below several sample size estimates in the sensitivity analysis.
Methods
- Methodological guidance paper with a worked example using a continuous outcome; it focuses on external pilot studies whose results are not combined with the main trial.
- The example is a hypothetical two-arm RCT comparing a new supportive care regimen for cancer patients to usual care, with quality of life at 3 months measured by FACT-G; the pilot had 50 participants, with 100 potential participants, 70 referred, 60 eligible, and 50 agreeing to participate.
- Main analysis demonstrates sample size sensitivity analyses varying the SD (pilot SD, upper 80% CI limit, literature estimate) and dropout rates (observed 20%, >5%, <5%), plus stepped rules of thumb for pilot sample size based on target effect size and future trial size.
Limitations
- Stated: pilot studies are small, so effect size and SD estimates are imprecise; using a pilot study’s SD to design a future sample size has been shown to often result in an underpowered study, and preliminary efficacy evidence from a pilot should not be overstated.
- Stated: sensitivity analyses are needed because sample size estimates can alter dramatically by plausibly varying assumptions, and some scenarios may not be feasible based on pilot recruitment and retention rates.
- Evident from the text: the worked example is explicitly hypothetical (“Suppose…”), so its numerical results are illustrative rather than empirical findings from an actual pilot study.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
31 Not checked yet · 8 No basis given · 7 Own result · 6 Own interpretation
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Required sample size for 90% power varied from 392 to 692 depending on assumptions.”
- Also stated in: § Sample size calculations and sensitivity analyses · plain
“For 90% power, sample size ranges from 392 to 692.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Abstract > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Sample size calculations and sensitivity analyses · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The example illustrates how sample size estimates for the main trial can alter dramatically by plausibly varying assumptions.”
- Also stated in: § Conclusion · boosted
“The example demonstrated how main trial sample size estimates can vary dramatically by plausibly altering assumptions.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Abstract > Results
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Conclusion · boosted
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Some scenarios were not feasible based on the pilot study recruitment and retention rates.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Abstract > Results
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For 80% power, sample sizes range from 296 to 518.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Sample size calculations and sensitivity analyses
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Using an MID estimate of four points, and an SD of 14, the standardized effect size is 4/14=0.29.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Pilot study sample size
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
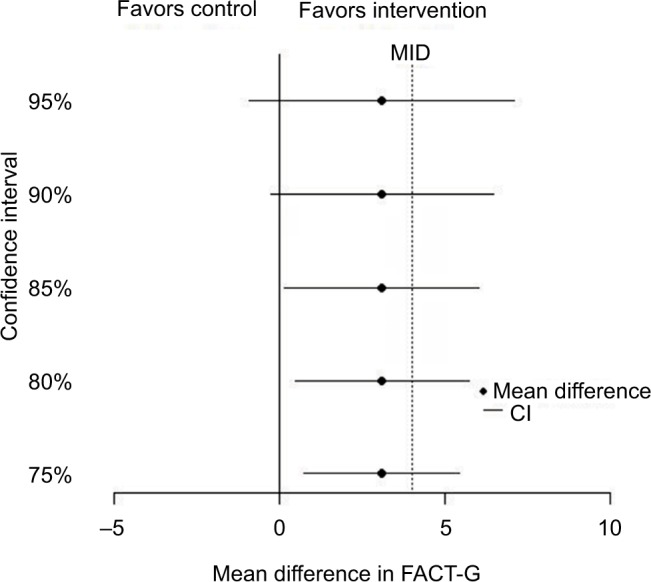
“Figure 1 shows several CIs demonstrating that the intervention is promising, as each CI contains the MID of 4.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Pilot study results
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“The target effect size must also be realistic, and the estimated effect size and confidence interval (CI) from the pilot can give some evidence here, ie, whether there is any indication that the intervention is effective and important differences might be obtained in the main trial.5”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Target effect size and potential efficacy
What the sources say
- Not checked yetcites [5] Cocks K Torgerson DJ Sample size calculations for pilot randomized trials: a confidence interval approach J Clin Epidemiol 2013 66 2 197 201 23195919
hedgedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
None of the sources cited for this claim have been checked yet.
In the paper
“However, estimation is poor because pilot studies are small, so sensitivity analyses for the main trial’s sample size calculations should be undertaken.”
- Also stated in: § Target effect size and potential efficacy · plain
“The small sample size of a pilot makes estimation uncertain, so caution must be exercised.19,20”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Abstract > Background
What the sources say
- Not checked yetcites [19] Kraemer HC Mintz J Noda A Tinklenberg J Yesavage JA Caution regarding the use of pilot studies to guide power calculations for study proposals Arch Gen Psychiatry 2006 63 5 484 489 16651505
- Not checked yetcites [20] Loscalzo J Pilot trials in clinical research: of what value are they? Circulation 2009 119 13 1694 1696 19349331
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Target effect size and potential efficacy · plain
None of the sources cited for this claim have been checked yet.
In the paper
“The small sample size of a pilot makes estimation uncertain, so caution must be exercised.19,20”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Target effect size and potential efficacy
What the sources say
- Not checked yetcites [19] Kraemer HC Mintz J Noda A Tinklenberg J Yesavage JA Caution regarding the use of pilot studies to guide power calculations for study proposals Arch Gen Psychiatry 2006 63 5 484 489 16651505
- Not checked yetcites [20] Loscalzo J Pilot trials in clinical research: of what value are they? Circulation 2009 119 13 1694 1696 19349331
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
In the paper
“pilot studies can also give estimates of retention rates and adherence rates.11”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Feasibility
What the sources say
- Not checked yetcites [11] Avery KNL Williamson PR Gamble C Informing efficient randomised controlled trials: exploration of challenges in developing progression criteria for internal pilot studies BMJ Open 2017 7 2 e013537 PMC5318608 28213598
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 23
- It may state two separate claims as one. 15
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“If the pilot recruitment rate of 25 participants per month is a good estimate, then the study will be able to recruit and enroll 450 participants.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Feasibility of the main trial
plainconditionaln = 25- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Of the 50 participants, 40 participants completed all three assessments; retention is 80%.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Pilot study results
plainn = 50- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“This indicates a recruitment rate of 50% of eligible patients, at 25 recruitments per month.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Pilot study results
hedgedn = 50- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“The difference in the quality of life between the arms at 3 months is estimated at 3.1 points, with 95% CI −1.8 to 8.0, and SD =11.2.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Pilot study results
hedgedn = 50- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“This falls below several of the estimates in Table 2.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Feasibility of the main trial
plainn = 450- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“Hislop et al15 undertook a systematic review to identify seven approaches for determining the target effect size for an RCT and classified them as clinically important and/or realistic.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Target effect size and potential efficacy
What the sources say
- Not checked yetcites [15] Hislop J Adewuyi TE Vale LD Methods for specifying the target difference in a randomised controlled trial: the Difference ELicitation in TriAls (DELTA) systematic review PLoS Med 2014 11 5 e1001645 24824338 PMC4019477
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
In the paper
“While some authors argue against carrying out hypothesis tests and assessing efficacy from pilots, even potential efficacy, most pilot studies do undertake hypothesis tests.6”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Target effect size and potential efficacy
What the sources say
- Not checked yetcites [6] Shanyinde M Pickering RM Weatherall M Questions asked and answered in pilot and feasibility randomized controlled trials BMC Med Res Methodol 2011 11 1 117 21846349 PMC3170294
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“Pilot studies can be used to estimate the recruitment and retention rates and population variance and to provide preliminary evidence of efficacy potential.”
- Also stated in: § Introduction · plain
“To address this aim, there are a number of objectives for a pilot study including assessing recruitment and retention rates, obtaining estimates of parameters required for sample size calculation, and providing preliminary evidence of efficacy potential.3–6”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Abstract > Background
What the sources say
- Not checked yetcites [3] Craig P Dieppe P Macintyre S Developing and evaluating complex interventions: the new Medical Research Council guidance BMJ 2008 337 a1655 18824488 PMC2769032
- Not checked yetcites [4] Lancaster G Campbell M Eldridge S Trials in primary care: statistical issues in the design, conduct and evaluation of complex interventions Stat Methods Med Res 2010 19 4 349 377 20442193
- Not checked yetcites [5] Cocks K Torgerson DJ Sample size calculations for pilot randomized trials: a confidence interval approach J Clin Epidemiol 2013 66 2 197 201 23195919
- Not checked yetcites [6] Shanyinde M Pickering RM Weatherall M Questions asked and answered in pilot and feasibility randomized controlled trials BMC Med Res Methodol 2011 11 1 117 21846349 PMC3170294
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § Introduction · plain
In the paper
“A figure showing these CIs, the MID, and the null value can be a helpful way of displaying pilot results, by facilitating an assessment of both statistical significance and the potential for clinical significance.31”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Target effect size and potential efficacy
What the sources say
- Not checked yetcites [31] Bell ML Fiero MH Dhillon HM Bray VJ Vardy JL Statistical controversies in cancer research: using standardized effect size graphs to enhance interpretability of cancer-related clinical trials with patient-reported outcomes Ann Oncol 2017 28 8 1730 1733 28327975 PMC5834129
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Pilot trial results can inform each of these elements.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“The population SD is another key element of sample size estimation for continuous outcomes, and its estimation is one of the objectives for conducting a pilot study.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Estimating the standard deviation (SD)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“In the absence of a known MID for continuous outcomes, particularly patient-reported outcomes, a standardized effect size15 between 0.3 and 0.5 has been recommended.17,18”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Target effect size and potential efficacy
What the sources say
- Not checked yetcites [15] Hislop J Adewuyi TE Vale LD Methods for specifying the target difference in a randomised controlled trial: the Difference ELicitation in TriAls (DELTA) systematic review PLoS Med 2014 11 5 e1001645 24824338 PMC4019477
- Not checked yetcites [17] King M A point of minimal important difference (MID): a critique of terminology and methods Expert Rev Pharmacoecon Outcomes Res 2011 11 2 171 184 21476819
- Not checked yetcites [18] Norman GR Sloan JA Wyrwich KW The truly remarkable universality of half a standard deviation: confirmation through another look Expert Rev Pharmacoecon Outcomes Res 2004 4 5 581 585 19807551
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“Factors such as type I error and power are set independent of the pilot and are discussed in detail elsewhere.7”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design
What the sources say
- Not checked yetcites [7] Julious SA Sample sizes for clinical trials with normal data Stat Med 2004 23 12 1921 1986 15195324
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“Many trials struggle to reach their sample size goal, which can result in trial extensions or failure to recruit to their prespecified sample size.10”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Feasibility
What the sources say
- Not checked yetcites [10] Sully B Julious SA Nicholl J A reinvestigation of recruitment to randomised, controlled, multicenter trials: a review of trials funded by two UK funding agencies Trials 2013 14 166 23758961 PMC3691846
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“Pilot trials are often small versions of the main trial, undertaken to test trial methods and procedures.1,2”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Introduction
What the sources say
- Not checked yetcites [1] Thabane L Ma J Chu R A tutorial on pilot studies: the what, why and how BMC Med Res Methodol 2010 10 1 20053272 PMC2824145
- Not checked yetcites [2] Arain M Campbell MJ Cooper CL Lancaster GA What is a pilot or feasibility study? A review of current practice and editorial policy BMC Med Res Methodol 2010 10 67 20637084 PMC2912920
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“To address this aim, there are a number of objectives for a pilot study including assessing recruitment and retention rates, obtaining estimates of parameters required for sample size calculation, and providing preliminary evidence of efficacy potential.3–6”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Introduction
What the sources say
- Not checked yetcites [3] Craig P Dieppe P Macintyre S Developing and evaluating complex interventions: the new Medical Research Council guidance BMJ 2008 337 a1655 18824488 PMC2769032
- Not checked yetcites [4] Lancaster G Campbell M Eldridge S Trials in primary care: statistical issues in the design, conduct and evaluation of complex interventions Stat Methods Med Res 2010 19 4 349 377 20442193
- Not checked yetcites [5] Cocks K Torgerson DJ Sample size calculations for pilot randomized trials: a confidence interval approach J Clin Epidemiol 2013 66 2 197 201 23195919
- Not checked yetcites [6] Shanyinde M Pickering RM Weatherall M Questions asked and answered in pilot and feasibility randomized controlled trials BMC Med Res Methodol 2011 11 1 117 21846349 PMC3170294
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
In the paper
“Although some researchers use the pilot effect size to power the definitive trial, this is a practice that should be avoided in general, as estimation is poor due to the small sample size, and is likely to mislead.19”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Target effect size and potential efficacy
What the sources say
- Not checked yetcites [19] Kraemer HC Mintz J Noda A Tinklenberg J Yesavage JA Caution regarding the use of pilot studies to guide power calculations for study proposals Arch Gen Psychiatry 2006 63 5 484 489 16651505
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“One approach for handling this uncertainty is to use significance levels other than the “traditional” 5% to provide preliminary evidence for efficacy, with corresponding CIs such as 85 and 75% in addition to 95% CIs.21”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Target effect size and potential efficacy
What the sources say
- Not checked yetcites [21] Lee EC Whitehead AL Jacques RM Julious SA The statistical interpretation of pilot trials: should significance thresholds be reconsidered? BMC Med Res Methodol 2014 14 1 41 24650044 PMC3994566
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“From this work, they proposed stepped rules of thumb for pilot studies based on the target effect size and the size of the future trial.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Pilot study sample size
What the sources say
- Not checked yetcites [27] Whitehead A Julious S Cooper C Campbell MJ Estimating the sample size for a pilot randomised trial to minimise the overall trial sample size for the external pilot and main trial for a continuous outcome variable Stat Methods Med Res 2016 25 3 1057 1073 26092476 PMC4876429
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
None of the sources cited for this claim have been checked yet.
In the paper
“The decision to progress from a pilot trial to a main trial is generally made using feasibility estimates, as well as issues such as protocol nonadherence.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Conclusion
What the sources say
- Not checked yetcites [11] Avery KNL Williamson PR Gamble C Informing efficient randomised controlled trials: exploration of challenges in developing progression criteria for internal pilot studies BMJ Open 2017 7 2 e013537 PMC5318608 28213598
- Not checked yetcites [14] Hampson LV Williamson PR Wilby MJ Jaki T A framework for prospectively defining progression rules for internal pilot studies monitoring recruitment Stat Methods Med Res Epub 2017 1 01 28589752
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
None of the sources cited for this claim have been checked yet.
In the paper
“While there are several rules of thumb for the size of a pilot study, ranging from 12 to 35 individuals per arm,5,27 none of these guidelines account for the likely size of the future trial.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Pilot study sample size
What the sources say
- Not checked yetcites [5] Cocks K Torgerson DJ Sample size calculations for pilot randomized trials: a confidence interval approach J Clin Epidemiol 2013 66 2 197 201 23195919
- Not checked yetcites [27] Whitehead A Julious S Cooper C Campbell MJ Estimating the sample size for a pilot randomised trial to minimise the overall trial sample size for the external pilot and main trial for a continuous outcome variable Stat Methods Med Res 2016 25 3 1057 1073 26092476 PMC4876429
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Although traditional power calculations are inappropriate for pilot studies (since the primary aim of a pilot study is not to test superiority of one treatment over the other), a sample size justification is important.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Pilot study sample size
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We have illustrated how pilot studies can aid in the design of future trials with continuous outcomes by providing estimates of population SD, evidence of potential for intervention effectiveness, and quantification of feasibility in the form of recruitment and retention rates.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Conclusion
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These rates will aid in estimating the main trial duration.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Pilot study results
plaindirectn = 50- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
None of the sources cited for this claim have been checked yet.
In the paper
“They find that the estimated FACT-G MID is between three and six points29 and an SD estimate from the literature30 is 14 in similar populations.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Pilot study sample size
What the sources say
- Not checked yetcites [29] Webster K Cella D Yost K The functional assessment of chronic illness therapy (FACIT) measurement system: properties, applications, and interpretation Health Qual Life Outcomes 2003 1 79 14678568 PMC317391
- Not checked yetcites [30] Bell ML McKenzie JE Designing psycho-oncology randomised trials and cluster randomised trials: variance components and intra-cluster correlation of commonly used psychosocial measures Psychooncology 2013 22 8 1738 1747 23080401
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Sensitivity analyses should also be performed in the design stage26 and can take the form of accounting for the uncertainty in estimation by calculating sample sizes based on a range of plausible SDs and retention/dropout rates.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Sensitivity analysis for sample size
What the sources say
- Not checked yetcites [26] Lewis JA Statistical principles for clinical trials (ICH E9): an introductory note on an international guideline Stat Med 1999 18 15 1903 1942 10440877
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“Sensitivity analyses are important to assess the robustness of study results to the assumptions made in the primary analysis.25”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Sensitivity analysis for sample size
What the sources say
- Not checked yetcites [25] Thabane L Mbuagbaw L Zhang S A tutorial on sensitivity analyses in clinical trials: the what, why, when and how BMC Med Res Methodol 2013 13 1 92 23855337 PMC3720188
plain- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Thus, the objective of the pilot study to provide preliminary evidence of efficacy has been met.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Pilot study results
plainn = 50- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“For example, if the future trial will be designed around a small effect, then the number of patients per arm for the pilot study should be 25 for 90% power.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Pilot study sample size
What the sources say
- Not checked yetcites [27] Whitehead A Julious S Cooper C Campbell MJ Estimating the sample size for a pilot randomised trial to minimise the overall trial sample size for the external pilot and main trial for a continuous outcome variable Stat Methods Med Res 2016 25 3 1057 1073 26092476 PMC4876429
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“A CONSORT extension for reporting results of pilot and feasibility studies gives detailed guidelines.9”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Conclusion
What the sources say
- Not checked yetcites [9] Eldridge SM Chan CL Campbell MJ CONSORT 2010 statement: extension to randomised pilot and feasibility trials BMJ 2016 355 i5239 27777223 PMC5076380
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For a 90% powered main trial, they should use a sample size of 25 per arm for the pilot (Table 1).”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Pilot study sample size
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“Browne23 suggested using the pilot study’s upper limit of the 80% CI for the SD to calculate sample size in the subsequent trial.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Considerations for trial design > Sensitivity analysis for sample size
What the sources say
- Not checked yetcites [23] Browne RH On the use of a pilot sample for sample size determination Stat Med 1995 14 17 1933 1940 8532986
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“Cocks and Torgerson5 also recommend basing the pilot study size on the future trial’s size, if the SD is known.”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Pilot study sample size
What the sources say
- Not checked yetcites [5] Cocks K Torgerson DJ Sample size calculations for pilot randomized trials: a confidence interval approach J Clin Epidemiol 2013 66 2 197 201 23195919
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“In order to stablish the sample size required for this trial, we follow recommendations by Bell et al. (2018) which proposed that a sample size of 60 participants would be adequate considering an effect size of 0.3 and 80% of power.”
From Unified Protocol for the transdiagnostic treatment of emotional disorders in people with post COVID-19 condition: study protocol for a multiple baseline n-of-1 trial (2023) · cites this paper as Bell et al., 2018
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“CIs and minimal clinically important differences (MCIDs) are presented to suggest plausible evidence of effect for respective study arms.34 35”
The cited source says what the claim attributes to it.
In the citing paper
“Lee et al35 and Bell et al34 suggest using CIs and the MCID to interpret feasibility trials.”
The cited source says what the claim attributes to it.
In the citing paper
“The method of setting the pilot trial sample size was applied [49,50], and the following parameters were chosen to establish the sample size:”
From HAPPY MAMA Project (Part 2)—Maternal Distress and Self-Efficacy: A Pilot Randomized Controlled Field Trial (2022) · cites this paper as [49]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“Of the 100 potential participants, 70 participants were referred by their oncologist, 60 participants met eligibility criteria, and 50 participants agreed to participate. This indicates a recruitment rate of 50% of eligible patients”
§ Guidance for using pilot studies to inform the design of intervention trials with continuous outcomes > Example > Pilot study results
Reported 50 · recomputed 83.333333
Citations
Cites
Developing and evaluating complex interventions: the new Medical Research Council guidance
Craig, P., Dieppe, P., Macintyre, S., Michie, S., Nazareth, I., & Petticrew, M. (2008) · BMJ · doi:10.1136/bmj.a1655 · Cited by 10,995
The functional assessment of cancer therapy scale: development and validation of the general measure
Cella, D. F., Tulsky, D. S., Gray, G., Sarafian, B., Linn, E., Bonomi, A., Silberman, M., Yellen, S. B., Winicour, P., & Brannon, J. (1993) · Journal of Clinical Oncology · doi:10.1200/jco.1993.11.3.570 · Cited by 6,020
CONSORT 2010 statement: extension to randomised pilot and feasibility trials.
Eldridge, S. M., Chan, C. L., Campbell, M. J., Bond, C. M., Hopewell, S., Thabane, L., & Lancaster, G. A. (2016) · BMJ · doi:10.1136/bmj.i5239 · Cited by 3,404
A tutorial on pilot studies: the what, why and how
Thabane, L., Ma, J., Chu, R., Cheng, J., Ismaila, A., Rios, L. P., Robson, R., Thabane, M., Giangregorio, L., & Goldsmith, C. H. (2010) · BMC Medical Research Methodology · doi:10.1186/1471-2288-10-1 · Cited by 3,384
CONSORT 2010 statement: extension to randomised pilot and feasibility trials
on behalf of the PAFS consensus group, Eldridge, S. M., Chan, C. L., Campbell, M. J., Bond, C. M., Hopewell, S., Thabane, L., & Lancaster, G. A. (2016) · Pilot and Feasibility Studies · doi:10.1186/s40814-016-0105-8 · Cited by 2,843
Design and analysis of pilot studies: recommendations for good practice
Lancaster, G. A., Dodd, S., & Williamson, P. R. (2004) · Journal of Evaluation in Clinical Practice · doi:10.1111/j..2002.384.doc.x · Cited by 2,572 · cited 1×
“We strongly stress that preliminary efficacy evidence from a pilot study should not be overstated, and researchers should avoid temptation to forgo the main trial.(20,22)”
Whitehead, A. L., Julious, S. A., Cooper, C. L., & Campbell, M. J. (2016) · Statistical Methods in Medical Research · doi:10.1177/0962280215588241 · Cited by 1,936 · cited 2×
“Whitehead et al 27 showed how, if you know the main trial’s target effect size, you can estimate the pilot study’s optimum sample size, minimizing the number of patients recruited across the two studies.”
Self-citation(2003) · Health and Quality of Life Outcomes · doi:10.1186/1477-7525-1-79 · Cited by 1,506
What is a pilot or feasibility study? A review of current practice and editorial policy
Arain, M., Campbell, M. J., Cooper, C. L., & Lancaster, G. A. (2010) · BMC Medical Research Methodology · doi:10.1186/1471-2288-10-67 · Cited by 1,483
On the use of a pilot sample for sample size determination
Browne, R. H. (1995) · Statistics in Medicine · doi:10.1002/sim.4780141709 · Cited by 1,007
A tutorial on sensitivity analyses in clinical trials: the what, why, when and how
Thabane, L., Mbuagbaw, L., Zhang, S., Samaan, Z., Marcucci, M., Ye, C., Thabane, M., Giangregorio, L., Dennis, B., Kosa, D., et al. (2013) · BMC Medical Research Methodology · doi:10.1186/1471-2288-13-92 · Cited by 893
. Caution regarding the use of pilot studies to guide power calculations for study proposals.
Kraemer, H. C., Mintz, J., Noda, A., Tinklenberg, J., & Yesavage, J. A. (2006) · Archives of General Psychiatry · doi:10.1001/archpsyc.63.5.484 · Cited by 702 · cited 2×
“The small sample size of a pilot makes estimation uncertain, so caution must be exercised.(19,20) One approach for handling this uncertainty is to use significance levels other than the “traditional” 5% to provide preliminary evidence for efficacy, with corresponding CIs such as 85 and 75% in addition to 95% CIs.”
A point of minimal important difference (MID): a critique of terminology and methods
King, M. T. (2011) · Expert Review of Pharmacoeconomics & Outcomes Research · doi:10.1586/erp.11.9 · Cited by 653
Sample sizes for clinical trials with normal data.
Julious, S. A. (2004) · Statistics in Medicine · doi:10.1002/sim.1783 · Cited by 605
Self-citationAvery, K. N. L., Williamson, P. R., Gamble, C., O'Connell Francischetto, E., Metcalfe, C., Davidson, P., Williams, H., & Blazeby, J. M. (2017) · BMJ Open · doi:10.1136/bmjopen-2016-013537 · Cited by 575
The truly remarkable universality of half a standard deviation: confirmation through another look
Norman, G. R., Sloan, J. A., & Wyrwich, K. W. (2004) · Expert Review of Pharmacoeconomics & Outcomes Research · doi:10.1586/14737167.4.5.581 · Cited by 490
Responsiveness and minimal important differences for patient reported outcomes
Revicki, D. A., Cella, D. F., Hays, R. D., Sloan, J. A., Lenderking, W. R., & Aaronson, N. K. (2006) · Health and Quality of Life Outcomes · doi:10.1186/1477-7525-4-70 · Cited by 475
The role of internal pilot studies in increasing the efficiency of clinical trials
Wittes, J. T., & Brittain, E. (1990) · Statistics in Medicine · doi:10.1002/sim.4780090113 · Cited by 443
Sample size calculations for pilot randomized trials: a confidence interval approach
Cocks, K., & Torgerson, D. J. (2013) · Journal of Clinical Epidemiology · doi:10.1016/j.jclinepi.2012.09.002 · Cited by 431
The statistical interpretation of pilot trials: should significance thresholds be reconsidered?
Lee, E. C., Whitehead, A. L., Jacques, R. M., & Julious, S. A. (2014) · BMC Medical Research Methodology · doi:10.1186/1471-2288-14-41 · Cited by 423
Self-citationSully, B. G. O., Julious, S. A., & Nicholl, J. (2013) · Trials · doi:10.1186/1745-6215-14-166 · Cited by 410
Self-citationHandling missing data in RCTs; a review of the top medical journals
Bell, M. L., Fiero, M., Horton, N. J., & Hsu, C.-H. (2014) · BMC Medical Research Methodology · doi:10.1186/1471-2288-14-118 · Cited by 395
Self-citationPractical and statistical issues in missing data for longitudinal patient-reported outcomes
Bell, M. L., & Fairclough, D. L. (2013) · Statistical Methods in Medical Research · doi:10.1177/0962280213476378 · Cited by 285
Self-citationQuestions asked and answered in pilot and feasibility randomized controlled trials
Shanyinde, M., Pickering, R. M., & Weatherall, M. (2011) · BMC Medical Research Methodology · doi:10.1186/1471-2288-11-117 · Cited by 229
Underpowering in randomized trials reporting a sample size calculation
Vickers, A. J. (2003) · Journal of Clinical Epidemiology · doi:10.1016/s0895-4356(03)00141-0 · Cited by 102
Bell, M. L., & McKenzie, J. E. (2012) · Psycho-Oncology · doi:10.1002/pon.3205 · Cited by 98
Self-citationPilot Trials in Clinical Research
Loscalzo, J. (2009) · Circulation · doi:10.1161/circulationaha.109.861625 · Cited by 57
Lancaster, G., Campbell, M. J., Eldridge, S. M., Farrin, A. J., Marchant, M., Müller, S., Perera, R., Peters, T., Prevost, A. T., & Rait, G. (2010) · Statistical Methods in Medical Research · doi:10.1177/0962280209359883 · Cited by 54
Hislop, J., Adewuyi, T. E., Vale, L. D., Harrild, K., Fraser, C. M., Gurung, T., Altman, D. G., Briggs, A. H., Fayers, P. M., Ramsay, C. R., et al. (2014) · PLoS Medicine · doi:10.1371/journal.pmed.1001645 · Cited by 36
Tan, M. T., Qu, Y., Mascha, E. J., & Schubert, A. (1999) · Statistics in Medicine · doi:10.1002/(sici)1097-0258(19990815)18:15 · Cited by 26
Hampson, L. V., Williamson, P. R., Wilby, M. J., & Jaki, T. (2017) · Statistical Methods in Medical Research · doi:10.1177/0962280217708906 · Cited by 16
Bell, M., Fiero, M., Dhillon, H., Bray, V., & Vardy, J. (2017) · Annals of Oncology · doi:10.1093/annonc/mdx064 · Cited by 15
Self-citation
Cited by
Sorted by citations
Guidance for conducting feasibility and pilot studies for implementation trials
Pearson, N., Naylor, P.-J., Ashe, M. C., Fernandez, M., Yoong, S. L., & Wolfenden, L. (2020) · Pilot and Feasibility Studies · doi:10.1186/s40814-020-00634-w · Cited by 475
A brief overview of pilot studies and their sample size justification
Kunselman, A. R. (2024) · Fertility and Sterility · doi:10.1016/j.fertnstert.2024.01.040 · Cited by 329
Applying mixed methods to pilot feasibility studies to inform intervention trials
Aschbrenner, K. A., Kruse, G. R., Gallo, J. J., & Clark, V. L. P. (2022) · Pilot and Feasibility Studies · doi:10.1186/s40814-022-01178-x · Cited by 188
“Investigators commonly use quantitative metrics such as recruitment and retention rates to determine whether or not pre-specified feasibility criteria and milestones were met to signal that the research can advance to the next stage of testing [7, 13, 16].”
MethodFontalis, A., Kayani, B., Asokan, A. K., Haddad, I. C., Tahmassebi, J. E., Konan, S., Oussedik, S. I., & Haddad, F. S. (2022) · Journal of Bone and Joint Surgery · doi:10.2106/jbjs.22.00167 · Cited by 85
Power Analysis and Exploratory Research
Haile, Z. T. (2023) · Journal of Human Lactation · doi:10.1177/08903344231195625 · Cited by 91
“However, alternative strategies for calculating sample sizes for pilot studies have recently been proposed (Bell et al., 2018; Julious, 2016).”
Background
Metadata
- Authors
- Bell, M. L., Whitehead, A. L., & Julious, S. A.
- Affiliations
- University of Arizona (US)
- University of Sheffield (GB)
- Corresponding author
- Bell, Melanie L
- Venue
- Clinical Epidemiology
- Publisher
- Informa UK Limited
- Published
- 2018-01
- Volume
- Volume 10
- Pages
- 153-157
- ISSN
- 1179-1349 (ISSN-L)
- PMC
- PMC5779280
- OpenAlex
- W2783709266
- Semantic Scholar
- cfec5aaa40794375792112254874a4c92fb0bf5e
- Cited by
- 280
- References
- 32
- Citations by year
- 2026: 37 · 2025: 52 · 2024: 22 · 2023: 48 · 2022: 43 · 2021: 37 · 2020: 26 · 2019: 12 · 2018: 3
- FWCI
- 16.18
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Clinical Epidemiology (publishedVersion, cc-by-nc)
- Europe PMC (PubMed Central) (publishedVersion, cc-by-nc)
- PubMed Central (publishedVersion, cc-by-nc)
- PubMed (publishedVersion)
- White Rose Research Online (University of Leeds, The University of Sheffield, University of York) (acceptedVersion)
- ePrints Soton (University of Southampton) (acceptedVersion)
- UA Campus Repository (The University of Arizona) (acceptedVersion, cc-by-nc)
- Dove Medical Press (Taylor and Francis Group) (submittedVersion, cc-by-nc)
- Funders
- University of Southampton
- National Cancer Institute (P30CA023074)
- Topics
- Physical Sciences › Mathematics › Statistics and Probability › Statistical Methods in Clinical Trials
- Physical Sciences › Mathematics › Statistics and Probability › Statistical Methods in Epidemiology
- Social Sciences › Decision Sciences › Statistics, Probability and Uncertainty › Meta-analysis and systematic reviews
- Keywords
- pilot study, trial design, sample size determination, sensitivity analysis, continuous outcomes, population variance estimation
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-09, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-09 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
