

The DOI matches its Crossref record; 29 of the 29 references it cites were found in a registry or an index.
AI chatbots not yet ready for clinical use.
Open accessPublished version of a preprint
Abstract
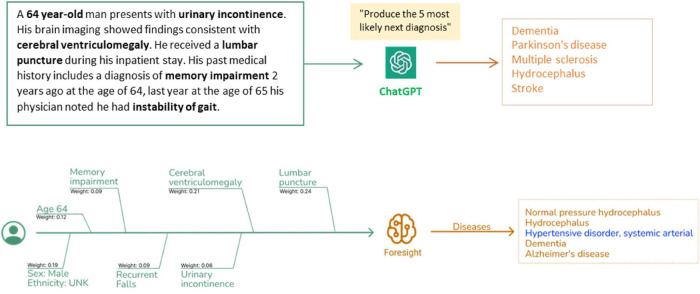
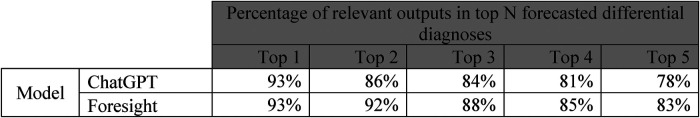
As large language models (LLMs) expand and become more advanced, so do the natural language processing capabilities of conversational AI, or "chatbots". OpenAI's recent release, ChatGPT, uses a transformer-based model to enable human-like text generation and question-answering on general domain knowledge, while a healthcare-specific Large Language Model (LLM) such as GatorTron has focused on the real-world healthcare domain knowledge. As LLMs advance to achieve near human-level performances on medical question and answering benchmarks, it is probable that Conversational AI will soon be developed for use in healthcare. In this article we discuss the potential and compare the performance of two different approaches to generative pretrained transformers-ChatGPT, the most widely used general conversational LLM, and Foresight, a GPT (generative pretrained transformer) based model focused on modelling patients and disorders. The comparison is conducted on the task of forecasting relevant diagnoses based on clinical vignettes. We also discuss important considerations and limitations of transformer-based chatbots for clinical use.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“hallucinations are also well described in transformerbased generative models, 24,25 including the recent ChatGPT”
From Foresight-a generative pretrained transformer for modelling of patient timelines using electronic health records: a retrospective modelling study (2024) · cites this paper as [25]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Jakubův, J., Chvalovský, K., Goertzel, Z., et al. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,648
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Large Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Semantics derived automatically from language corpora contain human-like biases
Caliskan, A., Bryson, J. J., & Narayanan, A. (2017) · Science · doi:10.1126/science.aal4230 · Cited by 2,887
PaLM: Scaling Language Modeling with Pathways
Chowdhery, A., Narang, S., Devlin, J., Bosma, M., Mishra, G., Roberts, A., Barham, P., Chung, H. W., Sutton, C., Gehrmann, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2204.02311 · Cited by 2,590
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · Proceedings of the 58th Annual Meeting of the Association for Computational Linguistics · doi:10.18653/v1/2020.acl-main.173 · Cited by 1,185
On Faithfulness and Factuality in Abstractive Summarization
Maynez, J., Narayan, S., Bohnet, B., & McDonald, R. (2020) · arXiv · doi:10.48550/arxiv.2005.00661 · Cited by 1,185
Training Compute-Optimal Large Language Models
Hoffmann, J., Borgeaud, S., Mensch, A., Buchatskaya, E., Cai, T., Rutherford, E., Casas, D. D. L., Hendricks, L. A., Welbl, J., Clark, A., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2176 · Cited by 932
Cited by
Sorted by citations
Alqahtani, T., Badreldin, H. A., Alrashed, M., Alshaya, A. I., Alghamdi, S. S., bin Saleh, K., Alowais, S. A., Alshaya, O. A., Rahman, I., Al Yami, M. S., et al. (2023) · Research in Social and Administrative Pharmacy · doi:10.1016/j.sapharm.2023.05.016 · Cited by 565
Haltaufderheide, J., & Ranisch, R. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01157-x · Cited by 396
Large Language Models in Medicine: The Potentials and Pitfalls
Omiye, J. A., Gui, H., Rezaei, S. J., Zou, J., & Daneshjou, R. (2024) · Annals of Internal Medicine · doi:10.7326/m23-2772 · Cited by 430
Zaretsky, J., Kim, J. M., Baskharoun, S., Zhao, Y., Austrian, J., Aphinyanaphongs, Y., Gupta, R., Blecker, S. B., & Feldman, J. (2024) · JAMA Network Open · doi:10.1001/jamanetworkopen.2024.0357 · Cited by 303
Large Language Models for Chatbot Health Advice Studies: A Systematic Review
Huo, B., Boyle, A., Marfo, N., Tangamornsuksan, W., Steen, J. P., McKechnie, T., Lee, Y., Mayol, J., Antoniou, S. A., Thirunavukarasu, A. J., et al. (2025) · JAMA Network Open · doi:10.1001/jamanetworkopen.2024.57879 · Cited by 283
Garg, R. K., Urs, V. L., Agrawal, A. A., Chaudhary, S. K., Paliwal, V. K., & Kar, S. K. (2023) · Health Promotion Perspectives · doi:10.34172/hpp.2023.22 · Cited by 247
An evaluation framework for clinical use of large language models in patient interaction tasks
Johri, S., Jeong, J., Tran, B. A., Schlessinger, D. I., Wongvibulsin, S., Barnes, L. A., Zhou, H.-Y., Cai, Z. R., Van Allen, E. M., Kim, D., et al. (2025) · Nature Medicine · doi:10.1038/s41591-024-03328-5 · Cited by 201
Assessing the research landscape and clinical utility of large language models: a scoping review
Park, Y.-J., Pillai, A., Deng, J., Guo, E., Gupta, M., Paget, M., & Naugler, C. (2024) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-024-02459-6 · Cited by 187
Choudhury, A., & Chaudhry, Z. (2024) · Journal of Medical Internet Research · doi:10.2196/56764 · Cited by 159
Chakraborty, C., Pal, S., Bhattacharya, M., Dash, S., & Lee, S. (2023) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2023.1237704 · Cited by 178
Black Box Warning: Large Language Models and the Future of Infectious Diseases Consultation
Schwartz, I. S., Link, K. E., Daneshjou, R., & Cortés-Penfield, N. (2024) · Clinical Infectious Diseases · doi:10.1093/cid/ciad633 · Cited by 131
Physician and artificial intelligence chatbot responses to cancer questions from social media
Chen, D., Parsa, R., Hope, A., Hannon, B., Mak, E., Eng, L., Liu, F.-F., Fallah-Rad, N., Heesters, A. M., & Raman, S. (2024) · JAMA Oncology · doi:10.1001/jamaoncol.2024.0836 · Cited by 120
Kraljevic, Z., Bean, D., Shek, A., Bendayan, R., Hemingway, H., Yeung, J. A., Deng, A., Balston, A., Ross, J., Idowu, E., et al. (2024) · The Lancet Digital Health · doi:10.1016/s2589-7500(24)00025-6 · Cited by 169
“Finally, hallucinations are also well described in transformerbased generative models, 24,25 including the recent ChatGPT, so such relevancy and mitigation systems would need to be built before the model would be suitable for clinical decision support.”
Self-citationGenerative Artificial Intelligence Through ChatGPT and Other Large Language Models in Ophthalmology
Tan, T. F., Thirunavukarasu, A. J., Campbell, J. P., Keane, P. A., Pasquale, L. R., Abràmoff, M. D., Kalpathy–Cramer, J., Lum, F., Kim, J. E., Baxter, S. L., et al. (2023) · Ophthalmology Science · doi:10.1016/j.xops.2023.100394 · Cited by 124
Essam, M., Deif, M. A., Attar, H. H., Alrosan, A., Kanan, M. A., & Elgohary, R. (2024) · IEEE Access · doi:10.1109/access.2024.3458466 · Cited by 112
Rokhshad, R., Zhang, P., Mohammad‐Rahimi, H., Pitchika, V., Entezari, N., & Schwendicke, F. (2024) · Journal of Dentistry · doi:10.1016/j.jdent.2024.104938 · Cited by 120
A Systematic Review of the Limitations and Associated Opportunities of ChatGPT
Cong‐Lem, N., Soyoof, A., & Tsering, D. (2024) · International Journal of Human-Computer Interaction · doi:10.1080/10447318.2024.2344142 · Cited by 140
DRG-LLaMA : tuning LLaMA model to predict diagnosis-related group for hospitalized patients
Wang, H., Gao, C., Dantona, C., Hull, B., & Sun, J. (2024) · npj Digital Medicine · doi:10.1038/s41746-023-00989-3 · Cited by 99
“Nonetheless, the medical domain introduces elevated concerns regarding safety and privacy, necessitating detailed analysis regarding the performance and limitations of LLMs to address the inherent risks such as hallucination, bias, and reasoning deficiencies (Au Yeung et al. 2023).”
Opportunities and risks of large language models in psychiatry
Obradovich, N., Khalsa, S. S., Khan, W. U., Suh, J., Perlis, R. H., Ajilore, O., & Paulus, M. P. (2024) · NPP—Digital Psychiatry and Neuroscience · doi:10.1038/s44277-024-00010-z · Cited by 103
New Horizons in artificial intelligence in the healthcare of older people
Shiwani, T., Relton, S. D., Evans, R., Kale, A. U., Heaven, A., Clegg, A. P., Abuzour, A. S., Alderman, J. E., Anand, A., Bhanu, C., et al. (2023) · Age and Ageing · doi:10.1093/ageing/afad219 · Cited by 102
Madrid-García, A., Rosales, Z., Freites, D., Pérez-Sancristóbal, I., Pato-Cour, E., Plasencia‐Rodríguez, C., Osorio, L. C., Abásolo, L., León, L., Fernández‐Gutiérrez, B., et al. (2023) · Scientific Reports · doi:10.1038/s41598-023-49483-6 · Cited by 81
Pushpanathan, K., Lim, Z. W., Yew, S. M. E., Chen, D. Z., Lin, H. A. H., Goh, J. H. L., Wong, W., Wang, X., Tan, M. C. J., Koh, V., et al. (2023) · iScience · doi:10.1016/j.isci.2023.108163 · Cited by 82
Chow, J. C. L., & Li, K. (2024) · JMIR Bioinformatics and Biotechnology · doi:10.2196/64406 · Cited by 75
Talyshinskii, A., Naik, N., Hameed, B. M. Z., Juliebø‐Jones, P., & Somani, B. K. (2023) · Current Urology Reports · doi:10.1007/s11934-023-01184-3 · Cited by 86
Can deepseek and ChatGPT be used in the diagnosis of oral pathologies?
Kaygisiz, Ö. F., & Teke, M. T. (2025) · BMC Oral Health · doi:10.1186/s12903-025-06034-x · Cited by 73
Suppadungsuk, S., Thongprayoon, C., Krisanapan, P., Tangpanithandee, S., Garcia Valencia, O., Miao, J., Mekraksakit, P., Kashani, K., & Cheungpasitporn, W. (2023) · Journal of Clinical Medicine · doi:10.3390/jcm12175550 · Cited by 56
Artificial intelligence chatbots for the nutrition management of diabetes and the metabolic syndrome
Naja, F., Taktouk, M., Matbouli, D., Khaleel, S., Maher, A., Uzun, B., Alameddine, M., & Nasreddine, L. (2024) · European Journal of Clinical Nutrition · doi:10.1038/s41430-024-01476-y · Cited by 59
Zhang, X., Li, Z., Zhang, M., Yin, M., Yang, Z., Gao, D., & Li, H. (2025) · Journal of Affective Disorders · doi:10.1016/j.jad.2025.03.141 · Cited by 56
Watters, C., & Lemański, M. K. (2023) · Frontiers in Big Data · doi:10.3389/fdata.2023.1224976 · Cited by 64
Mejia, M. R., Arroyave, J. S., Saturno, M. P., Ndjonko, L. C. M., Zaidat, B., Rajjoub, R., Ahmed, W., Zapolsky, I., & Cho, S. K.-W. (2024) · Neurospine · doi:10.14245/ns.2347052.526 · Cited by 54
Stroop, A., Stroop, T., Alsofy, S. Z., Nakamura, M., Möllmann, F., Greiner, C., & Stroop, R. (2023) · European Spine Journal · doi:10.1007/s00586-023-07975-z · Cited by 53
The Development and Validation of an Artificial Intelligence Chatbot Dependence Scale
Zhang, X., Yin, M., Zhang, M., Li, Z., & Li, H. (2025) · Cyberpsychology, Behavior, and Social Networking · doi:10.1089/cyber.2024.0240 · Cited by 52
Ponzo, V., Rosato, R., Scigliano, M. C., Onida, M., Cossai, S., Vecchi, M. D., Devecchi, A., Goitre, I., Favaro, E., Merlo, F. D., et al. (2024) · Journal of Clinical Medicine · doi:10.3390/jcm13247810 · Cited by 55
Chat Generative Pre-Trained Transformer (ChatGPT) usage in healthcare
Zhang, Y., Pei, H., Zhen, S., Li, Q., & Liang, F. (2023) · Gastroenterology & Endoscopy · doi:10.1016/j.gande.2023.07.002 · Cited by 57
Harnessing generative artificial intelligence to support nature‐based solutions
Richards, D. R., Worden, D., Song, X. P., & Lavorel, S. (2024) · People and Nature · doi:10.1002/pan3.10622 · Cited by 59
AI Agents in Clinical Medicine: A Systematic ReviewPreprint
Gorenshtein, A., Omar, M., Glicksberg, B. S., Nadkarni, G. N., & Klang, E. (2025) · medRxiv · doi:10.1101/2025.08.22.25334232 · Cited by 65
Li, B., Gross, O., Crampton, N., Kapoor, M., Tauseef, S., Jain, M., Truong, K. N., & Mariakakis, A. T. (2024) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3613904.3641913 · Cited by 51
Large Language Models for Simplified Interventional Radiology Reports: A Comparative Analysis
Can, E., Uller, W., Vogt, K., Doppler, M. C., Busch, F., Bayerl, N., Ellmann, S., Kader, A., Elkilany, A., Makowski, M. R., et al. (2024) · Academic Radiology · doi:10.1016/j.acra.2024.09.041 · Cited by 38
Garg, R. K., Urs, V. L., Agrawal, A. A., Chaudhary, S. K., Paliwal, V. K., & Kar, S. K. (2023) · medRxiv · doi:10.1101/2023.06.13.23291311 · Cited by 36
Bucher, A., Blazek, E. S., & Symons, C. T. (2024) · Mayo Clinic Proceedings Digital Health · doi:10.1016/j.mcpdig.2024.05.007 · Cited by 41
Yapar, D., Avcı, Y. D., Sonuvar, E. T., Eğerci, Ö. F., & Yapar, A. (2023) · Joint Diseases and Related Surgery · doi:10.52312/jdrs.2023.1402 · Cited by 30
Bužančić, I., Belec, D., Držaić, M., Kummer, I., Brkić, J., Fialová, D., & Hadžiabdić, M. O. (2023) · British Journal of Clinical Pharmacology · doi:10.1111/bcp.15963 · Cited by 28
Akilesh, S., Sheik Abdullah, A., Abinaya, R., Dhanushkodi, S. R., & Sekar, R. (2023) · International Conference on Research Methodologies in Knowledge Management, Artificial Intelligence and Telecommunication Engineering (RMKMATE) · doi:10.1109/rmkmate59243.2023.10368616 · Cited by 29
Bond, A., Cilliers, D., Retief, F., Alberts, R. C., Roos, C., & Moolman, J. (2024) · Impact Assessment and Project Appraisal · doi:10.1080/14615517.2024.2320591 · Cited by 32
Karakas, C., Brock, D. C., & Lakhotia, A. (2023) · Pediatric Neurology · doi:10.1016/j.pediatrneurol.2023.08.035 · Cited by 28
Kapsali, M. Z., Livanis, E., Tsalikidis, C., Oikonomou, P., Voultsos, P. P., & Tsaroucha, A. (2024) · Cureus · doi:10.7759/cureus.54759 · Cited by 27
Evaluating generative AI responses to real-world drug-related questions
Giorgi, S., Isman, K., Liu, T., Fried, Z., Sedoc, J., & Curtis, B. (2024) · Psychiatry Research · doi:10.1016/j.psychres.2024.116058 · Cited by 24
Racial, ethnic, and sex bias in large language model opioid recommendations for pain management
Young, C. C., Enichen, E. J., Rao, A. S., & Succi, M. D. (2024) · Pain · doi:10.1097/j.pain.0000000000003388 · Cited by 26
Natural language processing data services for healthcare providers
Yeung, J. A., Shek, A., Searle, T., Kraljević, Ž., Dinu, V., Ratas, M., Al-Agil, M., Foy, A., Rafferty, B., Oliynyk, V., et al. (2024) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-024-02713-x · Cited by 28
Self-citationChatGPT and oral cancer: a study on informational reliability
Çıtır, M. (2025) · BMC Oral Health · doi:10.1186/s12903-025-05479-4 · Cited by 25
CataractBot: An LLM-powered Expert-in-the-Loop Chatbot for Cataract Patients
Ramjee, P., Sachdeva, B., Golechha, S., Kulkarni, S., Fulari, G., Murali, K., & Jain, M. (2025) · Proceedings of the ACM on Interactive Mobile Wearable and Ubiquitous Technologies · doi:10.1145/3729479 · Cited by 28
Artificial intelligence (AI) for neurologists: do digital neurones dream of electric sheep?
Yeung, J. A., Wang, Y. Y., Kraljević, Ž., & Teo, J. (2023) · Practical Neurology · doi:10.1136/pn-2023-003757 · Cited by 23
Self-citationLarge Language Models in Orthopaedics
Yao, J. J., Aggarwal, M., Lopez, R. D., & Namdari, S. (2024) · Journal of Bone and Joint Surgery · doi:10.2106/jbjs.23.01417 · Cited by 19
Evaluation of performance of generative large language models for stroke care
Lee, J. T., Li, V. C.-S., Wu, J.-J., Chen, H.-H., Su, S. S.-Y., Chang, B. P.-H., Lai, R. L., Liu, C.-H., Chen, C.-T., Tanapima, V., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01830-9 · Cited by 20
A perspective for adapting generalist AI to specialized medical AI applications and their challenges
Wang, Z., Wang, H., Danek, B. P., Li, Y., Mack, C. D., Arbuckle, L., Biswal, D., Poon, H., Wang, Y., Rajpurkar, P., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01789-7 · Cited by 35
Jeon, S., Lee, S., Kim, E. H., Eun, J., Lee, K., Lim, H., & Lee, J. (2025) · JMIR Formative Research · doi:10.2196/72553 · Cited by 27
Mapping the individual, social and biospheric impacts of Foundation Models
Hernández, A. D., Krishna, S., Perini, A., Katell, M. A., Bennett, S., Borda, A., Hashem, Y., Hadjiloizou, S., Mahomed, S., Jayadeva, S., et al. (2024) · ACM Conference on Fairness, Accountability, and Transparency (FAccT) · doi:10.1145/3630106.3658939 · Cited by 38
Large language models and rheumatology: are we there yet?
Benavent, D., & Madrid-García, A. (2024) · Rheumatology Advances in Practice · doi:10.1093/rap/rkae119 · Cited by 17
Guidelines For Rigorous Evaluation of Clinical LLMs For Conversational ReasoningPreprint
Johri, S., Jeong, J., Tran, B. A., Schlessinger, D. I., Wongvibulsin, S., Cai, Z. R., Daneshjou, R., & Rajpurkar, P. (2023) · medRxiv · doi:10.1101/2023.09.12.23295399 · Cited by 17
Healthcare: A Growing Role for Large Language Models and Generative AI
Pahune, S. A., & Rewatkar, N. (2023) · International Journal for Research in Applied Science and Engineering Technology · doi:10.22214/ijraset.2023.55573 · Cited by 19
Ćirković, A., & Katz, T. R. (2023) · JMIR Formative Research · doi:10.2196/51798 · Cited by 16
Iyer, R., Christie, A. P., Madhavapeddy, A., Reynolds, S., Sutherland, W. J., & Jaffer, S. (2025) · PLoS ONE · doi:10.1371/journal.pone.0323563 · Cited by 16
Eğin, F., Onan, A., & Durak, H. Y. (2025) · European Journal of Education · doi:10.1111/ejed.12913 · Cited by 18
Empowering Preventive Care with GECA Chatbot
Maia, E., Vieira, P. N. D. A., & Praça, I. (2023) · Healthcare · doi:10.3390/healthcare11182532 · Cited by 19
Park, K. U., Lipsitz, S. R., Dominici, L. S., Lynce, F. C., Minami, C. A., Nakhlis, F., Waks, A. G., Warren, L. E., Eidman, N., Frazier, J., et al. (2024) · Cancer · doi:10.1002/cncr.35521 · Cited by 15
A Comparative Analysis of Three Large Language Models on Bruxism Knowledge
Camargo, E. S., Quadras, I. C. C., Garanhani, R. R., de Araújo, C. M., & Stuginski‐Barbosa, J. (2025) · Journal of Oral Rehabilitation · doi:10.1111/joor.13948 · Cited by 17
Bayram, H. M., Çelik, Z. M., & Güzeldere, H. K. B. (2025) · Nutrition and Health · doi:10.1177/02601060251329070 · Cited by 15
Dual-process theory and decision-making in large language models
Brady, O., Nulty, P., Zhang, L., Ward, T. E., & McGovern, D. P. (2025) · Nature Reviews Psychology · doi:10.1038/s44159-025-00506-1 · Cited by 19
Multilingual Framework for Risk Assessment and Symptom Tracking (MRAST)
Šafran, V., Lin, S. M., Nateqi, J., Martin, A. G., Smrke, U., Ariöz, U., Plohl, N., Rojc, M., Bēma, D., Chávez, M., et al. (2024) · Sensors · doi:10.3390/s24041101 · Cited by 14
Norris, M. L., Obeid, N., & Emam, K. E. (2024) · International Journal of Eating Disorders · doi:10.1002/eat.24215 · Cited by 14
Wyatt, K. D., Alexander, N., Hills, G. D., Liang, W. H., Kadauke, S., Volchenboum, S. L., Mian, A., & Phillips, C. (2024) · Pediatric Blood & Cancer · doi:10.1002/pbc.31143 · Cited by 13
Li, B., Tauseef, S., Truong, K. N., & Mariakakis, A. T. (2025) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3706598.3713613 · Cited by 13
Development and evaluation of a lightweight large language model chatbot for medication enquiry
Elangovan, K., Ong, J. C. L., Jin, L., Seng, J. J. B., Kwan, Y. H., Ng, L. S., Zhong, R. J., Li, J., Ke, Y. H., Liu, N., et al. (2025) · PLOS Digital Health · doi:10.1371/journal.pdig.0000961 · Cited by 18
Ehtesham, A., Singh, A., & Kumar, S. (2025) · IEEE World AI IoT Congress (AIIoT) · doi:10.1109/aiiot65859.2025.11105280 · Cited by 13
de Oliveira, R. S., & Nascimento, E. G. S. (2025) · Information Processing & Management · doi:10.1016/j.ipm.2025.104477 · Cited by 12
Sekli, G. M. (2024) · Kybernetes · doi:10.1108/k-03-2024-0554 · Cited by 13
Advancing Healthcare Accessibility: Development of an AI-Driven Multimodal Chatbot
Garimella, B. S., Garlapati, H. S., Choul, S., Cherukuri, R., & Lanke, P. (2024) · International Conference on Intelligent Technologies (CONIT) · doi:10.1109/conit61985.2024.10626795 · Cited by 11
Baskara, F. R. (2025) · Journal of Languages and Language Teaching · doi:10.33394/jollt.v13i1.9926 · Cited by 22
Enhanced large language models for effective screening of depression and anxiety
Liu, J. M., Gao, M., Sabour, S., Chen, Z., Huang, M., & Lee, T. M. C. (2025) · Communications Medicine · doi:10.1038/s43856-025-01158-1 · Cited by 25
Muthusamy, V., Rizk, Y., Kate, K., Venkateswaran, P., Isahagian, V., Gulati, A., & Dube, P. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.461 · Cited by 17
Bulck, L. V., & Moons, P. (2023) · European Journal of Cardiovascular Nursing · doi:10.1093/eurjcn/zvad049 · Cited by 11
Patil, N. S., Huang, R. S., Caterine, S., Yao, J. J., Larocque, N., van der Pol, C. B., & Stubbs, E. (2024) · Canadian Association of Radiologists Journal · doi:10.1177/08465371231220561 · Cited by 10
AI versus the spinal surgeons in the management of controversial spinal surgery scenarios
Mehmet, S., Elmarawany, M. N., Harding, I., Bowey, A. J., Andrews, J., Chan, D., Jayasuriya, R. L., Srinivas, S., Tomlinson, J. E., Bayley, E. J., et al. (2025) · European Spine Journal · doi:10.1007/s00586-025-08825-w · Cited by 10
The role of artificial intelligence in gynecologic and obstetric emergencies
Psilopatis, I., Heindl, F., Cupisti, S., Fischer, U., Kohlmann, V., Schneider, M. A., Bader, S., Krückel, A., & Emons, J. (2025) · European Journal of Obstetrics & Gynecology and Reproductive Biology · doi:10.1016/j.ejogrb.2025.01.007 · Cited by 9
General Practitioners’ Perspectives on a Pre-Consultation Chatbot for Shared Decision-Making
Samiee, M., Wester, J., Jacobsen, R., Rathleff, M. S., & van Berkel, N. (2025) · Conference on Designing Interactive Systems · doi:10.1145/3715336.3735674 · Cited by 10
Optimizing ChatGPT’s Interpretation and Reporting of Delirium Assessment Outcomes: Exploratory Study
Choi, Y. K., Lin, S., Fick, D. M., Shulman, R. W., Lee, S., Shrestha, P., & Santoso, K. P. (2024) · JMIR Formative Research · doi:10.2196/51383 · Cited by 9
Withdrawn: Large Language Models in Healthcare Decision Support: A ReviewPreprint
Vavekanand, R., Karttunen, P., Xu, Y., Milani, S., & Li, H. (2024) · Preprints.org · doi:10.20944/preprints202407.1842.v1 · Cited by 7
Artificial intelligence in academic Research: Contributor, constructivist or cheat?
Scott‐Kennel, J., 张, 蓉., & Scott, J. M. (2025) · The Journal of Marketing Theory and Practice · doi:10.1080/10696679.2025.2457672 · Cited by 12
Liu, X., Chen, Y., Guan, W., Jiang, P., Yan, L., Fan, M., & Zhou, Q. (2025) · Journal of Advanced Nursing · doi:10.1111/jan.70250 · Cited by 7
Meter, A. V., Wheaton, M. G., Cosgrove, V. E., Andreadis, K., & Robertson, R. E. (2025) · PLOS Digital Health · doi:10.1371/journal.pdig.0000711 · Cited by 7
Assessing the research landscape and clinical utility of large language models: A scoping reviewPreprint
Park, Y., Pillai, A., Deng, J., Guo, E., Gupta, M., Paget, M., & Naugler, C. T. (2023) · Research Square · doi:10.21203/rs.3.rs-3472000/v1 · Cited by 8
Evaluating the performance of ChatGPT in clinical multidisciplinary treatment: a retrospective study
Wang, X., Guo, J., Zhang, T., Lu, H., Zhou, D., Zhang, H., & Wang, X. (2025) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-025-03181-7 · Cited by 6
Medical QA dialogue datasets in RAG systems performance evaluation and ChatGPT optimization
Muhetaer, M., Yusupu, A., Yifan, W., Mutalipu, M., & Fan, H. (2025) · Scientific Reports · doi:10.1038/s41598-025-28015-4 · Cited by 6
Validation of an Artificial Intelligence-Powered Virtual Assistant for Emergency Triage in Neurology
Alessandro, L., Crema, S., Castiglione, J. I., Dossi, D., Eberbach, F., Köhler, A., Laffue, A., Marone, A., Nagel, V., Rueda, J. M. P., et al. (2025) · The Neurologist · doi:10.1097/nrl.0000000000000594 · Cited by 6
López-Ojeda, W., & Hurley, R. A. (2023) · Journal of Neuropsychiatry · doi:10.1176/appi.neuropsych.20230117 · Cited by 7
Using chatgpt to enhance student learning: a case study in a nursing curriculum
Elliott, M., Williams, J., Aldwikat, R. K., & Wong, P. (2024) · Teaching and learning in nursing · doi:10.1016/j.teln.2024.09.009 · Cited by 5
Liu, W., Wei, H., Xiang, L., Liu, Y., Wang, C., & Hua, Z. (2025) · Pediatric Pulmonology · doi:10.1002/ppul.71020 · Cited by 5
Large Language Model-assisted EIA screening: a case study using GPT
Cilliers, D., Bond, A., Retief, F., Alberts, R. C., & Roos, C. (2025) · Impact Assessment and Project Appraisal · doi:10.1080/14615517.2025.2523628 · Cited by 7
Evaluating chatbots in psychiatry: Rasch-based insights into clinical knowledge and reasoning
Chang, Y., Huang, S., Hsu, W., & Liu, Y. (2025) · PLoS ONE · doi:10.1371/journal.pone.0330303 · Cited by 5
Leveraging Virtual Reality to Enhance Diversity, Equity and Inclusion training at Google
Bursztein, E., Brown, K., Sanderson, L., & Kelley, P. G. (2024) · CHI Conference Extended Abstracts on Human Factors in Computing Systems (CHI EA) · doi:10.1145/3613905.3637128 · Cited by 5
Metadata
- Authors
- Au Yeung, J., Kraljevic, Z., Luintel, A., Balston, A., Idowu, E., Dobson, R. J., & Teo, J. T.
- Affiliations
- King's College Hospital (GB)
- St Thomas' Hospital (GB)
- King's College London (GB)
- Venue
- Frontiers in Digital Health
- Publisher
- Frontiers Media SA
- Published
- 2023-04-12
- Volume
- 5
- Pages
- 1161098-1161098
- ISSN
- 2673-253X (ISSN-L)
- PMC
- PMC10130576
- OpenAlex
- W4365148488
- Cited by
- 176
- References
- 23
- Citations by year
- 2026: 21 · 2025: 61 · 2024: 59 · 2023: 34
- FWCI
- 6.97
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Frontiers in Digital Health (publishedVersion, cc-by)
- medRxiv (acceptedVersion, cc-by-nd)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Research Portal (King's College London) (publishedVersion, other-oa)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Funders
- National Institute for Health and Care Research (ACF-2021-17-002)
- King's College London
- Medical Research Council (HDR-23004, MC_PC_17214)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Keywords
- large language models, chatbots, clinical decision support, ChatGPT, foresight, generative pre-trained transformer, clinical vignettes, medical question answering
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
