

The DOI matches its Crossref record; 37 of the 39 references it cites were found in a registry or an index; 2 of the 14 sources its claims cite were checked for support.
ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations
Open accessAbstract
This study aimed to assess the knowledge, attitudes, and intended practices of healthcare workers (HCWs) in Saudi Arabia towards ChatGPT, an artificial intelligence (AI) Chatbot, within the first three months after its launch. We also aimed to identify potential barriers to AI Chatbot adoption among healthcare professionals. A cross-sectional survey was conducted among 1057 HCWs in Saudi Arabia, distributed electronically via social media channels from 21 February to 6 March 2023. The survey evaluated HCWs’ familiarity with ChatGPT-3.5, their satisfaction, intended future use, and perceived usefulness in healthcare practice. Of the respondents, 18.4% had used ChatGPT for healthcare purposes, while 84.1% of non-users expressed interest in utilizing AI Chatbots in the future. Most participants (75.1%) were comfortable with incorporating ChatGPT into their healthcare practice. HCWs perceived the Chatbot to be useful in various aspects of healthcare, such as medical decision-making (39.5%), patient and family support (44.7%), medical literature appraisal (48.5%), and medical research assistance (65.9%). A majority (76.7%) believed ChatGPT could positively impact the future of healthcare systems. Nevertheless, concerns about credibility and the source of information provided by AI Chatbots (46.9%) were identified as the main barriers. Although HCWs recognize ChatGPT as a valuable addition to digital health in the early stages of adoption, addressing concerns regarding accuracy, reliability, and medicolegal implications is crucial. Therefore, due to their unreliability, the current forms of ChatGPT and other Chatbots should not be used for diagnostic or treatment purposes without human expert oversight. Ensuring the trustworthiness and dependability of AI Chatbots is essential for successful implementation in healthcare settings. Future research should focus on evaluating the clinical outcomes of ChatGPT and benchmarking its performance against other AI Chatbots.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
This cross-sectional survey of 1057 healthcare workers in Saudi Arabia assessed early perceptions of ChatGPT within three months of its launch. Most saw potential value in healthcare but reported concerns about credibility, accuracy, and medicolegal implications.
Key findings
- Among respondents, 18.4% had used ChatGPT for healthcare purposes, while 84.1% of non-users expressed interest in using AI Chatbots in the future; 75.1% were comfortable incorporating ChatGPT into healthcare practice.
- Perceived usefulness included medical decision-making (39.5%), patient and family support (44.7%), medical literature appraisal (48.5%), and medical research assistance (65.9%); 76.7% believed ChatGPT could positively impact the future of healthcare systems.
- The main barrier was concern about lack of credibility and unclear sources of information feeding AI Chatbots (46.9%), followed by harmful or incorrect medical decision recommendations (40.2%), difficulty accessing AI models at work (38.1%), and medicolegal implications (30.8%).
- In adjusted analyses, belief that ChatGPT could improve patient outcomes was associated with higher odds of believing it could improve the future healthcare system (OR = 7.92, p < 0.001), as were comfort using ChatGPT for medical purposes (OR = 2.327, p < 0.001), prior healthcare use (OR = 1.902, p = 0.004), and familiarity (OR = 2.023, p < 0.001).
Methods
- Cross-sectional electronic survey distributed via social media channels, email invitations, and personal contacts among healthcare workers in Saudi Arabia from 21 February to 6 March 2023; 1057 HCWs participated.
- The survey was developed by a multidisciplinary team, refined using focus groups, and piloted among 20 HCWs; it had three parts covering knowledge/use, perceived obstacles, and demographics/computer literacy, with multiple-choice questions and no Likert scale or open-ended questions.
- Analysis used descriptive statistics, multiple response dichotomies for multiple-option questions, and multivariate-adjusted odds ratios with 95% confidence intervals; significance was set at p < 0.05 using SPSS version 21.
Limitations
- The paper states that as a cross-sectional survey, the study is subject to sampling bias, response bias, and recall bias; the sampling technique may lead to selection bias, and participants may not represent the entire healthcare worker population.
- The paper states that response bias may occur from socially desirable answers, misunderstanding questions, or unmeasured confounding; almost half reported unfamiliarity with ChatGPT, which could introduce bias.
- The paper states that regional information was not collected due to privacy concerns, the absence of total population size limits generalizability, the study included respondents from one country, and no qualitative techniques were included.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
52 Own result · 12 Own method · 10 Not checked yet · 5 Own interpretation · 3 No basis given · 1 Partly supported · accuracy not yet measured
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Of the respondents, 18.4% had used ChatGPT for healthcare purposes, while 84.1% of non-users expressed interest in utilizing AI Chatbots in the future.”
- Also stated in: § 3. Results · plain
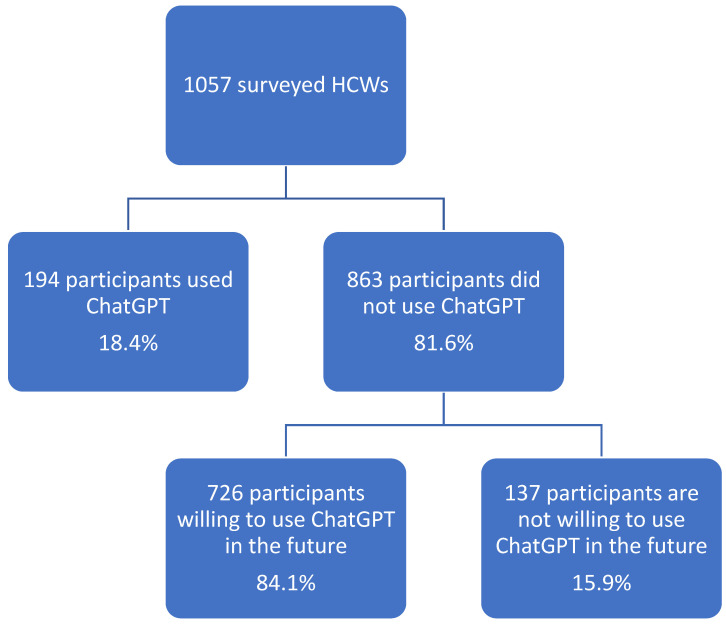
“Among the surveyed HCWs, only 18.4% reported using ChatGPT for healthcare purposes as of the time of the survey, while 81.6% did not (Figure 1).”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 3. Results · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Interestingly, HCWs who were concerned about AI Chatbots potentially taking over human roles in healthcare practice were significantly more inclined to use them for healthcare purposes in the future (OR = 1.969, p = 0.018).”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 3. Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“A majority (76.7%) believed ChatGPT could positively impact the future of healthcare systems.”
- Also stated in: § 3. Results · plain
“Most HCWs (76.7%) anticipate a positive effect; 17.7% anticipate a negative impact, and 5.6% anticipate no impact at all.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 3. Results · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As a result of our survey, 81.8% of participants expressed a triggered interest in learning more about ChatGPT and other AI Chatbots.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 3. Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, no correlation between HCWs’ trust in AI Chatbots or more specifically ChatGPT and the potential for ChatGPT to improve healthcare systems was found.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 3. Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As far as familiarity with ChatGPT is concerned, 50.9% were unfamiliar with ChatGPT; 15.1% were very familiar, and 34% reported being familiar to some degree.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 3. Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Of the respondents, 18.4% had used ChatGPT for healthcare purposes, while 84.1% of non-users expressed interest in utilizing AI Chatbots in the future.”
- Also stated in: § 3. Results · plain
“Of those who did not use it, 84.1% expressed the expectation of using it in the future (Figure 1).”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 3. Results · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Over a third of HCWs (38.1%) expressed difficulty accessing AI models in their work setting, and 37.6% had concerns about AI models not being fully developed for medical practice use.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 3. Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Most HCWs were concerned about the lack of credibility and unclear sources of information feeding AI Chatbots (46.9%), followed by concerns over harmful or incorrect medical decision recommendations made by AI models (40.2%).”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 3. Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“HCWs perceived the Chatbot to be useful in various aspects of healthcare, such as medical decision-making (39.5%), patient and family support (44.7%), medical literature appraisal (48.5%), and medical research assistance (65.9%).”
- Also stated in: § 3. Results · plain
“Participants’ perceived usefulness of ChatGPT in healthcare practice were captured using the question with multiple choices and included providing medical decisions (39.5%), supporting patients and families (44.7%), appraising medical literature (48.5%), and aiding in medical research (65.9%) (Table 2).”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § 3. Results · plain
- It may state two separate claims as one. 11
- Probably not a substantial claim. 14
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“ChatGPT was frequently utilized to quickly generate educational materials and provide healthcare advice to patients and communities [22,23,24].”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.2. Perceived Usefulness of ChatGPT
What the sources say
- Partly supportedcites [22] Alhasan, K., Al-Tawfiq, J., Aljamaan, F., Jamad, A., Al-Eyadhy, A., and Temsah, M.-H. (2023). Mitigating the Burden of Severe Pediatric Respiratory Viruses in the Post-COVID-19 Era: ChatGPT Insights and Recommendations. Cureus. sourceExperimental — accuracy not yet measured
The Editorial describes using ChatGPT to generate medical advice and guidelines for healthcare providers, and its example includes a suggestion that providers educate families. It does not report frequent use, the generation of educational materials, or ChatGPT providing advice directly to patients and communities. (LLM, conf=0.88)
- Partly supportedcites [23] Temsah, 2023, Reflection with ChatGPT about the excess death after the COVID-19 pandemic, New Microbes New Infect. sourceExperimental — accuracy not yet measured
In the letter text (indexed under Abbreviations; page unavailable), the authors describe asking ChatGPT three questions for rapid healthcare insights, and its responses include suggestions on vaccination and healthy behaviors. The paper does not describe frequent use, generation of educational materials, or advice delivered to patients and communities. (LLM, conf=0.82)
- Not checked yetcites [24] Alhasan, K., Raina, R., Jamal, A., and Temsah, M.H. (2023). Combining human and AI could predict nephrologies future, but should be handled with care. Acta Paediatr. source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Partly supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our study identified several obstacles and concerns about ChatGPT’s use in healthcare, including its lack of credibility and questioned source of information, medicolegal implications, resistance to its use, and concerns about patient confidentiality and personalized care.”
- Also stated in: § 4.5. Medicolegal Implications of ChatGPT · plain
“Notably, HCWs expressed concerns regarding the credibility of AI Chatbots and their potential medicolegal implications.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.4. Obstacles and Concerns about ChatGPT
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The survey responses accurately reflect the participants' true perceptions and experiences.
- Also stated in: § 4.5. Medicolegal Implications of ChatGPT · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The current study revealed that HCWs showed moderate to low levels of trust in ChatGPT’s ability to generate medical decisions, and only a small proportion showed a high level of trust.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.3. Trust and Credibility of ChatGPT
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The survey responses accurately reflect the participants' true perceptions and experiences.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“HCWs users of ChatGPT and those with more clinical experience, self-rated familiarity, and comfort level in using ChatGPT for medical purposes a positive perception of its usefulness and with higher levels of trust.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.3. Trust and Credibility of ChatGPT
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The survey responses accurately reflect the participants' true perceptions and experiences.
In the paper
“The recent Artificial Intelligence Index Report 2023 from Stamford University about the world countries’ acceptability ranked Saudi Arabia as one of the top three countries with a positive perception of AI products and services [10].”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 1. Introduction
What the sources say
- Not checked yetcites [10] HAI (2023, June 12). Artificial Intelligence Index Report 2023, Available online: https://aiindex.stanford.edu/wp-content/uploads/2023/04/HAI_AI-Index-Report_2023.pdf.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“According to the Artificial Intelligence Index Report 2023 by Stanford University, 76% of Saudi respondents agreed that products and services using AI have more benefits than drawbacks, making it the second most positive country towards AI after China [10].”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.2. Perceived Usefulness of ChatGPT
What the sources say
- Not checked yetcites [10] HAI (2023, June 12). Artificial Intelligence Index Report 2023, Available online: https://aiindex.stanford.edu/wp-content/uploads/2023/04/HAI_AI-Index-Report_2023.pdf.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Estimating a proportion of 50% of HCWs using ChatGPT and a margin of error of 0.05, confidence level of 95%, and study power of 80%, the sample size required for this study was 386. To account for incomplete and non-responses, the sample size was increased by 20%, making the minimum sample size required 463 HCWs.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 2. Methods > 2.3. Sample Size
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The Institutional Review Board (IRB) at King Saud University approved the study (Approval # 23/0155/IRB). Informed consent was obtained from all participants.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 2. Methods > 2.4. Ethical Considerations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“As a result of their feedback, it was further refined to eliminate any ambiguities, ultimately resulting in a well-structured, valid, and reliable instrument for assessing HCWs’ perceptions of ChatGPT (Supplementary Materials).”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 2. Methods > 2.1. Study Design
boosteddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“These findings are consistent with previous studies that have reported concerns about the accuracy and reliability of AI Chatbots in healthcare and were labeled as “Artificial Hallucinations” [26,27].”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.3. Trust and Credibility of ChatGPT
What the sources say
- Not checked yetcites [26] Howard, 2023, ChatGPT and antimicrobial advice: The end of the consulting infection doctor?, Lancet Infect. Dis. source
- Not checked yetcites [27] Alkaissi, 2023, Artificial Hallucinations in ChatGPT: Implications in Scientific Writing, Cureus
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“The checklist emphasizes the need for algorithms and data to be auditable and accessible and for redressal processes to be fair and equally accessible [31].”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.5. Medicolegal Implications of ChatGPT
What the sources say
- Not checked yetcites [31] Parikh, 2023, Judge Juan Manuel Padilla Garcia, ChatGPT, and a controversial medicolegal milestone, Indian J. Med. Sci. source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
In the paper
“The European Commission has outlined a checklist for trustworthy AI, which includes requirements for human oversight, robustness and safety, data privacy, process transparency, equitability, societal well-being, and accountability [32].”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.5. Medicolegal Implications of ChatGPT
What the sources say
- Not checked yetcites [32] Commission, E. (2023, March 26). Ethics Guidelines for Trustworthy AI. Available online: https://digital-strategy.ec.europa.eu/en/library/ethics-guidelines-trustworthy-ai.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“One study showed that physicians had a deeper level of specific training in ethics than nurses [30].”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.5. Medicolegal Implications of ChatGPT
What the sources say
- Not checked yetcites [30] Leuter, 2018, Ethical difficulties in healthcare: A comparison between physicians and nurses, Nurs. Ethics source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“To the best of our knowledge, this is the first study that explored early HCWs’ usage of ChatGPT.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.7. Comparison with Prior Work
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
In the paper
“Prior to the ChatGPT era, several papers described adaptations of AI Chatbots by specific medical disciplines, with promising initial results [35].”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.5. Medicolegal Implications of ChatGPT
What the sources say
- Not checked yetcites [35] Noble, 2022, Developing, Implementing, and Evaluating an Artificial Intelligence-Guided Mental Health Resource Navigation Chatbot for Health Care Workers and Their Families During and Following the COVID-19 Pandemic: Protocol for a Cross-sectional Study, JMIR Res. Protoc. source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Additionally, the anonymity of the survey responses will ensure that participants feel comfortable providing honest and accurate responses.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.6. Limitations
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
In the paper
“A recent study found that transparency, accountability, and user-centered design are key factors that can improve the acceptance of AI Chatbots among healthcare professionals [34].”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.5. Medicolegal Implications of ChatGPT
What the sources say
- Not checked yetcites [34] Borji, A. (2023). A categorical archive of chatgpt failures. arXiv. source
plainconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“As a cross-sectional survey study, this research is subject to some limitations, including sampling bias, response bias, and recall bias.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.6. Limitations
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Response bias may occur if participants provide answers that are socially desirable, if they misunderstand the questions, or if there were other unmeasured confounding factors that could have influenced the results.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.6. Limitations
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“While ChatGPT is seen as a potentially beneficial tool in healthcare settings, concerns about its accuracy, reliability, and medicolegal implications persist.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 5. Conclusions
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The survey responses accurately reflect the participants' true perceptions and experiences.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Additionally, the study has a relatively large sample size of HCWs from different regions in Saudi Arabia.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 4. Discussion > 4.7. Comparison with Prior Work
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper relies on this without support.
At the time of the study, there was no available data to assess healthcare workers' experience with ChatGPT.
“With ChatGPT’s recent emergence, there is no available data to assess healthcare workers’ (HCWs) experience, which is crucial information, given the potential consequences to healthcare.”
The paper relies on this without support.
Current forms of ChatGPT and other Chatbots are unreliable.
“Therefore, due to their unreliability, the current forms of ChatGPT and other Chatbots should not be used for diagnostic or treatment purposes without human expert oversight.”
The paper relies on this without support.
The social media recruitment sample is representative of healthcare workers in Saudi Arabia.
“This recruitment method was chosen to ensure broad geographic coverage and to include a diverse group of HCWs, considering the widespread use of these social media platforms among HCWs in Saudi Arabia [14].”
The paper relies on this without support.
The survey responses accurately reflect the participants' true perceptions and experiences.
“Additionally, the anonymity of the survey responses will ensure that participants feel comfortable providing honest and accurate responses.”
The paper relies on this without support.
ChatGPT was launched only three months prior to the study.
“ChatGPT was launched only three months prior to our study”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Facilitators of trust included the endorsement of the technology by experts as well as academically backed clinicians, including regulating bodies such as the government; evidence of output accuracy based on the evaluation of AI; and positive opinions from trusted thought leaders in the respective clinical fields [42,58,60].”
From Barriers to and facilitators of artificial intelligence adoption in health care: scoping review (2024) · cites this paper as [60]
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“A lack of regulation and policies from the government, including uncertainty around legal direction or law, was presented as a barrier to the application of AI technologies [37,45,57,60,77,78].”
From Barriers to and facilitators of artificial intelligence adoption in health care: scoping review (2024) · cites this paper as [60]
Experimental — accuracy not yet measuredIn the citing paper
“In the realm of pharmaceutical research, ChatGPT can contribute by sifting through vast volumes of scientific literature, identifying potential drug candidates, and suggesting innovative research directions.”
In the citing paper
“It can assist in drug discovery, research proposal writing, and summarising complex medical research, expediting the research process [11,24,34,35,36,37,38].”
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > Abstract
“within the first three months after its launch. We also aimed to identify potential barriers to AI Chatbot adoption among healthcare professionals. A cross-sectional survey was conducted among 1057 HCWs in Saudi Arabia, distributed electronically via social media channels from 21 February to 6 March 2023.”
§ ChatGPT and the Future of Digital Health: A Study on Healthcare Workers’ Perceptions and Expectations > 1. Introduction
“OpenAI launched Chat Generative Pre-trained Transformer version 3.5 (ChatGPT-3.5) on 30 November 2022, as an advanced AI Chatbot.”
Citations
Cites
Kung, T. H., Cheatham, M., Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., Maningo, J., et al. (2023) · PLOS Digital Health · doi:10.1371/journal.pdig.0000198 · Cited by 4,115
ChatGPT: five priorities for research
van Dis, E. A. M., Bollen, J., Zuidema, W., van Rooij, R., & Bockting, C. L. (2023) · Nature · doi:10.1038/d41586-023-00288-7 · Cited by 1,842
Benefits, Limits, and Risks of GPT-4 as an AI Chatbot for Medicine
Lee, P., Bubeck, S., & Petro, J. (2023) · New England Journal of Medicine · doi:10.1056/nejmsr2214184 · Cited by 1,738
Artificial hallucinations in ChatGPT: implications in scientific writing
Alkaissi, H., & McFarlane, S. I. (2023) · Cureus · doi:10.7759/cureus.35179 · Cited by 1,540
Conversational agents in healthcare: a systematic review
Laranjo, L., Dunn, A. G., Tong, H. L., Kocaballi, A. B., Chen, J., Bashir, R., Surian, D., Gallego, B., Magrabi, F., Lau, A. Y. S., et al. (2018) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocy072 · Cited by 1,388 · cited 1×
“Introduction Artificial Intelligence (AI) is the ability of digital computers or computer-controlled robots to perform tasks typically associated with intelligent beings [1,2].”
BackgroundDave, T., Athaluri, S. A., & Singh, S. (2023) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2023.1169595 · Cited by 1,204
Cascella, M., Montomoli, J., Bellini, V., & Bignami, E. (2023) · Journal of Medical Systems · doi:10.1007/s10916-023-01925-4 · Cited by 1,120
The benefits and challenges of chatgpt: An overview
Deng, J., & Lin, Y. (2023) · Frontiers in Computing and Intelligent Systems · doi:10.54097/fcis.v2i2.4465 · Cited by 611
Ferdous, M. Z., Islam, M. S., Sikder, M. T., Mosaddek, A. S. M., Zegarra-Valdivia, J. A., & Gozal, D. (2020) · PLoS ONE · doi:10.1371/journal.pone.0239254 · Cited by 590
A Categorical Archive of ChatGPT Failures
Borji, A. (2023) · doi:10.21203/rs.3.rs-2895792/v1 · Cited by 514
Cited by
Sorted by citations
Barriers to and facilitators of artificial intelligence adoption in health care: scoping review
Hassan, M., Kushniruk, A., & Borycki, E. (2024) · JMIR Human Factors · doi:10.2196/48633 · Cited by 435
Younis, H. A., Eisa, T. A. E., Nasser, M., Sahib, T. M., Noor, A. A., Alyasiri, O. M., Salisu, S., Hayder, I. M., & Younis, H. A. (2024) · Diagnostics · doi:10.3390/diagnostics14010109 · Cited by 242
Alkhaaldi, S. M. I., Kassab, C. H., Dimassi, Z., Oyoun Alsoud, L., Al Fahim, M., Al Hageh, C., & Ibrahim, H. (2023) · JMIR Medical Education · doi:10.2196/51302 · Cited by 132
Gupta, V. (2024) · Systems · doi:10.3390/systems12030103 · Cited by 120
Suicide Risk Assessments Through the Eyes of ChatGPT-3.5 Versus ChatGPT-4: Vignette Study
Levkovich, I., & Elyoseph, Z. (2023) · JMIR Mental Health · doi:10.2196/51232 · Cited by 119
Metadata
- Authors
- Temsah, M.-H., Aljamaan, F., Malki, K. H., Alhasan, K., Altamimi, I., Aljarbou, R., Bazuhair, F., Alsubaihin, A., Abdulmajeed, N., Alshahrani, F. S., Temsah, R., Alshahrani, T., Al-Eyadhy, L., Alkhateeb, S. M., Saddik, B., Halwani, R., Jamal, A., Al-Tawfiq, J. A., & Al-Eyadhy, A.
- Affiliations
- King Saud Medical City (SA)
- King Saud University (SA)
- King Faisal Specialist Hospital & Research Centre (SA)
- Pediatric Department, King Saud University Medical City, King Saud University, Riyadh 11411, Saudi Arabia
- Riyadh Armed Forces Hospital (SA)
- Alfaisal University (SA)
- Jordan University of Science and Technology (JO)
- University of Sharjah (AE)
- Specialty Internal Medicine and Quality Department, Johns Hopkins Aramco Healthcare, Dhahran 34465, Saudi Arabia
- Corresponding author
- Temsah, Mohamad-Hani
- ORCID
- Venue
- Healthcare
- Publisher
- MDPI AG
- Published
- 2023-06-21
- Volume
- 11
- Issue
- 13
- Pages
- 1812
- ISSN
- 2227-9032 (ISSN-L)
- PMC
- PMC10340744
- OpenAlex
- W4381550225
- Cited by
- 179
- References
- 39
- Citations by year
- 2026: 30 · 2025: 59 · 2024: 65 · 2023: 25
- FWCI
- 7.13
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- Healthcare (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- IUScholarWorks (Indiana University) (submittedVersion, cc-by)
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Artificial Intelligence Applications
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Keywords
- ChatGPT, AI chatbots, healthcare workers, digital health, AI adoption barriers, perceived usefulness, clinical decision-making, AI credibility, medicolegal issues, Saudi Arabia
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
