

The DOI matches its DataCite record; 85 of the 91 references it cites were found in a registry or an index.
Explaining Neural Scaling Laws
Open accessAbstract
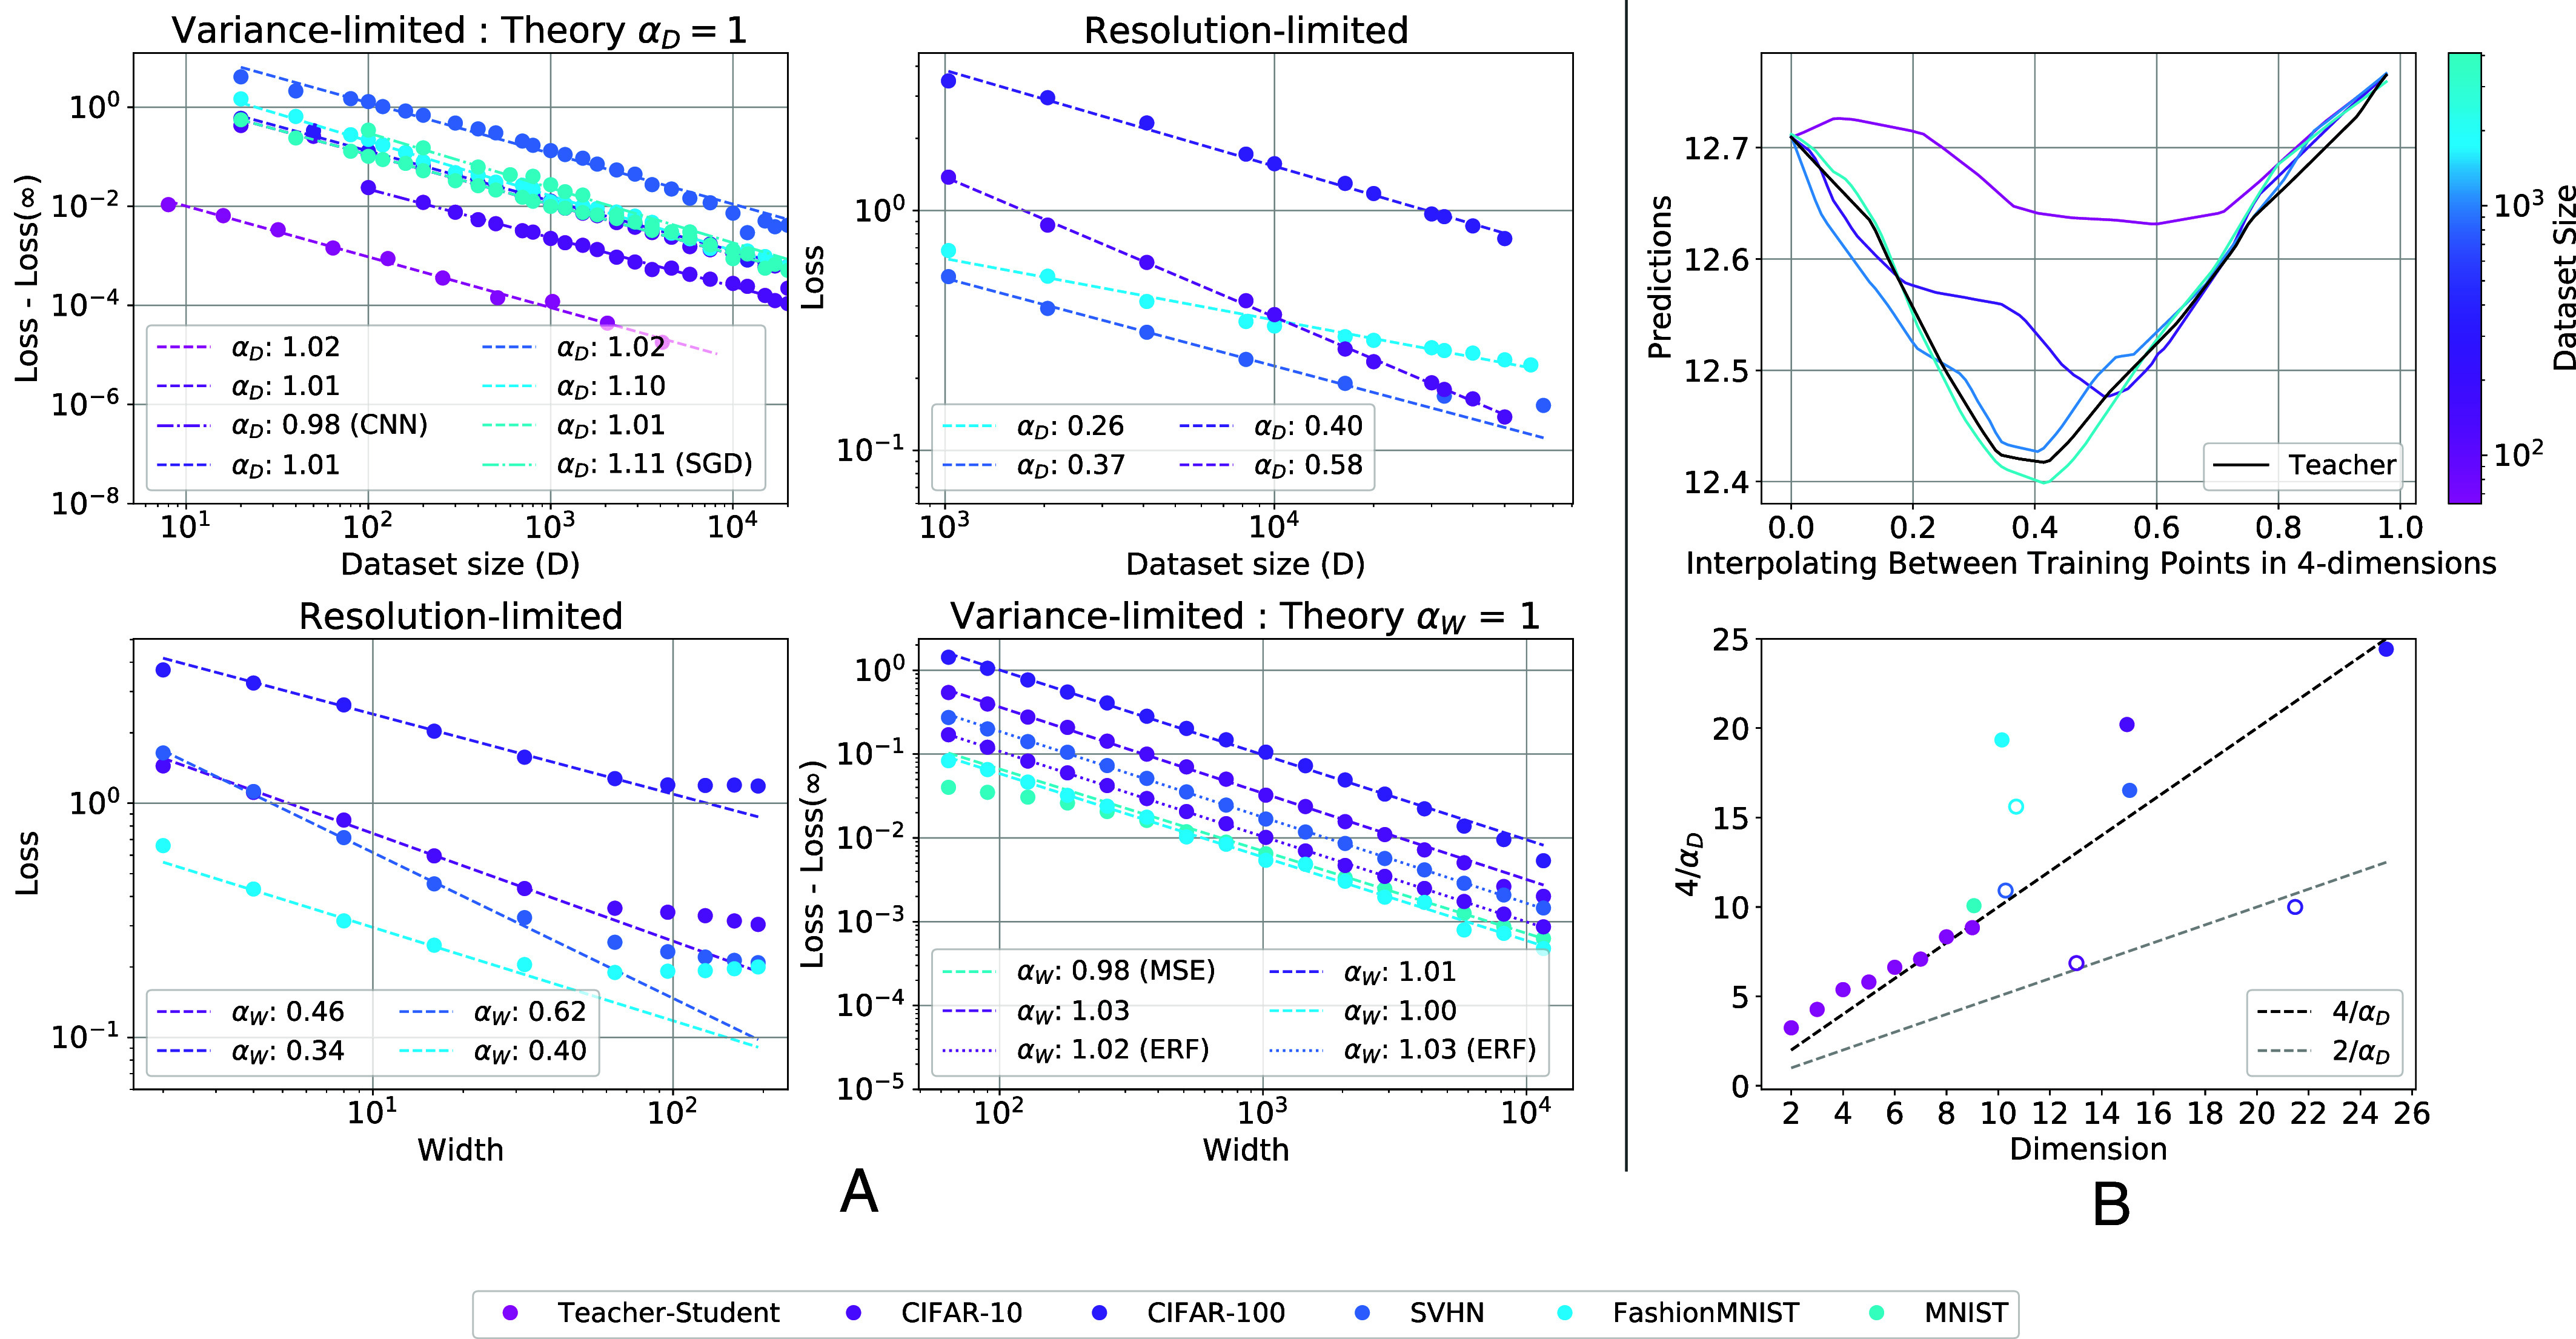
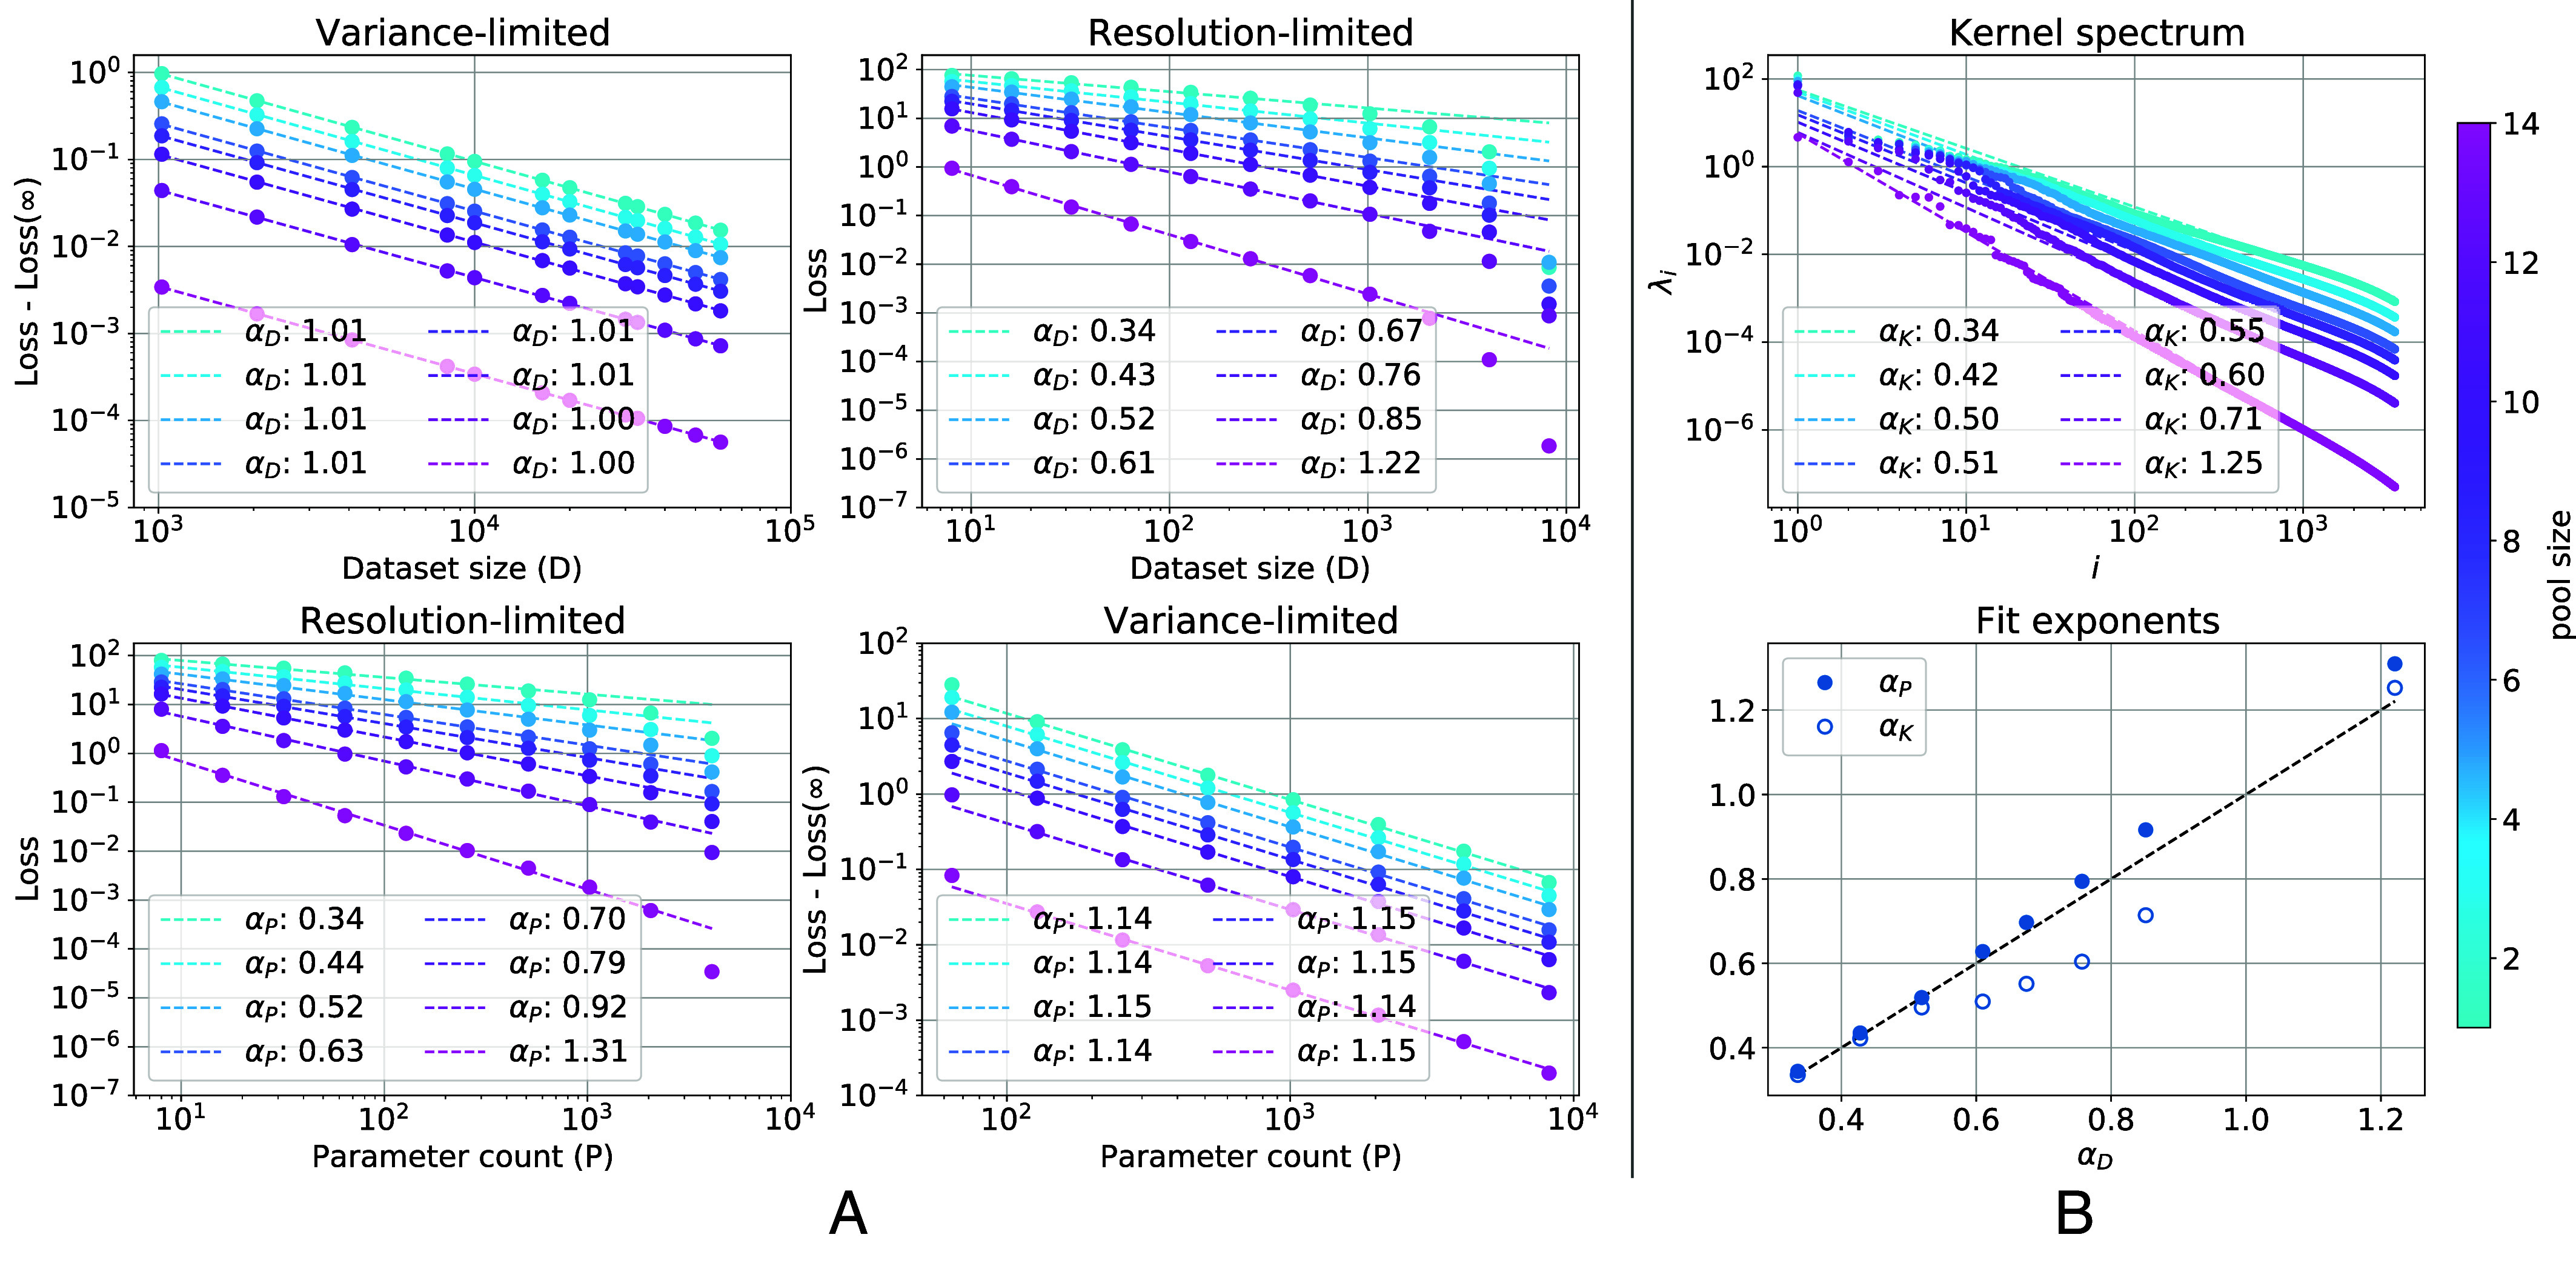
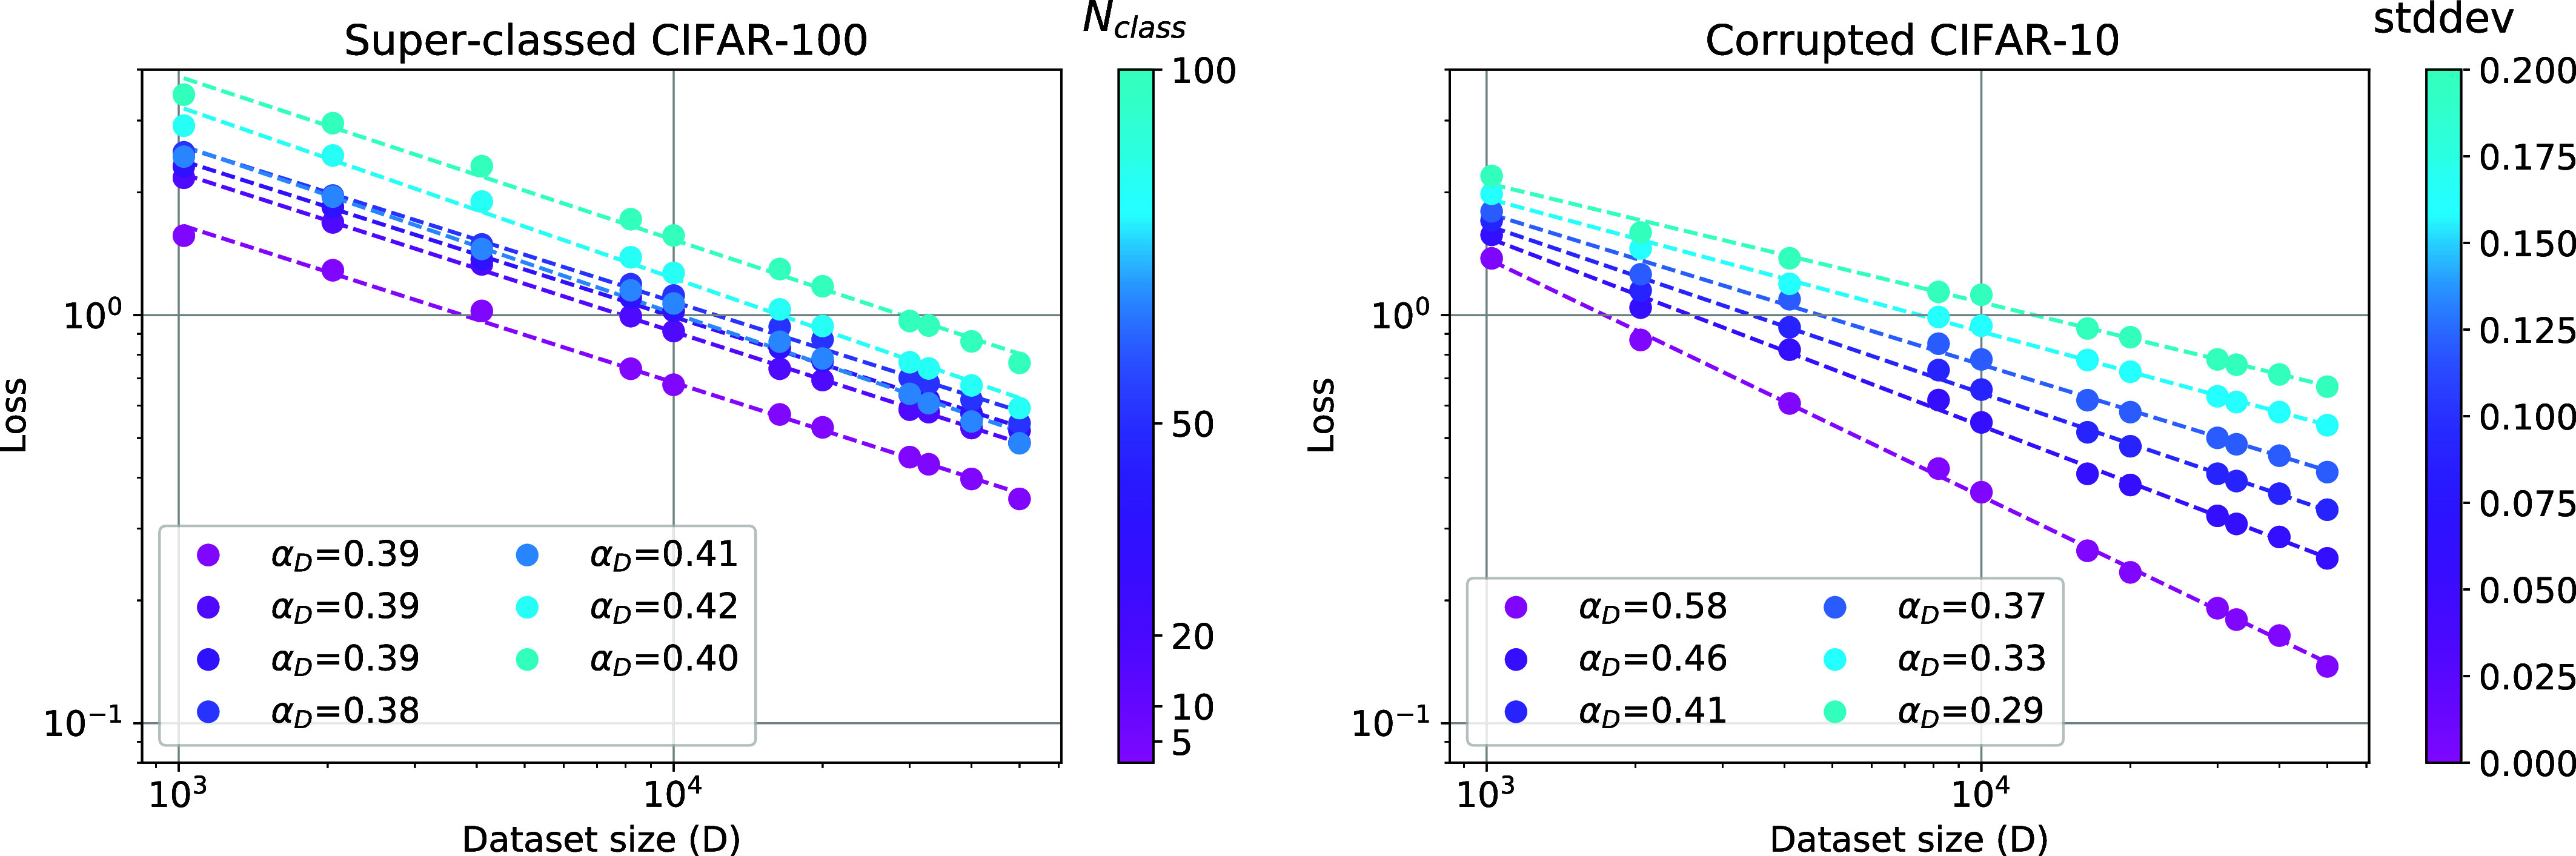
The population loss of trained deep neural networks often follows precise power-law scaling relations with either the size of the training dataset or the number of parameters in the network. We propose a theory that explains the origins of and connects these scaling laws. We identify variance-limited and resolution-limited scaling behavior for both dataset and model size, for a total of four scaling regimes. The variance-limited scaling follows simply from the existence of a well-behaved infinite data or infinite width limit, while the resolution-limited regime can be explained by positing that models are effectively resolving a smooth data manifold. In the large width limit, this can be equivalently obtained from the spectrum of certain kernels, and we present evidence that large width and large dataset resolution-limited scaling exponents are related by a duality. We exhibit all four scaling regimes in the controlled setting of large random feature and pretrained models and test the predictions empirically on a range of standard architectures and datasets. We also observe several empirical relationships between datasets and scaling exponents under modifications of task and architecture aspect ratio. Our work provides a taxonomy for classifying different scaling regimes, underscores that there can be different mechanisms driving improvements in loss, and lends insight into the microscopic origins of and relationships between scaling exponents.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Return follows a powerlaw: loss scales as a power-law with the amount of compute used for training (Henighan et al., 2020;Kaplan et al., 2020;Bahri et al., 2021;Ghorbani et al., 2021;Bansal et al., 2022;Hernandez et al., 2021).”
From Scaling Data-Constrained Language Models (2023) · cites this paper as Bahri et al., 2021
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
PyTorch: An Imperative Style, High-Performance Deep Learning Library
Paszke, A., Gross, S., Massa, F., Lerer, A., Bradbury, J., Chanan, G., Killeen, T., Lin, Z., Gimelshein, N., Antiga, L., et al. (2019) · arXiv · doi:10.48550/arxiv.1912.01703 · Cited by 31,473
The Elements of Statistical Learning
Hastie, T., Tibshirani, R., & Friedman, J. (2009) · Springer Series in Statistics · doi:10.1007/978-0-387-84858-7 · Cited by 25,970
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks
Tan, M., & Le, Q. V. (2019) · arXiv · doi:10.48550/arxiv.1905.11946 · Cited by 17,072
McCullagh, P., & Nelder, J. A. (1989) · doi:10.1007/978-1-4899-3242-6 · Cited by 16,836
Scaling Laws for Neural Language Models
Kaplan, J., McCandlish, S., Henighan, T., Brown, T. B., Chess, B., Child, R., Gray, S., Radford, A., Wu, J., & Amodei, D. (2020) · arXiv · doi:10.48550/arxiv.2001.08361 · Cited by 9,550
Zagoruyko, S., & Komodakis, N. (2016) · Procedings of the British Machine Vision Conference 2016 · doi:10.5244/c.30.87 · Cited by 7,244
SGDR: Stochastic Gradient Descent with Warm Restarts
Loshchilov, I., & Hutter, F. (2016) · arXiv · doi:10.48550/arxiv.1608.03983 · Cited by 5,309
Bayesian Learning for Neural Networks
Neal, R. M. (1996) · Lecture Notes in Statistics · doi:10.1007/978-1-4612-0745-0 · Cited by 4,276
Stein, M. L. (1999) · Springer series in statistics · doi:10.1007/978-1-4612-1494-6 · Cited by 2,358
Research works printed but not linked: 4
- [9]J. Hoffmann, An empirical analysis of compute-optimal large language model training. Adv. Neural Inf. Process. Syst. 35, 30016– 30030 (2022).
- [14]A. Matthews, J. Hron, M. Rowland, R. E. Turner, Z. Ghahramani, “Gaussian process behaviour in wide deep neural networks” in International Conference on Learning Representations (2018).
- [30]M. S. Advani, A. M. Saxe, High-dimensional dynamics of generalization error in neural networks. arXiv [Preprint] (2017). 10.48550/arXiv.1710.03667 (Accessed 1 January 2021). PMC7685244 33022471 · DOI
- [44]D. de Laat, “Approximating manifolds by meshes: Asymptotic bounds in higher codimension” Thesis, University of Groningen, Groningen, The Netherlands (2011).
Cited by
Sorted by citations
Beyond the Imitation Game: Quantifying and extrapolating the capabilities of language models
Srivastava, A., Rastogi, A., Rao, A., Shoeb, A. A. M., Abid, A., Fisch, A., Brown, A. R., Santoro, A., Gupta, A., Garriga-Alonso, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2206.04615 · Cited by 569
Self-citationHow critical is brain criticality?
O’Byrne, J., & Jerbi, K. (2022) · Trends in Neurosciences · doi:10.1016/j.tins.2022.08.007 · Cited by 283
He, J., Treude, C., & Lo, D. (2025) · ACM Transactions on Software Engineering and Methodology · doi:10.1145/3712003 · Cited by 246
A Theory for Emergence of Complex Skills in Language Models
Arora, S., & Goyal, A. (2023) · arXiv · doi:10.48550/arxiv.2307.15936 · Cited by 129
Dataset Distillation with Infinitely Wide Convolutional NetworksPreprint
Nguyen, T., Novak, R., Xiao, L., & Lee, J. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2107.13034 · Cited by 100
Self-citationMachine learning and Bayesian inference in nuclear fusion research: an overview
Pavone, A., Merlo, A., Kwak, S., & Svensson, J. (2023) · Plasma Physics and Controlled Fusion · doi:10.1088/1361-6587/acc60f · Cited by 72
Economic impacts of AI-augmented R&D
Besiroglu, T., Emery-Xu, N., & Thompson, N. (2024) · Research Policy · doi:10.1016/j.respol.2024.105037 · Cited by 82
Scale Efficiently: Insights from Pre-training and Fine-tuning Transformers
Tay, Y., Dehghani, M., Rao, J., Fedus, W., Abnar, S., Chung, H. W., Narang, S., Yogatama, D., Vaswani, A., & Metzler, D. (2021) · arXiv · doi:10.48550/arxiv.2109.10686 · Cited by 63
The Quantization Model of Neural Scaling
Michaud, E. J., Liu, Z., Girit, U., & Tegmark, M. (2023) · arXiv · doi:10.48550/arxiv.2303.13506 · Cited by 57
Scaling Data-Constrained Language Models
Muennighoff, N., Rush, A., Barak, B., Scao, T. L., Tazi, N., Piktus, A., Pyysalo, S., Wolf, T., & Raffel, C. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-2191 · Cited by 47
GeoLLM: A specialized large language model framework for intelligent geotechnical design
Xu, H., Zhang, N., Yin, Z., & Njock, P. G. A. (2024) · Computers and Geotechnics · doi:10.1016/j.compgeo.2024.106849 · Cited by 50
Michaud, E. J., Liu, Z., & Tegmark, M. (2023) · Entropy · doi:10.3390/e25010175 · Cited by 58
Ye, Z., Chen, T., Wang, F., Zhang, H., & Zhang, L. (2025) · Scientific Reports · doi:10.1038/s41598-025-16797-6 · Cited by 39
Foundation models for atomistic simulation of chemistry and materials
Yuan, E. C., Liu, Y., Chen, J., Zhong, P., Raja, S., Kreiman, T., Vargas, S., Xu, W., Head‐Gordon, M., Yang, C., et al. (2026) · Nature Reviews Chemistry · doi:10.1038/s41570-025-00793-5 · Cited by 75
Scaling Laws vs Model Architectures: How does Inductive Bias Influence Scaling?
Tay, Y., Dehghani, M., Abnar, S., Chung, H., Fedus, W., Rao, J., Narang, S., Tran, V., Yogatama, D., & Metzler, D. (2023) · Findings of the Association for Computational Linguistics: EMNLP 2023 · doi:10.18653/v1/2023.findings-emnlp.825 · Cited by 34
The sociolinguistic foundations of language modeling
Grieve, J., Bartl, S., Fuoli, M., Grafmiller, J., Huang, W., Jawerbaum, A., Murakami, A., Perlman, M., Rœmling, D., & Winter, B. (2025) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2024.1472411 · Cited by 56
Machine learning meets physics: A two-way street
Levine, H., & Tu, Y. (2024) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2403580121 · Cited by 33
Deng, J., Elghobashy, M. E., Zang, K., Patel, S. K., Guo, E., & Heybati, K. (2025) · Medical Decision Making · doi:10.1177/0272989x251343082 · Cited by 36
How Much More Data Do I Need? Estimating Requirements for Downstream Tasks
Mahmood, R., Lucas, J., Acuna, D., Li, D., Philion, J., Álvarez, J. M., Yu, Z., Fidler, S., & Law, M. T. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00037 · Cited by 32
Scaling Law for Recommendation Models: Towards General-Purpose User Representations
Shin, K., Kwak, H., Kim, S. Y., Ramström, M. N., Jeong, J.-S., Ha, J.-W., & Kim, K.-M. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i4.25582 · Cited by 43
Scaling Laws for Deep LearningPreprint
Rosenfeld, J. S. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2108.07686 · Cited by 52
Bayesian interpolation with deep linear networks
Hanin, B., & Zlokapa, A. (2023) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.2301345120 · Cited by 32
Scaling Laws for Neural Machine TranslationPreprint
Ghorbani, B., Fırat, O., Freitag, M., Bapna, A., Krikun, M., Garcia, X., Chelba, C. I., & Cherry, C. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2109.07740 · Cited by 35
Evaluating the Impact of Model Scale for Compositional Generalization in Semantic Parsing
Qiu, L., Shaw, P. M., Pasupat, P., Shi, T., Herzig, J., Pitler, E., Sha, F., & Toutanova, K. (2022) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2022.emnlp-main.624 · Cited by 41
Physics-informed neural networks for solving thermal response of charring materials
Zheng, J., Huang, J., & Huang, H. (2025) · Acta Astronautica · doi:10.1016/j.actaastro.2025.07.010 · Cited by 21
Berman, D. S., Klinger, M. S., & Stapleton, A. G. (2023) · Machine Learning Science and Technology · doi:10.1088/2632-2153/ad0102 · Cited by 34
Neural Scaling of Deep Chemical Models
Frey, N., Soklaski, R., Axelrod, S., Samsi, S., Gomez-Bombarelli, R., Coley, C., & Gadepally, V. (2022) · doi:10.26434/chemrxiv-2022-3s512 · Cited by 20
Capodici, A., Fanconi, C., Curtin, C. M., Shapiro, A., Noci, F., Giannoni, A., & Hernandez‐Boussard, T. (2025) · Diagnostic and Prognostic Research · doi:10.1186/s41512-025-00190-y · Cited by 19
Chen, C. L. P., Li, L., Wang, T., Wang, Z. Z., Leng, J., Shao, H., & Cheng, L. (2026) · Journal of Manufacturing Systems · doi:10.1016/j.jmsy.2026.02.008 · Cited by 26
Anda: Unlocking Efficient LLM Inference with a Variable-Length Grouped Activation Data Format
Fang, C., Shi, M., Geens, R., Symons, A., Wang, Z., & Verhelst, M. (2025) · IEEE International Symposium on High-Performance Computer Architecture (HPCA) · doi:10.1109/hpca61900.2025.00110 · Cited by 24
Compact deep neural network models of the visual cortex
Cowley, B. R., Stan, P. L., Pillow, J. W., & Smith, M. A. (2026) · Nature · doi:10.1038/s41586-026-10150-1 · Cited by 24
Prompt-Enabled Large AI Models for CSI Feedback
Guo, J., Cui, Y., Wen, C.-K., & Jin, S. (2025) · IEEE Journal on Selected Areas in Communications · doi:10.1109/jsac.2025.3643823 · Cited by 17
Deep multi-task mining Calabi–Yau four-folds
Erbin, H., Finotello, R., Schneider, R., & Tamaazousti, M. (2021) · Machine Learning Science and Technology · doi:10.1088/2632-2153/ac37f7 · Cited by 19
Towards Green AI: Current Status and Future Research
Clemm, C., Stobbe, L., Wimalawarne, K., & Druschke, J. (2024) · Electronics Goes Green · doi:10.23919/egg62010.2024.10631247 · Cited by 26
Scaling Laws for Data Filtering—Data Curation Cannot be Compute Agnostic
Goyal, S., Maini, P., Lipton, Z. C., Raghunathan, A., & Kolter, J. Z. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.02142 · Cited by 44
Light Code: Light Analytical and Neural Codes for Channels With Feedback
Ankireddy, S. K., Narayanan, K. R., & Kim, H. (2025) · IEEE Journal on Selected Areas in Communications · doi:10.1109/jsac.2025.3531411 · Cited by 13
Lessons from complex systems science for AI governance
Kolt, N., Shur‐Ofry, M., & Reuven Cohen, C. (2025) · Patterns · doi:10.1016/j.patter.2025.101341 · Cited by 34
Cross-functional transferability in foundation machine learning interatomic potentials
Huang, X., Deng, B., Zhong, P., Kaplan, A. D., Persson, K. A., & Ceder, G. (2025) · npj Computational Materials · doi:10.1038/s41524-025-01796-y · Cited by 27
Transformer Models improve the acoustic recognition of buzz-pollinating bee species
Ferreira, A. I. S., da Silva, N. F. F., Mesquita, F. N., Rosa, T. C., Buchmann, S. L., & Neto, J. N. M. (2025) · Ecological Informatics · doi:10.1016/j.ecoinf.2025.103010 · Cited by 14
A review of state-of-the-art techniques for large language model compression
Dantas, P. V., Cordeiro, L. C., & Waldir, S. S. (2025) · Complex & Intelligent Systems · doi:10.1007/s40747-025-02019-z · Cited by 13
CLEAR: Spatial-Temporal Traffic Data Representation Learning for Traffic Prediction
Yu, J. J. Q., Fang, X., Zhang, S., & Ma, Y. (2025) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2025.3536009 · Cited by 11
Han, P., Huang, X., Fang, Y., & Han, G. (2025) · IEEE Transactions on Network Science and Engineering · doi:10.1109/tnse.2025.3572362 · Cited by 11
Wang, M., Zhang, R.-P., Wu, W.-J., Lu, Y., Wei, X.-E., Sun, Z., Guan, B.-H., Zhang, J.-J., Wu, X., Zhang, L., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02380-4 · Cited by 10
Reaching the ceiling? Empirical scaling behaviour for deep EEG pathology classification
Kiessner, A.-K., Schirrmeister, R. T., Boedecker, J., & Ball, T. (2024) · Computers in Biology and Medicine · doi:10.1016/j.compbiomed.2024.108681 · Cited by 16
Gain, M., Amirjon, A., Dam, S. K., Adhikary, A., Bairagi, A. K., Debnath, R., & Raha, A. D. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.126423 · Cited by 10
Taher, J., Hyyppä, E., Hyyppä, M., Salolahti, K., Yu, X., Leena Matikainen, A., Kukko, A., Lehtomäki, M., Kaartinen, H., Thurachen, S., et al. (2026) · ISPRS Journal of Photogrammetry and Remote Sensing · doi:10.1016/j.isprsjprs.2026.01.031 · Cited by 10
Bigger is not always better: The importance of human-scale language modeling for psycholinguistics
Wilcox, E. G., Hu, M. Y., Mueller, A., Warstadt, A., Choshen, L., Zhuang, C., Williams, A., Cotterell, R., & Linzen, T. (2025) · Journal of Memory and Language · doi:10.1016/j.jml.2025.104650 · Cited by 9
Bountzis, P., Kavallieros, D., Tsikrika, T., Vrochidis, S., & Kompatsiaris, I. Y. (2025) · Frontiers in Computer Science · doi:10.3389/fcomp.2025.1646679 · Cited by 9
Scaling Laws Under the Microscope: Predicting Transformer Performance from Small Scale Experiments
Ivgi, M., Carmon, Y., & Berant, J. (2022) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2022.findings-emnlp.544 · Cited by 17
OmniXAS: A universal deep-learning framework for materials x-ray absorption spectra
Kharel, S. R., Meng, F., Qu, X., Carbone, M. R., & Lu, D. (2025) · Physical Review Materials · doi:10.1103/physrevmaterials.9.043803 · Cited by 8
He, W., Wu, X., Jin, Z., Sun, J., Jiang, X., Zhang, S., & Zhang, B. (2025) · Interdisciplinary medicine · doi:10.1002/inmd.20250024 · Cited by 8
Wu, Q., Ding, X., Gao, S. H., Luo, J. T., & Huang, W. (2025) · Advanced Engineering Informatics · doi:10.1016/j.aei.2025.103516 · Cited by 8
State and capacity in neural models of cognition and consciousness
Wang, P., Liu, H., Ilievski, F., Ganushchak, L., Zou, L., Laureys, S., & Paas, F. (2026) · Trends Open · doi:10.1016/j.treopn.2026.04.004 · Cited by 8
Causal BERT: Improving object detection by searching for challenging groups
Resnick, C., Litany, O., Kar, A., Kreis, K., Lucas, J., Cho, K., & Fidler, S. (2021) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw54120.2021.00332 · Cited by 8
Köhler, M., & Krzyżak, A. (2025) · IEEE Transactions on Information Theory · doi:10.1109/tit.2025.3541181 · Cited by 8
Generalized domain prompt learning for accessible scientific vision-language models
Cao, Q., Chen, Y., Lu, L., Sun, H., Zeng, Z., Yang, X., & Zhang, D. (2025) · Nexus · doi:10.1016/j.ynexs.2025.100069 · Cited by 7
Cai, L., Zheng, Q., Wang, Y., Xiong, X., & Xu, Y. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.129772 · Cited by 7
Evaluating DL Model Scaling Trade-Offs During Inference via an Empirical Benchmark Analysis
Trihinas, D., Michael, P., & Symeonides, M. (2024) · Future Internet · doi:10.3390/fi16120468 · Cited by 7
A Meta-Learning Approach to Predicting Performance and Data Requirements
Jain, A., Swaminathan, G., Favaro, P., Yang, H., Ravichandran, A., Harutyunyan, H., Achille, A., Dabeer, O., Schiele, B., Swaminathan, A. D., et al. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00353 · Cited by 7
Protein foundation models: a comprehensive survey
Xu, H., Li, L., Pan, S., Cheng, P., Wang, Y., Rong, Z., Feng, L., Huang, X., Wang, S., & Shu, W. (2026) · Science China Life Sciences · doi:10.1007/s11427-025-3147-2 · Cited by 8
Tensor network to learn the wave function of data
Dymarsky, A. Y., & Pavlenko, K. (2022) · Physical Review Research · doi:10.1103/physrevresearch.4.043111 · Cited by 7
Fast and robust visual object recognition in young children
Ayzenberg, V., Sener, S. B., Novick, K., & Lourenco, S. F. (2025) · Science Advances · doi:10.1126/sciadv.ads6821 · Cited by 7
Incorporating Causality Into Deep Learning Architectures to Improve Flash Drought Forecasts
Tang, S., Wang, S., Jiang, J., & Zheng, Y. (2025) · Water Resources Research · doi:10.1029/2024wr039470 · Cited by 7
Wilsonian renormalization of neural network Gaussian processes*
Howard, J. N., Jefferson, R., Maiti, A., & Ringel, Z. (2025) · Machine Learning Science and Technology · doi:10.1088/2632-2153/adc8fc · Cited by 5
A Scaling Law for Synthetic-to-Real Transfer: How Much Is Your Pre-training Effective?Preprint
Mikami, H., Fukumizu, K., Murai, S., Suzuki, S., Kikuchi, Y., Suzuki, T., Maeda, S., & Hayashi, K. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2108.11018 · Cited by 5
Brcković, A., Malvić, T., Orešković, J., & Kapuralić, J. (2025) · Geosciences · doi:10.3390/geosciences15060206 · Cited by 5
Tu, P., Zheng, C., Xie, X., Lv, J., Xie, M., Guo, J., Yin, S., Qiu, K., Wei, Y., Wang, C., et al. (2026) · Nature Biomedical Engineering · doi:10.1038/s41551-026-01622-w · Cited by 4
May, M., Jacobs, G., Dehn, S., Höpfner, G., Zerwas, T., Boelsen, K., & Hacker, S. (2026) · Systems · doi:10.3390/systems14030302 · Cited by 4
Bresó-Pla, V., Heinrich, G., Magerya, V., & Olsson, A. (2025) · SciPost Physics · doi:10.21468/scipostphys.19.5.123 · Cited by 31
Bayesian RG flow in neural network field theories
Howard, J. N., Klinger, M. S., Maiti, A., & Stapleton, A. G. (2025) · SciPost Physics Core · doi:10.21468/scipostphyscore.8.1.027 · Cited by 11
Scaling laws in jet classification
Batson, J., & Kahn, Y. F. (2025) · SciPost Physics Core · doi:10.21468/scipostphyscore.8.1.034 · Cited by 4
Universal scaling laws in the gradient descent training of neural networksPreprint
Velikanov, M., & Yarotsky, D. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2105.00507 · Cited by 4
Chen, Z.-Y., Li, T., Yang, Y., Huang, H., Lin, H., Liu, H., Zhong, G., & Li, Z. (2025) · Polymer · doi:10.1016/j.polymer.2025.128875 · Cited by 4
Ma, D., Pang, J., Velan, S. S., Gotway, M. B., & Liang, J. (2025) · Medical Image Analysis · doi:10.1016/j.media.2025.103828 · Cited by 5
Multimodal LLM vs. Human-Measured Features for AI Predictions of Autism in Home Videos
Azizian, P., Honarmand, M., Jaiswal, A., Kline, A., Dunlap, K., Washington, P. Y., & Wall, D. P. (2025) · Algorithms · doi:10.3390/a18110687 · Cited by 3
Juntao, Y., Adie, J., See, S. C. W., Gualandi, A., & Mengaldo, G. (2025) · Journal of Computational Physics · doi:10.1016/j.jcp.2025.114502 · Cited by 3
Wu, L., Shi, Y., Song, C., Xiong, X., He, Z., Hu, J., & Xia, D. (2025) · Journal of environmental chemical engineering · doi:10.1016/j.jece.2025.120183 · Cited by 3
Cagnetta, F., Favero, A., Sclocchi, A., & Wyart, M. (2025) · Physical review. E · doi:10.1103/qtd6-nl8p · Cited by 8
Very-large-scale mimetic optogenetic synapses for physical reservoir computing
Han, X., Qi, Z., Kundrát, V., Li, H., Li, Z., Guo, X., Mao, P., Zheng, W., Hou, S., Liu, R., et al. (2026) · Nature Communications · doi:10.1038/s41467-025-68229-8 · Cited by 4
Forecasting migraine with time-series machine learning from mobile health data
Faisal, F., Poole, A. C., Danelakis, A., Meisingset, T. W., Bjørk, M., Khanevski, A. N., Kristoffersen, E. S., Kumelj, T., Larsen, I. C. K., Lunder, O. V., et al. (2026) · The Journal of Headache and Pain · doi:10.1186/s10194-026-02346-7 · Cited by 3
Atomic-level protein–ligand recognition with PBCNet2.0 for probe discovery
Yu, J., Sheng, X., Fan, Z., Wang, Z., Cao, D., Tang, Y., Hao, Y., Zhang, Y., Shao, P., Ma, H., et al. (2026) · Nature Chemical Biology · doi:10.1038/s41589-026-02241-x · Cited by 8
When Can AI Models Explain Learning? Validity Criteria for AI as Cognitive Models in Education
Wang, P., Viberg, O., Law, E. L.-C., & Greiff, S. (2026) · Educational Psychology Review · doi:10.1007/s10648-026-10202-y · Cited by 3
SDSL: Spectral Distance Scaling Loss Pretraining SwinUNETR for 3D Medical Image Segmentation
Lee, J., Vu, D. T., Yu, G.-H., Kim, J., Kim, K., & Kim, J. Y. (2024) · IEEE Access · doi:10.1109/access.2024.3450961 · Cited by 3
Self-citationPan, R., Fang, X., Azizzadenesheli, K., Liu-Schiaffini, M., Gu, M., & Wu, J. (2025) · The Journal of Chemical Physics · doi:10.1063/5.0284515 · Cited by 3
Geometric deep learning for galaxy-halo connection: a case study for galaxy intrinsic alignments
Jagvaral, Y., Lanusse, F., & Mandelbaum, R. (2025) · Monthly Notices of the Royal Astronomical Society · doi:10.1093/mnras/staf592 · Cited by 3
Streamlining distributed Deep Learning I/O with ad hoc file systems
Schimmelpfennig, F., Vef, M.-A., Salkhordeh, R., Miranda, A., Nou, R., & Brinkmann, A. (2021) · IEEE International Conference on Cluster Computing (CLUSTER) · doi:10.1109/cluster48925.2021.00062 · Cited by 3
Lee, D., Lee, H., & Yi, J. (2025) · Physical Review Research · doi:10.1103/tf5z-7q29 · Cited by 6
Neural scaling laws from large-N field theory: solvable model beyond the ridgeless limit
Zhang, Z. (2025) · Machine Learning Science and Technology · doi:10.1088/2632-2153/adc872 · Cited by 10
Learning Curves for SGD on Structured FeaturesPreprint
Bordelon, B., & Pehlevan, C. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2106.02713 · Cited by 3
Observational Scaling Laws and the Predictability of Language Model Performance
Ruan, Y., Maddison, C. J., & Hashimoto, T. (2024) · arXiv · doi:10.48550/arxiv.2405.10938 · Cited by 3
Utilizing Unsupervised Learning for Improving ML Channel State Feedback in Cellular Networks
Flowers, B., Sawant, A., Wang, R., & Zhang, D. (2023) · IEEE Vehicular Technology Conference · doi:10.1109/vtc2023-spring57618.2023.10199181 · Cited by 2
A comprehensive taxonomy of machine consciousness
Qin, R., Zhou, C., & He, M. (2025) · Information Fusion · doi:10.1016/j.inffus.2025.102994 · Cited by 5
Knowledge-Based Sampling Method for Deep Learning-Assisted Planar Antenna Array Design
Zhang, R., Cai, H., Shen, Y., Xu, S., & Hu, S. (2025) · IEEE Transactions on Antennas and Propagation · doi:10.1109/tap.2025.3589734 · Cited by 2
El-Hakim, M., Khaled, H., Fawzy, A., & Anthonappa, R. P. (2025) · Dentistry Journal · doi:10.3390/dj13110531 · Cited by 3
Hashemi, N., Mose, M., Østergaard, L. R., Bjerrum, F., Søgaard-Andersen, E., Fabrin, K., Tuckus, G., Friis, M. L., Rasmussen, S., & Tolsgaard, M. G. (2025) · Journal of Robotic Surgery · doi:10.1007/s11701-025-02994-y · Cited by 3
Kong, L., & An, Y. (2026) · Advanced Engineering Informatics · doi:10.1016/j.aei.2026.104546 · Cited by 2
Liao, Y., Bai, Y., Chen, S., Wang, J., You, Y., Chen, Z. L., Wu, H. B., Huang, H., Li, W., Zang, M., et al. (2026) · Remote Sensing of Environment · doi:10.1016/j.rse.2026.115529 · Cited by 2
Sustainability assessment using multimodal artificial intelligence agents
Zhang, Z., Metzger, A. L., Mei, Y., Hähnlein, F., Englhardt, Z., Cheng, T., Abowd, G. D., Patel, S., Schulz, A., & Iyer, V. (2026) · Nature Electronics · doi:10.1038/s41928-026-01653-w · Cited by 11
Training from Zero: Forecasting of Radio Frequency Machine Learning Data Quantity
Clark, W. H., & Michaels, A. J. (2024) · Telecom · doi:10.3390/telecom5030032 · Cited by 2
How feature learning can improve neural scaling laws *
Bordelon, B., Atanasov, A., & Pehlevan, C. (2025) · Journal of Statistical Mechanics Theory and Experiment · doi:10.1088/1742-5468/adefb1 · Cited by 37
Metadata
- Authors
- Bahri, Y., Dyer, E., Kaplan, J., Lee, J., & Sharma, U.
- Affiliations
- Google (United States) (US)
- Johns Hopkins University (US)
- Corresponding author
- Bahri, Yasaman
- Dyer, Ethan
- Lee, Jaehoon
- Sharma, Utkarsh
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2021
- Volume
- 121
- Issue
- 27
- Pages
- e2311878121-e2311878121
- ISSN
- 0027-8424 (ISSN-L)
- arXiv
- 2102.06701
- PMC
- PMC11228526
- OpenAlex
- W3133450183
- Cited by
- 182
- References
- 91
- Citations by year
- 2026: 56 · 2025: 74 · 2024: 17 · 2023: 15 · 2022: 7 · 2021: 13
- FWCI
- 21.65
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by-nc-nd
- arxiv.org/licenses/nonexclusive-distrib/1.0/
- Locations
- Proceedings of the National Academy of Sciences (publishedVersion, cc-by-nc-nd)
- PubMed Central (publishedVersion, cc-by-nc-nd)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Funders
- Open Philanthropy Project
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Stochastic Gradient Optimization Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Neural Networks and Applications
- Physical Sciences › Computer Science › Artificial Intelligence › Domain Adaptation and Few-Shot Learning
- Keywords
- neural scaling laws, power-law scaling, population decline, infinite-width limit, data manifold, random features, pre-trained models, scaling exponents, duality, model size, training data size
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
