

The DOI matches its DataCite record; 75 of the 75 references it cites were found in a registry or an index; 65 of the 82 sources its claims cite were checked for support.
Diffusion Models Beat GANs on Image Synthesis
Open accessAbstract
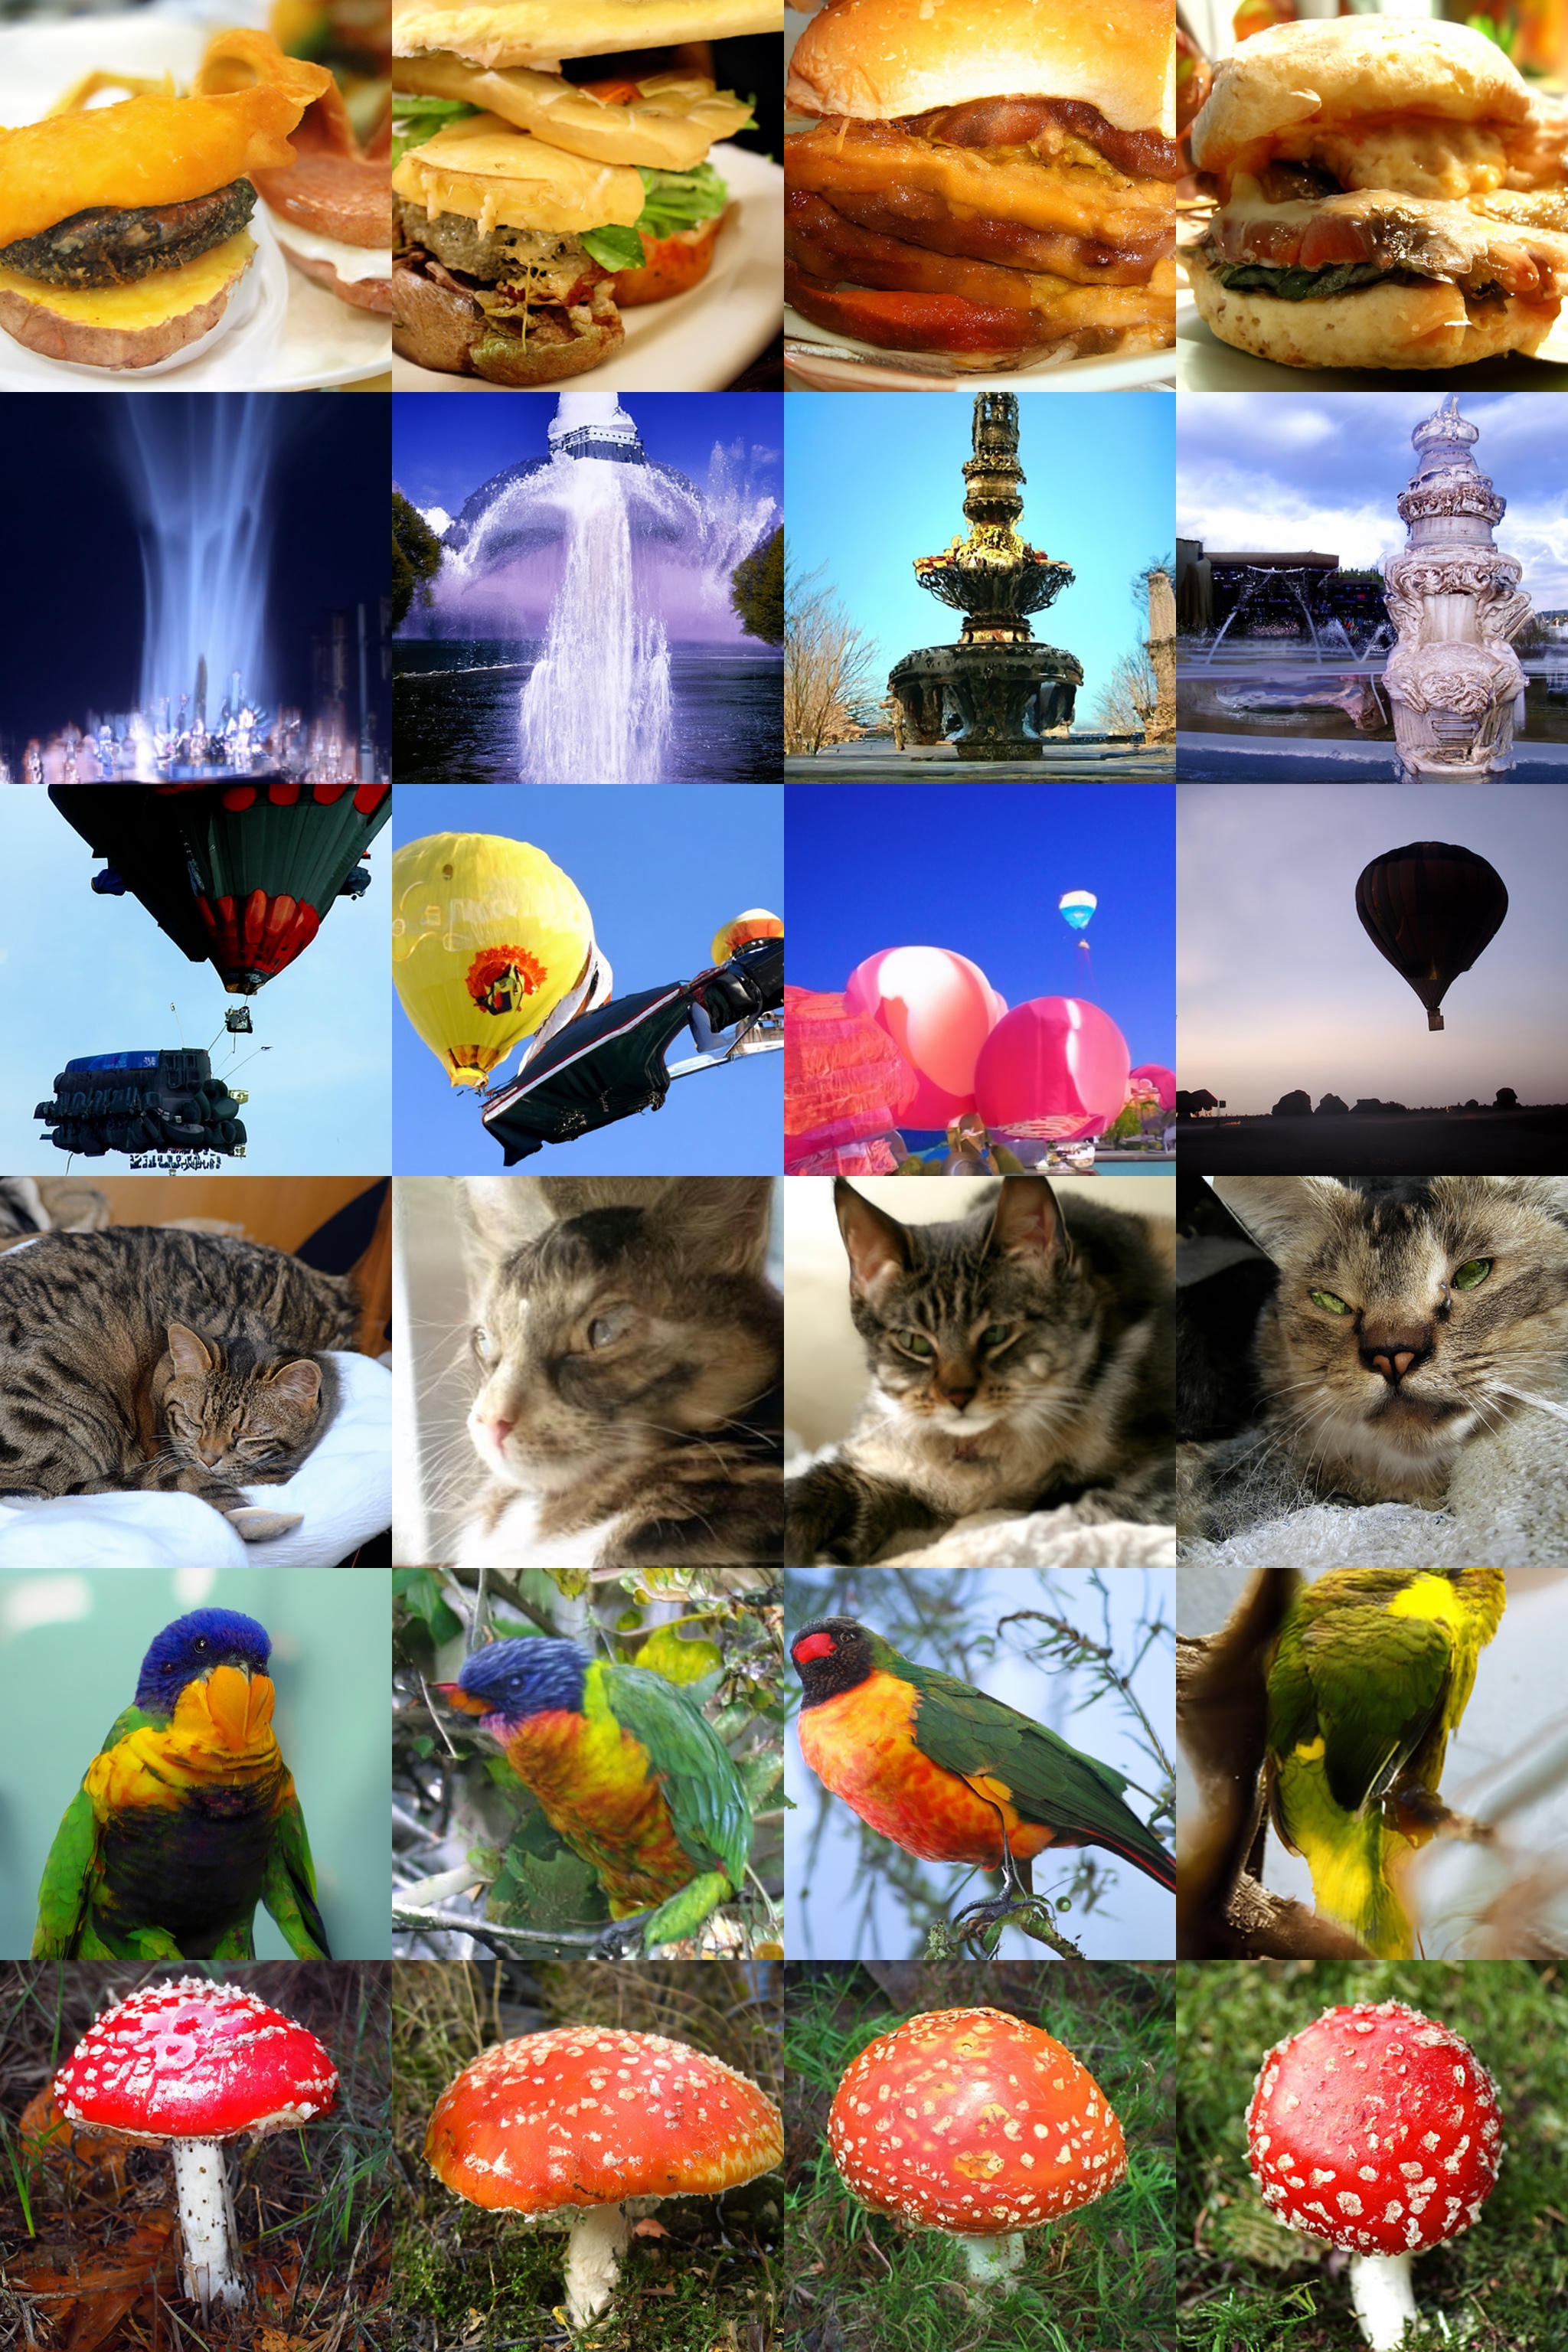
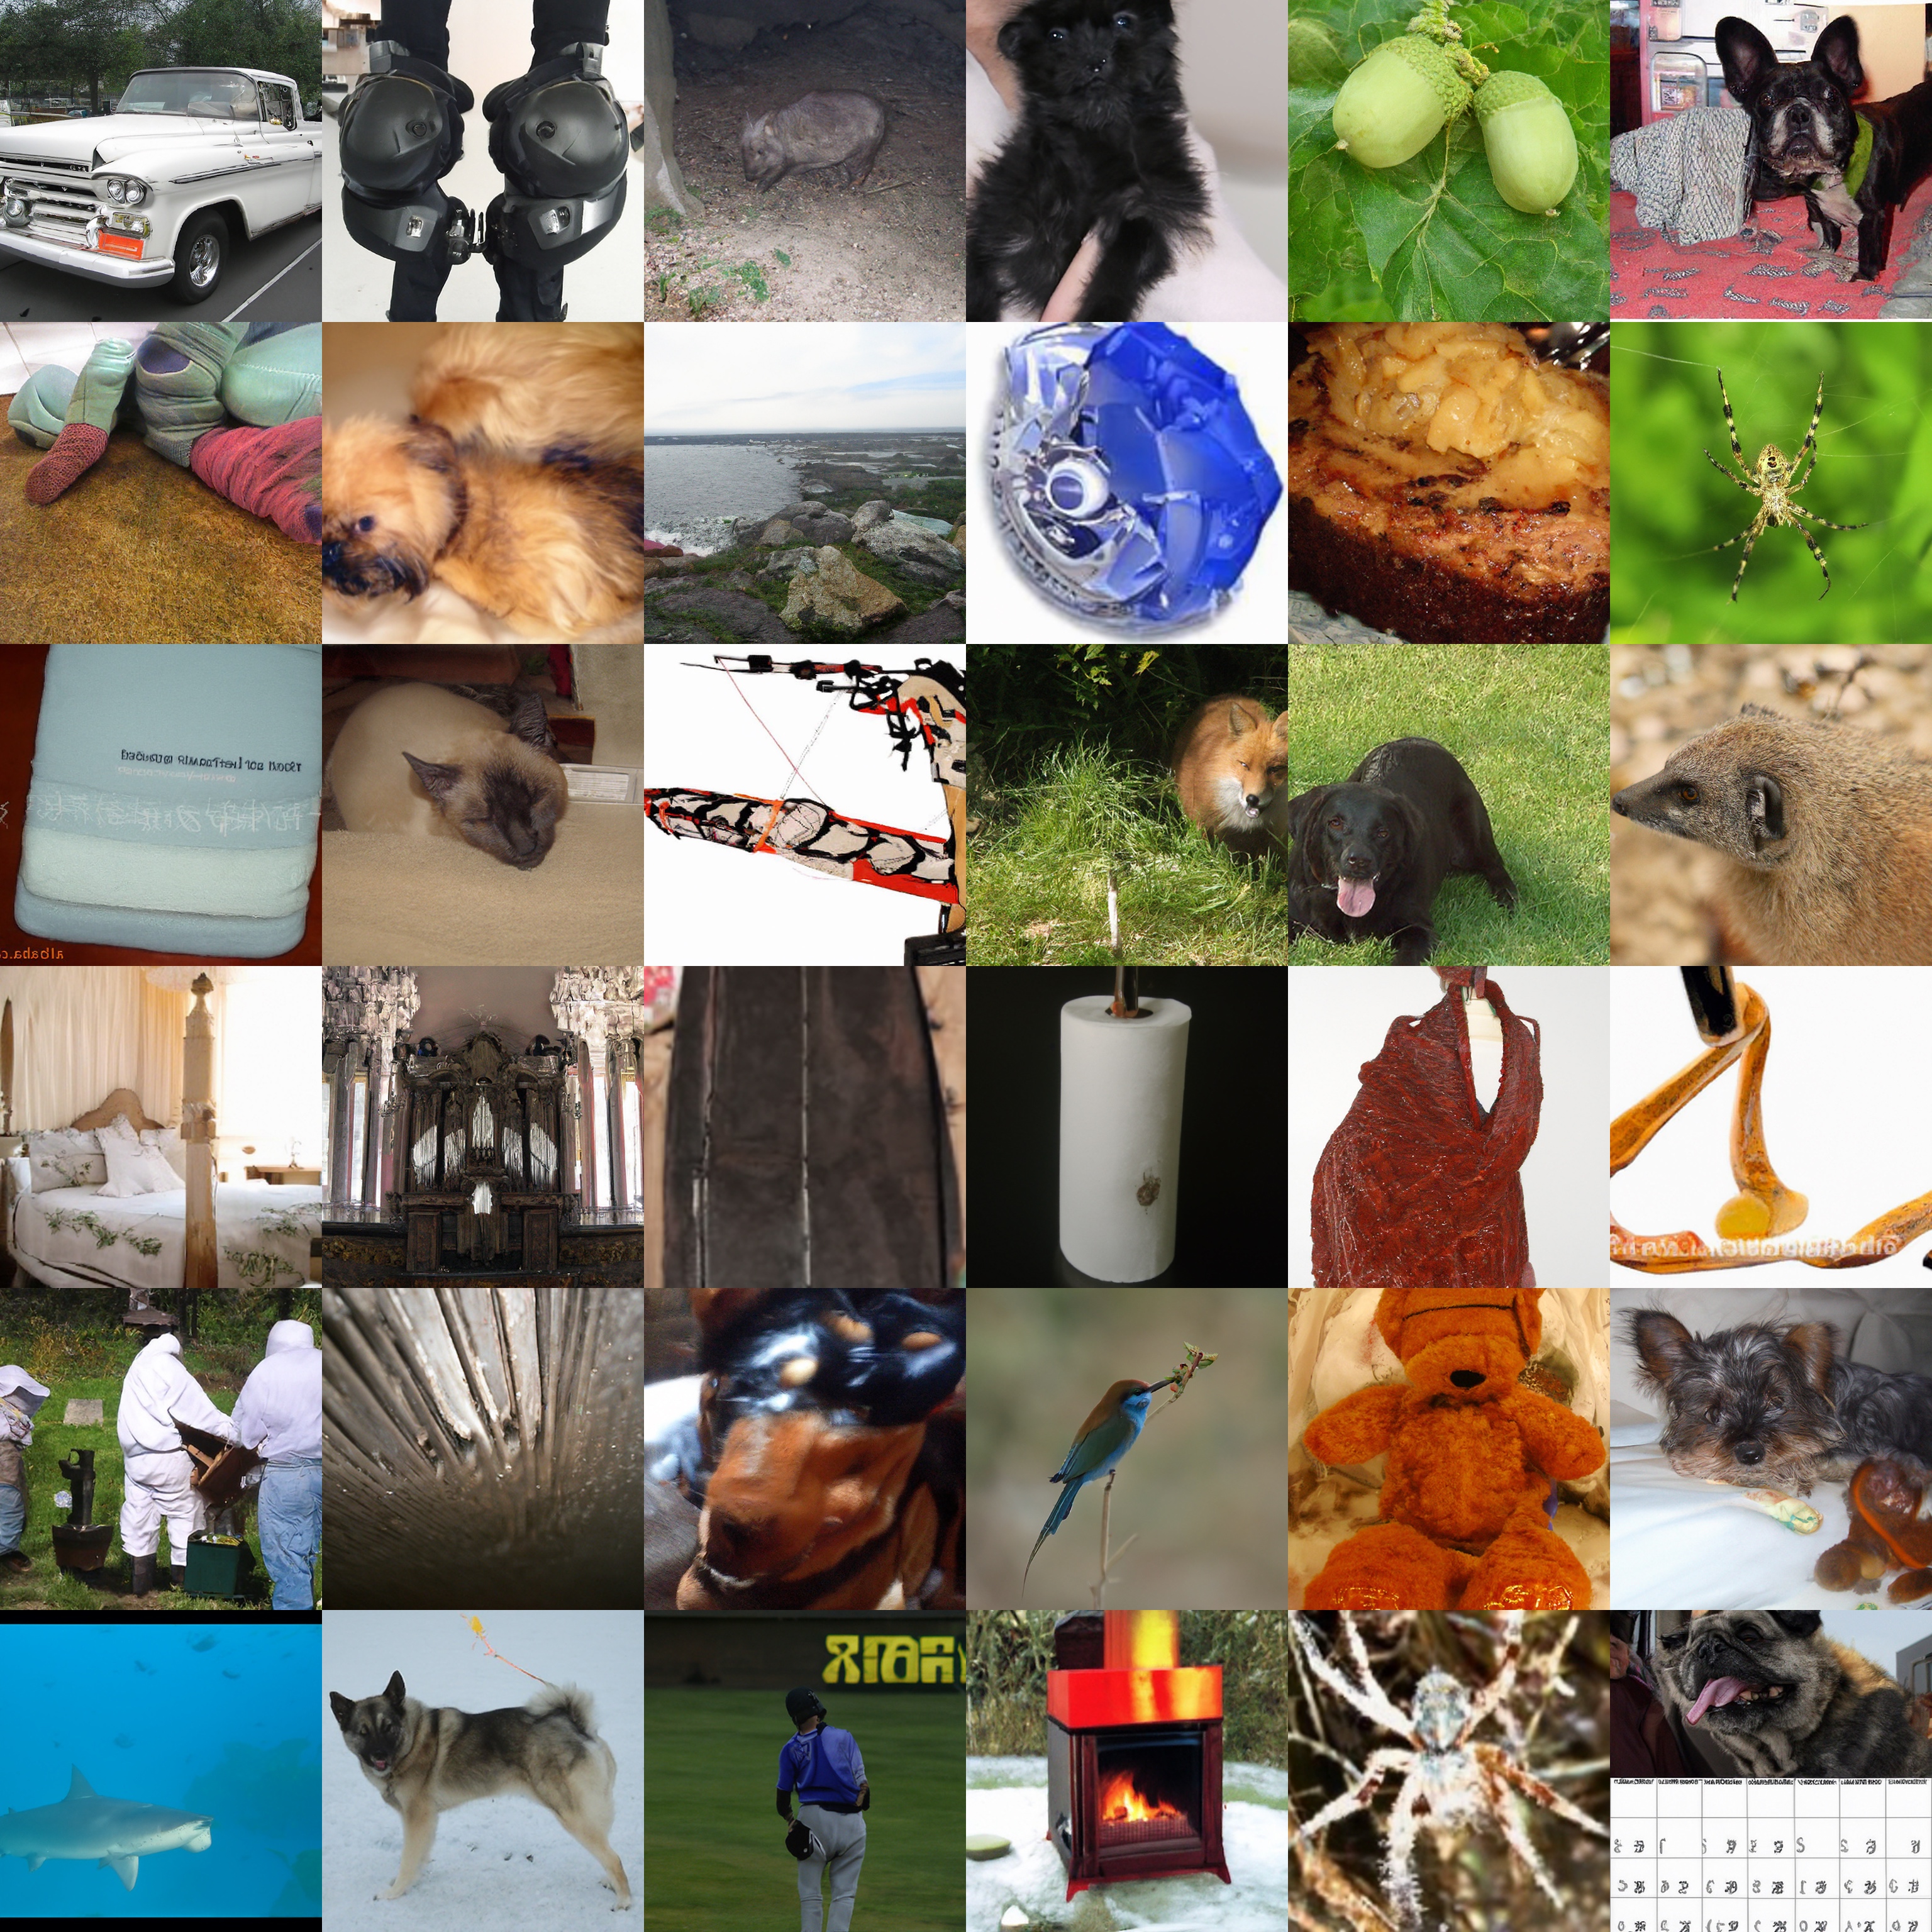
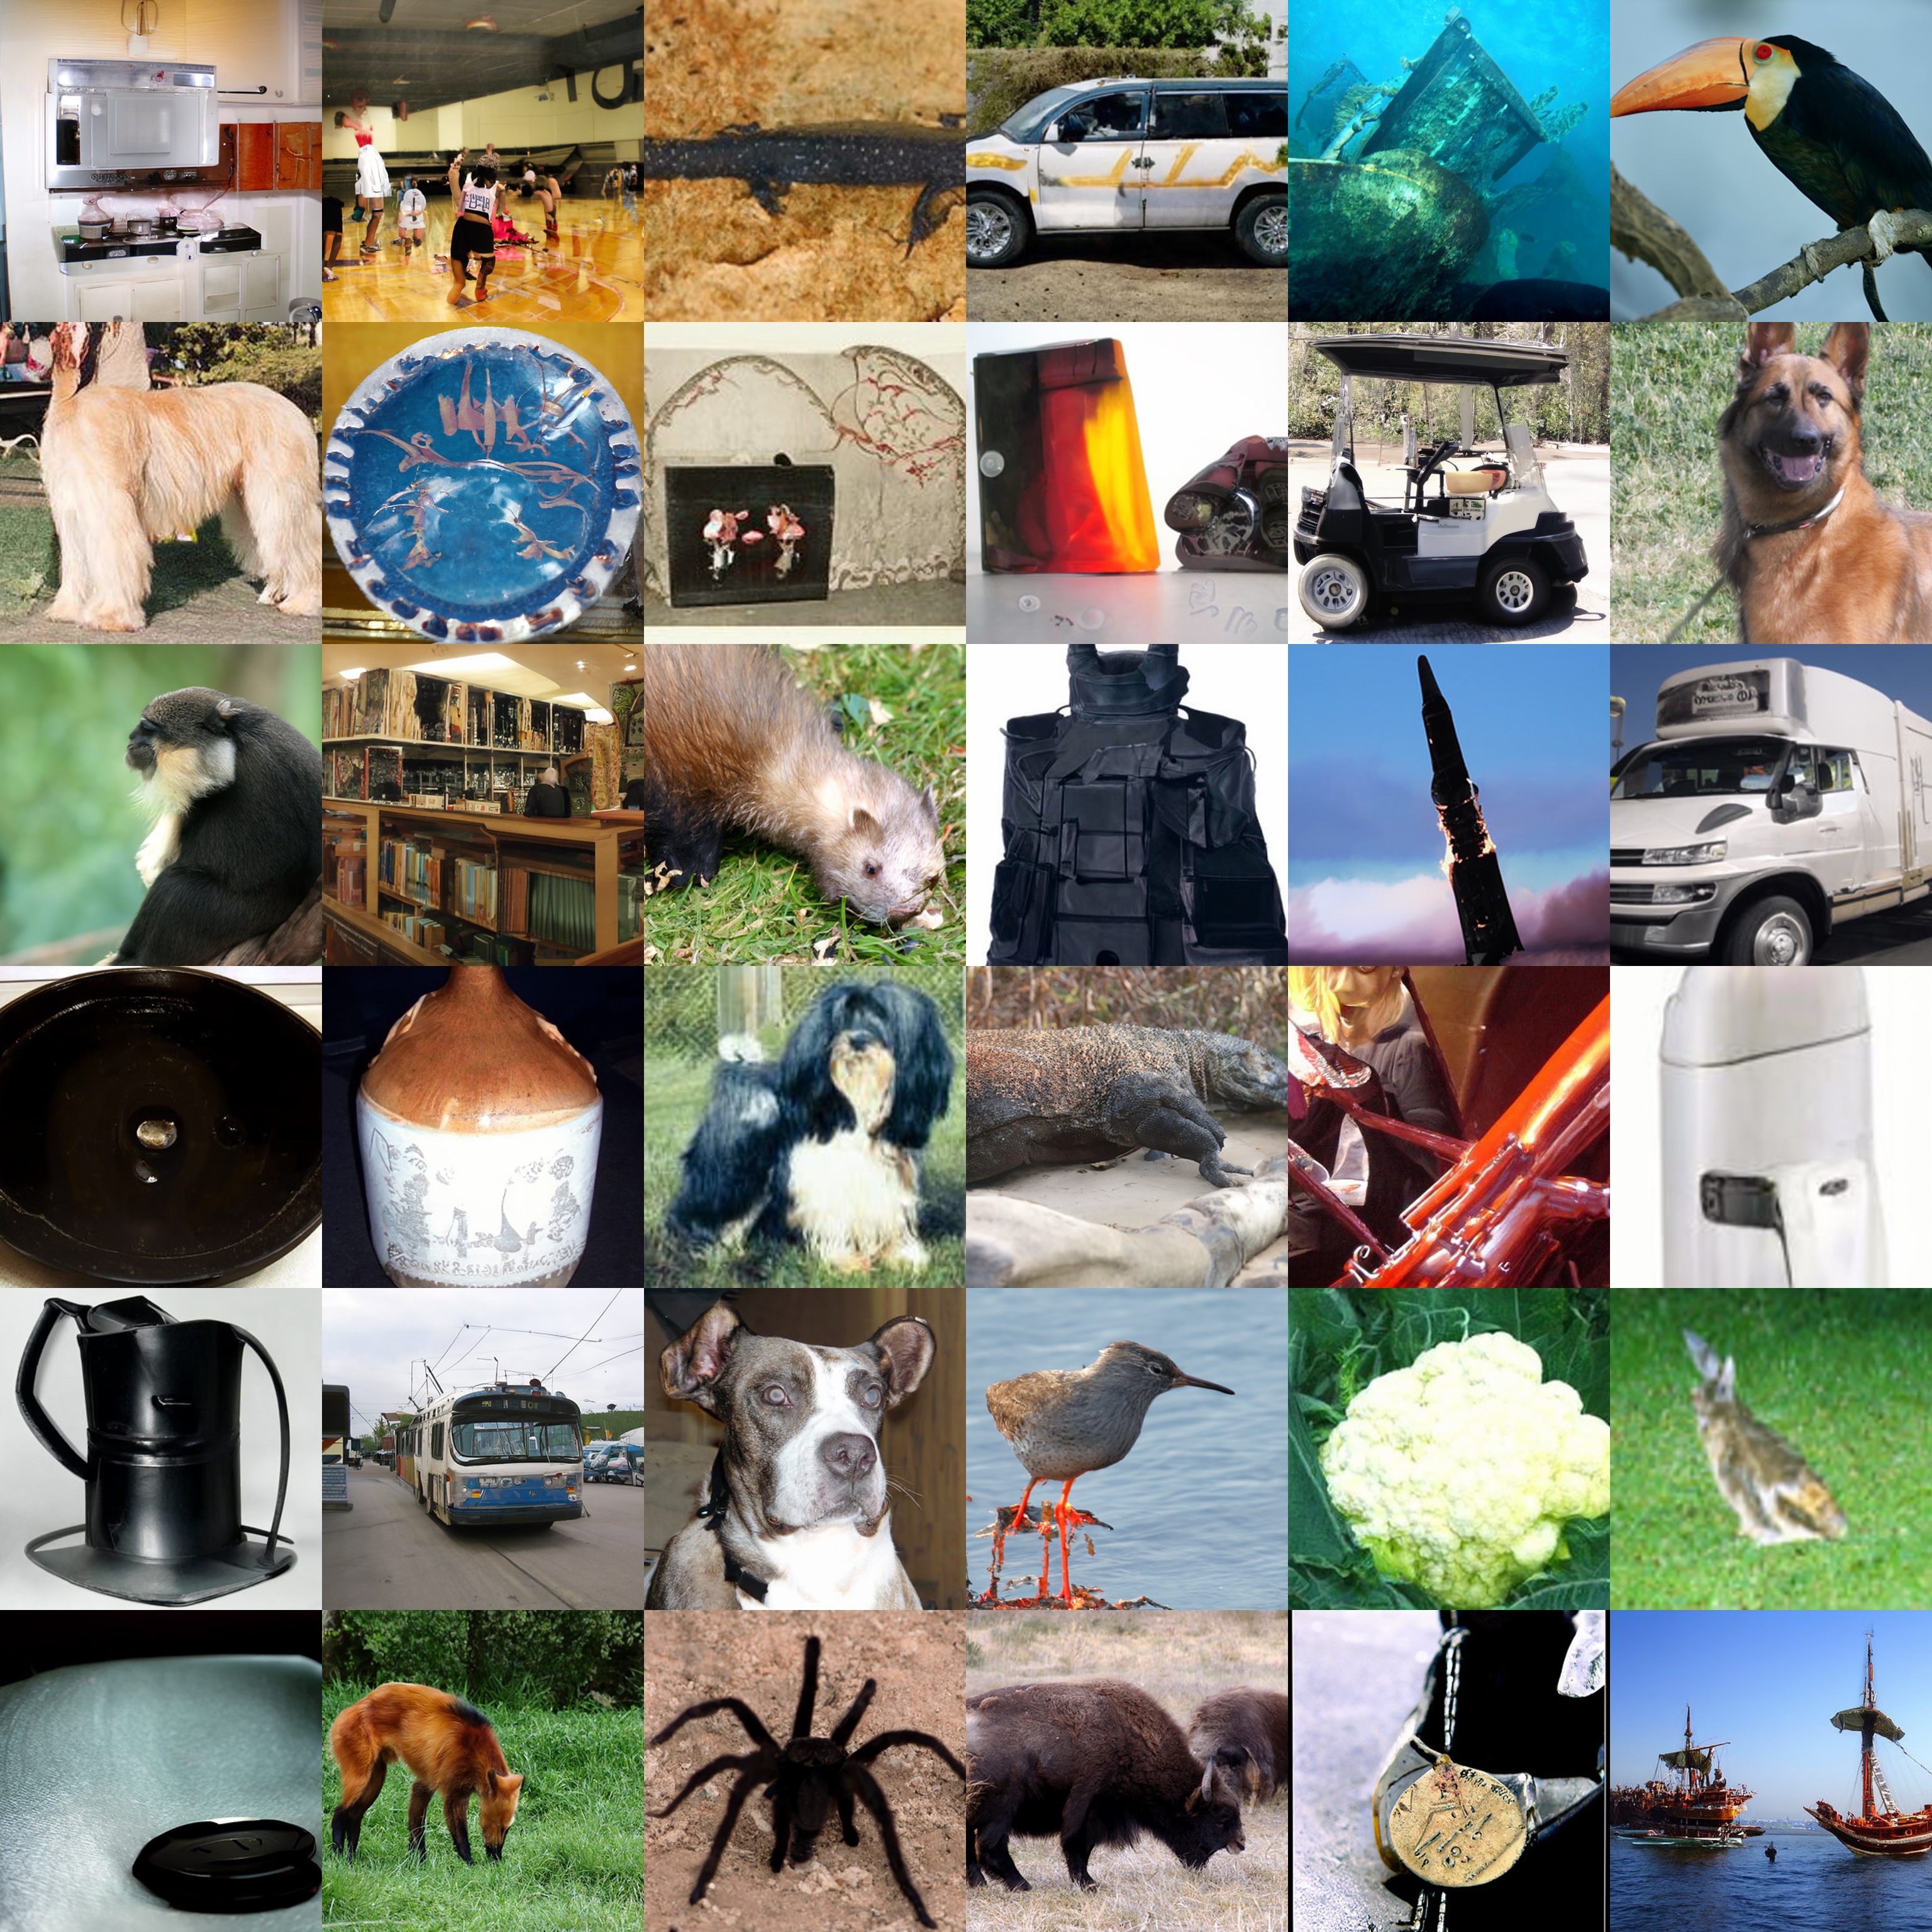
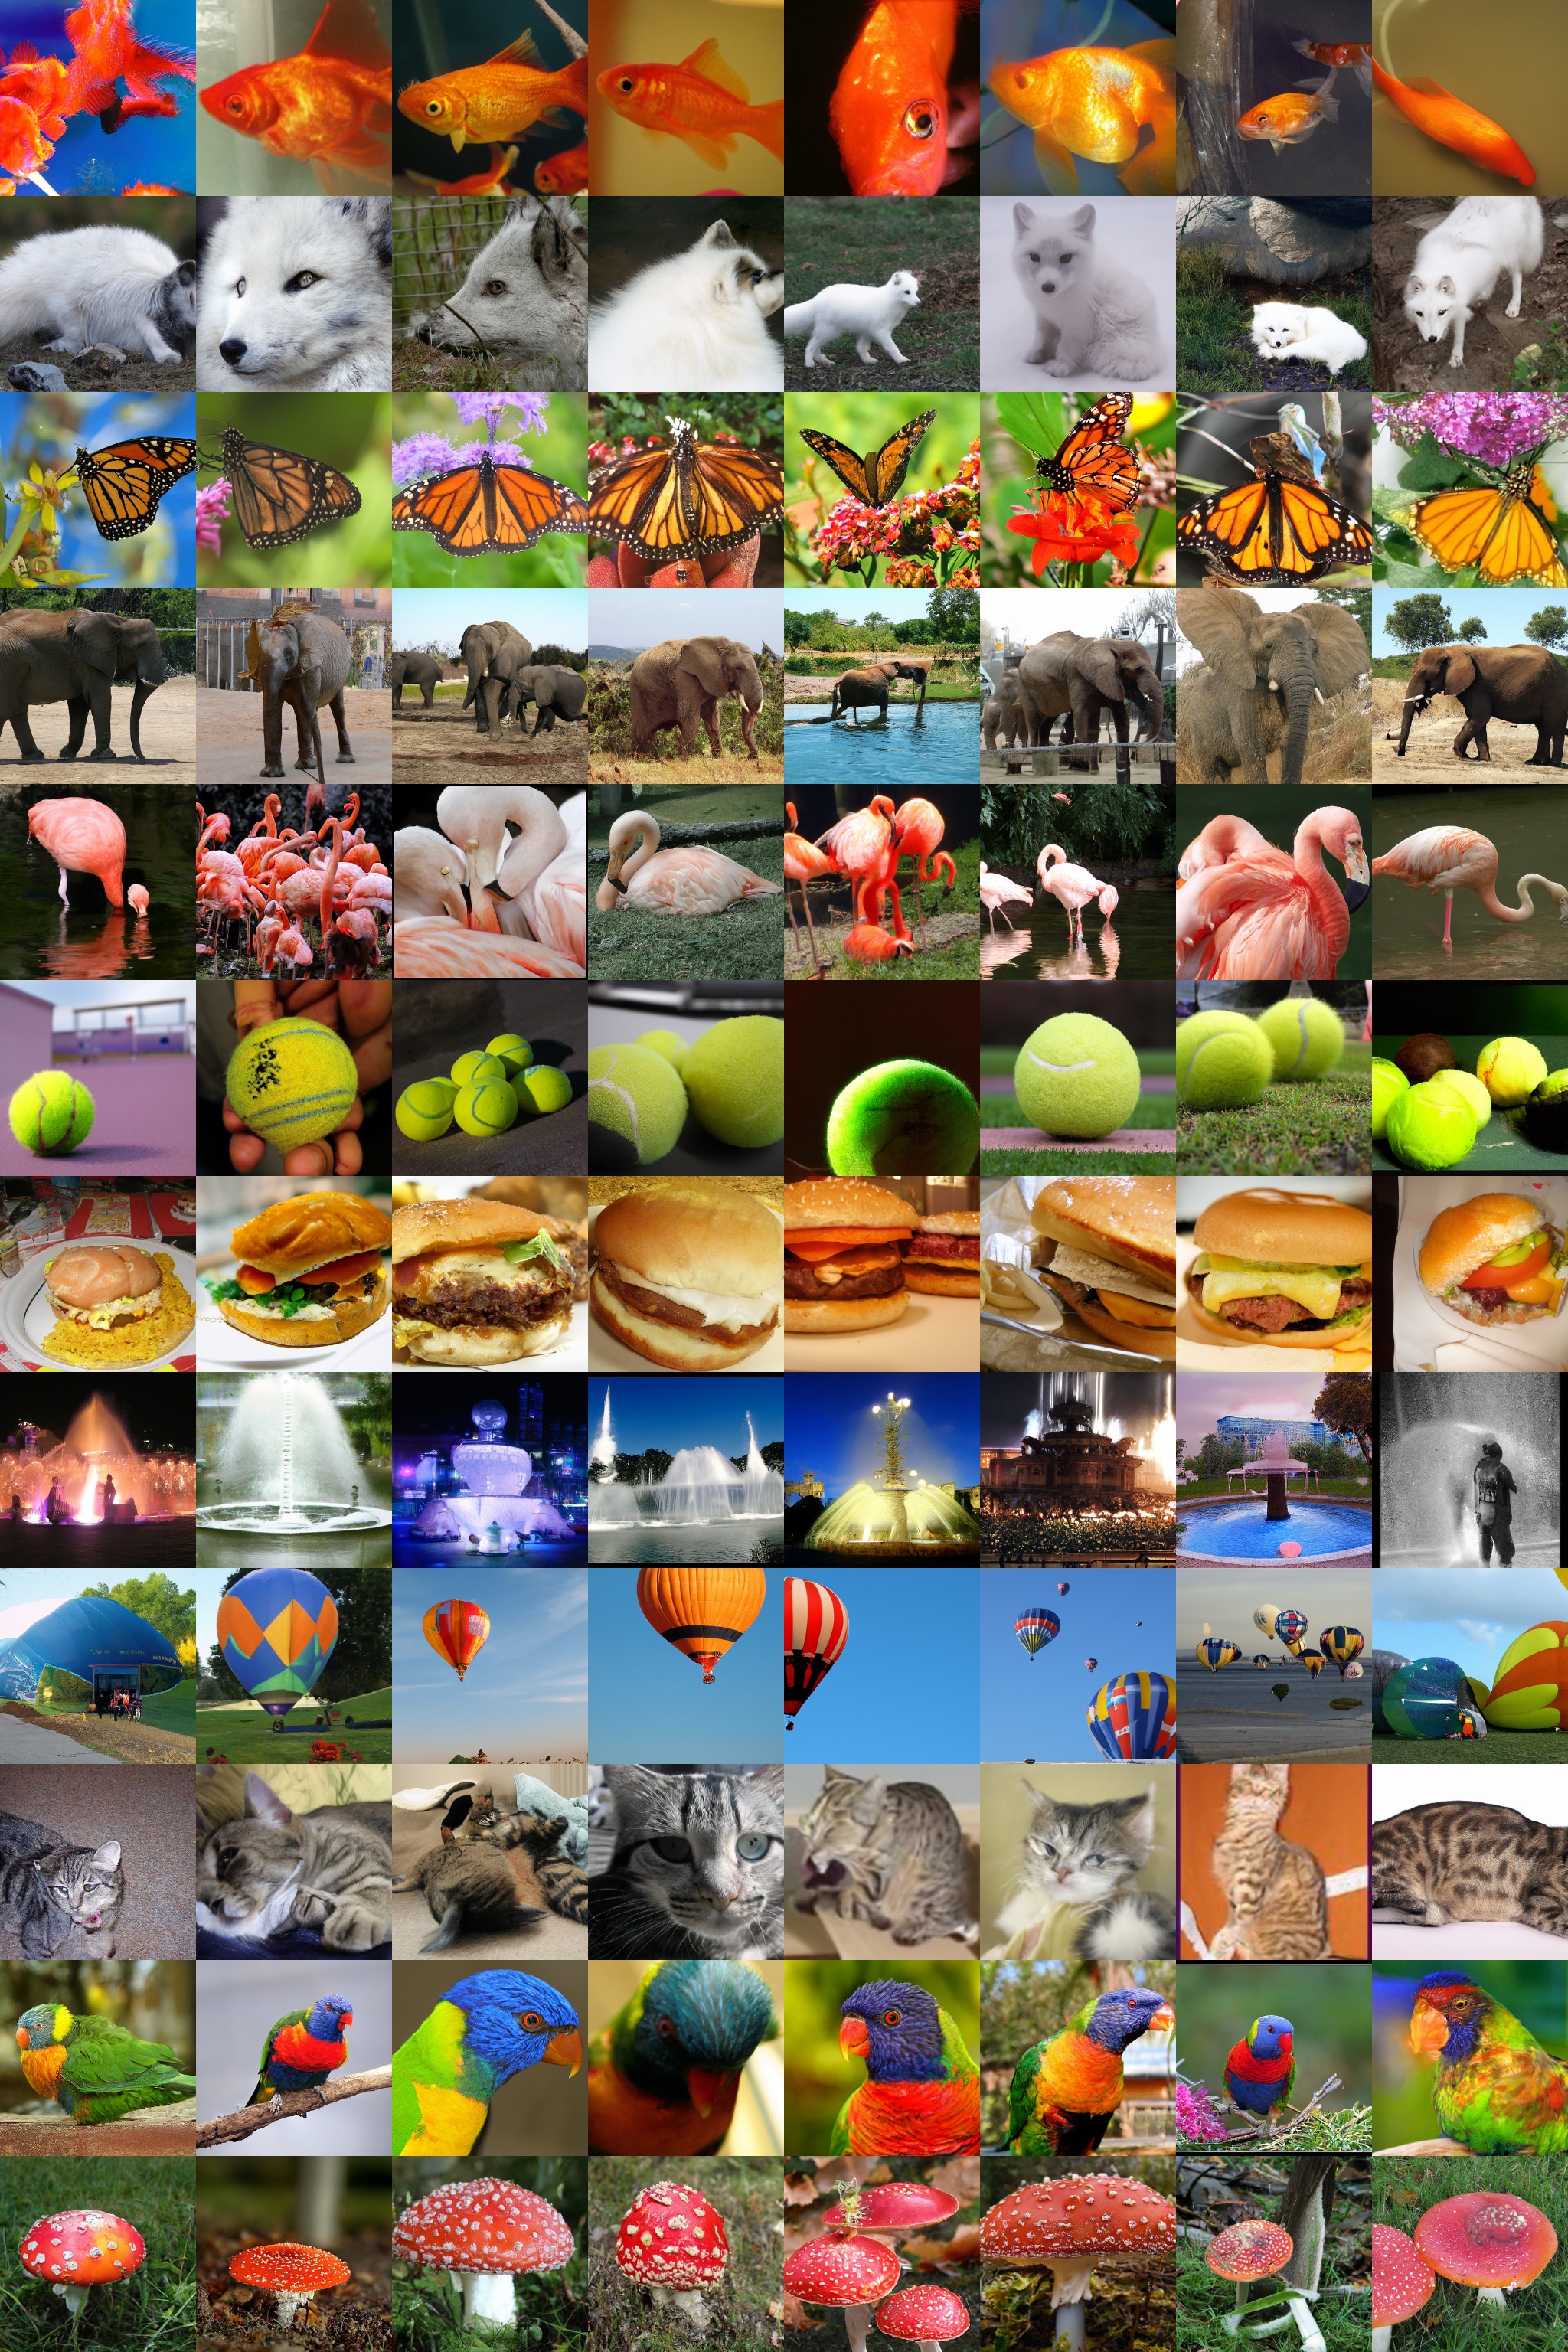
We show that diffusion models can achieve image sample quality superior to the current state-of-the-art generative models. We achieve this on unconditional image synthesis by finding a better architecture through a series of ablations. For conditional image synthesis, we further improve sample quality with classifier guidance: a simple, compute-efficient method for trading off diversity for fidelity using gradients from a classifier. We achieve an FID of 2.97 on ImageNet 128$\times$128, 4.59 on ImageNet 256$\times$256, and 7.72 on ImageNet 512$\times$512, and we match BigGAN-deep even with as few as 25 forward passes per sample, all while maintaining better coverage of the distribution. Finally, we find that classifier guidance combines well with upsampling diffusion models, further improving FID to 3.94 on ImageNet 256$\times$256 and 3.85 on ImageNet 512$\times$512. We release our code at https://github.com/openai/guided-diffusion
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
Diffusion models with improved UNet architectures and classifier guidance surpass state-of-the-art GANs on class-conditional ImageNet synthesis, achieving FID 2.97 at 128×128, 4.59 at 256×256, and 7.72 at 512×512. Combining guidance with upsampling further improves FID to 3.94 at 256×256 and 3.85 at 512×512.
Key findings
- Improved architecture alone gives state-of-the-art unconditional results: LSUN bedrooms FID 1.90, horses 2.57, cats 5.57; ImageNet 64×64 ADM (dropout) FID 2.07.
- Classifier guidance improves conditional ImageNet: ADM-G FID 2.97 at 128×128, 4.59 at 256×256, and 7.72 at 512×512; with 25 DDIM steps, FID is 5.98, 5.44, and 8.41 respectively, comparable to BigGAN-deep.
- Guidance trades diversity for fidelity: increasing gradient scale improves precision/IS but lowers recall. For example, a conditional ImageNet 256×256 model with guidance scale 1.0 has FID 4.59, precision 0.82, recall 0.52; scale 10.0 has FID 9.11, precision 0.88, recall 0.32.
- Combining guidance with upsampling gives the best FIDs: ADM-G + ADM-U reaches FID 3.94 on ImageNet 256×256 and 3.85 on ImageNet 512×512.
Methods
- Architecture ablations were run on ImageNet 128×128 with batch size 256 and 250 sampling steps, testing depth vs. width, attention heads/resolutions, BigGAN up/downsampling, residual rescaling, and AdaGN. The final default uses variable width, 2 residual blocks per resolution, 64 channels per head, attention at 32/16/8, BigGAN residual blocks, and AdaGN.
- Classifier guidance trains a classifier \(p_\phi(y|x_t,t)\) on noisy images and uses gradients \(\nabla_{x_t}\log p_\phi(y|x_t,t)\) to guide diffusion sampling, with a gradient scale \(s\) for stochastic and DDIM samplers. Models are trained on ImageNet 128×128, 256×256, and 512×512, and on LSUN bedroom, horse, and cat.
- Evaluation uses FID, sFID, Inception Score, and Improved Precision/Recall; comparisons re-compute metrics using public samples or models where possible and use the entire training set as the reference batch.
Limitations
- Stated: diffusion models are still slower than GANs at sampling time because they use multiple denoising steps/forward passes.
- Stated: classifier guidance is limited to labeled datasets, and the paper provides no effective strategy for trading off diversity for fidelity on unlabeled datasets.
- Evident from the text: compute requirements are high, e.g., ImageNet 256×256 ADM-G (1980K) uses 916 generator V100-days plus 46 classifier V100-days (962 total), and ImageNet 512×512 best uses 1878 + 36 = 1914 V100-days; guidance also trades recall for precision, so best FID occurs at an intermediate scale.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
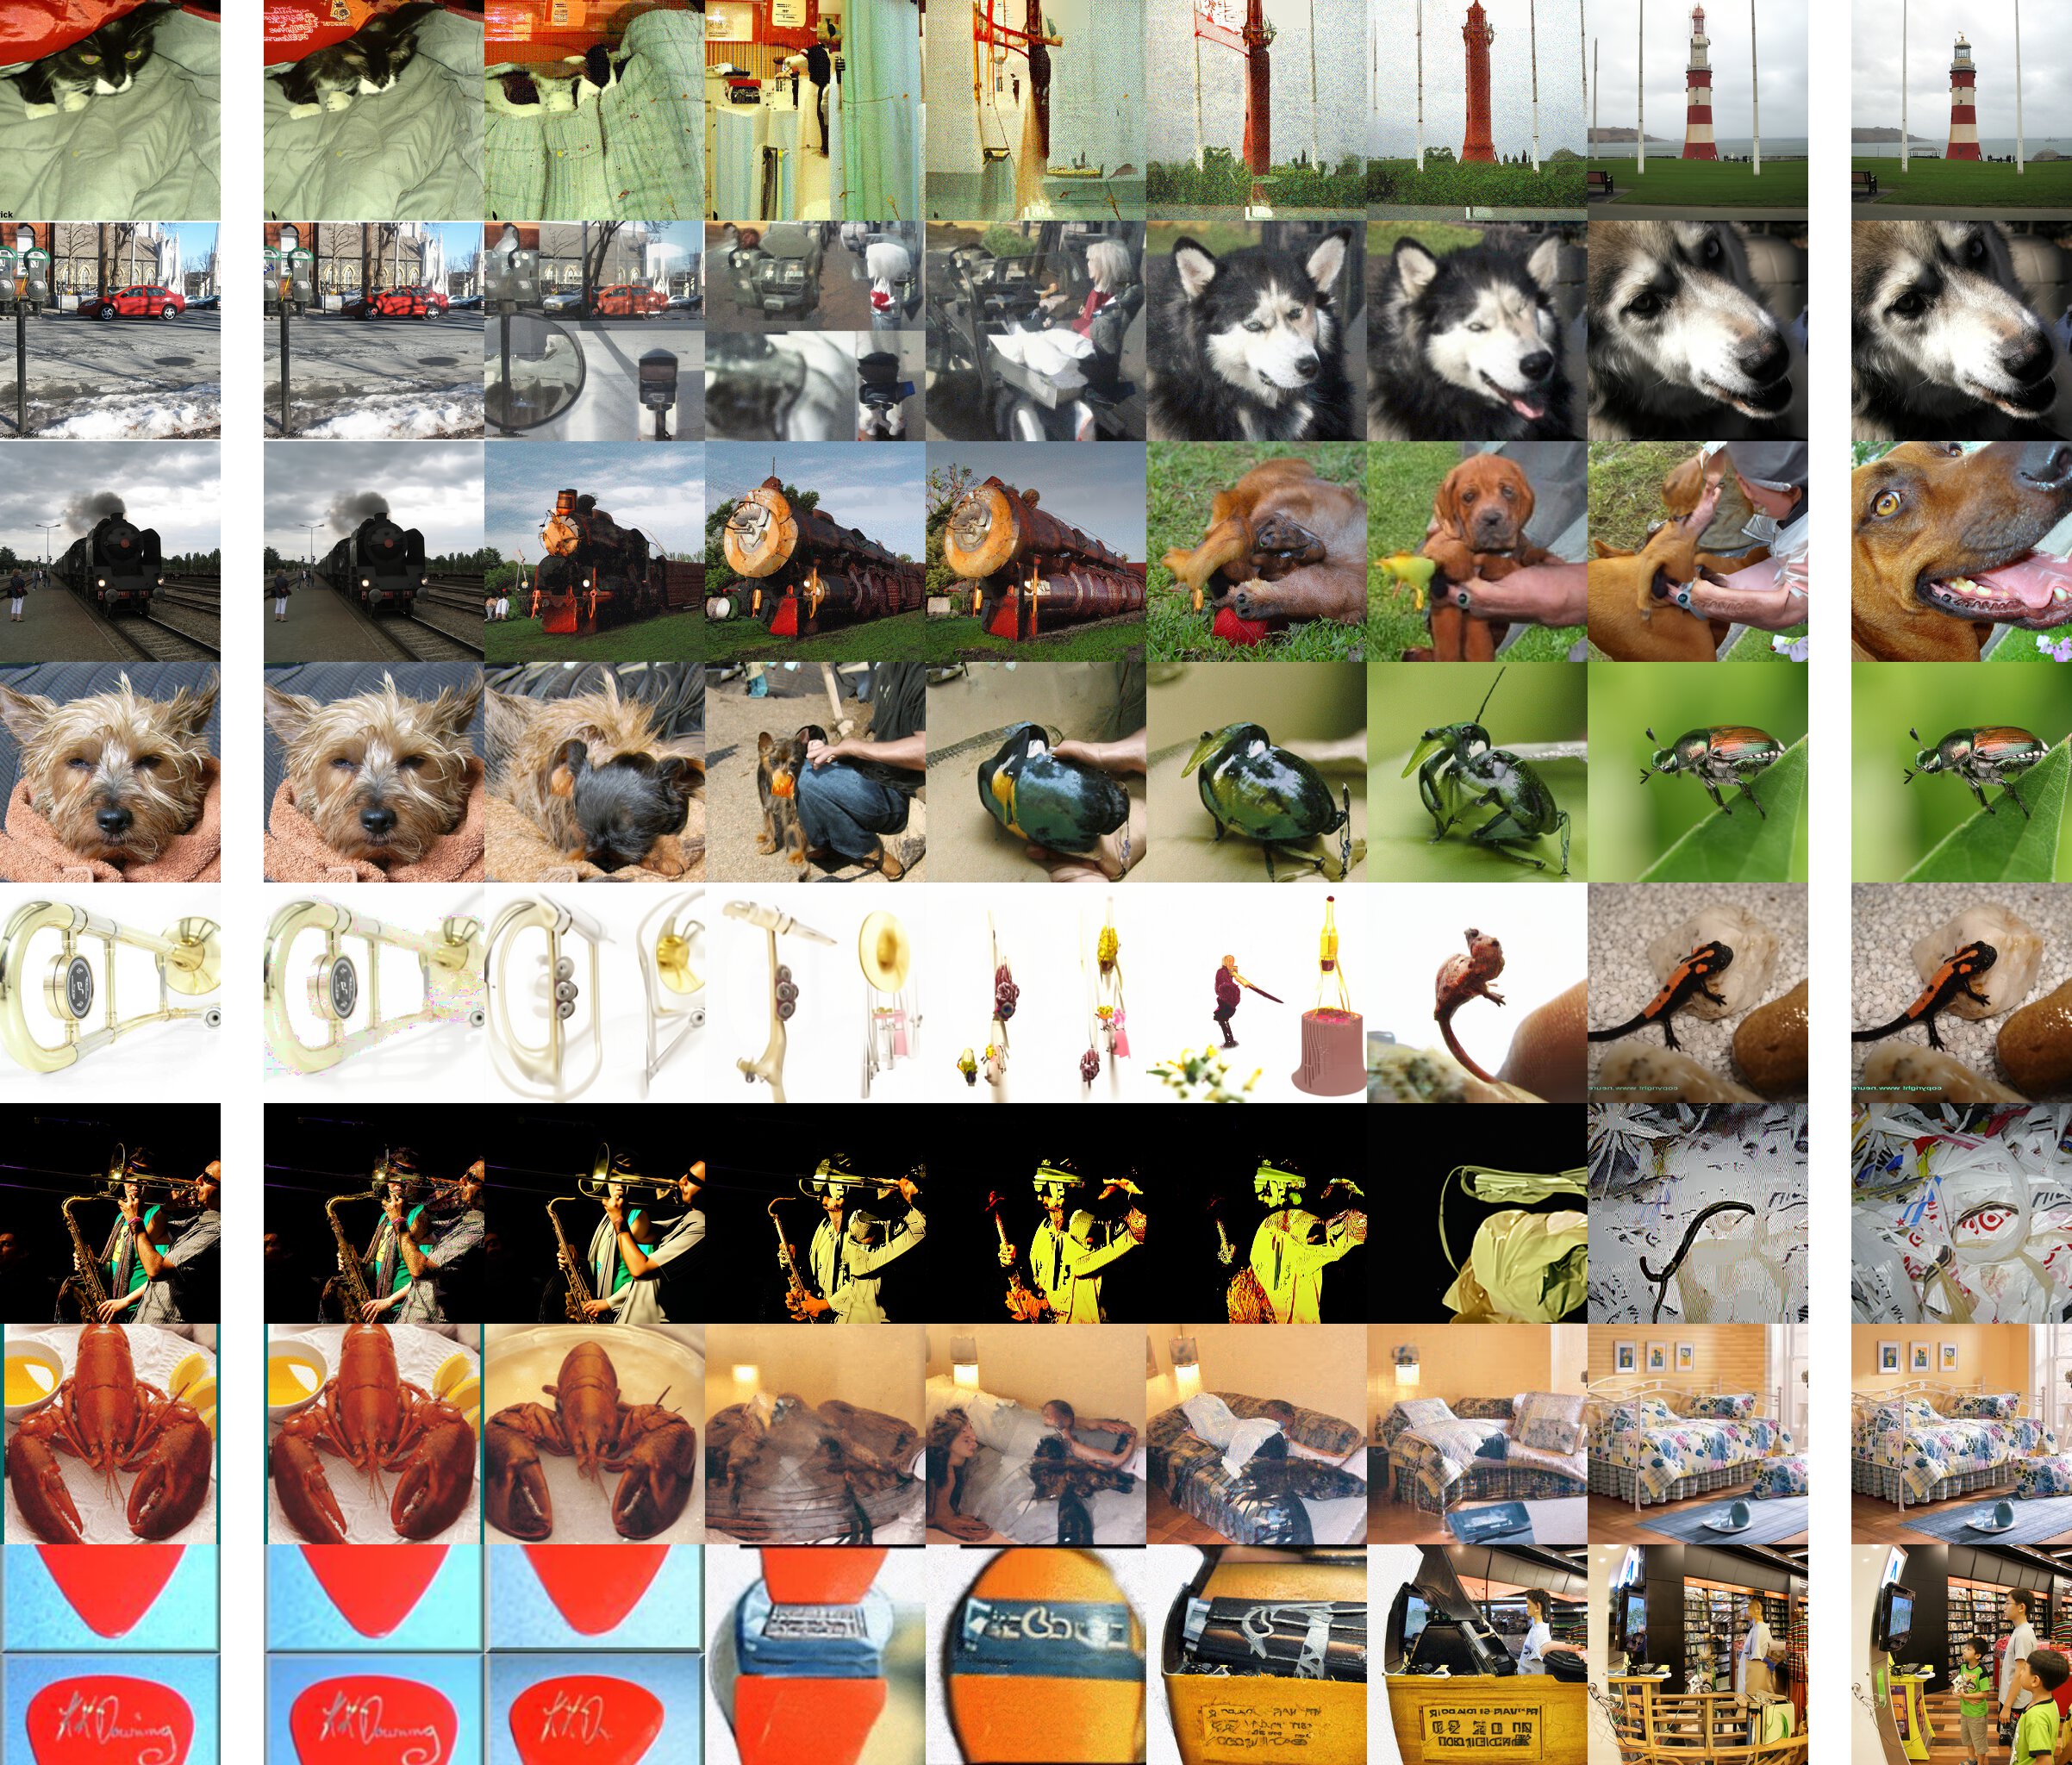
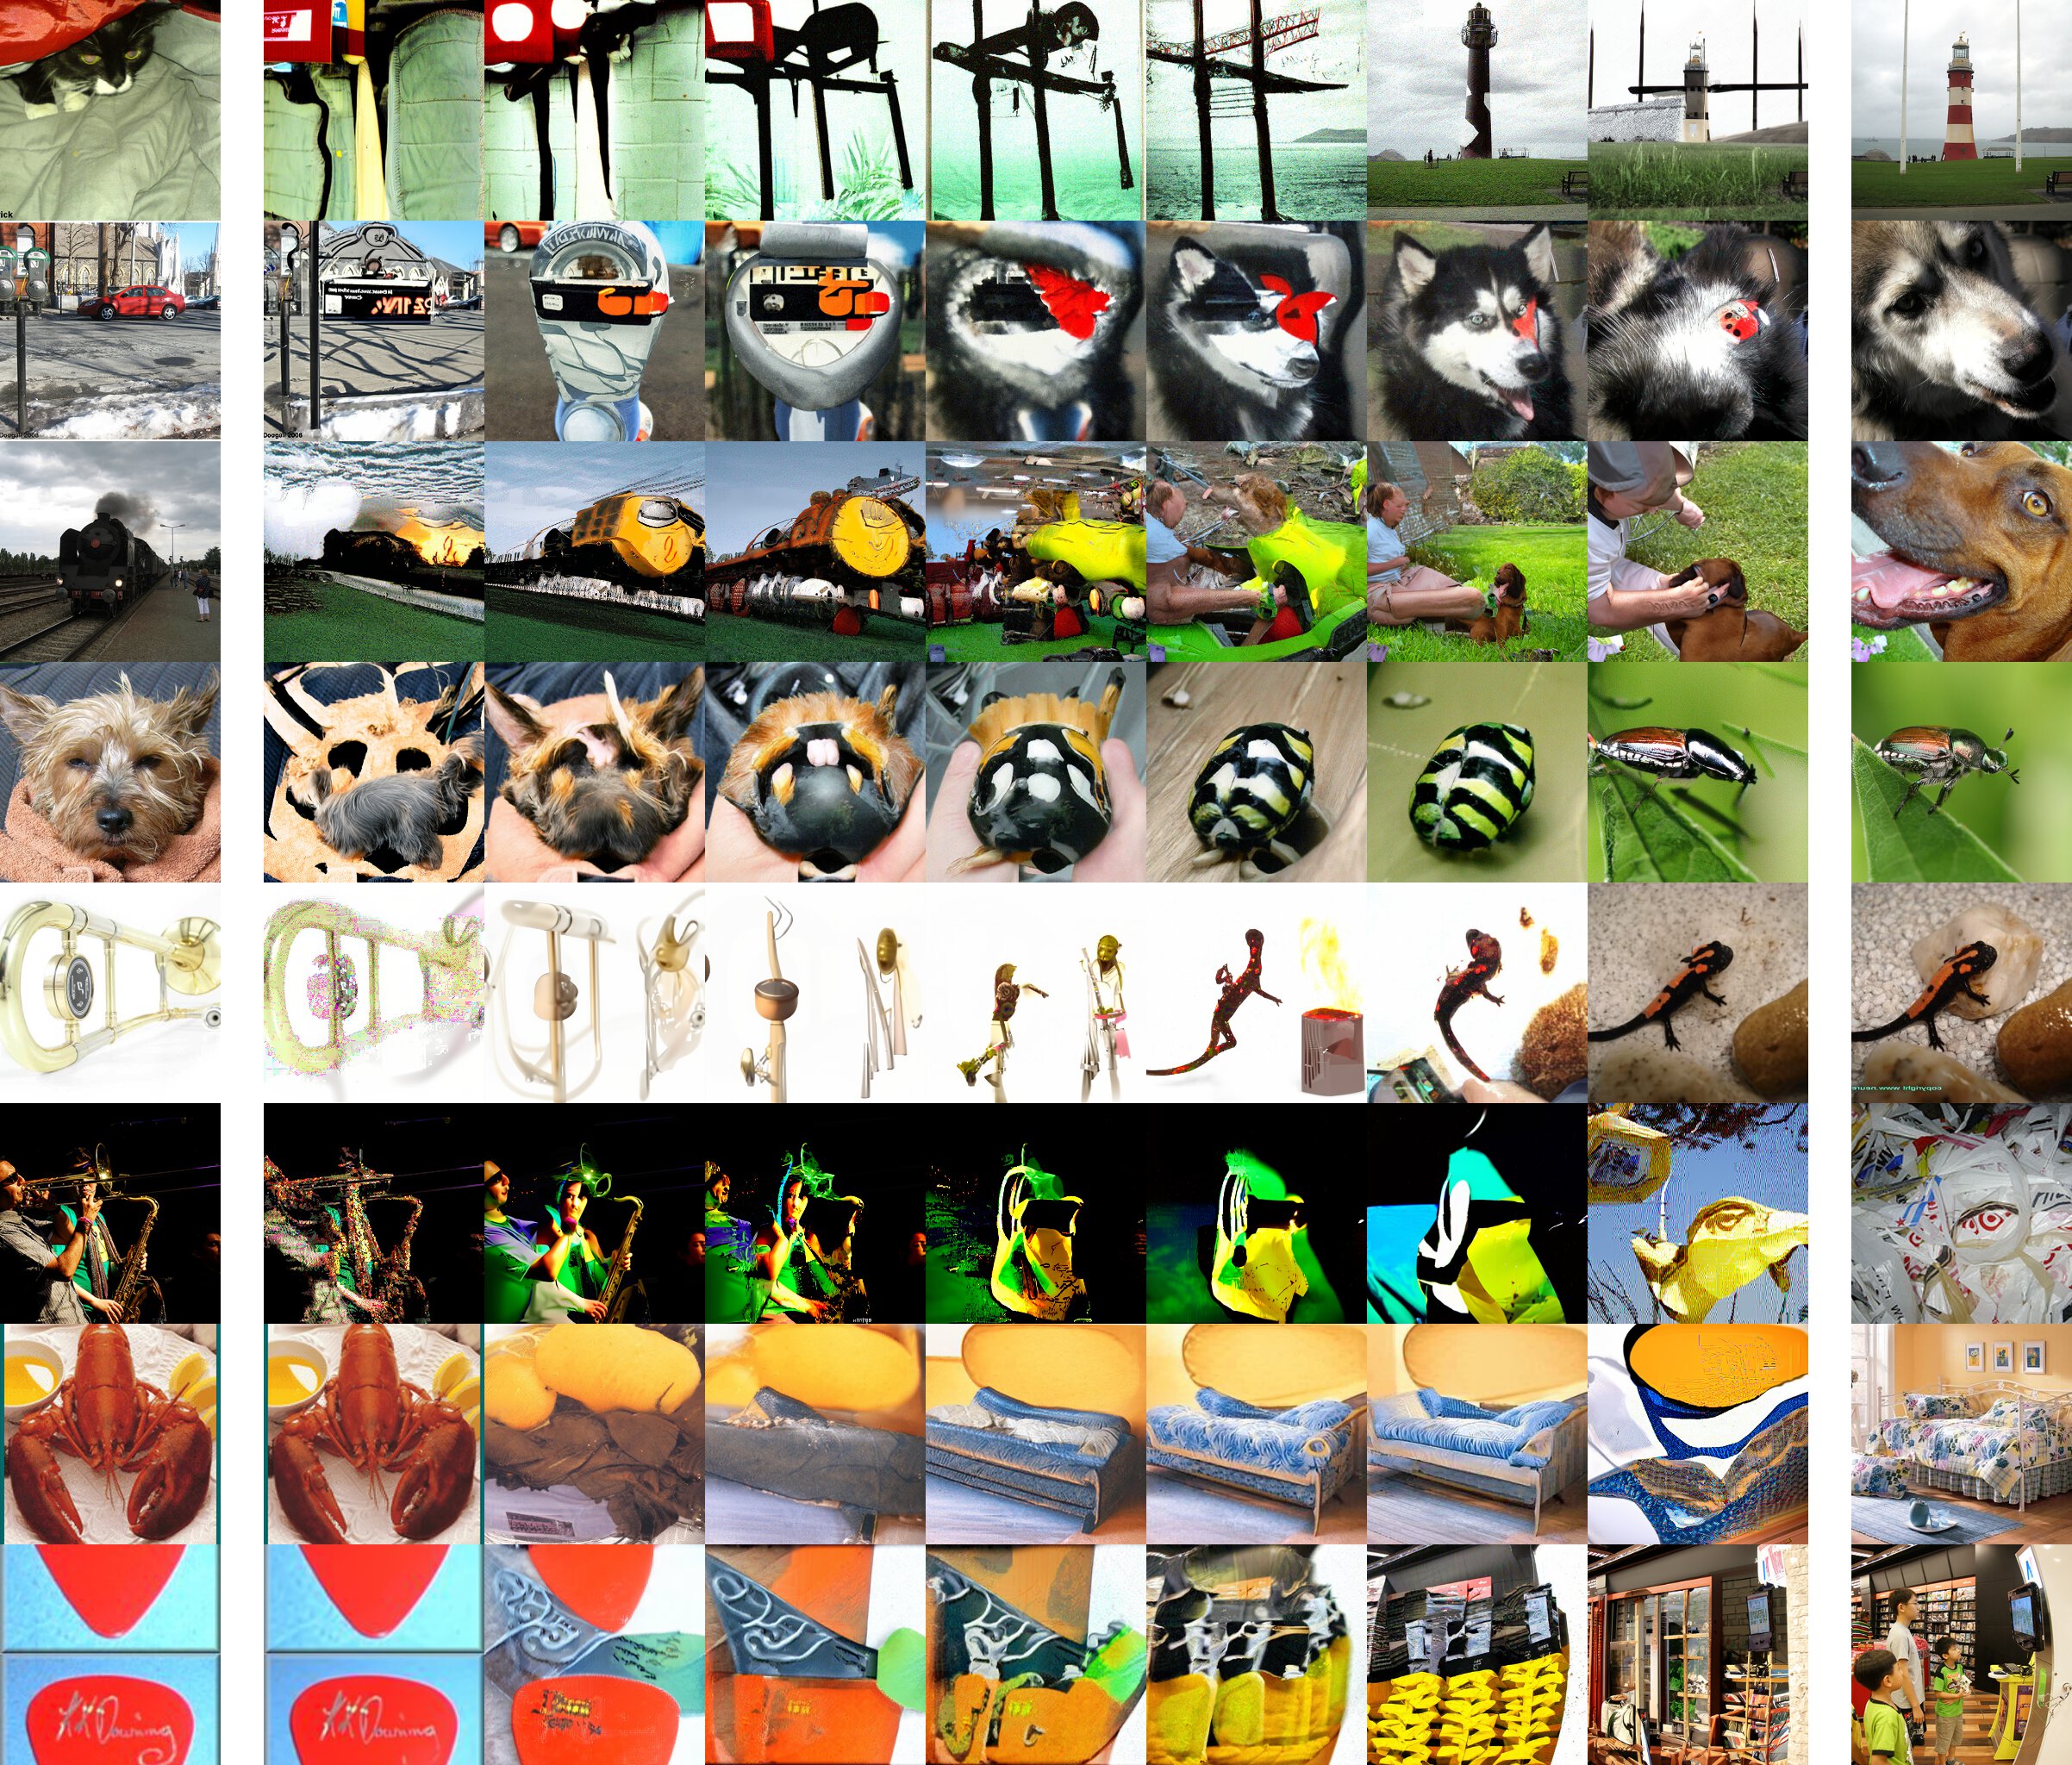
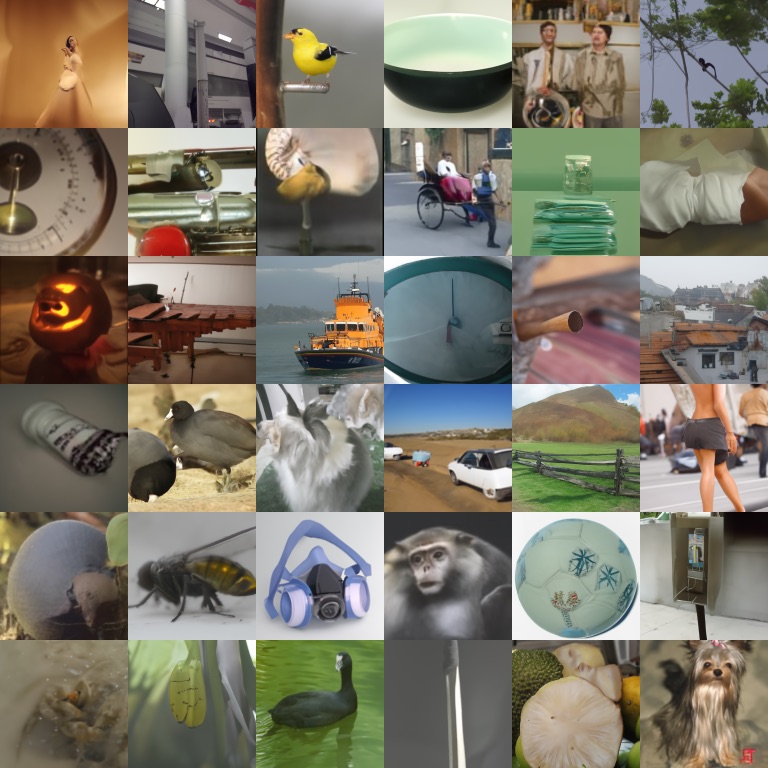
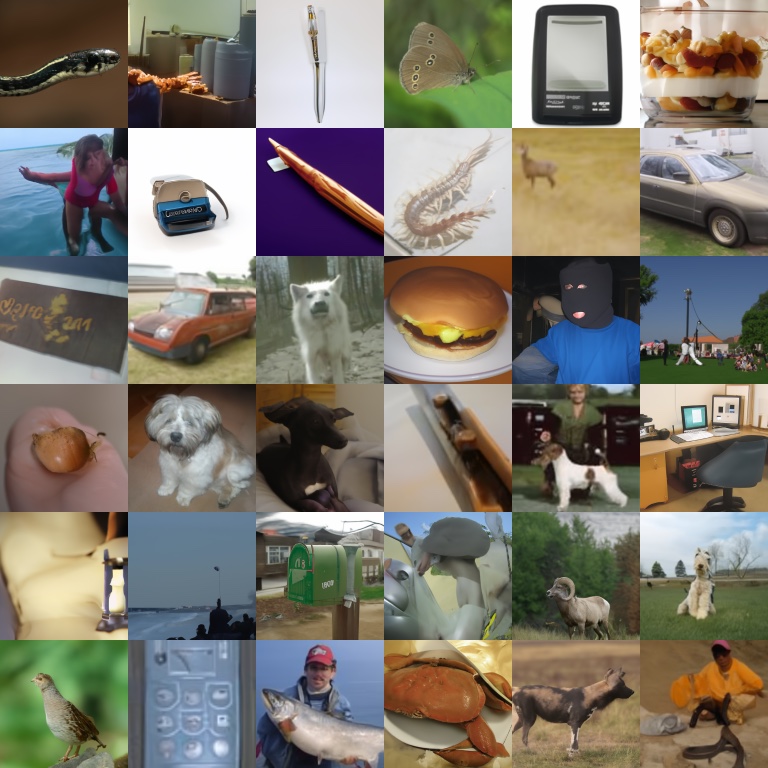
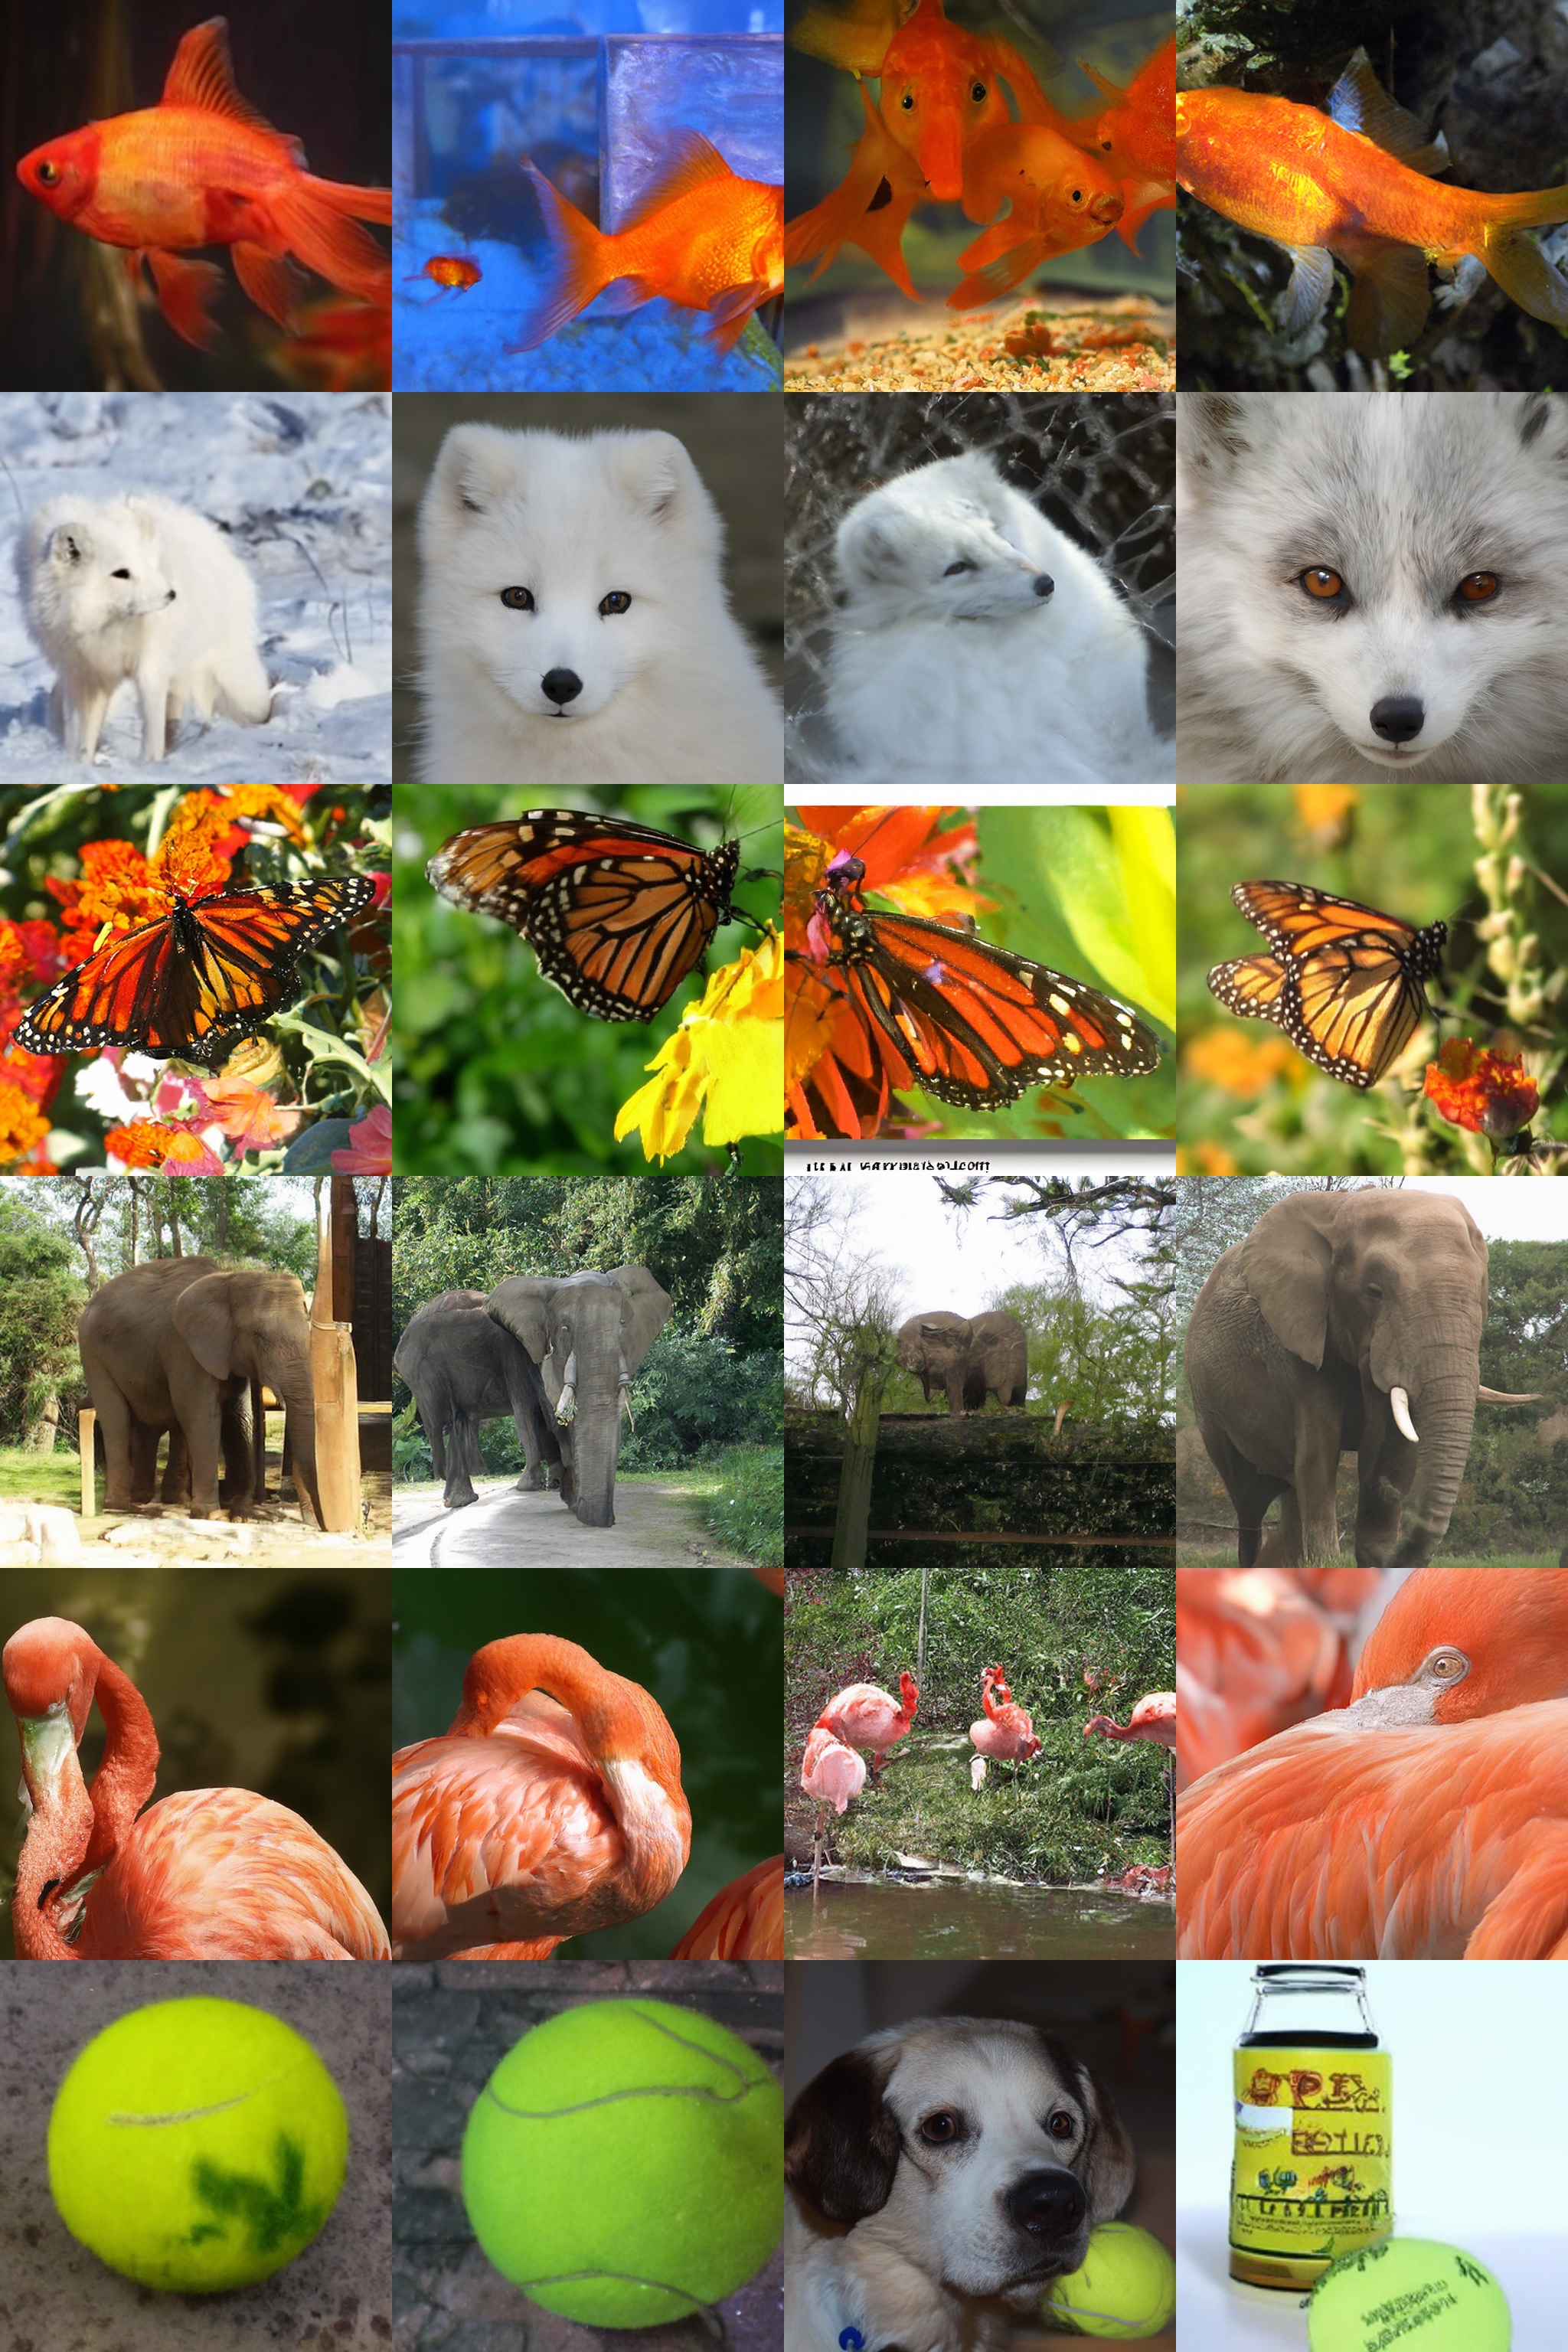
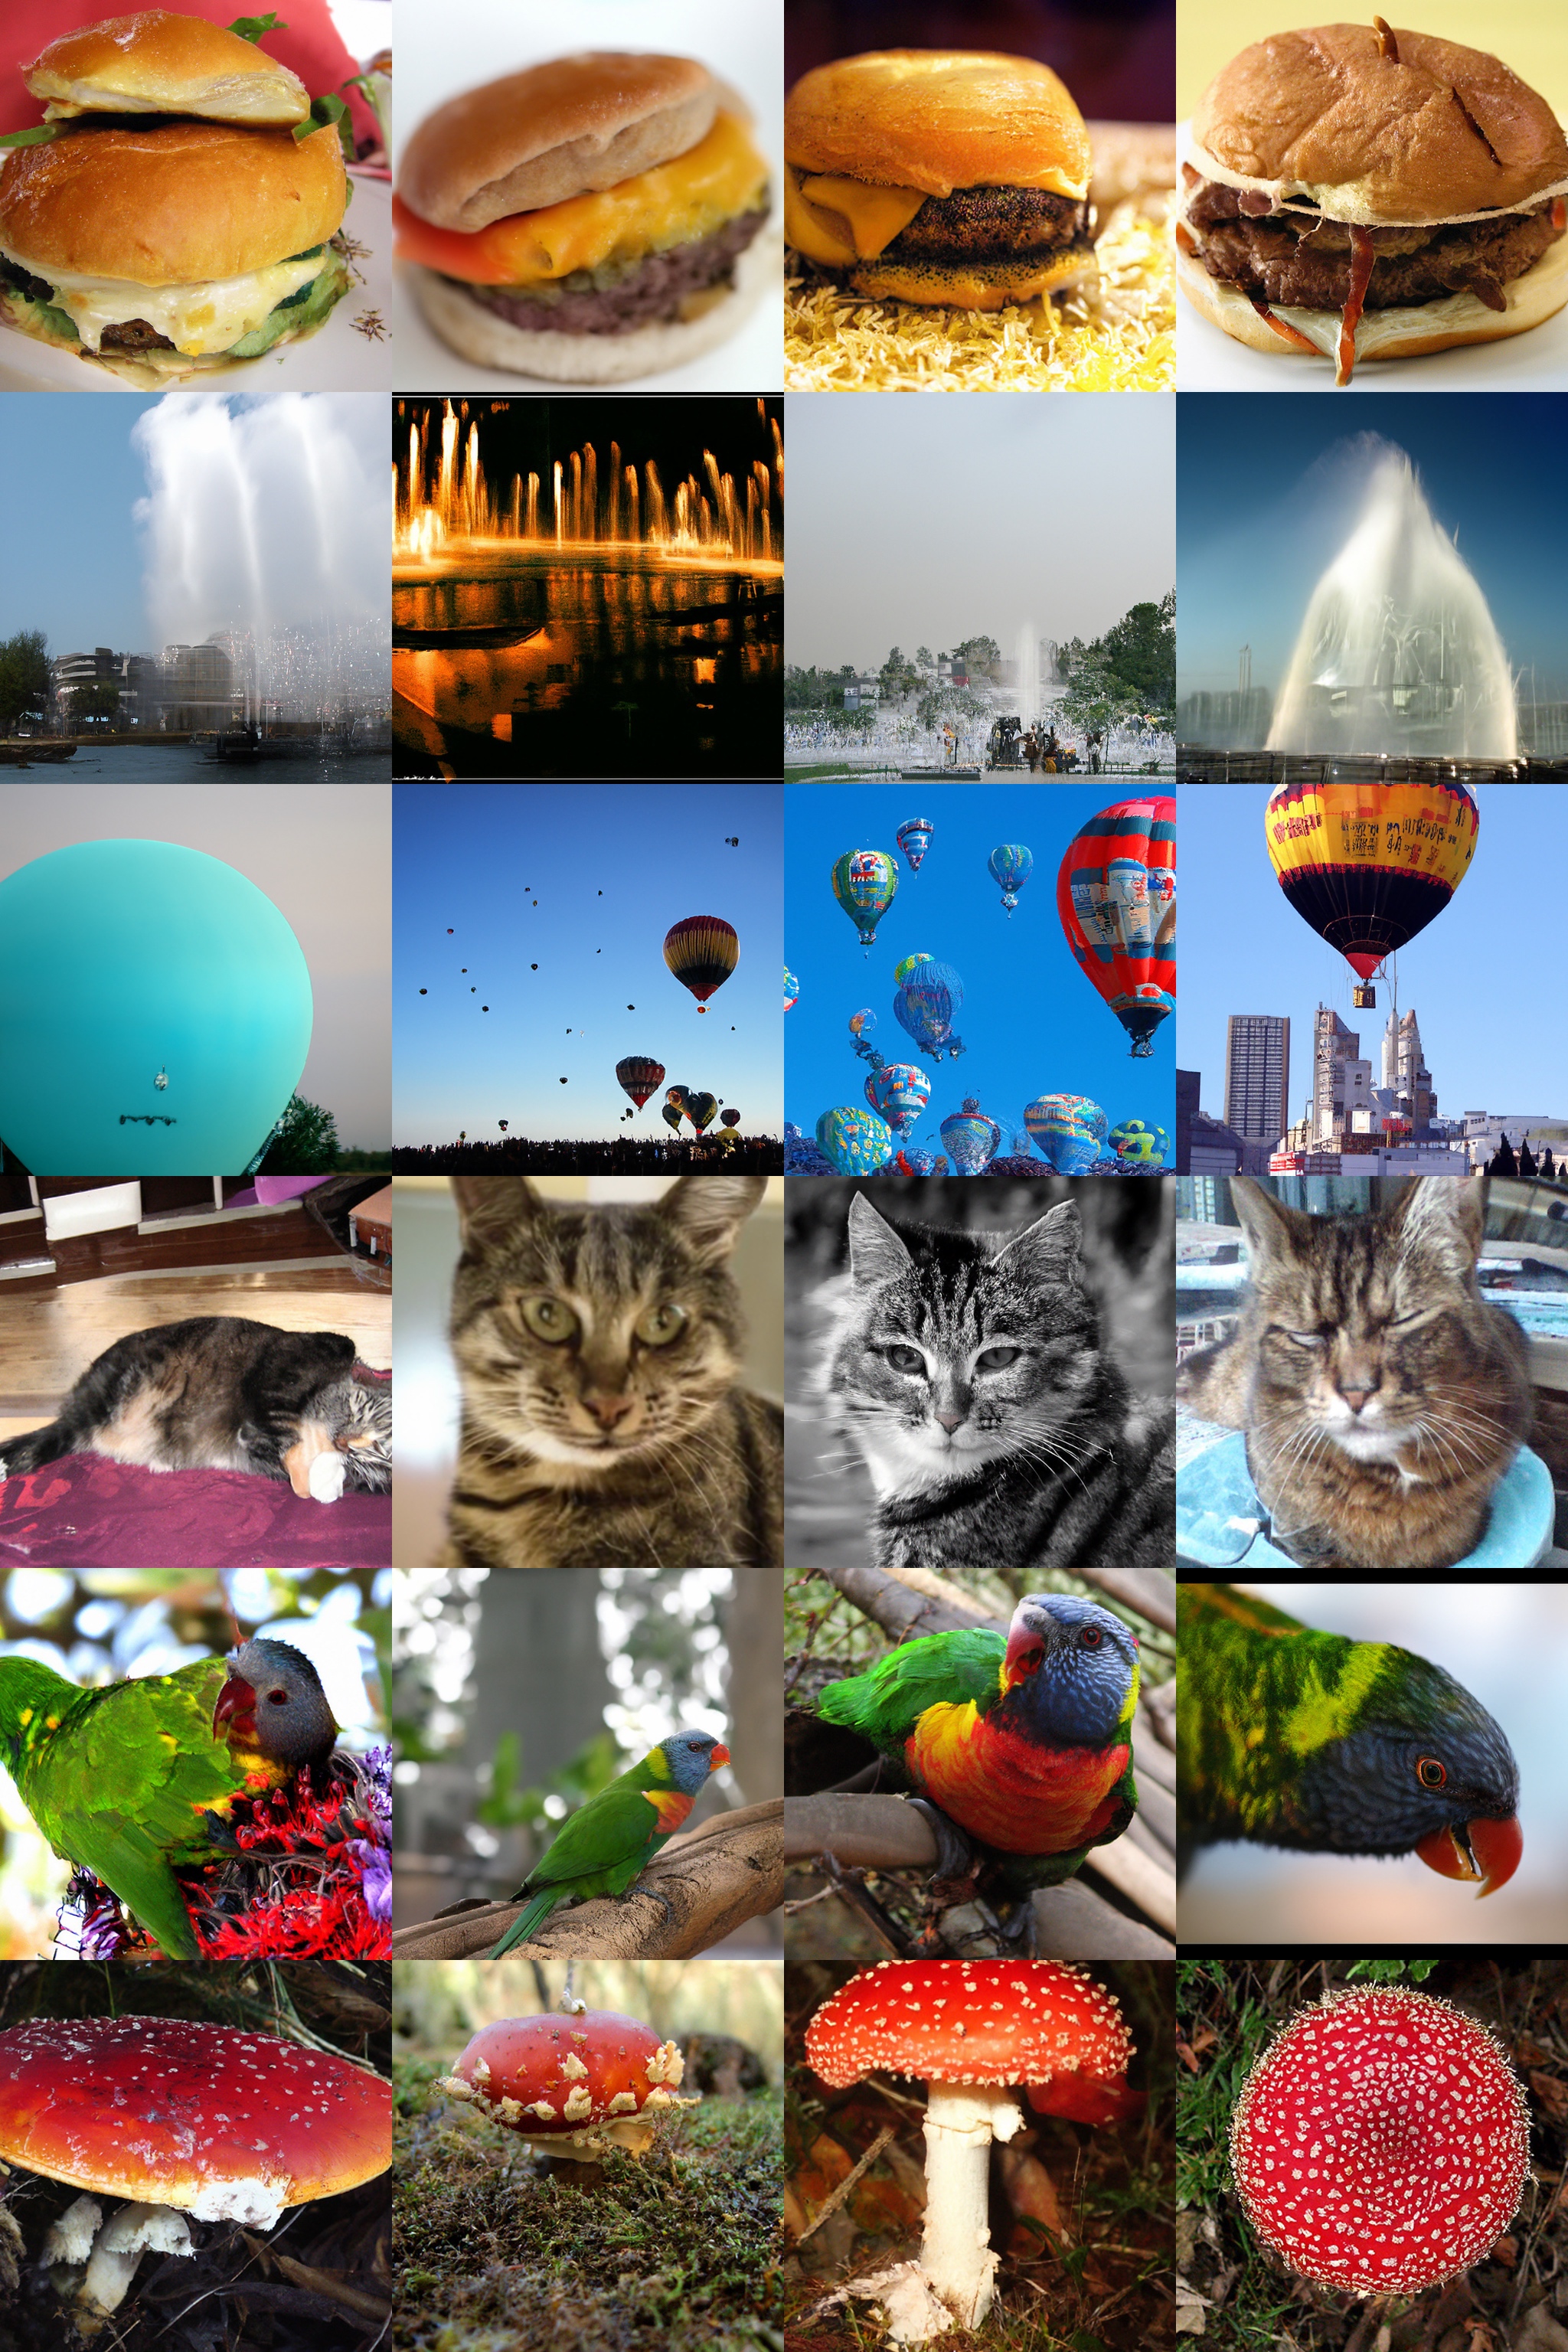
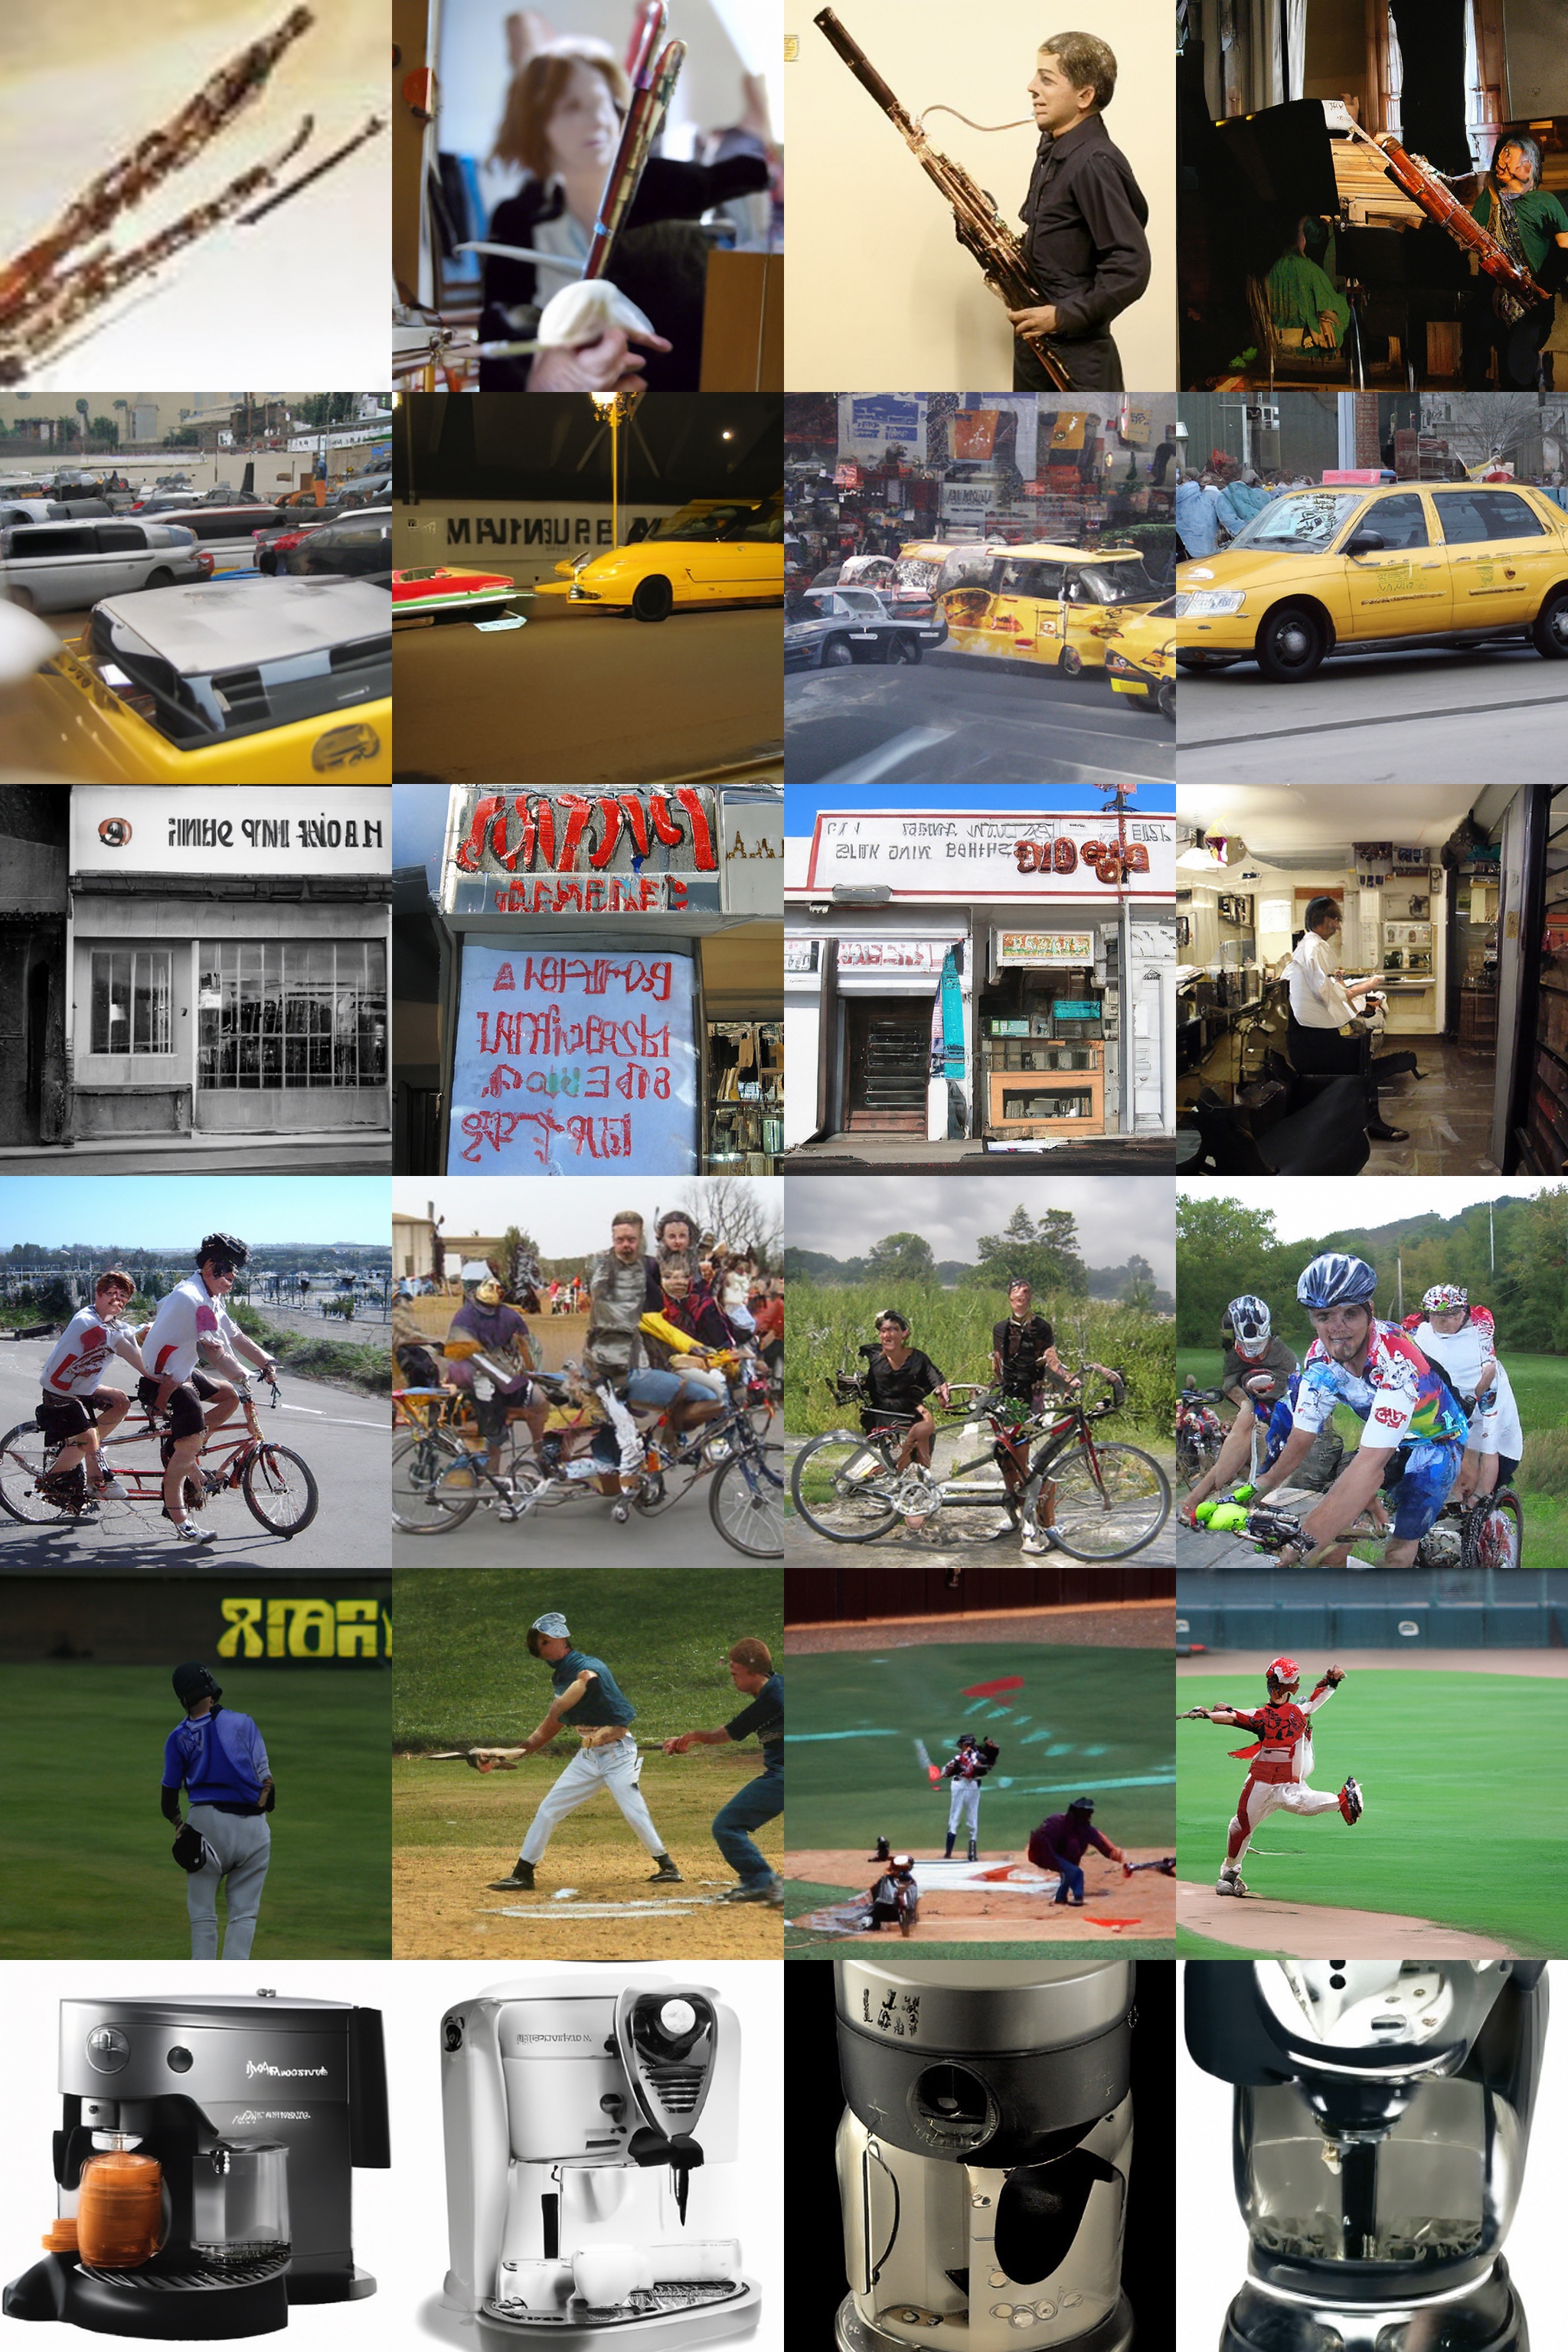
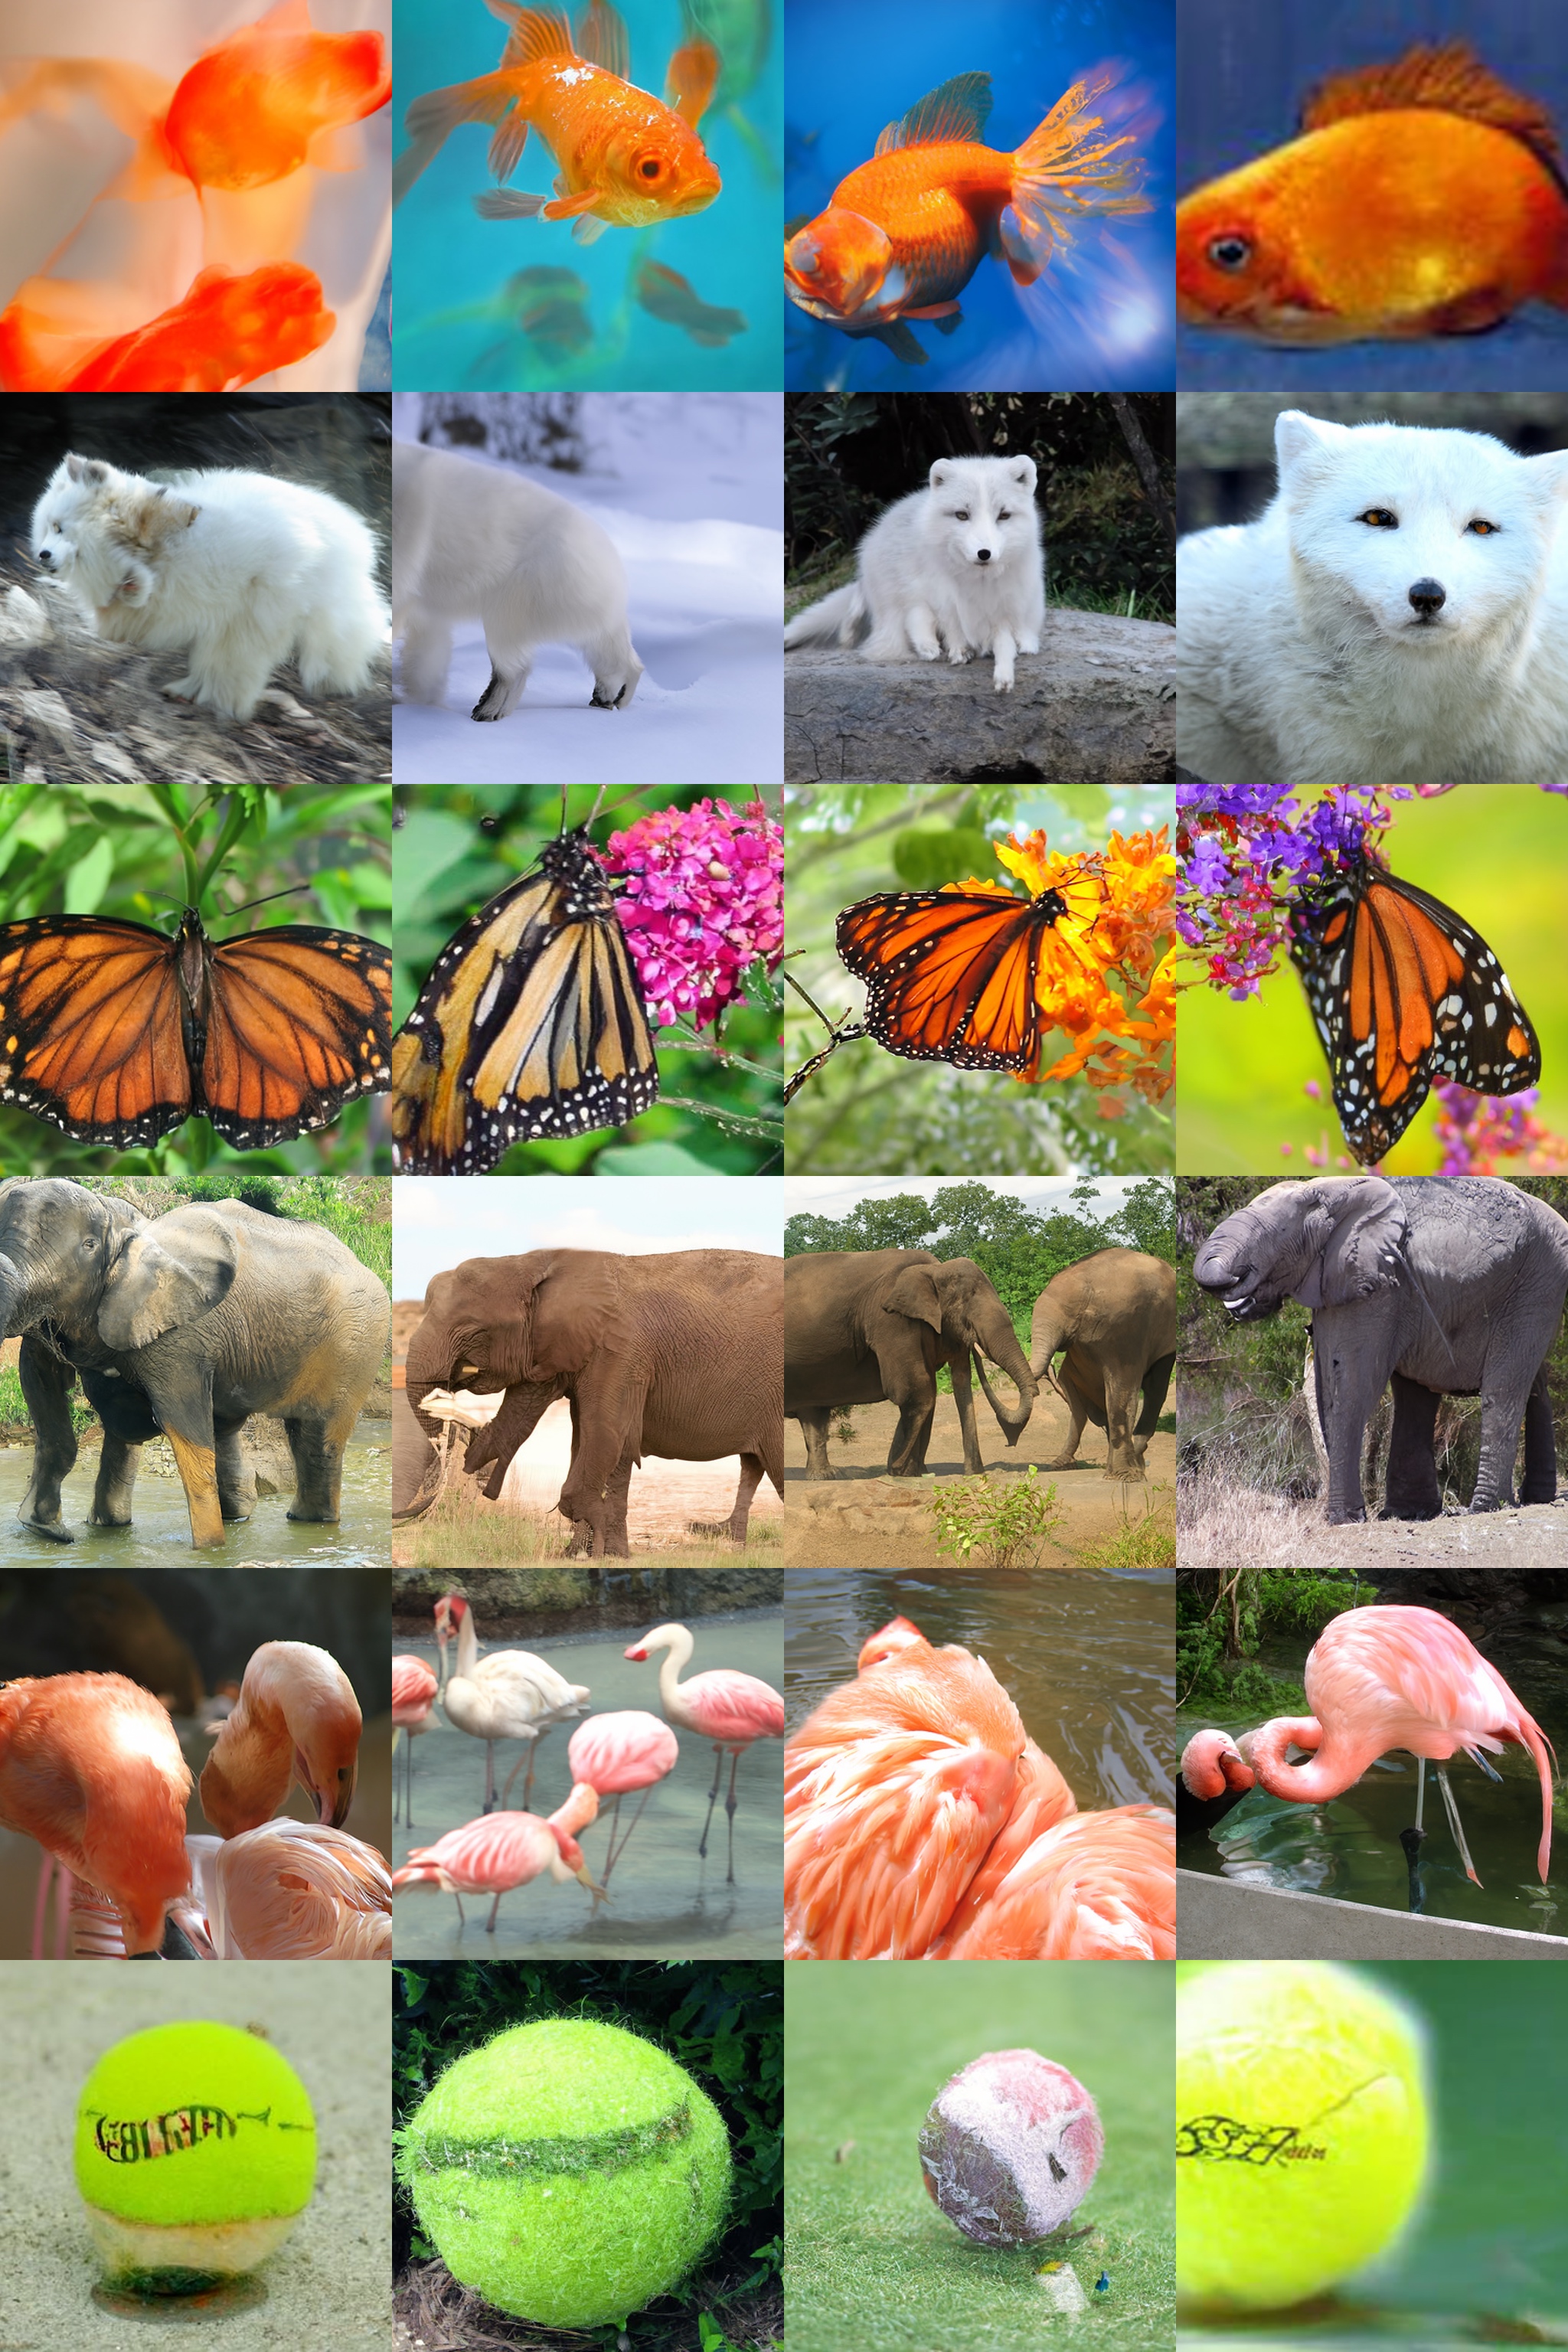
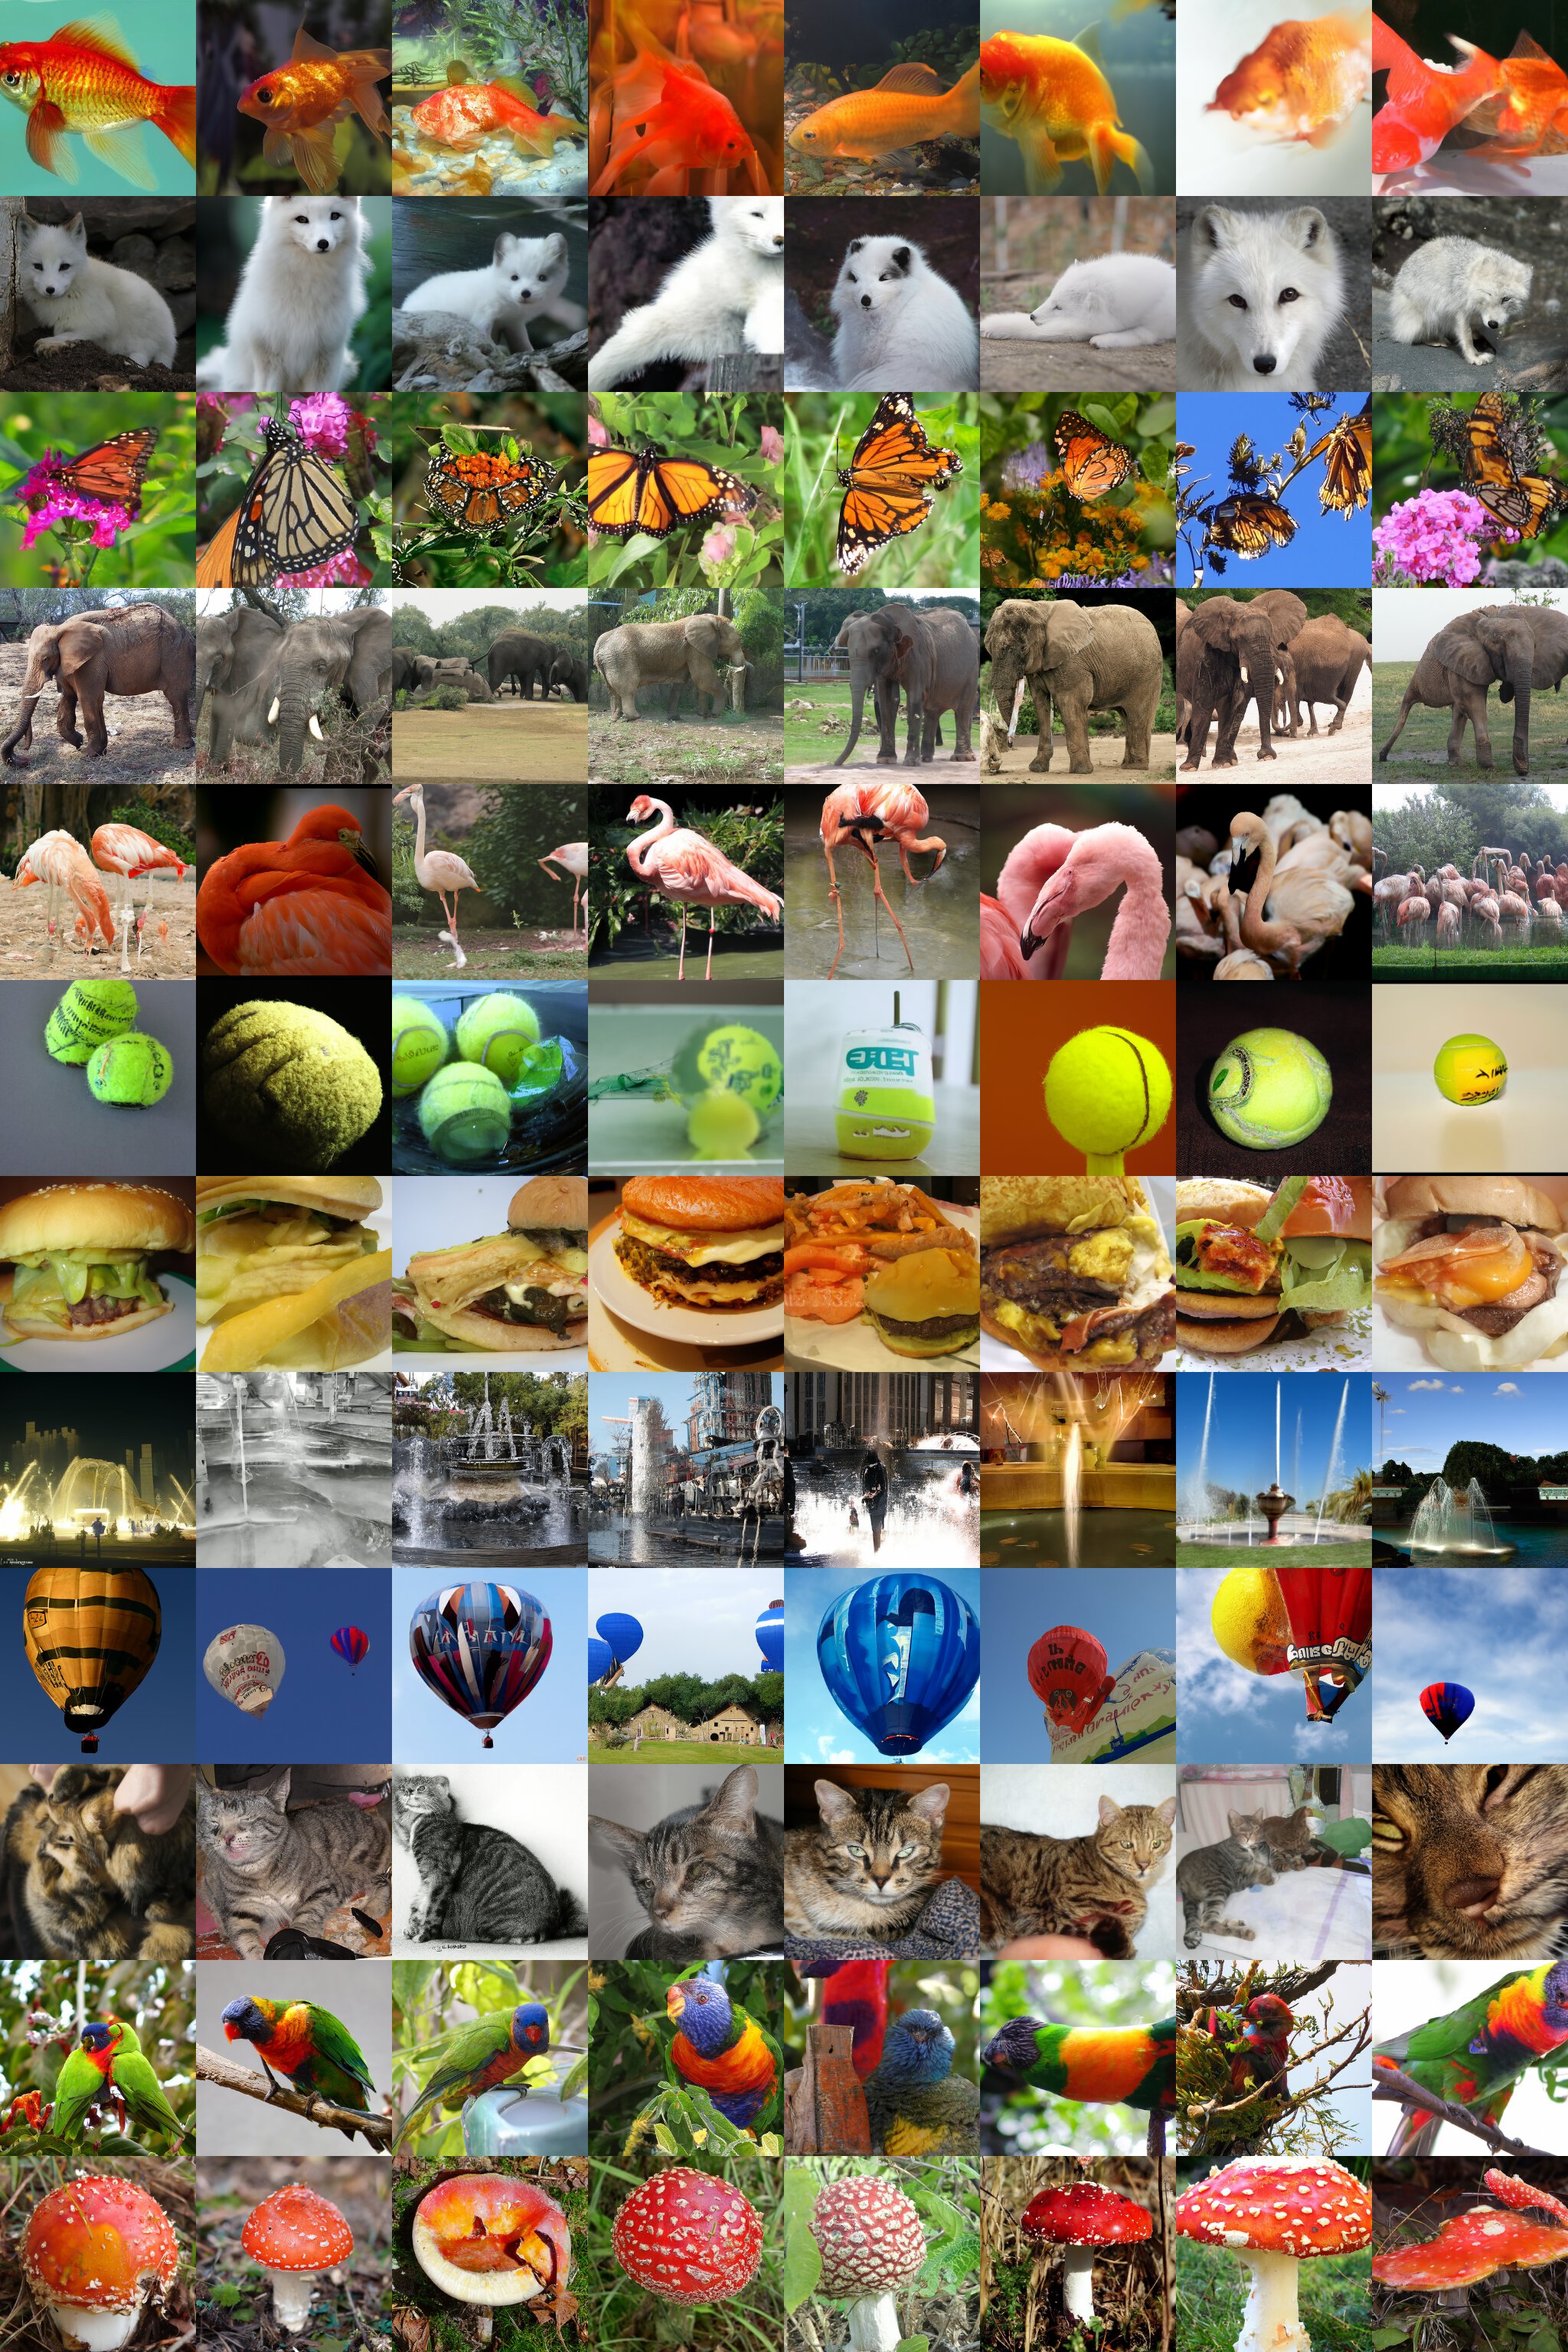
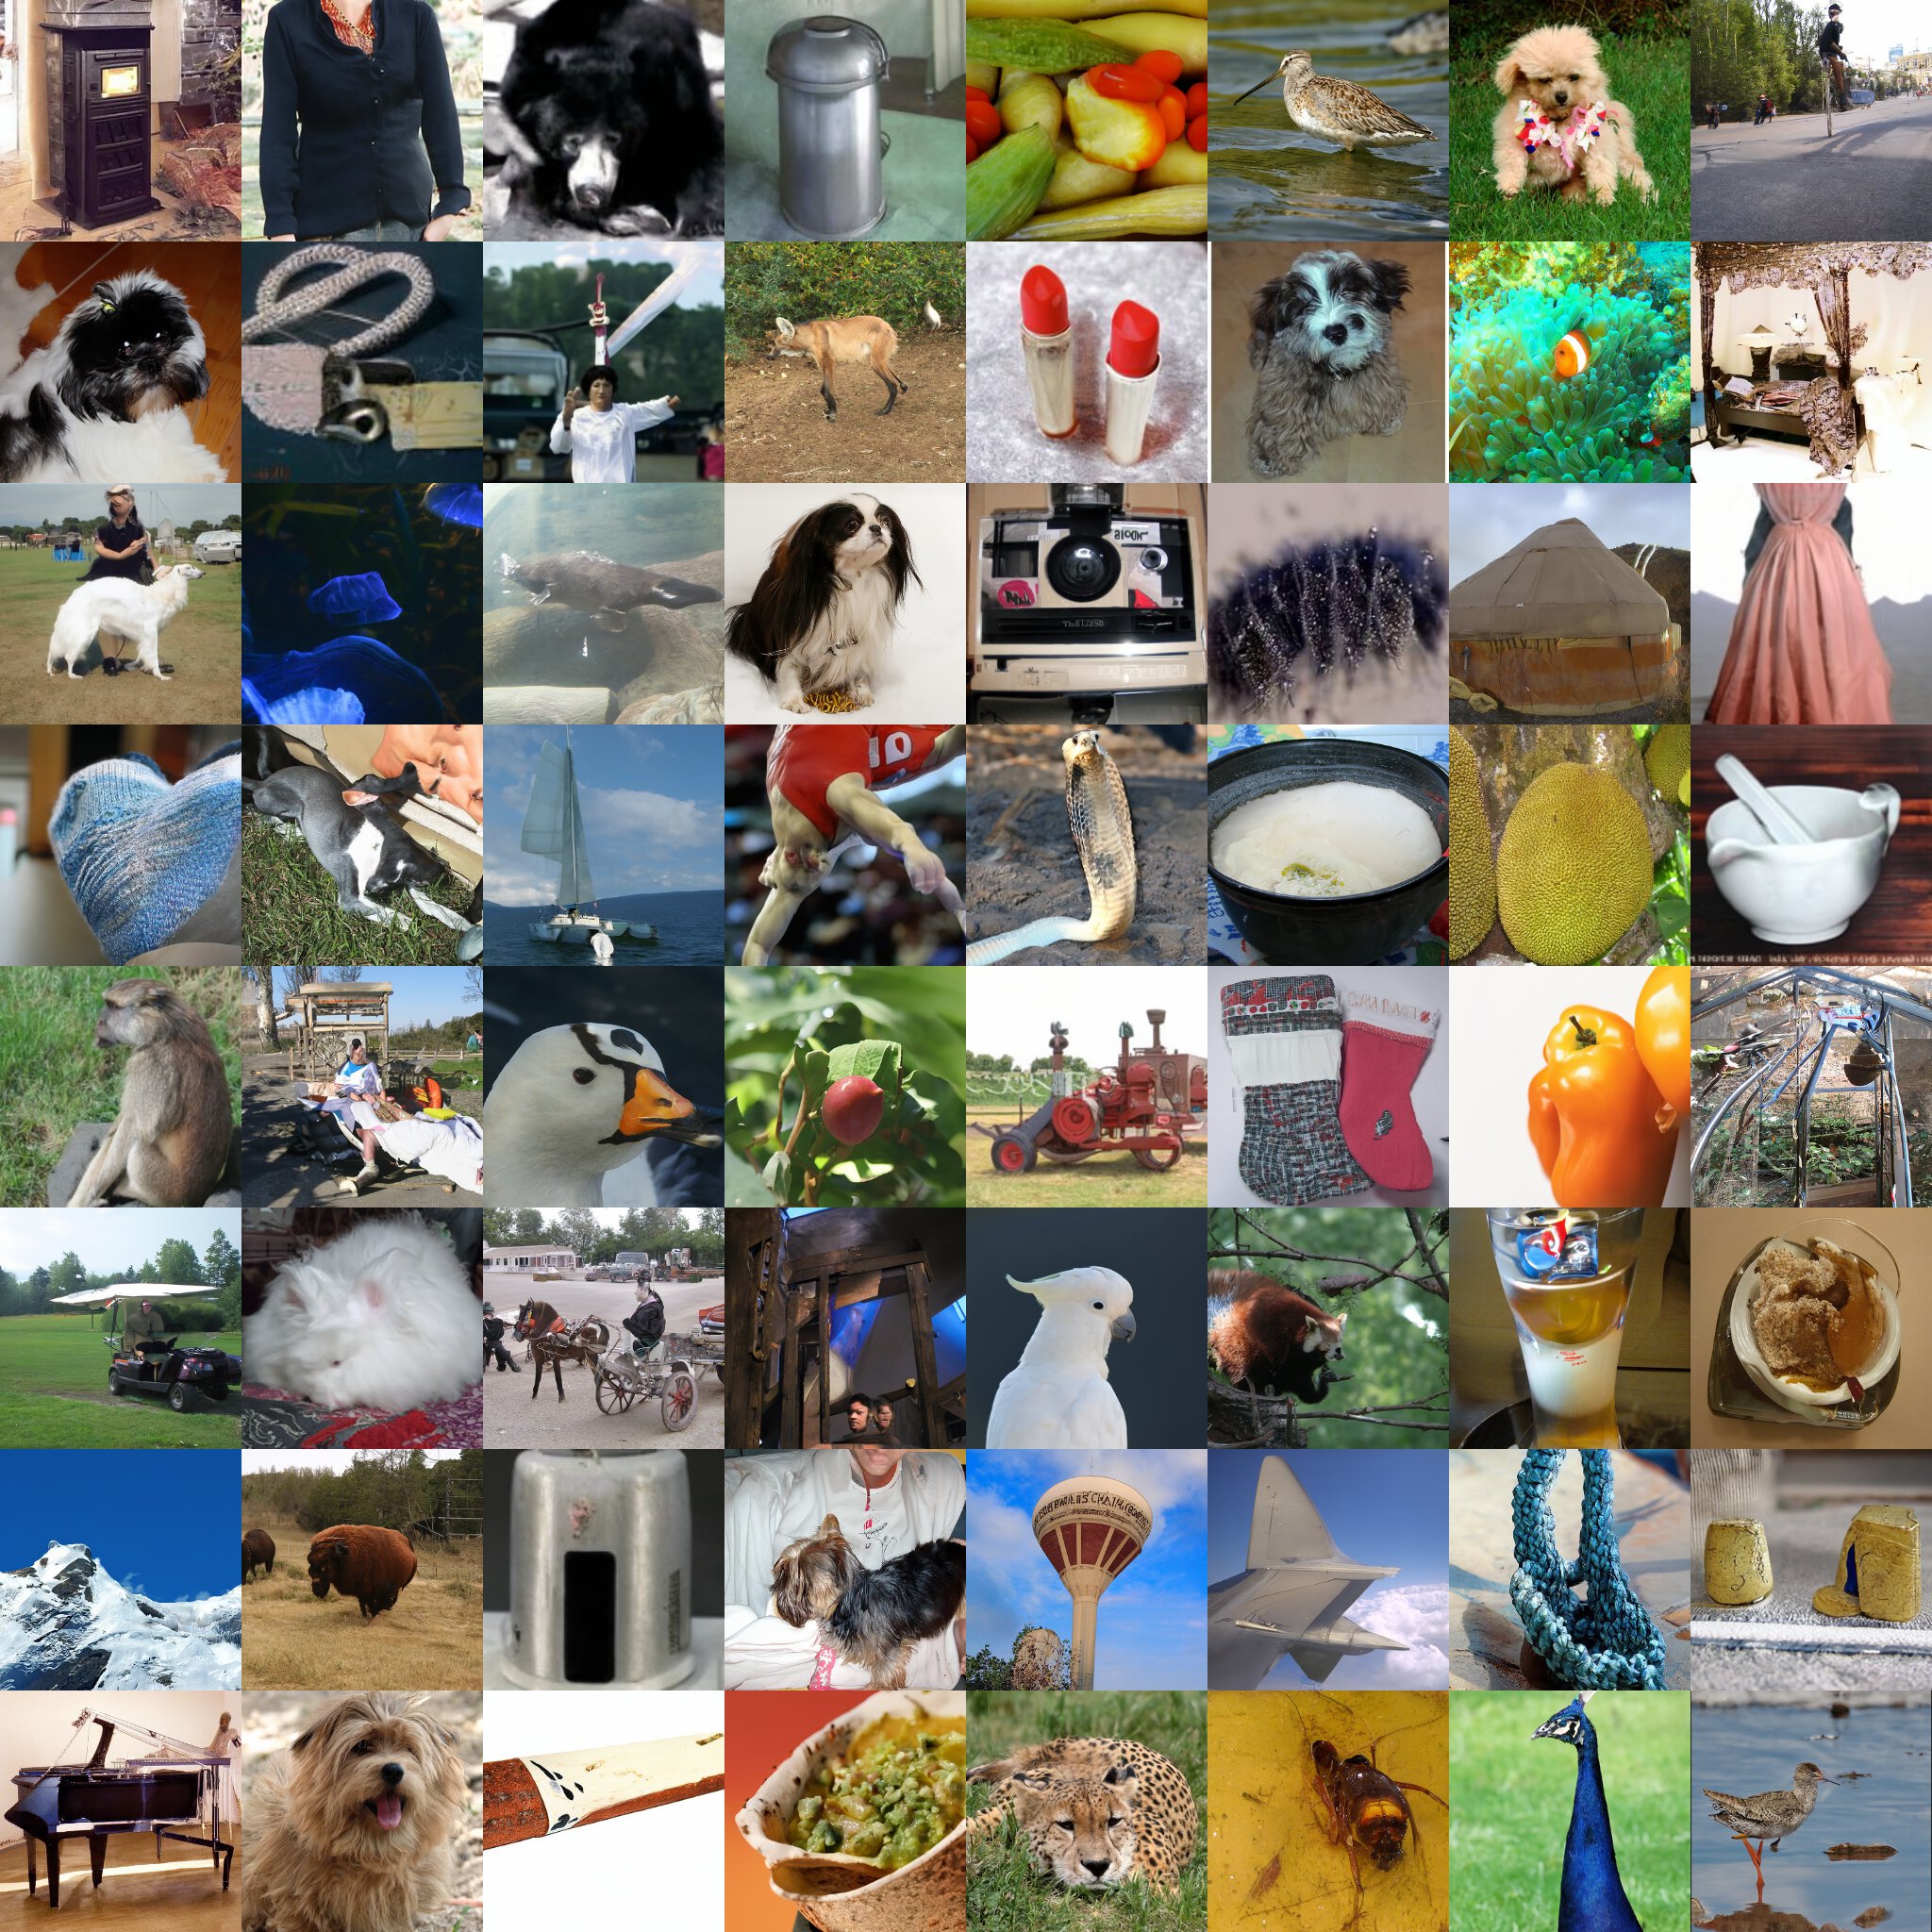
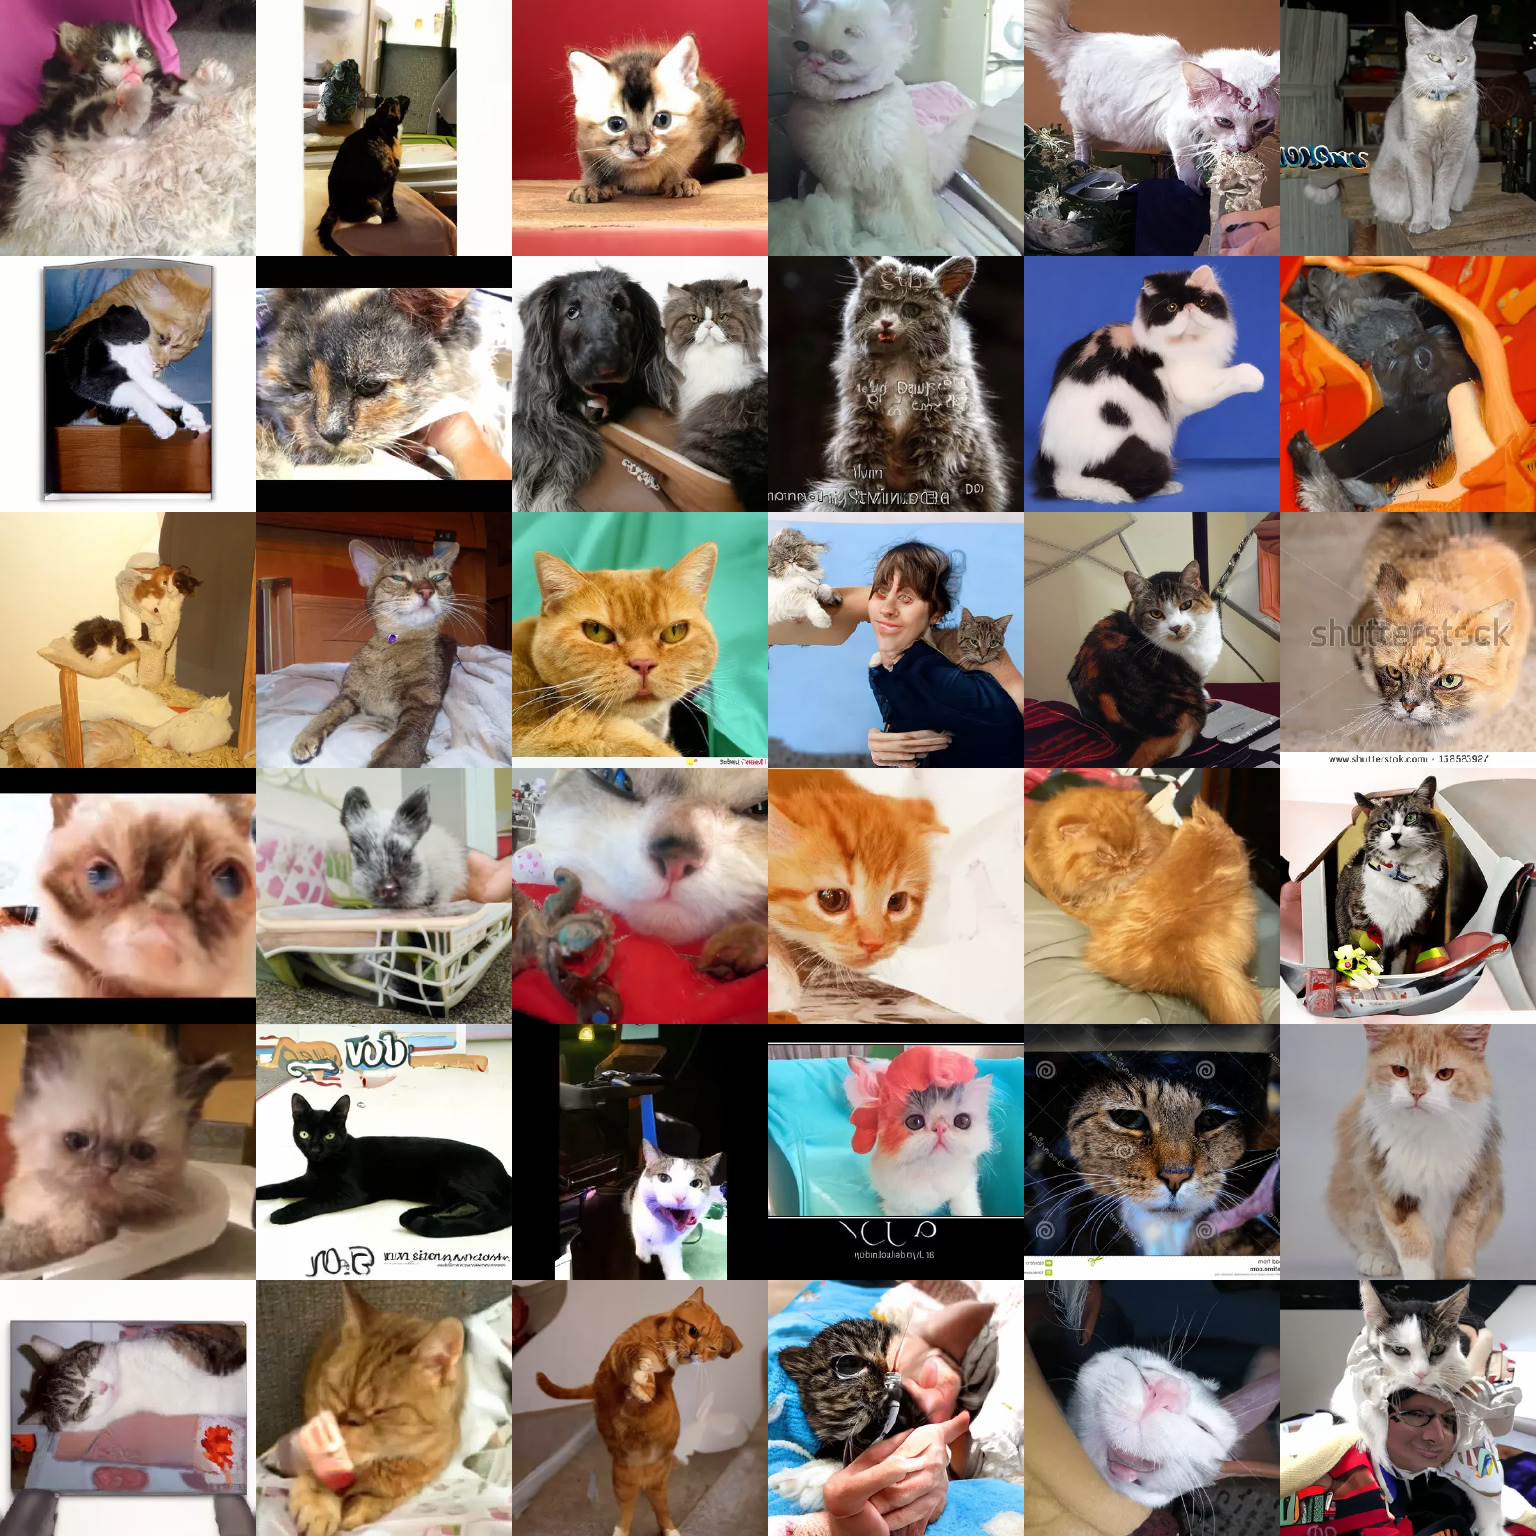
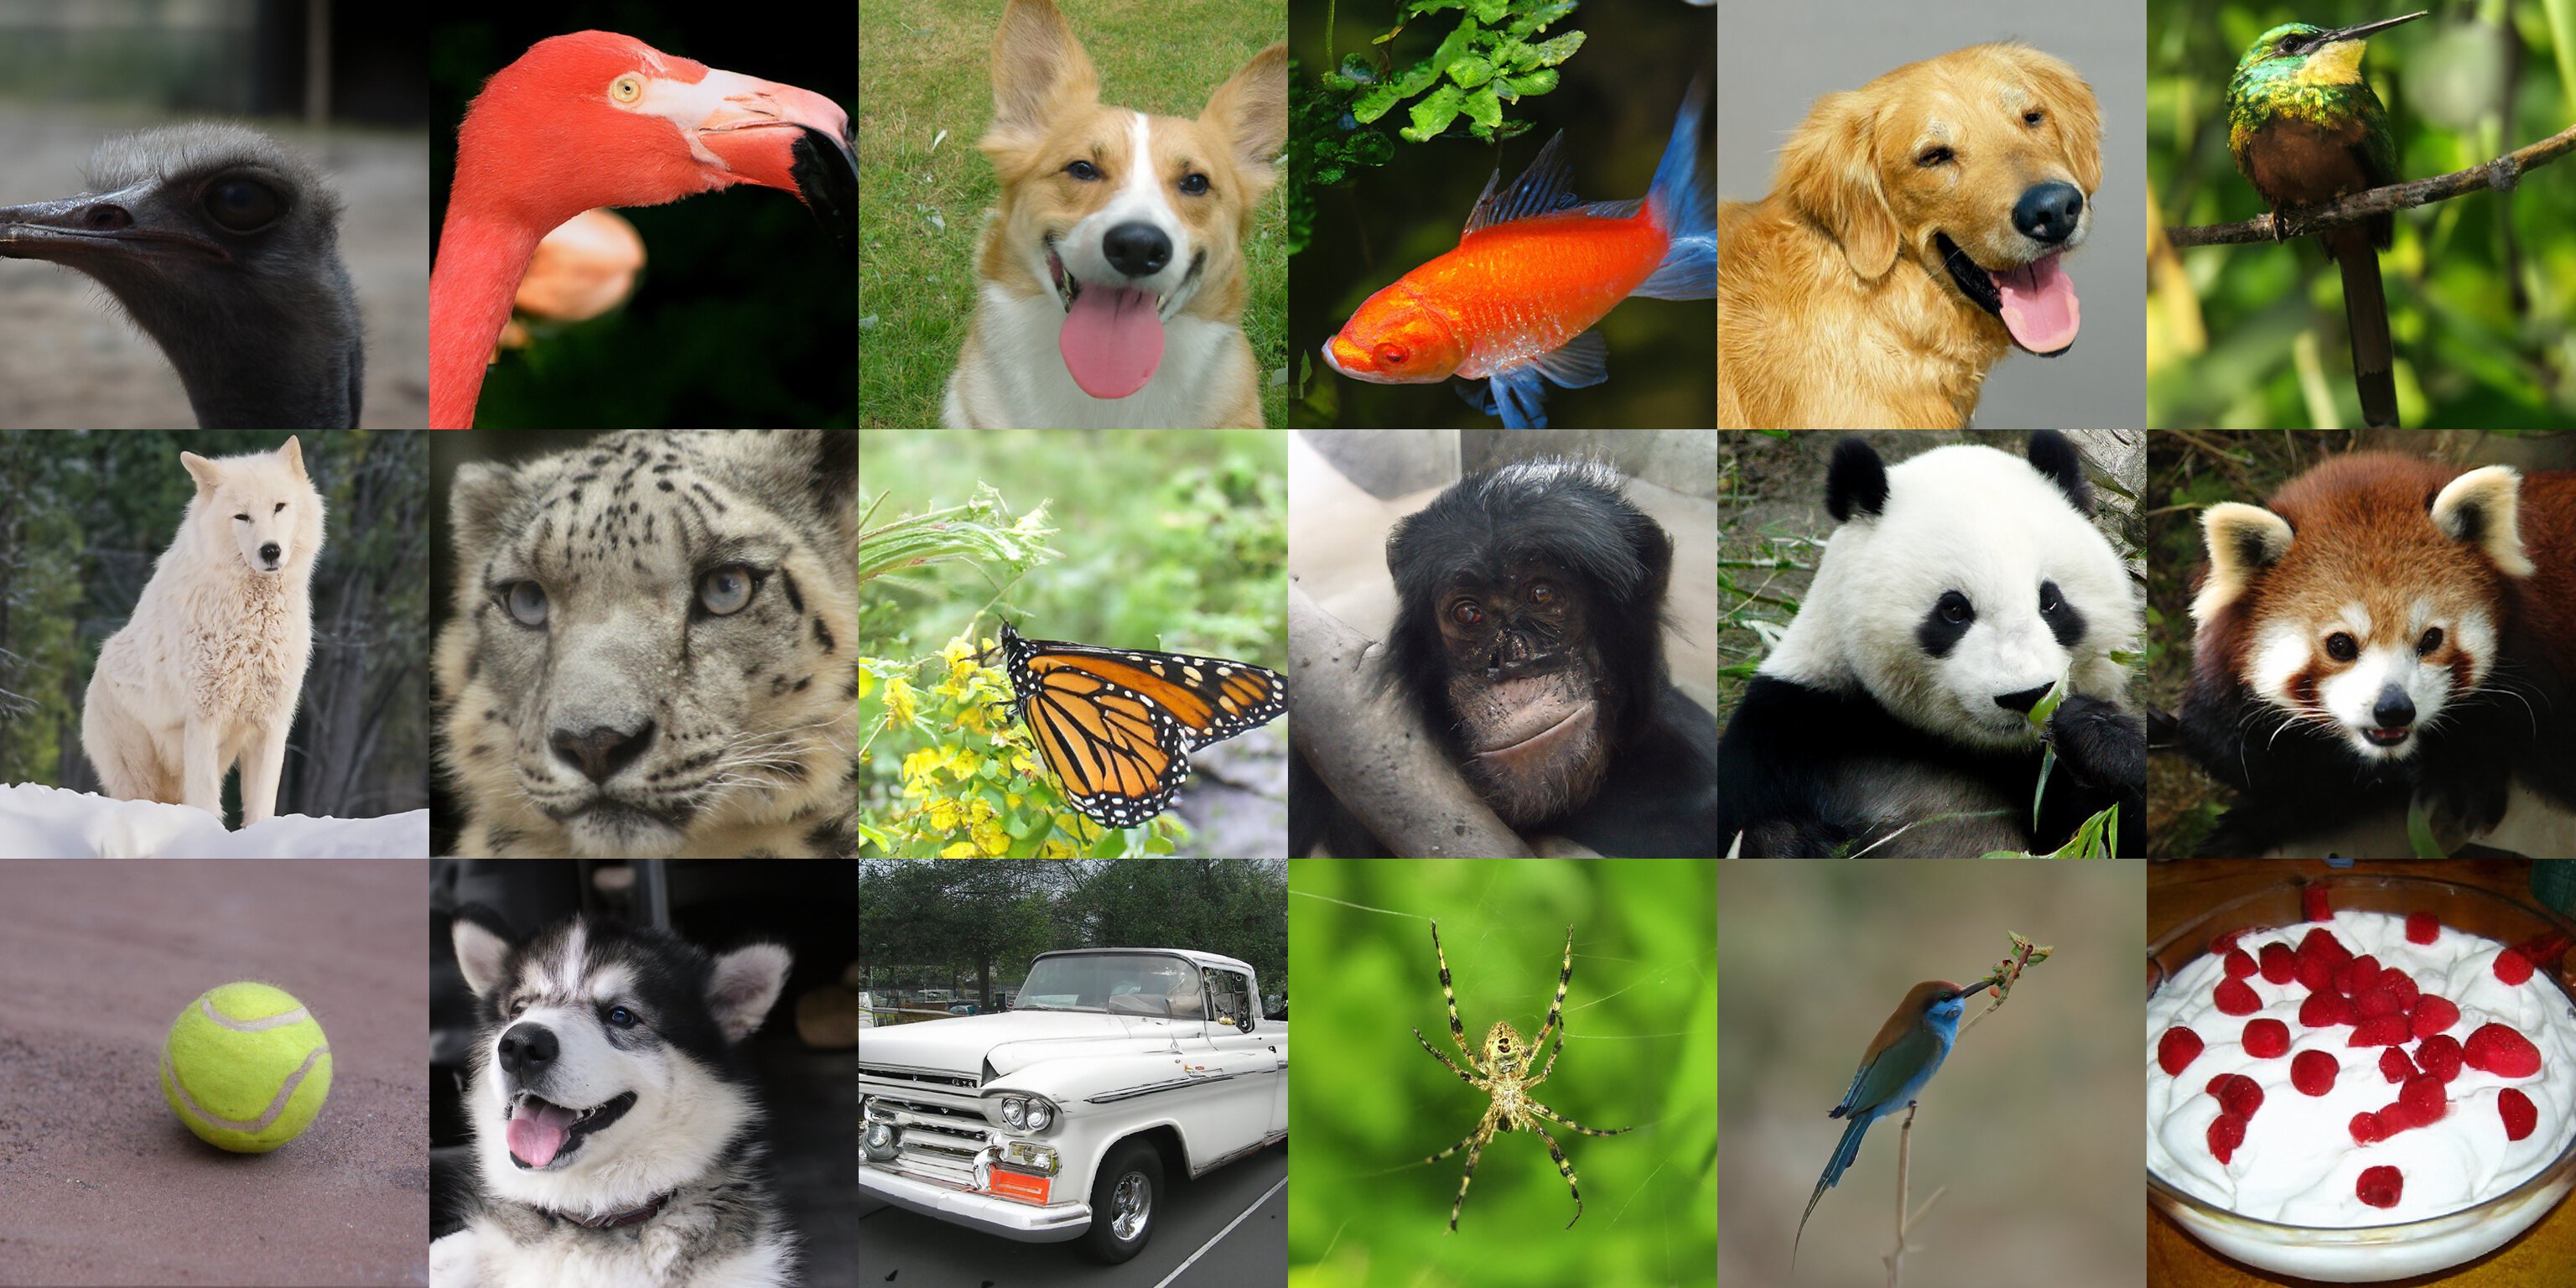
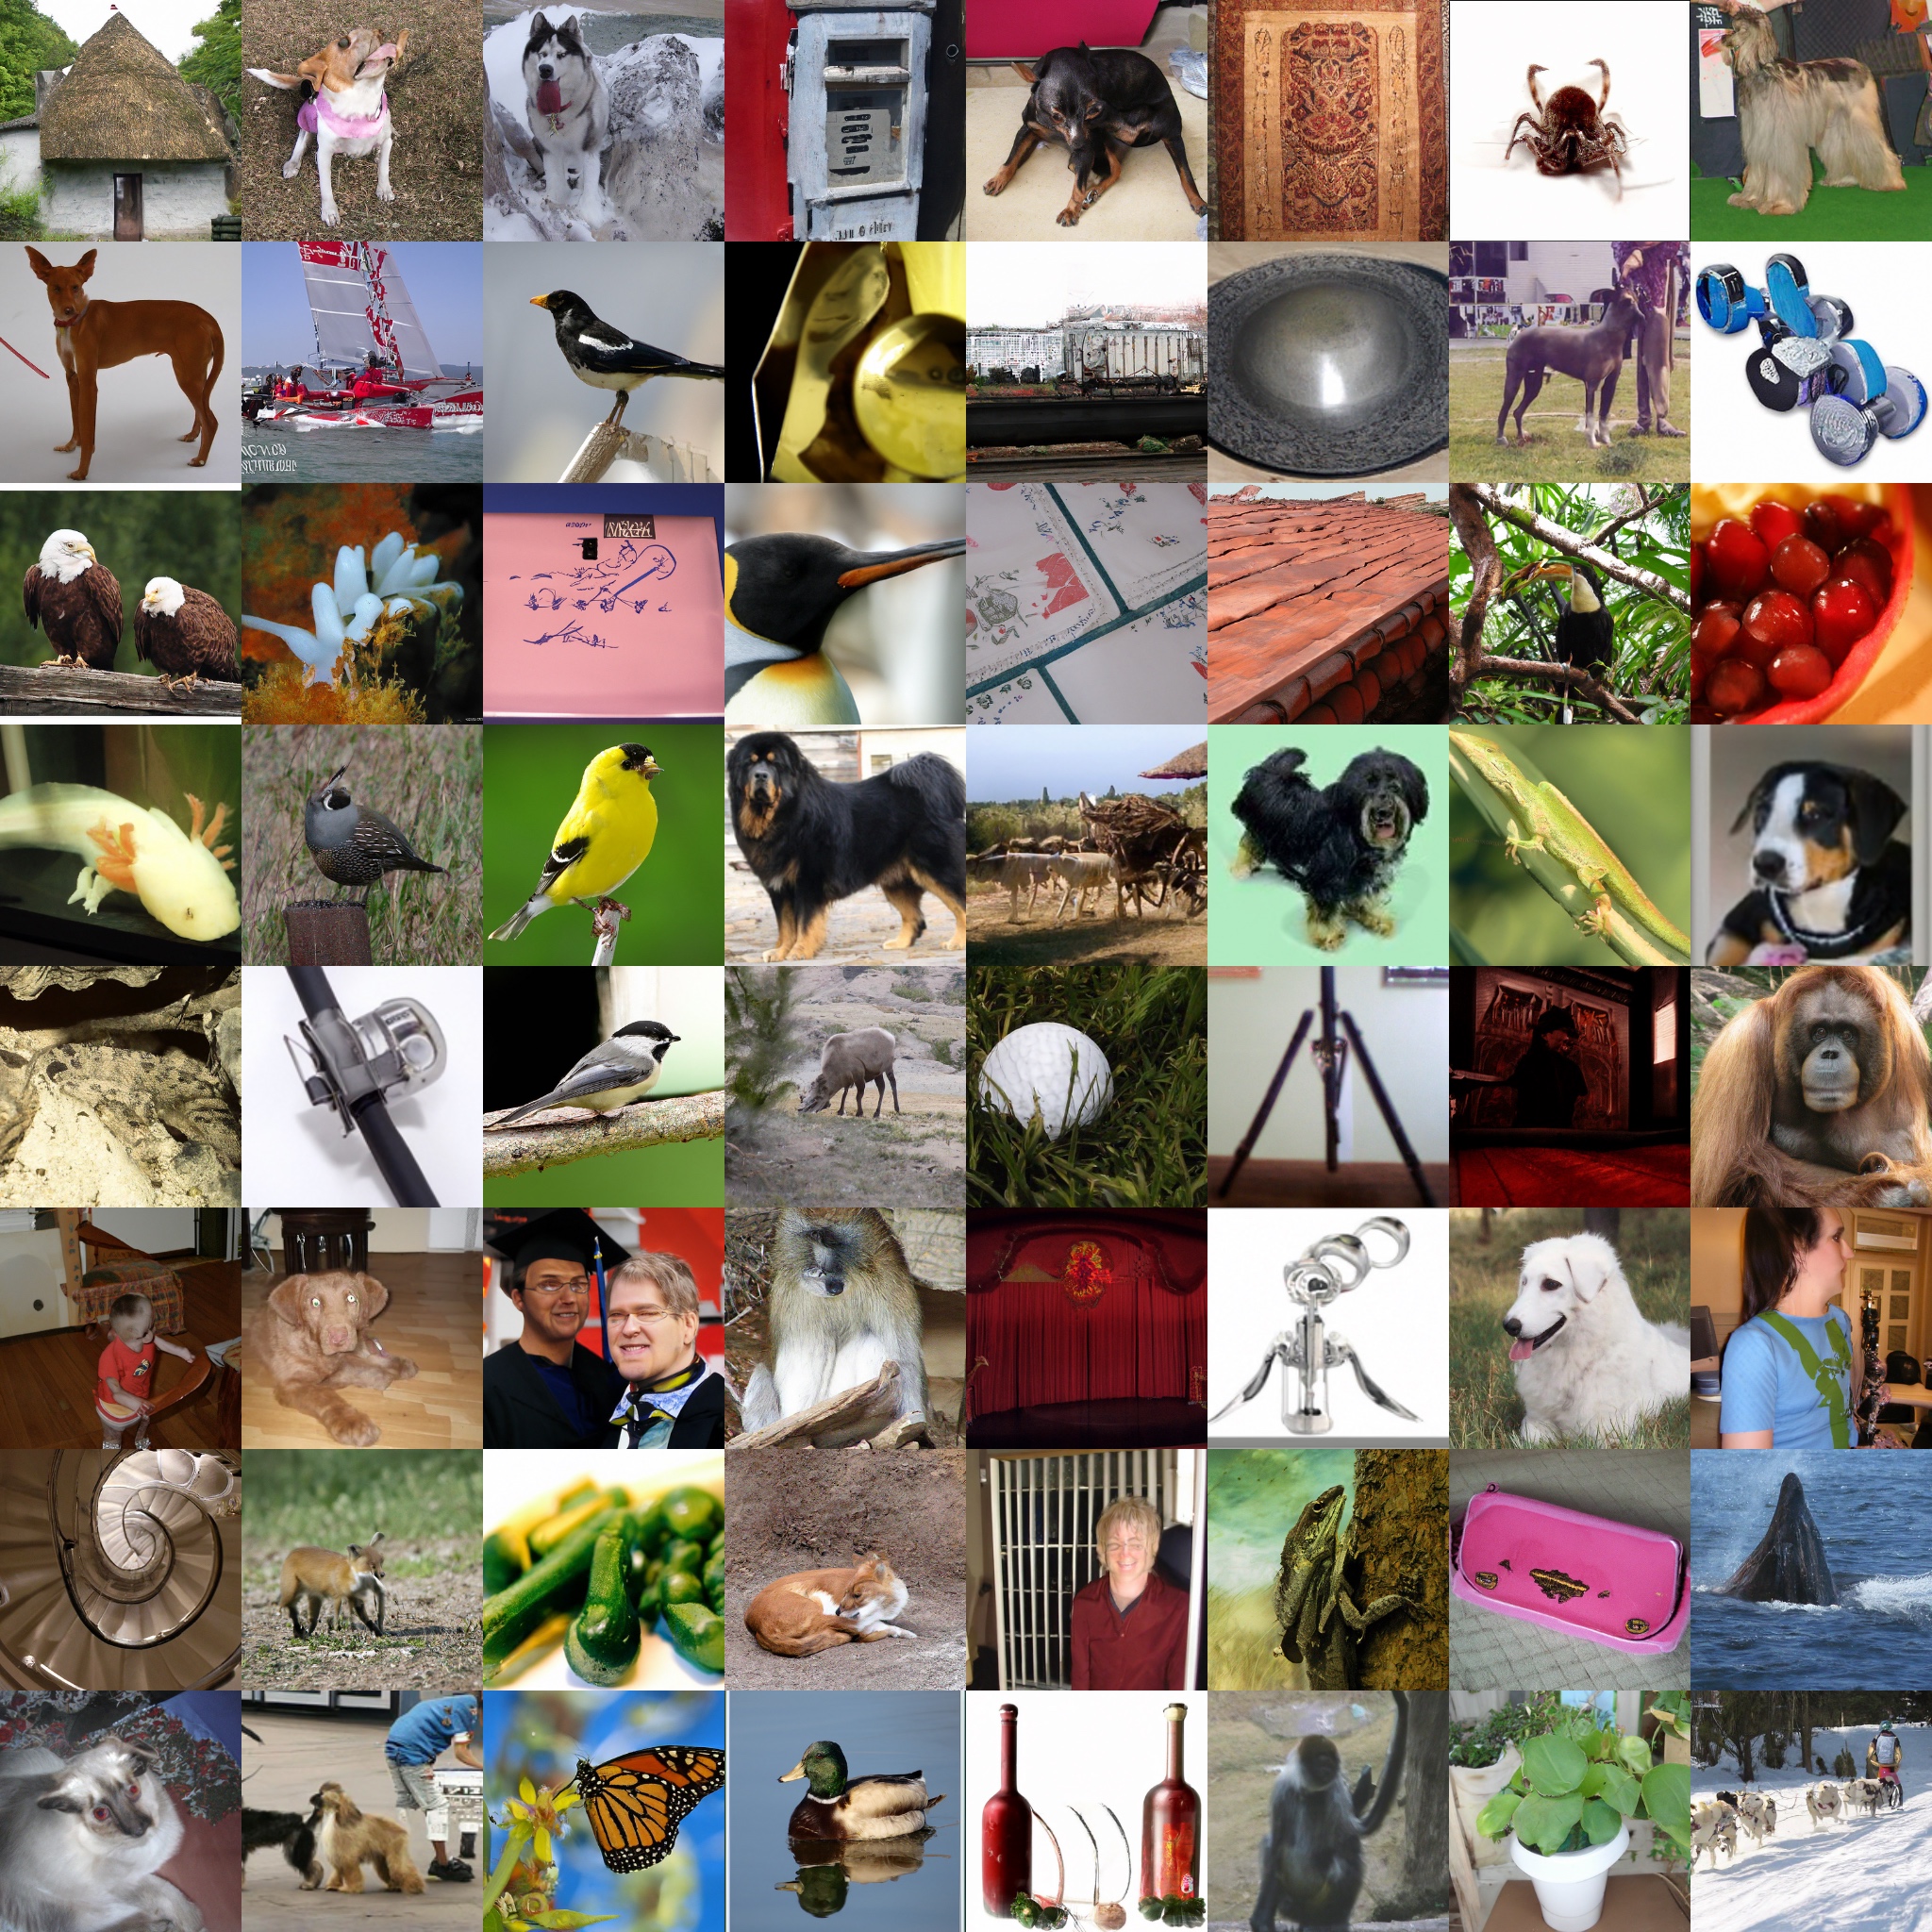
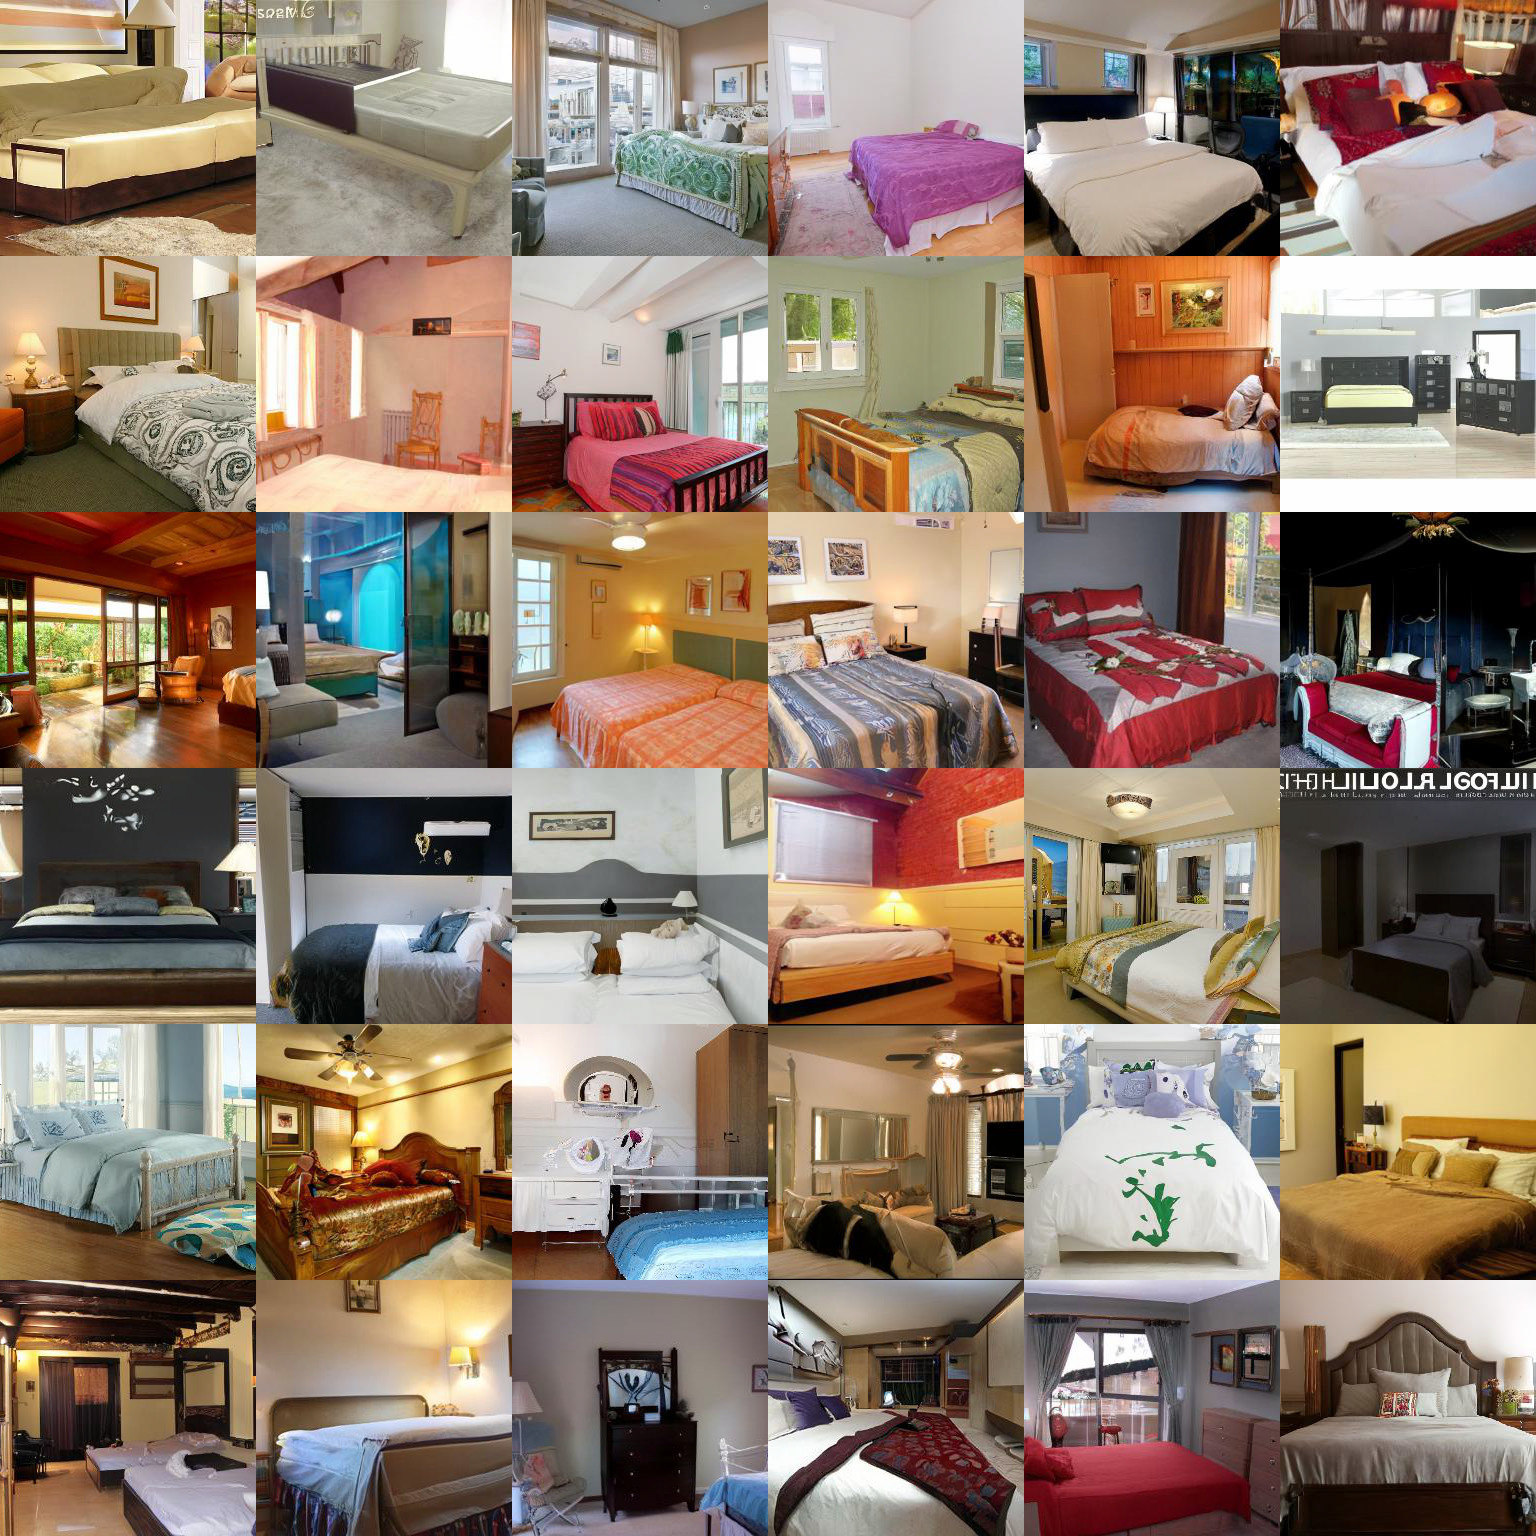
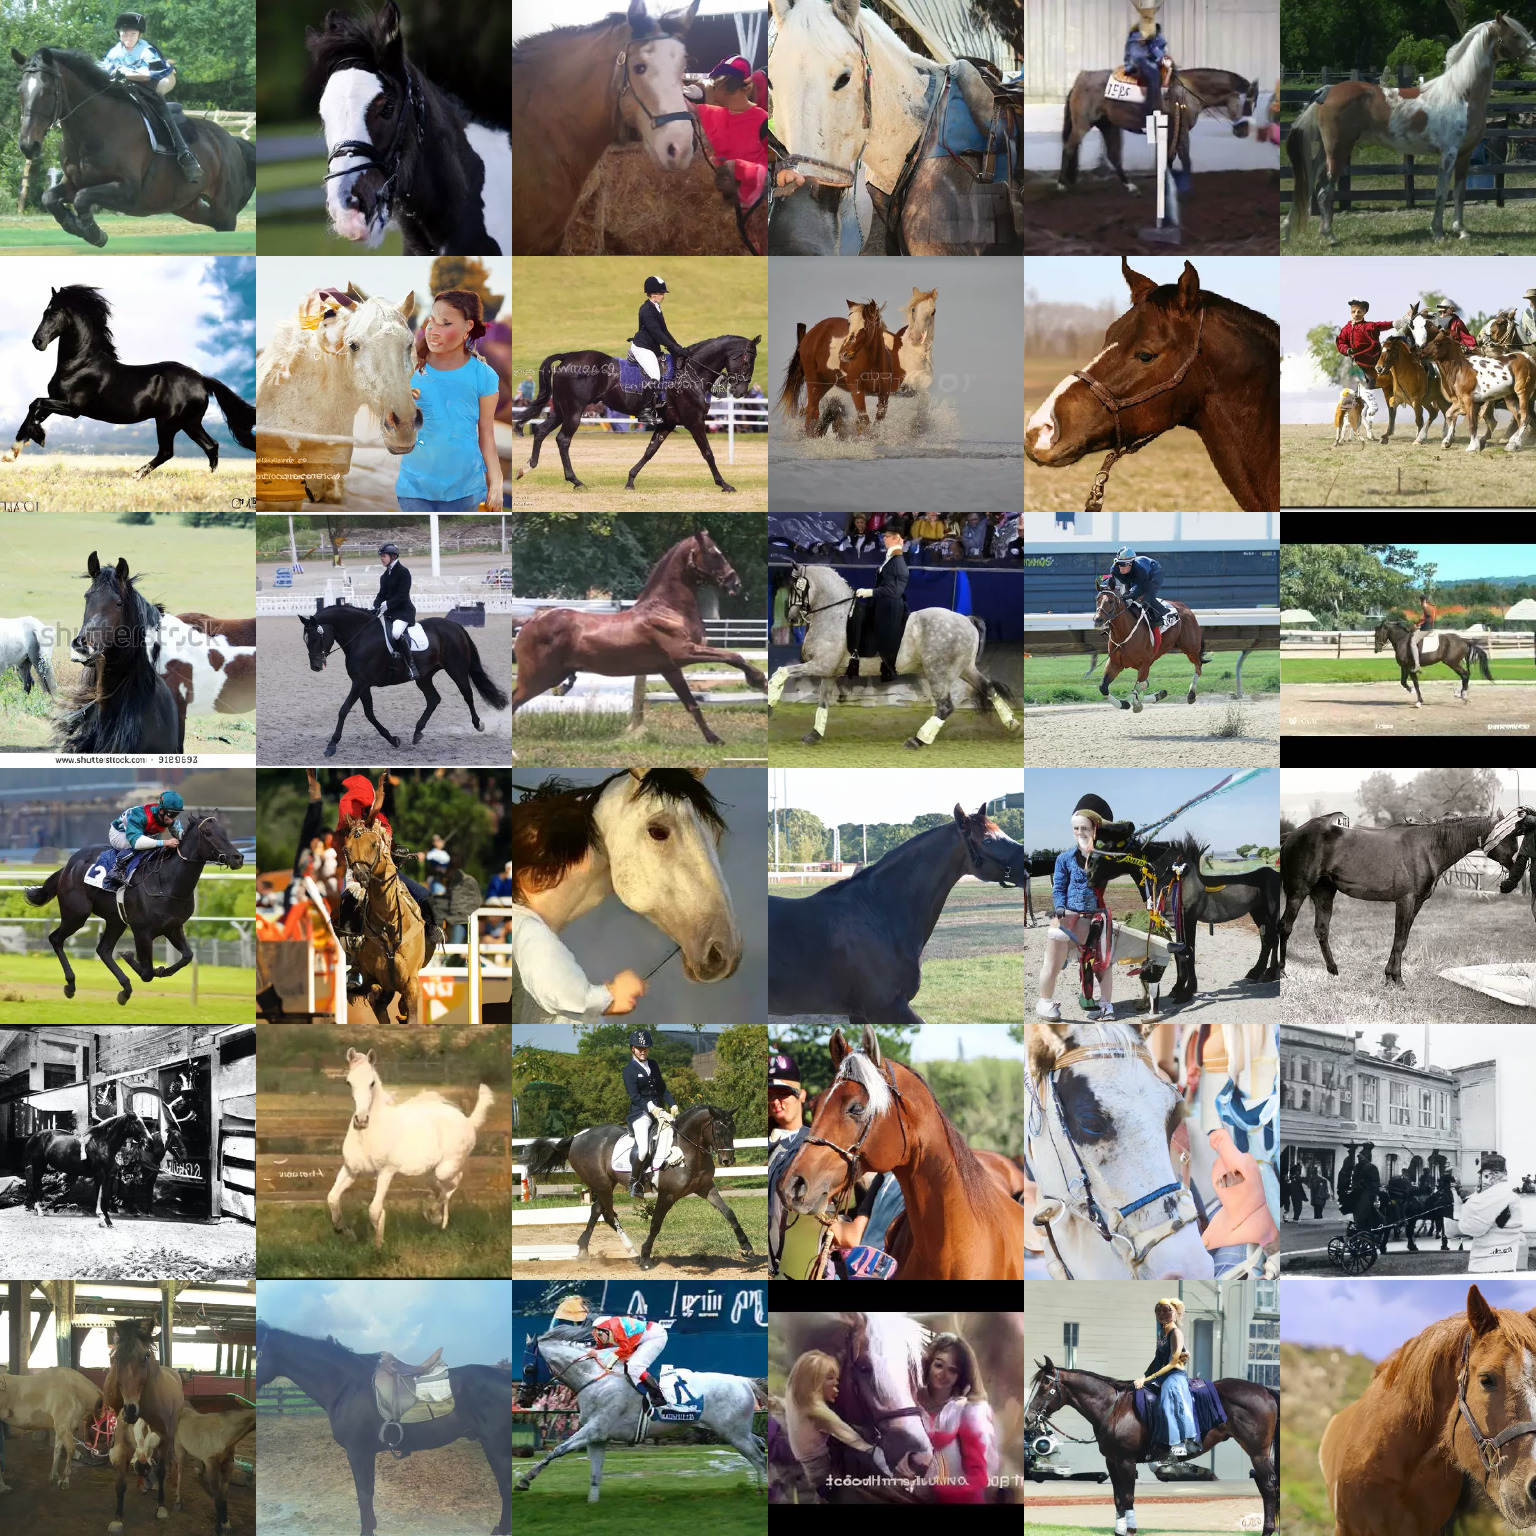
Verification
Claims the paper makes
66 Own result · 23 Supported · 19 Own interpretation · 18 Partly supported · 8 Not checked yet · 8 No basis given · 2 Supported so far · 2 Mixed support · 2 Own method · 1 Couldn’t confirm · 1 Sources not found · 1 No full text of the sources · accuracy not yet measured
Some cited sources support this claim and some don’t — read each source’s verdict below.
In the paper
“While these models capture more diversity and are typically easier to scale and train than GANs, they still fall short in terms of visual sample quality.”
What the sources say
- Disputedcites [51] [51] Ali Razavi, Aaron van den Oord, and Oriol Vinyals. Generating diverse high-fidelity images with VQ-VAE-2. arXiv:1906.00446, 2019. sourceExperimental — accuracy not yet measured
Section 3.3 (p. 5) says that fitting the full data distribution with likelihood-based models is considerably more difficult than adversarial modeling, contrary to the claimed ease of training. The paper discusses training larger models in Section 3.2 (p. 5), but does not say likelihood-based models are easier to scale than GANs. (LLM, conf=0.82)
Checked by a reasoning model — may be wrong.
- Partly supportedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. sourceExperimental — accuracy not yet measured
The Conclusion (p. 8) says DDPMs have a stationary training objective that scales easily with training compute. It does not say they are typically easier to scale or train than GANs, or extend that claim to likelihood-based models generally. The GAN comparison (p. 7) addresses sample quality and mode coverage, not ease of training. (LLM, conf=0.83)
- Partly supportedcites [42] [42] Charlie Nash, Jacob Menick, Sander Dieleman, and Peter W. Battaglia. Generating images with sparse representations. arXiv:2103.03841, 2021. sourceExperimental — accuracy not yet measured
The Introduction says likelihood-based training tends to be more stable than adversarial training, supporting the training comparison. It does not establish that likelihood-based image models are easier to scale; the Discussion instead says good results on complex, high-resolution datasets require substantial computational resources, while GANs achieve high quality with less. (LLM, conf=0.88)
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Disputed
Some cited sources support this claim and some don’t — read each source’s verdict below.
In the paper
“While these models capture more diversity and are typically easier to scale and train than GANs, they still fall short in terms of visual sample quality.”
What the sources say
- Disputedcites [51] [51] Ali Razavi, Aaron van den Oord, and Oriol Vinyals. Generating diverse high-fidelity images with VQ-VAE-2. arXiv:1906.00446, 2019. sourceExperimental — accuracy not yet measured
The Experiments section (p. 6) says the paper’s likelihood-based VQ-VAE produces samples of comparable fidelity to BigGAN-deep, with higher diversity. The Conclusion (p. 11) likewise calls its best samples competitive with state-of-the-art GANs, contrary to the unqualified claim that likelihood-based models still fall short in visual quality. (LLM, conf=0.86)
Checked by a reasoning model — may be wrong.
- Disputedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. sourceExperimental — accuracy not yet measured
The Conclusion (p. 8) says DDPMs can match the sample quality of GANs, contrary to the unqualified claim that they still fall short. The comparison is mixed: Table 4 (p. 6) gives the larger diffusion model a better FID than BigGAN-deep at ImageNet 64 × 64, while Table 5 (p. 12) shows a remaining gap at 256 × 256. (LLM, conf=0.83)
Checked by a reasoning model — may be wrong.
- Partly supportedcites [42] [42] Charlie Nash, Jacob Menick, Sander Dieleman, and Peter W. Battaglia. Generating images with sparse representations. arXiv:2103.03841, 2021. sourceExperimental — accuracy not yet measured
The Image generation benchmarks section reports that GANs had the strongest precision and FID scores, and that DCTransformer samples were less reliably coherent than GAN samples. But it calls the overall comparison mixed: DCTransformer led on spatial FID in three of five datasets, and the Introduction describes its sample quality as competitive with state-of-the-art GANs. The source therefore supports a qualified quality gap, not a blanket claim that likelihood-based models fall short. (LLM, conf=0.84)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Disputed
Every source the paper cites for this claim was checked and supports it.
In the paper
“This class of models already holds the state-of-the-art [60] on CIFAR-10 [31]”
What the sources say
- Supportedcites [60] [60] Yang Song, Jascha Sohl-Dickstein, Diederik P. Kingma, Abhishek Kumar, Stefano Ermon, and Ben Poole. Score-based generative modeling through stochastic differential equations. arXiv:2011.13456, 2020. source
The Introduction reports new state-of-the-art Inception and FID scores on CIFAR-10. Section 4.4 likewise says the authors’ model sets records for unconditional CIFAR-10 generation, supporting the cited claim. (LLM, conf=0.93)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Furthermore, GANs are often difficult to train, collapsing without carefully selected hyperparameters and regularizers [5, 41, 4].”
What the sources say
- Supportedcites [5] [5] Andrew Brock, Jeff Donahue, and Karen Simonyan. Large scale gan training for high fidelity natural image synthesis. arXiv:1809.11096, 2018. source
The Background (p. 2) describes extensive work on modifications intended to stabilize GAN training. The paper reports collapse even in its improved models (3.2 Summary, p. 5), and shows that changes to learning rates can trigger immediate collapse (Appendix G.1, p. 32), supporting the claim that training is sensitive to hyperparameters and regularization. (LLM, conf=0.90)
- Partly supportedcites [41] [41] Takeru Miyato, Toshiki Kataoka, Masanori Koyama, and Yuichi Yoshida. Spectral normalization for generative adversarial networks. arXiv:1802.05957, 2018. sourceExperimental — accuracy not yet measured
The Introduction (p. 1) describes unstable GAN training, and the ImageNet results (p. 11) report that GANs without normalization collapsed. But the paper does not establish that avoiding collapse generally requires carefully selected hyperparameters and regularizers: the Introduction (pp. 1–2) says spectral normalization works without intensive hyperparameter tuning or complementary regularization techniques. (LLM, conf=0.84)
- Not checked yetcites [4] [4] Andrew Brock, Theodore Lim, J. M. Ritchie, and Nick Weston. Neural photo editing with introspective adversarial networks. arXiv:1609.07093, 2016. source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“it has been shown that GANs capture less diversity than state-of-the-art likelihood-based models [51, 43, 42].”
What the sources say
- Supportedcites [51] [51] Ali Razavi, Aaron van den Oord, and Oriol Vinyals. Generating diverse high-fidelity images with VQ-VAE-2. arXiv:1906.00446, 2019. source
The Introduction (p. 2) says likelihood-based models in principle cover all modes of the data, unlike GANs, which can lack diversity. The Experiments section (p. 6) also reports higher sample diversity for VQ-VAE than for BigGAN-deep, which it identifies as a state-of-the-art GAN. (LLM, conf=0.90)
- Partly supportedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. sourceExperimental — accuracy not yet measured
The Introduction (p. 1) reports that diffusion models achieved much higher recall than GANs at similar FID, and the Conclusion (p. 8) describes better mode coverage for DDPMs. This supports the diversity comparison for the models studied, but not the broader claim about GANs versus state-of-the-art likelihood-based models generally. (LLM, conf=0.83)
- Supportedcites [42] [42] Charlie Nash, Jacob Menick, Sander Dieleman, and Peter W. Battaglia. Generating images with sparse representations. arXiv:2103.03841, 2021. source
The Introduction describes mode-dropping as a common downside of GANs and says likelihood-based training incentivizes coverage of the full data distribution. In §4.1, the paper reports that its likelihood-based DCTransformer typically achieves better recall than the GANs compared, which it interprets as better data coverage. (LLM, conf=0.89)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“However, the FID of this model is still not competitive with BigGAN-deep [5], the current state-of-the-art on this dataset.”
What the sources say
- Supportedcites [5] [5] Andrew Brock, Jeff Donahue, and Karen Simonyan. Large scale gan training for high fidelity natural image synthesis. arXiv:1809.11096, 2018. source
Table 2 (p. 7) identifies BigGAN-deep as an ImageNet 256 × 256 model and reports its FID. Section 5.1 (p. 7) says the models outperform previous state-of-the-art FID scores. The comparison with the citing authors’ own model is their assessment, not a result attributed to this source. (LLM, conf=0.90)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“Nichol and Dhariwal [43] found that these models improve reliably with increased compute”
What the sources say
- Supportedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. source
Section 6 (p. 7) reports that the authors’ preliminary results suggest DDPM performance improves predictably as training compute increases. The Abstract (p. 1) likewise says sample quality and likelihood scale smoothly with training compute. (LLM, conf=0.91)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources that could be checked couldn’t confirm or dispute this claim.
In the paper
“and we can increase this gradient scale factor by an order of magnitude without obtaining adversarial examples [61].”
What the sources say
- Could not verifycites [61] [61] Christian Szegedy, Wojciech Zaremba, Ilya Sutskever, Joan Bruna, Dumitru Erhan, Ian Good- fellow, and Rob Fergus. Intriguing properties of neural networks. arXiv:1312.6199, 2013. sourceExperimental — accuracy not yet measured
The Experimental results (pp. 5–8) discuss generating adversarial examples and magnifying image distortions, but do not test whether a tenfold increase in a gradient scale factor fails to produce them. I searched for the claimed scale factor, gradients, and an order-of-magnitude increase; the 10× figure on p. 6 refers only to magnifying an image difference for display. (LLM, conf=0.73)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Could not verify
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“GANs [19] currently hold the state-of-the-art on most image generation tasks [5, 68, 28] as measured by sample quality metrics such as FID [23], Inception Score [54] and Precision [32].”
What the sources say
- Partly supportedcites [5] [5] Andrew Brock, Jeff Donahue, and Karen Simonyan. Large scale gan training for high fidelity natural image synthesis. arXiv:1809.11096, 2018. sourceExperimental — accuracy not yet measured
Section 5.1 (p. 7) reports that BigGAN surpassed previous state-of-the-art Inception Score and FID results on ImageNet. Section 2 (p. 3) describes those metrics as measures of sample quality. The paper does not establish that GANs lead on most image-generation tasks, and it does not report Precision as a performance metric. (LLM, conf=0.87)
- Not checked yetcites [68] [68] Yan Wu, Jeff Donahue, David Balduzzi, Karen Simonyan, and Timothy Lillicrap. Logan: Latent optimisation for generative adversarial networks. arXiv:1912.00953, 2019. source
A check is scheduled.
- Partly supportedcites [28] [28] Tero Karras, Samuli Laine, Miika Aittala, Janne Hellsten, Jaakko Lehtinen, and Timo Aila. Analyzing and improving the image quality of stylegan. arXiv:1912.04958, 2019. sourceExperimental — accuracy not yet measured
The Introduction describes StyleGAN as state of the art for high-resolution image synthesis, and the Conclusions say StyleGAN2 advanced the state of the art on several datasets. Neither passage establishes that GANs lead on most image-generation tasks. FID, Inception Score, and Precision have separate citations in the citing sentence, so they are not the part attributed to this paper. (LLM, conf=0.85)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“However, some of these metrics do not fully capture diversity”
What the sources say
- Supportedcites [51] [51] Ali Razavi, Aaron van den Oord, and Oriol Vinyals. Generating diverse high-fidelity images with VQ-VAE-2. arXiv:1906.00446, 2019. source
The Conclusion (p. 11) says concrete measures of sample quality and diversity are still in their infancy and visual inspection remains necessary. Section 5.3.1 (p. 11) also notes drawbacks of common metrics, supporting the claim that some metrics do not fully capture diversity. (LLM, conf=0.88)
- Supportedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. source
The Introduction (p. 1) reports much higher recall for diffusion models at similar FID, indicating that FID alone does not fully reflect distribution coverage. Section 5 (p. 7) likewise reports better FID for BigGAN-deep but worse recall than a diffusion model. (LLM, conf=0.90)
- Supportedcites [42] [42] Charlie Nash, Jacob Menick, Sander Dieleman, and Peter W. Battaglia. Generating images with sparse representations. arXiv:2103.03841, 2021. source
Section 4 (Experiments; page unavailable) says standard FID features compress spatial information, making the metric less sensitive to spatial variability. Section 4.1 reports that GANs had the strongest FID scores while DCTransformer typically had the best recall scores, which the authors associate with data coverage and diverse samples. Together, these passages support the qualified claim that some metrics do not fully capture diversity. (LLM, conf=0.88)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
- Probably not a substantial claim. 42
- It may state two separate claims as one. 34
- The quote only partly states this claim. 1
Every source the paper cites for this claim was checked and supports it.
In the paper
“Nichol and Dhariwal [43] find that fixing the variance Σθ(xt, t) to a constant as done in Ho et al. [25] is sub-optimal for sampling with fewer diffusion steps”
§ 2 Background > 2.1 Improvements
What the sources say
- Supportedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. source
Section 4 (p. 6) reports that models with fixed variances suffered much greater losses in sample quality when the number of sampling steps was reduced, while the model with learned variances maintained high quality. Section 3.1 (p. 3) identifies the fixed-variance approach used by Ho et al.; the variances were fixed rather than learned, not necessarily the same value at every step. (LLM, conf=0.94)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“They also note that training with this objective and using their corresponding sampling procedure is equivalent to the denoising score matching model from Song and Ermon [58]”
What the sources say
- Not checked yetcites [25] [25] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv:2006.11239, 2020.
- Partly supportedcites [58] [58] Yang Song and Stefano Ermon. Improved techniques for training score-based generative models. arXiv:2006.09011, 2020. sourceExperimental — accuracy not yet measured
The Introduction (p. 1) says score-based generative models learn their score functions through denoising score matching, and Section 2.2 (pp. 2–3) describes training and sampling with a noise-conditional score network. Our copy does not state that training with Lsimple and its corresponding sampling procedure are equivalent to that model; a search for the equivalence found no such passage. (LLM, conf=0.84)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The sources with a verdict support this claim; the rest weren’t checked yet, have no full text we could read, or their verdicts aren’t rated yet.
In the paper
“As a result, much work has been done to achieve GAN-like sample quality with likelihood-based models [51, 25, 42, 9].”
What the sources say
- Supportedcites [51] [51] Ali Razavi, Aaron van den Oord, and Oriol Vinyals. Generating diverse high-fidelity images with VQ-VAE-2. arXiv:1906.00446, 2019. source
The Introduction (p. 1) identifies VAEs and autoregressive models as likelihood-based models. The Conclusion (p. 11) describes this paper’s VQ-VAE with an autoregressive prior and says its best samples have fidelity competitive with state-of-the-art GANs. The paper therefore serves as an example of the work described in the citing sentence. (LLM, conf=0.93)
- Not checked yetcites [25] [25] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv:2006.11239, 2020.
- Supportedcites [42] [42] Charlie Nash, Jacob Menick, Sander Dieleman, and Peter W. Battaglia. Generating images with sparse representations. arXiv:2103.03841, 2021. source
The Introduction describes likelihood-based approaches to image generation and says this paper’s autoregressive DCTransformer achieves sample quality competitive with state-of-the-art GANs. This paper is therefore an example of the work the citing sentence describes. (LLM, conf=0.90)
- Not checked yetcites [9] [9] Rewon Child. Very deep vaes generalize autoregressive models and can outperform them on images. arXiv:2011.10650, 2021.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“By setting this noise to 0, they provide a way to turn any model εθ(xt, t) into a deterministic mapping from latents to images”
§ 2 Background > 2.1 Improvements
What the sources say
- Supportedcites [57] [57] Jiaming Song, Chenlin Meng, and Stefano Ermon. Denoising diffusion implicit models. arXiv:2010.02502, 2020. source
Section 4.1 (p. 5) states that setting σₜ = 0 for all steps removes the random-noise term from the generative process, yielding samples from latent variables xₜ through a fixed procedure to x₀. Section 5 (p. 6) also describes DDIM as deterministic and says the same trained model can be used by changing the sampling parameters. (LLM, conf=0.94)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
The sources with a verdict support this claim; the rest weren’t checked yet, have no full text we could read, or their verdicts aren’t rated yet.
In the paper
“The variance Σθ(xt, t) of this Gaussian distribution can be fixed to a known constant [25] or learned with a separate neural network head [43], and both approaches yield high-quality samples when the total number of diffusion steps T is large enough.”
What the sources say
- Not checked yetcites [25] [25] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv:2006.11239, 2020.
- Supportedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. source
Section 3.1 (pp. 3–4) describes learning the variance from a model output distinct from its mean output. It also explains that, as the number of diffusion steps increases, the choice of variance matters less for sample quality; Section 2.2 (p. 2) reports high-quality results with fixed variance. The cited paper therefore supports the learned-variance approach and the sample-quality comparison, though it does not use the phrase “separate neural network head.” (LLM, conf=0.86)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
Every source the paper cites for this claim was checked and supports it.
In the paper
“and can produce high-quality samples even on the difficult ImageNet 256×256 dataset using an upsampling stack.”
What the sources say
- Supportedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. source
Section C (p. 12) describes a two-stage diffusion model that chains a 64×64 model with an upsampling diffusion model to generate class-conditional ImageNet 256×256 images. Table 5 reports an FID of 12.3 for this model, supporting the claim about sample quality. (LLM, conf=0.92)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“and find that this provides an alternative way to sample with fewer steps.”
§ 2 Background > 2.1 Improvements
What the sources say
- Supportedcites [57] [57] Jiaming Song, Chenlin Meng, and Stefano Ermon. Denoising diffusion implicit models. arXiv:2010.02502, 2020. source
Section 5.1 (p. 7) explicitly says DDIM can generate samples in fewer steps, with quality comparable to 1000-step models in 20–100 steps. Section 5 (p. 6) describes changing how samples are produced without changing the trained model, supporting its characterization as an alternative sampling method. (LLM, conf=0.94)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“and propose to parameterize Σθ(xt, t) as a neural network whose output v is interpolated as:”
§ 2 Background > 2.1 Improvements
What the sources say
- Supportedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. source
Section 3.1 (p. 3) says the model outputs a vector v that is converted into variances by interpolation between βt and β̃t in the log domain. This supports the attribution: the network parameterizes Σθ indirectly through v, rather than predicting Σθ directly. (LLM, conf=0.92)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“Song et al. [57] propose DDIM, which formulates an alternative non-Markovian noising process that has the same forward marginals as DDPM”
§ 2 Background > 2.1 Improvements
What the sources say
- Supportedcites [57] [57] Jiaming Song, Chenlin Meng, and Stefano Ermon. Denoising diffusion implicit models. arXiv:2010.02502, 2020. source
Section 3 (p. 3) says the authors explore non-Markovian inference processes whose joint distributions differ while retaining the DDPM marginals q(x_t | x_0). The Introduction (p. 2) identifies this generalization as part of their DDIM proposal. (LLM, conf=0.94)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Diffusion models are a class of likelihood-based models which have recently been shown to produce high-quality images [56, 59, 25]”
What the sources say
- Supportedcites [56] [56] Jascha Sohl-Dickstein, Eric A. Weiss, Niru Maheswaranathan, and Surya Ganguli. Deep unsupervised learning using nonequilibrium thermodynamics. arXiv:1503.03585, 2015. source
Section 1.1 (pp. 1–2) describes diffusion models whose log likelihood can be evaluated and reports high-log-likelihood models trained on image datasets. Figure 4’s caption (p. 6) describes a generated dead-leaves image with consistent occlusion and multiscale structure; Section 3.2.1 (p. 9) also reports generated CIFAR-10 samples and state-of-the-art performance on dead-leaves images. Together, these support the broad claim, though the paper does not use the phrase “high-quality images.” (LLM, conf=0.85)
- Partly supportedcites [59] [59] Yang Song and Stefano Ermon. Generative modeling by estimating gradients of the data distribution. arXiv:arXiv:1907.05600, 2020. sourceExperimental — accuracy not yet measured
The Experiments section (p. 7) reports high-quality images generated by the paper’s models on MNIST, CelebA, and CIFAR-10. But Related Work (p. 9) explicitly says its objective is based on score matching instead of likelihood, so this source does not support describing its model as likelihood-based. (LLM, conf=0.90)
- Not checked yetcites [25] [25] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv:2006.11239, 2020.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“Learning the reverse process variances with their hybrid objective allows sampling with fewer steps without much drop in sample quality.”
§ 2 Background > 2.1 Improvements
What the sources say
- Supportedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. source
Section 3.1 (p. 4) says the hybrid objective lets the model learn reverse-process variances. Section 4 (p. 6) reports that the hybrid model with learned variances maintains high sample quality with fewer sampling steps, unlike models with fixed variances. (LLM, conf=0.95)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“To this end, Sohl-Dickstein et al. [56] note that q(xt−1|xt) approaches a diagonal Gaussian distribution as T →∞ and correspondingly βt → 0, so it is sufficient to train a neural network to predict a mean µθ and a diagonal covariance matrix Σθ:”
What the sources say
- Supportedcites [56] [56] Jascha Sohl-Dickstein, Eric A. Weiss, Niru Maheswaranathan, and Surya Ganguli. Deep unsupervised learning using nonequilibrium thermodynamics. arXiv:1503.03585, 2015. source
Section 2.2 (p. 5) says that, for Gaussian diffusion, the reverse conditional is Gaussian when βₜ is small and that a longer trajectory permits a smaller diffusion rate. It also says the model estimates the reverse kernel’s mean and covariance; Appendix D.2.1 (p. 17) specifies a diagonal covariance matrix. (LLM, conf=0.90)
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“The above derivation for conditional sampling is only valid for the stochastic diffusion sampling process, and cannot be applied to deterministic sampling methods like DDIM [57].”
§ 4 Classifier Guidance > 4.2 Conditional Sampling for DDIM
What the sources say
- Partly supportedcites [57] [57] Jiaming Song, Chenlin Meng, and Stefano Ermon. Denoising diffusion implicit models. arXiv:2010.02502, 2020. sourceExperimental — accuracy not yet measured
Section 4.1 (p. 5) describes DDIM sampling as deterministic when the noise coefficient is zero, supporting the description of DDIM. The paper does not address the citing authors’ conditional-sampling derivation or say that it cannot be applied to DDIM; searches for conditional sampling and conditioning did not establish that limitation. (LLM, conf=0.87)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“Recently, sFID was proposed by Nash et al. [42] as a version of FID that uses spatial features rather than the standard pooled features.”
What the sources say
- Supportedcites [42] [42] Charlie Nash, Jacob Menick, Sander Dieleman, and Peter W. Battaglia. Generating images with sparse representations. arXiv:2103.03841, 2021. source
The Table 1 caption in Section 4 (Experiments) explicitly says sFID uses intermediate spatial Inception features rather than the spatially pooled features used in standard FID. The section also identifies standard FID's features as pool 3 features. (LLM, conf=0.94)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“Finally, Kynkäänniemi et al. [32] proposed Improved Precision and Recall metrics to separately measure sample fidelity as the fraction of model samples which fall into the data manifold (precision), and diversity as the fraction of data samples which fall into the sample manifold (recall).”
What the sources say
- Supportedcites [32] [32] Tuomas Kynkäänniemi, Tero Karras, Samuli Laine, Jaakko Lehtinen, and Timo Aila. Improved precision and recall metric for assessing generative models. arXiv:1904.06991, 2019. source
Section 2 describes the authors’ improved metric as estimating the manifolds of real and generated data. The Figure 1 caption defines precision as the probability that a generated image falls within the real-data support, and recall as the probability that a real image falls within the generated-data support; Section 1.1 connects these to sample quality and coverage. (LLM, conf=0.94)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Inception Score (IS) was proposed by Salimans et al. [54], and it measures how well a model captures the full ImageNet class distribution while still producing individual samples that are convincing examples of a single class.”
§ 2 Background > 2.2 Sample Quality Metrics
What the sources say
- Partly supportedcites [54] [54] Tim Salimans, Ian Goodfellow, Wojciech Zaremba, Vicki Cheung, Alec Radford, and Xi Chen. Improved techniques for training gans. arXiv:1606.03498, 2016. sourceExperimental — accuracy not yet measured
Section 4 (p. 4) proposes the Inception Score and says it rewards low-entropy class predictions for individual images and high-entropy marginal predictions across generated images, using an ImageNet-pretrained classifier. It does not say the score measures whether a model captures the full ImageNet class distribution or whether individual samples are convincing examples of a class; those are stronger claims than the stated criteria. (LLM, conf=0.86)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Partly supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“They found that increasing truncation naturally led to a decrease in diversity but an increase in fidelity.”
What the sources say
- Supportedcites [5] [5] Andrew Brock, Jeff Donahue, and Karen Simonyan. Large scale gan training for high fidelity natural image synthesis. arXiv:1809.11096, 2018. source
Section 3.1 (p. 4) states that stronger truncation improves individual sample quality at the cost of overall variety. The paper qualifies this trade-off: some models are not amenable to truncation and produce artifacts. (LLM, conf=0.93)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“For BigGAN-deep, Brock et al. [5] do not explicitly describe the compute requirements for training their models, but rather provide rough estimates in terms of days on a Google TPUv3 pod [20].”
What the sources say
- Partly supportedcites [5] [5] Andrew Brock, Jeff Donahue, and Karen Simonyan. Large scale gan training for high fidelity natural image synthesis. arXiv:1809.11096, 2018. sourceExperimental — accuracy not yet measured
Appendix C (p. 23) reports training on a Google TPU v3 Pod and says most models take 24–48 hours, supporting a rough duration estimate. It also specifies 128, 256, or 512 cores by image resolution, so the claim that the paper does not explicitly describe compute requirements overlooks hardware requirements it does give. The duration is for most models, not specifically BigGAN-deep. (LLM, conf=0.84)
- Not checked yetcites [20] [20] Google. Cloud tpus. https://cloud.google.com/tpu/, 2018.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“To ensure consistent comparisons, we use the entire training set as the reference batch [23, 5], and evaluate metrics for all models using the same codebase.”
What the sources say
- Supportedcites [23] [23] Martin Heusel, Hubert Ramsauer, Thomas Unterthiner, Bernhard Nessler, and Sepp Hochreiter. Gans trained by a two time-scale update rule converge to a local nash equilibrium. Advances in Neural Information Processing Systems 30 (NIPS 2017), 2017. source
The Experiments section (p. 6) says the paper used all images from the training dataset to compute the reference statistics for FID. The citation is attached to that reference-set choice; the statement about using the same codebase describes the citing authors’ own evaluation practice. (LLM, conf=0.92)
- Could not verifycites [5] [5] Andrew Brock, Jeff Donahue, and Karen Simonyan. Large scale gan training for high fidelity natural image synthesis. arXiv:1809.11096, 2018. sourceExperimental — accuracy not yet measured
Section 5.1 (p. 7) reports IS and FID comparisons, but does not say that the entire training set was used as a reference batch. Searches for FID reference statistics and a shared metrics codebase found no passage establishing either practice. Appendix C.1 (p. 23) discusses a different kind of batch statistics, used when sampling images. (LLM, conf=0.70)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“and models which memorize a small subset of the full dataset will still have high IS [3].”
§ 2 Background > 2.2 Sample Quality Metrics
What the sources say
- Supportedcites [3] [3] Shane Barratt and Rishi Sharma. A note on the inception score. arXiv:1801.01973, 2018. source
Section 4.2.3, “Not Reporting Overfitting” (page not provided), says a generative algorithm that memorizes an appropriate subset of the training data would perform extremely well on the Inception Score. This supports the claim that memorizing a subset can yield a high score, though the paper specifies that the subset must be appropriate. (LLM, conf=0.92)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“One drawback of this metric is that it does not reward covering the whole distribution or capturing diversity within a class”
§ 2 Background > 2.2 Sample Quality Metrics
What the sources say
- Supportedcites [3] [3] Shane Barratt and Rishi Sharma. A note on the inception score. arXiv:1801.01973, 2018. source
Section 4 shows that an analog of the Inception Score gives its highest score to a generator producing only two extreme outputs, while the true distribution scores lower. Section 3.3 explains that the score depends on predicted class entropy and classification confidence, not on diversity within each class. Together, these support both drawbacks in the claim. (LLM, conf=0.90)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
- Supported
Every source the paper cites for this claim was checked and supports it.
In the paper
“The DDIM [57] sampling process is deterministic given the initial noise xT , thus giving rise to an implicit latent space.”
What the sources say
- Supportedcites [57] [57] Jiaming Song, Chenlin Meng, and Stefano Ermon. Denoising diffusion implicit models. arXiv:2010.02502, 2020. source
Section 4.1 (p. 5) says that when the noise coefficient is zero, DDIM generates samples from the latent variable xT through a fixed procedure. Related Work (p. 9) states that samples are uniquely determined by the latent variables, and Experiments (p. 6) explicitly identifies xT as the initial latent variable. (LLM, conf=0.94)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“They find that this metric better captures spatial relationships, rewarding image distributions with coherent high-level structure.”
What the sources say
- Partly supportedcites [42] [42] Charlie Nash, Jacob Menick, Sander Dieleman, and Peter W. Battaglia. Generating images with sparse representations. arXiv:2103.03841, 2021. sourceExperimental — accuracy not yet measured
In §4, the authors say sFID uses intermediate spatial features because standard FID features compress spatial information, supporting the spatial-relationships part. But §4.1 says DCTransformer performs better on sFID despite producing samples that are less reliably coherent than GAN samples. The paper therefore does not support the claim that sFID rewards coherent high-level structure. (LLM, conf=0.86)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“BigGAN-deep [5] 64-128 6.02 7.18 0.86 0.35 ADM-G (4360K) 521 9 530 3.09 5.59 0.82 0.54 ADM-G (450K) 54 9 63 5.67 6.19 0.82 0.49”
What the sources say
- Partly supportedcites [5] [5] Andrew Brock, Jeff Donahue, and Karen Simonyan. Large scale gan training for high fidelity natural image synthesis. arXiv:1809.11096, 2018. sourceExperimental — accuracy not yet measured
The citation identifies BigGAN-deep, and the source’s Table 2 (p. 7, reproduced in the 4.3 Summary) reports its ImageNet 128×128 FID as 5.7 ± 0.3. It does not give the cited comparison’s exact 6.02 FID or 64–128 V100-days. The ADM-G figures are in the citing paper’s row, not findings attributed to this source. (LLM, conf=0.87)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Partly supported
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“This greatly improves FID on ImageNet 256×256, but does not reach the same performance as state-of-the-art models like BigGAN-deep [43, 53], as seen in Table 5.”
§ 5 Results > 5.2 Comparison to Upsampling
What the sources say
- Supportedcites [43] [43] Alex Nichol and Prafulla Dhariwal. Improved denoising diffusion probabilistic models. arXiv:2102.09672, 2021. source
Table 5 in “Sample Quality on ImageNet 256 × 256” (p. 12) reports that the two-stage diffusion model improves FID from 31.5 for the single-stage model to 12.3, but remains behind BigGAN-deep at 7.0. The comparison is for class-conditional ImageNet 256 × 256. (LLM, conf=0.94)
- Partly supportedcites [53] [53] Chitwan Saharia, Jonathan Ho, William Chan, Tim Salimans, David J. Fleet, and Mohammad Norouzi. Image super-resolution via iterative refinement. arXiv:arXiv:2104.07636, 2021. 15 https://arxiv.org/abs/1711.05101 https://arxiv.org/abs/1903.02271 https://arxiv.org/abs/2101.02388 https://arxiv.org/abs/1710.03740 https://arxiv.org/abs/1411.1784 https://arxiv.org/abs/1802.05637 https://arxiv.org/abs/1802.05957 https://arxiv.org/abs/2103.03841 https://arxiv.org/abs/2102.09672 https://github.com/NVlabs/stylegan2 https://arxiv.org/abs/2104.11222 https://arxiv.org/abs/1912.01703 https://arxiv.org/a sourceExperimental — accuracy not yet measured
Section 4.7, Table 5 reports an FID of 11.3 for two-stage SR3, versus 38.1 for VQ-VAE-2 and 7.4 for BigGAN at truncation 1.0. But SR3 slightly outperforms BigGAN at truncation 1.5 (11.8), so the unqualified statement that it does not reach BigGAN's performance overstates the comparison. (LLM, conf=0.88)
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Supported
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We show the same result on ImageNet 128×128, finding that architecture can indeed give a substantial boost to sample quality on much larger and more diverse datasets at a higher resolution.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We show that diffusion models can achieve image sample quality superior to the current state-of-the-art generative models.”
- Also stated in: § 1 Introduction · plain
“With these improvements, we achieve a new state-of-the-art, surpassing GANs on several different metrics and datasets.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Also stated in: § 1 Introduction · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our diffusion models can obtain the best FID on each task, and the best sFID on all but one task.”
§ 5 Results > 5.1 State-of-the-art Image Synthesis
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Aside from rescaling residual connections, all of the other modifications improve performance and have a positive compounding effect.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Table 2 shows our results, indicating that more heads or fewer channels per head improves FID.”
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Figure 7 shows our results, revealing that the samples are indeed unique and not stored in the training set.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, we noticed some noise artifacts when reversing all 250 steps, and find that reversing the first 249 steps gives much better reconstructions.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“We note that our classifier training is relatively lightweight compared to training the generative model.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We find that the sweep schedule produces better results than the uniform 250 step schedule on all three datasets, and mostly bridges the gap to the 1000 step schedule.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Table 4 also shows that classifier guidance improves precision at the cost of recall, thus introducing a trade-off in sample fidelity versus diversity.”
§ 4 Classifier Guidance > 4.3 Scaling Classifier Gradients
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We find that two techniques behave similarly, and neither technique provides any substantial improvement in our evaluation metrics.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These models obtain perceptual quality similar to GANs, while maintaining a higher coverage of the distribution as measured by recall, and can even do so using only 25 diffusion steps.”
§ 5 Results > 5.1 State-of-the-art Image Synthesis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We find that a naive implementation of our models in PyTorch 1.7 is very inefficient, utilizing only 20-30% of the hardware.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Scaling up the classifier gradients remedied this problem, and the class probabilities from the classifier increased to nearly 100%.”
§ 4 Classifier Guidance > 4.3 Scaling Classifier Gradients
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We also find that low temperatures have both low precision and low recall, indicating that the model is not focusing on modes of the real data distribution.”
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our improved architecture is sufficient to achieve this on unconditional image generation tasks, and our classifier guidance technique allows us to do so on class-conditional tasks.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“LSUN Horse 256×256 StyleGAN2 [28] 130 3.84 6.46 0.63 0.48 ADM (250K) 116 - 116 2.95 5.94 0.69 0.55”
What the sources say
- Not matchedcites [28] [28] Tero Karras, Samuli Laine, Miika Aittala, Janne Hellsten, Jaakko Lehtinen, and Timo Aila. Analyzing and improving the image quality of stylegan. arXiv:1912.04958, 2019.
Couldn’t be matched to a paper in Crossref, so it can’t be checked.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Not matched
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We had already seen AdaGN improve our earliest diffusion models”
§ 1 head > 3.1 Adaptive Group Normalization
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For our ImageNet 128×128 model in particular, we find that we can increase the per-GPU batch size from 4 to 32 while still fitting in GPU memory, and this makes a large utilization difference.”
plaindirectSingle case- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“When using a scale of 1, we observed that the classifier assigned reasonable probabilities (around 50%) to the desired classes for the final samples, but these samples did not match the intended classes upon visual inspection.”
§ 4 Classifier Guidance > 4.3 Scaling Classifier Gradients
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We see that the model with no guidance has almost perfect reconstructions due to its high recall, whereas raising the guidance scale to 2.5 only finds approximately similar reconstructions.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“it increases training time and takes longer to reach the same performance as a wider model”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In Table 6, we show that guidance and upsampling improve sample quality along different axes.”
§ 5 Results > 5.2 Comparison to Upsampling
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
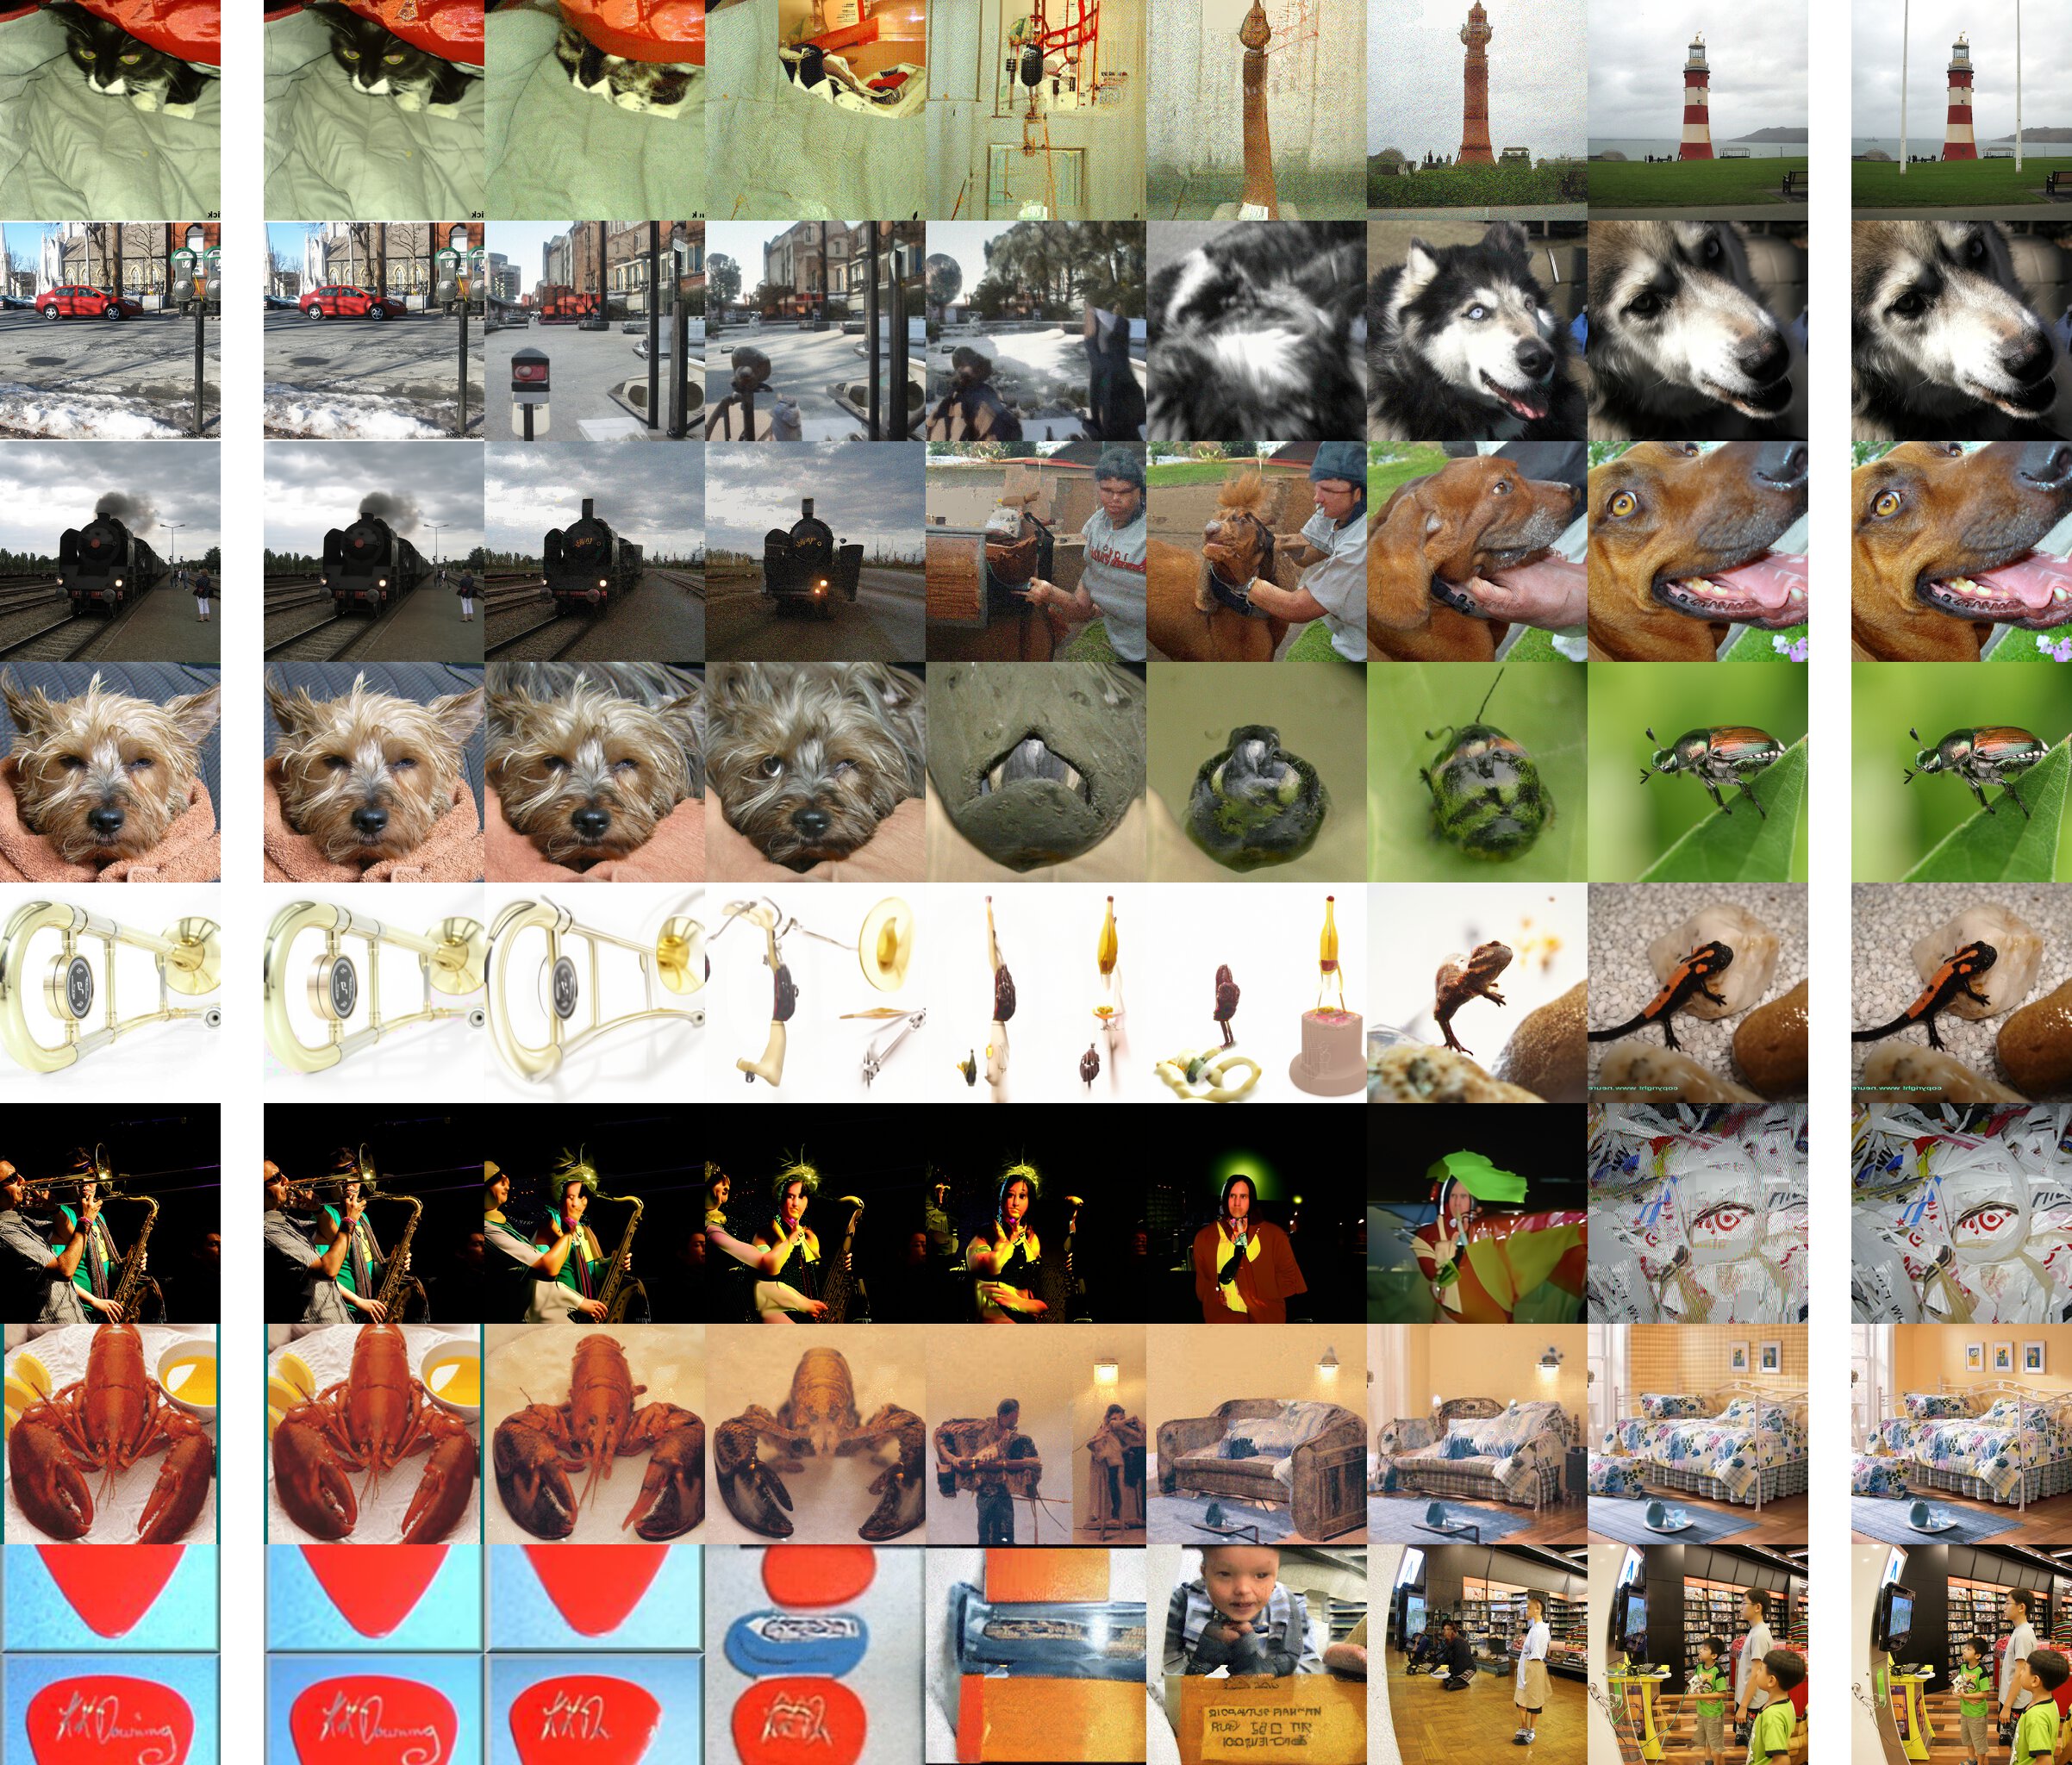
“We observe that the classifier drastically changes some images, while leaving others relatively unaffected.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
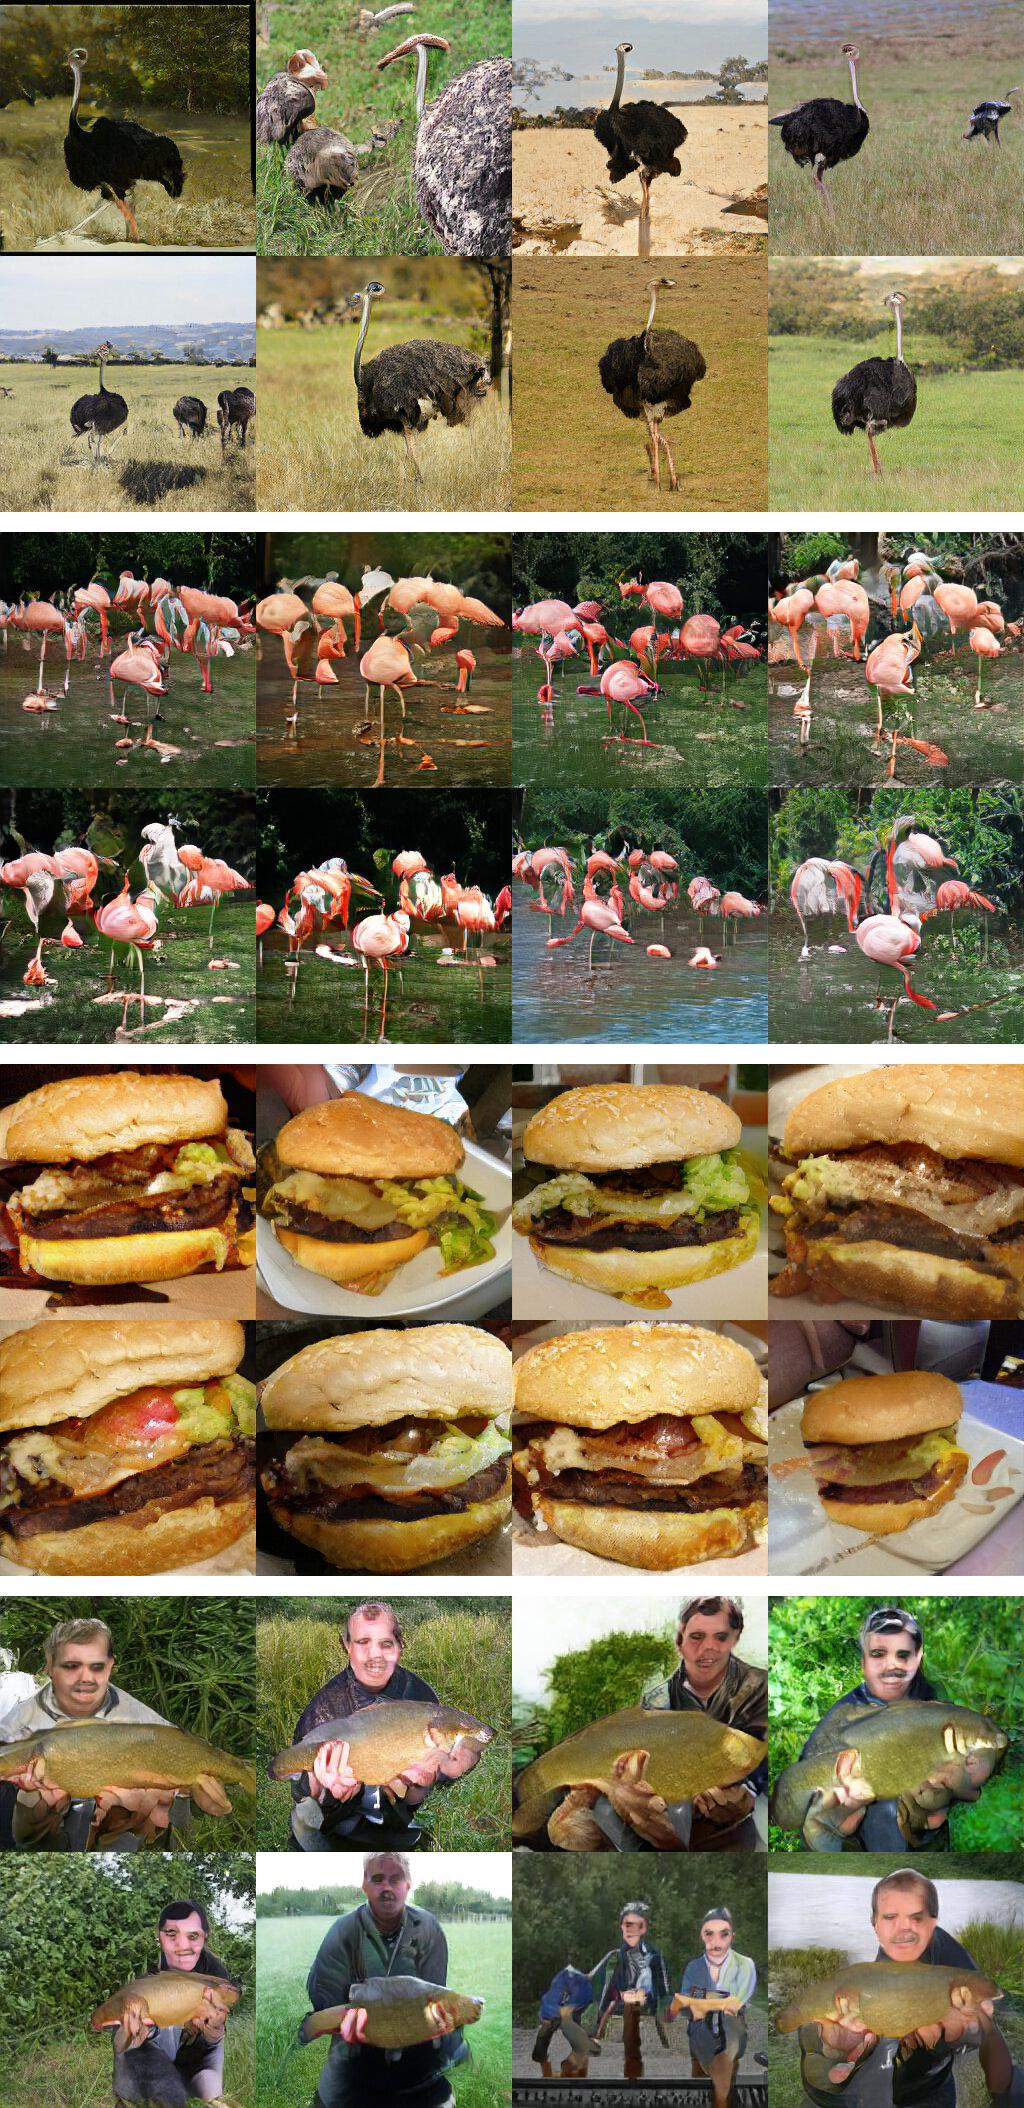
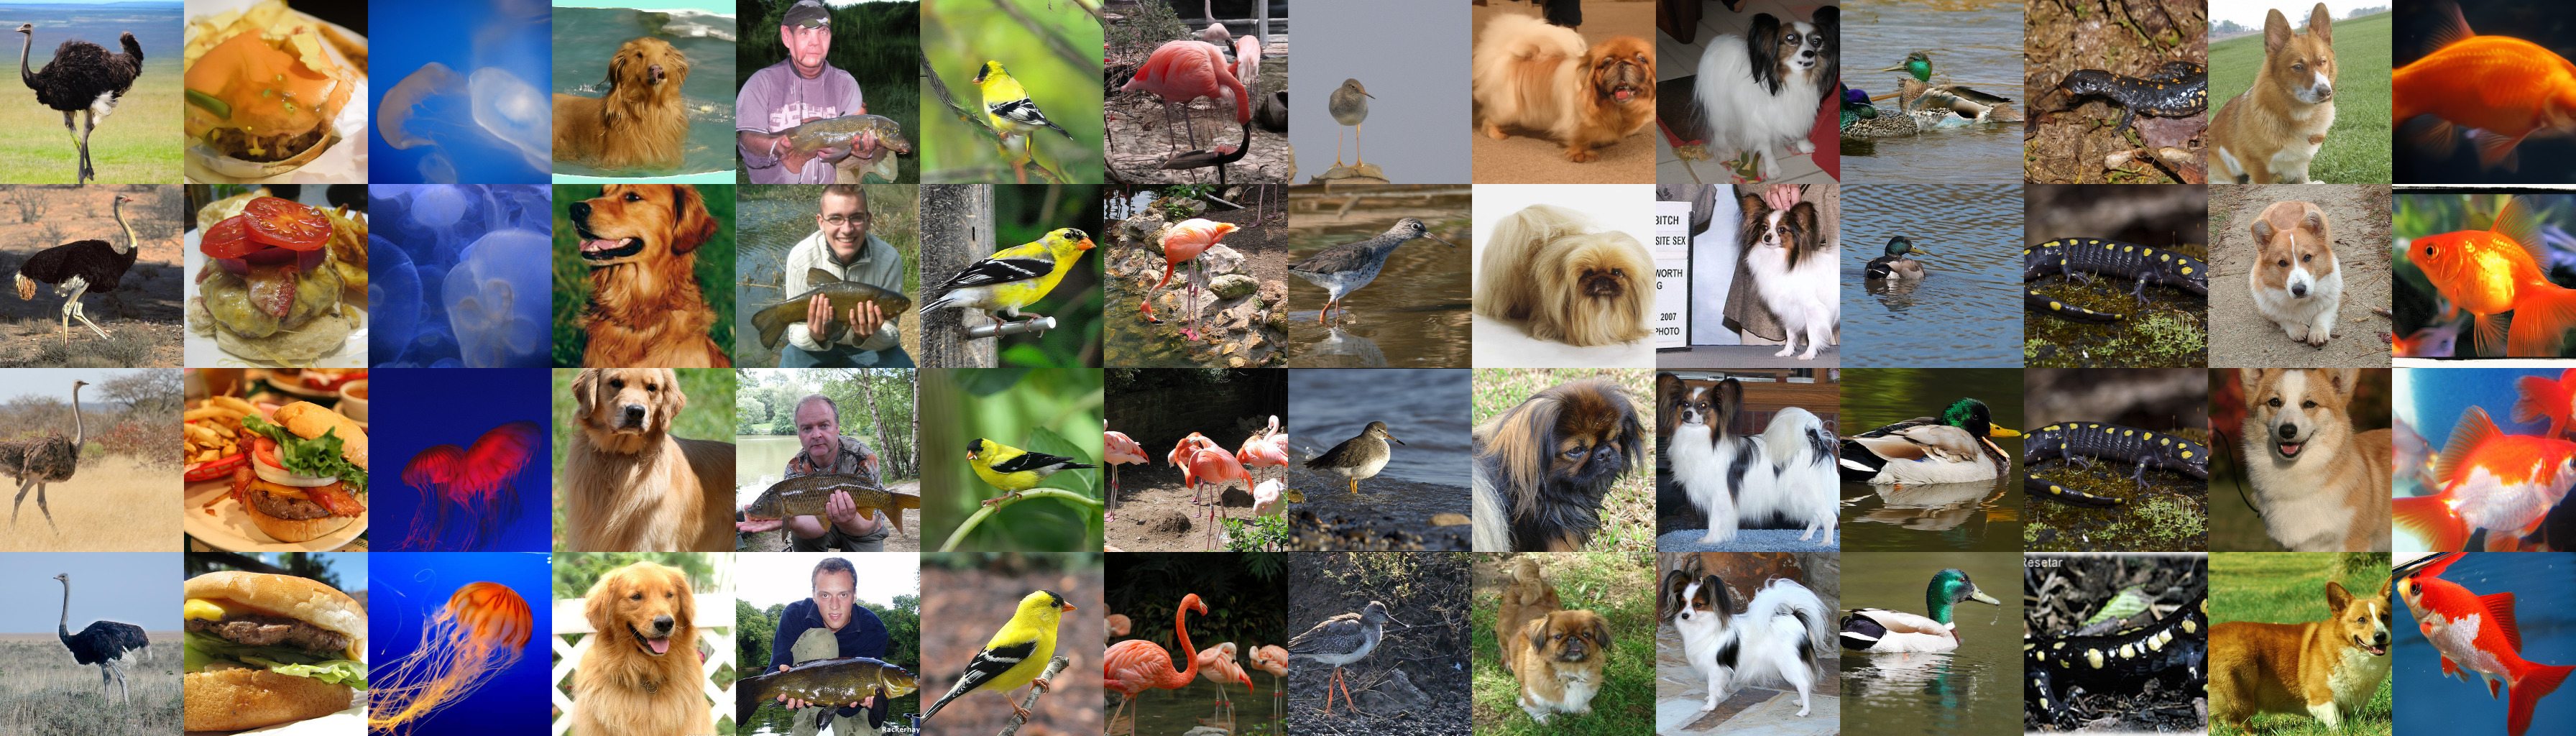
“While the samples are of similar perceptual quality, the diffusion model contains more modes than the GAN, such as zoomed ostrich heads, single flamingos, different orientations of cheeseburgers, and a tinca fish with no human holding it.”
§ 5 Results > 5.1 State-of-the-art Image Synthesis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We observe in Figure 2 that while increased depth helps performance”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“Ho et al. [25] show that, under reasonable assumptions, we can model the distribution pθ(xt−1|xt) of xt−1 given xt as a diagonal Gaussian”
What the sources say
- Not checked yetcites [25] [25] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv:2006.11239, 2020.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“while offering desirable properties such as distribution coverage, a stationary training objective, and easy scalability.”
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Ho et al. [25] observe that the simple mean-sqaured error objective, Lsimple, works better in practice than the actual variational lower bound Lvlb”
What the sources say
- Not checked yetcites [25] [25] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv:2006.11239, 2020.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Furthermore, except for VAEs, sampling from these models is slower than GANs in terms of wall-clock time.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As a result, we did not conduct an exhaustive sweep, and superior schedules are likely to exist.”
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it.
In the paper
“While the above objective is well-justified, Ho et al. [25] found that a different objective produces better samples in practice.”
What the sources say
- Not checked yetcites [25] [25] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv:2006.11239, 2020.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“It is typically intractable to sample from this distribution exactly”
§ 4 Classifier Guidance > 4.1 Conditional Reverse Noising Process
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These guided diffusion models can reduce the sampling time gap between GANs and diffusion models, although diffusion models still require multiple forward passes during sampling.”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“Ho et al. [25] introduced the UNet architecture for diffusion models”
What the sources say
- Not checked yetcites [25] [25] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv:2006.11239, 2020.
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
In the paper
“For many classes of generative models, there is a much simpler way to reduce diversity: reducing the temperature [1].”
What the sources say
- Not checked — no full text of the sourcecites [1] [1] David Ackley, Geoffrey Hinton, and Terrence Sejnowski. A learning algorithm for boltzmann machines. Cognitive science, 9(1):147-169, 1985. source
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We thus want to sample from the distribution Zq(xt|xt+1)q̂(y|xt) where Z is a normalizing constant.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
- The authors state this as an assumption: The label distribution q̂(y|x0) is known and readily available for each sample.
In the paper
“Ho et al. [25] note that we need not apply q repeatedly to sample from xt ∼ q(xt|x0).”
What the sources say
- Not checked yetcites [25] [25] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv:2006.11239, 2020.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Our proposed classifier guidance technique is currently limited to labeled datasets, and we have provided no effective strategy for trading off diversity for fidelity on unlabeled datasets.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Finally, we can define a new epsilon prediction ε̂(xt) which corresponds to the score of the joint distribution:”
§ 4 Classifier Guidance > 4.2 Conditional Sampling for DDIM
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“they are still slower than GANs at sampling time due to the use of multiple denoising steps (and therefore forward passes).”
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“As a result, we did not conduct an exhaustive sweep, and superior schedules are likely to exist.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“When comparing against other methods, we re-compute these metrics using public samples or models whenever possible.”
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
In the paper
“Ho et al. [25] find that instead of learning Σθ(xt, t), they can fix it to a constant, choosing either βtI or β̃tI.”
What the sources say
- Not checked yetcites [25] [25] Jonathan Ho, Ajay Jain, and Pieter Abbeel. Denoising diffusion probabilistic models. arXiv:2006.11239, 2020.
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The authors state this as an assumption.
The noise ε is drawn from a diagonal Gaussian distribution.
“For the remainder of this paper, we assume that the noise ε is drawn from a diagonal Gaussian distribution”
The authors state this as an assumption.
logφ p(y|xt) has low curvature compared to Σ−1.
“We can assume that logφ p(y|xt) has low curvature compared to Σ−1.”
The authors state this as an assumption.
The underlying diffusion model is unconditional in the above derivations.
“In the above derivations, we assumed that the underlying diffusion model was unconditional, modeling p(x).”
The paper relies on this without support.
More compute typically yields better results.
“Compute is essential to modern machine learning applications, and more compute typically yields better results.”
The authors state this as an assumption.
The label distribution q̂(y|x0) is known and readily available for each sample.
“we start by defining a conditional Markovian noising process q̂ similar to q, and assume that q̂(y|x0) is a known and readily available label distribution for each sample.”
The paper relies on this without support.
Under reasonable settings for βt and T, the distribution q(xT) is nearly an isotropic Gaussian distribution.
“Under reasonable settings for βt and T , the distribution q(xT ) is nearly an isotropic Gaussian distribution, so sampling xT is trivial.”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Diffusion models can produce more realistic images compared to GANs and VAEs (Aghasanli etal. 2023; Dhariwal and Nichol 2021).”
From Deepfake video detection: challenges and opportunities (2024) · cites this paper as Dhariwal and Nichol 2021
Experimental — accuracy not yet measuredThe source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“PSNR and SSIM can be pushed by using a post-hoc guiding mechanism [15] and we implement this image-based guider via a perceptual loss, see Sec. D.6.”
From High-Resolution Image Synthesis with Latent Diffusion Models (2022) · cites this paper as [15]
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Recently, Diffusion Probabilistic Models (DM) have outperformed GANs in image synthesis, demonstrating superior results in terms of both quality and diversity [42,67,85,86,140,164].”
From Past, Present, and Future of Sensor-based Human Activity Recognition Using Wearables: A Surveying Tutorial on a Still Challenging Task (2025) · cites this paper as [42]
The cited source says what the claim attributes to it.
In the citing paper
“The final FID scores are 4.1 (Lion) vs. 4.7 (AdamW), and for reference, the FID of ADM (Dhariwal and Nichol, 2021) is 10.94.”
From Symbolic Discovery of Optimization Algorithms (2023) · cites this paper as Dhariwal and Nichol, 2021
The cited source says what the claim attributes to it.
In the citing paper
“and define the state-of-the-art in class-conditional image synthesis [15,31] and super-resolution [72].”
From High-Resolution Image Synthesis with Latent Diffusion Models (2022) · cites this paper as [15]
The cited source says what the claim attributes to it.
In the citing paper
“training the most powerful DMs often takes hundreds of GPU days (e.g. 150 - 1000 V100 days in [15]) and repeated evaluations on a noisy version of the input space render also inference expensive”
From High-Resolution Image Synthesis with Latent Diffusion Models (2022) · cites this paper as [15]
The cited source says what the claim attributes to it.
In the citing paper
“Recently, Diffusion Probabilistic Models (DM) [82], have achieved state-of-the-art results in density estimation [45] as well as in sample quality [15].”
From High-Resolution Image Synthesis with Latent Diffusion Models (2022) · cites this paper as [15]
The cited source says what the claim attributes to it.
In the citing paper
“In particular, [15] presented an algorithm to guide both unconditional and conditional models trained on the ImageNet dataset with a classifier log pΦ(y|xt), trained on each xt of the diffusion process.”
From High-Resolution Image Synthesis with Latent Diffusion Models (2022) · cites this paper as [15]
The cited source says what the claim attributes to it.
In the citing paper
“This can be interpreted as an update correcting the”
From High-Resolution Image Synthesis with Latent Diffusion Models (2022) · cites this paper as [15]
The cited source says what the claim attributes to it.
In the citing paper
“An intriguing feature of diffusion models is that unconditional models can be conditioned at test-time [15, 82, 85].”
From High-Resolution Image Synthesis with Latent Diffusion Models (2022) · cites this paper as [15]
The cited source says what the claim attributes to it.
In the citing paper
“We closely reach the performance of state of the art methods as StyleGAN2 [42] and ADM [15] while significantly reducing the required compute resources.”
From High-Resolution Image Synthesis with Latent Diffusion Models (2022) · cites this paper as [15]
The check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“so that producing 50k samples takes approximately 5 days [15] on a single A100 GPU.”
From High-Resolution Image Synthesis with Latent Diffusion Models (2022) · cites this paper as [15]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ References
“ADM-G (540K), ADM-U (500K) 329 30 359 3.85 5.86 0.84 0.53”
§ 5 Results > 5.2 Comparison to Upsampling
“ADM-G, ADM-U 250 250 3.94 6.14 215.84 0.83 0.53”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“ADM-G (200K), ADM-U (150K) 110 10‡ 126 4.93 5.82 0.82 0.52”
Reported 126 · recomputed 120
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ 4 Classifier Guidance > 4.1 Conditional Reverse Noising Process
“Algorithm 2 Classifier guided DDIM sampling, given a diffusion model εθ(xt), classifier pφ(y|xt), and gradient scale s.”
§ 4 Classifier Guidance > 4.1 Conditional Reverse Noising Process
“ε̂← εθ(xt)− √ 1− ᾱt∇xt log pφ(y|xt)”
Citations
Cites
Part of this paper’s reference list could not be split into single entries.
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Adam: A Method for Stochastic Optimization
Kingma, D. P., & Ba, J. (2014) · arXiv · doi:10.48550/arxiv.1412.6980 · Cited by 98,946
PyTorch: An Imperative Style, High-Performance Deep Learning Library
Paszke, A., Gross, S., Massa, F., Lerer, A., Bradbury, J., Chanan, G., Killeen, T., Lin, Z., Gimelshein, N., Antiga, L., et al. (2019) · arXiv · doi:10.48550/arxiv.1912.01703 · Cited by 31,473
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Self-citationLearning Transferable Visual Models From Natural Language Supervision
Radford, A., Kim, J. W., Hallacy, C., Ramesh, A., Goh, G., Agarwal, S., Sastry, G., Askell, A., Mishkin, P., Clark, J., et al. (2021) · arXiv · doi:10.48550/arxiv.2103.00020 · Cited by 15,293
Decoupled Weight Decay Regularization
Loshchilov, I., & Hutter, F. (2017) · arXiv · doi:10.48550/arxiv.1711.05101 · Cited by 12,522
A Style-Based Generator Architecture for Generative Adversarial Networks
Karras, T., Laine, S., & Aila, T. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00453 · Cited by 11,714
Conditional Generative Adversarial Nets
Mirza, M., & Osindero, S. (2014) · arXiv · doi:10.48550/arxiv.1411.1784 · Cited by 8,863
Denoising Diffusion Probabilistic Models
Ho, J., Jain, A., & Abbeel, P. (2020) · arXiv · doi:10.48550/arxiv.2006.11239 · Cited by 8,712
GANs Trained by a Two Time-Scale Update Rule Converge to a Local Nash Equilibrium
Heusel, M., Ramsauer, H., Unterthiner, T., Nessler, B., & Hochreiter, S. (2017) · arXiv · doi:10.48550/arxiv.1706.08500 · Cited by 8,365
Research works printed but not linked: 1
- [12][12] DeepMind. Biggan-deep 128x128 on tensorflow hub. https://tfhub.dev/deepmind/ biggan-deep-128/1, 2018. 13 https://twitter.com/advadnoun/status/1351038053033406468 https://twitter.com/advadnoun/status/1351038053033406468 https://arxiv.org/abs/1801.01973 https://arxiv.org/abs/1609.07093 https://arxiv.org/abs/1809.11096 https://arxiv.org/abs/2005.14165 https://arxiv.org/abs/2009.00713 https://arxiv.org/abs/2011.10650 https://arxiv.org/abs/1707.00683 https://tfhub.dev/deepmind/biggan-deep-128/1 https://tfhub.dev/deepmind/biggan-deep-128/1 · arXiv
Cited by
Sorted by citations
Items 2,501–2,600 of 3,985
Diffusion Model-Based Augmentation Using Asymmetric Attention Mechanisms for Cardiac MRI Images
Özdemir, M., & Eroğul, O. (2025) · Diagnostics · doi:10.3390/diagnostics15161985 · Cited by 4
Kim, S., Xin, X., Kim, S.-Y., Kim, G. D., Baek, M.-G., Won, D. Y., Baek, C. H., & Kim, G. (2025) · Plant Phenomics · doi:10.1016/j.plaphe.2025.100097 · Cited by 4
Frequency-sensitive diffusion model for personalized sequential recommendation
Wei, L., Ni, R., Wei, J., & Jiang, Y. (2025) · Neurocomputing · doi:10.1016/j.neucom.2025.131313 · Cited by 4
Li, G., Jiang, C., Li, J., Wan, J., Zhou, M., & Han, D. (2025) · Expert Systems with Applications · doi:10.1016/j.eswa.2025.129844 · Cited by 4
Camagni, F., Nakas, A., Parrella, G., Vai, A., Molinelli, S., Vitolo, V., Barcellini, A., Chalaszczyk, A., Imparato, S., Pella, A., et al. (2025) · Medical & Biological Engineering & Computing · doi:10.1007/s11517-025-03437-4 · Cited by 4
MusicSwarm: Biologically Inspired Intelligence for Music Composition
Buehler, M. J. (2026) · Advanced Intelligent Systems · doi:10.1002/aisy.202501253 · Cited by 4
Ensemble score filter for data assimilation of two-phase flow models in porous media
Hu, R., Poudel, S., Bao, F., & Lee, S. (2025) · Journal of Computational Physics · doi:10.1016/j.jcp.2025.114416 · Cited by 4
Lai, N., Dewi, D. A., & Maidin, S. S. (2025) · SICE Journal of Control Measurement and System Integration · doi:10.1080/18824889.2025.2567085 · Cited by 4
Wen, Z., Lian, Y., Zeng, L., Tian, C., Li, J., & Shao, X. (2025) · Aerospace Science and Technology · doi:10.1016/j.ast.2025.111070 · Cited by 4
Fast and Fluent Diffusion Language Models via Convolutional Decoding and Rejective Fine-tuning
Seo, Y., Lee, D., Kim, J., & Yeo, J. (2025) · neural information processing systems · doi:10.52202/085713-3719 · Cited by 4
CD-TVD: Contrastive Diffusion for 3D Super-Resolution with Scarce High-Resolution Time-Varying Data
Bi, C., Gao, X., Deng, J., Li, G., & Han, J. (2025) · IEEE Transactions on Visualization and Computer Graphics · doi:10.1109/tvcg.2025.3634787 · Cited by 4
Asali, E., Li, G., Saeidifar, M., Liu, T. S., Oso, O. M., Mandiga, A., Bodempudi, V. U. C., & Kota, S. A. R. (2025) · Computers and Electronics in Agriculture · doi:10.1016/j.compag.2025.111305 · Cited by 4
Ohnuki, J., & Okazaki, K.-I. (2026) · JACS Au · doi:10.1021/jacsau.6c00596 · Cited by 4
Wang, Z., García, C. G., & Halpern, B. S. (2026) · International Journal of Applied Earth Observation and Geoinformation · doi:10.1016/j.jag.2025.105046 · Cited by 4
A survey on design choices for self-supervised learning in computer vision
Wittscher, L. (2026) · Artificial Intelligence Review · doi:10.1007/s10462-026-11506-9 · Cited by 4
Prabhu, O., Naik, S. S., Prarthana, B. K., Prabhu, S., & Chadaga, K. (2026) · Systems and Soft Computing · doi:10.1016/j.sasc.2026.200476 · Cited by 4
Translation-based multimodal learning: a survey
Lu, Z., Liao, Y., & Li, J. (2025) · Intelligence & Robotics · doi:10.20517/ir.2025.40 · Cited by 4
Bayesian Cramér-Rao Bound Estimation With Score-Based Models
Crafts, E. S., & Zhao, B. (2023) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49357.2023.10095110 · Cited by 4
Li, L., Li, Q., Yong, W., Zhang, S., Yang, M., & Jiang, P. (2023) · Systems · doi:10.3390/systems11090484 · Cited by 4
Liang, 林. L., & Binbin, 杨. Y. (2023) · Acta Optica Sinica · doi:10.3788/aos230758 · Cited by 4
Complex Event Schema Induction with Knowledge-Enriched Diffusion Model
Hao, Y., Cao, P., Chen, Y., Liu, K., Xu, J., Li, H., Jiang, X., & Zhao, J. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.319 · Cited by 4
Difforecast: Image Generation Based Highway Traffic Forecasting with Diffusion Model
Chi, P., & Ma, X. (2023) · IEEE International Conference on Big Data (BigData) · doi:10.1109/bigdata59044.2023.10386463 · Cited by 4
An Overview of OpenAI's Sora and Its Potential for Physics Engine Free Games and Virtual Reality
Chen, Z., Li, S., & Haque, M. A. (2024) · EAI Endorsed Transactions on AI and Robotics · doi:10.4108/airo.5273 · Cited by 4
Denoising Diffusion Probabilistic Models for Action-Conditioned 3D Motion Generation
Zhao, M., Liu, M., Ren, B., Dai, S., & Sebe, N. (2024) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp48485.2024.10446185 · Cited by 4
Audio-Journey: Open Domain Latent Diffusion Based Text-To-Audio Generation
Michaels, J., Li, J. B., Yao, L., Yu, L., Wood-Doughty, Z., & Metze, F. (2024) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp48485.2024.10448220 · Cited by 5
Improving Denoising Diffusion Probabilistic Models via Exploiting Shared Representations
Pirhayatifard, D., Toghani, M. T., Balakrishnan, G., & Uribe, C. A. (2023) · Asilomar Conference on Signals, Systems and Computers (ACSSC) · doi:10.1109/ieeeconf59524.2023.10476867 · Cited by 4
Lu, R. M. T. (2024) · International Journal of Adaptive Control and Signal Processing · doi:10.1002/acs.3817 · Cited by 4
Generating Synthetic Images Using Stable Diffusion Model for Skin Lesion Classification
Patcharapimpisut, P., & Khanarsa, P. (2024) · International Conference on Knowledge and Smart Technology · doi:10.1109/kst61284.2024.10499667 · Cited by 4
Agricultural Applicability of AI based Image Generation
Yoon, S., Lee, Y., Jung, E., & Ahn, T. I. (2024) · Journal of Bio-Environment Control · doi:10.12791/ksbec.2024.33.2.120 · Cited by 4
Wu, J. B., Xie, R., Wu, H., & Yuan, G. (2024) · IET Image Processing · doi:10.1049/ipr2.13122 · Cited by 4
Lee, D., Chen, W., & Rojas, N. (2024) · International Conference on Mechatronics and Robotics Engineering (ICMRE) · doi:10.1109/icmre60776.2024.10532168 · Cited by 4
Unsupervised Anomaly Detection of Industrial Images Based on Dual Generator Reconstruction Networks
Gu, C., Ren, S., & Duan, Q. (2024) · Information Technology And Control · doi:10.5755/j01.itc.53.2.36018 · Cited by 4
Samson, G. (2024) · International Journal of Electronics and Telecommunications · doi:10.24425/ijet.2024.149550 · Cited by 4
Natural generative noise diffusion model imputation
Wibisono, A., Denny, D., Mursanto, P., & See, S. C. W. (2024) · Knowledge-Based Systems · doi:10.1016/j.knosys.2024.112310 · Cited by 4
Robust Cross-modal Medical Image Translation via Diffusion Model and Knowledge Distillation
Xia, Y., Feng, S., Zhao, J., & Yuan, Z. (2024) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn60899.2024.10650498 · Cited by 4
When guided diffusion model meets zero-shot image super-resolution
Liu, H., Shao, M., Shang, K., Qiao, Y., & Wang, S. (2024) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2024.109336 · Cited by 4
Primer on Generative Artificial Intelligence and Large Language Models in Medical Imaging
Kim, K., Hong, G.-S., & Kim, N. (2024) · Journal of the Korean Society of Radiology · doi:10.3348/jksr.2024.0066 · Cited by 4
Jin, S.-W., Noh, H., Go, M., & Lim, J. H. (2024) · Computational Materials Science · doi:10.1016/j.commatsci.2024.113441 · Cited by 4
Diffusion models for super-resolution microscopy: a tutorial
Bachimanchi, H., & Volpe, G. (2024) · Journal of Physics Photonics · doi:10.1088/2515-7647/ada101 · Cited by 4
ACMamba: A State Space Model-Based Approach for Multi-Weather Degraded Image Restoration
Wang, W., Pei, Z., Lei, W., & Ju, Y. (2024) · Electronics · doi:10.3390/electronics13214294 · Cited by 4
Unsupervised co-generation of foreground–background segmentation from Text-to-Image synthesis
Ahmed, Y. A., & Mittal, A. (2024) · Computer Vision and Image Understanding · doi:10.1016/j.cviu.2024.104223 · Cited by 4
Pal, B., Roy, A., Kathirvel, R. P., O’Toole, A. J., & Chellappa, R. (2024) · IEEE International Joint Conference on Biometrics (IJCB) · doi:10.1109/ijcb62174.2024.10744513 · Cited by 4
Robust Real-World Image Dehazing via Knowledge Guided Conditional Diffusion Model Finetuning
Wei, H., Wu, Q., Wu, C., Chen, S., Wang, L., Ngan, K. N., Meng, F., & Li, H. (2024) · IEEE International Workshop on Multimedia Signal Processing (MMSP) · doi:10.1109/mmsp61759.2024.10743595 · Cited by 4
WavePurifier: Purifying Audio Adversarial Examples via Hierarchical Diffusion Models
Guo, H., Wang, G., Chen, B., Wang, Y., Zhang, X., Chen, X., Yan, Q., & Xiao, L. (2024) · ACM Annual International Conference on Mobile Computing and Networking (MobiCom) · doi:10.1145/3636534.3690692 · Cited by 4
Ultrasound Image Enhancement with the Variance of Diffusion Models
Zhang, Y., Huneau, C., Idier, J., & Mateus, D. (2024) · IEEE Ultrasonics, Ferroelectrics, and Frequency Control Joint Symposium (UFFC-JS) · doi:10.1109/uffc-js60046.2024.10793819 · Cited by 4
DiffRSS: A Diffusion-Guided Multi-Scale Features Remote Sensing Image Segmentation Method
Liu, H., Yang, R., Xu, Y., Chen, Z., & Zheng, Y. (2024) · IEEE Access · doi:10.1109/access.2024.3522286 · Cited by 4
SketchTriplet: Self-Supervised Scenarized Sketch–Text–Image Triplet Generation
Wu, Z., Wang, Q., & Yang, J. (2025) · IEEE Internet of Things Journal · doi:10.1109/jiot.2024.3523382 · Cited by 4
VSRDiff: Learning Inter-Frame Temporal Coherence in Diffusion Model for Video Super-Resolution
Liu, L., Niu, L., Tang, J., & Ding, Y. S. (2025) · IEEE Access · doi:10.1109/access.2025.3529758 · Cited by 4
Personalized and Controllable Voice Style Transfer With Speech Diffusion Transformer
Choi, H.-Y., Lee, S.-H., & Lee, S.-W. (2025) · IEEE Transactions on Audio Speech and Language Processing · doi:10.1109/taslpro.2025.3533362 · Cited by 4
Terashita, N., Ohashi, H., & Hara, S. (2025) · IEEE Transactions on Neural Networks and Learning Systems · doi:10.1109/tnnls.2025.3529540 · Cited by 4
DiffusionLoc: A diffusion model-based framework for crowd localization
Zhang, Q., Li, Y., Liu, Y., Zhou, Y., & Jiao, J. (2025) · Image and Vision Computing · doi:10.1016/j.imavis.2025.105439 · Cited by 4
Dunhuang Art Style Transfer via Hierarchical Vision Transformer and Color Consistency Constraints
Cao, Y., Zhang, Y., Lin, Y., & Wu, K. (2025) · IEEE Transactions on Consumer Electronics · doi:10.1109/tce.2025.3547427 · Cited by 4
Diffusion Model with Multi-layer Wavelet Transform for Low-Light Image Enhancement
Jin, H., Wang, J., Zuo, F., Su, H., Xiao, Z., Wang, B., & Zhang, Y. (2025) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49660.2025.10888098 · Cited by 4
Expressive Image Generation and Editing with Rich Text
Ge, S., Park, T., Zhu, J.-Y., & Huang, J. (2025) · International Journal of Computer Vision · doi:10.1007/s11263-025-02361-2 · Cited by 4
High-Dimensional Radio Frequency Fingerprint Synthesis for Indoor Positioning
Lyu, Z., Chan, T. C. T., Leung, G. C. M., Chan, Y., Lun, D. P.-K., & PECHT, M. G. (2025) · IEEE Transactions on Instrumentation and Measurement · doi:10.1109/tim.2025.3551824 · Cited by 4
Semi-supervised semantic segmentation of cell nuclei with diffusion model and collaborative learning
Shao, Z., Sengupta, S., Anastasio, M. A., & Li, H. (2025) · Journal of medical imaging · doi:10.1117/1.jmi.12.6.061403 · Cited by 5
Al-Mohamade, A., Jarraya, S. K., & Alsolami, F. J. (2025) · Journal of Imaging · doi:10.3390/jimaging11040108 · Cited by 4
Latent Abstractions in Generative Diffusion Models
Franzese, G., Martini, M., Corallo, G., Papotti, P., & Pietro Michiardi, A. (2025) · Entropy · doi:10.3390/e27040371 · Cited by 4
GAUDA: Generative Adaptive Uncertainty-Guided Diffusion-Based Augmentation for Surgical Segmentation
Frisch, Y., Bornberg, C., Fuchs, M., & Mukhopadhyay, A. (2025) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61041.2025.00370 · Cited by 4
ColorizeDiffusion: Improving Reference-Based Sketch Colorization with Latent Diffusion Model
Yan, D., Yuan, L., Wu, E., Nishioka, Y., Fujishiro, I., & Saito, S. (2025) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61041.2025.00498 · Cited by 4
FitDiff: Robust Monocular 3D Facial Shape and Reflectance Estimation using Diffusion Models
Galanakis, S., Lattas, A., Moschoglou, S., & Zafeiriou, S. P. (2025) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61041.2025.00106 · Cited by 4
Huang, J., Li, M., & Chen, W. (2025) · Advanced Engineering Informatics · doi:10.1016/j.aei.2025.103298 · Cited by 5
Dynamic synthesis augmented TimeGAN and adaptive temperature control for microwave heating
Xu, J., Hao, K., Meng, C., Yan, C., Liu, X., & Wei, B. (2025) · Journal of Manufacturing Systems · doi:10.1016/j.jmsy.2025.03.026 · Cited by 4
Tandon, A., Sharma, G., Jaswal, G., Nigam, A., & Ramachandra, R. (2025) · IEEE/CVF Winter Conference on Applications of Computer Vision Workshops (WACVW) · doi:10.1109/wacvw65960.2025.00155 · Cited by 4
Responsible Diffusion Models via Constraining Text Embeddings within Safe Regions
Li, Z., Chen, D. Y., Fan, M., Chen, C., Li, Y., Wang, Y., & Zhou, W. (2025) · International World Wide Web Conference (WWW) · doi:10.1145/3696410.3714912 · Cited by 4
Qiao, Q., & Hou, X. (2025) · Biomedical Optics Express · doi:10.1364/boe.562924 · Cited by 4
SRP-CR: Semantic and Representational Priors for Diffusion-Based Cloud Removal
Zou, Z., Zhang, Z., Zhou, Y., & Jiang, X. (2025) · IEEE Journal of Selected Topics in Applied Earth Observations and Remote Sensing · doi:10.1109/jstars.2025.3581368 · Cited by 4
Hashemi, M. S., Delzendehrooy, F., Nguyen, K., Kirby, L., Song, X., & Sheidaei, A. (2025) · Journal of the Mechanics and Physics of Solids · doi:10.1016/j.jmps.2025.106253 · Cited by 4
Learning and Generation of Drawing Sequences Using a Deep Network for a Drawing Support System
Matsumoto, H., Nakamura, A., & Nishide, S. (2025) · Applied Sciences · doi:10.3390/app15137038 · Cited by 4
Abud, K., Lavrushkin, S., & Vatolin, D. S. (2025) · Big Data and Cognitive Computing · doi:10.3390/bdcc9070166 · Cited by 4
Elevating GPR Imaging With DDPM: A Comprehensive Study on Synthetic Data Generation
Chen, G., Hu, C., Hou, L., Ge, S., Zhang, Y., Wang, C., Fu, L., & Zhao, Y. (2025) · IEEE Transactions on Geoscience and Remote Sensing · doi:10.1109/tgrs.2025.3585865 · Cited by 3
ThermalDiff: A diffusion architecture for thermal image synthesis
Qazi, T., Lall, B., & Mukherjee, P. (2025) · Journal of Visual Communication and Image Representation · doi:10.1016/j.jvcir.2025.104524 · Cited by 4
ClusterDDPM: An EM clustering framework with Denoising Diffusion Probabilistic Models
Yan, J., Liu, J., & Zhang, Z. (2025) · Information Sciences · doi:10.1016/j.ins.2025.122518 · Cited by 4
Lyu, M., Yu, L., Wang, R., & Fang, Y. (2025) · Mechanical Systems and Signal Processing · doi:10.1016/j.ymssp.2025.113091 · Cited by 4
Ahamed, S., & Rahmim, A. (2025) · Computerized Medical Imaging and Graphics · doi:10.1016/j.compmedimag.2025.102615 · Cited by 4
Image harmonization in complex degradation scenes
Li, G., Zhao, B., & Li, X. (2025) · Pattern Recognition · doi:10.1016/j.patcog.2025.112227 · Cited by 4
Schrödinger bridge based deep conditional generative learning
Huang, H., & Huang, M. (2025) · Journal of Multivariate Analysis · doi:10.1016/j.jmva.2025.105486 · Cited by 4
Personalized Image Generation for Recommendations Beyond Catalogs
Patron, G. A. (2025) · ACM Conference on Recommender Systems (RecSys) · doi:10.1145/3705328.3748757 · Cited by 4
Wang, J., Shi, Z., Gu, X., Yang, Y. C., & Sun, J. (2025) · Medical Image Analysis · doi:10.1016/j.media.2025.103814 · Cited by 4
Generative diffusion model surrogates for mechanistic agent-based biological models
Comlekoglu, T., Toledo-Marín, J. Q., DeSimone, D. W., Peirce, S. M., Fox, G., & Glazier, J. A. (2025) · Machine Learning Science and Technology · doi:10.1088/2632-2153/ae11f8 · Cited by 4
DeDiM: De-identification using a diffusion model
Uchida, H., Abe, N., & Yamada, S. (2022) · International Conference of the Biometrics Special Interest Group (BIOSIG) · doi:10.1109/biosig55365.2022.9896972 · Cited by 4
WALDO: Future Video Synthesis using Object Layer Decomposition and Parametric Flow Prediction
Moing, G. L., Ponce, J., & Schmid, C. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.02123 · Cited by 4
Mimicking DBS halftoning via a deep learning approach
Choi, B., & Allebach, J. P. (2022) · Electronic Imaging · doi:10.2352/ei.2022.34.15.color-158 · Cited by 4
Portrait Reification with Generative Diffusion Models
Asperti, A., Colasuonno, G., & Guerra, A. (2023) · Applied Sciences · doi:10.3390/app13116487 · Cited by 4
Denoising Diffusion Models on Model-Based Latent Space
Scribano, C., Pezzi, D., Franchini, G., & Prato, M. (2023) · Algorithms · doi:10.3390/a16110501 · Cited by 4
Wu, T., Shi, L., Zhang, L., Wen, X., Lu, J., & Li, Z. (2023) · Applied Sciences · doi:10.3390/app132212206 · Cited by 4
Privacy through Diffusion: A White-listing Approach to Sensor Data Anonymization
Yang, X., & Ardakanian, O. (2023) · ACM Workshop on CPS&IoT Security and Privacy (CPSIoTSec) · doi:10.1145/3605758.3623496 · Cited by 4
Text-Conditioned Sampling Framework for Text-to-Image Generation with Masked Generative Models
Lee, J., Jang, S., Jo, J., Yoon, J., Kim, Y., Kim, J.-H., Ha, J.-W., & Hwang, S. J. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.02125 · Cited by 4
Behind the AI Art Creation: A Study of Generative Models for Text-to-Image Generation
Zhao, L., & Zhang, H. (2024) · International Conference on Art Design and Digital Technology (ADDT) · doi:10.4108/eai.15-9-2023.2340842 · Cited by 4
Voiceextender: Short-Utterance Text-Independent Speaker Verification With Guided Diffusion Model
He, Y., Kang, Z., Wang, J., Peng, J., & Xiao, J. Z. (2023) · IEEE Workshop on Automatic Speech Recognition and Understanding (ASRU) · doi:10.1109/asru57964.2023.10389784 · Cited by 4
Learning Based Infinite Terrain Generation with Level of Detailing
Jain, A., Sharma, A. K., & Rajan, K. S. (2024) · International Conference on 3D Vision (3DV) · doi:10.1109/3dv62453.2024.00077 · Cited by 4
Ding, X., Wang, Y., & Xu, Z. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i10.29065 · Cited by 4
Javaheri, A. H., Motamednia, H., & Mahmoudi-Azanveh, A. (2024) · Iranian Conference on Machine Vision and Image Processing · doi:10.1109/mvip62238.2024.10491148 · Cited by 4
FacadeNet: Conditional Facade Synthesis via Selective Editing
Georgiou, Y., Loizou, M., Kelly, T., & Averkiou, M. (2024) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv57701.2024.00530 · Cited by 4
Generating Point Cloud Augmentations via Class-Conditioned Diffusion Model
Sharma, G., Gupta, C., Agarwal, A., Sharma, L., & Dhall, A. (2024) · IEEE/CVF Winter Conference on Applications of Computer Vision Workshops (WACVW) · doi:10.1109/wacvw60836.2024.00057 · Cited by 4
Scenario Generation of PV Power Based on DDPM
Yang, Z., Yan, J. W., Hong, Y., Yang, J., Wang, K., & Li, Y. (2023) · IEEE Conference on Energy Internet and Energy System Integration (EI2) · doi:10.1109/ei259745.2023.10512827 · Cited by 4
EDiffuRec: An Enhanced Diffusion Model for Sequential Recommendation
Lee, H., & Kim, J. (2024) · Mathematics · doi:10.3390/math12121795 · Cited by 4
Legibility Diffuser: Offline Imitation for Intent Expressive Motion
Bronars, M., Cheng, S., & Xu, D. (2024) · IEEE Robotics and Automation Letters · doi:10.1109/lra.2024.3421849 · Cited by 4
PromoterDiff: De Novo Design Approach for Escherichia coli Promoters Based on a Diffusion Model
Cheng, Y., Zhang, X., Liu, F., Zhao, D., & Luo, X. (2024) · International Conference on Computer Supported Cooperative Work in Design (CSCWD) · doi:10.1109/cscwd61410.2024.10580553 · Cited by 4
Colorectal polyp segmentation with denoising diffusion probabilistic models
Wang, Z., Liu, M., Jiang, J., & Qu, X. (2024) · Computers in Biology and Medicine · doi:10.1016/j.compbiomed.2024.108981 · Cited by 4
Metadata
- Authors
- Dhariwal, P., & Nichol, A.
- Affiliations
- OpenAI (United States) (US)
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2021
- ISSN
- 2331-8422 (ISSN-L)
- arXiv
- 2105.05233
- OpenAlex
- W3162926177
- Semantic Scholar
- 64ea8f180d0682e6c18d1eb688afdb2027c02794
- Cited by
- 3,362
- References
- 60
- Citations by year
- 2026: 43 · 2025: 923 · 2024: 1508 · 2023: 770 · 2022: 79 · 2021: 39
- Type
- posted content
- Language
- en
- Open access
- green
- arxiv.org
- Locations
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Generative Adversarial Networks and Image Synthesis
- Physical Sciences › Computer Science › Artificial Intelligence › Adversarial Robustness in Machine Learning
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Image and Signal Denoising Methods
- Keywords
- diffusion models, image generation, unconditional image generation, conditional image generation, classifier guidance, sample quality, ImageNet
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-08, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-08 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
