

The DOI matches its DataCite record; 34 of the 34 references it cites were found in a registry or an index.
Towards Accurate Differential Diagnosis with Large Language Models
Open accessAbstract
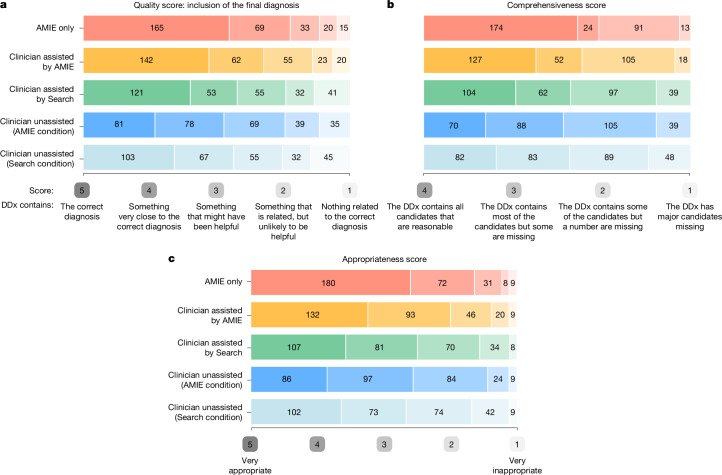
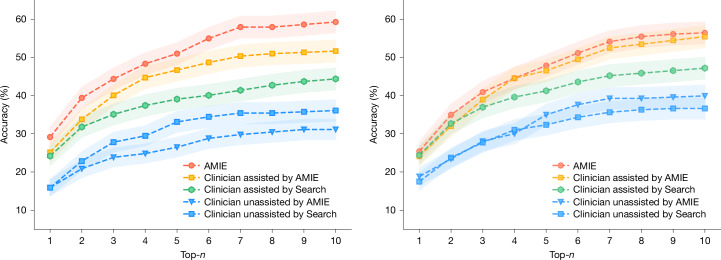
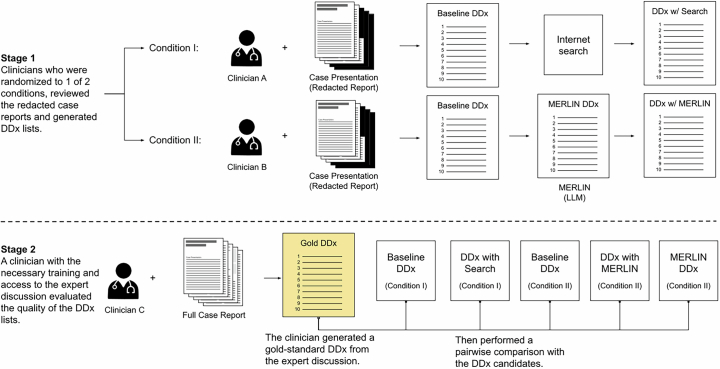
An accurate differential diagnosis (DDx) is a cornerstone of medical care, often reached through an iterative process of interpretation that combines clinical history, physical examination, investigations and procedures. Interactive interfaces powered by Large Language Models (LLMs) present new opportunities to both assist and automate aspects of this process. In this study, we introduce an LLM optimized for diagnostic reasoning, and evaluate its ability to generate a DDx alone or as an aid to clinicians. 20 clinicians evaluated 302 challenging, real-world medical cases sourced from the New England Journal of Medicine (NEJM) case reports. Each case report was read by two clinicians, who were randomized to one of two assistive conditions: either assistance from search engines and standard medical resources, or LLM assistance in addition to these tools. All clinicians provided a baseline, unassisted DDx prior to using the respective assistive tools. Our LLM for DDx exhibited standalone performance that exceeded that of unassisted clinicians (top-10 accuracy 59.1% vs 33.6%, [p = 0.04]). Comparing the two assisted study arms, the DDx quality score was higher for clinicians assisted by our LLM (top-10 accuracy 51.7%) compared to clinicians without its assistance (36.1%) (McNemar's Test: 45.7, p < 0.01) and clinicians with search (44.4%) (4.75, p = 0.03). Further, clinicians assisted by our LLM arrived at more comprehensive differential lists than those without its assistance. Our study suggests that our LLM for DDx has potential to improve clinicians' diagnostic reasoning and accuracy in challenging cases, meriting further real-world evaluation for its ability to empower physicians and widen patients' access to specialist-level expertise.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“An unexpected secondary result was that the LLM alone performed significantly better than both groups of humans, similar to a recent study with different LLM technology.31”
From Large Language Model Influence on Diagnostic Reasoning: A Randomized Clinical Trial (2024) · cites this paper as [31]
Experimental — accuracy not yet measuredThe check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Our study included 6 cases that could feasibly be completed within a single study session while remaining comparable to standard practices in national licensing and objective structured clinical examinations to use a small, but broad sample of clinical cases.6,46,47,48,49”
From Large Language Model Influence on Diagnostic Reasoning: A Randomized Clinical Trial (2024) · cites this paper as [46]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The Measurement of Observer Agreement for Categorical Data
Landis, J. R., & Koch, G. G. (1977) · Biometrics · doi:10.2307/2529310 · Cited by 81,148
MIMIC-III, a freely accessible critical care database
Johnson, A. E. W., Pollard, T. J., Shen, L., Lehman, L.-W. H., Feng, M., Ghassemi, M., Moody, B., Szolovits, P., Anthony Celi, L., & Mark, R. G. (2016) · Scientific Data · doi:10.1038/sdata.2016.35 · Cited by 8,141
Dissecting racial bias in an algorithm used to manage the health of populations
Obermeyer, Z., Powers, B., Vogeli, C., & Mullainathan, S. (2019) · Science · doi:10.1126/science.aax2342 · Cited by 7,137
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Self-citationLlama 2: Open Foundation and Fine-Tuned Chat Models
Touvron, H., Martin, L., Stone, K., Albert, P., Almahairi, A., Babaei, Y., Bashlykov, N., Batra, S., Bhargava, P., Bhosale, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2307.09288 · Cited by 2,604
Reasoning Foundations of Medical Diagnosis
Ledley, R. S., & Lusted, L. B. (1959) · Science · doi:10.1126/science.130.3366.9 · Cited by 998
LLaVA-Med: Training a Large Language-and-Vision Assistant for Biomedicine in One Day
Li, C., Wong, C., Zhang, S., Usuyama, N., Liu, H., Yang, J., Naumann, T., Poon, H., & Gao, J. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-1240 · Cited by 986
Seyyed-Kalantari, L., Zhang, H., McDermott, M. B. A., Chen, I. Y., & Ghassemi, M. (2021) · Nature Medicine · doi:10.1038/s41591-021-01595-0 · Cited by 928
A deep learning system for differential diagnosis of skin diseases
Liu, Y., Jain, A., Eng, C., Way, D. H., Lee, K., Bui, P., Kanada, K., de Oliveira Marinho, G., Gallegos, J., Gabriele, S., et al. (2020) · Nature Medicine · doi:10.1038/s41591-020-0842-3 · Cited by 853
Self-citationAnil, R., Dai, A. M., Firat, O., Johnson, M., Lepikhin, D., Passos, A., Shakeri, S., Taropa, E., Bailey, P., Chen, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2305.10403 · Cited by 834
Self-citation
Research works printed but not linked: 5
- [6]6. OpenAI. GPT-4 Technical Report 2023. arXiv: 2303.08774 [cs.CL] . · arXiv
- [13]13. Buckley, T., Diao, J. A., Rodman, A. & Manrai, A. K. Accuracy of a Vision-Language Model on Challenging Medical Cases 2023. arXiv: 2311.05591 [cs.CV] . · arXiv
- [17]17. Hong, J., Levine, S. & Dragan, A. Zero-Shot Goal-Directed Dialogue via RL on Imagined Conversations. arXiv preprint arXiv:2311.05584 (2023). · arXiv
- [21]21. Miller, R. A., Pople Jr, H. E. & Myers, J. D. in Computer-assisted medical decision making 139-158 (Springer, 1985).
- [30]30. Umapathi, L. K., Pal, A. & Sankarasubbu, M. Med-halt: Medical domain hallucination test for large language models. arXiv preprint arXiv:2307.15343 (2023). · arXiv
Cited by
Sorted by citations
Evaluation and mitigation of the limitations of large language models in clinical decision-making
Hager, P., Jungmann, F., Holland, R., Bhagat, K., Hubrecht, I., Knauer, M., Vielhauer, J., Makowski, M., Braren, R., Kaissis, G., et al. (2024) · Nature Medicine · doi:10.1038/s41591-024-03097-1 · Cited by 798
“LLMs can summarize reports 3–5 , generate reports 2,4 , serve as diagnostic assistants 21,27 and could ultimately autonomously diagnose patients.”
Large Language Model Influence on Diagnostic Reasoning: A Randomized Clinical Trial
Goh, E., Gallo, R., Hom, J., Strong, E., Weng, Y., Kerman, H., Cool, J. A., Kanjee, Z., Parsons, A. S., Ahuja, N., et al. (2024) · JAMA Network Open · doi:10.1001/jamanetworkopen.2024.40969 · Cited by 724
Towards conversational diagnostic artificial intelligence
Tu, T., Schaekermann, M., Palepu, A., Saab, K., Freyberg, J., Tanno, R., Wang, A., Li, B., Amin, M., Cheng, Y., et al. (2025) · Nature · doi:10.1038/s41586-025-08866-7 · Cited by 366
“Previous research has shown that AI systems may match or exceed human diagnostic performance in specific, narrow tasks 21,22 in retrospective evaluation.”
Self-citationCurrent applications and challenges in large language models for patient care: a systematic review
Busch, F., Hoffmann, L., Rueger, C., van Dijk, E. H., Kader, R., Ortiz-Prado, E., Makowski, M. R., Saba, L., Hadamitzky, M., Kather, J. N., et al. (2025) · Communications Medicine · doi:10.1038/s43856-024-00717-2 · Cited by 358
The Opportunities and Risks of Large Language Models in Mental Health
Lawrence, H. R., Schneider, R. A., Rubin, S. B., Matarić, M. J., McDuff, D. J., & Jones Bell, M. (2024) · JMIR Mental Health · doi:10.2196/59479 · Cited by 235
Self-citation
Metadata
- Authors
- McDuff, D., Schaekermann, M., Tu, T., Palepu, A., Wang, A., Garrison, J., Singhal, K., Sharma, Y., Azizi, S., Kulkarni, K., Hou, L., Cheng, Y., Liu, Y., Mahdavi, S. S., Prakash, S., Pathak, A., Semturs, C., Patel, S., Webster, D. R., Dominowska, E., Gottweis, J., Barral, J., Chou, K., Corrado, G. S., Matias, Y., Sunshine, J., Karthikesalingam, A., & Natarajan, V.
- Affiliations
- Google (United States) (US)
- Google (Switzerland) (CH)
- Google (United Kingdom) (GB)
- Corresponding author
- McDuff, Daniel
- Schaekermann, Mike
- Karthikesalingam, Alan
- Natarajan, Vivek
- ORCID
- McDuff, Daniel
- Schaekermann, Mike
- Tu, Tao
- Palepu, Anil
- Wang, Amy
- Singhal, Karan
- Azizi, Shekoofeh
- Cheng, Yong
- Liu, Yun
- Mahdavi, S Sara
- Prakash, Sushant
- Pathak, Anupam
- Semturs, Christopher
- Patel, Shwetak
- Webster, Dale R
- Dominowska, Ewa
- Gottweis, Juraj
- Barral, Joelle
- Chou, Katherine
- Corrado, Greg S
- Matias, Yossi
- Karthikesalingam, Alan
- Natarajan, Vivek
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2023
- Volume
- 642
- Issue
- 8067
- Pages
- 451-457
- ISSN
- 0028-0836 (ISSN-L)
- arXiv
- 2312.00164
- PMC
- PMC12158753
- OpenAlex
- W4409283616
- Cited by
- 311
- References
- 34
- Citations by year
- 2026: 172 · 2025: 108 · 2024: 31
- FWCI
- 67.40
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Nature (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, other-oa)
- arXiv (Cornell University)
- Funders
- Massachusetts Medical Society
- DeepMind
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Keywords
- differential diagnosis, large language models, diagnostic reasoning, clinical decision support, clinician performance, AI-assisted diagnosis, medical knowledge retrieval
- MeSH terms
- Case Reports as Topic, Large Language Models, Artificial Intelligence, Diagnosis, Differential, Humans, Language
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
