

The DOI matches its DataCite record; 34 of the 34 references it cites were found in a registry or an index.
Towards Accurate Differential Diagnosis with Large Language Models
Open accessAbstract
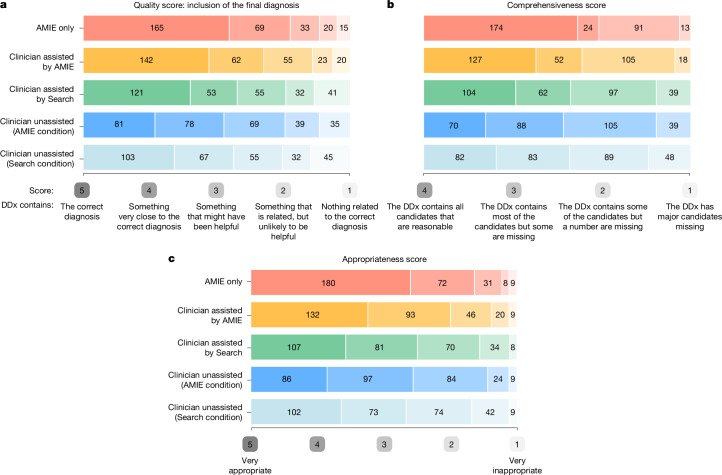
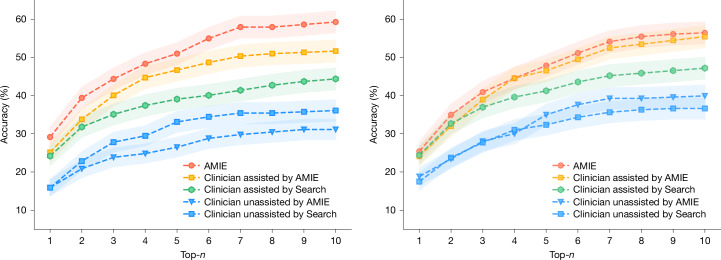
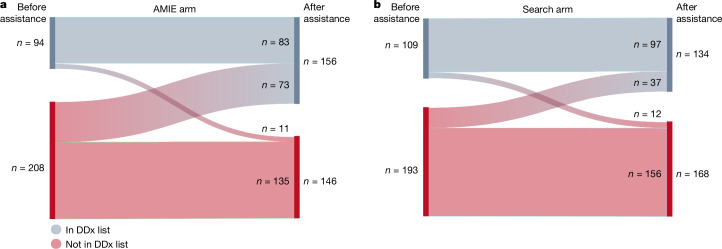
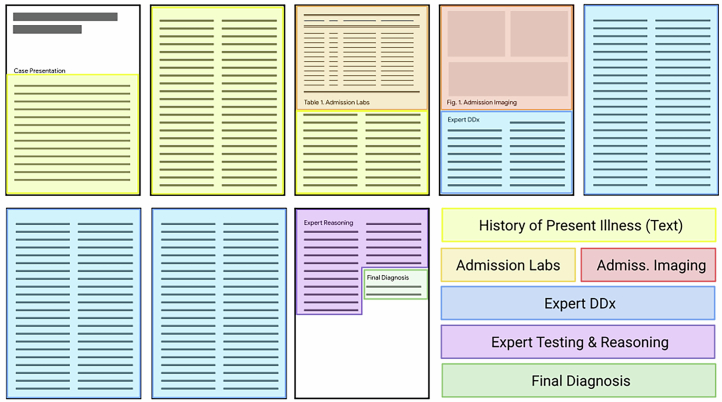
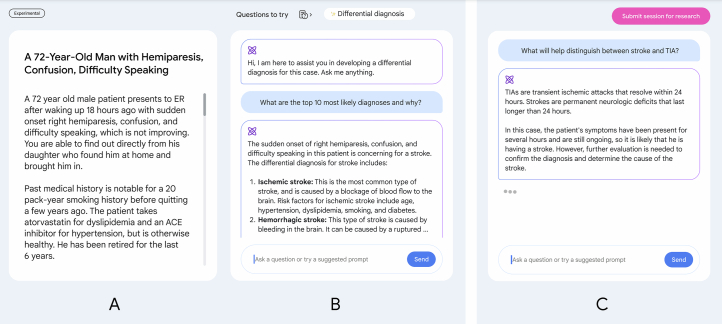
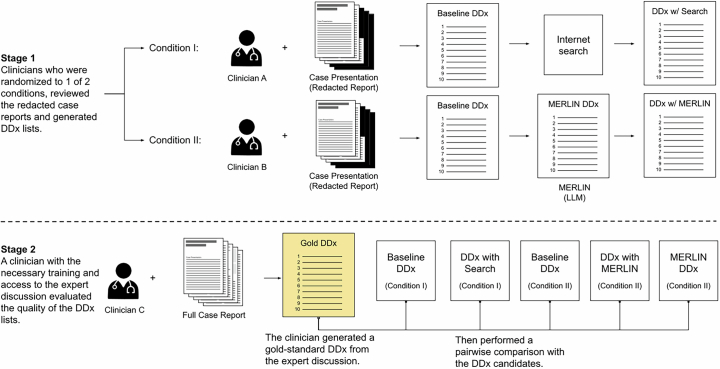
An accurate differential diagnosis (DDx) is a cornerstone of medical care, often reached through an iterative process of interpretation that combines clinical history, physical examination, investigations and procedures. Interactive interfaces powered by Large Language Models (LLMs) present new opportunities to both assist and automate aspects of this process. In this study, we introduce an LLM optimized for diagnostic reasoning, and evaluate its ability to generate a DDx alone or as an aid to clinicians. 20 clinicians evaluated 302 challenging, real-world medical cases sourced from the New England Journal of Medicine (NEJM) case reports. Each case report was read by two clinicians, who were randomized to one of two assistive conditions: either assistance from search engines and standard medical resources, or LLM assistance in addition to these tools. All clinicians provided a baseline, unassisted DDx prior to using the respective assistive tools. Our LLM for DDx exhibited standalone performance that exceeded that of unassisted clinicians (top-10 accuracy 59.1% vs 33.6%, [p = 0.04]). Comparing the two assisted study arms, the DDx quality score was higher for clinicians assisted by our LLM (top-10 accuracy 51.7%) compared to clinicians without its assistance (36.1%) (McNemar's Test: 45.7, p < 0.01) and clinicians with search (44.4%) (4.75, p = 0.03). Further, clinicians assisted by our LLM arrived at more comprehensive differential lists than those without its assistance. Our study suggests that our LLM for DDx has potential to improve clinicians' diagnostic reasoning and accuracy in challenging cases, meriting further real-world evaluation for its ability to empower physicians and widen patients' access to specialist-level expertise.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“An unexpected secondary result was that the LLM alone performed significantly better than both groups of humans, similar to a recent study with different LLM technology.31”
From Large Language Model Influence on Diagnostic Reasoning: A Randomized Clinical Trial (2024) · cites this paper as [31]
Experimental — accuracy not yet measuredThe check wasn’t confident either way, so it gives no verdict — never disputed.
In the citing paper
“Our study included 6 cases that could feasibly be completed within a single study session while remaining comparable to standard practices in national licensing and objective structured clinical examinations to use a small, but broad sample of clinical cases.6,46,47,48,49”
From Large Language Model Influence on Diagnostic Reasoning: A Randomized Clinical Trial (2024) · cites this paper as [46]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The Measurement of Observer Agreement for Categorical Data
Landis, J. R., & Koch, G. G. (1977) · Biometrics · doi:10.2307/2529310 · Cited by 81,148
MIMIC-III, a freely accessible critical care database
Johnson, A. E. W., Pollard, T. J., Shen, L., Lehman, L.-W. H., Feng, M., Ghassemi, M., Moody, B., Szolovits, P., Anthony Celi, L., & Mark, R. G. (2016) · Scientific Data · doi:10.1038/sdata.2016.35 · Cited by 8,141
Dissecting racial bias in an algorithm used to manage the health of populations
Obermeyer, Z., Powers, B., Vogeli, C., & Mullainathan, S. (2019) · Science · doi:10.1126/science.aax2342 · Cited by 7,137
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Self-citationLlama 2: Open Foundation and Fine-Tuned Chat Models
Touvron, H., Martin, L., Stone, K., Albert, P., Almahairi, A., Babaei, Y., Bashlykov, N., Batra, S., Bhargava, P., Bhosale, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2307.09288 · Cited by 2,604
Reasoning Foundations of Medical Diagnosis
Ledley, R. S., & Lusted, L. B. (1959) · Science · doi:10.1126/science.130.3366.9 · Cited by 998
LLaVA-Med: Training a Large Language-and-Vision Assistant for Biomedicine in One Day
Li, C., Wong, C., Zhang, S., Usuyama, N., Liu, H., Yang, J., Naumann, T., Poon, H., & Gao, J. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-1240 · Cited by 986
Seyyed-Kalantari, L., Zhang, H., McDermott, M. B. A., Chen, I. Y., & Ghassemi, M. (2021) · Nature Medicine · doi:10.1038/s41591-021-01595-0 · Cited by 928
A deep learning system for differential diagnosis of skin diseases
Liu, Y., Jain, A., Eng, C., Way, D. H., Lee, K., Bui, P., Kanada, K., de Oliveira Marinho, G., Gallegos, J., Gabriele, S., et al. (2020) · Nature Medicine · doi:10.1038/s41591-020-0842-3 · Cited by 853
Self-citationAnil, R., Dai, A. M., Firat, O., Johnson, M., Lepikhin, D., Passos, A., Shakeri, S., Taropa, E., Bailey, P., Chen, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2305.10403 · Cited by 834
Self-citation
Research works printed but not linked: 5
- [6]6. OpenAI. GPT-4 Technical Report 2023. arXiv: 2303.08774 [cs.CL] . · arXiv
- [13]13. Buckley, T., Diao, J. A., Rodman, A. & Manrai, A. K. Accuracy of a Vision-Language Model on Challenging Medical Cases 2023. arXiv: 2311.05591 [cs.CV] . · arXiv
- [17]17. Hong, J., Levine, S. & Dragan, A. Zero-Shot Goal-Directed Dialogue via RL on Imagined Conversations. arXiv preprint arXiv:2311.05584 (2023). · arXiv
- [21]21. Miller, R. A., Pople Jr, H. E. & Myers, J. D. in Computer-assisted medical decision making 139-158 (Springer, 1985).
- [30]30. Umapathi, L. K., Pal, A. & Sankarasubbu, M. Med-halt: Medical domain hallucination test for large language models. arXiv preprint arXiv:2307.15343 (2023). · arXiv
Cited by
Sorted by citations
Evaluation and mitigation of the limitations of large language models in clinical decision-making
Hager, P., Jungmann, F., Holland, R., Bhagat, K., Hubrecht, I., Knauer, M., Vielhauer, J., Makowski, M., Braren, R., Kaissis, G., et al. (2024) · Nature Medicine · doi:10.1038/s41591-024-03097-1 · Cited by 798
“LLMs can summarize reports 3–5 , generate reports 2,4 , serve as diagnostic assistants 21,27 and could ultimately autonomously diagnose patients.”
Large Language Model Influence on Diagnostic Reasoning: A Randomized Clinical Trial
Goh, E., Gallo, R., Hom, J., Strong, E., Weng, Y., Kerman, H., Cool, J. A., Kanjee, Z., Parsons, A. S., Ahuja, N., et al. (2024) · JAMA Network Open · doi:10.1001/jamanetworkopen.2024.40969 · Cited by 724
Towards conversational diagnostic artificial intelligence
Tu, T., Schaekermann, M., Palepu, A., Saab, K., Freyberg, J., Tanno, R., Wang, A., Li, B., Amin, M., Cheng, Y., et al. (2025) · Nature · doi:10.1038/s41586-025-08866-7 · Cited by 366
“Previous research has shown that AI systems may match or exceed human diagnostic performance in specific, narrow tasks 21,22 in retrospective evaluation.”
Self-citationCurrent applications and challenges in large language models for patient care: a systematic review
Busch, F., Hoffmann, L., Rueger, C., van Dijk, E. H., Kader, R., Ortiz-Prado, E., Makowski, M. R., Saba, L., Hadamitzky, M., Kather, J. N., et al. (2025) · Communications Medicine · doi:10.1038/s43856-024-00717-2 · Cited by 358
The Opportunities and Risks of Large Language Models in Mental Health
Lawrence, H. R., Schneider, R. A., Rubin, S. B., Matarić, M. J., McDuff, D. J., & Jones Bell, M. (2024) · JMIR Mental Health · doi:10.2196/59479 · Cited by 235
Self-citationEducational Strategies for Clinical Supervision of Artificial Intelligence Use
Abdulnour, R.-E. E., Gin, B., & Boscardin, C. K. (2025) · New England Journal of Medicine · doi:10.1056/nejmra2503232 · Cited by 209
Goh, E., Gallo, R. J., Strong, E., Weng, Y., Kerman, H. M., Freed, J. A., Cool, J. A., Kanjee, Z., Lane, K. P., Parsons, A. S., et al. (2025) · Nature Medicine · doi:10.1038/s41591-024-03456-y · Cited by 216
Masanneck, L., Schmidt, L., Seifert, A., Kölsche, T., Huntemann, N., Jansen, R., Mehsin, M., Bernhard, M., Meuth, S. G., Böhm, L., et al. (2024) · Journal of Medical Internet Research · doi:10.2196/53297 · Cited by 157
Large language models for disease diagnosis: a scoping review
Zhou, S., Xu, Z., Zhang, M., Xu, C., Guo, Y., Zhan, Z., Fang, Y., Ding, S., Wang, J., Xu, K., et al. (2025) · npj Artificial Intelligence · doi:10.1038/s44387-025-00011-z · Cited by 188
A toolbox for surfacing health equity harms and biases in large language models
Pfohl, S. R., Cole-Lewis, H., Sayres, R., Neal, D., Asiedu, M., Dieng, A., Tomasev, N., Rashid, Q. M., Azizi, S., Rostamzadeh, N., et al. (2024) · Nature Medicine · doi:10.1038/s41591-024-03258-2 · Cited by 113
Self-citationCapabilities of Gemini Models in Medicine
Saab, K., Tu, T., Weng, W.-H., Tanno, R., Stutz, D., Wulczyn, E., Zhang, F., Strother, T., Park, C., Vedadi, E., et al. (2024) · arXiv · doi:10.48550/arxiv.2404.18416 · Cited by 117
Self-citationApplication of large language models in medicine
Liu, F., Zhou, H., Gu, B., Zou, X., Huang, J., Wu, J., Li, Y., Chen, S. S., Hua, Y., Zhou, P., et al. (2025) · Nature Reviews Bioengineering · doi:10.1038/s44222-025-00279-5 · Cited by 94
Savage, T., Wang, J., Gallo, R., Boukil, A., Patel, V., Safavi-Naini, S. A. A., Soroush, A., & Chen, J. H. (2025) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae254 · Cited by 92
LLM-assisted systematic review of large language models in clinical medicine
Chen, S. F., Alyakin, A., Seas, A., Yang, E., Choi, J. J., Lee, J. V., Chen, A. L., Warman, P. I., Bitolas, R., Steele, R. J., et al. (2026) · Nature Medicine · doi:10.1038/s41591-026-04229-5 · Cited by 99
Jung, K.-H. (2025) · Healthcare Informatics Research · doi:10.4258/hir.2025.31.2.114 · Cited by 84
Medical foundation large language models for comprehensive text analysis and beyond
Xie, Q., Chen, Q., Chen, A., Peng, C., Hu, Y., Lin, F., Peng, X., Huang, J., Zhang, J., Keloth, V., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01533-1 · Cited by 74
Generative artificial intelligence, patient safety and healthcare quality: a review
Howell, M. D. (2024) · BMJ Quality & Safety · doi:10.1136/bmjqs-2023-016690 · Cited by 83
Performance of a large language model on the reasoning tasks of a physician
Brodeur, P. G., Buckley, T. A., Kanjee, Z., Goh, E., Ling, E., Jain, P., Cabral, S., Abdulnour, R.-E. E., Haimovich, A. D., Freed, J. A., et al. (2026) · Science · doi:10.1126/science.adz4433 · Cited by 187
An agentic system for rare disease diagnosis with traceable reasoning
Zhao, W., Wu, C., Fan, Y., Qiu, P., Zhang, X., Sun, Y., Zhou, X., Zhang, S., Peng, Y., Wang, Y., et al. (2026) · Nature · doi:10.1038/s41586-025-10097-9 · Cited by 62
Hadweh, P., Niset, A., Salvagno, M., Barajraji, M. A., Hadwe, S. E., Taccone, F. S., & Barrit, S. (2025) · Journal of Clinical Medicine · doi:10.3390/jcm14124026 · Cited by 72
A personal health large language model for sleep and fitness coaching
Khasentino, J., Belyaeva, A., Liu, X., Yang, Z., Furlotte, N. A., Lee, C., Schenck, E., Patel, Y., Cui, J., Schneider, L. D., et al. (2025) · Nature Medicine · doi:10.1038/s41591-025-03888-0 · Cited by 151
Self-citationAn eyecare foundation model for clinical assistance: a randomized controlled trial
Wu, Y.-L., Qian, B., Li, T., Qin, Y., Guan, Z., Chen, T., Jia, Y., Zhang, P., Zeng, D., Moroi, S. E., et al. (2025) · Nature Medicine · doi:10.1038/s41591-025-03900-7 · Cited by 67
Kim, J., Wang, K., Weng, C., & Liu, C. (2024) · The American Journal of Human Genetics · doi:10.1016/j.ajhg.2024.08.010 · Cited by 53
Large models in medical imaging: Advances and prospects
Fang, M., Wang, Z., Pan, S., Feng, X., Zhao, Y., Hou, D., Wu, L., Xie, X., Zhang, X.-Y., Tian, J., et al. (2025) · Chinese Medical Journal · doi:10.1097/cm9.0000000000003699 · Cited by 43
Influence of a Large Language Model on Diagnostic Reasoning: A Randomized Clinical Vignette Study
Goh, E., Gallo, R., Hom, J., Strong, E., Weng, Y., Kerman, H., Cool, J., Kanjee, Z., Parsons, A. S., Ahuja, N., et al. (2024) · doi:10.1101/2024.03.12.24303785 · Cited by 38
Human–large language model collaboration in clinical medicine: a systematic review and meta-analysis
Wang, G., Zhang, K., Jiang, J., Wang, C., Bi, H., Liang, H., Qi, Z., Huang, Y., Li, Y., & Yang, X. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02382-2 · Cited by 48
Large language models for clinical decision support in gastroenterology and hepatology
Wiest, I. C., Bhat, M., Clusmann, J., Schneider, C. V., Jiang, X., & Kather, J. N. (2025) · Nature Reviews Gastroenterology & Hepatology · doi:10.1038/s41575-025-01108-1 · Cited by 34
Scott, I. A., & Zuccon, G. (2024) · Internal Medicine Journal · doi:10.1111/imj.16393 · Cited by 36
Automating expert-level medical reasoning evaluation of large language models
Zhou, S., Xie, W., Li, J., Zhan, Z., Song, M., Yang, H., Espinoza, C., Welton, L., Mai, X., Jin, Y., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-02208-7 · Cited by 30
Chitoran, E., Rotaru, V., Gelal, A., Ionescu, S. O., Gullo, G., Stefan, D. C., & Simion, L. (2025) · Diagnostics · doi:10.3390/diagnostics15182391 · Cited by 30
Transforming wearable data into personal health insights using large language model agents
Merrill, M. A., Paruchuri, A., Rezaei, N., Kovacs, G., Perez, J., Liu, Y., Schenck, E., Hammerquist, N., Sunshine, J., Tailor, S. A., et al. (2026) · Nature Communications · doi:10.1038/s41467-025-67922-y · Cited by 80
Self-citationQazi, I. A., Ali, A., Khawaja, A. U., Akhtar, M. J., Sheikh, A. Z., & Alizai, M. H. (2026) · NEJM AI · doi:10.1056/aioa2501001 · Cited by 37
Generative artificial intelligence: implications for biomedical and health professions education
Hersh, W. (2025) · Annual Review of Biomedical Data Science · doi:10.1146/annurev-biodatasci-103123-094756 · Cited by 28
A large language model for complex cardiology care
O’Sullivan, J. W., Palepu, A. K., Saab, K. K., Weng, W., Amponsah, D., Cheng, E., Cheng, Y., Chu, E. L., Desai, Y. B., Elezaby, A., et al. (2026) · Nature Medicine · doi:10.1038/s41591-025-04190-9 · Cited by 33
Self-citationEverett, S., Bunning, B., Jain, P., López, I., Agarwal, A., Desai, M., Gallo, R. J., Goh, E., Kadiyala, V., Kanjee, Z., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02545-1 · Cited by 66
Uncertainty-aware large language models for explainable disease diagnosis
Zhou, S., Wang, J., Xu, Z., Wang, S., Brauer, D., Welton, L., Cogan, J., Chung, Y.-H., Tian, L., Zhan, Z., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-02071-6 · Cited by 27
Wang, S., Tang, Z., Yang, H., Gong, Q., Gu, T., Ma, H., Wang, Y., Sun, W., Lian, Z., Mao, K., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-02277-8 · Cited by 33
Self-citationData-Centric Foundation Models in Computational Healthcare: A Survey
Zhang, Y., Gao, J. G., Tan, Z., Zhou, L., Ding, K., Zhou, M., Zhang, S., & Wang, D. (2026) · ACM Computing Surveys · doi:10.1145/3800677 · Cited by 65
Combining Multiple Large Language Models Improves Diagnostic Accuracy
Barabucci, G., Shia, V., Chu, E., Harack, B., Laskowski, K., & Fu, N. (2024) · NEJM AI · doi:10.1056/aics2400502 · Cited by 24
Artificial intelligence agents in cancer research and oncology
Truhn, D., Azizi, S., Zou, J., Cerdá-Alberich, L., Mahmood, F., & Kather, J. N. (2026) · Nature reviews. Cancer · doi:10.1038/s41568-025-00900-0 · Cited by 29
Self-citationBhasuran, B., Jin, Q., Xie, Y., Yang, C., Hanna, K., Costa, J., Shavor, C., Han, W., Lu, Z., & He, Z. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01556-8 · Cited by 27
Transforming mental health research and care through artificial intelligence
Opel, N., & Breakspear, M. J. (2026) · Science · doi:10.1126/science.adz9193 · Cited by 29
Patient agency and large language models in worldwide encoding of equity
Armoundas, A. A., & Loscalzo, J. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01598-y · Cited by 25
EndoChat: Grounded multimodal large language model for endoscopic surgery
Wang, G., Bai, L., Wang, J., Yuan, K., Li, Z., Jiang, T., He, X., Wu, J., Chen, Z., Lei, Z., et al. (2025) · Medical Image Analysis · doi:10.1016/j.media.2025.103789 · Cited by 54
Qazi, I. A., Ali, A., Khawaja, A. U., Akhtar, M. J., Sheikh, A. Z., & Alizai, M. H. (2026) · Nature Health · doi:10.1038/s44360-025-00007-8 · Cited by 23
A survey on biomedical automatic text summarization with large language models
Huang, Z., Chen, X., Wang, Y., Huang, J., & Zhao, X. (2025) · Information Processing & Management · doi:10.1016/j.ipm.2025.104216 · Cited by 24
Patient-Clinician Communication: ASCO Guideline Update
Gilligan, T. D., Bohlke, K., Alpert, A. B., Coyle, N., Harichand-Herdt, S., Lathan, C. S., Razis, E., Rivera, K., Sanft, T. B., Seigel, C., et al. (2026) · Journal of Clinical Oncology · doi:10.1200/jco-26-00118 · Cited by 21
Dietrich, N., & Stubbert, B. (2025) · Canadian Association of Radiologists Journal · doi:10.1177/08465371251323124 · Cited by 20
Gómez, C., Yin, J., Huang, C., & Unberath, M. (2024) · Frontiers in Computer Science · doi:10.3389/fcomp.2024.1427463 · Cited by 27
Wen, P., Ai, Q., Fan, X., Gu, Z., 陈波, & Qian, H. (2026) · Cancer Letters · doi:10.1016/j.canlet.2026.218257 · Cited by 20
Everett, S. S., Bunning, B. J., Jain, P., Lopez, I., Agarwal, A., Desai, M., Gallo, R., Goh, E., Kadiyala, V. B., Kanjee, Z., et al. (2025) · doi:10.1101/2025.06.07.25329176 · Cited by 18
Beyond Accuracy: Investigating Error Types in GPT-4 Responses to USMLE Questions
Roy, S., Khatua, A., Ghoochani, F., Hadler, U., Nejdl, W., & Ganguly, N. (2024) · Proceedings of the 47th International ACM SIGIR Conference on Research and Development in Information Retrieval · doi:10.1145/3626772.3657882 · Cited by 17
Hashjin, N. M., Amiri, M. H., & Najafabadi, M. K. (2026) · Scientific Reports · doi:10.1038/s41598-026-38715-0 · Cited by 19
An overview of diagnostics and therapeutics using large language models
Malgaroli, M., & McDuff, D. (2024) · Journal of Traumatic Stress · doi:10.1002/jts.23082 · Cited by 19
Self-citationScaling medical AI across clinical contexts
Li, M. M., Reis, B. Y., Rodman, A. M., Cai, T., Dagan, N., Balicer, R. D., Loscalzo, J., Kohane, I. S., & Žitnik, M. (2026) · Nature Medicine · doi:10.1038/s41591-025-04184-7 · Cited by 24
Towards conversational artificial intelligence for disease management
Liévin, V., Palepu, A. K., Weng, W., Saab, K. K., Stutz, D., Cheng, Y., Kulkarni, K., Mahdavi, S. S., Barral, J. K., Webster, D. R., et al. (2026) · Nature · doi:10.1038/s41586-026-10764-5 · Cited by 53
Self-citationHersh, W., & Hollis, K. F. (2024) · npj Digital Medicine · doi:10.1038/s41746-024-01251-0 · Cited by 20
AML diagnostics in the 21st century: Use of AI
Haferlach, T., Eckardt, J., Walter, W., Maschek, S., Kather, J. N., Pohlkamp, C., & Middeke, J. M. (2025) · Seminars in Hematology · doi:10.1053/j.seminhematol.2025.06.002 · Cited by 18
Automation Bias in Large Language Model Assisted Diagnostic Reasoning Among AI-Trained Physicians
Qazi, I. A., Ali, A., Khawaja, A. U., Akhtar, M. J., Sheikh, A. Z., & Alizai, M. H. (2025) · medRxiv · doi:10.1101/2025.08.23.25334280 · Cited by 16
Large Language Model Influence on Management Reasoning: A Randomized Controlled Trial
Goh, E., Gallo, R., Strong, E., Weng, Y., Kerman, H., Freed, J., Cool, J. A., Kanjee, Z., Lane, K. P., Parsons, A. S., et al. (2024) · medRxiv · doi:10.1101/2024.08.05.24311485 · Cited by 13
The Development Landscape of Large Language Models for Biomedical Applications
Cao, Z., Keloth, V. K., Xie, Q., Qian, L., Liu, Y., Wang, Y., Shi, R., Zhou, W., Yang, G. F., Zhang, J., et al. (2025) · Annual Review of Biomedical Data Science · doi:10.1146/annurev-biodatasci-102224-074736 · Cited by 16
Self-citationA survey on large language models driven meta-optimizers for automated intelligent optimization
Zheng, Y., Zhang, L., Li, K., Wang, R., Li, W., Zhang, T., Zhang, Q., & Jin, Y. (2026) · Artificial Intelligence Review · doi:10.1007/s10462-025-11470-w · Cited by 14
van Kessel, R., Anderson, M., McMillan, B., Matthews, M. R., Rust, P., Pearcy, P., Nasir, K., & Mossialos, E. A. (2026) · BMJ Health & Care Informatics · doi:10.1136/bmjhci-2025-101959 · Cited by 18
Capable language models can outgrow the benefits of collaboration
Kim, Y., Gu, K., Park, C., Park, C., Schmidgall, S., Heydari, A. A., Yan, Y., Zhang, Z., Zhuang, Y., Liu, Y., et al. (2026) · Nature Machine Intelligence · doi:10.1038/s42256-026-01268-y · Cited by 27
Self-citationLiu, J., Koopman, B., Brown, N. J., Chu, K., & Nguyen, A. N. (2024) · Artificial Intelligence in Medicine · doi:10.1016/j.artmed.2024.103027 · Cited by 21
Hayat, H., Kudrautsau, M., Makarov, E., Melnichenko, V., Tsykunou, T., Varaksin, P., Pavelle, M., & Oskowitz, A. (2025) · medRxiv · doi:10.1101/2025.07.14.25331406 · Cited by 12
Large Language Model Uncertainty Measurement and Calibration for Medical Diagnosis and Treatment
Savage, T., Wang, J., Gallo, R., Boukil, A., Patel, V., Ahmad Safavi-Naini, S. A., Soroush, A., & Chen, J. H. (2024) · doi:10.1101/2024.06.06.24308399 · Cited by 11
Scaffolding for success: Blending learning with and about Generative AI in medical education
Boman, M., Jhun, P., & Schaekermann, M. (2025) · Medical Teacher · doi:10.1080/0142159x.2025.2571041 · Cited by 11
Self-citationBáez, J. C., Ahn, E., Tamietti, A., Victor, B. G., & Goldkind, L. (2025) · Journal of Evidence-Based Social Work · doi:10.1080/26408066.2025.2542450 · Cited by 14
A Licensure Framework for Autonomous Clinical AI
Bergman, A., Wachter, R. M., & Emanuel, E. (2026) · JAMA · doi:10.1001/jama.2026.5483 · Cited by 10
AI-assisted human clinical reasoning in the ICU: beyond “to err is human”
Gharib, K. E., Jundi, B., Furfaro, D. M., & Abdulnour, R.-E. E. (2024) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2024.1506676 · Cited by 9
A scalable framework for evaluating health language models
Mallinar, N., Heydari, A. A., Liu, X., Faranesh, A. Z., Winslow, B. D., Hammerquist, N., Graef, B., Speed, C., Malhotra, M., Patel, S., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02492-x · Cited by 23
Self-citationMe LLaMA: Foundation Large Language Models for Medical Applications
Xie, Q., Chen, Q., Chen, A., Peng, C., Hu, Y., Lin, F., Peng, X., Huang, J., Zhang, J., Keloth, V., et al. (2024) · arXiv · doi:10.48550/arxiv.2402.12749 · Cited by 8
Maurya, R., Rajput, N., Diviit, M. G., Mahapatra, S., & Ojha, M. K. (2025) · Scientific Reports · doi:10.1038/s41598-025-05012-1 · Cited by 9
Artificial intelligence in rehabilitation: a living systematic mapping review - first release
Morone, G., REHALISE Group, Carbonetti, R., Cinnera, A. M., Malfitano, C., Bisirri, A., & Negrini, F. (2025) · European Journal of Physical and Rehabilitation Medicine · doi:10.23736/s1973-9087.25.09331-1 · Cited by 11
Chen, M., Wu, Y., Ma, J., Jia, X., Gao, C., Zhao, F., & Qiao, Y. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02409-8 · Cited by 15
A clinical environment simulator for dynamic AI evaluation
Luo, L., Kim, S. E., Zhang, X., Kernbach, J. M., Kenia, R., Acosta, J. N., Nathanson, L. A., Haimovich, A. D., Rodman, A. M., Goh, E., et al. (2026) · Nature Medicine · doi:10.1038/s41591-026-04252-6 · Cited by 14
Self-citationGiuffrè, M., You, K., Pang, Z., Kresevic, S., Chung, S., Chen, R., Ko, Y., Chan, C., Saarinen, T., Ajčević, M., et al. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-01589-z · Cited by 10
Hu, R., Yang, Y., Liu, S., Li, Z., Liu, J., Ding, X., Sun, H., & Ren, L. (2025) · Scientific Reports · doi:10.1038/s41598-025-15627-z · Cited by 10
Artificial intelligence in emergency medicine: a narrative review
Rego, A., Arango-Ibañez, J. P., Taylor, R. A., Smith, M. E., Jones, D. D., Pelletier, J., Colletti, J. E., Gottlieb, M. A., & Long, B. (2026) · The American Journal of Emergency Medicine · doi:10.1016/j.ajem.2026.01.028 · Cited by 7
Maitín, A. M., Nogales, A., Fernández-Rincón, S., Aranguren, E., Barba, E. C., Arranz, S. D., Rodríguez, A. A. M., & García-Tejedor, Á. J. (2024) · Journal of the American Medical Informatics Association · doi:10.1093/jamia/ocae302 · Cited by 8
Artificial intelligence–enabled precision medicine for inflammatory skin diseases
Tang, A. S., Wei, M. L., Haemel, A., La, C., Sirota, M., & Lee, E. Y. (2026) · Journal of Investigative Dermatology · doi:10.1016/j.jid.2025.10.596 · Cited by 10
Bridging BioSciences and technology: The impact of AI & GenAI in life sciences and agribusiness
da Cunha, N. B., Fernandes, F. C., Gil-Ley, A., Franco, O. L., Timakondu, N., & Costa, F. F. (2025) · Gene · doi:10.1016/j.gene.2025.149623 · Cited by 7
A survey on electronic health record driven multimodal representation learning
Dou, Y., Liu, Y., Zou, H., Zeng, W., Xu, K., & Peng, S. (2025) · Information Fusion · doi:10.1016/j.inffus.2025.103810 · Cited by 7
Self-citationApplication of Large Language Models in Automated Interpretation of Urodynamic Parameters
Wang, Z., Xu, Z., Shi, Y., Xi, J., & Zhang, Y. (2025) · Neurourology and Urodynamics · doi:10.1002/nau.70160 · Cited by 6
HUANG, A. S., Fam, A., ZHAO, H., PAULESCU, N., Fabczak-Kubicka, A., Wiggs, J. L., Zebardast, N., Friedman, D. S., Do, R., Aziz, K., et al. (2025) · American Journal of Ophthalmology · doi:10.1016/j.ajo.2025.11.046 · Cited by 6
Roemer, A., Schlicker, N., Kernder, A. L., Albe, B., Hack, J., Hirsch, M., Mayr, A. J., Kuhn, S., & Knitza, J. (2026) · BMC Medical Education · doi:10.1186/s12909-026-09079-w · Cited by 15
Using conversant artificial intelligence to improve diagnostic reasoning: ready for prime time?
Scott, I. A., Miller, T., & Crock, C. (2024) · The Medical Journal of Australia · doi:10.5694/mja2.52401 · Cited by 6
Harnessing Internet Search Data as a Potential Tool for Medical Diagnosis: Literature Review
Downing, G. J., Tramontozzi, L. M., Garcia, J., & Villanueva, E. (2024) · JMIR Mental Health · doi:10.2196/63149 · Cited by 6
Basics of Artificial Intelligence (AI) Modeling
Richie, R. C. (2024) · Journal of Insurance Medicine · doi:10.17849/insm-51-1-35-40.1 · Cited by 6
La inteligencia artificial en atención primaria: ¿solución o problema?
Sanz, J. B., & Toledo, R. B. (2025) · Atención Primaria · doi:10.1016/j.aprim.2025.103223 · Cited by 6
Farrokhi, M., Fallahian, A., Rahmani, E., Aghajan, A., Alipour, M., Khouzani, P. J., Hezarani, H. B., Sabzehie, H., Pirouzan, M., Pirouzan, Z., et al. (2025) · Archives of Academic Emergency Medicine · doi:10.22037/aaemj.v13i1.2712 · Cited by 7
Augmenting Medical Diagnostics with AI: A Dual Approach Using RAG-Based Chatbots and Nano GPT Models
Bande, S. P., Vinutha, N., & Krishnamurthy, P. K. (2025) · International Conference on Recent Advances in Information Technology · doi:10.1109/rait65068.2025.11088917 · Cited by 5
Chan, M. D. Z., Tjio, C. K. E., Chan, T. L. Y., Tan, Y. L., Chua, A. X. Y., Loh, S. K. Y., Leow, G. Z., Gan, M. Y., Lim, X., Choo, A. K., et al. (2025) · Cancers · doi:10.3390/cancers17193198 · Cited by 5
Self-citationMerchant, S. A., Merchant, N., Varghese, S. L., & Shaikh, M. J. S. (2025) · World Journal of Radiology · doi:10.4329/wjr.v17.i11.114754 · Cited by 6
Liu, D., Long, Y., Zuoqiu, S., Liu, D., Li, K., Lin, Y., Liu, H., Yin, R., & Tang, T. (2025) · Journal of Medical Internet Research · doi:10.2196/85206 · Cited by 5
Reis, F., Agha-Mir-Salim, L., Hickstein, R., Reis, M., Piper, S. K., Balzer, F., & Boie, S. D. (2026) · Journal of Medical Internet Research · doi:10.2196/84668 · Cited by 8
Jiang, Z., Chen, H., Wu, Y., Qin, Y., Pei, C., Zeng, D., Sheng, B., & Wong, T. Y. (2026) · Intelligent Medicine · doi:10.1016/j.imed.2026.01.001 · Cited by 6
McPeak, G., Sautmann, A., George, O. S., Hallal, A., Simal, E. A., Schwartz, A. L., Abaluck, J., Ravi, N., & Pless, R. B. (2024) · IEEE International Conference on Healthcare Informatics (ICHI) · doi:10.1109/ichi61247.2024.00094 · Cited by 6
Schönfelder, A., Eberlein-Gonska, M., Hülsken-Giesler, M., Jovy-Klein, F., Kather, J. N., Kohoutek, E., Lennefer, T., Liebert, E., Lipprandt, M., Mathias, R., et al. (2025) · Journal of Medical Internet Research · doi:10.2196/80754 · Cited by 5
Metadata
- Authors
- McDuff, D., Schaekermann, M., Tu, T., Palepu, A., Wang, A., Garrison, J., Singhal, K., Sharma, Y., Azizi, S., Kulkarni, K., Hou, L., Cheng, Y., Liu, Y., Mahdavi, S. S., Prakash, S., Pathak, A., Semturs, C., Patel, S., Webster, D. R., Dominowska, E., Gottweis, J., Barral, J., Chou, K., Corrado, G. S., Matias, Y., Sunshine, J., Karthikesalingam, A., & Natarajan, V.
- Affiliations
- Google (United States) (US)
- Google (Switzerland) (CH)
- Google (United Kingdom) (GB)
- Corresponding author
- McDuff, Daniel
- Schaekermann, Mike
- Karthikesalingam, Alan
- Natarajan, Vivek
- ORCID
- McDuff, Daniel
- Schaekermann, Mike
- Tu, Tao
- Palepu, Anil
- Wang, Amy
- Singhal, Karan
- Azizi, Shekoofeh
- Cheng, Yong
- Liu, Yun
- Mahdavi, S Sara
- Prakash, Sushant
- Pathak, Anupam
- Semturs, Christopher
- Patel, Shwetak
- Webster, Dale R
- Dominowska, Ewa
- Gottweis, Juraj
- Barral, Joelle
- Chou, Katherine
- Corrado, Greg S
- Matias, Yossi
- Karthikesalingam, Alan
- Natarajan, Vivek
- Venue
- arXiv
- Publisher
- arXiv
- Published
- 2023
- Volume
- 642
- Issue
- 8067
- Pages
- 451-457
- ISSN
- 0028-0836 (ISSN-L)
- arXiv
- 2312.00164
- PMC
- PMC12158753
- OpenAlex
- W4409283616
- Cited by
- 311
- References
- 34
- Citations by year
- 2026: 172 · 2025: 108 · 2024: 31
- FWCI
- 67.40
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Nature (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, other-oa)
- arXiv (Cornell University)
- Funders
- Massachusetts Medical Society
- DeepMind
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Keywords
- differential diagnosis, large language models, diagnostic reasoning, clinical decision support, clinician performance, AI-assisted diagnosis, medical knowledge retrieval
- MeSH terms
- Case Reports as Topic, Large Language Models, Artificial Intelligence, Diagnosis, Differential, Humans, Language
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
