

The DOI matches its Crossref record; 59 of the 59 references it cites were found in a registry or an index; 2 of the 30 sources its claims cite were checked for support.
Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study
Open accessAbstract
Background: Generative AI tools such as ChatGPT are increasingly integrated into higher education. Empirical evidence on how they shape learning dynamics over time remains limited. Previous studies have often examined single learning outcomes, neglecting the interplay between cognitive, motivational, and metacognitive processes that evolve throughout the semester. Objectives: This longitudinal study investigated how generative AI influences students' knowledge gain, motivation, cognitive load, critical thinking, and reflective use across an entire semester. It further explored whether prior knowledge and AI experience moderated these learning effects, addressing concerns about potential Matthew effects. Methods: A quasi‐experimental design was implemented with three parallel classes of business informatics students ( N = 87) assigned to different instructional conditions: tutor‐AI use, unguided AI, and a control group without AI. Data were collected at three measurement points (T1–T3). Results and Conclusion: Students showed significant knowledge gains across all groups, but no additional benefits of AI integration. Motivation remained largely stable; germane cognitive load increased and was positively associated with knowledge gain. Critical thinking remained stable, while reflective use was higher in the AI condition and positively associated with critical thinking. No evidence emerged for a Matthew effect, indicating that AI did not intensify performance inequalities. Overall, the findings did not support the view of generative AI as a consistent learning outcome. Its impact depended on pedagogical framing and learners' metacognitive regulation, underscoring the need for structured guidance and reflective engagement in AI‐supported education.
Overview
CoChat Summary
TL;DR
This longitudinal quasi-experiment with 87 business informatics students found significant knowledge gains across all conditions but no additional benefit of generative AI integration. AI’s impact depended on pedagogical framing and learners’ metacognitive regulation, with reflective use higher in AI conditions and germane cognitive load predicting knowledge gain.
Key findings
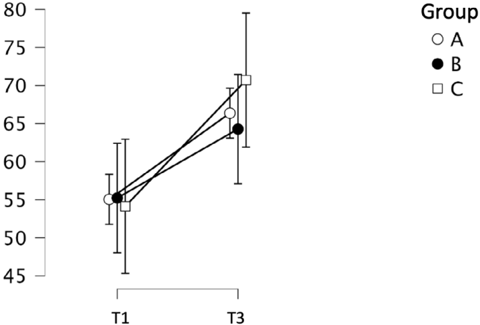
- Knowledge increased from T1 to T3 across all groups, F(1, 50) = 29.87, p < 0.001, η²p = 0.374; there was no significant Group or Time × Group effect (p = 0.682 and p = 0.469), and no moderation by prior achievement or prior AI experience (BF01 = 8.70), indicating no Matthew effect.
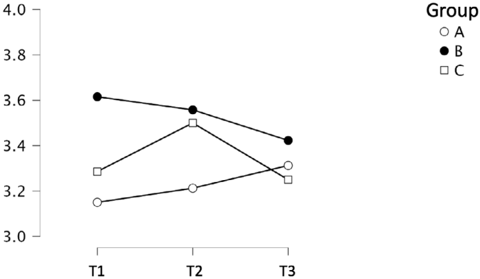
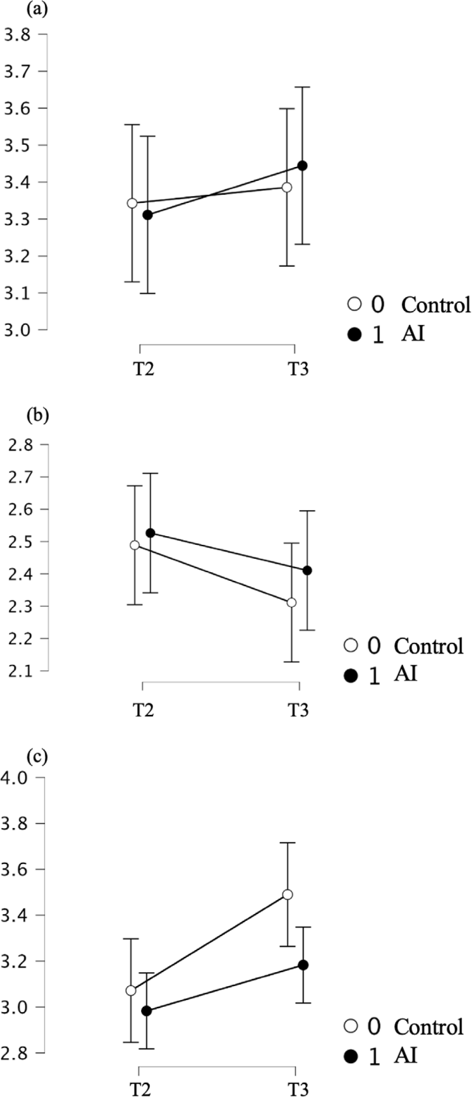
- Motivation remained stable (no Time effect, p = 0.467) and did not predict knowledge gain (R² = 0.010, p = 0.533). Germane cognitive load increased from T2 to T3, F(1, 37) = 10.86, p = 0.002, η²p = 0.227; GCL (β = 0.51, p = 0.001) and ECL (β = 0.36, p = 0.018) predicted knowledge gain.
- Critical thinking remained stable and did not predict knowledge gain (p = 0.204) or cognitive load. Reflective use was higher in the AI-supported condition than control, F(1, 40) = 20.21, p < 0.001, η²p = 0.336, and positively associated with critical thinking (β = 0.43, p < 0.001), but did not predict knowledge gain (p = 0.652).
- Of 16 hypotheses tested, six were supported and one partially supported.
Methods
- Quasi-experimental longitudinal design across one semester with three parallel classes of second-semester Business Informatics students (N = 87; 19 females, 68 males; age 18–29), assigned to tutor-AI, unguided AI, or control conditions; the same instructor and materials were used, and students completed weekly individual in-class question-generation tasks over a nine-week theory phase.
- Data were collected at T1 (first lecture), T2 (fourth lecture), and T3 (eighth lecture) via anonymised LimeSurvey questionnaires; knowledge was assessed with a 14-item multiple true-false test (maximum 70 points, converted to percentages), alongside self-report measures of motivation, cognitive load (ICL, ECL, GCL), critical thinking, and reflective use.
- Analyses in JASP included repeated-measures ANOVA/ANCOVA, linear regressions, and PROCESS moderation/mediation models; groups were compared either as three conditions or as AI versus control depending on focus and power, with α = 0.05 and complete-case handling.
Limitations
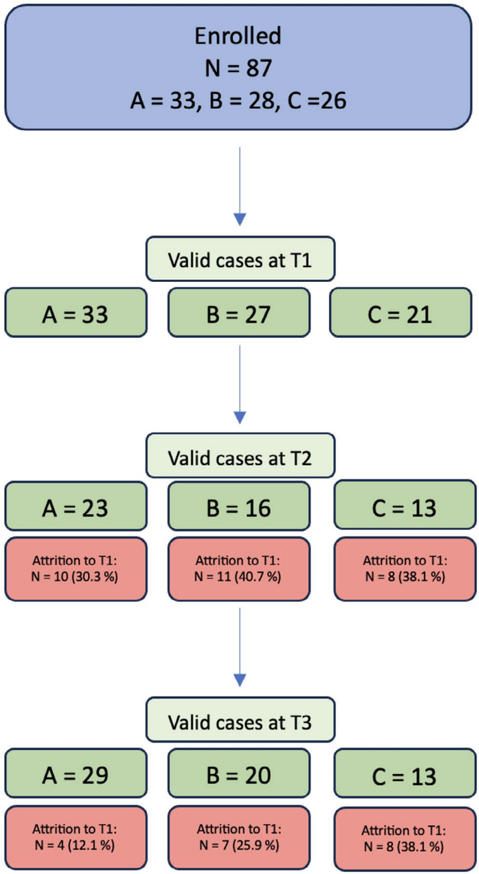
- The paper states that the quasi-experimental design assigned participants by pre-existing class groups rather than random allocation, so class-level confounds and causal caution remain; attrition was high and uneven (T3 missing relative to T1: Group C 38.1%, Group B 25.9%, Group A 12.1%), and complete-case analysis reduced statistical power.
- The paper states further limitations: small and uneven group sizes limited detection of interaction effects; the single business informatics, practice-oriented programme limits generalisability; the approximately three-month semester may be too short for critical thinking or durable AI literacy; no explicit scaffolding or structured prompting was included; novelty/Hawthorne effects may have influenced engagement; and self-report measures were used, with the motivation scale showing low internal consistency (α ≈ 0.50).
- Evident from the text: sample sizes vary widely by construct and measurement point (e.g., ECL T2 N = 33 vs. T3 N = 56; knowledge T1 N = 81 vs. T3 N = 62), and analyses use different complete-case Ns, which complicates cross-construct comparisons.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
1 Valid · 1 Not valid · 23 Not checked · 163 Own results and interpretations
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“While there are first attempts at longitudinal perspectives, they rarely link adoption patterns of AI to core educational outcomes such as knowledge gain, motivation, or critical thinking (Polyportis 2024).”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 1.7 | Research Gap and Aim
What the sources say
- Partly supportedcites Polyportis 2024 sourceExperimental — accuracy not yet measured
The Introduction describes this study as a longitudinal investigation of students’ ChatGPT usage, and the Results analyze changes in usage, trust, perceived behavioral control, and emotional creepiness. The Limitations section says the study did not examine details of how students used ChatGPT for academic purposes. This supports the paper as an example that does not link adoption to knowledge gain, motivation, or critical thinking, but it does not establish that longitudinal studies rarely make such links. (LLM, conf=0.86)
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Partly supported
The cited sources that could be checked couldn’t confirm or dispute this claim.
In the paper
“Few studies, however, track how cognitive load evolves across a semester (Sweller 1988;Leppink et al. 2014).”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 1.4 | Cognitive Load
What the sources say
- Not checked — no full text of the sourcecites Sweller 1988 source
- Could not verifycites Leppink et al. 2014 sourceExperimental — accuracy not yet measured
Study II (section 3) measured cognitive load after studying and after a subsequent task, while Study I’s Procedure (section 2.1.2) describes a questionnaire completed at the end of a class. Neither passage addresses whether few studies track cognitive load across a semester. Searches for semester-long and longitudinal tracking found no such statement in our copy. (LLM, conf=0.73)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“reflective use was higher in the AI condition and positively associated with critical thinking”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > Abstract
plainstates an associationn = 87- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“reflective use was higher in the AI condition”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > Abstract
plainn = 87- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“but no additional benefits of AI integration”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > Abstract
plainn = 87- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
103 more claims
Create a free account to see all 188 claims and to verify the 3 references still open.
- It may state two separate claims as one. 56
- Probably not a substantial claim. 38
Statistics that don’t add up
Each reported p-value recomputed from its test statistic and degrees of freedom.
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“F(1, 39) = 0.82, p = 0.204”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 3.4 | RQ4: Critical Thinking
Reported p = .204 · recomputed p = .371
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“F(1, 39) = 0.15, p = 0.693”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 3.3 | RQ3: Cognitive Load
Reported p = .693 · recomputed p = .701
Statistics recomputed
Every reported test result, recomputed from its test statistic and degrees of freedom. A result shows as not adding up only once an independent check has confirmed it.
- Doesn’t add upF(1, 39) = 0.15reported p = .693 · recomputed p = .701
“F(1, 39) = 0.15, p = .693”
- Doesn’t add upF(1, 39) = 0.82reported p = .204 · recomputed p = .371
“F(1, 39) = 0.82, p = .204”
- Not confirmedF(1, 39) = 0.01reported p = .945 · recomputed p = .921
“F(1, 39) = 0.01, p = .945”
- ConsistentF(1, 50) = 29.87reported p < .001 · recomputed p < .001
“F(1, 50) = 29.87,p < .001”
- ConsistentF(2, 50) = 0.39reported p = .682 · recomputed p = .679
“F(2, 50) = 0.39, p = .682”
30 more recomputed tests
Create a free account to see every test the Stats check recomputed.
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated major: it would touch a result — a value a result rests on, reported and recomputed p-values on opposite sides of the significance level, two passages that conflict with no sign which is right, or a cited work retracted before this paper was published.
In the paper
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 3.5 | RQ5: Reflective Use
“For ECL, the model was nonsignificant, F(2, 53) = 0.39, p = 0.678, R 2 = 0.02.”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 5 | Conclusion
“| Reflective use (T2) | 23 | 16 | 11 | 50 |”
Rated major: it would touch a result — a value a result rests on, reported and recomputed p-values on opposite sides of the significance level, two passages that conflict with no sign which is right, or a cited work retracted before this paper was published.
In the paper
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 3.5 | RQ5: Reflective Use
“A linear regression examined whether reflective use (T3) was positively associated with critical thinking (T3).The model was significant, F(1, 58) = 12.95, p < 0.001, R 2 = 0.183.”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 5 | Conclusion
“| Critical thinking (T3) | 27 | 17 | 12 | 56 |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 2.2 | Participants
“At T1, data were available for up to 81 students, at T2 for up to 52, and at T3 for up to 62.”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 5 | Conclusion
“| Motivation (T2) | 23 | 16 | 11 | 50 |”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 4.6 | Limitations and Future Research
“Moreover, the intervention did not include explicit scaffolding or structured prompting, which may have limited the pedagogical impact of AI support.”
§ Generative AI and Learning Dynamics in Higher Education: A Longitudinal Empirical Study > 2.1 | Research Design
“Group A received explicit instructional introduction to the AI-as-tutor approach, including structured guidance on effective prompting (role-task-output framing) and explicit contrasts between appropriate and inappropriate forms of generative AI regarding the task.”
Citations
Cites
The "what" and "why" of goal pursuits: Human needs and the self-determination of behavior
Deci, E. L., & Ryan, R. M. (2000) · Psychological Inquiry · doi:10.1207/s15327965pli1104_01 · Cited by 34,210
Intrinsic Motivation and Self-Determination in Human Behavior
Deci, E. L., & Ryan, R. M. (1985) · doi:10.1007/978-1-4899-2271-7 · Cited by 26,772
Metacognition and cognitive monitoring: A new area of cognitive–developmental inquiry
Flavell, J. H. (1979) · American Psychologist · doi:10.1037/0003-066x.34.10.906 · Cited by 11,282
Cognitive Load During Problem Solving: Effects on Learning
Sweller, J. (1988) · Cognitive Science · doi:10.1016/0364-0213(88)90023-7 · Cited by 11,048
Kirschner, P. A., Sweller, J., & Clark, R. E. (2006) · Educational Psychologist · doi:10.1207/s15326985ep4102_1 · Cited by 7,776
Zawacki-Richter, O., Marín, V. I., Bond, M., & Gouverneur, F. (2019) · International Journal of Educational Technology in Higher Education · doi:10.1186/s41239-019-0171-0 · Cited by 7,242
Sweller, J., Ayres, P., & Kalyuga, S. (2011) · Elsevier eBooks · doi:10.1007/978-1-4419-1428-6_446 · Cited by 6,210
Cognitive Architecture and Instructional Design
Sweller, J., van Merrienboer, J. J. G., & Paas, F. G. W. C. (1998) · Educational Psychology Review · doi:10.1023/a:1022193728205 · Cited by 6,023
Sweller, J., Ayres, P., & Kalyuga, S. (2011) · doi:10.1007/978-1-4419-8126-4 · Cited by 5,531
Stanovich, K. E. (1986) · Reading Research Quarterly · doi:10.1598/rrq.21.4.1 · Cited by 5,222
Humans and automation: Use, misuse, disuse, abuse
Parasuraman, R., & Riley, V. (1997) · Human Factors: The Journal of the Human Factors and Ergonomics Society · doi:10.1518/001872097778543886 · Cited by 4,554
Enhancing teaching through constructive alignment
Biggs, J. (1996) · Higher Education · doi:10.1007/bf00138871 · Cited by 4,084
What is AI Literacy? Competencies and Design Considerations
Long, D., & Magerko, B. (2020) · Proceedings of the 2020 CHI Conference on Human Factors in Computing Systems · doi:10.1145/3313831.3376727 · Cited by 3,241
Cognitive Load Theory and Instructional Design: Recent Developments
Paas, F., Renkl, A., & Sweller, J. (2003) · Educational Psychologist · doi:10.1207/s15326985ep3801_1 · Cited by 3,041
Human trust in artificial intelligence: Review of empirical research
Glikson, E., & Woolley, A. W. (2020) · Academy of Management Annals · doi:10.5465/annals.2018.0057 · Cited by 2,921
Conceptualizing AI literacy: An exploratory review
Ng, D. T. K., Leung, J. K. L., Chu, S. K. W., & Qiao, M. S. (2021) · Computers and Education: Artificial Intelligence · doi:10.1016/j.caeai.2021.100041 · Cited by 2,205
A Review of Artificial Intelligence (AI) in Education from 2010 to 2020
Zhai, X., Chu, X., Chai, C. S., Jong, M. S. Y., Istenic, A., Spector, M., Liu, J.-B., Yuan, J., & Li, Y. (2021) · Complexity · doi:10.1155/2021/8812542 · Cited by 1,364
AI Tools in Society: Impacts on Cognitive Offloading and the Future of Critical Thinking
Gerlich, M. (2025) · Societies · doi:10.3390/soc15010006 · Cited by 1,248
Credibility and trust of information in online environments: The use of cognitive heuristics
Metzger, M. J., & Flanagin, A. J. (2013) · Journal of Pragmatics · doi:10.1016/j.pragma.2013.07.012 · Cited by 1,000
The development of epistemological understanding
Kuhn, D., Cheney, R. E., & Weinstock, M. P. (2000) · Cognitive Development · doi:10.1016/s0885-2014(00)00030-7 · Cited by 840
Development of a Questionnaire to Measure the Level of Reflective Thinking
Kember, D., Leung, D. Y. P., Jones, A., Loke, A. Y., McKay, J., Sinclair, K., Tse, H., Webb, C., Yuet Wong, F. K., Wong, M., et al. (2000) · Assessment & Evaluation in Higher Education · doi:10.1080/713611442 · Cited by 812
Kuhn, D. (2000) · Current Directions in Psychological Science · doi:10.1111/1467-8721.00088 · Cited by 555
Can Students Evaluate Online Sources? Learning From Assessments of Civic Online Reasoning
McGrew, S., Breakstone, J., Ortega, T., Smith, M., & Wineburg, S. (2018) · Theory & Research in Social Education · doi:10.1080/00933104.2017.1416320 · Cited by 533
Effects of pairs of problems and examples on task performance and different types of cognitive load
Leppink, J., Paas, F., van Gog, T., van der Vleuten, C. P. M., & van Merriënboer, J. J. G. (2014) · Learning and Instruction · doi:10.1016/j.learninstruc.2013.12.001 · Cited by 520
AI literacy and its implications for prompt engineering strategies
Knoth, N., Tolzin, A., Janson, A., & Leimeister, J. M. (2024) · Computers and Education: Artificial Intelligence · doi:10.1016/j.caeai.2024.100225 · Cited by 368
Gruenhagen, J. H., Sinclair, P. M., Carroll, J.-A., Baker, P. R. A., Wilson, A., & Demant, D. (2024) · Computers and Education: Artificial Intelligence · doi:10.1016/j.caeai.2024.100273 · Cited by 339
Artificial Intelligence in Education
Holmes, W. (2019) · Encyclopedia of Education and Information Technologies · doi:10.1007/978-3-319-60013-0_107-1 · Cited by 336
Entwistle, N. J. (1991) · Higher Education · doi:10.1007/bf00132287 · Cited by 277
Chiu, T. K. F. (2024) · Educational technology research and development · doi:10.1007/s11423-024-10366-w · Cited by 235
Kestin, G., Miller, K., Klales, A., Milbourne, T., & Ponti, G. (2025) · Scientific Reports · doi:10.1038/s41598-025-97652-6 · Cited by 214
Kaplan, A., & Garner, J. (2020) · The Journal of Experimental Education · doi:10.1080/00220973.2020.1745738 · Cited by 146
Halpern, D. F. (2013) · doi:10.4324/9781315885278 · Cited by 140
Krieglstein, F., Beege, M., Rey, G. D., Ginns, P., Krell, M., & Schneider, S. (2022) · Educational Psychology Review · doi:10.1007/s10648-022-09683-4 · Cited by 118
Self-citationThe longitudinal trajectories of online engagement over a full program
Saqr, M., & López‐Pernas, S. (2021) · Computers & Education · doi:10.1016/j.compedu.2021.104325 · Cited by 113
Polyportis, A. (2024) · Frontiers in Artificial Intelligence · doi:10.3389/frai.2023.1324398 · Cited by 111
Critical Thinking: Reflection and Perspective Part II
Ennis, R., & Philosophy Documentation Center (2011) · Inquiry: Critical Thinking Across the Disciplines · doi:10.5840/inquiryctnews201126215 · Cited by 92
Hou, C., Zhu, G., & Sudarshan, V. (2025) · British Journal of Educational Technology · doi:10.1111/bjet.13613 · Cited by 72
Cohen, R., Katz, I., Aelterman, N., & Vansteenkiste, M. (2022) · European Journal of Psychology of Education · doi:10.1007/s10212-022-00635-8 · Cited by 67
Boguslawski, S., Deer, R., & Dawson, M. G. (2025) · Information and Learning Sciences · doi:10.1108/ils-10-2023-0163 · Cited by 66
Laru, J., Çelik, İ., Jokela, I., & Mäkitalo‐Siegl, K. (2025) · European Journal of Teacher Education · doi:10.1080/02619768.2025.2535623 · Cited by 65
Generative AI as a Tool for Enhancing Reflective Learning in StudentsPreprint
Yuan, B., & Hu, J. (2024) · doi:10.36227/techrxiv.173324189.99227671/v1 · Cited by 64
Zhao, G., Sheng, H., Wang, Y., Cai, X., & Long, T. (2025) · Education Sciences · doi:10.3390/educsci15050554 · Cited by 60
Börekci, C., & Çelik, Ö. (2024) · Sakarya University Journal of Education · doi:10.19126/suje.1468866 · Cited by 59
Huang, K., & Ball, C. (2024) · Proceedings of the Association for Information Science and Technology · doi:10.1002/pra2.1146 · Cited by 47
Generative AI in Undergraduate Medical Education: A Rapid Review
Hale, J., Alexander, S., Wright, S. T., & Gilliland, K. (2024) · Journal of Medical Education and Curricular Development · doi:10.1177/23821205241266697 · Cited by 46
Generative AI and Educational (In)Equity
Gabriel, S. (2024) · Proceedings of the International Conference on AI Research. · doi:10.34190/icair.4.1.3153 · Cited by 42
The Role of Prior Achievement as an Antecedent to Student Homework Engagement
Piñeiro, I., Estévez, I., Freire, C., Fuertes, A. M. D. C., Souto-Seijo, A., & Sanmamed, M. G. (2019) · Frontiers in Psychology · doi:10.3389/fpsyg.2019.00140 · Cited by 39
Zhao, Y., & Huang, L. (2025) · Frontiers in Psychology · doi:10.3389/fpsyg.2025.1699174 · Cited by 32
Bosch, E., & Spinath, B. (2023) · Zeitschrift für Psychologie · doi:10.1027/2151-2604/a000519 · Cited by 27
Prompting Minds: Evaluating how Students Perceive Generative AI’s Critical Thinking Dispositions
Oliveira, L., Tavares, C., Strzelecki, A., & Silva, M. (2025) · Electronic Journal of e-Learning · doi:10.34190/ejel.23.2.3986 · Cited by 21
Multiple true–false items: a comparison of scoring algorithms
Lahner, F.-M., Lörwald, A. C., Bauer, D., Nouns, Z. M., Krebs, R., Guttormsen, S., Fischer, M. R., & Huwendiek, S. (2017) · Advances in Health Sciences Education · doi:10.1007/s10459-017-9805-y · Cited by 20
Use of cognitive load measurements to design a new architecture of intelligent learning systems
Zammouri, A., Moussa, A. A., & Chevallier, S. (2023) · Expert Systems with Applications · doi:10.1016/j.eswa.2023.121253 · Cited by 19
AI Ethics in the Fields of Education and Research: A Systematic Literature Review
Contreras, M. R., & Jaimes, J. O. P. (2024) · 2024 International Symposium on Accreditation of Engineering and Computing Education (ICACIT) · doi:10.1109/icacit62963.2024.10788651 · Cited by 18
Suprobo, W., Basuki, S., & Nurasiah, N. (2025) · Khazanah Informatika Jurnal Ilmu Komputer dan Informatika · doi:10.23917/khif.v10i2.3056 · Cited by 11
Generative AI as a Tool for Enhancing Reflective Learning in Students
Yuan, B., & Hu, J. (2024) · arXiv · doi:10.48550/arxiv.2412.02603 · Cited by 8
Moy, M., & Feldstein, A. (2024) · Proceedings of the International Conference on Networked Learning · doi:10.54337/nlc.v14i1.8091 · Cited by 7
Cervantes, J., & Navarro, E. (2025) · Journal of interdisciplinary perspectives · doi:10.69569/jip.2025.194 · Cited by 7
Reconceptualise a dynamic framework of the learning constructs in higher education
Geng, G. H., Zhu, Y., & Disney, L. (2023) · Higher Education Quarterly · doi:10.1111/hequ.12427 · Cited by 6
True-False Tests that Measure and Promote Structural Understanding
Diekhoff, G. M. (1984) · Teaching of Psychology · doi:10.1207/s15328023top1102_11 · Cited by 5
Research works printed but not linked: 5
- Hayes A. F., 2022, Introduction to Mediation, Moderation, and Conditional Process Analysis: A Regression‐Based Approach
- Liu Y. W.Cui S.Wu andW.Kek Tan.2025.“Generative AI in Education: A Review of Applications Impacts and Future Research Directions.”ICIS 2025 Proceedings (International Conference on Information Systems 2025).https://aisel.aisnet.org/icis2025/learn_curricula/learn_curricula/13.
- Melanou C., 2026, Transforming Education With AI
- Rigney D., 2010, The Matthew Effect: How Advantage Begets Further Advantage
- Wong A. H. L. W.Wong S. C.Hooi andS. S.Lee.2024.Student‐Generated Questions: A Novel Approach for Encouraging Cognitive EngagementHigher Education Conference in Singapore (HECS) 2024. National University of Singapore.https://blog.nus.edu.sg/hecs/hecs2024‐ahpwong‐et‐al‐2/.
Cited by
Artificial Intelligence and Human Cognitive Development: A Thematic Analysis
GUDIA, R. (2026) · International Journal For Multidisciplinary Research · doi:10.36948/ijfmr.2026.v08i06.91433
Wei, J. (2026) · Frontiers in Psychology · doi:10.3389/fpsyg.2026.2029407
Metadata
- Authors
- Melanou, C., Beege, M., & Kimmig, M.
- Affiliations
- Baden-Wuerttemberg Cooperative State University (DE)
- University of Education Freiburg (DE)
- Corresponding author
- Melanou, Chrysanthi
- Venue
- Journal of Computer Assisted Learning
- Publisher
- Wiley
- Published
- 2026-09-10
- Volume
- 42
- Issue
- 5
- ISSN
- 0266-4909 (ISSN-L)
- 1365-2729
- OpenAlex
- W7212183669
- Semantic Scholar
- abb3784e5c6bb84a28c373e0942d9bf82992f846
- Cited by
- 2
- References
- 56
- Citations by year
- 2026: 2
- FWCI
- 9.92
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- creativecommons.org/licenses/by/4.0/ (vor)
- doi.wiley.com/10.1002/tdm_license_1.1 (tdm)
- Locations
- Journal of Computer Assisted Learning (publishedVersion, cc-by)
- Topics
- Social Sciences › Education › Artificial Intelligence in Education
- Physical Sciences › Computer Science › Artificial Intelligence › Intelligent Tutoring Systems and Adaptive Learning
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Keywords
- generative AI in education, ChatGPT, higher education, knowledge improvement, student motivation, cognitive load, critical thinking, Matthew effect, prior knowledge, AI experience, metacognitive regulation, business informatics education
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-11-12, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-12 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
