

The DOI matches its Crossref record; 63 of the 63 references it cites were found in a registry or an index; none of the 32 sources its claims cite is checked for support yet.
Large-scale simulation study of active learning models for systematic reviews
Open accessAbstract
Despite progress in active learning, evaluation remains limited by constraints in simulation size, infrastructure, and dataset availability. This study advocates for large-scale simulations as the gold standard for evaluating active learning models in systematic review screening. Two large-scale simulations, totaling over 29 thousand runs, assessed active learning solutions. The first study evaluated 13 combinations of classification models and feature extraction techniques using high-quality datasets from the SYNERGY dataset. The second expanded this to 92 model combinations with additional classifiers and feature extractors. In every scenario tested, active learning outperformed random screening. The performance gained varied across datasets, models, and screening progression, ranging from considerable to near-flawless results. The findings demonstrate that active learning consistently outperforms random screening in systematic review tasks, offering significant efficiency gains. While the extent of improvement varies depending on the dataset, model choice, and screening stage, the overall advantage is clear. Since model performance differs, active learning systems should remain adaptable to accommodate new classifiers and feature extraction techniques. The publicly available results underscore the importance of open benchmarking to ensure reproducibility and the development of robust, generalizable active learning strategies.
Overview
CoChat Summary
TL;DR
This large-scale simulation study evaluated active learning for systematic review screening across 26 SYNERGY datasets, using 13 common model combinations in study 1 and 92 expanded combinations in study 2. Active learning consistently outperformed random screening, but no single classifier–feature extractor combination was universally best across datasets or screening stages.
Key findings
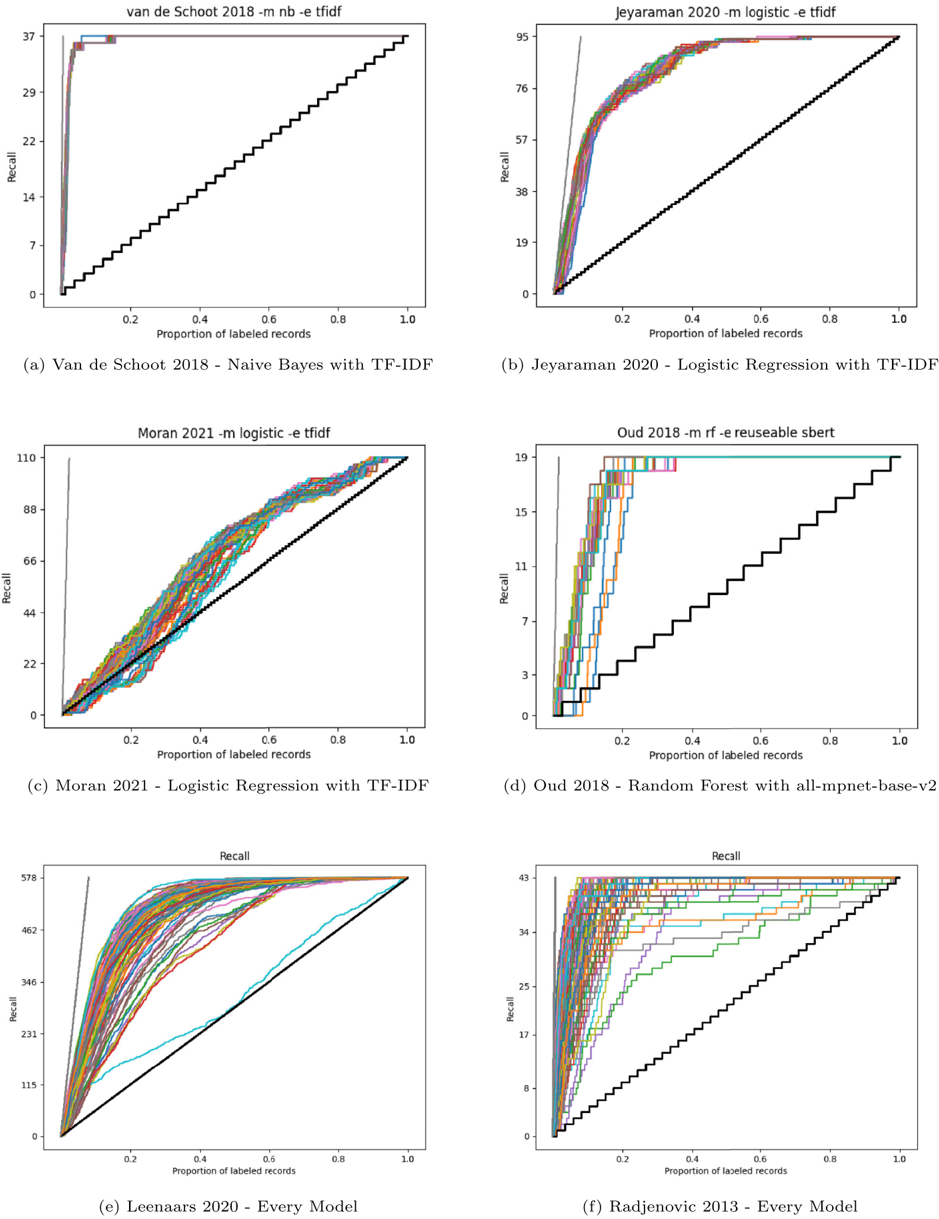
- Across all tested scenarios, active learning outperformed random screening; performance gains ranged from marginal to near-flawless depending on dataset, model, and screening stage.
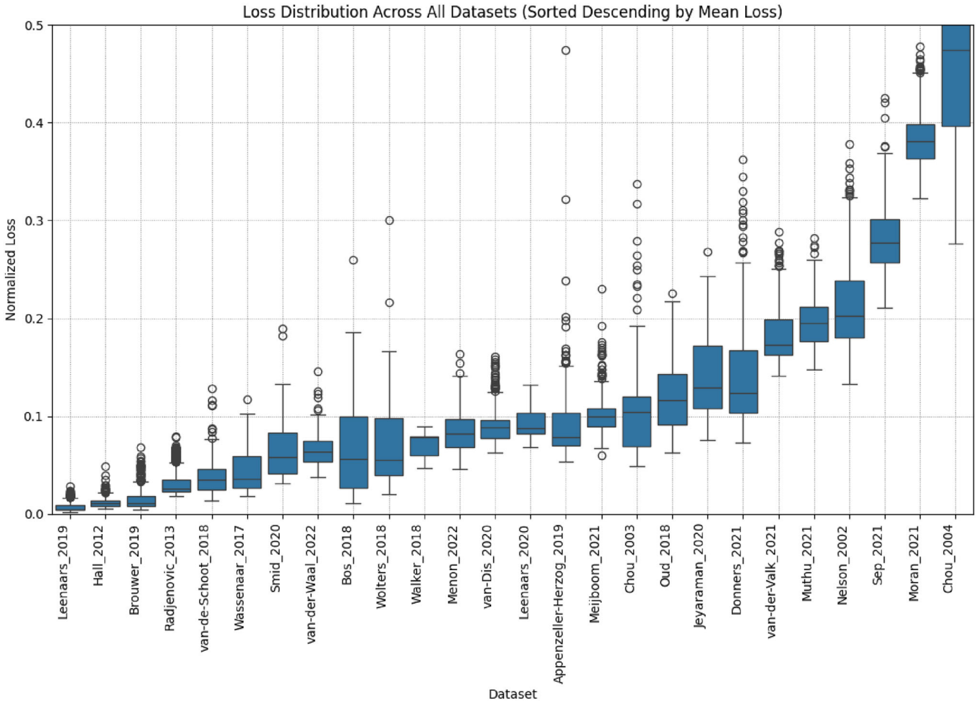
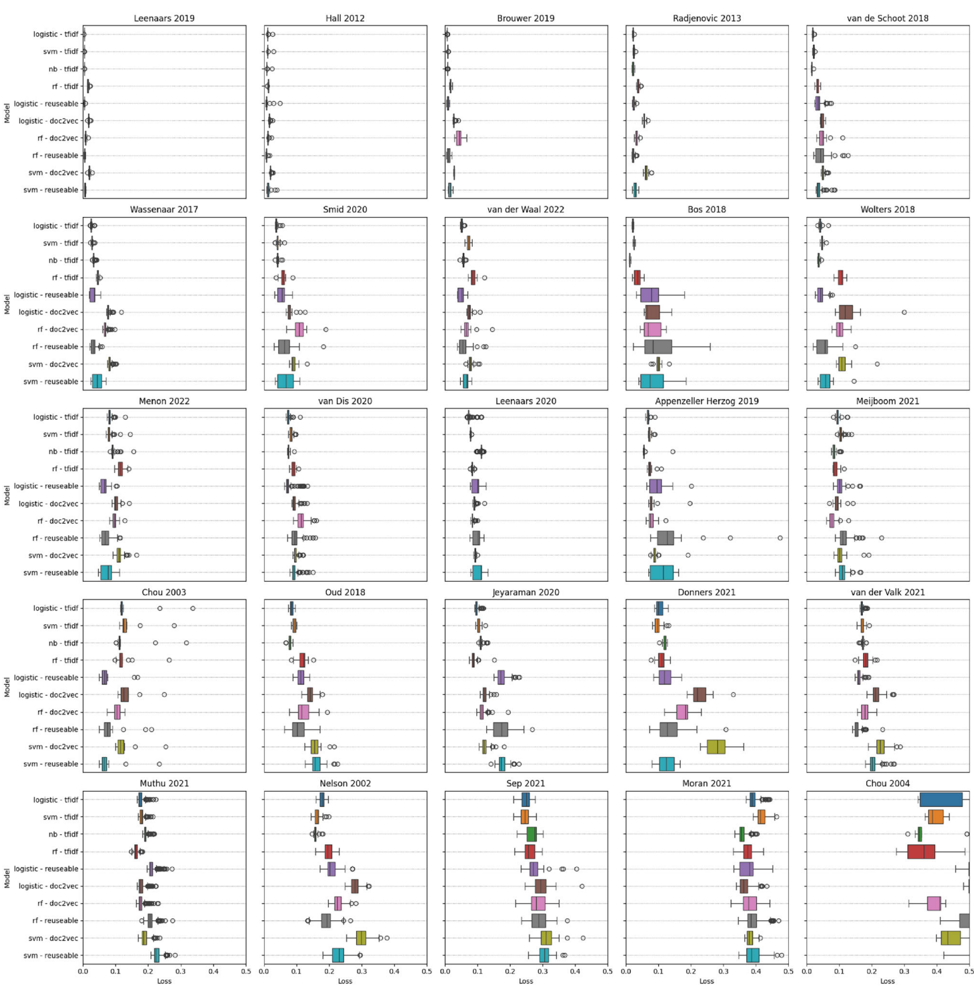
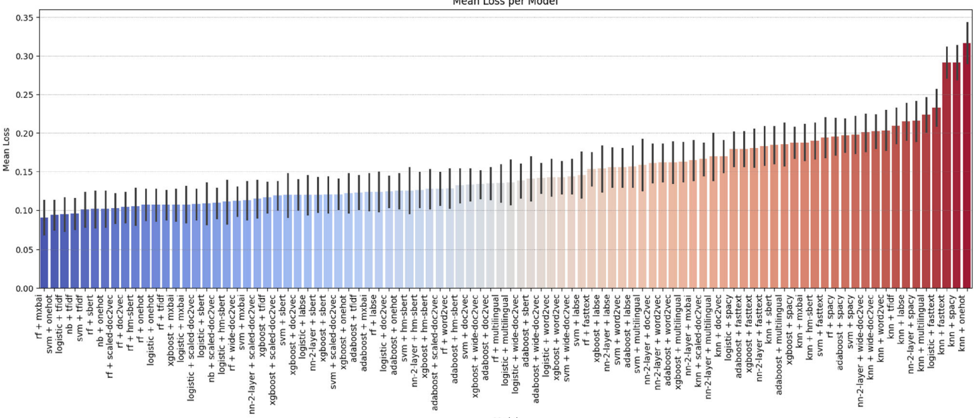
- No model was universally optimal: out of 26 datasets, 14 different classifier–feature extractor combinations achieved the lowest loss at least once, and the most frequent top performer, “mxbai-embed-large-v1 transformer with Random Forest,” was best in only 7 of 26 cases.
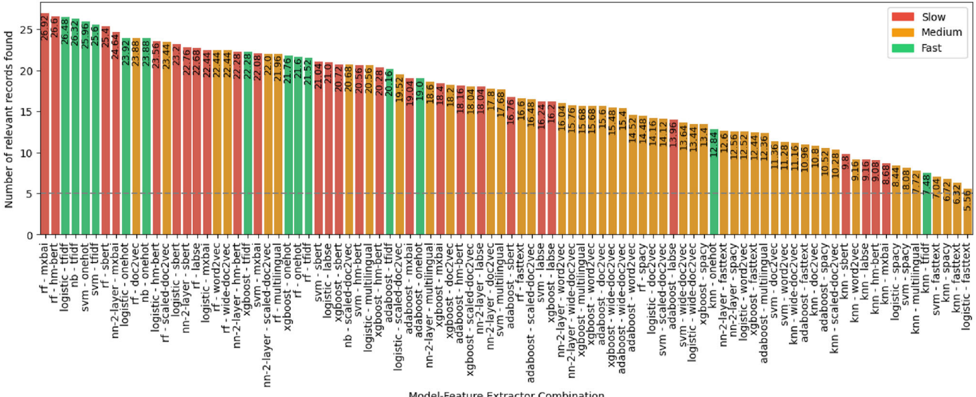
- For starting performance, the best models identified an average of 27 relevant records within the first 100 screened records, against a theoretical maximum of 51; 44 of 92 models reached the top-performing spot at least once.
- For last-to-find records, advanced models significantly outperformed simpler models, and Random Forest with mxbai-embed-large-v1 was recommended for identifying difficult final records.
Methods
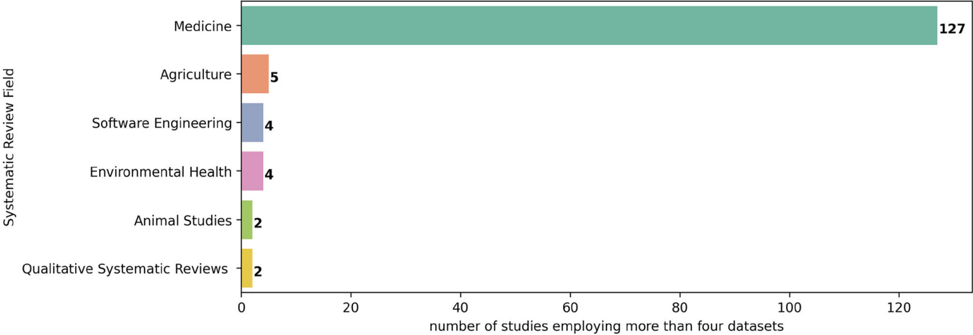
- Two simulation studies used 26 prelabeled systematic review datasets from SYNERGY, spanning medicine, psychology, computational sciences, and biology, with dataset sizes from 238 to 48,375 records and relevance densities from <0.25% to >20%.
- Study 1 evaluated 13 classifier–feature extractor combinations using the ARFI template with one relevant record plus 10 fixed irrelevant records as prior knowledge; study 2 evaluated 92 combinations using the MultiModel template with 5 relevant and 10 irrelevant prior records.
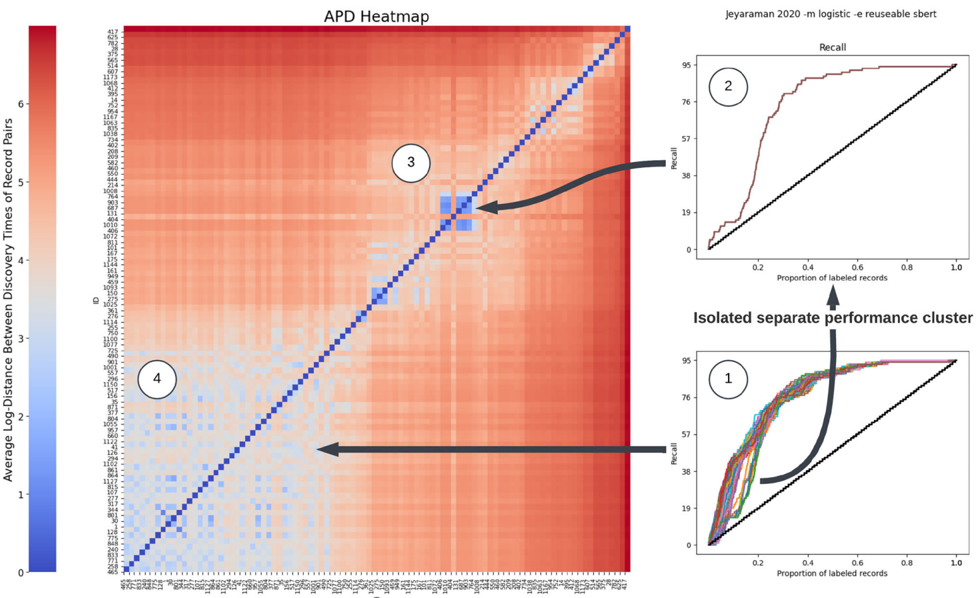
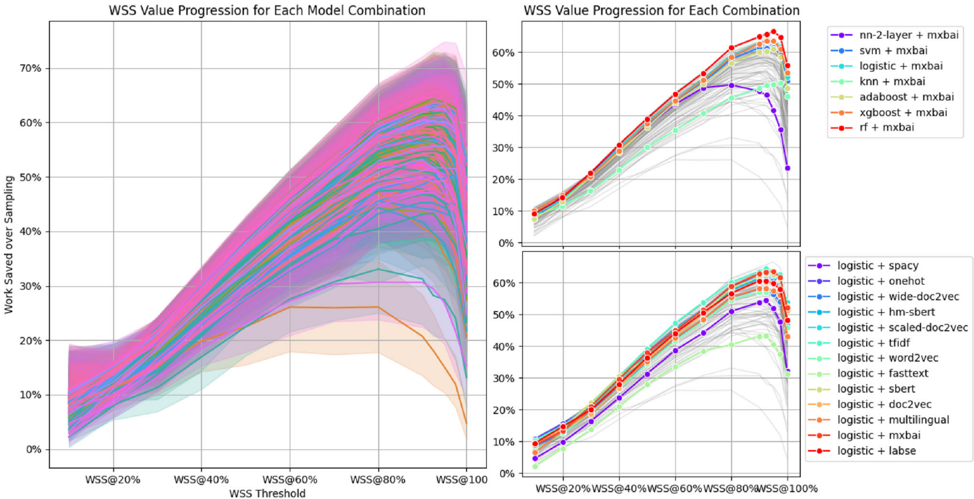
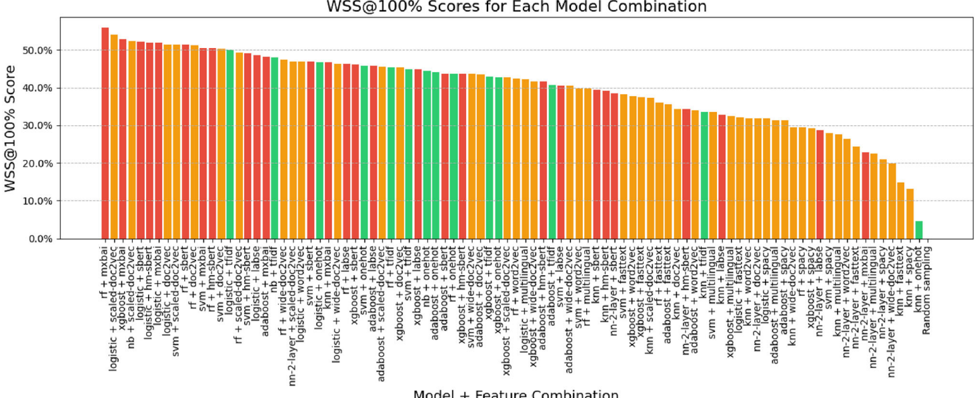
- Analyses used Normalized Recall Regret (Loss), Work Saved over Sampling (WSS@10%–WSS@100%), starting performance within the first 100 records, last-to-find performance, and Average Pair Distance heatmaps; simulations ran via ASReview on a Kubernetes cluster.
Limitations
- The paper states that not all possible configurations were covered: samplers and balancers were unexplored, models were treated as feature extractor–classifier combinations rather than separately, and hyperparameter optimization was not performed.
- The paper states that dataset characteristics such as size or topic showed no significant correlation with model preference, but 26 datasets were insufficient to draw conclusions, and SYNERGY remains 50% “medicine, NOS.”
- Evident from the text: the study relies on prelabeled retrospective datasets and simulated screening, so real-world reviewer behavior, stopping-rule interactions, and LLM-based classification remain outside the tested scope.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
36 Own result · 26 Own interpretation · 20 Not checked yet · 6 Own method · 2 Check pending · 1 No full text of the sources
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Instead, the optimal model varies depending on the specific dataset, highlighting the need for a flexible, adaptable approach when creating active learning software.”
§ Large-scale simulation study of active learning models for systematic reviews > 4 Discussion
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
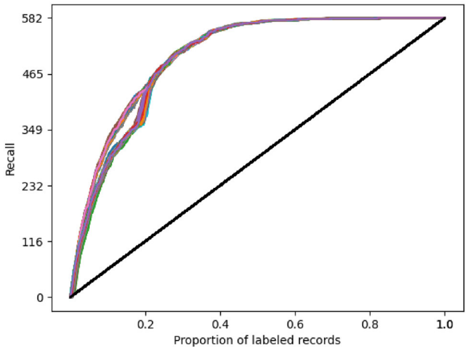
“When examining the documents from the subset, we find a significant overlap between the subcluster of identified records from the recall curve and the observed subcluster in the APD heatmap.”
§ Large-scale simulation study of active learning models for systematic reviews > Average Pair Distance Heatmap
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Out of 92 models evaluated, 44 models reached the top-performing spot at least once.”
§ Large-scale simulation study of active learning models for systematic reviews > 3.2 Simulation Study 2
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“However, the current study shows that even the weakest models generally detect enough of a pattern to slightly outperform random sampling.”
§ Large-scale simulation study of active learning models for systematic reviews > 4 Discussion
plainstates a cause- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“No model achieved superior performance across all datasets.”
§ Large-scale simulation study of active learning models for systematic reviews > 4 Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
57 more claims
Create a free account to see all 91 claims and to verify the 29 references still open.
- It may state two separate claims as one. 14
- Probably not a substantial claim. 16
- The quote only partly states this claim. 2
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated major: it would touch a result — a value a result rests on, reported and recomputed p-values on opposite sides of the significance level, two passages that conflict with no sign which is right, or a cited work retracted before this paper was published.
In the paper
§ Large-scale simulation study of active learning models for systematic reviews > 1 Introduction
“These simulations use only two records to start the active learning cycle.One relevant and one irrelevant document, which together, are known as the Prior Knowledge.”
§ Large-scale simulation study of active learning models for systematic reviews > 2.4 Prior knowledge
“In our first simulation study, we conduct one simulation for each relevant record, together with 10 fixed irrelevant records, using the ARFI (All Relevant -Fixed Irrelevant) template from ASReview-Makita [56] to minimize inter-dataset variation.”
Rated minor: it would not touch a result — a value no result rests on, a p-value that stays on the same side of the significance level, or a conflict that is clerical, resolved elsewhere in the paper, or outside its own findings.
In the paper
“Valk_2021 Medicine, Psychology 725 89 0.8%”
§ Large-scale simulation study of active learning models for systematic reviews > 2.3 Models
Reported 0.8 · recomputed 12.275862
Citations
Cites
XGBoost: A Scalable Tree Boosting System
Chen, T., & Guestrin, C. (2016) · Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining · doi:10.1145/2939672.2939785 · Cited by 54,569
PRISMA-P Group, Moher, D., Shamseer, L., Clarke, M., Ghersi, D., Liberati, A., Petticrew, M., Shekelle, P., & Stewart, L. A. (2015) · Systematic Reviews · doi:10.1186/2046-4053-4-1 · Cited by 26,223
Page, M. J., Moher, D., Bossuyt, P. M., Boutron, I., Hoffmann, T. C., Mulrow, C. D., Shamseer, L., Tetzlaff, J. M., Akl, E. A., Brennan, S. E., et al. (2021) · BMJ · doi:10.1136/bmj.n160 · Cited by 13,262
Sentence-BERT: Sentence Embeddings using Siamese BERT-Networks
Reimers, N., & Gurevych, I. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1410 · Cited by 12,778
Enriching Word Vectors with Subword Information
Bojanowski, P., Grave, E., Joulin, A., & Mikolov, T. (2017) · Transactions of the Association for Computational Linguistics · doi:10.1162/tacl_a_00051 · Cited by 9,645
Cumpston, M., Li, T., Page, M. J., Chandler, J., Welch, V. A., Higgins, J. P., & Thomas, J. (2019) · Cochrane Database of Systematic Reviews · doi:10.1002/14651858.ed000142 · Cited by 7,218
How to Fine-Tune BERT for Text Classification?
Sun, C., Qiu, X., Xu, Y., & Huang, X. (2019) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-32381-3_16 · Cited by 1,534
An open source machine learning framework for efficient and transparent systematic reviews
van de Schoot, R., de Bruin, J., Schram, R., Zahedi, P., de Boer, J., Weijdema, F., Kramer, B., Huijts, M., Hoogerwerf, M., Ferdinands, G., et al. (2021) · Nature Machine Intelligence · doi:10.1038/s42256-020-00287-7 · Cited by 1,157
A Systematic Literature Review on Fault Prediction Performance in Software Engineering
Hall, T., Beecham, S., Bowes, D., Gray, D., & Counsell, S. (2012) · IEEE Transactions on Software Engineering · doi:10.1109/tse.2011.103 · Cited by 1,154
Language-agnostic BERT Sentence Embedding
Feng, F., Yang, Y., Cer, D., Arivazhagan, N., & Wang, W. (2022) · Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2022.acl-long.62 · Cited by 758
Marshall, I. J., & Wallace, B. C. (2019) · Systematic Reviews · doi:10.1186/s13643-019-1074-9 · Cited by 638
Automation of systematic literature reviews: A systematic literature review
van Dinter, R., Tekinerdogan, B., & Catal, C. (2021) · Information and Software Technology · doi:10.1016/j.infsof.2021.106589 · Cited by 432
Reducing Workload in Systematic Review Preparation Using Automated Citation Classification
Cohen, A. M., Hersh, W. R., Peterson, K., & Yen, P.-Y. (2006) · Journal of the American Medical Informatics Association · doi:10.1197/jamia.m1929 · Cited by 411 · cited 4×
“Even the high-quality Cohen dataset [11], often considered the gold standard in the field, is limited to drug class reviews.”
InfluentialMiniLMv2: Multi-Head Self-Attention Relation Distillation for Compressing Pretrained Transformers
Wang, W., Bao, H., Huang, S., Dong, L., & Wei, F. (2021) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2021.findings-acl.188 · Cited by 372
Artificial intelligence and the conduct of literature reviews
Wagner, G., Lukyanenko, R., & Paré, G. (2021) · Journal of Information Technology · doi:10.1177/02683962211048201 · Cited by 364
Living systematic reviews: 2. Combining human and machine effort
Thomas, J., Noel-Storr, A., Marshall, I., Wallace, B., McDonald, S., Mavergames, C., Glasziou, P., Shemilt, I., Synnot, A., Turner, T., et al. (2017) · Journal of Clinical Epidemiology · doi:10.1016/j.jclinepi.2017.08.011 · Cited by 355
Semi-automated screening of biomedical citations for systematic reviews
Wallace, B. C., Trikalinos, T. A., Lau, J., Brodley, C., & Schmid, C. H. (2010) · BMC Bioinformatics · doi:10.1186/1471-2105-11-55 · Cited by 351
Applications of text mining within systematic reviews
Thomas, J., McNaught, J., & Ananiadou, S. (2011) · Research Synthesis Methods · doi:10.1002/jrsm.27 · Cited by 212
On behalf of the founding members of the ICASR group, Beller, E., Clark, J., Tsafnat, G., Adams, C., Diehl, H., Lund, H., Ouzzani, M., Thayer, K., Thomas, J., et al. (2018) · Systematic Reviews · doi:10.1186/s13643-018-0740-7 · Cited by 191
Tools to support the automation of systematic reviews: a scoping review.
Khalil, H., Ameen, D., & Zarnegar, A. (2022) · Journal of Clinical Epidemiology · doi:10.1016/j.jclinepi.2021.12.005 · Cited by 190
Howard, B. E., Phillips, J., Tandon, A., Maharana, A., Elmore, R., Mav, D., Sedykh, A., Thayer, K., Merrick, B. A., Walker, V., et al. (2020) · Environment International · doi:10.1016/j.envint.2020.105623 · Cited by 157
Prioritising references for systematic reviews with RobotAnalyst: A user study
Przybyła, P., Brockmeier, A. J., Kontonatsios, G., Le Pogam, M., McNaught, J., von Elm, E., Nolan, K., & Ananiadou, S. (2018) · Research Synthesis Methods · doi:10.1002/jrsm.1311 · Cited by 148 · cited 1×
“Despite the widespread use of Support Vector Machines (SVMs) in active learning [2, 8, 42, 67], our results suggest that SVM can underperform compared to several other clas-sifiers.”
Boetje, J., & van de Schoot, R. (2024) · Systematic Reviews · doi:10.1186/s13643-024-02502-7 · Cited by 146 · cited 1×
“To balance efficiency and thorough-ness, users should follow the SAFE procedure [4].”
Hamel, C., Kelly, S. E., Thavorn, K., Rice, D. B., Wells, G. A., & Hutton, B. (2020) · BMC Medical Research Methodology · doi:10.1186/s12874-020-01129-1 · Cited by 140
Oud, M., Arntz, A., Hermens, M. L., Verhoef, R., & Kendall, T. (2018) · Australian & New Zealand Journal of Psychiatry · doi:10.1177/0004867418791257 · Cited by 134
Text mining approaches for dealing with the rapidly expanding literature on COVID-19
Wang, L. L., & Lo, K. (2020) · Briefings in Bioinformatics · doi:10.1093/bib/bbaa296 · Cited by 119
O’Connor, A. M., Tsafnat, G., Gilbert, S. B., Thayer, K. A., Shemilt, I., Thomas, J., Glasziou, P., & Wolfe, M. S. (2019) · Systematic Reviews · doi:10.1186/s13643-019-0975-y · Cited by 110
Topic detection using paragraph vectors to support active learning in systematic reviews
Hashimoto, K., Kontonatsios, G., Miwa, M., & Ananiadou, S. (2016) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2016.06.001 · Cited by 103
Ferdinands, G., Schram, R., de Bruin, J., Bagheri, A., Oberski, D. L., Tummers, L., Teijema, J. J., & van de Schoot, R. (2023) · Systematic Reviews · doi:10.1186/s13643-023-02257-7 · Cited by 96 · cited 3×
“For last-to-find records [7, 19, 22], advanced models sig-nificantly outperform simpler models due to their ability to detect contextual and semantic relationships.”
Self-citationCierco Jimenez, R., Lee, T., Rosillo, N., Cordova, R., Cree, I. A., Gonzalez, A., & Indave Ruiz, B. I. (2022) · BMC Medical Research Methodology · doi:10.1186/s12874-022-01805-4 · Cited by 85
Scott, A. M., Forbes, C., Clark, J., Carter, M., Glasziou, P., & Munn, Z. (2021) · Journal of Clinical Epidemiology · doi:10.1016/j.jclinepi.2021.06.030 · Cited by 81
Robledo, S., Grisales Aguirre, A. M., Hughes, M., & Eggers, F. (2023) · Journal of Small Business Management · doi:10.1080/00472778.2021.1955125 · Cited by 80
Cowie, K., Rahmatullah, A., Hardy, N., Holub, K., & Kallmes, K. (2022) · JMIR Medical Informatics · doi:10.2196/33219 · Cited by 68
ASReview LAB - A tool for AI-assisted systematic reviews
developers, A. L. (2026) · Zenodo · doi:10.5281/zenodo.3345592 · Cited by 59
Olorisade, B. K., Brereton, P., & Andras, P. (2017) · Journal of Biomedical Informatics · doi:10.1016/j.jbi.2017.07.010 · Cited by 54
Olorisade, B. K., de Quincey, E., Brereton, P., & Andras, P. (2016) · Proceedings of the 20th International Conference on Evaluation and Assessment in Software Engineering · doi:10.1145/2915970.2915982 · Cited by 42
Pharmacokinetics and Associated Efficacy of Emicizumab in Humans: A Systematic Review
Donners, A. A. M. T., Rademaker, C. M. A., Bevers, L. A. H., Huitema, A. D. R., Schutgens, R. E. G., Egberts, T. C. G., & Fischer, K. (2021) · Clinical Pharmacokinetics · doi:10.1007/s40262-021-01042-w · Cited by 40
Carvallo, A., Parra, D., Löbel, H., & Soto, Á. (2020) · Scientometrics · doi:10.1007/s11192-020-03648-6 · Cited by 37
Teijema, J. J., Hofstee, L., Brouwer, M., de Bruin, J., Ferdinands, G., de Boer, J., Vizan, P., van den Brand, S., Bockting, C., van de Schoot, R., et al. (2023) · Frontiers in Research Metrics and Analytics · doi:10.3389/frma.2023.1178181 · Cited by 36
Self-citationTowards Question-based High-recall Information Retrieval
Zou, J., & Kanoulas, E. (2020) · ACM Transactions on Information Systems · doi:10.1145/3388640 · Cited by 35
Measuring the impact of screening automation on meta-analyses of diagnostic test accuracy
Norman, C. R., Leeflang, M., Porcher, R., & Névéol, A. (2019) · Systematic Reviews · doi:10.1186/s13643-019-1162-x · Cited by 34
Ferdinands, G. (2020) · Multivariate Behavioral Research · doi:10.1080/00273171.2020.1853501 · Cited by 34
Muthu, S., & Ramakrishnan, E. (2021) · Spine · doi:10.1097/brs.0000000000003645 · Cited by 30
Machine learning to optimize literature screening in medical guideline development
Harmsen, W., de Groot, J., Harkema, A., van Dusseldorp, I., de Bruin, J., van den Brand, S., & van de Schoot, R. (2024) · Systematic Reviews · doi:10.1186/s13643-024-02590-5 · Cited by 21
SYNERGY - Open machine learning dataset on study selection in systematic reviews
De Bruin, J., Ma, Y., Ferdinands, G., Teijema, J., & Van de Schoot, R. (2023) · DataverseNL · doi:10.34894/he6naq · Cited by 20
Self-citationReproducibility and Data Storage for Active Learning-Aided Systematic Reviews
Lombaers, P., de Bruin, J., & van de Schoot, R. (2024) · Applied Sciences · doi:10.3390/app14093842 · Cited by 20
Semi-automated Tools for Systematic Searches
Adam, G. P., Wallace, B. C., & Trikalinos, T. A. (2022) · Methods in Molecular Biology · doi:10.1007/978-1-0716-1566-9_2 · Cited by 19
Evaluating software tools to conduct systematic reviews: a feature analysis and user survey
Pellegrini, M., & Marsili, F. (2021) · Form@re - Open Journal per la formazione in rete · doi:10.36253/form-11343 · Cited by 17
The rodent object-in-context task: A systematic review and meta-analysis of important variables
Sep, M. S. C., Vellinga, M., Sarabdjitsingh, R. A., & Joëls, M. (2021) · PLOS ONE · doi:10.1371/journal.pone.0249102 · Cited by 17
Sleep and Microdialysis: An Experiment and a Systematic Review of Histamine and Several Amino Acids
Leenaars, C. H. C., Drinkenburg, W. H. P., Nolten, C., Dematteis, M., Joosten, R. N. J. M. A., Feenstra, M. G. P., & De Vries, R. B. M. (2019) · Journal of Circadian Rhythms · doi:10.5334/jcr.183 · Cited by 11
Simulation-based Active Learning for Systematic Reviews: A Scoping Review of Literature
Teijema, J. J., Ribeiro, G., Seuren, S., Anadria, D., Bagheri, A., & van de Schoot, R. (2023) · doi:10.31234/osf.io/67zmt · Cited by 10
Self-citationByrne, F., Hofstee, L., Teijema, J., De Bruin, J., & van de Schoot, R. (2024) · Systematic Reviews · doi:10.1186/s13643-024-02587-0 · Cited by 9
Self-citationTeijema, J. J., van den Brand, S. A. G. E., Bagheri, A., & van de Schoot, R. (2021) · doi:10.17605/osf.io/t9hgm · Cited by 8
Self-citationRomanov, S., Siqueira, A. S., de Bruin, J., Teijema, J., Hofstee, L., & van de Schoot, R. (2024) · Data Intelligence · doi:10.1162/dint_a_00244 · Cited by 7
Self-citationTeijema, J. J., van de Schoot, R., Ferdinands, G., Lombaers, P., & de Bruin, J. (2024) · Software Impacts · doi:10.1016/j.simpa.2024.100663 · Cited by 7
Self-citationUsing Chao’s Estimator as a Stopping Criterion for Technology-Assisted Review
Bron, M., van der Heijden, P. G. M., Feelders, A., & Siebes, A. (2025) · ACM Transactions on Information Systems · doi:10.1145/3724116 · Cited by 7
Nieto González, D. M. (2022) · doi:10.11144/javeriana.10554.58492 · Cited by 6
Ambert, K. H., Cohen, A. M., Burns, G. A. P. C., Boudreau, E., & Sonmez, K. (2013) · Frontiers in Neuroinformatics · doi:10.3389/fninf.2013.00038 · Cited by 6
Assessing expert system-assisted literature reviews with a case study
Yu, Z., Carver, J. C., Rothermel, G., & Menzies, T. (2022) · Expert Systems with Applications · doi:10.1016/j.eswa.2022.116958 · Cited by 6
jteijema/asreview-simulation-project: v1.1.3
Teijema, J. J. (2023) · Zenodo (CERN European Organization for Nuclear Research) · doi:10.5281/zenodo.7991081 · Cited by 4
Self-citationCarey, N., Harte, M., & McCullagh, L. (2021) · International Journal of Technology Assessment in Health Care · doi:10.1017/s0266462321000696 · Cited by 2
Simulation Data for: Large-Scale Simulation Study of Active Learning models for Systematic Reviews
Teijema, J. J. (2023) · DataverseNL · doi:10.34894/nyfsjy · Cited by 2
Self-citationjteijema/synergy-simulations-website: Release on Zenodo
Teijema, J. J. (2024) · Zenodo (CERN European Organization for Nuclear Research) · doi:10.5281/zenodo.10841479 · Cited by 1
Self-citation
Research works printed but not linked: 2
- Molinari, A., Kanoulas, E.: Transferring knowledge between topics in systematic reviews. Intell. Syst. Appl. 16, 200150 (2022)
- Xuan, Q., Jiali, L., Yuning, W., et al.: Application of natural language processing in systematic reviews. Chin. J. Evid.-Based Med. 21(6), 715–720 (2021). https://doi.org/10.7507/1672-2531.202012150 · DOI
Cited by
LLM-Guided Weak Supervision Improves Active Learning for Abstract ScreeningPreprint
Akinseloyin, O., Jiang, X., & Palade, V. (2025) · medRxiv · doi:10.1101/2025.08.24.25334314 · Cited by 6
ASReview Dory: Bringing new and exciting models to ASReview LAB
van der Kuil, T., Teijema, J. J., Bruin, J. D., & van de Schoot, R. (2026) · Software Impacts · doi:10.1016/j.simpa.2025.100809 · Cited by 2
Self-citationActive Learning for Medical Article Classification with Bag of Words and Bag of Concepts Embeddings
Pytlak, R., Cichosz, P., Fajdek, B., & Jastrzębski, B. (2025) · Applied Sciences · doi:10.3390/app15147955 · Cited by 1
Screenathon 2.0: human–AI collaborative screening applied to patient-generated health data
Bergmann, J. G., Azzi, T. D. S., Neeleman, R. C., Monschau, K., Yazan, B., Jalsovec, E., Westerbeek, E., Weijdema, F., Bruin, J. D., Fang, Q., et al. (2026) · Scientific Reports · doi:10.1038/s41598-026-45385-5 · Cited by 1
Empowered XR through Generative AI: Balancing Superpowers and Risks
Tang, Y., Wu, M., Situ, J., Liu, J., Cui, A. Y., & Huang, Y. (2026) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3772318.3791307 · Cited by 1
Metadata
- Authors
- Teijema, J. J., de Bruin, J., Bagheri, A., & van de Schoot, R.
- Affiliations
- Utrecht University (NL)
- Corresponding author
- Teijema, Jelle Jasper
- Venue
- International Journal of Data Science and Analytics
- Published
- 2025-05-02
- Volume
- 20
- Issue
- 6
- Pages
- 5435-5456
- ISSN
- 2364-4168 (ISSN-L)
- 2364-415X
- OpenAlex
- W4410030482
- Semantic Scholar
- a1024997e1ec0350279625c7185443a1bd3d0c2d
- Cited by
- 13
- References
- 63
- Citations by year
- 2026: 10 · 2025: 3
- FWCI
- 0.72
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Locations
- International Journal of Data Science and Analytics (publishedVersion, cc-by)
- PsyArXiv (OSF Preprints) (submittedVersion, cc-by)
- Funders
- OCRE
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning and Algorithms
- Social Sciences › Decision Sciences › Statistics, Probability and Uncertainty › Meta-analysis and systematic reviews
- Physical Sciences › Computer Science › Information Systems › Information Retrieval and Search Behavior
- Keywords
- active learning (machine learning), systematic review screening, large-scale simulation, classifier comparison, feature extraction, random screening, benchmarking, reproducibility, screening efficiency
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-11-12, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-11-12 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
