

Larger and more instructable language models become less reliable
Open accessThe DOI matches its Crossref record; 61 of the 61 references it cites were found in a registry or an index; 2 of the 15 sources its claims cite were checked for support.
Abstract
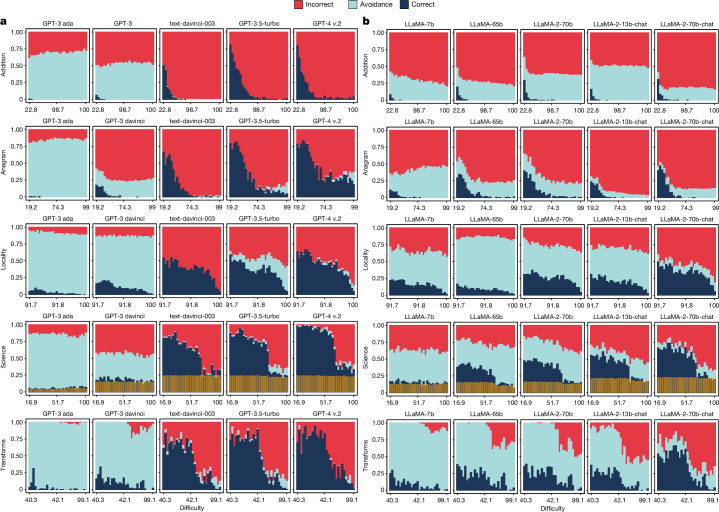
The prevailing methods to make large language models more powerful and amenable have been based on continuous scaling up (that is, increasing their size, data volume and computational resources 1 ) and bespoke shaping up (including post-filtering 2,3 , fine tuning or use of human feedback 4,5 ). However, larger and more instructable large language models may have become less reliable. By studying the relationship between difficulty concordance, task avoidance and prompting stability of several language model families, here we show that easy instances for human participants are also easy for the models, but scaled-up, shaped-up models do not secure areas of low difficulty in which either the model does not err or human supervision can spot the errors. We also find that early models often avoid user questions but scaled-up, shaped-up models tend to give an apparently sensible yet wrong answer much more often, including errors on difficult questions that human supervisors frequently overlook. Moreover, we observe that stability to different natural phrasings of the same question is improved by scaling-up and shaping-up interventions, but pockets of variability persist across difficulty levels. These findings highlight the need for a fundamental shift in the design and development of general-purpose artificial intelligence, particularly in high-stakes areas for which a predictable distribution of errors is paramount.
Overview
CoChat Summary
TL;DR
Across 32 LLMs from the GPT, LLaMA and BLOOM families on five benchmarks, scaling and instruction/alignment shaping improved correctness and prompt stability but did not create reliable low-difficulty operating regions. Shaped-up models increasingly replaced avoidance with plausible but incorrect answers, making errors harder for human supervisors to catch.
Key findings
- Human difficulty proxies predicted correctness, but no error-free easy region emerged: for LLaMA, no model achieved 60% correctness at the simplest difficulty level (discounting 25% random guess for science), and only GPT-4 showed a low-difficulty science region with almost perfect results up to medium difficulty.
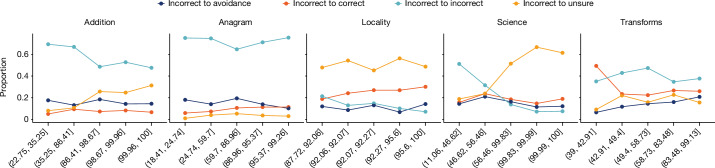
- Scaling and shaping exchanged avoidance for incorrectness: avoidance almost disappeared for GPT-4, incorrectness increased markedly from raw to shaped-up models, and ultracrepidarianism—incorrect over avoidant plus incorrect answers, i/(a + i)—rose.
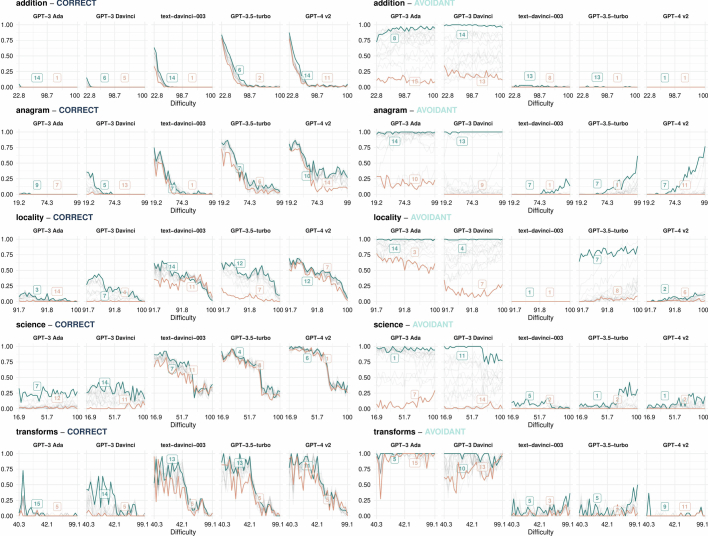
- Prompting stability improved with scaling and shaping, but pockets of variability persisted across difficulty levels; raw GPT and all LLaMA models were highly prompt-sensitive even for unambiguous addition.
- Human supervision study S2 found few areas where the dangerous error of considering an incorrect answer correct was low enough to constitute a safe operating region.
Methods
- Analysed 32 models: 10 GPT, 10 LLaMA and 12 BLOOM, including raw and shaped-up versions, across five benchmarks: addition, anagram, locality, science and transforms. Each example was run with 15 natural prompt templates per benchmark, yielding approximately 4.2 million answers; temperature was set to zero and no system prompt was used.
- Data samples: 3,142 addition instances, 1,570 anagrams, 2,341 locality instances, science from 1,000 OpenBookQA questions plus 546 GPQA questions minus two over-length items, and 730 transforms items (73 tasks × 10 instances). Two human studies (S1 and S2) recruited participants via Prolific at £9 per hour.
- Difficulty was calibrated to a 0–100 human-failure scale via logistic mapping, then examples were split into 30 equal-sized difficulty bins. Analyses included Spearman rank correlations, six reliability indicators for correctness and prudence (proportion, prompting stability, difficulty concordance), and a scaling analysis using FLOPs.
Limitations
- Stated: participants were mostly non-experts, which affects calibrated difficulty values; the natural prompt sample came from diverse sources but lacked real-world prompt-frequency data; and only a sample of model families was covered, excluding LLMs that delegate to external tools or use sophisticated reasoning techniques.
- Evident: GPT models were accessed through APIs and may change over time; response scoring relied on algorithmic conditions and regular expressions, which may not capture all response nuance; calibrated difficulty values are estimates from human study S1 and should be interpreted cautiously, especially for small differences.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures




Verification
Claims the paper makes
1 Valid · 0 Not valid · 9 Not checked · 58 Own results and interpretations
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“F3b—improvement in prompt performance is not monotonic across difficulty levels.”
§ Larger and more instructable language models become less reliable > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For the LLaMA family, no model achieves 60% correctness at the simplest difficulty level (discounting 25% random guess for ‘science’).”
§ Larger and more instructable language models become less reliable > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on 2 assumptions not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The percentage of avoidant answers rarely rises quicker than the percentage of incorrect ones.”
§ Larger and more instructable language models become less reliable > Results
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on 2 assumptions not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“scaled-up, shaped-up models do not secure areas of low difficulty in which either the model does not err or human supervision can spot the errors”
§ Larger and more instructable language models become less reliable > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on 2 assumptions not shown here.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Supplementary Table 8 shows the correlations between correctness and the proxies for human difficulty. Except for BLOOM for addition, all of them are high.”
§ Larger and more instructable language models become less reliable > Results
plainstates an association- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Rests on an assumption not shown here.
18 more claims
Create a free account to see all 68 claims and to verify the 13 references still open.
- Probably not a substantial claim. 26
- It may state two separate claims as one. 27
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“while its intrinsic fallibility, the tendency to produce confident but incorrect outputs, demands continuous human oversight.”
From Generative AI and Organizational Structure in the Knowledge Economy (2025) · cites this paper as Zhou et al. 2024
Experimental — accuracy not yet measuredThe cited source says what the claim attributes to it.
In the citing paper
“Second, they struggle with many aspects of reasoning (Shwartz, 2024;Zhou et al., 2024;Huckle and Williams, 2025).”
From There is no such thing as conscious artificial intelligence (2025) · cites this paper as Zhou et al., 2024
The cited source says what the claim attributes to it.
In the citing paper
“our result aligns with and extends recent findings that earlier LLMs were more likely to avoid answering difficult questions, whereas newer, larger, and more instructible models, instead of refusing to answer, often produced misleadingly authoritative yet flawed responses [41].”
From Generalization bias in large language model summarization of scientific research (2025) · cites this paper as [41]
The cited source says what the claim attributes to it.
In the citing paper
“Zhou et al. (2024) document that more capable language models can exhibit equal or higher hallucination rates on certain task categories”
From Generative AI and Organizational Structure in the Knowledge Economy (2025) · cites this paper as Zhou et al. (2024)
Citations
Cites
Language Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372 · cited 2×
“The first four models, GPT-3 ada, babbage, curie and davinci, are the original raw models in the family 14 .”
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P. J. (2019) · arXiv · doi:10.48550/arxiv.1910.10683 · Cited by 10,929 · cited 12×
“In Supplementary Note 13, we discuss how different groups of cells are named.”
InfluentialScaling Laws for Neural Language Models
Kaplan, J., McCandlish, S., Henighan, T., Brown, T. B., Chess, B., Child, R., Gray, S., Radford, A., Wu, J., & Amodei, D. (2020) · arXiv · doi:10.48550/arxiv.2001.08361 · Cited by 9,550
ChatGPT for Good? On Opportunities and Challenges of Large Language Models for Education
Kasneci, E., Seßler, K., Küchemann, S., Bannert, M., Dementieva, D., Fischer, F., Gasser, U., Groh, G., Günnemann, S., Hüllermeier, E., et al. (2023) · doi:10.35542/osf.io/5er8f · Cited by 7,552
ChatGPT for good? On opportunities and challenges of large language models for education
Kasneci, E., Sessler, K., Küchemann, S., Bannert, M., Dementieva, D., Fischer, F., Gasser, U., Groh, G., Günnemann, S., Hüllermeier, E., et al. (2023) · Learning and Individual Differences · doi:10.1016/j.lindif.2023.102274 · Cited by 7,326
LLaMA: Open and Efficient Foundation Language Models
Touvron, H., Lavril, T., Izacard, G., Martinet, X., Lachaux, M.-A., Lacroix, T., Rozière, B., Goyal, N., Hambro, E., Azhar, F., et al. (2023) · arXiv · doi:10.48550/arxiv.2302.13971 · Cited by 4,602
Liu, P., Yuan, W., Fu, J., Jiang, Z., Hayashi, H., & Neubig, G. (2023) · ACM Computing Surveys · doi:10.1145/3560815 · Cited by 4,361 · cited 1×
“Although this prompt sensitivity has been analysed extensively 17–20 , it is poorly understood why an over-diligent system spouts a wrong answer for 100-digit addition instead of simply answering ‘I’m afraid I can’t do that’.”
Liu, P., Yuan, W., Fu, J., Jiang, Z., Hayashi, H., & Neubig, G. (2021) · arXiv · doi:10.48550/arxiv.2107.13586 · Cited by 4,352 · cited 1×
“Although this prompt sensitivity has been analysed extensively 17–20 , it is poorly understood why an over-diligent system spouts a wrong answer for 100-digit addition instead of simply answering ‘I’m afraid I can’t do that’.”
Training language models to follow instructions with human feedback
Ouyang, L., Wu, J., Jiang, X., Almeida, D., Wainwright, C. L., Mishkin, P., Zhang, C., Agarwal, S., Slama, K., Ray, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.02155 · Cited by 4,208
Large language models in medicine
Thirunavukarasu, A. J., Ting, D. S. J., Elangovan, K., Gutierrez, L., Tan, T. F., & Ting, D. S. W. (2023) · Nature Medicine · doi:10.1038/s41591-023-02448-8 · Cited by 3,944 · cited 12×
“In Supplementary Note 13, we discuss how different groups of cells are named.”
InfluentialLlama 2: Open Foundation and Fine-Tuned Chat Models
Touvron, H., Martin, L., Stone, K., Albert, P., Almahairi, A., Babaei, Y., Bashlykov, N., Batra, S., Bhargava, P., Bhosale, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2307.09288 · Cited by 2,604
GPTs are GPTs: An Early Look at the Labor Market Impact Potential of Large Language Models
Eloundou, T., Manning, S., Mishkin, P., & Rock, D. (2023) · arXiv · doi:10.48550/arxiv.2303.10130 · Cited by 2,330 · cited 12×
“In Supplementary Note 13, we discuss how different groups of cells are named.”
InfluentialA Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Dong, Z., Hou, Y., Zhang, B., Min, Y., Zhang, J., Liu, P., et al. (2026) · Frontiers of Computer Science · doi:10.1007/s11704-026-60308-3 · Cited by 2,093
A Survey of Large Language Models
Zhao, W. X., Zhou, K., Li, J., Tang, T., Wang, X., Hou, Y., Min, Y., Zhang, B., Zhang, J., Dong, Z., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.18223 · Cited by 2,090
Scaling Instruction-Finetuned Language Models
Chung, H. W., Hou, L., Longpre, S., Zoph, B., Tay, Y., Fedus, W., Li, Y., Wang, X., Dehghani, M., Brahma, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2210.11416 · Cited by 1,441
Autonomous chemical research with large language models
Boiko, D. A., MacKnight, R., Kline, B., & Gomes, G. (2023) · Nature · doi:10.1038/s41586-023-06792-0 · Cited by 1,050 · cited 1×
“They represent tasks that LLMs are likely to encounter in educational, academic and research settings 6,8,48 , some of which require considerable time to solve.”
Training Compute-Optimal Large Language Models
Hoffmann, J., Borgeaud, S., Mensch, A., Buchatskaya, E., Cai, T., Rutherford, E., Casas, D. D. L., Hendricks, L. A., Welbl, J., Clark, A., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-2176 · Cited by 932 · cited 2×
“FLOPs information usually captures both data and parameter count if models are well dimensioned 40 .”
Training Compute-Optimal Large Language Models
Hoffmann, J., Borgeaud, S., Mensch, A., Buchatskaya, E., Cai, T., Rutherford, E., Casas, D. D. L., Hendricks, L. A., Welbl, J., Clark, A., et al. (2022) · arXiv · doi:10.48550/arxiv.2203.15556 · Cited by 929 · cited 2×
“FLOPs information usually captures both data and parameter count if models are well dimensioned 40 .”
Artificial intelligence and illusions of understanding in scientific research
Messeri, L., & Crockett, M. J. (2024) · Nature · doi:10.1038/s41586-024-07146-0 · Cited by 707 · cited 1×
“Millions of people are using general-purpose artificial intelligence (AI) systems based on large language models (LLMs), which have become commonplace in areas such as education 6 , medicine 7 , science 8,9 and administration 10,11 .”
Expectations and Actions: Expectancy-Value Models in Psychology
Feather, N. T. (2021) · Routledge eBooks · doi:10.4324/9781003150879 · Cited by 693
Can a Suit of Armor Conduct Electricity? A New Dataset for Open Book Question Answering
Mihaylov, T., Clark, P., Khot, T., & Sabharwal, A. (2018) · Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d18-1260 · Cited by 649 · cited 5×
“This benchmark is built by integrating multiple-choice questions from educational settings: OpenBookQA 29 and GPQA 49 .”
InfluentialHarnessing the Power of LLMs in Practice: A Survey on ChatGPT and Beyond
Yang, J., Jin, H., Tang, R., Han, X., Feng, Q., Jiang, H., Yin, B., & Hu, X. (2023) · arXiv · doi:10.48550/arxiv.2304.13712 · Cited by 644 · cited 1×
“The GPT family has been at the fore-front in performance and has been used over a few years, making OpenAI extremely influential in the development of other language models 22,23 .”
Harnessing the power of llms in practice: a survey on chatGPT and beyond
Yang, J., Jin, H., Tang, R., Han, X., Feng, Q., Jiang, H., Zhong, S., Yin, B., & Hu, X. (2024) · ACM Transactions on Knowledge Discovery from Data · doi:10.1145/3649506 · Cited by 644 · cited 1×
“The GPT family has been at the fore-front in performance and has been used over a few years, making OpenAI extremely influential in the development of other language models 22,23 .”
Multitask Prompted Training Enables Zero-Shot Task Generalization
Sanh, V., Webson, A., Raffel, C., Bach, S. H., Sutawika, L., Alyafeai, Z., Chaffin, A., Stiegler, A., Scao, T. L., Raja, A., et al. (2021) · arXiv · doi:10.48550/arxiv.2110.08207 · Cited by 612 · cited 1×
“Although this prompt sensitivity has been analysed extensively 17–20 , it is poorly understood why an over-diligent system spouts a wrong answer for 100-digit addition instead of simply answering ‘I’m afraid I can’t do that’.”
How Is ChatGPT’s Behavior Changing Over Time?
Chen, L., Zaharia, M., & Zou, J. (2024) · Harvard Data Science Review · doi:10.1162/99608f92.5317da47 · Cited by 507
How is ChatGPT's behavior changing over time?
Chen, L., Zaharia, M., & Zou, J. (2023) · arXiv · doi:10.48550/arxiv.2307.09009 · Cited by 507
The Self-Worth Theory of Achievement Motivation: Findings and Implications
Covington, M. V. (1984) · The Elementary School Journal · doi:10.1086/461388 · Cited by 469
Beyond Accuracy: The Role of Mental Models in Human-AI Team Performance
Bansal, G., Nushi, B., Kamar, E., Lasecki, W. S., Weld, D. S., & Horvitz, E. (2019) · Proceedings of the AAAI Conference on Human Computation and Crowdsourcing · doi:10.1609/hcomp.v7i1.5285 · Cited by 466
Crosslingual Generalization through Multitask Finetuning
Muennighoff, N., Wang, T., Sutawika, L., Roberts, A., Biderman, S., Le Scao, T., Bari, M. S., Shen, S., Yong, Z. X., Schoelkopf, H., et al. (2023) · Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2023.acl-long.891 · Cited by 361
Science in the age of large language models
Birhane, A., Kasirzadeh, A., Leslie, D., & Wachter, S. (2023) · Nature Reviews Physics · doi:10.1038/s42254-023-00581-4 · Cited by 344 · cited 2×
“Millions of people are using general-purpose artificial intelligence (AI) systems based on large language models (LLMs), which have become commonplace in areas such as education 6 , medicine 7 , science 8,9 and administration 10,11 .”
Bai, Y., Kadavath, S., Kundu, S., Askell, A., Kernion, J., Jones, A., Chen, A., Goldie, A., Mirhoseini, A., & Kaplan, J. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2212.08073 · Cited by 326 · cited 3×
“For LLMs, avoidance is also referred to as hedging, refusal 3 or evasiveness 21 , including fortuitous utterances or continuations that are not answers (non-conforming), and those responses at the meta-level explaining why the question is not answered (for epistemic or ethical reasons).”
Cross-Task Generalization via Natural Language Crowdsourcing Instructions
Mishra, S., Khashabi, D., Baral, C., & Hajishirzi, H. (2022) · Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2022.acl-long.244 · Cited by 269 · cited 1×
“We integrate many data-formatting questions from a data-wrangling dataset 51 and from a ‘natural instructions’ dataset 54 , manually regenerating or adapting some of them.”
Distance estimation from cognitive maps
Thorndyke, P. W. (1981) · Cognitive Psychology · doi:10.1016/0010-0285(81)90019-0 · Cited by 256 · cited 1×
“This benchmark contains questions relating to geographical knowledge, inspired by some cognitive models of distance estimation 47 .”
Super-NaturalInstructions: Generalization via Declarative Instructions on 1600+ NLP Tasks
Wang, Y., Mishra, S., Alipoormolabashi, P., Kordi, Y., Mirzaei, A., Naik, A., Ashok, A., Dhanasekaran, A. S., Arunkumar, A., Stap, D., et al. (2022) · Proceedings of the 2022 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/2022.emnlp-main.340 · Cited by 247
Marececk, J., & Mettee, D. R. (1972) · Journal of Personality and Social Psychology · doi:10.1037/h0032399 · Cited by 194 · cited 1×
“Avoidance in human participants has been extensively explored in psychology 33–35 .”
Language Models (Mostly) Know What They Know
Kadavath, S., Conerly, T., Askell, A., Henighan, T., Drain, D., Perez, E., Schiefer, N., Hatfield-Dodds, Z., DasSarma, N., Tran-Johnson, E., et al. (2022) · arXiv · doi:10.48550/arxiv.2207.05221 · Cited by 187
Language Models can Solve Computer Tasks
Kim, G., Baldi, P., & McAleer, S. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-1723 · Cited by 137
A Holistic Approach to Undesired Content Detection in the Real World
Markov, T., Zhang, C., Agarwal, S., Eloundou, T., Lee, T., Adler, S., Jiang, A., & Weng, L. (2022) · arXiv · doi:10.48550/arxiv.2208.03274 · Cited by 129
A Holistic Approach to Undesired Content Detection in the Real World
Markov, T., Zhang, C., Agarwal, S., Eloundou Nekoul, F., Lee, T., Adler, S., Jiang, A., & Weng, L. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i12.26752 · Cited by 129
Is the Most Accurate AI the Best Teammate? Optimizing AI for Teamwork
Bansal, G., Nushi, B., Kamar, E., Horvitz, E., & Weld, D. S. (2021) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v35i13.17359 · Cited by 121 · cited 1×
“Systematically controlling for human difficulty is crucial for the understanding of user-driven reliability: human expectations of success depend on the perception of the difficulty of instances 30–32 .”
Rethink reporting of evaluation results in AI
Burnell, R., Schellaert, W., Burden, J., Ullman, T. D., Martinez-Plumed, F., Tenenbaum, J. B., Rutar, D., Cheke, L. G., Sohl-Dickstein, J., Mitchell, M., et al. (2023) · Science · doi:10.1126/science.adf6369 · Cited by 104
Self-citationLi, M., Wang, W., Feng, F., Zhu, F., Wang, Q., & Chua, T. (2024) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2024.findings-emnlp.693 · Cited by 86
Emergent autonomous scientific research capabilities of large language models
Boiko, D. A., MacKnight, R., & Gomes, G. (2023) · arXiv · doi:10.48550/arxiv.2304.05332 · Cited by 72
Ecosystem Graphs: The Social Footprint of Foundation ModelsPreprint
Bommasani, R., Soylu, D., Liao, T., Creel, K. A., & Liang, P. (2023) · arXiv.org · doi:10.48550/arxiv.2303.15772 · Cited by 54 · cited 1×
“In fact, the OpenAI application programming interface has the most dependencies when the ecosystems of foundation models are analysed 24 .”
Johnson, D. M. (1966) · Psychological Bulletin · doi:10.1037/h0023886 · Cited by 51 · cited 1×
“45), and researchers have been using anagrams to examine a variety of phenomena, such as the cognitive processes involved in problem solving 46 .”
General intelligence disentangled via a generality metric for natural and artificial intelligence
Hernández‐Orallo, J., Loe, B. S., Cheke, L. G., Martínez‐Plumed, F., & hÉigeartaigh, S. Ó. (2021) · Scientific Reports · doi:10.1038/s41598-021-01997-7 · Cited by 48
Self-citationCan language models automate data wrangling?
Jaimovitch-López, G., Ferri, C., Hernández-Orallo, J., Martínez-Plumed, F., & Ramírez-Quintana, M. J. (2023) · Machine Learning · doi:10.1007/s10994-022-06259-9 · Cited by 48 · cited 2×
“We integrate not only many data-formatting tasks—a well-studied area in LLMs 51 —but also new tasks about world knowledge, information retrieval, advertising, administration, coding, scheduling and retailing.”
Self-citationSuper-NaturalInstructions: Generalization via Declarative Instructions on 1600+ NLP Tasks
Wang, Y., Mishra, S. R., Alipoormolabashi, P., Kordi, Y., Mirzaei, A., Arunkumar, A., Ashok, A., Dhanasekaran, A. S., Naik, A., Stap, D., et al. (2022) · arXiv (Cornell University) · doi:10.48550/arxiv.2204.07705 · Cited by 46
GPQA: A Graduate-Level Google-Proof Q&A Benchmark
Rein, D., Hou, B. L., Stickland, A. C., Petty, J., Pang, R. Y., Dirani, J., Michael, J., & Bowman, S. R. (2023) · arXiv · doi:10.48550/arxiv.2311.12022 · Cited by 30 · cited 5×
“This benchmark is built by integrating multiple-choice questions from educational settings: OpenBookQA 29 and GPQA 49 .”
InfluentialCrosslingual Generalization through Multitask Finetuning
Muennighoff, N., Wang, T., Sutawika, L., Roberts, A., Biderman, S., Scao, T. L., Bari, M. S., Shen, S., Yong, Z.-X., Schoelkopf, H., et al. (2022) · arXiv · doi:10.48550/arxiv.2211.01786 · Cited by 29
LMSYS-Chat-1M: A Large-Scale Real-World LLM Conversation Dataset
Zheng, L., Chiang, W.-L., Sheng, Y., Li, T., Zhuang, S., Wu, Z., Zhuang, Y., Li, Z., Lin, Z., Xing, E. P., et al. (2023) · arXiv · doi:10.48550/arxiv.2309.11998 · Cited by 27 · cited 1×
“It focuses on domains that are most prevalent in the use of LLMs today 50 , and ensure that there is a ground truth for evaluation.”
Can ChatGPT be trusted to provide reliable estimates?
Tsigaris, P., & Teixeira da Silva, J. A. (2024) · Accountability in Research · doi:10.1080/08989621.2023.2179919 · Cited by 22 · cited 1×
“Because of this prowess, people may start using them as calculators (for example, to convert measurements to different units 16 ).”
Your Prompt is My Command: On Assessing the Human-Centred Generality of Multimodal Models
Schellaert, W., Martínez-Plumed, F., Vold, K., Burden, J., A. M. Casares, P., Sheng Loe, B., Reichart, R., Ó hÉigeartaigh, S., Korhonen, A., & Hernández-Orallo, J. (2023) · Journal of Artificial Intelligence Research · doi:10.1613/jair.1.14157 · Cited by 19 · cited 12×
“In Supplementary Note 13, we discuss how different groups of cells are named.”
InfluentialSelf-citationEcosystem Graphs: The Social Footprint of Foundation Models
Bommasani, R., Soylu, D., Liao, T., Creel, K., & Liang, P. (2023) · doi:10.21203/rs.3.rs-2961271/v1 · Cited by 14
Yang, L., McClean, S., Donnelly, M., Khan, K., & Burke, K. (2024) · ACM Transactions on Knowledge Discovery from Data · doi:10.1145/3669942 · Cited by 9
R-Tuning: Instructing Large Language Models to Say `I Don't Know'
Zhang, H., Diao, S., Lin, Y., Fung, Y. R., Lian, Q., Wang, X., Chen, Y., Ji, H., & Zhang, T. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2311.09677 · Cited by 7 · cited 1×
“Specialized language models in medicine and other critical areas may be designed with reject options, or coupled with external AI supervisors, thereby favouring avoidance by teaching the AI models when to refrain from answering 37 .”
Li, M., Wang, W., Feng, F., et al. (2024) · arXiv (Cornell University) · doi:10.48550/arxiv.2403.09972 · Cited by 6 · cited 1×
“Relevance: this predictability is crucial as alternative success estimators when model self-confidence is either not available or markedly weakened (for example, RLHF ruining calibration 3,41 ).”
Case-Mixing Effects on Anagram Solution
Witte, K. L., Freund, J. S., & Csiki, I. (2002) · The Journal of General Psychology · doi:10.1080/00221300209603132 · Cited by 5 · cited 1×
“45), and researchers have been using anagrams to examine a variety of phenomena, such as the cognitive processes involved in problem solving 46 .”
Larger and More Instructable Language Models Become Less Reliable (Code and Data)
Zhou, L., Schellaert, W., Martínez‐Plumed, F., Moros-Daval, Y., Ferri, C. S., & Hernández-Orallo, J. (2024) · Zenodo (CERN European Organization for Nuclear Research) · doi:10.5281/zenodo.12794510 · Cited by 1
Self-citationOpenAI, Achiam, J., Adler, S., Agarwal, S., Ahmad, L., Akkaya, I., Aleman, F. L., Almeida, D., Altenschmidt, J., Altman, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2303.08774
BLOOM: A 176B-Parameter Open-Access Multilingual Language Model
Workshop, B., :, Scao, T. L., Fan, A., Akiki, C., Pavlick, E., Ilić, S., Hesslow, D., Castagné, R., Luccioni, A. S., et al. (2022) · arXiv · doi:10.48550/arxiv.2211.05100
Research works printed but not linked: 7
- Devlin, J., Chang, M.-W., Lee, K. & Toutanova, K. Bert: Pre-training of deep bidirectional transformers for language understanding. In Proc. 2019 Conference of the North American Chapter of the Association for Computational Linguistics 4171–4186 (Association for Computational Linguistics, 2019).
- Sun, J., Shaib, C. & Wallace, B. C. Evaluating the zero-shot robustness of instruction-tuned language models. In The Twelfth International Conference on Learning Representations (2024).
- Zeidner, M. & Matthews, G. Evaluation anxiety. Handb. Competence Motiv. 141, 163 (2005).
- Kuhn, L., Gal, Y. & Farquhar, S. Semantic uncertainty: linguistic invariances for uncertainty estimation in natural language generation. In The Eleventh International Conference on Learning Representations (2023).
- Li, M. et al. Think twice before assure: confidence estimation for large language models through reflection on multiple answers. Preprint at https://arxiv.org/html/2403.09972v1 (2024).
- Villalobos, P. et al. Position: Will we run out of data? Limits of LLM scaling based on human-generated data. In Proc. 41st International Conference on Machine Learning (PMLR, 2024)
- Dettmers, T., Pagnoni, A., Holtzman, A. & Zettlemoyer, L. QLoRA: efficient finetuning of quantized LLMs. Adv. Neural Inf. Process. Syst.36, 10088–10115 (2024).
Cited by
Human-AI agency in the age of generative AI
Krakowski, S. (2025) · Information and Organization · doi:10.1016/j.infoandorg.2025.100560 · Cited by 162
Harmonizome 3.0: integrated knowledge about genes and proteins from diverse multi-omics resources
Diamant, I., Clarke, D. J. B., Evangelista, J. E., Lingam, N., & Ma’ayan, A. (2024) · Nucleic Acids Research · doi:10.1093/nar/gkae1080 · Cited by 197
Mirakhori, F., & Niazi, S. K. (2025) · Pharmaceuticals · doi:10.3390/ph18010047 · Cited by 143
“Real-world user interactions provide invaluable insights, enabling developers to enhance usability and performance [48].”
Generalization bias in large language model summarization of scientific research
Peters, U., & Chin-Yee, B. (2025) · Royal Society Open Science · doi:10.1098/rsos.241776 · Cited by 126
AI hallucinations can’t be stopped — but these techniques can limit their damage
Jones, N. (2025) · Nature · doi:10.1038/d41586-025-00068-5 · Cited by 118
Metadata
- Authors
- Zhou, L., Schellaert, W., Martínez-Plumed, F., Moros-Daval, Y., Ferri, C., & Hernández-Orallo, J.
- Affiliations
- University of Cambridge (GB)
- Universitat Politècnica de València (ES)
- ORCID
- Venue
- Nature
- Published
- 2024-09-25
- Volume
- 634
- Issue
- 8032
- Pages
- 61-68
- ISSN
- 0028-0836 (ISSN-L)
- 1476-4687
- PMC
- PMC11446866
- OpenAlex
- W4402827393
- Cited by
- 203
- References
- 47
- Citations by year
- 2026: 98 · 2025: 95 · 2024: 10
- FWCI
- 29.90
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- creativecommons.org/licenses/by/4.0 (tdm)
- creativecommons.org/licenses/by/4.0 (vor)
- Locations
- Nature (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- RiuNet (Universitat Politècnica de València) (publishedVersion, cc-by)
- Apollo (University of Cambridge) (submittedVersion, cc-by)
- RePEc: Research Papers in Economics (submittedVersion)
- Funders
- Open Philanthropy Project
- Generalitat Valenciana (CIPROM/2022/6, 952215, PID2021-122830OB-C42)
- Defense Advanced Research Projects Agency (HR00112120007)
- Horizon 2020 Framework Programme (EC H2020, 952215)
- European Regional Development Fund (MCIN/AEI/10, H2020, PID2021-122830OB-C42, MICIU/AEI/10)
- Agencia Estatal de Investigación (13039, MCIN / AEI/10, PID2021-122830OB-C42, 10.13039, H2020, AEI/10, PID2021)
- Topics
- Physical Sciences › Computer Science › Artificial Intelligence › Topic Modeling
- Physical Sciences › Computer Science › Artificial Intelligence › Natural Language Processing Techniques
- Physical Sciences › Computer Science › Artificial Intelligence › Adversarial Robustness in Machine Learning
- Keywords
- large language models, model reliability, task avoidance, scale-up, human oversight, error distribution
- MeSH terms
- Feedback, Natural Language Processing, Research Design, Reproducibility of Results
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
The claim verdicts this report counts are experimental: their accuracy is not yet measured.
A language model drew the claims from the paper on 2026-10-05, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-05 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
