

The DOI matches its Crossref record; 37 of the 38 references it cites were found in a registry or an index, and 1 are not checked yet.
Towards accurate differential diagnosis with large language models
Open accessAbstract
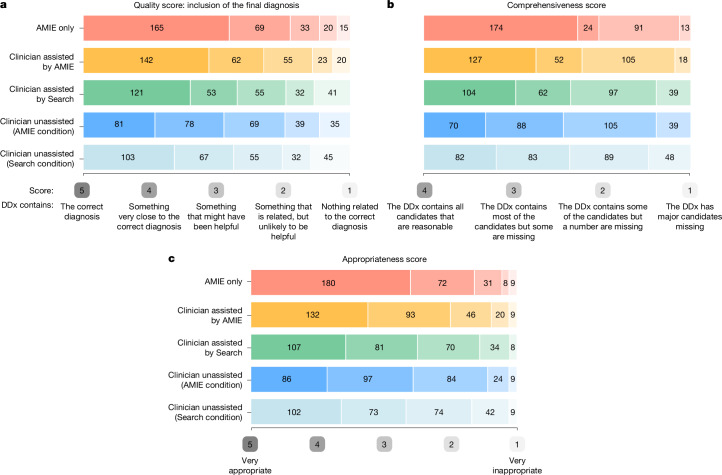
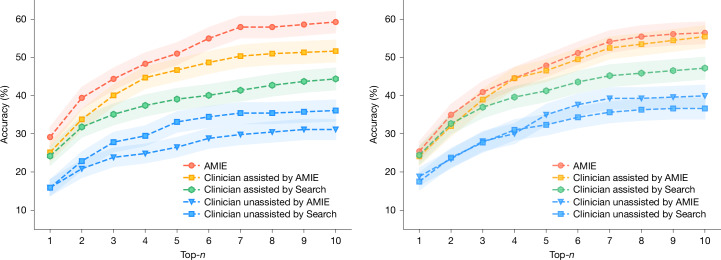
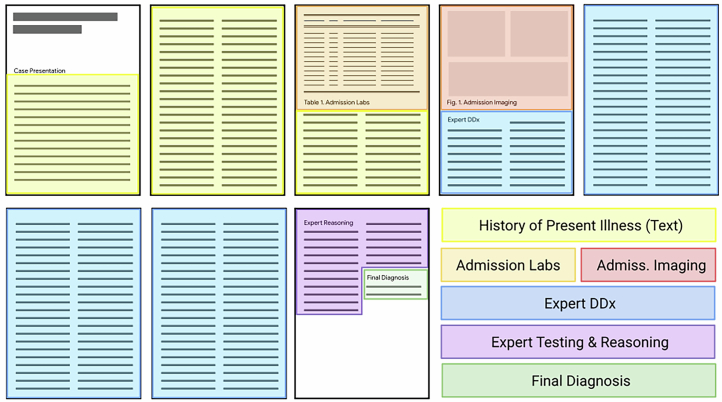
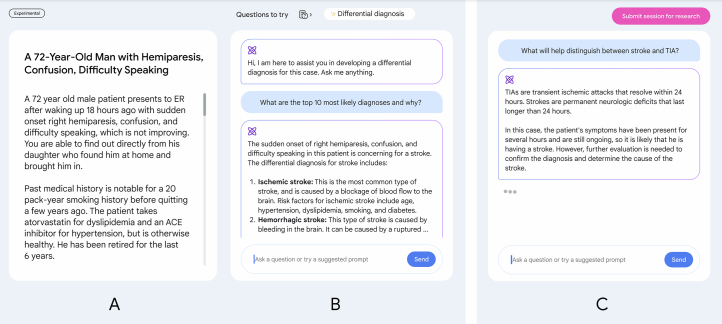
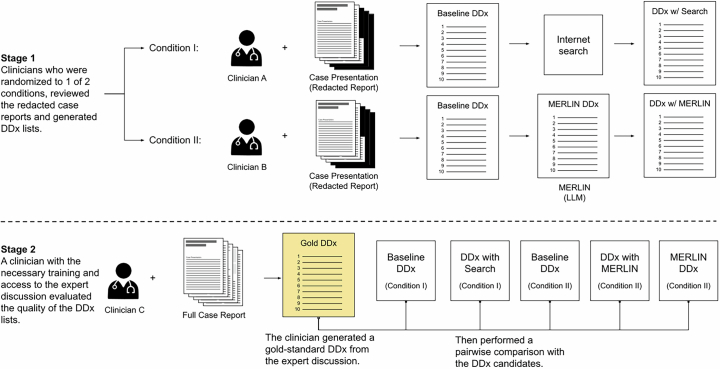
A comprehensive differential diagnosis is a cornerstone of medical care that is often reached through an iterative process of interpretation that combines clinical history, physical examination, investigations and procedures. Interactive interfaces powered by large language models present new opportunities to assist and automate aspects of this process 1 . Here we introduce the Articulate Medical Intelligence Explorer (AMIE), a large language model that is optimized for diagnostic reasoning, and evaluate its ability to generate a differential diagnosis alone or as an aid to clinicians. Twenty clinicians evaluated 302 challenging, real-world medical cases sourced from published case reports. Each case report was read by two clinicians, who were randomized to one of two assistive conditions: assistance from search engines and standard medical resources; or assistance from AMIE in addition to these tools. All clinicians provided a baseline, unassisted differential diagnosis prior to using the respective assistive tools. AMIE exhibited standalone performance that exceeded that of unassisted clinicians (top-10 accuracy 59.1% versus 33.6%, P = 0.04). Comparing the two assisted study arms, the differential diagnosis quality score was higher for clinicians assisted by AMIE (top-10 accuracy 51.7%) compared with clinicians without its assistance (36.1%; McNemar’s test: 45.7, P < 0.01) and clinicians with search (44.4%; McNemar’s test: 4.75, P = 0.03). Further, clinicians assisted by AMIE arrived at more comprehensive differential lists than those without assistance from AMIE. Our study suggests that AMIE has potential to improve clinicians’ diagnostic reasoning and accuracy in challenging cases, meriting further real-world evaluation for its ability to empower physicians and widen patients’ access to specialist-level expertise.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Previous health-related benchmarks graded short responses, extracted fixed entities from responses, or used weakly correlated natural language generation metrics (Jain et al., 2021; Fleming et al., 2024; McDuff et al., 2025).”
From HealthBench: Evaluating Large Language Models Towards Improved Human Health (2025) · cites this paper as McDuff et al., 2025
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The Measurement of Observer Agreement for Categorical Data
Landis, J. R., & Koch, G. G. (1977) · Biometrics · doi:10.2307/2529310 · Cited by 81,148
MIMIC-III, a freely accessible critical care database
Johnson, A. E. W., Pollard, T. J., Shen, L., Lehman, L.-W. H., Feng, M., Ghassemi, M., Moody, B., Szolovits, P., Anthony Celi, L., & Mark, R. G. (2016) · Scientific Data · doi:10.1038/sdata.2016.35 · Cited by 8,141
Dissecting racial bias in an algorithm used to manage the health of populations
Obermeyer, Z., Powers, B., Vogeli, C., & Mullainathan, S. (2019) · Science · doi:10.1126/science.aax2342 · Cited by 7,137 · cited 1×
“Deep learning tools have shown considerable promise in many areas of medicine, but are overwhelmingly used as assistive rather than autonomous tools 24 , given the safety-critical nature of medical practice and the many issues of robustness 25 and fairness 26–28 seen in deployment.”
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Self-citationLarge Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Self-citationLlama 2: Open Foundation and Fine-Tuned Chat Models
Touvron, H., Martin, L., Stone, K., Albert, P., Almahairi, A., Babaei, Y., Bashlykov, N., Batra, S., Bhargava, P., Bhosale, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2307.09288 · Cited by 2,604
Reasoning Foundations of Medical Diagnosis
Ledley, R. S., & Lusted, L. B. (1959) · Science · doi:10.1126/science.130.3366.9 · Cited by 998
LLaVA-Med: Training a Large Language-and-Vision Assistant for Biomedicine in One Day
Li, C., Wong, C., Zhang, S., Usuyama, N., Liu, H., Yang, J., Naumann, T., Poon, H., & Gao, J. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-1240 · Cited by 986
Seyyed-Kalantari, L., Zhang, H., McDermott, M. B. A., Chen, I. Y., & Ghassemi, M. (2021) · Nature Medicine · doi:10.1038/s41591-021-01595-0 · Cited by 928
A deep learning system for differential diagnosis of skin diseases
Liu, Y., Jain, A., Eng, C., Way, D. H., Lee, K., Bui, P., Kanada, K., de Oliveira Marinho, G., Gallegos, J., Gabriele, S., et al. (2020) · Nature Medicine · doi:10.1038/s41591-020-0842-3 · Cited by 853
Self-citation
Research works printed but not linked: 2
- Hong, J., Levine, S. & Dragan, A. Zero-shot goal-directed dialogue via RL on imagined conversations. In Proc. Foundation Models for Decision Making Workshop at NeurIPS 2023 (eds Yang, S. et al.) 77 (NeurIPS, 2023).
- Umapathi, L. K., Pal, A. & Sankarasubbu, M. Med-HALT: medical domain hallucination test for large language models. In Proc. 27th Conference on Computational Natural Language Learning (CoNLL) (eds Jiang, J. et al.) 314–334 (Association for Computational Linguistics, 2023).
Cited by
Sorted by citations
Items 101–200 of 378
Quo Vadis, AI-Empowered Doctor?
Takahashi, G., von Liechti, L., & Tarshizi, E. (2025) · JMIR Medical Education · doi:10.2196/70079 · Cited by 4
Tekchandani, N., Mukherjee, A., Poonthottam, N., & Boussios, S. (2025) · Cureus · doi:10.7759/cureus.92089 · Cited by 4
Artificial intelligence in forensic psychiatry: potential applications and key considerations
Blott, H., Hind, E., Brown, C., & Forrester, A. (2025) · Journal of Forensic and Legal Medicine · doi:10.1016/j.jflm.2025.103016 · Cited by 4
Chu, Y.-C., Chen, Y., Hsu, C., Kuo, C.-T., Cheng, Y., Lin, K., & Liao, W. (2025) · Digital Health · doi:10.1177/20552076251395449 · Cited by 4
Self-citationYum, J.-E. I., Naqvi, S. A. A., Zhou, B., & Riaz, I. B. (2025) · JCO Clinical Cancer Informatics · doi:10.1200/cci-25-00134 · Cited by 4
Wen, R., Assalif, A., Lee, A. S.-H., Kamadod, R., Behdinan, A., Carshon-Marsh, R., Meh, C., Ng, T. K. S., Brown, P., Jha, P. N., et al. (2025) · BMC Medicine · doi:10.1186/s12916-025-04584-z · Cited by 4
Large language models in neuropsychology: Emerging applications and ethical considerations
Kronenberger, O. R., Gottlieb, M. C., & Cullum, C. M. (2025) · The Clinical Neuropsychologist · doi:10.1080/13854046.2025.2604094 · Cited by 4
Brivá-Iglesias, V., & O’Brien, S. (2026) · International Journal of Human-Computer Interaction · doi:10.1080/10447318.2026.2622588 · Cited by 4
A federated graph learning method to realize multi-party collaboration for molecular discovery
Zhang, L., Zhang, J., Huang, R., Wang, Y., Liu, L., Zhang, Y., Chen, K., Jiang, J., & Wu, Y. (2026) · Nature Machine Intelligence · doi:10.1038/s42256-026-01184-1 · Cited by 4
Mustafa, M., Shahnawaz, A., Ammara, U., Abrar, M., Ahtisham, B., Qureshi, F. U., Shahin, M. A., & Ahmed, B. (2026) · Proceedings of the ACM on Interactive Mobile Wearable and Ubiquitous Technologies · doi:10.1145/3790115 · Cited by 4
Artificial intelligence in orthopedics: current applications, challenges, and future directions
Kim, S. Y., Choi, B. S., Han, H., & Ro, D. H. (2026) · Knee Surgery and Related Research · doi:10.1186/s43019-026-00317-5 · Cited by 4
Schramm, S., Guellec, B. L., Topka, M., Svec, M., Backhaus, P., Eisenkolb, V. M., Riedel, E. O., Beyrle, M., Platzek, P., Ramschütz, C., et al. (2026) · Radiology · doi:10.1148/radiol.253477 · Cited by 4
TeF-SAM: Prototype memory for medical lesion segmentation with text-free inference
Liang, J., Liu, X., Zang, Z., Wang, X., Qi, Y., & Li, X. (2026) · Computerized Medical Imaging and Graphics · doi:10.1016/j.compmedimag.2026.102816 · Cited by 4
Vashisht, P., Lodha, A., Maddipatla, M., Yao, Z., Mitra, A., Yang, Z., Kwon, S., Wang, J., & Yu, H. (2024) · Clinical Natural Language Processing Workshop (ClinicalNLP) · doi:10.18653/v1/2024.clinicalnlp-1.50 · Cited by 4
Promises and challenges of artificial intelligence in haematological diagnostics
Eckardt, J., & Middeke, J. M. (2025) · British Journal of Haematology · doi:10.1111/bjh.70055 · Cited by 4
AI vs Human Performance in Conversational Hospital-Based Neurological DiagnosisPreprint
Sorka, M., Gorenshtein, A., Abramovitch, H., Soontrapa, P., Shelly, S., & Aran, D. (2025) · medRxiv · doi:10.1101/2025.08.13.25333529 · Cited by 4
DeVisE: Behavioral Testing of Medical Large Language ModelsPreprint
Tagliabue, C. Z., Boll, H. O., Erdem, A., Erdem, E., & Calixto, I. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2506.15339 · Cited by 4
The Effect of LLM Assistance on Diagnostic Accuracy: A Systematic Review and Meta-AnalysisPreprint
Tretow, I., Ergon, E., Schwebel, M., Treffers, T., Welpe, I. M., & Feuerriegel, S. (2025) · medRxiv · doi:10.64898/2025.12.11.25341476 · Cited by 4
Towards Conversational Medical AI with Eyes, Ears and a VoicePreprint
Shah, M., Gusdorf, J., Palepu, A. K., Park, C., O’Sullivan, J. W., Ravi, V., Strother, T., Dubov, P., Rysbek, A., Fukuzawa, T., et al. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2605.09272 · Cited by 4
Self-citationA Generative AI-Based Virtual Physician Assistant
Rutledge, G. W., & Sivura, A. (2024) · Proceedings of the AAAI Symposium Series · doi:10.1609/aaaiss.v3i1.31182 · Cited by 3
Sallam, M., Beaini, C., Mijwil, M. M., & Sallam, M. (2025) · Journal of Studies in Medical Sciences · doi:10.20849/jsms.v1i1.1515 · Cited by 3
Performance of ChatGPT on optometry and vision science exam questions
Yoshioka, N., Honson, V., Mani, R., Oberstein, S. L., Watt, K., & Maseedupally, V. (2025) · Ophthalmic and Physiological Optics · doi:10.1111/opo.13544 · Cited by 3
Wang, M., Sushil, M., Williams, C. Y. K., Miao, B. Y., Kim, S., Masharani, U. B., Ku, G., Hsiao, V. C., Shah, A., Koliwad, S. K., et al. (2025) · Clinical Diabetes · doi:10.2337/cd25-0015 · Cited by 3
Advancing rheumatic disease care through generative artificial intelligence
Mahajan, A., Bates, D. W., Liao, K. P., & Sparks, J. A. (2025) · Nature Reviews Rheumatology · doi:10.1038/s41584-025-01310-0 · Cited by 3
He, Y., Wang, Y., Lai, L., Liu, N., Hong, Y., Chen, P., & Zhang, Z. (2025) · Scientific Reports · doi:10.1038/s41598-025-20210-7 · Cited by 3
Xu, Y., Prentice, C., Rueda, S. T., Meczner, A., Multmeier, J., Wickham, A. P., Kelly, L., Klepchukova, A., Stsefanovich, H., & Zhaunova, L. (2026) · npj Digital Medicine · doi:10.1038/s41746-025-02332-4 · Cited by 3
sLLM: Accelerating LLM Inference using Semantic Load Balancing with Shared Memory Data Structures
Lin, J., Zhang, S. Q., & Leon‐Garcia, A. (2024) · International Symposium on Quality Electronic Design (ISQED) · doi:10.1109/isqed60706.2024.10528703 · Cited by 3
Tinajero, C. A. C. (2025) · European Journal of Pediatric Surgery · doi:10.1055/a-2722-3871 · Cited by 3
Mingole, B., Majumdar, A., Choudhury, F. A., Kraschnewski, J. L., Sundar, S. S., & Yadav, A. (2026) · ACM Conference on Fairness, Accountability, and Transparency (FAccT) · doi:10.1145/3805689.3812315 · Cited by 3
Shi, P., Li, J., Yang, Z., Cao, Y., Ju, L., Bao, H., Xu, H., Fan, Y., Ren, T., Xiao, Y., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02942-6 · Cited by 3
Boceck, D., Laugwitz, L., Sturm, M., Bezdan, D., Gschwind, A., Haack, T. B., & Ossowski, S. (2026) · npj Genomic Medicine · doi:10.1038/s41525-026-00611-x · Cited by 3
Штучний інтелект у цифровій трансформації бізнесу та маркетингу
Havryliuk, O., & Ponomarenko, I. (2025) · Проблеми сучасних трансформацій Серія економіка та управління · doi:10.54929/2786-5738-2025-20-04-03 · Cited by 3
Salim, M. S., Fu, L., Ramakrishnan, A. A., Yao, Z., & Yu, H. Q. (2025) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2025.findings-emnlp.350 · Cited by 3
Artificial Intelligence Applications in Oral and Maxillofacial Medicine
Uribe, S. E. (2025) · Springer eBooks · doi:10.1007/978-3-031-84047-0_3 · Cited by 3
L’IA et la gestion de la sécurité: enjeux et questions clés
Marsden, E., & Steyer, V. (2025) · doi:10.57071/iae289 · Cited by 3
FindTheFlaws: Annotated Errors for Detecting Flawed Reasoning and Scalable Oversight ResearchPreprint
Recchia, G. L., Mangat, C. S., Li, I., & Krishnakumar, G. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2503.22989 · Cited by 3
Alignment, Exploration, and Novelty in Human-AI InteractionPreprint
Fundal, H. N., Rambøll, J. E., & Olsen, K. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2512.17117 · Cited by 3
Steinbuch, S., de Vos‐Hillebrand, L., O'Neill-Dee, C., Wu, I., Steinbuch, H., Kulcsár, Z., Ranjan, A., Verma, A., Landsberg, J., Dietrich, D., et al. (2026) · medRxiv · doi:10.64898/2026.01.23.26344723 · Cited by 3
LiveClin: A Live Clinical Benchmark without LeakagePreprint
Wang, X., Guo, S., Shen, Y., Chen, J., Wang, J., Gu, J., Zhang, P., Liu, L., & Wang, B. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2602.16747 · Cited by 3
Dinc, R., & Ardic, N. (2026) · JMIR Medical Informatics · doi:10.2196/92584 · Cited by 2
“…embolism, and aortic dissection), retrieves relevant clinical guidelines, checks recent imaging and laboratory results, identifies missing data (eg, D-dimer status and previous cardiac history), and constructs a structured assessment with confidence estimates and suggested next steps [20].”
Kułakowski, P., Alarcón, A., Škorić, T., Seoni, S., O’Sullivan, M., & O’Toole, J. M. (2025) · The Journal of Pediatrics · doi:10.1016/j.jpeds.2025.114708 · Cited by 2
Conversational AI in Medicine: Redefining Diagnostics with AMIE
Lin, Z., Du, Y., Yang, W., Qian, Y., & Li, J. J. (2025) · BIO Integration · doi:10.15212/bioi-2025-0085 · Cited by 2
Physician Perspectives on Large Language Models in Health Care: A Cross-Sectional Survey Study
Hong, H. J., Shah, N. H., Pfeffer, M. A., & Lehmann, L. S. (2025) · Applied Clinical Informatics · doi:10.1055/a-2735-0527 · Cited by 2
Cheema, M. N., Nazir, A., Harmanci, A. O., Harmanci, A. O., Cheema, Y., Masood, S., & Khokhar, F. A. (2026) · The Visual Computer · doi:10.1007/s00371-026-04385-2 · Cited by 2
Song, C. W., Baek, B. H., Kim, S. K., Yoon, W., Lee, Y. Y., Park, I., Park, J. H., Park, S. B., & Choi, I. W. (2026) · Journal of Clinical Medicine · doi:10.3390/jcm15041673 · Cited by 2
The physician as a catalyst: Reimagining medical education for an AI era
Patel, M. S., Dee, E. C., Toby, S., Ramos, M., & Celi, L. A. (2026) · Medical Teacher · doi:10.1080/0142159x.2026.2653205 · Cited by 2
Metzger, A., Patil, S., Sugarmann, L., Karabacak, M., & Margetis, K. D. (2026) · JMIR AI · doi:10.2196/81134 · Cited by 2
Structured reasoning failures compromise LLM interpretation of clinical oncology notes
Kenaston, M. W., Ayub, U., Parmar, M., Kumar, P., Anjum, M. U., Naqvi, S. A. A., Chaudhuri, A. A., Zakharia, Y., Heath, E. I., Bekaii-Saab, T. S., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-02951-5 · Cited by 2
Chu, Y.-C., Lin, K., Chen, Y., Hsu, C.-Y., Kuo, C.-T., Cheng, Y., & Liao, W. (2025) · World Congress on Medical Physics and Biomedical Engineering, September 7 - 12, 2009, Munich, Germany · doi:10.1007/978-3-031-86323-3_22 · Cited by 2
Self-citationArtificial Intelligence (AI) in Patient–Healthcare Relationships: Psychosocial Perspective
Saikia, M. J., & Borthakur, D. (2025) · IEEE Access · doi:10.1109/access.2025.3611818 · Cited by 2
Sesen, M. B., Yeung, J. A., & Asgari, E. (2026) · BMJ Digital Health & AI · doi:10.1101/2025.11.25.25341010 · Cited by 2
Shao, M., & Zhang, H. (2025) · npj Digital Medicine · doi:10.1038/s41746-025-02146-4 · Cited by 2
Li, X., Wu, X. T., Wang, Q., Zhu, Y., Zhang, L., Song, Y., Lv, B., Chen, J., Fan, W., Chai, G., et al. (2026) · ACS Sensors · doi:10.1021/acssensors.5c03495 · Cited by 2
Chen, A., & Lu, Y. (2026) · Journal of Management Information Systems · doi:10.1080/07421222.2025.2602395 · Cited by 2
AI on Trial: LLM-as-a-Judge for Private and Reliable Clinical Decision-Making
Khan, T. A., Rafiq, M., & Michalas, A. (2025) · Annual Computer Security Applications Conference Workshops (ACSAC Workshops) · doi:10.1109/acsacw69556.2025.00033 · Cited by 2
Xiong, X., Xiao, M., Liu, H., Jiang, C., Li, M., Song, Y., Zhou, J., & Xu, B. (2026) · BMC Medical Education · doi:10.1186/s12909-026-08951-z · Cited by 2
Tandon, U. (2026) · Frontiers in Digital Health · doi:10.3389/fdgth.2026.1772345 · Cited by 2
From Regression to Reasoning: Predicting M&A Announcement Returns With Large Language Models
Schreiter, M., Struve, A., & Uhle, M. (2026) · European Financial Management · doi:10.1111/eufm.70059 · Cited by 2
Serrano, J. D. A., Caño-Marín, E., & Sicilia, M. (2026) · Knowledge-Based Systems · doi:10.1016/j.knosys.2026.115882 · Cited by 2
Paging the algorithm: applying the Best Available Human principle to graduate medical education
Stamos, D. B., & Dharod, A. (2026) · Academic Medicine · doi:10.1093/acamed/wvag119 · Cited by 2
Generative Artificial Intelligence and Large Language Models in Clinical Oncology
Yu, Y., Zhao, Z., Wang, Z., Lin, R., Tan, Y., Chen, Y., Li, T., Baptista‐Hon, D. T., Zhang, X., Wu, C., et al. (2026) · MedComm · doi:10.1002/mco2.70833 · Cited by 2
A roadmap for medical large language models: a review of foundations, applications, and challenges
Sha, Y.-Y., Yu, L., Lin, Z.-H., Kaur, A., Lou, Y., Gornale, S. S., Zhang, T., Wong, L. S., Wang, Z., Yan, Y., et al. (2026) · Military Medical Research · doi:10.1016/j.mmr.2026.100050 · Cited by 3
Machine Learning and Human Expertise in the Balance: Generative AI in Healthcare Settings
Montalvo, F. L., Pavlov, K., Thai, P., Devkota, B., & Takahashi, B. (2024) · Proceedings of the International Symposium on Human Factors and Ergonomics in Health Care · doi:10.1177/2327857924131010 · Cited by 2
Klinisches Denken, ärztliche Kunst und Artificial Intelligence
Bassetti, S., Hirsch, M. C., & Battegay, E. J. (2024) · DMW - Deutsche Medizinische Wochenschrift · doi:10.1055/a-2201-5412 · Cited by 2
Probing Hidden States for Calibrated, Alignment-Resistant Predictions in LLMsPreprint
Berkowitz, J. S., Kivelson, S., Srinivasan, A., Gisladottir, U., Tsang, K. K., Cortina, J. M. A., Kuchi, A., Patock, J. R., Czarny, R., & Tatonetti, N. P. (2025) · medRxiv · doi:10.1101/2025.09.17.25336018 · Cited by 2
Second Opinion Matters: Towards Adaptive Clinical AI via the Consensus of Expert Model EnsemblePreprint
Kumthekar, A., Tilley, Z., Duong, H. K. L., Patel, B. M., Magnoli, M., Omar, A., Nasser, A., Gharpure, C. P., & Reztzov, Y. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.23075 · Cited by 2
Kim, S. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2512.10996 · Cited by 3
Jin, K. W., Abadi, Y. R., Chaudhary, P., Garrett, M. A., Huang, A. S., Montelongo, M., Nagpal, C., Shei, J., Weathers, J., Zhang, J. S., et al. (2026) · medRxiv · doi:10.64898/2026.02.03.26345402 · Cited by 2
The value of doubt: training LLMs to consider diagnostic uncertainty may improve clinical utility
Sui, M., Rosen, K. L., Heydari, K., Enichen, E. J., & Kvedar, J. C. (2026) · npj Digital Medicine · doi:10.1038/s41746-025-02307-5 · Cited by 2
CausalFlip: A Benchmark for LLM Causal Judgment Beyond Semantic MatchingPreprint
Wang, Y., Zhu, Y., & Li, J. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2602.20094 · Cited by 2
Qazi, I. A., Ali, A., Khawaja, A. U., Akhtar, M. J., Sheikh, A. Z., & Alizai, M. H. (2026) · medRxiv · doi:10.64898/2026.06.01.26354596 · Cited by 2
Towards a Science of Scaling Agent Systems
Kim, Y., Gu, K., Park, C., Park, C., Schmidgall, S., Heydari, A. A., Yan, Y., Zhang, Z., Zhuang, Y., Liu, Y., et al. (2025) · arXiv · doi:10.48550/arxiv.2512.08296 · Cited by 197
Self-citationKulkarni Kale, U., & Vemulapalli, G. (2025) · The Cancer Journal · doi:10.1097/ppo.0000000000000799 · Cited by 1
Geantă, M., Боата, А., Cucoş, B., & Cioroboiu, C. (2024) · Springer eBooks · doi:10.1007/978-981-97-4974-4_8 · Cited by 1
Computerized diagnostic decision support systems—Isabel Pro versus ChatGPT-4 part II
Bridges, J. M., Jiang, X., Ige, M., & Toyobo, O. (2025) · JAMIA Open · doi:10.1093/jamiaopen/ooaf048 · Cited by 1
Hunton, R. W., Potter, D., & Schuer, K. M. (2025) · The Journal of Physician Assistant Education · doi:10.1097/jpa.0000000000000690 · Cited by 1
Impact of LLM assistance on physician decision-making: a multi-country randomized controlled trial
Rounding, N., Arif, L. S., Berg, J., Cals, J., de Boer, D. P., de Bont, E. G. P. M., Dijksman, S., Findyartini, A., Fouarge, D. J. A. G., Fregin, M.-C., et al. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-03111-5 · Cited by 1
Krumsvik, R. J. (2025) · Nordic Journal of Digital Literacy · doi:10.18261/njdl.20.2.5 · Cited by 1
BioSage: Human-Agent Collaboration Platform for Cross-Disciplinary Knowledge Discovery and Synthesis
Klinefelter, Z. P., Erickson, I., Ganberg, G., Abele, N., Engberson, G., Penafiel, L., Kao, H.-T., Hiriyanna, A., Bautista, P., & Volkova, S. (2025) · Proceedings of the Human Factors and Ergonomics Society Annual Meeting · doi:10.1177/10711813251369365 · Cited by 1
New Frontiers in Human-Agent Team Modeling and Evaluation in the Era of Agentic AI
Bruni, S., Volkova, S., Cassani, L., Neville, K., & Cooke, N. J. (2025) · Proceedings of the Human Factors and Ergonomics Society Annual Meeting · doi:10.1177/10711813251369392 · Cited by 1
Expertise and Information Seeking in the Age of Generative AI: New Procedures, New Problematics
Lodoen, S., & Orchard, A. (2026) · IEEE Transactions on Technology and Society · doi:10.1109/tts.2026.3690975 · Cited by 1
Generative AI: A Disruptor to Health Professions Learner Assessment
Morjaria, L., Gandhi, B., Burns, L., & Sibbald, M. (2025) · Cureus · doi:10.7759/cureus.96034 · Cited by 1
Künstliche Intelligenz: Chancen und Grenzen
Clusmann, J., Schneider, C. V., Foersch, S., Truhn, D., & Kather, J. N. (2025) · Forum · doi:10.1007/s12312-025-01520-3 · Cited by 1
Winkel, A. F., Myrick, O., Smith, M., & Triola, M. M. (2025) · Clinical Obstetrics & Gynecology · doi:10.1097/grf.0000000000000982 · Cited by 1
Hierarchical agent reflection for aligning LLM reasoning with clinical diagnostic processes
Wang, X., Li, X., Zhao, D., Feng, K., Liang, L., Zhang, Z., Ding, K., Chen, H., Wan, B., & Zhang, Q. (2026) · Health Information Science and Systems · doi:10.1007/s13755-025-00410-1 · Cited by 1
Lu, J., Chiu, K. W.-H., Chan, C., Cheng, H.-M., Zhou, J., Justin Christopher, N. G., Tang, F. F. Y., Kan, W. K., Yu, P. L. H., & Seto, W. (2026) · European Journal of Radiology · doi:10.1016/j.ejrad.2026.112689 · Cited by 1
Practical Frameworks for Integrating Artificial Intelligence in Forensic Psychology
Rilen, S. (2026) · Journal of Forensic Psychology Research and Practice · doi:10.1080/24732850.2026.2630383 · Cited by 1
MedBLINK: Probing Basic Perception in Multimodal Language Models for Medicine
Bigverdi, M., Ikezogwo, W. O., Zhang, K., Jeong, H., Lu, M., Cho, S., Shapiro, L. G., & Krishna, R. (2025) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw69036.2025.00132 · Cited by 1
COMFORT: A Continual Fine-Tuning Framework for Foundation Models Targeted at Consumer Healthcare
Li, C., & Jha, N. (2026) · ACM Transactions on Embedded Computing Systems · doi:10.1145/3797955 · Cited by 1
Physicians’ expectations of the use of conversational agents in healthcare: a qualitative study
Wutz, M., Söling, S., & Köberlein-Neu, J. (2026) · BMC Health Services Research · doi:10.1186/s12913-026-14321-8 · Cited by 1
Limitations of Large Language Models in Clinical Diagnostic Reasoning
Tordjman, M., & Mei, X. (2026) · JAMA Network Open · doi:10.1001/jamanetworkopen.2026.4014 · Cited by 1
Four Aspirations for Evaluating AI-Infused Technologies: A Narrative Review
Morey, D. A., Jalaeian, M., Reynolds, M. E., McGeorge, N., Oldham, H. K., & Rayo, M. F. (2026) · Journal of Cognitive Engineering and Decision Making · doi:10.1177/15553434261443032 · Cited by 1
Assessment of frontier Large Language Models in sleep medicine
Patel, A., Contractor, H., Heninger, H., Vallamchetla, S. K., Li, P., Tao, C., & Cheung, J. (2026) · Frontiers in Digital Health · doi:10.3389/fdgth.2026.1769386 · Cited by 1
How can we prevent clinical deskilling when using AI?
Scott, I., van der Vegt, A. H., & Douglas, P. (2026) · BMJ Quality & Safety · doi:10.1136/bmjqs-2026-020130 · Cited by 1
Akazua, L., Zhou, J. J., Chen, F., Shafiabady, N., George, T., Holzinger, A., & Müller, H. (2026) · Machine Learning and Knowledge Extraction · doi:10.3390/make8060144 · Cited by 1
Basu, S., Patel, S., Sheth, P., Arevalo, B., Schifberg, J., Morgan, J., & Batniji, R. (2026) · BMC Medical Informatics and Decision Making · doi:10.1186/s12911-026-03763-z · Cited by 1
Self-citationYan, B., Zhang, R., Chen, L., Song, X. Z., Cao, Z., & Li, Y. (2026) · Journal of Medical Internet Research · doi:10.2196/96304 · Cited by 1
Rojansky, R. B., Keyes, T., & Oak, J. S. (2026) · Cytometry Part B Clinical Cytometry · doi:10.1002/cyto.b.70051 · Cited by 2
Evaluating the First CE ‐Marked LLM ‐Based Chatbot for Evidence‐Based Neurology
Kirschner, P., Epping, P. Z., Meuth, S. G., Pawlitzki, M., & Masanneck, L. (2026) · European Journal of Neurology · doi:10.1111/ene.70736 · Cited by 1
Metadata
- Authors
- McDuff, D., Schaekermann, M., Tu, T., Palepu, A., Wang, A., Garrison, J., Singhal, K., Sharma, Y., Azizi, S., Kulkarni, K., Hou, L., Cheng, Y., Liu, Y., Mahdavi, S. S., Prakash, S., Pathak, A., Semturs, C., Patel, S., Webster, D. R., Dominowska, E., Gottweis, J., Barral, J., Chou, K., Corrado, G. S., Matias, Y., Sunshine, J., Karthikesalingam, A., & Natarajan, V.
- Affiliations
- Google (United States) (US)
- Google (Switzerland) (CH)
- Google (United Kingdom) (GB)
- Corresponding author
- McDuff, Daniel
- Schaekermann, Mike
- Karthikesalingam, Alan
- Natarajan, Vivek
- ORCID
- McDuff, Daniel
- Schaekermann, Mike
- Tu, Tao
- Palepu, Anil
- Wang, Amy
- Singhal, Karan
- Azizi, Shekoofeh
- Cheng, Yong
- Liu, Yun
- Mahdavi, S. Sara
- Prakash, Sushant
- Pathak, Anupam
- Semturs, Christopher
- Patel, Shwetak
- Webster, Dale R.
- Dominowska, Ewa
- Gottweis, Juraj
- Barral, Joelle
- Chou, Katherine
- Corrado, Greg S.
- Matias, Yossi
- Sunshine, Jake
- Karthikesalingam, Alan
- Natarajan, Vivek
- Venue
- Nature
- Published
- 2025-04-09
- Volume
- 642
- Issue
- 8067
- Pages
- 451-457
- ISSN
- 0028-0836 (ISSN-L)
- 1476-4687
- PMC
- PMC12158753
- OpenAlex
- W4409283616
- Cited by
- 311
- References
- 34
- Citations by year
- 2026: 172 · 2025: 108
- FWCI
- 67.40
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Locations
- Nature (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, other-oa)
- arXiv (Cornell University)
- Funders
- Massachusetts Medical Society
- DeepMind
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Keywords
- differential diagnosis, large language models, diagnostic reasoning, clinical decision support, clinician performance, AI-assisted diagnosis, medical knowledge retrieval
- MeSH terms
- Case Reports as Topic, Large Language Models, Artificial Intelligence, Diagnosis, Differential, Humans, Language
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
