

The DOI matches its Crossref record; 37 of the 38 references it cites were found in a registry or an index, and 1 are not checked yet.
Towards accurate differential diagnosis with large language models
Open accessAbstract
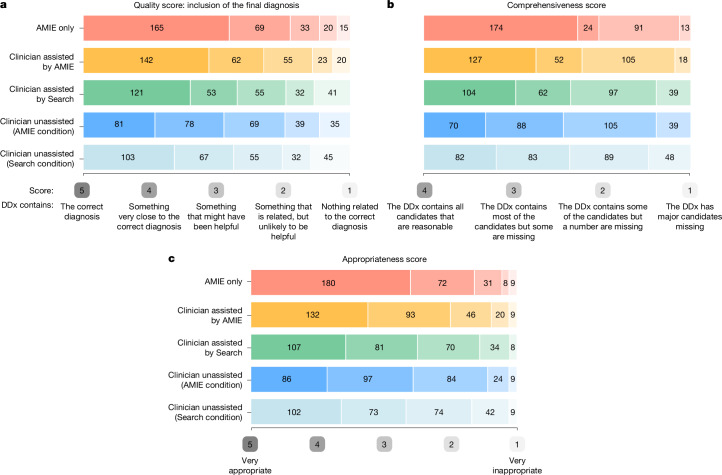
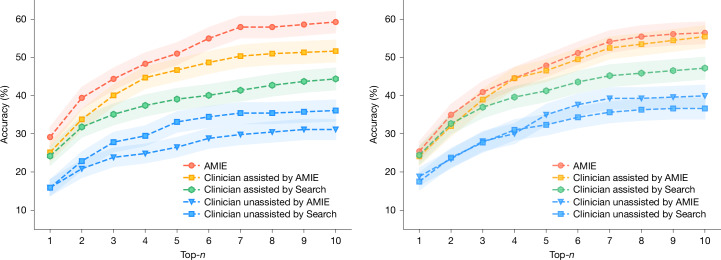
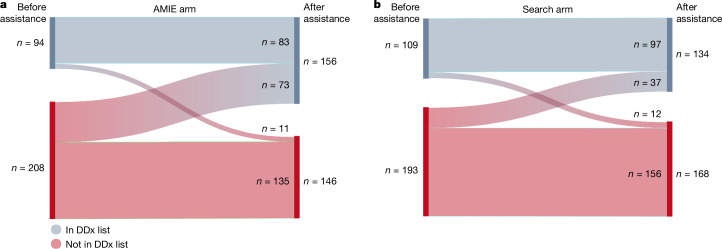
A comprehensive differential diagnosis is a cornerstone of medical care that is often reached through an iterative process of interpretation that combines clinical history, physical examination, investigations and procedures. Interactive interfaces powered by large language models present new opportunities to assist and automate aspects of this process 1 . Here we introduce the Articulate Medical Intelligence Explorer (AMIE), a large language model that is optimized for diagnostic reasoning, and evaluate its ability to generate a differential diagnosis alone or as an aid to clinicians. Twenty clinicians evaluated 302 challenging, real-world medical cases sourced from published case reports. Each case report was read by two clinicians, who were randomized to one of two assistive conditions: assistance from search engines and standard medical resources; or assistance from AMIE in addition to these tools. All clinicians provided a baseline, unassisted differential diagnosis prior to using the respective assistive tools. AMIE exhibited standalone performance that exceeded that of unassisted clinicians (top-10 accuracy 59.1% versus 33.6%, P = 0.04). Comparing the two assisted study arms, the differential diagnosis quality score was higher for clinicians assisted by AMIE (top-10 accuracy 51.7%) compared with clinicians without its assistance (36.1%; McNemar’s test: 45.7, P < 0.01) and clinicians with search (44.4%; McNemar’s test: 4.75, P = 0.03). Further, clinicians assisted by AMIE arrived at more comprehensive differential lists than those without assistance from AMIE. Our study suggests that AMIE has potential to improve clinicians’ diagnostic reasoning and accuracy in challenging cases, meriting further real-world evaluation for its ability to empower physicians and widen patients’ access to specialist-level expertise.
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“Previous health-related benchmarks graded short responses, extracted fixed entities from responses, or used weakly correlated natural language generation metrics (Jain et al., 2021; Fleming et al., 2024; McDuff et al., 2025).”
From HealthBench: Evaluating Large Language Models Towards Improved Human Health (2025) · cites this paper as McDuff et al., 2025
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
The Measurement of Observer Agreement for Categorical Data
Landis, J. R., & Koch, G. G. (1977) · Biometrics · doi:10.2307/2529310 · Cited by 81,148
MIMIC-III, a freely accessible critical care database
Johnson, A. E. W., Pollard, T. J., Shen, L., Lehman, L.-W. H., Feng, M., Ghassemi, M., Moody, B., Szolovits, P., Anthony Celi, L., & Mark, R. G. (2016) · Scientific Data · doi:10.1038/sdata.2016.35 · Cited by 8,141
Dissecting racial bias in an algorithm used to manage the health of populations
Obermeyer, Z., Powers, B., Vogeli, C., & Mullainathan, S. (2019) · Science · doi:10.1126/science.aax2342 · Cited by 7,137 · cited 1×
“Deep learning tools have shown considerable promise in many areas of medicine, but are overwhelmingly used as assistive rather than autonomous tools 24 , given the safety-critical nature of medical practice and the many issues of robustness 25 and fairness 26–28 seen in deployment.”
Large language models encode clinical knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2023) · Nature · doi:10.1038/s41586-023-06291-2 · Cited by 4,083
Self-citationLarge Language Models Encode Clinical Knowledge
Singhal, K., Azizi, S., Tu, T., Mahdavi, S. S., Wei, J., Chung, H. W., Scales, N., Tanwani, A., Cole-Lewis, H., Pfohl, S., et al. (2022) · arXiv · doi:10.48550/arxiv.2212.13138 · Cited by 4,083
Self-citationLlama 2: Open Foundation and Fine-Tuned Chat Models
Touvron, H., Martin, L., Stone, K., Albert, P., Almahairi, A., Babaei, Y., Bashlykov, N., Batra, S., Bhargava, P., Bhosale, S., et al. (2023) · arXiv · doi:10.48550/arxiv.2307.09288 · Cited by 2,604
Reasoning Foundations of Medical Diagnosis
Ledley, R. S., & Lusted, L. B. (1959) · Science · doi:10.1126/science.130.3366.9 · Cited by 998
LLaVA-Med: Training a Large Language-and-Vision Assistant for Biomedicine in One Day
Li, C., Wong, C., Zhang, S., Usuyama, N., Liu, H., Yang, J., Naumann, T., Poon, H., & Gao, J. (2023) · Advances in Neural Information Processing Systems 36 · doi:10.52202/075280-1240 · Cited by 986
Seyyed-Kalantari, L., Zhang, H., McDermott, M. B. A., Chen, I. Y., & Ghassemi, M. (2021) · Nature Medicine · doi:10.1038/s41591-021-01595-0 · Cited by 928
A deep learning system for differential diagnosis of skin diseases
Liu, Y., Jain, A., Eng, C., Way, D. H., Lee, K., Bui, P., Kanada, K., de Oliveira Marinho, G., Gallegos, J., Gabriele, S., et al. (2020) · Nature Medicine · doi:10.1038/s41591-020-0842-3 · Cited by 853
Self-citation
Research works printed but not linked: 2
- Hong, J., Levine, S. & Dragan, A. Zero-shot goal-directed dialogue via RL on imagined conversations. In Proc. Foundation Models for Decision Making Workshop at NeurIPS 2023 (eds Yang, S. et al.) 77 (NeurIPS, 2023).
- Umapathi, L. K., Pal, A. & Sankarasubbu, M. Med-HALT: medical domain hallucination test for large language models. In Proc. 27th Conference on Computational Natural Language Learning (CoNLL) (eds Jiang, J. et al.) 314–334 (Association for Computational Linguistics, 2023).
Cited by
Sorted by citations
Items 201–300 of 378
Samsel, K., Dharma, C., Rezaie, A. H. H. M., Bahakim, A., Ravikumar, K., Bhat, V., Kamaleddin, M. A., & Abad, Z. S. H. (2026) · Artificial Intelligence in Medicine · doi:10.1016/j.artmed.2026.103516 · Cited by 1
Toma, M., & YUSUPOV, D. (2026) · Bioengineering · doi:10.3390/bioengineering13091034 · Cited by 1
The Long road to AI–physician partnership starts with learners: a map for AI in medical education
Patel, N., Kumar, A. D., Chi, J., Keet, K., Kugler, J., Hom, J., & Hosamani, P. (2026) · BMJ Digital Health & AI · doi:10.1136/bmjdh-2026-000056 · Cited by 1
Li, J., Xiao, L., Qu, X., Du, L., Gong, T., Yu, Y., Li, Y., 谢鹏飞, Chu, G., Li, H., et al. (2026) · Radiology · doi:10.1148/radiol.253579 · Cited by 1
BAYDİLİ, I., Taşçı, B., Taşçı, G., Doğan, Ş., & Tuncer, T. (2026) · Bioengineering · doi:10.3390/bioengineering13101175 · Cited by 1
Understanding human detection of algorithmic bias through drift-diffusion modeling
Overbye-Thompson, H. E., Hamilton, K. A., & Fisher, J. (2026) · Computers in Human Behavior · doi:10.1016/j.chb.2026.109209 · Cited by 1
LLM-Prompting Driven AutoML: From Sleep Disorder—Classification to Beyond
Zhao, Y., Pang, J., Zhu, X., & Shao, W. (2025) · Transactions on Artificial Intelligence · doi:10.53941/tai.2025.100004 · Cited by 1
Jang, W. S., Sultana, S., Yao, Z., Tran, H., Yang, Z., Kwon, S., & Yu, H. (2026) · JMIR AI · doi:10.2196/75561 · Cited by 1
Harnessing Internet Search Data as a Potential Tool for Medical DiagnosisPreprint
Downing, G. J., Tramontozzi, L. M., Garcia, J., & Villanueva, E. (2024) · medRxiv · doi:10.1101/2024.05.03.24305695 · Cited by 1
Is Strong Artificial Intelligence Skepticism Justified or Counterproductive?
Hänscheid, T., & Grobusch, M. P. (2024) · Clinical Infectious Diseases · doi:10.1093/cid/ciae443 · Cited by 1
Zhao, Y. (2025) · Research Square · doi:10.21203/rs.3.rs-6124845/v1 · Cited by 1
Artificial intelligence and safety management: an overview of key challenges
Marsden, E., & Steyer, V. (2025) · doi:10.57071/iae290 · Cited by 1
How Large Language Models Can Affect Clinical Reasoning: A Randomized Clinical TrialPreprint
Levels, M., Levels, M., Rounding, Dijksman, Fouarge, D. J. A. G., Fregin, Steens, Velasco, Boer, D., Bont, D., et al. (2025) · medRxiv · doi:10.64898/2025.12.17.25342338 · Cited by 1
Practical Considerations For the Deployment of Clinical NLP Systems
Lehman, E. (2024) · DSpace@MIT (Massachusetts Institute of Technology) · Cited by 1
Shimelash, N., Rutunda, S., Menon, V., Emmanuel-Fabula, M., Uwimbabazi, A., Rugege, C., Nshimiyimana, C., Rwema, I. S., Kandekwe, M., Berhe, D. F., et al. (2026) · medRxiv · doi:10.64898/2026.02.16.26346409 · Cited by 1
Hassoon, A., Peng, X., Irimia, R. M., Lianjie, A., Leo, H., Bandeira, A., Woo, H., Dredze, M., Abdulnour, R.-E. E., McDonald, K. M., et al. (2026) · medRxiv · doi:10.64898/2026.02.22.26346832 · Cited by 1
A Self-Evolving Agent for Longitudinal Personal Health ManagementPreprint
Li, H., Deng, J., Jin, T., Han, J., Wang, Y., Wang, Z., Sun, J., Si, Q., Gong, W., 庄吓海, et al. (2026) · Research Square · doi:10.21203/rs.3.rs-11605391/v1 · Cited by 1
Large language models enable consensus-level interpretation in metagenomic diagnosticsPreprint
Steinig, E. J., Krysiak, M., Deo, K., Duncan, A., Prestedge, J., Barr, J. J., Moselen, J. M., Khan, S. F., Fernando, J. A., Savic, I., et al. (2026) · medRxiv · doi:10.64898/2026.07.29.26358751 · Cited by 1
Human-AI Collaboration in Radiology: The Blind Spots
Kim, S. H., Adams, L. C., Wiestler, B., & Hedderich, D. M. (2026) · Radiology Artificial Intelligence · doi:10.1148/ryai.260325 · Cited by 1
The widening evaluation gap in medical large language model research 2023 to 2026Preprint
Tareaf, R. B., Al-Rajab, M., & Loucif, S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2609.11770 · Cited by 1
LiveMedBench: A Contamination-Limited Medical Benchmark for LLMs with Automated Rubric Evaluation
Yan, Z., Song, D., Fang, Z., Ji, Y., Li, X., Li, Q., & Sun, L. (2026) · Proceedings of the 32nd ACM SIGKDD Conference on Knowledge Discovery and Data Mining V.2 · doi:10.1145/3770855.3817579
Me-LLaMA: Medical Foundation Large Language Models for Comprehensive Text Analysis and BeyondPreprint
Xie, Q., Chen, Q., Chen, A., Cheng, P., Hu, Y., Lin, F., Peng, X., Huang, J., Zhang, J., Keloth, V. K., et al. (2024) · SSRN Electronic Journal · doi:10.2139/ssrn.4943761
Generative Artificial Intelligence in Medicine: A Mixed Methods Survey of UK General PractitionersPreprint
Blease, C. R., Kharko, A., Locher, C., Torous, J. B., Roche, A. S., Hägglund, M., Gaab, J., McMillan, B., Sundemo, D. S., & Mandl, K. D. (2024) · Research Square · doi:10.21203/rs.3.rs-5454088/v1
The role of large language models in medical genetics
Merdler-Rabinowicz, R., Omar, M., Ganesh, J., Morava, É., Nadkarni, G. N., & Klang, E. (2025) · Molecular Genetics and Metabolism · doi:10.1016/j.ymgme.2025.109098
Beyond Scaling Laws: Towards Scientific Reasoning-Driven LLM ArchitecturesPreprint
Chen, F. (2025) · Preprints.org · doi:10.20944/preprints202504.2088.v1
El futuro es hoy: Integrando la inteligencia artificial en la práctica médica
Pedro Errázuriz, G. (2025) · Revista Chilena de Reumatología/Revista chilena de reumatología · doi:10.58450/rcr.v41i2.141
Hunton, R. W., & Potter, D. J. (2025) · doi:10.2196/preprints.80150
Context is King: From Prompt Engineering to Context Engineering in Healthcare AIPreprint
Shankar, R. (2025) · SSRN Electronic Journal · doi:10.2139/ssrn.5365971
Zero-Shot Evaluation of Kimi K2 on Pediatric Clinical CasesPreprint
Mondillo, G., Masino, M., Colosimo, S., Perrotta, A., Frattolillo, V., & Abbate, F. G. (2025) · medRxiv · doi:10.1101/2025.07.29.25332368
Foundations of Clinical Informatics for Generalists
Patel, S. Y., Mezoff, E. A., & Rust, L. (2025) · Medical Clinics of North America · doi:10.1016/j.mcna.2025.06.003
Self-citationDifferential diagnosis making with large language models and probabilistic logic program
Galitsky, B. A. (2025) · Elsevier eBooks · doi:10.1016/b978-0-443-30046-2.00010-7
Å være lege med hjelp fra kunstig intelligens
Benestad, H. B. (2025) · Tidsskrift for Den norske legeforening · doi:10.4045/tidsskr.25.0427
Yano, Y., Kakizaki, H., Nagasu, H., Kishi, S., Koshida, T., Nihei, Y., Hirano, A., Nangaku, M., Mori, H., Naito, T., et al. (2025) · medRxiv · doi:10.1101/2025.09.04.25334460
Emerging Role of AI in Cardiovascular Medicine
Kodera, S., & Takeda, N. (2025) · Journal of Coronary Artery Disease · doi:10.7793/jcad.31.007
Contemplating the Potential of My Own Obsolescence
El‐Samad, H. (2025) · GEN Biotechnology · doi:10.1177/27681572251363643
Fragments to Facts: Partial-Information Fragment Inference from LLMsPreprint
Rosenblatt, L., Han, B., Wolfe, R., & Howe, B. (2025) · arXiv (Cornell University) · doi:10.48550/arxiv.2505.13819
Meißner, T., Konrad, K., Kerth, J.-L., Reinhart, L., Henn, A. T., Bell, L., Bischops, A., & Hagemeister, M. (2025) · Springer eBooks · doi:10.1007/978-3-658-48573-3_15
Transforming LLMs into Domain Experts: A Case Study of Train Trajectory Evaluation
Yu, Y., Sun, P., Zhao, H., Wang, Q., & Liu, C. (2025) · IEEE International Conference on Intelligent Rail Transportation (ICIRT) · doi:10.1109/icirt66379.2025.11216746
Zusatzweiterbildung „Digitale Medizin“, ergibt das Sinn?
Fuchtmann, J., & Wilhelm, D. (2025) · Zentralblatt für Chirurgie - Zeitschrift für Allgemeine Viszeral- Thorax- und Gefäßchirurgie · doi:10.1055/a-2690-4214
Biased decisions of Large Language Models (LLM): Computer control agents and the decoy effect
Bösch, K. (2026) · Journal of Behavioral and Experimental Economics · doi:10.1016/j.socec.2026.102641
Comparing the Neuropsychology Knowledge Base of Publicly Available Large Language Models
Kronenberger, O. R., Hutnyan, M., Kaser, A. N., Bullinger, L., Lacritz, L. H., & Cullum, C. M. (2025) · Archives of Clinical Neuropsychology · doi:10.1093/arclin/acaf112
Yan, B.-C., Zhang, R., Fan, Y., Li, Y., Chen, L., Song, X., Tang, Y., Tu, Y., Cao, Z., Shen, L., et al. (2025) · Research Square · doi:10.21203/rs.3.rs-7998391/v1
Transforming Healthcare: Sustainable and Inclusive Outcomes through AI and Deep Learning
Gokhale, P., & Pande, M. (2025) · International Conference on Sustainable Technologies for Humanity and Smart World (HSWTech) · doi:10.1109/hswtech64936.2025.11277427
Confidence and information seeking in medical decision making
Aiyer, S. (2025) · Oxford University Research Archive (ORA) (University of Oxford) · doi:10.5287/ora-r8robxmvx
Sediva, H. (2024) · WestminsterResearch (University of Westminster) · doi:10.34737/ww762
Healthcare Agents: Large Language Models in Health Prediction and Decision-Making
Kim, Y. (2025) · DSpace@MIT (Massachusetts Institute of Technology)
Inteligencia artificial y neurotecnologías
Castro Campolongo, C. A. (2024) · Repositorio Institucional UCA (Pontificia Universidad Católica Argentina)
Ahmed, M., & Abbas, G. (2025) · IEEE International Conference on Smart Communities: Improving Quality of Life using AI, Robotics and IoT (HONET) · doi:10.1109/honet67928.2025.11318509
RiemannInfer: improving transformer inference through Riemannian geometry
Mao, R., Zhang, Z., Yang, M., Xie, H., Wei, S., & Hu, C. (2026) · Scientific Reports · doi:10.1038/s41598-026-37328-x
Multimodal Models of Time Series and Text
Merrill, M. A. (2024) · ResearchWorks at the University of Washington (University of Washington)
Rahdari, B., Shaikh, S., Chen, J. H., Gerstenberg, T., & Raj, S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2601.22338
Biological risk and the AI capability shift
Turner, S. D. (2026) · doi:10.59350/zp9qy-3gg73
Figueroa, C. A., Garikipati, K., Yang, H., & Capecelatro, J. (2026) · Annual Review of Biomedical Engineering · doi:10.1146/annurev-bioeng-081325-031501
Next Generation Herzchirurgie: Prompt Engineering
Safarov, R., Wippermann, J., & Wacker, M. (2026) · Zeitschrift für Herz- Thorax- und Gefäßchirurgie · doi:10.1007/s00398-026-00763-z
Yang, J., Yang, S., Shao, Z., Chen, T., Shen, H., Zhou, P., Xia, B., Lei, X., Wang, L., Xue, D., et al. (2026) · Burns & Trauma · doi:10.1093/burnst/tkag026
DeVisE: Towards the Behavioral Testing of Medical Large Language Models
Tagliabue, C. Z., Boll, H. O., Erdem, A., Erdem, E., & Calixto, I. (2026) · Findings of the Association for Computational Linguistics: EACL · doi:10.18653/v1/2026.findings-eacl.338
Huang, J., Nezafati, K., Chi, Z., Rong, R., Treager, C., Wanyan, T., Xu, Y., Zhan, X., Leavey, P. J., Xiao, G., et al. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2603.20435
Taraf, N. H., Camalan, B. V., Doluoğlu, S., Arslan, E., Ural, A., Demiroğlu, G., Elhan, A. E., & Özlügedik, S. (2026) · European Journal of Rhinology and Allergy · doi:10.65396/ejra.1846059
Lu, X., Wang, X., Liu, D., Zhang, Z., Zhang, Y., Zhang, T., Lü, D., Kuang, S., Lai, C., Piao, F., et al. (2026) · PLOS Digital Health · doi:10.1371/journal.pdig.0001317
Okada, N., Nakanishi, H., Sakamoto, Y., Hirayama, S., Liu, C., Mitarai, S., Mitarai, S., Yamamoto, G., & Okamoto, K. (2026) · JMIR Medical Informatics · doi:10.2196/preprints.96996
Yang, X., Li, J., Xiang, Y., Ju, M., Liang, K., He, Y., Zhao, Q., & Huang, H. (2026) · doi:10.2196/preprints.99511
Advancements, challenges, and prospects of explainable AI in sleep disordered breathing
Lisik, D., Dinh, T. P. L., & Zou, D. (2026) · Sleep And Breathing · doi:10.1007/s11325-026-03674-3
Preparing Citizens for Emergency Calls with a Hybrid FSM-LLM Dialogue Agent
Klein, S. P., & Kiam, J. J. (2026) · ACM International Conference on Intelligent Virtual Agents (IVA) · doi:10.1145/3806774.3827975
Feistkorn, E., Böhning, D. A., Reuser, M., Davis, E., Begemann, K., & Greiner, M. (2026) · Clinical Toxicology · doi:10.1080/15563650.2026.2647647
Case Studies of Explainable LLMs in Diagnosis, Treatment Planning, and Patient Interaction
Tabatabaei, A., Gorji, M., & Rahimi, A. (2026) · Springer eBooks · doi:10.1007/978-3-032-15088-2_8
The Potential Expertise Paradox in AI-Assisted Radiology
McMillan, A. B. (2026) · Radiology · doi:10.1148/radiol.261178
Responsible AI for safer opioid risk management in older adults
Bakshi, S., Gopal, R., & Yaraghi, N. (2026) · npj Health Systems · doi:10.1038/s44401-026-00092-1
Demystifying Artificial Intelligence
Collins, J. E., Harari, R. E., & Duryea, J. (2026) · Rheumatic Disease Clinics of North America · doi:10.1016/j.rdc.2026.04.001
Yano, Y., Kakizaki, H., Nagasu, H., Kishi, S., Koshida, T., Nihei, Y., Hirano, A., Nangaku, M., Mori, H., (43611), T. N., et al. (2026) · JMIR Formative Research · doi:10.2196/89726
MetaGD-CAN: A Hybrid Generative–Discriminative Method for Cancer Detection in EHR Data
Chang, Y., Tsai, W.-C., Ting, L. P.-Y., & Chuang, K.-T. (2026) · Lecture notes in computer science · doi:10.1007/978-981-92-1465-5_22
Et-Tousy, J., Malek, C., & Zyane, A. (2026) · International Conference on Innovative Research in Applied Science, Engineering and Technology (IRASET) · doi:10.1109/iraset68627.2026.11538732
Zhu, J., Pan, W., Wang, Y., Yan, K., Fang, Z., & Yang, X. (2026) · Journal of Medical Internet Research · doi:10.2196/91222
Caring in the Age of AI: A Framework for the Pediatric Trainee
Lima, G. P., & Morton, S. U. (2026) · PEDIATRICS · doi:10.1542/peds.2025-075138
Proulx, J., Daines, B., Barton, M. B., Leonard, M. E., Garcia, J. A., Young, B., Snell, Q. O., West, T. W., Watson, S. R., Alqaseer, M., et al. (2026) · medRxiv · doi:10.64898/2026.06.05.26354271
Clinical artificial intelligence applications of vision-language foundation models
Thirunavukarasu, A. J., Li, S. Y., Qin, P., Nie, D., Sanghera, R., Lim, E., Yu, J., & Zhang, L. (2026) · PLOS Digital Health · doi:10.1371/journal.pdig.0001453
AI in Healthcare: Promise, Pitfalls, and Future Directions
Nguyen, N. P., Le, T. D. V., Nguyen, N. G. U. Y. E. N., Truong, T. N., Chau, N. C., Nguyen, J., Nguyen, N. G. U. Y. E. N., Nguyen, T. U. O. N. G., Vu, L. T., & Nguyen, T. N. (2026) · TTU Journal of Science · doi:10.53901/tjs.2026.v01.issue02.art02
Custom and Off-the-Shelf Large Language Models Routinely Misinterpret Implant Technique Guides
Woo, J. J., Yang, A. J., Saboo, Y. S., Wassef, A. J., Stavrakis, A. I., Bini, S. A., Christ, A. B., & Ramkumar, P. N. (2026) · JBJS Open Access · doi:10.2106/jbjs.oa.26.00076
Cusácovich, I., Martin, M. P., & Castro, R. G. (2026) · JMIR Formative Research · doi:10.2196/104579
Basu, S. (2026) · arXiv (Cornell University) · doi:10.48550/arxiv.2606.16890
Zhang, S., Li, J., Chen, W., Bao, Z., & Wang, Y. (2026) · Research Square · doi:10.21203/rs.3.rs-9979859/v1
Large reasoning models as thinking machines for medicine
Zhou, H.-Y., Rodman, A. M., Liu, P., Rajpurkar, P., Hu, Y., Wong, T. Y., & Topol, E. J. (2026) · Nature Biomedical Engineering · doi:10.1038/s41551-026-01701-y
MedGenesis: Toward a World Model for Autonomous Clinical and Translational ResearchPreprint
Hao, X., Jiang, N., Zhang, T., Yin, Z., Gui, T., Zhang, Z., Shao, K., Ge, J., Wei, R., Pan, J., et al. (2026) · medRxiv · doi:10.64898/2026.06.14.26355612
Academia and industry in the age of artificial intelligence: a narrative review
Bernstam, E. V., Johnson, T. R., & Alahdab, F. (2026) · BMJ Digital Health & AI · doi:10.1136/bmjdh-2026-000047
Wang, L., Zhang, L., Zhang, Y., Zhang, L. L., & Xie, X. (2026) · Diagnostics · doi:10.3390/diagnostics16132020
From Where to What: The Geo-Intervention Modelling Framework
Wen, R., & Li, S. (2026) · ISPRS International Journal of Geo-Information · doi:10.3390/ijgi15070292
Saha, D., Lin, Y., & Ghose, D. (2026) · ACM Transactions on Computing for Healthcare · doi:10.1145/3828166
Physician epistemic framing alters the accuracy of large language models for medical second opinionsPreprint
Reis, F., Kunde, W., Balzer, F., & Boie, S. D. (2026) · medRxiv · doi:10.64898/2026.06.30.26356911
The 5R's of large language model‐assisted diagnosis: A practical framework for hospitalists
Barish, P. N., Auerbach, A. D., & Ranji, S. R. (2026) · Journal of Hospital Medicine · doi:10.1002/jhm.70390
AI-powered Dynamic Hybrid Teaming
Fouse, A. S., Ganberg, G., Bruni, S., Volkova, S., Orvis, K. L., & Klinefelter, Z. P. (2026) · Emerald Group Publishing Limited eBooks · doi:10.1108/s1534-085620260000021015
Epistemologically Guided LLM Reasoning for Differential Diagnosis
Rancati, S., Bergomi, L., Parimbelli, E., Nicora, G., & Bellazzi, R. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-30710-1_14
Liu, W., & Peltz, G. (2026) · Advanced Science · doi:10.1002/advs.76484
Developing an approach to differential diagnosis of eye diseases based on knowledge formalization
Dolinina, O. N., Kochkareva, E. I., Arutyunyan, D. A., Kamenskikh, T. G., & Викторовна, В. Е. (2026) · Saratov Medical Journal · doi:10.15275/sarmj.2026.0104
Diagnostic performance of artificial intelligence in the syncope unit
van Zanten, S., Boel, T. T., de Jong, J. S. Y., Koomen, E. M., Bais, B., Dara, A., Giele, F., Geertsma, C., Sutton, R., Scheffer, M. G., et al. (2026) · Exploration of Cardiology · doi:10.37349/ec.2026.1012114
İlgün, M., Eren, E., Kibar, B., Okur, S., Aktaş, M. S., EROĞLU, M. S., Arslan, T., Baykal, B., Petek, B., Gürel, A., et al. (2026) · The Veterinary Journal · doi:10.1016/j.tvjl.2026.106776
Assessing AI and Neurologist Diagnostic Reasoning Against Neuropathological Ground TruthPreprint
Leng, Y., Noori, A., He, Y., Favaro, A., Dickson, J. R., Serrano‐Pozo, A., Avetisyan, M., Rodriguez, D., Rosenberg, E. S., Oakley, D. H., et al. (2026) · medRxiv · doi:10.64898/2026.07.07.26356930
Hautz, S. C., Epprecht, T. P., Marcin, T., Jankovska, K., Krummrey, G., & Hautz, W. E. (2026) · Diagnosis · doi:10.1515/dx-2026-0025
Artificial intelligence needs better health systems to reduce inequalities
van Kessel, R., Carter, A. W., Nasir, K., & Mossialos, E. (2026) · npj Digital Medicine · doi:10.1038/s41746-026-03041-2 · Cited by 1
Benchmarking the Evolution of Large Language Models Toward Safe and Collaborative Clinical Reasoning
Asawaponwiput, W., Sri-iesaranusorn, P., Angkurawaranon, C., & Surangsrirat, D. (2026) · International Conference on Human Centric Artificial Intelligence (ICHCAI) · doi:10.1109/ichcai70183.2026.11607497
Can AI assist in reducing diagnostic error? A narrative review
Scott, I. A. (2026) · Diagnosis · doi:10.1515/dx-2026-0021
Contextual Cue Susceptibility in Clinical AI: A Randomized Controlled Clinician-Comparator StudyPreprint
Omar, M., Agbareia, R., Charney, A. W., Abdulnour, R.-E. E., Sakhuja, A., Klang, E., Nadkarni, G. N., & Glicksberg, B. S. (2026) · Research Square · doi:10.21203/rs.3.rs-10408940/v1
Metadata
- Authors
- McDuff, D., Schaekermann, M., Tu, T., Palepu, A., Wang, A., Garrison, J., Singhal, K., Sharma, Y., Azizi, S., Kulkarni, K., Hou, L., Cheng, Y., Liu, Y., Mahdavi, S. S., Prakash, S., Pathak, A., Semturs, C., Patel, S., Webster, D. R., Dominowska, E., Gottweis, J., Barral, J., Chou, K., Corrado, G. S., Matias, Y., Sunshine, J., Karthikesalingam, A., & Natarajan, V.
- Affiliations
- Google (United States) (US)
- Google (Switzerland) (CH)
- Google (United Kingdom) (GB)
- Corresponding author
- McDuff, Daniel
- Schaekermann, Mike
- Karthikesalingam, Alan
- Natarajan, Vivek
- ORCID
- McDuff, Daniel
- Schaekermann, Mike
- Tu, Tao
- Palepu, Anil
- Wang, Amy
- Singhal, Karan
- Azizi, Shekoofeh
- Cheng, Yong
- Liu, Yun
- Mahdavi, S. Sara
- Prakash, Sushant
- Pathak, Anupam
- Semturs, Christopher
- Patel, Shwetak
- Webster, Dale R.
- Dominowska, Ewa
- Gottweis, Juraj
- Barral, Joelle
- Chou, Katherine
- Corrado, Greg S.
- Matias, Yossi
- Sunshine, Jake
- Karthikesalingam, Alan
- Natarajan, Vivek
- Venue
- Nature
- Published
- 2025-04-09
- Volume
- 642
- Issue
- 8067
- Pages
- 451-457
- ISSN
- 0028-0836 (ISSN-L)
- 1476-4687
- PMC
- PMC12158753
- OpenAlex
- W4409283616
- Cited by
- 311
- References
- 34
- Citations by year
- 2026: 172 · 2025: 108
- FWCI
- 67.40
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Locations
- Nature (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, other-oa)
- arXiv (Cornell University)
- Funders
- Massachusetts Medical Society
- DeepMind
- Topics
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Health Sciences › Health Professions › Health Information Management › Artificial Intelligence in Healthcare
- Keywords
- differential diagnosis, large language models, diagnostic reasoning, clinical decision support, clinician performance, AI-assisted diagnosis, medical knowledge retrieval
- MeSH terms
- Case Reports as Topic, Large Language Models, Artificial Intelligence, Diagnosis, Differential, Humans, Language
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
