

The DOI matches its Crossref record; 34 of the 34 references it cites were found in a registry or an index; 9 of the 17 sources its claims cite were checked for support.
Perception, performance, and detectability of conversational artificial intelligence across 32 university courses
Open accessAbstract
The emergence of large language models has led to the development of powerful tools such as ChatGPT that can produce text indistinguishable from human-generated work. With the increasing accessibility of such technology, students across the globe may utilize it to help with their school work—a possibility that has sparked ample discussion on the integrity of student evaluation processes in the age of artificial intelligence (AI). To date, it is unclear how such tools perform compared to students on university-level courses across various disciplines. Further, students’ perspectives regarding the use of such tools in school work, and educators’ perspectives on treating their use as plagiarism, remain unknown. Here, we compare the performance of the state-of-the-art tool, ChatGPT, against that of students on 32 university-level courses. We also assess the degree to which its use can be detected by two classifiers designed specifically for this purpose. Additionally, we conduct a global survey across five countries, as well as a more in-depth survey at the authors’ institution, to discern students’ and educators’ perceptions of ChatGPT’s use in school work. We find that ChatGPT’s performance is comparable, if not superior, to that of students in a multitude of courses. Moreover, current AI-text classifiers cannot reliably detect ChatGPT’s use in school work, due to both their propensity to classify human-written answers as AI-generated, as well as the relative ease with which AI-generated text can be edited to evade detection. Finally, there seems to be an emerging consensus among students to use the tool, and among educators to treat its use as plagiarism. Our findings offer insights that could guide policy discussions addressing the integration of artificial intelligence into educational frameworks.
Overview
AI snapshot
Written from the paper’s full text.
TL;DR
This paper compares ChatGPT against students across 32 university courses, surveys student and educator perceptions in five countries and at NYUAD, and tests whether AI-text classifiers can detect ChatGPT use. It finds ChatGPT often performs comparably or superior to students, current detectors are unreliable, and a simple paraphrasing attack evades detection almost entirely.
Key findings
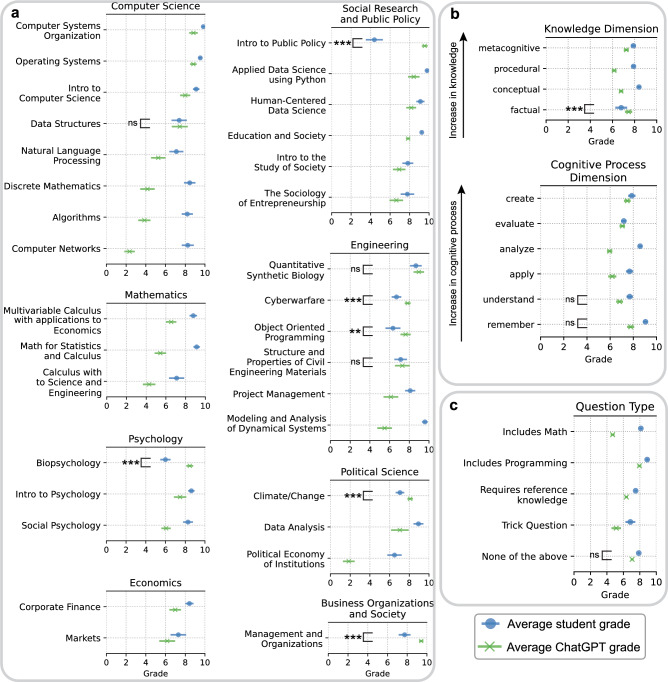
- ChatGPT’s performance was comparable or superior to students on nine of 32 courses in the Results (Data Structures; Introduction to Public Policy; Quantitative Synthetic Biology; Cyberwarfare; Object Oriented Programming; Structure and Properties of Civil Engineering Materials; Biopsychology; Climate/Change; Management and Organizations); the Discussion states 12 (38%) of 32. The largest gaps favoring students were for math-related and trick questions, while ChatGPT outperformed students only on factual-knowledge questions.
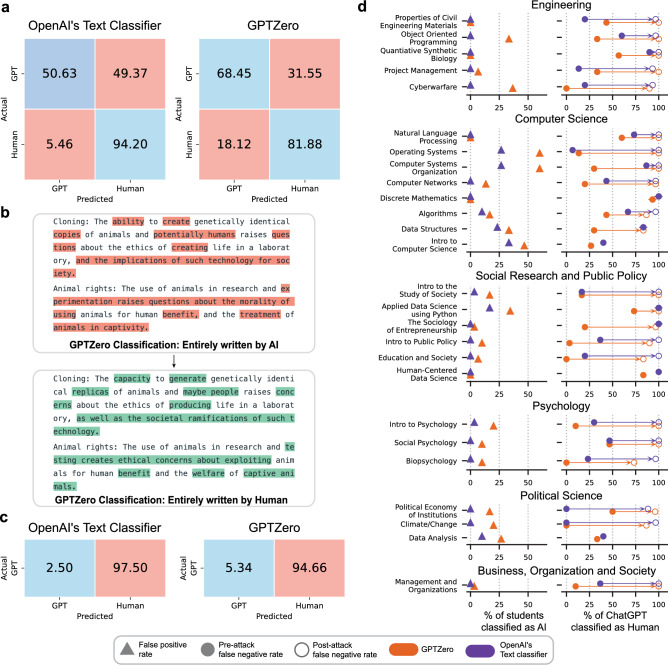
- Detection was poor: OpenAI’s Text Classifier misclassified 5% of student submissions as AI-generated and 49% of ChatGPT submissions as human-generated; GPTZero had an 18% false-positive rate and 32% false-negative rate. After the Quillbot attack, false-negative rates rose from 49% to 98% for OpenAI’s classifier and from 32% to 95% for GPTZero.
- In the global survey (N=1601 across Brazil, India, Japan, UK, US), 74% of students said they would use ChatGPT for their studies; main reasons were improving skills and saving time, while non-users mainly cited not knowing how or no need. OLS results showed students in Brazil and India were significantly more likely, and students in Japan significantly less likely, to use ChatGPT than those in the USA; prior use was associated with future use, and poor/working-class students were more likely to indicate they would use it.
- At NYUAD, 57% of surveyed students planned to use ChatGPT for assignments and 64% expected peers to do so; 61% believed it should be used and 55% expected peers to believe so. Among professors, 69% planned to treat ChatGPT use as plagiarism and 71% expected others to do so; 72% believed it should be treated as plagiarism and 73% expected peers to believe so.
Methods
- Course comparison: NYUAD faculty provided 10 text-based questions per course and three randomly chosen student answers per question; ChatGPT generated three distinct answers per question. Submissions were randomized and graded by three graders per course, with faculty annotating questions by Anderson and Krathwohl taxonomy dimensions and question type.
- Surveys: a global survey recruited participants from Brazil, India, Japan, the UK, and the US, targeting at least 200 students and 100 educators per country (N=1601). A second NYUAD survey included 151 students (7.2% of 2103) and 60 professors (15.2% of 393), with OLS regression used to explore factors associated with students’ decision to use ChatGPT.
- Detection: GPTZero and OpenAI’s AI text classifier were tested on 280 questions after excluding 40 math-only questions; 47 code-snippet questions were excluded from the Quillbot attack. Normalized confusion matrices quantified false-positive and false-negative rates before and after paraphrasing.
Limitations
- Paper-stated: student and educator sentiments were measured in the two months after ChatGPT’s release and may evolve; large language models and detection classifiers will continue to improve, so future work should examine newer models and lower educational levels.
- Evident from text: inter-rater reliability was below 0.6 for six of 32 courses; four were essay-based and subjective, while two were not, though excluding the two non-essay courses gave qualitatively similar results.
- Evident from text: the survey relies on self-reports, and the NYUAD response rates were low (7.2% of students and 15.2% of professors). The text also reports nine comparable/superior courses in Results but 12 (38%) in the Discussion, an inconsistency.
Model-written summary. Check it against the paper before relying on it.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
53 Own result · 13 Own method · 13 Own interpretation · 5 No basis given · 4 Not checked yet · 2 Partly supported · 1 Couldn’t confirm · accuracy not yet measured
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“While these studies demonstrated mixed results with regards to ChatGPT’s performance in standardized exams against that of students, studies which specifically compared the model’s performance against that of previous large language models all indicated a significant improvement in the task of question answering20,21,23.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Introduction
What the sources say
- Supportedcites [20] Gilson, A. et al. How well does ChatGPT do when taking the medical licensing exams? The implications of large language models for medical education and knowledge assessment. medRxiv 2022–12 (2022). source
The Abstract calls ChatGPT a significant improvement over earlier natural-language-processing models for medical question answering. The discussion of prior work says it equals or outperforms earlier models on questions of similar difficulty and content. This supports the claim as applied to this cited study, rather than independently establishing what every other cited study found. (LLM, conf=0.89)
- Partly supportedcites [21] Kung, T. H. et al. Performance of ChatGPT on USMLE: Potential for AI-assisted medical education using large language models. PLoS Digital Health 2, e0000198 (2023). sourceExperimental — accuracy not yet measured
The Discussion (‘The rising accuracy of ChatGPT’; page not provided) reports higher ChatGPT accuracy than figures for earlier language models. But it says the models were tested on different question sets and that no direct comparison was performed, so it does not establish the claimed significant improvement from a direct comparison. (LLM, conf=0.87)
- Partly supportedcites [23] Fijačko, N., Gosak, L., Štiglic, G., Picard, C. T. & Douma, M. J. Can ChatGPT pass the life support exams without entering the American heart association course? Resuscitation185 (2023). sourceExperimental — accuracy not yet measured
In “To the Editor,” the paper says ChatGPT’s answers showed significantly better congruence with resuscitation guidelines than earlier AI-based systems. But the systems identified in its references are voice and conversational assistants, not previous large language models; the reported improvement is specific to resuscitation answers, not question answering generally. (LLM, conf=0.88)
boostedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Supported
The cited sources that could be checked couldn’t confirm or dispute this claim.
In the paper
“Despite these examples, the literature still lacks a systematic study comparing the performance of ChatGPT against that of students across various disciplines at the same institution.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Introduction
What the sources say
- Could not verifycites [20] Gilson, A. et al. How well does ChatGPT do when taking the medical licensing exams? The implications of large language models for medical education and knowledge assessment. medRxiv 2022–12 (2022). sourceExperimental — accuracy not yet measured
The Introduction describes an assessment of ChatGPT on US medical-exam questions, and the Results compare its performance with AMBOSS users. Neither passage addresses whether the literature lacks a systematic comparison with students across disciplines at one institution. Searches for that comparison and for a related literature gap found no supporting passage. (LLM, conf=0.72)
- Could not verifycites [21] Kung, T. H. et al. Performance of ChatGPT on USMLE: Potential for AI-assisted medical education using large language models. PLoS Digital Health 2, e0000198 (2023). sourceExperimental — accuracy not yet measured
The Discussion section on AI-assisted human learning calls for future studies with students in medical education, but it does not assess whether the literature lacks systematic comparisons of ChatGPT and students across disciplines at one institution. Searches for that specific comparison and literature gap found no passage addressing them in our copy; page numbers were not available. (LLM, conf=0.73)
- Could not verifycites [22] Sallam, M. ChatGPT utility in healthcare education, research, and practice: systematic review on the promising perspectives and valid concerns. Healthcare 11, 887 (2023). sourceExperimental — accuracy not yet measured
Section 4.6 (Future Perspectives; page unavailable) calls for more studies of ChatGPT in health care education, but does not identify a lack of comparisons with students across disciplines at one institution. Section 2.1 (Search Strategy and Inclusion Criteria; page unavailable) limits the review’s scope to health care and academic writing. Searches for cross-disciplinary student comparisons and the same-institution condition found no passage establishing the claimed gap. (LLM, conf=0.76)
- Could not verifycites [23] Fijačko, N., Gosak, L., Štiglic, G., Picard, C. T. & Douma, M. J. Can ChatGPT pass the life support exams without entering the American heart association course? Resuscitation185 (2023). sourceExperimental — accuracy not yet measured
The 'To the Editor' section says that ChatGPT's performance had not been examined in life support and resuscitation, and describes comparing its answers with exam keys. It does not address whether the literature lacks a systematic comparison with students across disciplines at the same institution. Searches for that comparison found no passage in our copy. (LLM, conf=0.75)
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Could not verify
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“On the contrary, simply hearing about ChatGPT is not significantly associated with the students’ decision to use it to assist with their studies.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As for prior experience with ChatGPT, those who have used it are significantly more likely to use it again.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These courses are: (i) Data Structures; (ii) Introduction to Public Policy; (iii) Quantitative Synthetic Biology; (iv) Cyberwarfare; (v) Object Oriented Programming; (vi) Structure and Properties of Civil Engineering Materials; (vii) Biopsychology; (viii) Climate/Change; and (ix) Management and Organizations.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
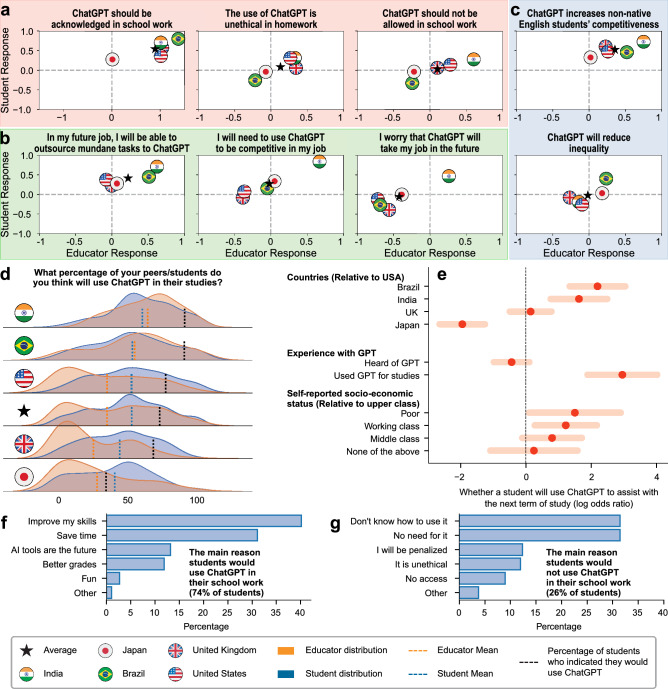
“Starting with panel a (ethics), there seems to be a consensus that using ChatGPT in school work should be acknowledged.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“We find that ChatGPT’s performance is comparable, if not superior, to that of students in a multitude of courses.”
- Also stated in: § Introduction · plain
“We find that ChatGPT’s performance is comparable, or even superior, to that of students on nine out of the 32 courses.”
- Also stated in: § Results · plain
“Apart from Mathematics and Economics, each discipline has at least one course on which ChatGPT’s performance is comparable to, or even surpasses, that of students.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Abstract
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Also stated in: § Introduction · plain
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As a robustness check, we standardized the grades given by each grader of each course to account for grader-specific effects, and again found ChatGPT’s performance is comparable, or superior, to student in the above nine courses (Supplementary Table 3).”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As for those who said they would not use ChatGPT (26%), their main reasons are not knowing how to do so or not having a need for it, rather than a fear of being penalized or acting unethically (Fig. 2g).”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For the students who said they would use it (74%), their main reasons are to improve their skills and save time (Fig. 2f).”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
- Probably not a substantial claim. 21
- It may state two separate claims as one. 28
- The quote only partly states this claim. 6
The cited sources support only part of this claim — read each source’s verdict below.
In the paper
“Studies have shown the validity of using this platform to conduct surveys used in academic research, in addition to the numerous studies which use such platforms for conducting surveys globally56–60.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > Survey
What the sources say
- Not checked yetcites [56] Bentley, F. R., Daskalova, N. & White, B. Comparing the reliability of Amazon Mechanical Turk and Survey Monkey to traditional market research surveys. In Conf. Hum. Factors Comput. Syst. - Proc., 1092–1099 (2017). source
- Could not verifycites [57] Mielke, J., Vermaßen, H. & Ellenbeck, S. Ideals, practices, and future prospects of stakeholder involvement in sustainability science. Proc. Natl. Acad. Sci. U.S.A. 114, E10648–E10657 (2017). sourceExperimental — accuracy not yet measured
Materials and Methods describes an academic survey conducted online, but does not identify SurveyMonkey or assess the validity of using that platform. Searches for SurveyMonkey and platform validity found no passage addressing either point in our copy; the paper’s discussion of content validity concerns its questionnaire, not the survey platform. (LLM, conf=0.73)
- Partly supportedcites [58] Parsa, S. et al. Obstacles to integrated pest management adoption in developing countries. Proc. Natl. Acad. Sci. U.S.A. 111, 3889–3894 (2014). sourceExperimental — accuracy not yet measured
The Materials and Methods section (page unavailable) says the researchers conducted their academic survey using Survey Monkey, supporting the platform-use part of the citing sentence. It does not report a study of the platform’s validity, so it does not support the stronger claim that its validity has been shown. (LLM, conf=0.86)
- Not checked yetcites [59] Evans, R. R. et al. Developing valid and reliable online survey instruments using commercial software programs. J. Consum. Health Internet 13, 42–52 (2009). source
- Not checked yetcites [60] Péloquin, K. & Lafontaine, M.-F. Measuring empathy in couples: Validity and reliability of the interpersonal reactivity index for couples. J. Pers. Assess. 92, 146–157 (2010). source
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In terms of panel c (inequality), there seems to be a consensus that ChatGPT will increase the competitiveness of non-native English students.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As can be seen in the fourth row, representing the average response across the five countries, 74% of students indicate that they would use ChatGPT (black line), while both educators and students underestimated this share.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Moving on to panel b (jobs), students in all five countries believe they can outsource mundane tasks to ChatGPT, and the educators in Brazil and India seem to agree with this statement.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“In contrast, opinions vary when it comes to determining whether the use of ChatGPT in homework is unethical and whether it should be prohibited in school work, e.g., students in India and the US believe it is unethical and should be prohibited, while those in Brazil believe otherwise.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“When it comes to whether ChatGPT will reduce inequality in education, educators in Brazil and Japan (the two non-English speaking countries in our sample) agree with this statement, while those in the remaining three countries disagree.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As can be seen, students from Brazil and India are significantly more likely, and students from Japan are significantly less likely, to use ChatGPT than those from the USA.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“India is the only country where educators believe ChatGPT is needed to increase their competitiveness in their job, and the students therein agree the most with this statement.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Again, we find that the largest performance gap between ChatGPT and students was for math-related questions, followed by trick questions.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
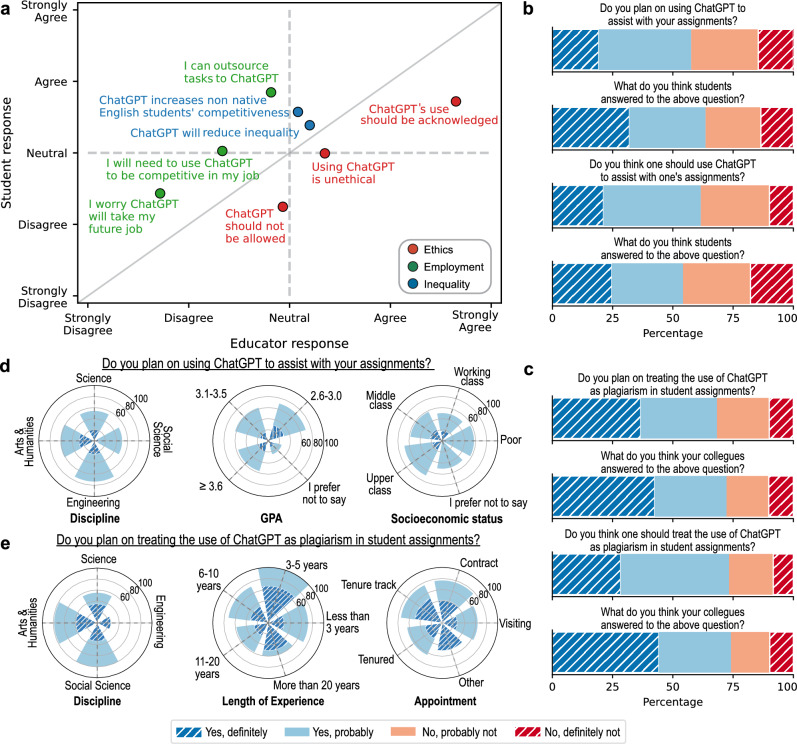
“The majority of students plan to use ChatGPT to assist with their assignments (57%), and expect their peers to use it for this purpose (64%).”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Most professors plan to treat the use of ChatGPT as plagiarism (69%), and expect others to do so (71%).”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As can be seen, professors agreed more, or disagreed less, with all statements in category (i) compared to students (notice how all red data points fall below the diagonal) while students agreed more, or disagreed less, with all statements in categories (ii) and (iii).”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Moreover, the majority believe ChatGPT should be used (61%), and expect that their peers believe it should be used (55%), to assist with assignments.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“GPTZero has a higher false positive rate (18%), but a lower false-negative rate (32%).”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The majority of students plan to use ChatGPT to assist with their assignments (57%), and expect their peers to use it for this purpose (64%).”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Importantly, the Quillbot attack is successful on all courses, often increasing the false-negative rate to 100%.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As can be seen, OpenAI’s Text Classifier misclassifies 5% of student submissions as AI-generated, and 49% of ChatGPT’s submissions as human-generated.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Despite these differences, professors and students seem to agree that ChatGPT’s use should be acknowledged, and neither believes that it will take their future job.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As the figure illustrates, in each discipline, there are courses for which students’ submissions are misclassified, as well as courses for which ChatGPT submissions are misclassified.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one. The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“As for GPA, disregarding those who preferred not to disclose their GPA, the majority of students from all GPA brackets into which students fell indicated that they would use the tool.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
The quote only partly states this claim.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“while those in Brazil think it is ethical and should be allowed”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The survey samples are representative of students and educators in the surveyed countries.
A result the paper reports from its own data — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“students in India think the use of ChatGPT in homework is unethical and should not be allowed”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Discussion
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: The survey samples are representative of students and educators in the surveyed countries.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“For the time being, humans seem to outperform ChatGPT in these areas.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Finally, the detectability of ChatGPT-generated solutions to homework remains unknown.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Introduction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper may give no reason why it holds.
In the paper
“Similarly, Pursnani et al. evaluated ChatGPT’s performance in the context of Engineering, testing the model on the US Fundamentals of Engineering exam33. In their study, they showed that the model’s performance varied across different sections of the exam, performing exceptionally in areas such as Ethics and Professional practice, while under-performing in others such as Hydrology.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Introduction
What the sources say
- Not checked yetcites [33] Pursnani, V., Sermet, Y. & Demir, I. Performance of ChatGPT on the US fundamentals of engineering exam: Comprehensive assessment of proficiency and potential implications for professional environmental engineering practice. arXiv preprintarXiv:2304.12198 (2023). source
plaincorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Worse still, an obfuscation attack renders these algorithms futile, failing to detect 95% of ChatGPT answers.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Introduction
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Finally, there seems to be an emerging consensus among students to use the tool, and among educators to treat its use as plagiarism.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Abstract
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
In the paper
“For instance, Kung et al. evaluated the performance of ChatGPT on the United States Medical Licensing Exam, where they show that ChatGPT performed at or near a passing level on all three stages of the test, without the need for additional specialized training or reinforcement21.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Introduction
What the sources say
- Not checked yetcites [21] Kung, T. H. et al. Performance of ChatGPT on USMLE: Potential for AI-assisted medical education using large language models. PLoS Digital Health 2, e0000198 (2023). source
boosted- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
The paper states this without a source or data behind it here, so there is nothing to check it against. The quote shows it is in the paper.
In the paper
“Moreover, the perspectives of students and educators around the globe regarding the usage of such technology remain unclear.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Introduction
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
In the paper
“which is unsurprising given that abstracts written by ChatGPT have been shown to be indistinguishable from human-generated work17.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Introduction
What the sources say
- Not checked yetcites [17] Else, H. Abstracts written by ChatGPT fool scientists. Nature 613, 423 (2023). source
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The survey was piloted in the United States on Prolific with open-ended questions to investigate that respondents did not find anything odd or surprising about survey questions, and also to ensure no new topics emerged about ChatGPT that the opinion statements covered.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > Survey
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“While the inter-rater reliability for the majority of courses was greater than 0.6, six of the 32 courses did not meet this threshold.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Both students’ and ChatGPT’s answers were then compiled into a single document in random order, labelled as “Submission 1” to “Submission 6”.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > ChatGPT performance analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The participating faculty vetted the graders’ output and ensured that the grading is in line with the rubrics.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > ChatGPT performance analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may state two separate claims as one.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Four of these six courses were essay-based and inherently subjective which may explain this discrepancy.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Results
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: unclear — It is unclear whether the paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“We excluded student participants who indicated that they aware of our study, as well as faculty members who coauthored the paper.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > Survey
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“Informed consent was obtained from all participants in every segment of this study.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > Ethical approval
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“All research was performed in accordance with relevant guidelines and regulations.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > Ethical approval
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“Treating the use of ChatGPT as plagiarism is likely to be the most common approach to counter its usage.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Discussion
hedged- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: fails — The paper may give no reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence. The paper’s conclusions may not depend on it. The paper may give no reason why it holds.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“These findings, coupled with the clear ease with which students can avoid detection by current AI-text classifiers as demonstrated in our study, suggests that educational institutions are facing a serious threat with regards to current student evaluation frameworks.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Discussion
hedgeddirect- Asserted: passes — The authors put it forward as true.
- Checkable: fails — It may be too vague to check against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. It may be too vague to check against evidence.
- Rests on an assumption: The 32 NYUAD courses are representative of university-level courses generally.
- Rests on an assumption: The AI-text classifiers’ classifications are valid indicators of whether text was generated by AI.
A conclusion the paper draws from its own results — it cites no other source for it, so there is none to check. The quote shows it is in the paper.
In the paper
“The inherent conflict between these two could create an environment where students’ incentives suggest they should hide the use of ChatGPT while professors are eager to detect its use (and may expect their colleagues to do the same).”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Discussion
hedgedconditional- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
It may state two separate claims as one.
- Rests on an assumption: Students’ self-reported intentions to use ChatGPT predict their actual use.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“In addition, we ensured that the analytical sample only contains current students and educators who are either teachers or professors based on respondents’ self-reports.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > Survey
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The platform utilizes email and location verification for fraud detection and ID exclusions, thereby guarding against duplicate and bot-submitted responses.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > Survey
plaindirect- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
None of the sources cited for this claim have been checked yet.
In the paper
“studies have demonstrated that academic misconduct in school is highly correlated to dishonesty and with similar decision-making patterns in the workplace39,40”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Discussion
What the sources say
- Not checked yetcites [39] Harding, T. S., Passow, H. J., Carpenter, D. D. & Finelli, C. J. An examination of the relationship between academic dishonesty and professional behavior. In 33rd Annual frontiers in education, 2003. FIE 2003., vol. 3, S2A–6 (IEEE, 2003). source
- Not checked yetcites [40] Nonis, S. & Swift, C. O. An examination of the relationship between academic dishonesty and workplace dishonesty: A multicampus investigation. J. Educ. Bus. 77, 69–77 (2001). source
boostedcorrelational- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The participating faculty was instructed not to inform the graders that some of the submissions are AI-generated.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > ChatGPT performance analysis
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: passes — The paper’s conclusions depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“The research was approved by the Institutional Review Board of New York University Abu Dhabi (HRPP-2023-5).”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > Ethical approval
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it.
What the paper did — it cites no source for this, so there is none to check. The quote shows it is in the paper.
In the paper
“As for the NYUAD survey, it includes responses from 151 students (out of a total of 2103, 7.2%) and 60 professors (out of a total of 393, 15.2%) collected between January 23rd and February 3rd, 2023.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Methods > Survey
plain- Asserted: passes — The authors put it forward as true.
- Checkable: passes — It can be checked against evidence.
- Load-bearing: fails — The paper’s conclusions may not depend on it.
- Based: passes — The paper gives a reason why it holds.
Probably not a substantial claim. The paper’s conclusions may not depend on it. It may state two separate claims as one.
The paper relies on this without support.
The global survey respondents are representative of students and educators in Brazil, India, Japan, the UK, and the US.
“To understand how the use of ChatGPT is perceived by educators and students, we fielded a global survey in five countries, namely Brazil, India, Japan, the UK, and the US, targeting a minimum of 100 educators and 200 students per country; see Methods for more details.”
The paper relies on this without support.
The NYUAD survey respondents are representative of NYUAD students and professors.
“Additionally, we survey 151 undergraduate students and 60 professors more extensively at the authors’ institution to explore differences in perceptions of ChatGPT across disciplines.”
The paper relies on this without support.
The Quillbot attack can be readily implemented by students without requiring any technical know-how.
“Our “Quillbot attack” was chosen since it can be readily implemented by students, without requiring any technical know-how; see Methods for a detailed description of the attack, and see Fig. 4b for a stylized example of how it works.”
The paper relies on this without support.
The value of a degree is in part linked to the validity of the assessment process.
“The value of the degree granted is in part linked to the validity of the assessment process.”
The paper relies on this without support.
The 32 NYUAD courses are representative of university-level courses generally.
“When comparing ChatGPT’s performance to that of students across university-level courses, the results indicate a clear need to take “AI-plagiarism” seriously.”
The paper relies on this without support.
The survey samples are representative of students and educators in the surveyed countries.
“Participants were recruited from Brazil, India, Japan, United Kingdom, and United States, with a minimum of 200 students and 100 educators per country”
The paper relies on this without support.
The AI-text classifiers’ classifications are valid indicators of whether text was generated by AI.
“Once all student and ChatGPT submissions were collected for all courses, they were used to test two classifiers designed specifically to determine whether a body of text has been generated using AI, namely, GPTZero35, and OpenAI’s own AI text classifier36.”
The paper relies on this without support.
Students’ self-reported intentions to use ChatGPT predict their actual use.
“the vast majority of surveyed students (94%) indicated that they would use it to assist with their homework and assignments in the coming semester”
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“A recent study [24] observed that there is an emerging consensus among students to use the tool, while educators tend to view its use as plagiarism, highlighting the need for policy discussions on integrating AI into educational frameworks.”
From ChatGPT for Academic Purposes: Survey Among Undergraduate Healthcare Students in Malaysia (2024) · cites this paper as [24]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
Each contradiction between two passages listed here was confirmed by an independent check.
Rated major: it would touch a result — a value a result rests on, reported and recomputed p-values on opposite sides of the significance level, two passages that conflict with no sign which is right, or a cited work retracted before this paper was published.
In the paper
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Discussion
“Specifically, ChatGPT’s performance was comparable, if not superior, to students’ performance on 12 (38%) out of the 32 courses considered in our analysis.”
§ Perception, performance, and detectability of conversational artificial intelligence across 32 university courses > Introduction
“We find that ChatGPT’s performance is comparable, or even superior, to that of students on nine out of the 32 courses.”
Citations
Cites
A revision of bloom's taxonomy: an overview
Krathwohl, D. R. (2002) · Theory Into Practice · doi:10.1207/s15430421tip4104_2 · Cited by 8,132
Cialdini, R. B., Reno, R. R., & Kallgren, C. A. (1990) · Journal of Personality and Social Psychology · doi:10.1037/0022-3514.58.6.1015 · Cited by 5,965
Kung, T. H., Cheatham, M., Medenilla, A., Sillos, C., De Leon, L., Elepaño, C., Madriaga, M., Aggabao, R., Diaz-Candido, G., Maningo, J., et al. (2023) · PLOS Digital Health · doi:10.1371/journal.pdig.0000198 · Cited by 4,115
Sallam, M. (2023) · Healthcare · doi:10.3390/healthcare11060887 · Cited by 3,126
Hierarchical Text-Conditional Image Generation with CLIP Latents
Ramesh, A., Dhariwal, P., Nichol, A., Chu, C., & Chen, M. (2022) · arXiv · doi:10.48550/arxiv.2204.06125 · Cited by 2,511
What Is the Impact of ChatGPT on Education? A Rapid Review of the Literature
Lo, C. K. (2023) · Education Sciences · doi:10.3390/educsci13040410 · Cited by 2,024
The Grammar of Society: The Nature and Dynamics of Social Norms
Bicchieri, C. (2005) · doi:10.1017/cbo9780511616037 · Cited by 1,991
Pavlik, J. V. (2023) · Journalism & Mass Communication Educator · doi:10.1177/10776958221149577 · Cited by 972 · cited 1×
“…work has examined the utility and performance of large language models in the context of education in a number of different disciplines, including medicine and healthcare 20–23 , computer and data science 24–26 , law 27,28 , business 29 , journalism and media 30 , and language learning 31,32 .”
Abstracts written by ChatGPT fool scientists
Else, H. (2023) · Nature · doi:10.1038/d41586-023-00056-7 · Cited by 611
Tools such as ChatGPT threaten transparent science; here are our ground rules for their use
(2023) · Nature · doi:10.1038/d41586-023-00191-1 · Cited by 605
ChatGPT Goes to Law SchoolPreprint
Choi, J. H., Hickman, K. E., Monahan, A., & Schwarcz, D. B. (2023) · SSRN Electronic Journal · doi:10.2139/ssrn.4335905 · Cited by 565
Nonis, S., & Swift, C. O. (2001) · Journal of Education for Business · doi:10.1080/08832320109599052 · Cited by 564
Ji, H., Han, I., & Ko, Y. (2023) · Journal of Research on Technology in Education · doi:10.1080/15391523.2022.2142873 · Cited by 394
Obstacles to integrated pest management adoption in developing countries
Parsa, S., Morse, S., Bonifacio, A., Chancellor, T. C. B., Condori, B., Crespo-Pérez, V., Hobbs, S. L. A., Kroschel, J., Ba, M. N., Rebaudo, F., et al. (2014) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.1312693111 · Cited by 334
Hong, W. C. H. (2023) · Journal of Educational Technology and Innovation · doi:10.61414/jeti.v5i1.103 · Cited by 328
Assigning AI: Seven Approaches for Students, with Prompts
Mollick, E. R., & Mollick, L. (2023) · SSRN Electronic Journal · doi:10.2139/ssrn.4475995 · Cited by 319
Mollick, E. R., & Mollick, L. (2023) · doi:10.2139/ssrn.4391243 · Cited by 278 · cited 2×
“While our study demonstrated potential issues that ChatGPT introduces in the process of student evaluation, it could also be potentially utilized as an assistive tool that can facilitate both teaching and learning 53–55 .”
Can ChatGPT pass the life support exams without entering the American heart association course?
Fijačko, N., Gosak, L., Štiglic, G., Picard, C. T., & John Douma, M. (2023) · Resuscitation · doi:10.1016/j.resuscitation.2023.109732 · Cited by 206
Generating Diverse Code Explanations using the GPT-3 Large Language Model
MacNeil, S., Tran, A., Mogil, D., Bernstein, S., Ross, E., & Huang, Z. (2022) · Proceedings of the 2022 ACM Conference on International Computing Education Research - Volume 2 · doi:10.1145/3501709.3544280 · Cited by 200
New Modes of Learning Enabled by AI Chatbots: Three Methods and Assignments
Mollick, E. R., & Mollick, L. (2022) · SSRN Electronic Journal · doi:10.2139/ssrn.4300783 · Cited by 176
Gilson, A., Safranek, C., Huang, T., Socrates, V., Chi, L., Taylor, R. A., & Chartash, D. (2022) · doi:10.1101/2022.12.23.22283901 · Cited by 172
Péloquin, K., & Lafontaine, M.-F. (2010) · Journal of Personality Assessment · doi:10.1080/00223890903510399 · Cited by 139
Pursnani, V., Sermet, Y., Kurt, M., & Demir, I. (2023) · Computers and Education: Artificial Intelligence · doi:10.1016/j.caeai.2023.100183 · Cited by 106
Norms, preferences, and conditional behavior
Bicchieri, C. (2010) · Politics Philosophy & Economics · doi:10.1177/1470594x10369276 · Cited by 101
Bentley, F. R., Daskalova, N., & White, B. (2017) · Proceedings of the 2017 CHI Conference Extended Abstracts on Human Factors in Computing Systems · doi:10.1145/3027063.3053335 · Cited by 91 · cited 1×
“Studies have shown the validity of using this platform to conduct surveys used in academic research, in addition to the numerous studies which use such platforms for conducting surveys globally 56–60 .”
Cribben, I., & Zeinali, Y. (2023) · SSRN Electronic Journal · doi:10.2139/ssrn.4404276 · Cited by 70
Rethinking homework in the age of artificial intelligence
Ibrahim, H., Asim, R., Zaffar, F., Rahwan, T., & Zaki, Y. (2023) · IEEE Intelligent Systems · doi:10.1109/mis.2023.3255599 · Cited by 65
Self-citationIdeals, practices, and future prospects of stakeholder involvement in sustainability science
Mielke, J., Vermaßen, H., & Ellenbeck, S. (2017) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.1706085114 · Cited by 56
Developing Valid and Reliable Online Survey Instruments Using Commercial Software Programs
Evans, R. R., Burnett, D. O., Kendrick, O. W., Macrina, D. M., Snyder, S. W., Roy, J. P. L., & Stephens, B. C. (2009) · Journal of Consumer Health On the Internet · doi:10.1080/15398280802674743 · Cited by 30
‘Words Are Flowing Out Like Endless Rain Into a Paper Cup’: ChatGPT & Law School Assessments
Hargreaves, S. (2023) · doi:10.2139/ssrn.4359407 · Cited by 30
An examination of the relationship between academic dishonesty and professional behavior
Harding, T. S., Passow, H. J., Carpenter, D. D., & Finelli, C. J. (2004) · 33rd Annual Frontiers in Education, 2003. FIE 2003. · doi:10.1109/fie.2003.1265933 · Cited by 20
Røberg, K. I. K., & Helland, H. (2016) · Journal of Education and Work · doi:10.1080/13639080.2016.1187265 · Cited by 20
Pursnani, V., Sermet, Y., & Demir, İ. (2023) · arXiv (Cornell University) · doi:10.48550/arxiv.2304.12198 · Cited by 17
Assigning AI: Seven Approaches for Students, with Prompts
Mollick, E., & Mollick, L. (2023) · arXiv · doi:10.48550/arxiv.2306.10052
Research works printed but not linked: 3
- Vincent, J. Top AI conference bans use of ChatGPT and AI language tools to write academic papers (2023). https://www.theverge.com/2023/1/5/23540291/chatgpt-ai-writing-tool-banned-writing-academic-icml-paper.
- Qureshi, B. Exploring the use of chatgpt as a tool for learning and assessment in undergraduate computer science curriculum: Opportunities and challenges. arXiv preprintarXiv:2304.11214 (2023).
- Bicchieri, C. Norms in the Wild (Oxford University Press, Oxford, 2016).
Cited by
Sorted by citations
The Influence of ChatGPT on Student Engagement: A Systematic Review and Future Research Agenda
Lo, C. K., Hew, K. F., & Jong, M. S.-Y. (2024) · Computers & Education · doi:10.1016/j.compedu.2024.105100 · Cited by 392
A multinational study on the factors influencing university students’ attitudes and usage of ChatGPT
Abdaljaleel, M., Barakat, M. M., Alsanafi, M., Salim, N. A., Abazid, H., Malaeb, D. N., Mohammed, A. H., Hassan, B. A. R., Wayyes, A. M., Farhan, S. S., et al. (2024) · Scientific Reports · doi:10.1038/s41598-024-52549-8 · Cited by 391
Higher education students’ perceptions of ChatGPT: A global study of early reactions
Ravšelj, D., Keržič, D., Tomaževič, N., Umek, L., Brezovar, N., A. Iahad, N., Abdulla, A. A., Akopyan, A., Aldana Segura, M. W., AlHumaid, J., et al. (2025) · PLOS ONE · doi:10.1371/journal.pone.0315011 · Cited by 376
Effects of Generative Chatbots in Higher Education
Ilieva, G., Yankova, T., Klisarova-Belcheva, S., Dimitrov, A., Bratkov, M., & Angelov, D. (2023) · Information · doi:10.3390/info14090492 · Cited by 258
A Survey on LLM-Generated Text Detection: Necessity, Methods, and Future Directions
Wu, J., Yang, S., Zhan, R., Yuan, Y., Chao, L. S., & Wong, D. F. (2025) · Computational Linguistics · doi:10.1162/coli_a_00549 · Cited by 212
Metadata
- Authors
- Ibrahim, H., Liu, F., Asim, R., Battu, B., Benabderrahmane, S., Alhafni, B., Adnan, W., Alhanai, T., AlShebli, B., Baghdadi, R., Bélanger, J. J., Beretta, E., Celik, K., Chaqfeh, M., Daqaq, M. F., Bernoussi, Z. E., Fougnie, D., Garcia de Soto, B., Gandolfi, A., Gyorgy, A., Habash, N., Harris, J. A., Kaufman, A., Kirousis, L., Kocak, K., Lee, K., Lee, S. S., Malik, S., Maniatakos, M., Melcher, D., Mourad, A., Park, M., Rasras, M., Reuben, A., Zantout, D., Gleason, N. W., Makovi, K., Rahwan, T., & Zaki, Y.
- Affiliations
- New York University Abu Dhabi (AE)
- Corresponding author
- Rahwan, Talal
- Zaki, Yasir
- ORCID
- Ibrahim, Hazem
- Liu, Fengyuan
- Asim, Rohail
- Battu, Balaraju
- Benabderrahmane, Sidahmed
- Adnan, Wifag
- Alhanai, Tuka
- AlShebli, Bedoor
- Baghdadi, Riyadh
- Bélanger, Jocelyn J.
- Beretta, Elena
- Chaqfeh, Moumena
- Daqaq, Mohammed F.
- Bernoussi, Zaynab El
- Fougnie, Daryl
- Habash, Nizar
- Harris, J. Andrew
- Kaufman, Aaron
- Kirousis, Lefteris
- Lee, Kangsan
- Lee, Seungah S.
- Malik, Samreen
- Maniatakos, Michail
- Melcher, David
- Mourad, Azzam
- Park, Minsu
- Rasras, Mahmoud
- Reuben, Alicja
- Gleason, Nancy W.
- Makovi, Kinga
- Rahwan, Talal
- Zaki, Yasir
- Venue
- Scientific Reports
- Published
- 2023-08-24
- Volume
- 13
- Issue
- 1
- Pages
- 12187-12187
- ISSN
- 2045-2322 (ISSN-L)
- PMC
- PMC10449897
- OpenAlex
- W4386136032
- Semantic Scholar
- 1ffc9d5ebfbc9596aa6c4b9072c60dc12858a718
- Cited by
- 154
- References
- 32
- Citations by year
- 2026: 19 · 2025: 58 · 2024: 69 · 2023: 7
- FWCI
- 38.28
- Type
- journal article
- Language
- en
- Update notices
- correction (2023-10-10)
- Open access
- gold
- doi.org
- Locations
- Scientific Reports (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- arXiv (Cornell University) (submittedVersion, cc-by)
- Iris (University of Trento) (submittedVersion, cc-by)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- arXiv (Cornell University) (cc-by)
- Funders
- New York University Abu Dhabi (CG001)
- Tamkeen (CG001)
- Topics
- Social Sciences › Education › Academic integrity and plagiarism
- Social Sciences › Education › Artificial Intelligence in Education
- Health Sciences › Medicine › Health Informatics › Artificial Intelligence in Healthcare and Education
- Keywords
- ChatGPT, large language models, AI-generated text, academic integrity, plagiarism, AI detection, student perceptions, educator perceptions, university courses, generative AI in education
- MeSH terms
- Artificial Intelligence, Communication, Humans, Perception, Schools, Universities
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
A language model drew the claims from the paper on 2026-10-10, under version 3 of the claim definition (model deepseek-v4.1-flash, prompt extract-v3).
A second model labelled each claim on 2026-10-10 (model jev-1.13-20260917, definition revision gold-guideline-v0.2).
Cited sources are checked with a language model’s help (gpt-6-sol).
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
