

ProteinBERT: a universal deep-learning model of protein sequence and function
Open accessPublished version of a preprint
The DOI matches its Crossref record; 48 of the 48 references it cites were found in a registry or an index.
Abstract
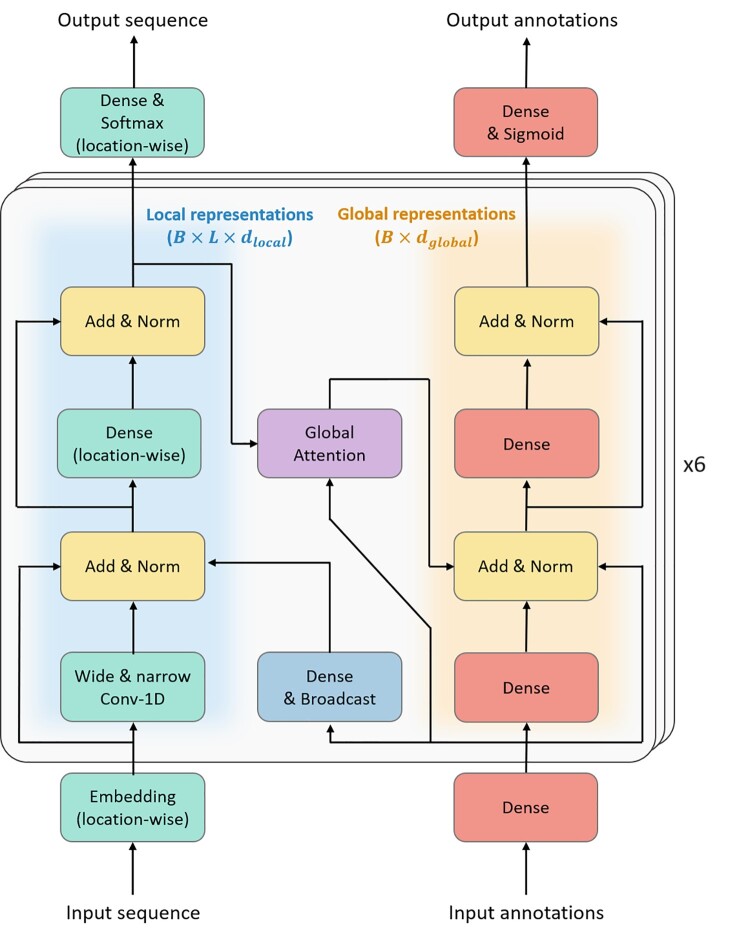
Summary: Self-supervised deep language modeling has shown unprecedented success across natural language tasks, and has recently been repurposed to biological sequences. However, existing models and pretraining methods are designed and optimized for text analysis. We introduce ProteinBERT, a deep language model specifically designed for proteins. Our pretraining scheme combines language modeling with a novel task of Gene Ontology (GO) annotation prediction. We introduce novel architectural elements that make the model highly efficient and flexible to long sequences. The architecture of ProteinBERT consists of both local and global representations, allowing end-to-end processing of these types of inputs and outputs. ProteinBERT obtains near state-of-the-art performance, and sometimes exceeds it, on multiple benchmarks covering diverse protein properties (including protein structure, post-translational modifications and biophysical attributes), despite using a far smaller and faster model than competing deep-learning methods. Overall, ProteinBERT provides an efficient framework for rapidly training protein predictors, even with limited labeled data. Availability and implementation: Code and pretrained model weights are available at https://github.com/nadavbra/protein_bert. Supplementary information: Supplementary data are available at Bioinformatics online.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures

Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“In biology applications, deep learning has been employed to learn the structure of DNA and protein sequences [6,7]”
From Challenges in AI-driven Biomedical Multimodal Data Fusion and Analysis (2025) · cites this paper as [7]
Experimental — accuracy not yet measured
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Basic local alignment search tool
Altschul, S. F., Gish, W., Miller, W., Myers, E. W., & Lipman, D. J. (1990) · Journal of Molecular Biology · doi:10.1006/jmbi.1990.9999 · Cited by 98,669
Gapped BLAST and PSI-BLAST: a new generation of protein database search programs
Altschul, S. (1997) · Nucleic Acids Research · doi:10.1093/nar/25.17.3389 · Cited by 73,302
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
Gene Ontology: tool for the unification of biology
Ashburner, M., Ball, C. A., Blake, J. A., Botstein, D., Butler, H., Cherry, J. M., Davis, A. P., Dolinski, K., Dwight, S. S., Eppig, J. T., et al. (2000) · Nature Genetics · doi:10.1038/75556 · Cited by 43,206
Pan, S. J., & Yang, Q. (2010) · IEEE Transactions on Knowledge and Data Engineering · doi:10.1109/tkde.2009.191 · Cited by 23,387 · cited 1×
“According to the transfer-learning paradigm, a model is first pre-trained on one task, and then fine-tuned on other downstream tasks of interest [7–9].”
MethodLanguage Models are Few-Shot Learners
Brown, T. B., Mann, B., Ryder, N., Subbiah, M., Kaplan, J., Dhariwal, P., Neelakantan, A., Shyam, P., Sastry, G., Askell, A., et al. (2020) · arXiv · doi:10.48550/arxiv.2005.14165 · Cited by 23,372
Advances in neural information processing systems 7
(1996) · Computers & Mathematics with Applications · doi:10.1016/s0898-1221(96)90463-0 · Cited by 14,281
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P. J. (2019) · arXiv · doi:10.48550/arxiv.1910.10683 · Cited by 10,929
XLNet: Generalized Autoregressive Pretraining for Language Understanding
Yang, Z., Dai, Z., Yang, Y., Carbonell, J., Salakhutdinov, R., & Le, Q. V. (2019) · arXiv · doi:10.48550/arxiv.1906.08237 · Cited by 6,687
Pfam: the protein families database
Finn, R. D., Bateman, A., Clements, J., Coggill, P., Eberhardt, R. Y., Eddy, S. R., Heger, A., Hetherington, K., Holm, L., Mistry, J., et al. (2014) · Nucleic Acids Research · doi:10.1093/nar/gkt1223 · Cited by 6,148 · cited 1×
“To this day, protein research is still dominated by classical sequence-similarity methods (such as BLAST [18] and hidden Markov models [19]), in contrast to domains such as computer vision which have become dominated by deep learning.”
Method
Research works printed but not linked: 2
- Abadi, 2016, 12th USENIX Symposium on Operating Systems Design and Implementation (OSDI16), 265
- Radford, 2019, Language models are unsupervised multitask learners, OpenAI Blog, 1, 9
Cited by
Items 1,001–1,005 of 1,005
SignalGen: A Protein Language Model Based AI Agent For Optimal Signal Peptide PredictionPreprint
McKenzie, J., Do, H. N., Shanker, A., Kubicek-Sutherland, J. Z., & Gnanakaran, S. (2025) · bioRxiv (Cold Spring Harbor Laboratory) · doi:10.1101/2025.11.12.688111
Predicting T Cell Receptor Specificity with Graph Attention Networks
Xu, A., Patel, D., Lin, W., & Luo, P. (2025) · Lecture notes in computer science · doi:10.1007/978-3-032-08452-1_17
Zhen, Z., Ma, T., Liu, Y., & Zeng, X. (2025) · IEEE Journal of Biomedical and Health Informatics · doi:10.1109/jbhi.2025.3632354
GGANet: A Geometry-Enhanced Gated Attention Network for Drug-Target Interaction Prediction
Luo, H. X., & Zhang, Y. (2025) · International Joint Conference on Neural Networks (IJCNN) · doi:10.1109/ijcnn64981.2025.11228548
Multilingual transfer ability: Find Rosetta Stone between DNA Language and Natural LanguagePreprint
Wang, L. (2025) · Research Square · doi:10.21203/rs.3.rs-7898312/v1
Metadata
- Authors
- Brandes, N., Ofer, D., Peleg, Y., Rappoport, N., & Linial, M.
- Affiliations
- Hebrew University of Jerusalem (IL)
- Deep Trading Ltd. , Haifa 3508401, Israel
- Ben-Gurion University of the Negev (IL)
- Department of Biological Chemistry, The Alexander Silberman Institute of Life Sciences, The Hebrew University of Jerusalem, Jerusalem 9190401, Israel
- Corresponding author
- Brandes, Nadav
- Venue
- Bioinformatics
- Publisher
- Oxford University Press (OUP)
- Published
- 2022-02-10
- Volume
- 38
- Issue
- 8
- Pages
- 2102-2110
- ISSN
- 1367-4803 (ISSN-L)
- 1367-4811
- PMC
- PMC9386727
- OpenAlex
- W4205773061
- Cited by
- 1,009
- References
- 44
- Citations by year
- 2026: 248 · 2025: 355 · 2024: 241 · 2023: 127 · 2022: 34
- FWCI
- 62.19
- Type
- journal article
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- Locations
- Bioinformatics (publishedVersion, cc-by)
- bioRxiv (Cold Spring Harbor Laboratory) (acceptedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- Funders
- Israel Science Foundation (2753/20)
- Topics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Machine Learning in Bioinformatics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Protein Structure and Dynamics
- Physical Sciences › Computer Science › Artificial Intelligence › Machine Learning in Healthcare
- Keywords
- protein sequence representation, protein function prediction, protein structure prediction, long sequence modeling
- MeSH terms
- Deep Learning, Amino Acid Sequence, Language, Natural Language Processing, Proteins
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
