

The DOI matches its Crossref record; 62 of the 62 references it cites were found in a registry or an index.
GO-PCA: An Unsupervised Method to Explore Gene Expression Data Using Prior Knowledge
Open accessPublished version of a preprint
Abstract
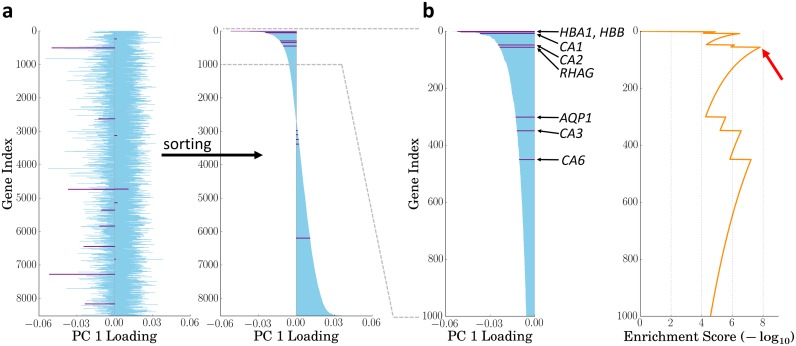
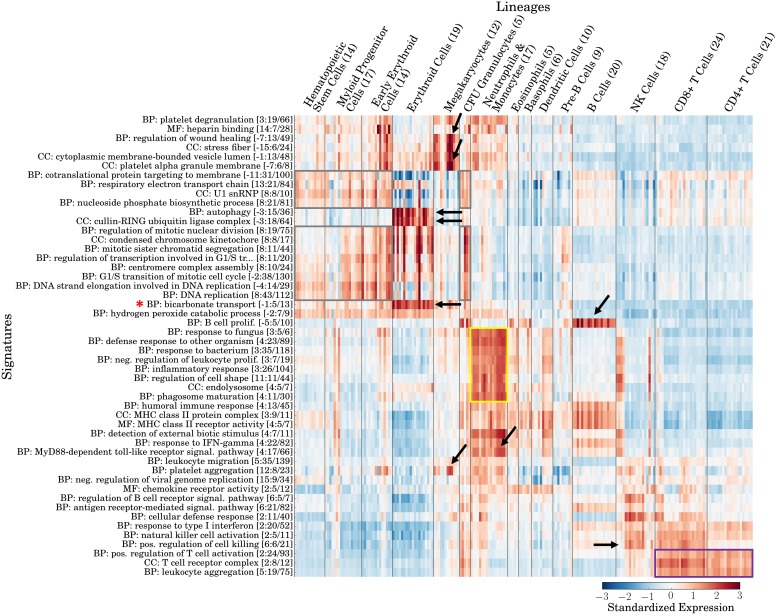
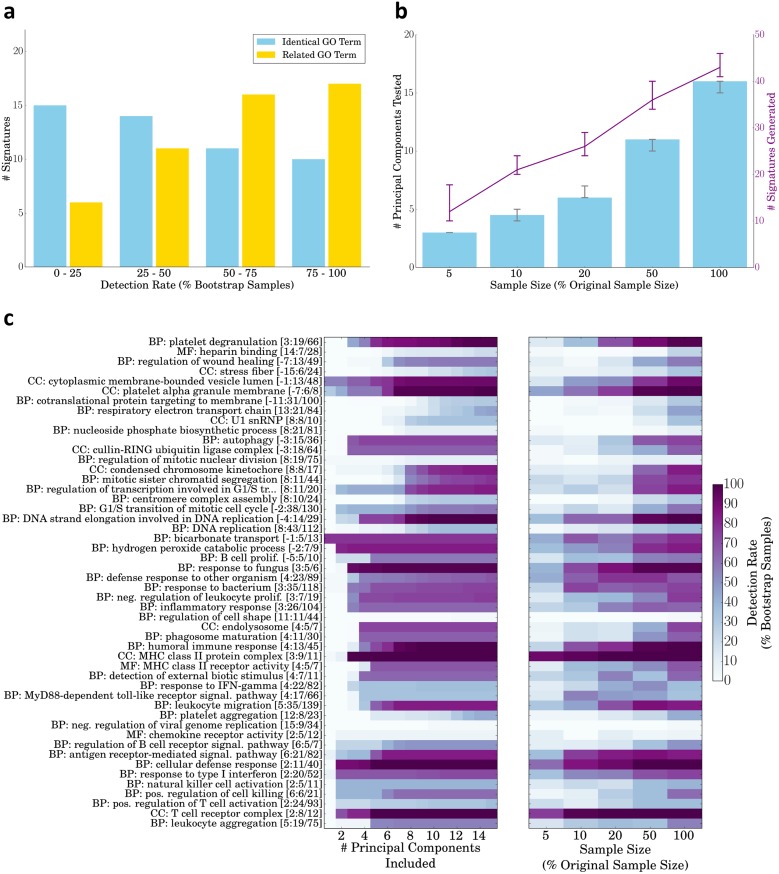
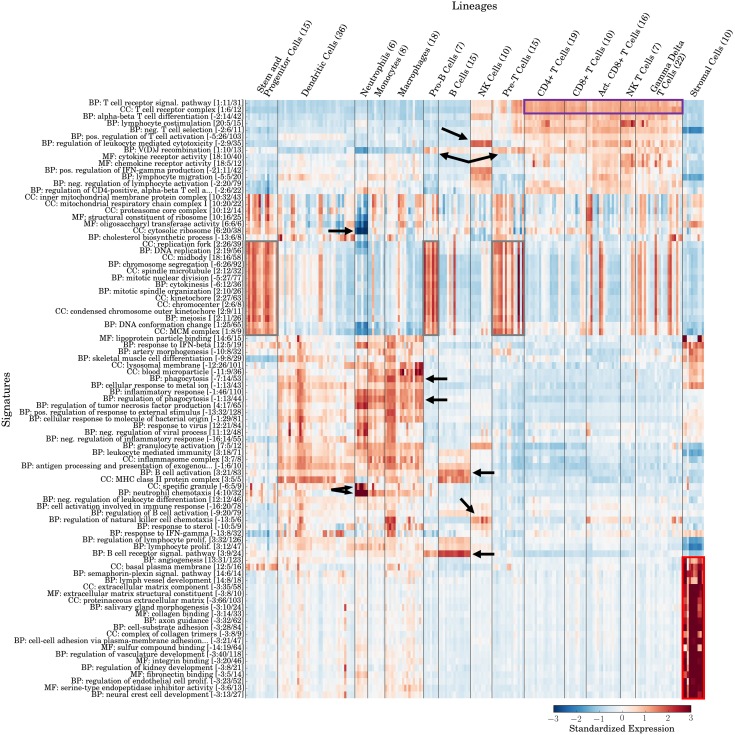
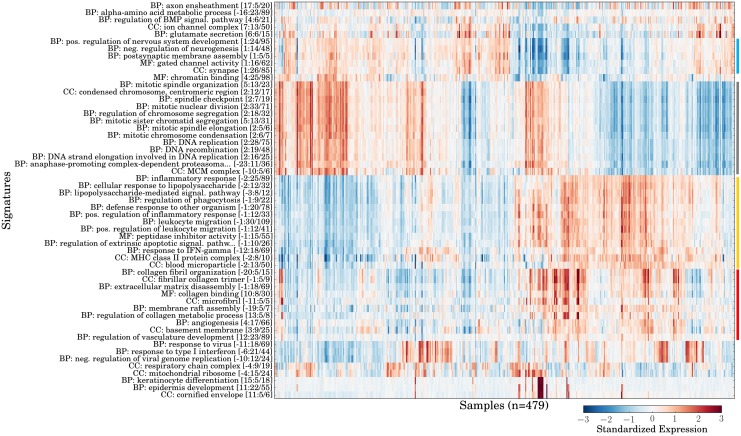
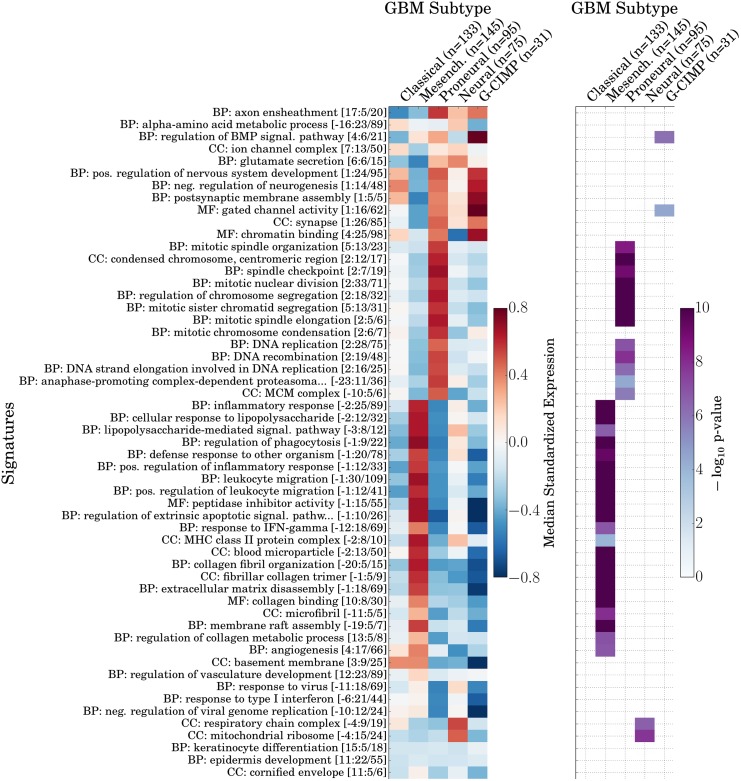
METHOD: Genome-wide expression profiling is a widely used approach for characterizing heterogeneous populations of cells, tissues, biopsies, or other biological specimen. The exploratory analysis of such data typically relies on generic unsupervised methods, e.g. principal component analysis (PCA) or hierarchical clustering. However, generic methods fail to exploit prior knowledge about the molecular functions of genes. Here, I introduce GO-PCA, an unsupervised method that combines PCA with nonparametric GO enrichment analysis, in order to systematically search for sets of genes that are both strongly correlated and closely functionally related. These gene sets are then used to automatically generate expression signatures with functional labels, which collectively aim to provide a readily interpretable representation of biologically relevant similarities and differences. The robustness of the results obtained can be assessed by bootstrapping. RESULTS: I first applied GO-PCA to datasets containing diverse hematopoietic cell types from human and mouse, respectively. In both cases, GO-PCA generated a small number of signatures that represented the majority of lineages present, and whose labels reflected their respective biological characteristics. I then applied GO-PCA to human glioblastoma (GBM) data, and recovered signatures associated with four out of five previously defined GBM subtypes. My results demonstrate that GO-PCA is a powerful and versatile exploratory method that reduces an expression matrix containing thousands of genes to a much smaller set of interpretable signatures. In this way, GO-PCA aims to facilitate hypothesis generation, design of further analyses, and functional comparisons across datasets.
Overview
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Free: it reads the open-access text and checks the first 5 claims that cite a source we can check. Create a free account to check every claim.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The cited source says what the claim attributes to it.
In the citing paper
“Similar approaches have been used in other biological settings1, and enhanced resolution, for example from pseudotemporal ordering, has helped recover such dependencies135,137.”
From Revealing the vectors of cellular identity with single-cell genomics (2016) · cites this paper as [137]
In the citing paper
“Thus, the large variation induced by the cell cycle in some scRNA-seq experiments may conceal other important sources of biological variation101, especially cellular differentiation processes137,141,151,152.”
From Revealing the vectors of cellular identity with single-cell genomics (2016) · cites this paper as [137]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Controlling the False Discovery Rate: A Practical and Powerful Approach to Multiple Testing
Benjamini, Y., & Hochberg, Y. (1995) · Journal of the Royal Statistical Society Series B: Statistical Methodology · doi:10.1111/j.2517-6161.1995.tb02031.x · Cited by 109,482 · cited 1×
“In combination with an FDR criterion [47], a jackstraw-like approach could allow GO-PCA to adjust the XL-mHG L parameter in a “smart” way for each PC.”
Scikit-learn: Machine Learning in Python
Pedregosa, F., Varoquaux, G., Gramfort, A., Michel, V., Thirion, B., Grisel, O., Blondel, M., Müller, A., Nothman, J., Louppe, G., et al. (2012) · arXiv · doi:10.48550/arxiv.1201.0490 · Cited by 71,016 · cited 1×
“PCA module from the scikit-learn Python package [48], version 0.”
Subramanian, A., Tamayo, P., Mootha, V. K., Mukherjee, S., Ebert, B. L., Gillette, M. A., Paulovich, A., Pomeroy, S. L., Golub, T. R., Lander, E. S., et al. (2005) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.0506580102 · Cited by 53,625 · cited 2×
“In light of the intuitive appeal of this idea, as well as its highly successful application in supervised settings [14], there exist surprisingly few methods that exploit prior biological”
An Introduction to the Bootstrap
Efron, B., & Tibshirani, R. J. (1994) · doi:10.1201/9780429246593 · Cited by 40,500
Molecular portraits of human breast tumours
Perou, C. M., Sørlie, T., Eisen, M. B., van de Rijn, M., Jeffrey, S. S., Rees, C. A., Pollack, J. R., Ross, D. T., Johnsen, H., Akslen, L. A., et al. (2000) · Nature · doi:10.1038/35021093 · Cited by 16,261 · cited 1×
“, the identification of clinically relevant cancer subtypes [10, 11]), arriving at such results typically requires significant human effort combined with expert knowledge, and can be fraught with difficulties.”
Cluster analysis and display of genome-wide expression patterns
Eisen, M. B., Spellman, P. T., Brown, P. O., & Botstein, D. (1998) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.95.25.14863 · Cited by 16,184 · cited 1×
“Popular approaches include principal component analysis (PCA) [5], hierarchical clustering [6], k-means clustering, consensus clustering [7], non-negative matrix factorization (reviewed in [8]), mixture models (e.”
Nishimura, R., Osako, T., Nishiyama, Y., Tashima, R., Nakano, M., Fujisue, M., Toyozumi, Y., & Arima, N. (2013) · Oncology · doi:10.1159/000353099 · Cited by 13,166
Distinct types of diffuse large B-cell lymphoma identified by gene expression profiling
Alizadeh, A. A., Eisen, M. B., Davis, R. E., Ma, C., Lossos, I. S., Rosenwald, A., Boldrick, J. C., Sabet, H., Tran, T., Yu, X., et al. (2000) · Nature · doi:10.1038/35000501 · Cited by 9,925 · cited 1×
“, the identification of clinically relevant cancer subtypes [10, 11]), arriving at such results typically requires significant human effort combined with expert knowledge, and can be fraught with difficulties.”
Statistical significance for genomewide studies
Storey, J. D., & Tibshirani, R. (2003) · Proceedings of the National Academy of Sciences · doi:10.1073/pnas.1530509100 · Cited by 9,692
Bolstad, B. M., Irizarry, R. A., Åstrand, M., & Speed, T. P. (2003) · Bioinformatics · doi:10.1093/bioinformatics/19.2.185 · Cited by 8,266 · cited 1×
“The resulting matrix containing expression for 10,785 genes was quantile-normalized [52].”
Cited by
Comprehensive Classification of Retinal Bipolar Neurons by Single-Cell Transcriptomics
Shekhar, K., Lapan, S. W., Whitney, I. E., Tran, N. M., Macosko, E. Z., Kowalczyk, M., Adiconis, X., Levin, J. Z., Nemesh, J., Goldman, M., et al. (2016) · Cell · doi:10.1016/j.cell.2016.07.054 · Cited by 1,176
Revealing the vectors of cellular identity with single-cell genomics
Wagner, A., Regev, A., & Yosef, N. (2016) · Nature Biotechnology · doi:10.1038/nbt.3711 · Cited by 632
A Distinct Gene Module for Dysfunction Uncoupled from Activation in Tumor-Infiltrating T Cells
Singer, M., Wang, C., Cong, L., Marjanovic, N. D., Kowalczyk, M. S., Zhang, H., Nyman, J., Sakuishi, K., Kurtulus, S., Gennert, D., et al. (2016) · Cell · doi:10.1016/j.cell.2016.08.052 · Cited by 420
Early emergence of cortical interneuron diversity in the mouse embryo
Mi, D., Li, Z., Lim, L., Li, M., Moissidis, M., Yang, Y., Gao, T., Hu, T. X., Pratt, T., Price, D. J., et al. (2018) · Science · doi:10.1126/science.aar6821 · Cited by 259
Sasagawa, Y., Danno, H., Takada, H., Ebisawa, M., Tanaka, K. Y., Hayashi, T., Kurisaki, A., & Nikaido, I. (2018) · Genome biology · doi:10.1186/s13059-018-1407-3 · Cited by 146
Metadata
- Authors
- Wagner, F.
- Affiliations
- Duke University (US)
- Corresponding author
- Wagner, Florian
- ORCID
- Wagner, Florian
- Venue
- PLOS ONE
- Publisher
- Public Library of Science (PLoS)
- Published
- 2015-11-17
- Volume
- 10
- Issue
- 11
- Pages
- e0143196
- ISSN
- 1932-6203 (ISSN-L)
- PMC
- PMC4648502
- OpenAlex
- W2174288164
- Cited by
- 35
- References
- 60
- Citations by year
- 2026: 1 · 2025: 2 · 2024: 4 · 2023: 3 · 2022: 4 · 2021: 7 · 2020: 2 · 2019: 2 · 2018: 4 · 2017: 2 · 2016: 3 · 2015: 1
- FWCI
- 1.45
- Type
- journal article
- Language
- en
- Open access
- gold
- doi.org
- Licence
- Locations
- PLoS ONE (publishedVersion, cc-by)
- bioRxiv (Cold Spring Harbor Laboratory) (acceptedVersion, cc-by-nc-nd)
- Europe PMC (PubMed Central) (publishedVersion, cc-by)
- PubMed Central (publishedVersion, cc-by)
- PubMed (publishedVersion)
- RePEc: Research Papers in Economics (submittedVersion)
- DOAJ (DOAJ: Directory of Open Access Journals) (submittedVersion, cc-by-sa)
- Figshare (submittedVersion, cc-by)
- Topics
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Gene expression and cancer classification
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Bioinformatics and Genomic Networks
- Life Sciences › Biochemistry, Genetics and Molecular Biology › Molecular Biology › Genomics and Phylogenetic Studies
- Keywords
- gene expression signatures, gene ontology enrichment, unsupervised dimensionality reduction, principal component analysis, hematopoietic lineage, glioblastoma subtypes, bootstrapping, hypothesis generation
- MeSH terms
- Algorithms, Animals, Glioblastoma, Hematopoietic Stem Cells, Humans, Neoplasm Staging, Software, Cluster Analysis, Genome, Cell Lineage, Principal Component Analysis, Databases, Genetic, Mice, Molecular Sequence Annotation, Transcriptome
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
How to cite
Cite CoChat for the checks on this page, and the paper for its own findings.
- This page
- CoChat. (2026). Citation check: GO-PCA: An Unsupervised Method to Explore Gene Expression Data Using Prior Knowledge. https://app.cochat.ai/papers/10.1371/journal.pone.0143196
- The paper
- Wagner, F. (2015). GO-PCA: An Unsupervised Method to Explore Gene Expression Data Using Prior Knowledge. PLOS ONE. https://doi.org/10.1371/journal.pone.0143196
Data sources
Bibliographic data: Semantic Scholar, OpenAlex, Crossref.
Contains information from the Semantic Scholar Academic Graph Datasets, made available under the ODC Attribution License (ODC-BY 1.0).
Semantic Scholar’s data is described in: Kinney, R., et al. (2023). The Semantic Scholar Open Data Platform. arXiv:2301.10140.
