

The DOI matches its Crossref record; 79 of the 79 references it cites were found in a registry or an index.
HERO: Hierarchical Encoder for Video+Language Omni-representation Pre-training
Open accessAbstract
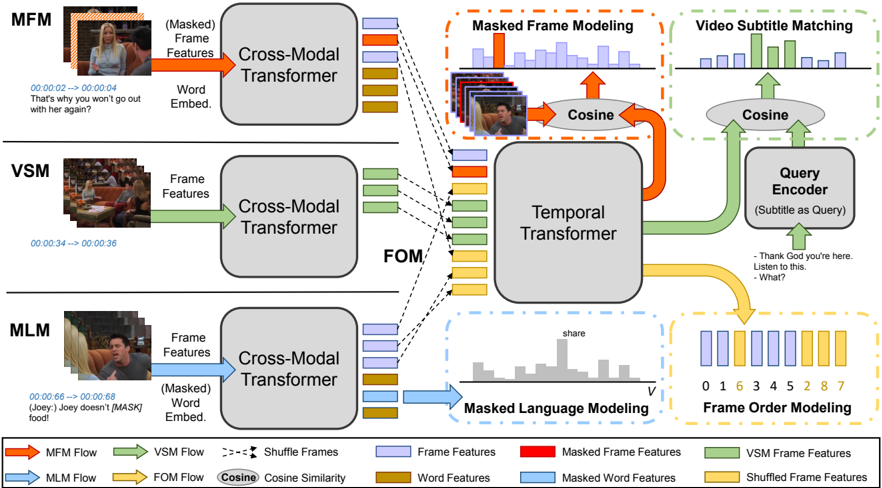
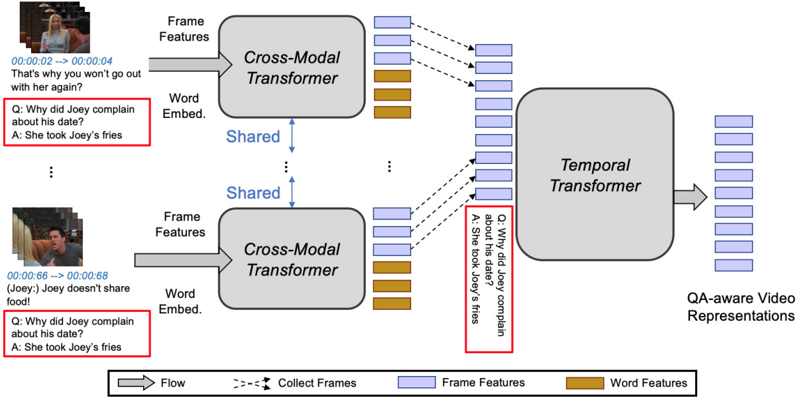
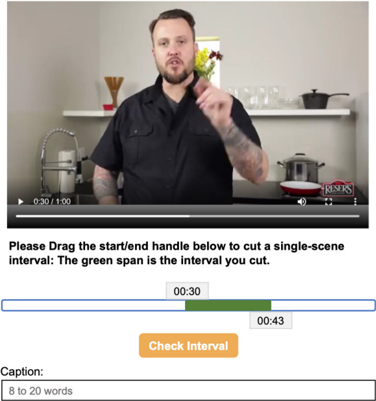
We present HERO, a novel framework for large-scale video+language omnirepresentation learning.HERO encodes multimodal inputs in a hierarchical structure, where local context of a video frame is captured by a Cross-modal Transformer via multimodal fusion, and global video context is captured by a Temporal Transformer.In addition to standard Masked Language Modeling (MLM) and Masked Frame Modeling (MFM) objectives, we design two new pre-training tasks: (i) Video-Subtitle Matching (VSM), where the model predicts both global and local temporal alignment; and (ii) Frame Order Modeling (FOM), where the model predicts the right order of shuffled video frames.HERO is jointly trained on HowTo100M and large-scale TV datasets to gain deep understanding of complex social dynamics with multi-character interactions.Comprehensive experiments demonstrate that HERO achieves new state of the art on multiple benchmarks over Text-based Video/Video-moment Retrieval, Video Question Answering (QA), Video-and-language Inference and Video Captioning tasks across different domains.We also introduce two new challenging benchmarks How2QA and How2R for Video QA and Retrieval, collected from diverse video content over multimodalities. 1
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“As demonstrated in Figure 2 in [192], the multimodal Transformer models have another architecture taxonomy based on the computational size of the components.”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
Experimental — accuracy not yet measuredIn the citing paper
“One simplifying is processing the visual input in convolution-free manner, e.g., E2E-VLP [271], ViLT [192].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Jakubův, J., Chvalovský, K., Goertzel, Z., et al. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,648
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
ImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333
Self-citationBERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
Decoupled Weight Decay Regularization
Loshchilov, I., & Hutter, F. (2017) · arXiv · doi:10.48550/arxiv.1711.05101 · Cited by 12,522
(2017) · Cited by 11,625
Research works printed but not linked: 4
- Lisa Anne Hendricks, Oliver Wang, Eli Shechtman, Josef Sivic, Trevor Darrell, and Bryan Russell. 2017b. Localizing moments in video with natural language. In CVPR.
- Myle Ott, Sergey Edunov, David Grangier, and Michael Auli. 2018. Scaling neural machine trans- lation. arXiv preprint arXiv:1806.00187. · arXiv
- Jun Xu, Tao Mei, Ting Yao, and Yong Rui. 2016b. Msr- vtt: A large video description dataset for bridging video and language. CVPR.
- Licheng Yu, Zhe Lin, Xiaohui Shen, Jimei Yang, Xin Lu, Mohit Bansal, and Tamara L Berg. 2018a. Mat- tnet: Modular attention network for referring expres- sion comprehension. In CVPR.
Cited by
Sorted by citations
Items 201–300 of 410
Rectify representation bias in vision-language models for long-tailed recognition
Li, B., Yao, Y., Tan, J., Gong, R., Lu, J., & Luo, Y. (2024) · Neural Networks · doi:10.1016/j.neunet.2024.106134 · Cited by 13
Transcript to Video: Efficient Clip Sequencing from Texts
Xiong, Y., Heilbron, F. C., & Lin, D. (2022) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3503161.3548268 · Cited by 11
Video and Text Matching with Conditioned Embeddings
Ali, A., Schwartz, I., Hazan, T., & Wolf, L. (2022) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv51458.2022.00055 · Cited by 13
Semantic Association Network for Video Corpus Moment Retrieval
Kim, D., Yoon, S., Hong, J. W., & Yoo, C. D. (2022) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp43922.2022.9747523 · Cited by 11
MAC: Masked Contrastive Pre-Training for Efficient Video-Text Retrieval
Shu, F., Chen, B., Liao, Y., Wang, J., & Liu, S. (2024) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2024.3402613 · Cited by 23
VITATECS: A Diagnostic Dataset for Temporal Concept Understanding of Video-Language Models
Li, S., Li, L., Liu, Y., Ren, S., Liu, Y., Gao, R., Sun, X., & Hou, L. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-72897-6_19 · Cited by 29
Self-citationAudio-Visual LLM for Video Understanding
Shu, F., Zhang, L., Jiang, H., & Xie, C. (2025) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw69036.2025.00447 · Cited by 73
All You Can Embed: Natural Language based Vehicle Retrieval with Spatio-Temporal Transformers
Scribano, C., Sapienza, D., Franchini, G., Verucchi, M., & Bertogna, M. (2021) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw53098.2021.00481 · Cited by 11
Improving Video Retrieval Using Multilingual Knowledge Transfer
Madasu, A., Aflalo, E., Stan, G. B. M., Tseng, S.-Y., Bertasius, G., & Lal, V. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-28244-7_42 · Cited by 10
Efficient End-to-End Video Question Answering with Pyramidal Multimodal Transformer
Peng, M., Wang, C., Shi, Y., & Zhou, X.-D. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i2.25296 · Cited by 14
SEM-POS: Grammatically and Semantically Correct Video Captioning
Nadeem, A., Hilton, A., Dawes, R., Thomas, G., & Mustafa, A. (2023) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw59228.2023.00259 · Cited by 12
Video-Text Retrieval by Supervised Sparse Multi-Grained Learning
Wang, Y., & Shi, P. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.46 · Cited by 12
Balance Act: Mitigating Hubness in Cross-Modal Retrieval with Query and Gallery Banks
Wang, Y., Jian, X., & Xue, B. (2023) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2023.emnlp-main.652 · Cited by 15
SMAUG: Sparse Masked Autoencoder for Efficient Video-Language Pre-training
Lin, Y., Wei, C., Wang, H., Yuille, A., & Xie, C. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00233 · Cited by 11
Video-guided machine translation via dual-level back-translation
Chen, S., YaWen, Z., Cao, D., & Lu, S. (2022) · Knowledge-Based Systems · doi:10.1016/j.knosys.2022.108598 · Cited by 10
Watching the News: Towards VideoQA Models that can Read
Jahagirdar, S., Mathew, M., Karatzas, D., & Jawahar, C. V. (2023) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv56688.2023.00442 · Cited by 12
Tuning Large Multimodal Models for Videos using Reinforcement Learning from AI Feedback
Ahn, D., Choi, Y., Yu, Y., Kang, D., & Choi, J. (2024) · Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) · doi:10.18653/v1/2024.acl-long.52 · Cited by 10
Ghorbani, S., Gaur, Y., Shi, Y., & Li, J. (2021) · IEEE Spoken Language Technology Workshop (SLT) · doi:10.1109/slt48900.2021.9383466 · Cited by 9
Hateful meme detection with multimodal deep neural networks
Constantin, M. G., Pârvu, D.-Ș., Stanciu, C. L., Ionaşcu, D., & Ionescu, B. E. (2021) · International Symposium on Signals, Circuits and Systems · doi:10.1109/isscs52333.2021.9497374 · Cited by 9
EgoPCA: A New Framework for Egocentric Hand-Object Interaction Understanding
Xu, Y., Li, Y., Huang, Z., Liu, M. X., Lu, C., Tai, Y., & Tang, C. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00486 · Cited by 9
mTVR: Multilingual Moment Retrieval in Videos
Lei, J., Berg, T. L., & Bansal, M. (2021) · doi:10.18653/v1/2021.acl-short.92 · Cited by 11
VTC: Improving Video-Text Retrieval with User Comments
Hanu, L., Thewlis, J., Asano, Y. M., & Rupprecht, C. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19833-5_36 · Cited by 9
RaP: Redundancy-aware Video-language Pre-training for Text-Video Retrieval
Wu, X., Gao, C., Lin, Z., Wang, Z., Han, J., & Hu, S. (2022) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2022.findings-emnlp.221 · Cited by 10
Ranking Distillation for Open-Ended Video Question Answering with Insufficient Labels
Liang, T., Tan, C., Xia, B., Zheng, W., & Hu, J. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01250 · Cited by 8
Rethinking Temporal Context in Video-QA: A Comprehensive Study of Single-Frame Static Bias
Liang, T., Li, L., Hu, J., Yu, X., Zheng, W., & Lai, J. (2025) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2025.3543031 · Cited by 8
Self-citationTC-MGC: Text-conditioned multi-grained contrastive learning for text–video retrieval
Jing, X., Yang, G., & Chu, J. (2025) · Information Fusion · doi:10.1016/j.inffus.2025.103151 · Cited by 8
Prototype-guided cross-task knowledge distillation
Li, D., Li, P., Wu, A., & Han, Y. (2025) · Frontiers of Information Technology & Electronic Engineering · doi:10.1631/fitee.2400383 · Cited by 12
Assorted Attention Network for Cross-Lingual Language-to-Vision Retrieval
Yu, T., Yang, Y., Fei, H., Li, Y., Chen, X., & Li, P. (2021) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3459637.3482233 · Cited by 8
Understanding Multimodal Procedural Knowledge by Sequencing Multimodal Instructional Manuals
Wu, T.-L., Spangher, A., Alipoormolabashi, P., Freedman, M., Weischedel, R., & Peng, N. (2022) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2022.acl-long.310 · Cited by 11
Video Question Answering Using Clip-Guided Visual-Text Attention
Ye, S., Kong, W., Yao, C., Ren, J., & Jiang, X. (2023) · Proceedings - International Conference on Image Processing · doi:10.1109/icip49359.2023.10222286 · Cited by 10
Efficient Spatio-Temporal Video Grounding with Semantic-Guided Feature Decomposition
Wang, W., Liu, J., Su, Y., & Nie, W. (2023) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3581783.3612441 · Cited by 8
Self-citationEgoTV: Egocentric Task Verification from Natural Language Task Descriptions
Hazra, R., Chen, B., Rai, A., Kamra, N., & Desai, R. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01414 · Cited by 12
Multimodal Distillation Pre-Training Model for Ultrasound Dynamic Images Annotation
Chen, X., Jia, K., Zhang, Y., Gou, J., Shen, A., & Wan, S. (2024) · IEEE Journal of Biomedical and Health Informatics · doi:10.1109/jbhi.2024.3438254 · Cited by 8
EA-VTR: Event-Aware Video-Text Retrieval
Ma, Z., Zhang, Z., Chen, Y., Qi, Z., Yuan, C., Li, B., Luo, Y., Li, X., Qi, X., Shan, Y., et al. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-72943-0_5 · Cited by 12
Self-citationTextomics: A Dataset for Genomics Data Summary Generation
Wang, M., Liu, Z., & Wang, S. (2022) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2022.acl-long.335 · Cited by 8
Lialin, V., Rawls, S., Chan, D., Ghosh, S., Rumshisky, A., & Hamza, W. (2023) · IEEE/CVF Winter Conference on Applications of Computer Vision Workshops (WACVW) · doi:10.1109/wacvw58289.2023.00043 · Cited by 8
Knowledge-Constrained Answer Generation for Open-Ended Video Question Answering
Jin, Y., Niu, G., Xiao, X., Zhang, J., Peng, X., & Yu, J. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i7.25983 · Cited by 8
Towards temporal sentence grounding in videos
Zhang, H. (2022) · doi:10.32657/10356/163788 · Cited by 8
Foundation Models for Video Understanding: A SurveyPreprint
Madan, N., Møgelmose, A., Modi, R., Rawat, Y. S., & Moeslund, T. B. (2024) · doi:10.36227/techrxiv.171769139.99464428/v2 · Cited by 11
TEVL: Trilinear Encoder for Video-language Representation Learning
Man, X., Shao, J., Chen, F., Zhang, M., & Shen, H. T. (2023) · ACM Transactions on Multimedia Computing Communications and Applications · doi:10.1145/3585388 · Cited by 8
Reading Between the Lanes: Text VideoQA on the Road
Tom, G., Mathew, M., Garcia-Bordils, S., Karatzas, D., & Jawahar, C. V. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-41731-3_9 · Cited by 17
Stitching Segments and Sentences towards Generalization in Video-Text Pre-training
Ma, F., Jin, X., Wang, H., Huang, J., Zhu, L., & Yang, Y. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i5.28202 · Cited by 7
Instruct-ReID++: Towards Universal Purpose Instruction-Guided Person Re-Identification
He, W., Deng, Y., Yan, Y., Zhu, F., Wang, Y., Bai, L., Xie, Q., Zhao, R., Qi, D., Ouyang, W., et al. (2025) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2025.3538766 · Cited by 7
MultiModal Language Modelling on Knowledge Graphs for Deep Video Understanding
Anand, V., Ramesh, R., Jin, B., Wang, Z., Lei, X., & Lin, C. (2021) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3474085.3479220 · Cited by 7
DeepRide: Dashcam Video Description Dataset for Autonomous Vehicle Location-Aware Trip Description
Rafiq, G., Rafiq, M. T., On, B.-W., Sung, M., & Choi, G. S. (2022) · IEEE Access · doi:10.1109/access.2022.3212745 · Cited by 7
Zero-Shot and Few-Shot Video Question Answering with Multi-Modal Prompts
Engin, D., & Avrithis, Y. (2023) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw60793.2023.00298 · Cited by 10
Ko, D., Lee, J. S., Choi, M., Chu, J., Park, J., & Kim, H. J. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00288 · Cited by 8
A CLIP-Enhanced Method for Video-Language UnderstandingPreprint
Li, G., He, F., & Feng, Z. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2110.07137 · Cited by 7
SgLFT: Semantic-guided Late Fusion Transformer for video corpus moment retrieval
Chen, T., Wang, W., Zhao, M., Li, R., Jiang, Z., & Yu, C. (2024) · Neurocomputing · doi:10.1016/j.neucom.2024.128029 · Cited by 6
Querying as Prompt: Parameter-Efficient Learning for Multimodal Language Model
Liang, T., Huang, J., Kong, M. C., Chen, L., & Zhu, Q. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.02536 · Cited by 7
Enhancing Text-Video Retrieval Performance With Low-Salient but Discriminative Objects
Zheng, Y., Huang, B., Chen, Z., & Yu, D. (2025) · IEEE Transactions on Image Processing · doi:10.1109/tip.2025.3527369 · Cited by 6
SHE-Net: Syntax-Hierarchy-Enhanced Text-Video Retrieval
Yu, X., Jiang, C., Dong, X., Gan, T., Yang, M., & Guo, Q. (2025) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2025.3543840 · Cited by 6
Data-driven personalisation of television content: a survey
Nixon, L. J. B., Foss, J., Apostolidis, K., & Mezaris, V. (2022) · Multimedia Systems · doi:10.1007/s00530-022-00926-6 · Cited by 7
PSAM: Parameter-Free Spatiotemporal Attention Mechanism for Video Question Answering
Zhang, F., Wang, R., Zhou, F., Luo, Y., & Li, J. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3333192 · Cited by 6
Learning Feature Semantic Matching for Spatio-Temporal Video Grounding
Zhang, T., Fang, H., Zhang, H., Gao, J., Lu, X., Nie, X., & Yin, Y. (2024) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2024.3387696 · Cited by 7
Interactive Video Corpus Moment Retrieval using Reinforcement Learning
Ma, Z., & Ngo, C. (2022) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3503161.3548277 · Cited by 6
Research Progress on Vision–Language Multimodal Pretraining Model Technology
Wang, H., Huang, R., & Zhang, J. (2022) · Electronics · doi:10.3390/electronics11213556 · Cited by 6
Bilaterally Slimmable Transformer for Elastic and Efficient Visual Question Answering
Zhou, Y., Jin, Z., Yu, J., Xu, M., Wang, H., & Jianping Fan, B. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3254205 · Cited by 6
Exploring TV Seriality and Television Studies through Data-Driven Approaches
Esposti, M. D., & Pescatore, G. (2023) · doi:10.21428/93b7ef64.ec022085 · Cited by 7
STOA-VLP: Spatial-Temporal Modeling of Object and Action for Video-Language Pre-training
Zhong, W., Zheng, M. S., Tang, D., Luo, X., Gong, H., Feng, X., & Qin, B. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i3.25483 · Cited by 6
Li, M., Shi, X., Leng, H., Zhou, W. G., Zheng, H.-T., & Zhang, K. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i1.25222 · Cited by 7
MemBridge: Video-Language Pre-Training With Memory-Augmented Inter-Modality Bridge
Yang, J., Li, X., Zheng, M., Wang, Z., Zhu, Y., Guo, X., Yuan, Y., Chai, Z., & Jiang, S. (2023) · IEEE Transactions on Image Processing · doi:10.1109/tip.2023.3283916 · Cited by 6
Attentive Snippet Prompting for Video Retrieval
Chen, S., Xu, Q., Ma, Y., Qiao, Y., & Wang, Y. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3321503 · Cited by 9
Exploring Temporal Concurrency for Video-Language Representation Learning
Zhang, H., Liu, D., Lv, Z., Su, B., & Tao, D. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01427 · Cited by 6
Lv, G., Sun, Y., & Nian, F. (2024) · Multimedia Systems · doi:10.1007/s00530-023-01205-8 · Cited by 6
YTCommentQA: Video Question Answerability in Instructional Videos
Yang, S., Park, S., Jang, Y., & Lee, M. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i17.29906 · Cited by 11
Detours for Navigating Instructional Videos
Ashutosh, K., Xue, Z., Nagarajan, T., & Grauman, K. L. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01779 · Cited by 7
Weakly-Supervised Moment Retrieval Network for Video Corpus Moment Retrieval
Yoon, S., Kim, D., Hong, J. W., Kim, J., Kim, K., & Yoo, C. D. (2021) · Proceedings - International Conference on Image Processing · doi:10.1109/icip42928.2021.9506218 · Cited by 7
Tencent-MVSE: A Large-Scale Benchmark Dataset for Multi-Modal Video Similarity Evaluation
Zeng, Z., Luo, Y., Liu, Z., Rao, F., Li, D., Guo, W., & Wen, Z. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00314 · Cited by 7
CNVid-3.5M: Build, Filter, and Pre-Train the Large-Scale Public Chinese Video-Text Dataset
Gan, T., Wang, Q., Dong, X., Ren, X., Nie, L., & Guo, Q. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01423 · Cited by 6
CUPID: Adaptive Curation of Pre-training Data for Video-and-Language Representation LearningPreprint
Zhou, L., Liu, J., Yu, C., Gan, Z., & Zhang, L. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2104.00285 · Cited by 8
Self-citationM5Product: A Multi-modal Pretraining Benchmark for E-commercial Product Downstream TasksPreprint
Dong, X. M., Zhan, X., Wu, Y., Wei, Y., & Liang, X. (2021) · arXiv (Cornell University) · doi:10.13140/rg.2.2.35620.81281 · Cited by 6
End-to-End Open-Vocabulary Video Visual Relationship Detection Using Multi-Modal Prompting
Wang, Y., Wu, X., Yang, S., & Luo, J. (2025) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2025.3561366 · Cited by 5
Nguyen-Nhu, T.-A., Tran, H.-L., Le, N.-K., Nguyen, M.-N., Nguyen, T.-H., Nguyen-Huu, H.-L., Phan-Nguyen, H.-P., Pham, H.-T., Nguyen, Q., Le, H. M., et al. (2025) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw67362.2025.00356 · Cited by 5
Language-aware Visual Semantic Distillation for Video Question Answering
Zou, B., Chao, Y., Qiao, Y., Quan, C., & Zhao, Y. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.02560 · Cited by 9
ReCLIP++: Learn to Rectify the Bias of CLIP for Unsupervised Semantic Segmentation
Wang, J., & Kang, G. (2025) · International Journal of Computer Vision · doi:10.1007/s11263-025-02566-5 · Cited by 5
Cascaded MPN: Cascaded Moment Proposal Network for Video Corpus Moment Retrieval
Yoon, S., Kim, D., Kim, J., & Yoo, C. D. (2022) · IEEE Access · doi:10.1109/access.2022.3183106 · Cited by 5
Video question answering supported by a multi-task learning objective
Falcon, A., Serra, G., & Lanz, O. (2023) · Multimedia Tools and Applications · doi:10.1007/s11042-023-14333-0 · Cited by 5
Dong, X., Guo, Q., Gan, T., Wang, Q., Wu, J., Ren, X., Cheng, Y., & Chu, W. (2023) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2023.3303945 · Cited by 5
Self-citationT2V2T: Text-to-Video-to-Text Fusion for Text-to-Video Retrieval
Kim, J., Lee, Y., & Moon, J. (2023) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw59228.2023.00594 · Cited by 5
Chinese Title Generation for Short Videos: Dataset, Metric and Algorithm
Zhang, Z., Ma, Z., Yuan, C., Chen, Y., Wang, P., Qi, Z., Hao, C., Li, B., Shan, Y., Hu, W., et al. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3365739 · Cited by 6
Self-citationMulti-Modal Prompting for Open-Vocabulary Video Visual Relationship Detection
Yang, S., Wang, Y., Ji, X., & Wu, X. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i7.28472 · Cited by 5
Exploiting Instance-level Relationships in Weakly Supervised Text-to-Video Retrieval
Yin, S., Zhao, S., Wang, H., Xu, T., & Chen, E. (2024) · ACM Transactions on Multimedia Computing Communications and Applications · doi:10.1145/3663571 · Cited by 5
Show, Think, and Tell: Thought-Augmented Fine-Tuning of Large Language Models for Video Captioning
Kim, B., Hwang, D., Cho, S., Jang, Y., Lee, H., & Lee, M. (2024) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw63382.2024.00187 · Cited by 5
Multi-scale Multi-modal Dictionary BERT For Effective Text-image Retrieval in Multimedia Advertising
Yu, T., Liu, J., Jin, Z., Yang, Y., Fei, H., & Li, P. (2022) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3511808.3557653 · Cited by 5
Self-citationDense but Efficient VideoQA for Intricate Compositional Reasoning
Lee, J., Kang, W., & Kim, E. (2023) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv56688.2023.00117 · Cited by 5
RewardTLG: Learning to Temporally Language Grounding from Flexible Reward
YaWen, Z., Pan, K., & Han, N. (2023) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3539618.3592054 · Cited by 5
Grafting Pre-trained Models for Multimodal Headline Generation
Qiao, L., Wu, C., Liu, Y., Peng, H., Yin, D., & Ren, B. (2022) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2022.emnlp-industry.25 · Cited by 5
INQUIRER: Harnessing internal knowledge graphs for video question generation
Choi, W. S., Jang, Y., Lee, M., & Zhang, B. (2025) · Knowledge-Based Systems · doi:10.1016/j.knosys.2025.114033 · Cited by 4
HOVER: Hyperbolic Video-Text Retrieval
Wen, J., Chen, Y., Shi, R., Ji, W., Yang, M., Gao, D., Yuan, J., & Zimmermann, R. (2025) · IEEE Transactions on Image Processing · doi:10.1109/tip.2025.3611174 · Cited by 4
Self-citationEmotion-Aware Multimodal Pre-training for Image-Grounded Emotional Response Generation
Tian, Z., Wen, Z., Wu, Z., Song, Y., Tang, J., Li, D., & Zhang, N. L. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-00129-1_1 · Cited by 4
Hierarchical3D Adapters for Long Video-to-text Summarization
Papalampidi, P., & Lapata, M. (2023) · Findings of the Association for Computational Linguistics: EACL · doi:10.18653/v1/2023.findings-eacl.96 · Cited by 7
No Head Left Behind – Multi-Head Alignment Distillation for Transformers
Zhao, T., Singh, K. Y., Appalaraju, S., Tang, P., Mahadevan, V., Manmatha, R., & Wu, Y. N. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i7.28583 · Cited by 6
Lee, J.-H., & Kang, J. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01299 · Cited by 4
Hong, X., Adam, T., & Ghazali, M. (2025) · Image and Vision Computing · doi:10.1016/j.imavis.2025.105628 · Cited by 4
Focus and Align: Learning Tube Tokens for Video-Language Pre-Training
Zhu, Y., Li, X., Zheng, M., Yang, J., Wang, Z., Guo, X., Chai, Z., Yuan, Y., & Jiang, S. (2022) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2022.3231108 · Cited by 4
CMMT: Cross-Modal Meta-Transformer for Video-Text Retrieval
Gao, Y., & Lu, Z. (2023) · International Conference on Multimedia Retrieval · doi:10.1145/3591106.3592238 · Cited by 4
Rafiq, G., Rafiq, M. T., & Choi, G. S. (2023) · IEEE Access · doi:10.1109/access.2023.3287783 · Cited by 4
Vote’n’Rank: Revision of Benchmarking with Social Choice Theory
Rofin, M., Mikhailov, V., Florinsky, M., Kravchenko, A., Shavrina, T., Tutubalina, E. V., Самвелович, К. Д., & Artemova, E. (2023) · Conference of the European Chapter of the Association for Computational Linguistics · doi:10.18653/v1/2023.eacl-main.48 · Cited by 4
External Commonsense Knowledge as a Modality for Social Intelligence Question-Answering
Natu, S., Sural, S., & Sarkar, S. (2023) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw60793.2023.00327 · Cited by 4
Metadata
- Authors
- Li, L., Chen, Y.-C., Cheng, Y., Gan, Z., Yu, L., & Liu, J.
- Affiliations
- Microsoft (United States) (US)
- Venue
- Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP)
- Published
- 2020
- Pages
- 2046-2065
- OpenAlex
- W3105232955
- Cited by
- 408
- References
- 79
- Citations by year
- 2026: 17 · 2025: 49 · 2024: 67 · 2023: 129 · 2022: 87 · 2021: 52 · 2020: 7
- FWCI
- 21.21
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Human Pose and Action Recognition
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Video Analysis and Summarization
- Keywords
- multimodal representation learning, hierarchical encoder, cross-modal transformer, temporal transformer, video question answering, video retrieval, video captioning, video moment retrieval
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
