

The DOI matches its Crossref record; 79 of the 79 references it cites were found in a registry or an index.
HERO: Hierarchical Encoder for Video+Language Omni-representation Pre-training
Open accessAbstract
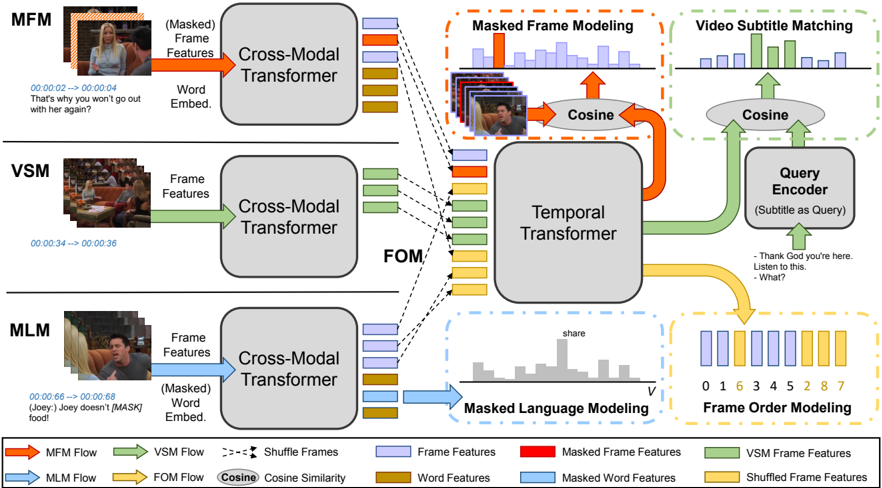
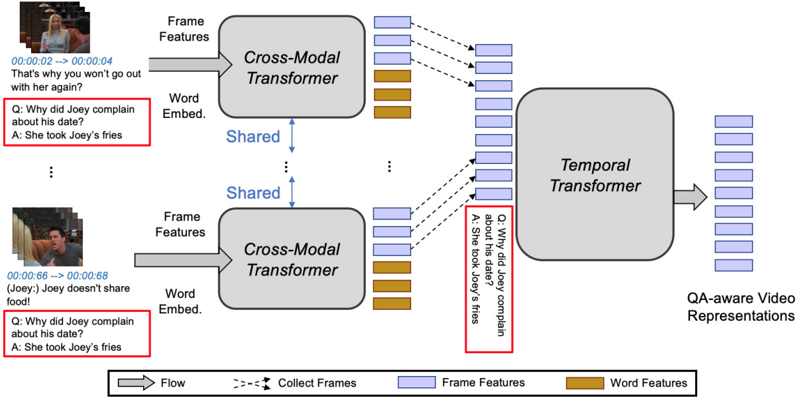
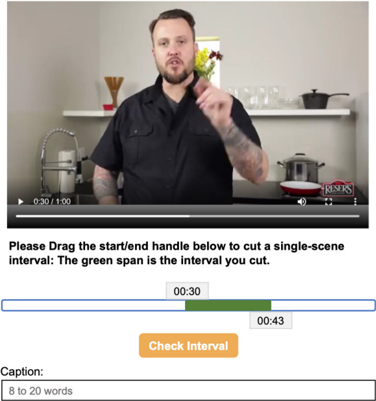
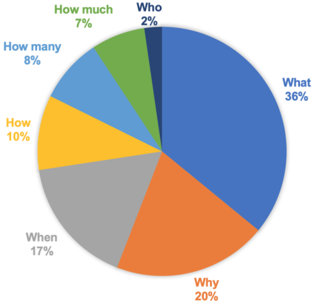
We present HERO, a novel framework for large-scale video+language omnirepresentation learning.HERO encodes multimodal inputs in a hierarchical structure, where local context of a video frame is captured by a Cross-modal Transformer via multimodal fusion, and global video context is captured by a Temporal Transformer.In addition to standard Masked Language Modeling (MLM) and Masked Frame Modeling (MFM) objectives, we design two new pre-training tasks: (i) Video-Subtitle Matching (VSM), where the model predicts both global and local temporal alignment; and (ii) Frame Order Modeling (FOM), where the model predicts the right order of shuffled video frames.HERO is jointly trained on HowTo100M and large-scale TV datasets to gain deep understanding of complex social dynamics with multi-character interactions.Comprehensive experiments demonstrate that HERO achieves new state of the art on multiple benchmarks over Text-based Video/Video-moment Retrieval, Video Question Answering (QA), Video-and-language Inference and Video Captioning tasks across different domains.We also introduce two new challenging benchmarks How2QA and How2R for Video QA and Retrieval, collected from diverse video content over multimodalities. 1
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“As demonstrated in Figure 2 in [192], the multimodal Transformer models have another architecture taxonomy based on the computational size of the components.”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
Experimental — accuracy not yet measuredIn the citing paper
“One simplifying is processing the visual input in convolution-free manner, e.g., E2E-VLP [271], ViLT [192].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Jakubův, J., Chvalovský, K., Goertzel, Z., et al. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,648
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
ImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333
Self-citationBERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
Decoupled Weight Decay Regularization
Loshchilov, I., & Hutter, F. (2017) · arXiv · doi:10.48550/arxiv.1711.05101 · Cited by 12,522
(2017) · Cited by 11,625
Research works printed but not linked: 4
- Lisa Anne Hendricks, Oliver Wang, Eli Shechtman, Josef Sivic, Trevor Darrell, and Bryan Russell. 2017b. Localizing moments in video with natural language. In CVPR.
- Myle Ott, Sergey Edunov, David Grangier, and Michael Auli. 2018. Scaling neural machine trans- lation. arXiv preprint arXiv:1806.00187. · arXiv
- Jun Xu, Tao Mei, Ting Yao, and Yong Rui. 2016b. Msr- vtt: A large video description dataset for bridging video and language. CVPR.
- Licheng Yu, Zhe Lin, Xiaohui Shen, Jimei Yang, Xin Lu, Mohit Bansal, and Tamara L Berg. 2018a. Mat- tnet: Modular attention network for referring expres- sion comprehension. In CVPR.
Cited by
Sorted by citations
Items 301–400 of 410
HiVLP: Hierarchical Interactive Video-Language Pre-Training
Shao, B., Liu, J., Pei, R., Xu, S., Dai, P., Lu, J., Li, W., & Yan, Y. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01265 · Cited by 4
Self-citationLiu, Y., Shen, T., Zhang, D., Sun, Q., Li, S., & Zhou, G. (2024) · International Conference on Multimedia Retrieval · doi:10.1145/3652583.3658094 · Cited by 4
CoCo-BERT: Improving Video-Language Pre-training with Contrastive Cross-modal Matching and DenoisingPreprint
Luo, J., Li, Y., Pan, Y., Yao, T., Chao, H., & Mei, T. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2112.07515 · Cited by 4
Cross-Modality Interaction-Based Traffic Accident Classification
Oh, C., & Ban, Y. (2024) · Applied Sciences · doi:10.3390/app14051958 · Cited by 3
Comment-Aware Multi-Modal Heterogeneous Pre-Training for Humor Detection in Short-Form Videos
Liu, Y., Ping, H., Zhang, D., Sun, Q., Li, S., & Zhou, G. (2023) · Frontiers in artificial intelligence and applications · doi:10.3233/faia230438 · Cited by 3
Survey of Dense Video Captioning: Techniques, Resources, and Future Perspectives
Liu, Z., & Song, R. (2025) · Applied Sciences · doi:10.3390/app15094990 · Cited by 3
Tran, H.-L., Nguyen-Nhu, T.-A., Phan-Nguyen, H.-P., Nguyen, T.-H., Nguyen-Dich, N.-M., Dao, A., Do, H.-D., Nguyen, Q., Le, H. M., & Dinh, Q.-V. (2025) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw67362.2025.00357 · Cited by 3
In Defense of Structural Symbolic Representation for Video Event-Relation Prediction
Lu, A., Lin, X., Niu, Y., & Chang, S. (2023) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw59228.2023.00522 · Cited by 3
MMTF: Multi-Modal Temporal Fusion for Commonsense Video Question Answering
Ahmad, M., Park, G., Park, D., & Park, S. (2023) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw60793.2023.00502 · Cited by 3
Multi-level video captioning method based on semantic space
Xiao, Y., Zeng, Y., Gu, M. J., Yuan, R., Li, J., & Ge, J. (2024) · Multimedia Tools and Applications · doi:10.1007/s11042-024-18372-z · Cited by 3
Generating Illustrated Instructions
Menon, S., Misra, I., & Girdhar, R. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00600 · Cited by 3
OVIS: Open-Vocabulary Visual Instance Search via Visual-Semantic Aligned Representation Learning
Liu, S., Lin, K., Wang, L., Yuan, J., & Liu, Z. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i2.20070 · Cited by 3
A Multi -level Alignment Training Scheme for Video-and-Language Grounding
Zhang, Y., Niu, F., Ping, Q., & Thattai, G. (2022) · IEEE ... International Conference on Data Mining workshops · doi:10.1109/icdmw58026.2022.00124 · Cited by 3
Shin, M., Mun, J., On, K.-W., Kang, W., Han, G., & Kim, E. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2110.06476 · Cited by 4
ATM: Action Temporality Modeling for Video Question Answering
Chen, J., Zhu, J., & Kong, Y. (2023) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3581783.3612509 · Cited by 2
Dynamic Tuning and Multi-Task Learning-Based Model for Multimodal Sentiment Analysis
Liang, Y., Tohti, T., Hu, W., Kong, B., Han, D., Yan, T., & Hamdulla, A. (2025) · Applied Sciences · doi:10.3390/app15116342 · Cited by 2
Robust Relevance Feedback for Interactive Known-Item Video Search
Ma, Z., & Ngo, C. (2025) · International Conference on Multimedia Retrieval · doi:10.1145/3731715.3733422 · Cited by 2
CoAVT: A Cognition-Inspired Unified Audio-Visual-Text Pre-Training Model for Multimodal Processing
Yue, X., Tian, X., Zhang, M., Wu, Z., & Li, H. (2025) · IEEE Transactions on Audio Speech and Language Processing · doi:10.1109/taslpro.2025.3587467 · Cited by 4
Video is Worth a Thousand Images: Exploring the Latest Trends in Long Video Generation
Waseem, F., & Shahzad, M. S. (2025) · ACM Computing Surveys · doi:10.1145/3771724 · Cited by 7
SFA: Scan, Focus, and Amplify toward guidance-aware answering for Video TextVQA
He, H., Zhong, Q., Liu, J., Du, B., Wang, P., & Zhang, J. (2026) · Pattern Recognition · doi:10.1016/j.patcog.2026.114009 · Cited by 2
Self-citationEnd-to-end Multi-task Learning Framework for Spatio-Temporal Grounding in Video Corpus
Gao, Y., Luo, Z., Chen, S., & Zhou, W. (2022) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3511808.3557596 · Cited by 2
Shot Retrieval and Assembly with Text Script for Video Montage Generation
Yang, G., Lu, H., Sun, Z., & Lu, Z. (2023) · International Conference on Multimedia Retrieval · doi:10.1145/3591106.3592247 · Cited by 2
MuMUR: Multilingual Multimodal Universal Retrieval
Madasu, A., Aflalo, E., Stan, G. B. M., Rosenman, S., Tseng, S.-Y., Bertasius, G., & Lal, V. (2023) · Information Retrieval · doi:10.1007/s10791-023-09422-5 · Cited by 2
ART: rule bAsed futuRe-inference deducTion
Li, M., Zhao, T., Jionghao, B., He, B., Miao, J., Ji, W., Lv, Z., Zhao, Z., Zhang, S., Zhang, W., et al. (2023) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2023.emnlp-main.592 · Cited by 2
In-Style: Bridging Text and Uncurated Videos with Style Transfer for Text-Video Retrieval
Shvetsova, N., Kukleva, A., Schiele, B., & Kuehne, H. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.02009 · Cited by 2
DI-VTR: Dual inter-modal interaction model for video-text retrieval
Guo, J., Wang, M., Wang, W., Zhou, Y., & Song, B. (2024) · Journal of Information and Intelligence · doi:10.1016/j.jiixd.2024.03.003 · Cited by 2
Komatsu, T., Kambara, M., Hatanaka, S., Matsuo, H., Hirakawa, T., Yamashita, T., Fujiyoshi, H., & Sugiura, K. (2024) · Advanced Robotics · doi:10.1080/01691864.2024.2388114 · Cited by 2
Learning Video Context as Interleaved Multimodal Sequences
Lin, K. Q., Zhang, P., Gao, D., Xia, X., Chen, J., Gao, Z., Xie, J., Xiao, X., & Shou, M. Z. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-72967-6_21 · Cited by 5
Dam: Dynamic Adapter Merging for Continual Video QA Learning
Cheng, F., Wang, Z., Sung, Y.-L., Lin, Y.-B., Bansal, M., & Bertasius, G. (2025) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61041.2025.00662 · Cited by 2
Perceive. Query & Reason: Enhancing Video QA with Question-Guided Temporal Queries
Amoroso, R., Zhang, G., Koner, R., Baraldi, L., Cucchiara, R., & Volker Tresp, C. (2025) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv61041.2025.00858 · Cited by 2
LvBench: A Benchmark for Long-form Video Understanding with Versatile Multi-modal Question Answering
Zhang, H., Dong, L., Liu, Y., Huang, Y., Wang, L., Wang, L., & Qiao, Y. (2025) · International Journal of Computer Vision · doi:10.1007/s11263-025-02555-8 · Cited by 48
Liu, H., Jiang, S., Duan, F., Lyu, Y., Wang, X., Ge, H., & Liang, C. (2025) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw67362.2025.00353 · Cited by 2
A Multi-modal System for Video Semantic Understanding
Lv, Z., Lei, T., Liang, X., Shi, Z., & Liu, D. (2022) · Communications in computer and information science · doi:10.1007/978-981-19-0713-5_5 · Cited by 2
Relation Enhanced Vision Language Pre-Training
Lee, J.-H., & Kang, J. (2022) · Proceedings - International Conference on Image Processing · doi:10.1109/icip46576.2022.9897623 · Cited by 2
SST-VLM: Sparse Sampling-Twice Inspired Video-Language Model
Gao, Y., & Lu, Z. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-26316-3_32 · Cited by 2
Barotsi, R., Fanchi, M., & Tarantino, M. (2023) · doi:10.21428/93b7ef64.ddf0a578 · Cited by 2
Fill-in-the-blank as a Challenging Video Understanding Evaluation Framework.Preprint
Castro, S., Wang, R., Huang, P., Stewart, I., Liu, N., Stroud, J., & Mihalcea, R. F. (2021) · arXiv (Cornell University) · Cited by 2
Maeoki, S., Mukuta, Y., & Harada, T. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2106.13566 · Cited by 3
ViSeRet: A simple yet effective approach to moment retrieval via fine-grained video segmentationPreprint
Lee, A. S., Oh, H., & Seo, M. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2110.05146 · Cited by 2
Enhanced visual multi-modal fusion framework for dense video captioningPreprint
Zhong, R., Zhang, Q., & Zuo, M. (2023) · Research Square · doi:10.21203/rs.3.rs-2563235/v1 · Cited by 2
Temporal-aware Mechanism with Bidirectional Complementarity for Video Q&A
Luo, Y., Wang, R., Zhang, F., Zhou, F., & Lin, S. (2022) · Conference proceedings/Conference proceedings - IEEE International Conference on Systems, Man, and Cybernetics · doi:10.1109/smc53654.2022.9945377 · Cited by 1
CMFG: Cross-Model Fine-Grained Feature Interaction for Text-Video Retrieval
Zhao, S., Liu, Y., Du, S., Tian, Z., Qu, T., & Xu, L. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-27818-1_36 · Cited by 1
KnowER: Knowledge enhancement for efficient text-video retrieval
Kou, H., Yang, Y., & Yan, H. (2023) · Intelligent and Converged Networks · doi:10.23919/icn.2023.0009 · Cited by 1
Fighting FIRe with FIRE: Assessing the Validity of Text-to-Video Retrieval Benchmarks
Rodríguez, P., Azab, M., Silvert, B., Sanchez, R., Labson, L., Shah, H., & Moon, S. (2023) · Findings of the Association for Computational Linguistics: EACL · doi:10.18653/v1/2023.findings-eacl.3 · Cited by 4
ADEM-VL: Adaptive and Embedded Fusion for Efficient Vision-Language Tuning
Hao, Z., Guo, J., Shen, L., Luo, Y., Hu, H., & Wen, Y. (2025) · International Journal of Computer Vision · doi:10.1007/s11263-025-02440-4 · Cited by 5
Xiang, T., Lyu, P., Xu, R., Hao, J., Song, H., & Cheng, S. (2025) · IEEE Sensors Journal · doi:10.1109/jsen.2025.3574155 · Cited by 1
A Flexible and Scalable Framework for Video Moment Search
Zhang, C., Zhu, X., & Sun, A. (2025) · Annual International ACM SIGIR Conference on Research and Development in Information Retrieval in the Asia Pacific Region (SIGIR-AP) · doi:10.1145/3767695.3769480 · Cited by 3
Event-Aware Video Corpus Moment Retrieval
Hou, D., Pang, L., Yanyan, L., Shen, H., & Cheng, X. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-21289-4_1 · Cited by 1
CLOP: Video-and-Language Pre-Training with Knowledge Regularizations
Li, G., Yang, H., He, F., Feng, Z., Lyu, Y., Wu, H. R., & Wang, H. (2022) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3503161.3548346 · Cited by 1
Inferential Knowledge-Enhanced Integrated Reasoning for Video Question Answering
Mao, J., Jiang, W., Liu, H., Wang, X., & Lyu, Y. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i11.26570 · Cited by 1
CSA-BERT: Video Question Answering
Jenni, K., Srinivas, M., Sannapu, R., & Perumal, M. (2023) · IEEE Statistical Signal Processing Workshop (SSP) · doi:10.1109/ssp53291.2023.10207954 · Cited by 2
CapFormer: A Space-Time Video Description Model using Joint-Attention Transformer
Moussa, M., Lim, C. H., & Wong, K. (2023) · Asia-Pacific Signal and Information Processing Association Annual Summit and Conference (APSIPA ASC) · doi:10.1109/apsipaasc58517.2023.10317466 · Cited by 1
Dataset Bias Mitigation in Multiple-Choice Visual Question Answering and Beyond
Wang, Z., Chen, L., You, H., Xu, K., He, Y., Li, W., Codella, N., Chang, K.-W., & Chang, S. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.576 · Cited by 4
Gao, Y. F., Xu, T., & Chen, E. (2024) · IFIP advances in information and communication technology · doi:10.1007/978-3-031-57808-3_12 · Cited by 1
Fang, J. Z., Zheng, S., Sharma, V., & Piramuthu, R. (2024) · IEEE/CVF Winter Conference on Applications of Computer Vision Workshops (WACVW) · doi:10.1109/wacvw60836.2024.00062 · Cited by 1
Research and Application of Multimodal Data Fusion Technology for Oil and Gas Pipelines
Jia, S. (2024) · IEEE International Conference on Control, Electronics and Computer Technology (ICCECT) · doi:10.1109/iccect60629.2024.10545908 · Cited by 1
LocoMotion: Learning Motion-Focused Video-Language Representations
Doughty, H., Thoker, F. M., & Snoek, C. G. M. (2024) · Lecture notes in computer science · doi:10.1007/978-981-96-0908-6_1 · Cited by 1
A Multimodal Hierarchical Attentional Ordering Network
Yang, Y., Cui, B., & Li, Y. (2025) · ACM Transactions on Multimedia Computing Communications and Applications · doi:10.1145/3711864 · Cited by 2
SparrowVQE: Visual Question Explanation for Course Content Understanding
Li, J., Thota, M. K., Gokhman, R., Holik, R., & Zhang, Y. (2024) · IEEE International Conference on Big Data (BigData) · doi:10.1109/bigdata62323.2024.10825179 · Cited by 1
Efficient Integration of ASR with Large Language Models to Enhance Video Search at Scale
Zhang, Q., Xiao, F., Li, T., Lin, L., Fang, H., Sun, H., Liu, R., Zhu, X., & Wang, J. (2025) · International World Wide Web Conference (WWW) · doi:10.1145/3701716.3715220 · Cited by 1
ActPrompt: In-Domain Feature Adaptation via Action Cues for Video Temporal Grounding
Wang, Y., Jiang, X., Cheng, D., Li, D., & Zhao, C. (2026) · IEEE Transactions on Image Processing · doi:10.1109/tip.2026.3671609 · Cited by 5
Ghorbani, S., Gaur, Y., Shi, Y., & Li, J. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2011.04084 · Cited by 1
Coarse to Fine: Video Retrieval before Moment LocalizationPreprint
Gao, Z., Liu, H., & Liu, J. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2110.07201 · Cited by 1
Self-citationVideo in 10 Bits: Few-Bit VideoQA for Efficiency and Privacy
Huang, S., Piramuthu, R., Chang, S., & Sigurdsson, G. A. (2023) · Lecture notes in computer science · doi:10.1007/978-3-031-25072-9_49
Weight-based multi-stream model for Multi-Modal Video Question Answering
Rajesh, M., Sridhar, S., Kulkarni, C., Shah, A., & Natarajan, S. (2023) · Proceedings of the ... International Florida Artificial Intelligence Research Society Conference · doi:10.32473/flairs.36.133306
Cross-modal representation learning and generation
Liu, H., Chen, J., Li, L., Bao, B., Li, Z., Liu, J., & Nie, L. (2023) · Journal of Image and Graphics · doi:10.11834/jig.230035 · Cited by 1
Self-citationYang, X., & Yang, C. H. (2023) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2023.findings-acl.600
Recombination Samples Training for Robust Natural Language Visual Reasoning
Jiang, Y., Zhao, Y., & Bao, B. (2023) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme55011.2023.00103
Mulan: A Multi-Level Alignment Model for Video Question Answering
Fu, Y., Cao, C., Yang, Y., Lu, Y., Yuan, F., Wang, D., & Liu, Y. (2023) · Findings of the Association for Computational Linguistics: EMNLP (Findings of EMNLP) · doi:10.18653/v1/2023.findings-emnlp.364
Video-and-Language (VidL) models and their cognitive relevance
Zonneveld, A. W., Albert Gatt, A., & Calixto, I. (2023) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw60793.2023.00040
Souza, A., Kim, J., & Moon, J. (2023) · SSRN Electronic Journal · doi:10.2139/ssrn.4676351
Implicit Affordance Acquisition via Causal Action–Effect Modeling in the Video Domain
Yang, H.-Y., & Silberer, C. (2023) · International Joint Conference on Natural Language Processing and Conference of the Asia-Pacific Chapter of the Association for Computational Linguistics (IJCNLP-AACL) · doi:10.18653/v1/2023.ijcnlp-main.55 · Cited by 1
IMF-MF: Interactive moment localization with adaptive multimodal fusion and self-attention
Singh, P., Kushwaha, A. K. S., & Varshney, N. (2024) · Journal of Intelligent & Fuzzy Systems · doi:10.3233/jifs-233071
Efficient text augmentation in latent space for video retrieval
Lee, N., Kang, S.-M., & Cho, Y.-S. (2024) · Multimedia Tools and Applications · doi:10.1007/s11042-024-20320-w
Meta-optimized Angular Margin Contrastive Framework for Video-Language Representation Learning
Nguyen, T. T., Bin, Y., Wu, X., Dong, X., Hu, Z., Le, K., Nguyen, C.-D. T., Ng, S.-K., & Tuan, L. A. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-72989-8_5
Label Text-aided Hierarchical Semantics Mining for Panoramic Activity Recognition
Liu, T., Lam, K., & Bao, B. (2024) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3664647.3681329
Self-expressive induced clustered attention for video-text retrieval
Zhu, J., Shen, X., Mehta, S., Abeo, T. A., & Zhan, Y. (2024) · Multimedia Systems · doi:10.1007/s00530-024-01549-9
Learning Temporally Composable Task Segmentations with Language
Raj, D., Patil, O. R., Gu, W., Baral, C. R., & Gopalan, N. (2024) · IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS) · doi:10.1109/iros58592.2024.10802712
Moment-Aware Video Retrieval for Video Corpus Moment Retrieval
Choi, Y., Ahn, D., & Choi, J. (2025) · IEEE Access · doi:10.1109/access.2025.3542720
Dialogue-to-Video Retrieval via Multi-Grained Attention Network
Yu, Y., Zhang, J., Tang, S., & Li, W. (2025) · IEEE Access · doi:10.1109/access.2025.3567086
Moon, J., Seol, M., & Kim, J. (2025) · Lecture notes in computer science · doi:10.1007/978-3-031-91581-9_21
Weakly-Supervised Multimodal Video Pre-Training via Image-Caption Pseudo-LabelingPreprint
Rhodes, C., Marwood, E., & Hale, J. (2025) · Preprints.org · doi:10.20944/preprints202506.2276.v1
HCFMN: Hierarchical Cross-Modal Fine-Grained Mining Network for Temporal Sentence Grounding
Ran, R., Wei, J., Zhou, Y., Guan, X., Yang, Y., & Shen, H. T. (2025) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2025.3586156
Key-semantics Alignment Learning with Contextual Understanding for Video Moment Retrieval
Gao, C., Li, M., Ren, J., Chen, L., Fu, J., & Su, W. (2025) · IEEE International Conference on Multimedia and Expo (ICME) · doi:10.1109/icme59968.2025.11209958
Hierarchical RAG-Driven Multi-hop Reasoning for Medical Video Question Answering
Gao, R., Zhao, Q., & Chen, Y. (2025) · Lecture notes in computer science · doi:10.1007/978-981-95-3352-7_34
Self-citationWang, X., Lan, X., & Zhu, W. (2025) · Springer eBooks · doi:10.1007/978-3-031-94837-4_1
Wang, X., Lan, X., & Zhu, W. (2025) · Springer eBooks · doi:10.1007/978-3-031-94837-4_3
Basics and Advances of Video Grounding
Wang, X., Lan, X., & Zhu, W. (2025) · Springer eBooks · doi:10.1007/978-3-031-94837-4_2
Video Captioning using Deep Learning with Greedy Search (VCDLGS)
Farag, M. A., Khafagy, M. H., & Hussien, S. A. (2026) · Franklin Open · doi:10.1016/j.fraope.2026.100497
Kruthika, C. G., Gagana, B. R., & Namithadevi, N. N. (2025) · IEEE Global Conference for Advancement in Technology (GCAT) · doi:10.1109/gcat66372.2025.11368428
DRGI: Disentangled Representation Graph Infomax for Video Retrieval
Kang, S.-M., Lee, N.-H., Park, J. H., & Cho, Y.-S. (2026) · IEEE Access · doi:10.1109/access.2026.3662719
Multimodal fusion and knowledge enhancement for accurate video captioning
Zhong, R., Zhang, Q., Li, H., & Zuo, M. (2026) · The Journal of Supercomputing · doi:10.1007/s11227-026-08284-0
Video Retrieval Using GAT Enhanced CLIP Model
Adil, M., Akhtar, N., Shoaib, H., & Khan, S. M. S. (2025) · IEEE International Conference on Recent Advances in Computing and Systems (REACS) · doi:10.1109/reacs67479.2025.11413305
Towards automatic understanding of narrative audiovisual content
Reboud, A. (2022) · theses.fr (ABES) · doi:10.70675/7b1296fez9f91z4484z8448z8040d28ab833
Une Approche Collaborative pour la Classification des Sites Web
Koufi, M. Z. (2024) · theses.fr (ABES) · doi:10.70675/1c35c522z32c3z4c0aza5eaz331e61ba1cd3
Video question answering with limited supervision
Engin, D. (2024) · theses.fr (ABES) · doi:10.70675/c9c7dcf2z4ca3z4e91z9d27zdacd00f76581
Multimodal deep learning for audiovisual production
Ouenniche, K. (2023) · theses.fr (ABES) · doi:10.70675/a01becf4z4ed9z4955z940cz49c821c1b8a8
Study of the multimodal understanding of vision-language transformer models
Salin, E. (2023) · theses.fr (ABES) · doi:10.70675/2beca704z5d3bz421dzbf61z61e00610aaeb
APT: A Two-Stage Image-Video Transfer Learning for Video Retrieval
Kang, S.-M., & Cho, Y.-S. (2026) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2026.3687737
Metadata
- Authors
- Li, L., Chen, Y.-C., Cheng, Y., Gan, Z., Yu, L., & Liu, J.
- Affiliations
- Microsoft (United States) (US)
- Venue
- Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP)
- Published
- 2020
- Pages
- 2046-2065
- OpenAlex
- W3105232955
- Cited by
- 408
- References
- 79
- Citations by year
- 2026: 17 · 2025: 49 · 2024: 67 · 2023: 129 · 2022: 87 · 2021: 52 · 2020: 7
- FWCI
- 21.21
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Human Pose and Action Recognition
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Video Analysis and Summarization
- Keywords
- multimodal representation learning, hierarchical encoder, cross-modal transformer, temporal transformer, video question answering, video retrieval, video captioning, video moment retrieval
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
