

The DOI matches its Crossref record; 79 of the 79 references it cites were found in a registry or an index.
HERO: Hierarchical Encoder for Video+Language Omni-representation Pre-training
Open accessAbstract
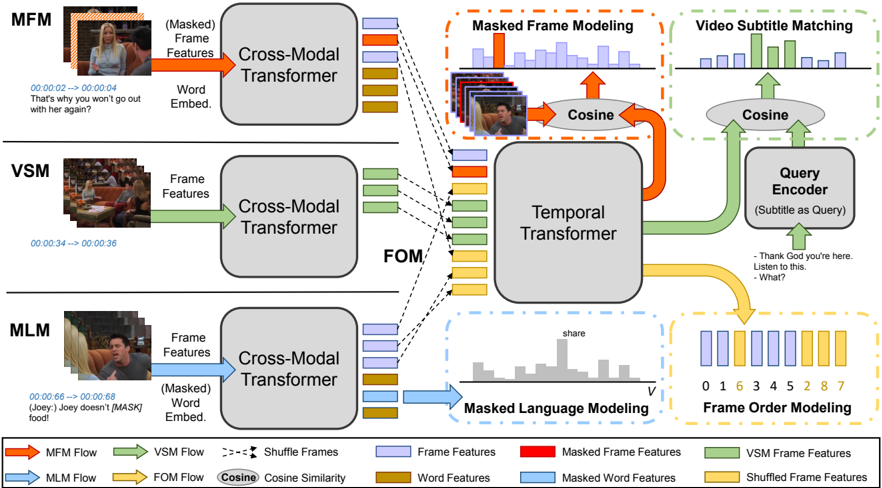
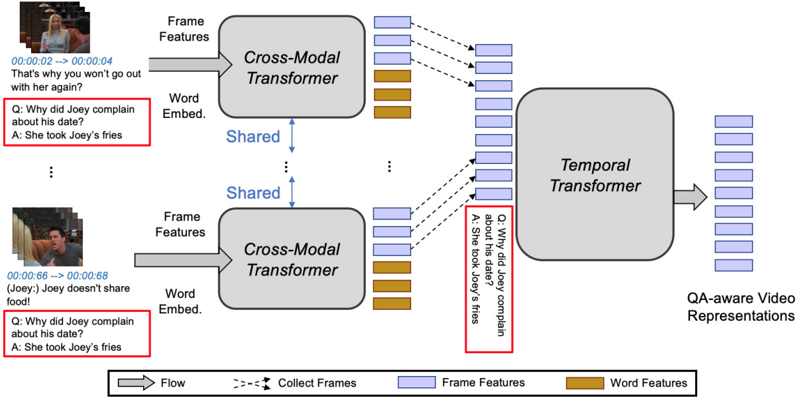
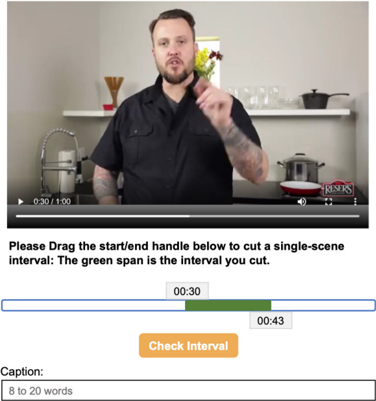
We present HERO, a novel framework for large-scale video+language omnirepresentation learning.HERO encodes multimodal inputs in a hierarchical structure, where local context of a video frame is captured by a Cross-modal Transformer via multimodal fusion, and global video context is captured by a Temporal Transformer.In addition to standard Masked Language Modeling (MLM) and Masked Frame Modeling (MFM) objectives, we design two new pre-training tasks: (i) Video-Subtitle Matching (VSM), where the model predicts both global and local temporal alignment; and (ii) Frame Order Modeling (FOM), where the model predicts the right order of shuffled video frames.HERO is jointly trained on HowTo100M and large-scale TV datasets to gain deep understanding of complex social dynamics with multi-character interactions.Comprehensive experiments demonstrate that HERO achieves new state of the art on multiple benchmarks over Text-based Video/Video-moment Retrieval, Video Question Answering (QA), Video-and-language Inference and Video Captioning tasks across different domains.We also introduce two new challenging benchmarks How2QA and How2R for Video QA and Retrieval, collected from diverse video content over multimodalities. 1
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“As demonstrated in Figure 2 in [192], the multimodal Transformer models have another architecture taxonomy based on the computational size of the components.”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
In the citing paper
“One simplifying is processing the visual input in convolution-free manner, e.g., E2E-VLP [271], ViLT [192].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Jakubův, J., Chvalovský, K., Goertzel, Z., et al. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,648
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
ImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333
Self-citationBERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
Decoupled Weight Decay Regularization
Loshchilov, I., & Hutter, F. (2017) · arXiv · doi:10.48550/arxiv.1711.05101 · Cited by 12,522
(2017) · Cited by 11,625
Research works printed but not linked: 4
- Lisa Anne Hendricks, Oliver Wang, Eli Shechtman, Josef Sivic, Trevor Darrell, and Bryan Russell. 2017b. Localizing moments in video with natural language. In CVPR.
- Myle Ott, Sergey Edunov, David Grangier, and Michael Auli. 2018. Scaling neural machine trans- lation. arXiv preprint arXiv:1806.00187. · arXiv
- Jun Xu, Tao Mei, Ting Yao, and Yong Rui. 2016b. Msr- vtt: A large video description dataset for bridging video and language. CVPR.
- Licheng Yu, Zhe Lin, Xiaohui Shen, Jimei Yang, Xin Lu, Mohit Bansal, and Tamara L Berg. 2018a. Mat- tnet: Modular attention network for referring expres- sion comprehension. In CVPR.
Cited by
Sorted by citations
Is Space-Time Attention All You Need for Video Understanding?
Bertasius, G., Wang, H., & Torresani, L. (2021) · arXiv · doi:10.48550/arxiv.2102.05095 · Cited by 1,663
Multimodal learning with transformers: A survey
Xu, P., Zhu, X., & Clifton, D. A. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3275156 · Cited by 1,072
Flamingo: a visual language model for few-shot learning
Alayrac, J.-B., Donahue, J., Luc, P., Miech, A., Barr, I., Hasson, Y., Lenc, K., Mensch, A., Millican, K., Reynolds, M., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1723 · Cited by 966
“In particular, BERT [23] inspired a large body of vision-language work [16, 28, 29, 38, 59, 61, 66, 101, 106, 107, 109, 118, 121, 142, 143, 151].”
BackgroundLess is More: CLIPBERT for Video-and-Language Learning via Sparse Sampling
Lei, J., Li, L., Zhou, L., Gan, Z., Berg, T. L., Bansal, M., & Liu, J. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.00725 · Cited by 639
Self-citationZhao, F., Zhang, C., & Geng, B. (2024) · ACM Computing Surveys · doi:10.1145/3649447 · Cited by 480
VideoCLIP: Contrastive Pre-training for Zero-shot Video-Text Understanding
Xu, H., Ghosh, G., Huang, P.-Y., Okhonko, D., Aghajanyan, A., Metze, F., Zettlemoyer, L., & Feichtenhofer, C. (2021) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2021.emnlp-main.544 · Cited by 510
SwinBERT: End-to-End Transformers with Sparse Attention for Video Captioning
Lin, K., Li, L., Lin, C.-C., Ahmed, F., Gan, Z., Liu, Z., Lu, Y., & Wang, L. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01742 · Cited by 333
Self-citationVL-ADAPTER: Parameter-Efficient Transfer Learning for Vision-and-Language Tasks
Sung, Y.-L., Cho, J., & Bansal, M. (2022) · 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52688.2022.00516 · Cited by 329
Large-Scale Adversarial Training for Vision-and-Language Representation LearningPreprint
Gan, Z., Chen, Y.-C., Li, L., Zhu, C., Cheng, Y., & Liu, J. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2006.06195 · Cited by 358
Self-citationVLP: A Survey on Vision-language Pre-training
Chen, F., Zhang, D., Han, M., Chen, X.-Y., Shi, J. C., Xu, S., & Xu, B. (2023) · Machine Intelligence Research · doi:10.1007/s11633-022-1369-5 · Cited by 330
Vid2Seq: Large-Scale Pretraining of a Visual Language Model for Dense Video Captioning
Yang, A., Nagrani, A., Seo, P. H., Miech, A., Pont-Tuset, J., Laptev, I., Šivic, J., & Schmid, C. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01032 · Cited by 296
VLN↻BERT: A Recurrent Vision-and-Language BERT for Navigation
Hong, Y., Wu, Q., Qi, Y., Rodriguez-Opazo, C., & Gould, S. (2021) · 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr46437.2021.00169 · Cited by 264
Scaling Up Vision-Language Pretraining for Image Captioning
Hu, X., Gan, Z., Wang, J., Yang, Z., Liu, Z., Lu, Y., & Wang, L. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01745 · Cited by 261
Self-citationJust Ask: Learning to Answer Questions from Millions of Narrated Videos
Yang, A., Miech, A., Šivic, J., Laptev, I., & Schmid, C. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00171 · Cited by 232
A Survey of Text Representation and Embedding Techniques in NLP
Patil, R., Boit, S., Gudivada, V. N., & Nandigam, J. (2023) · IEEE Access · doi:10.1109/access.2023.3266377 · Cited by 276
Video-MME: The First-Ever Comprehensive Evaluation Benchmark of Multi-modal LLMs in Video Analysis
Fu, C., Dai, Y., Luo, Y., Li, L., Ren, S., Zhang, R., Wang, Z., Zhou, C., Shen, Y., Zhang, M., et al. (2025) · 2025 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52734.2025.02245 · Cited by 291
Self-citationConFEDE: Contrastive Feature Decomposition for Multimodal Sentiment Analysis
Yang, J., Yu, Y., Niu, D., Guo, W., & Xu, Y. (2023) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2023.acl-long.421 · Cited by 201
Align and Prompt: Video-and-Language Pre-training with Entity Prompts
Li, D., Li, J., Li, H., Niebles, J. C., & Hoi, S. C. H. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00490 · Cited by 187
MaskCLIP: Masked Self-Distillation Advances Contrastive Language-Image Pretraining
Dong, X., Bao, J., Zheng, Y., Zhang, T., Chen, D., Yang, H., Zeng, M., Zhang, W., Yuan, L., Chen, D., et al. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01058 · Cited by 201
Selva, J., Johansen, A. S., Escalera, S., Nasrollahi, K., Moeslund, T. B., & Clapés, A. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3243465 · Cited by 192
End-to-end Generative Pretraining for Multimodal Video Captioning
Seo, P. H., Nagrani, A., Arnab, A., & Schmid, C. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01743 · Cited by 181
Vision-Language Pre-Training: Basics, Recent Advances, and Future Trends
Gan, Z., Li, L., Li, C., Wang, L., Liu, Z., & Gao, J. (2022) · Foundations and Trends® in Computer Graphics and Vision · doi:10.1561/0600000105 · Cited by 155
Self-citationZhao, S., Zhu, L., Wang, X., & Yang, Y. (2022) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3477495.3531950 · Cited by 171
TS2-Net: Token Shift and Selection Transformer for Text-Video Retrieval
Liu, Y., Xiong, P., Xu, L., Cao, S., & Jin, Q. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19781-9_19 · Cited by 164
Context-aware Biaffine Localizing Network for Temporal Sentence Grounding
Liu, D., Qu, X., Dong, J., Zhou, P., Cheng, Y., Wei, W., Xu, Z., & Xie, Y. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.01108 · Cited by 145
Self-citationRevisiting the “Video” in Video-Language Understanding
Buch, S., Eyzaguirre, C., Gaidon, A., Wu, J., Fei-Fei, L., & Niebles, J. C. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00293 · Cited by 154
Advancing High-Resolution Video-Language Representation with Large-Scale Video Transcriptions
Xue, H., Hang, T., Zeng, Y., Sun, Y., Liu, B., Yang, H., Fu, J., & Guo, B. (2022) · 2022 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52688.2022.00498 · Cited by 127
Bridging Video-text Retrieval with Multiple Choice Questions
Ge, Y., Ge, Y., Liu, X., Li, D., Shan, Y., Qie, X., & Luo, P. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01569 · Cited by 138
Kaleido-BERT: Vision-Language Pre-training on Fashion Domain
Zhuge, M., Gao, D., Fan, D.-P., Jin, L., Chen, B., Zhou, H., Qiu, M., & Shao, L. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.01246 · Cited by 130
Video Understanding With Large Language Models: A Survey
Tang, Y., Bi, J., Xu, S., Song, L., Liang, S., Wang, T., Zhang, D., An, J., Lin, J., Zhu, R., et al. (2025) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2025.3566695 · Cited by 288
TACo: Token-aware Cascade Contrastive Learning for Video-Text Alignment
Yang, J., Bisk, Y., & Gao, J. (2021) · 2021 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.01136 · Cited by 115
Self-Supervised Multimodal Learning: A Survey
Zong, Y., Aodha, O. M., & Hospedales, T. M. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3429301 · Cited by 165
CLIP4Clip: An Empirical Study of CLIP for End to End Video Clip RetrievalPreprint
Luo, H., Ji, L., Zhong, M., Chen, Y., Lei, W., Duan, N., & Li, T. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2104.08860 · Cited by 108
Self-citationBehind the Scene: Revealing the Secrets of Pre-trained Vision-and-Language Models
Cao, J., Gan, Z., Cheng, Y., Yu, L., Chen, Y.-C., & Liu, J. (2020) · Lecture notes in computer science · doi:10.1007/978-3-030-58539-6_34 · Cited by 112
Self-citationVideo Graph Transformer for Video Question Answering
Xiao, J., Zhou, P., Chua, T., & Yan, S. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-20059-5_3 · Cited by 108
VIOLET : End-to-End Video-Language Transformers with Masked Visual-token ModelingPreprint
Fu, T.-J., Li, L., Gan, Z., Lin, K., Wang, W. Y., Wang, L., & Liu, Z. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2111.12681 · Cited by 212
Self-citationTubeDETR: Spatio-Temporal Video Grounding with Transformers
Yang, A., Miech, A., Šivic, J., Laptev, I., & Schmid, C. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01595 · Cited by 114
Fine-grained Iterative Attention Network for Temporal Language Localization in Videos
Qu, X., Tang, P., Zou, Z., Cheng, Y., Dong, J., Zhou, P., & Xu, Z. (2020) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3394171.3414053 · Cited by 92
Self-citationVLM: Task-agnostic Video-Language Model Pre-training for Video Understanding
Xu, H., Ghosh, G., Huang, P.-Y., Arora, P., Aminzadeh, M., Feichtenhofer, C., Metze, F., & Zettlemoyer, L. (2021) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2021.findings-acl.370 · Cited by 94
OneLLM: One Framework to Align All Modalities with Language
Han, J., Gong, K., Zhang, Y., Wang, J., Zhang, K., Lin, D., Qiao, Y., Gao, P., & Yue, X. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.02510 · Cited by 152
Temporal Sentence Grounding in Videos: A Survey and Future Directions
Zhang, H., Sun, A., Jing, W., & Zhou, J. T. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3258628 · Cited by 105
Video Question Answering: Datasets, Algorithms and Challenges
Zhong, Y., Ji, W., Xiao, J., Li, Y., Deng, W., & Chua, T. (2022) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2022.emnlp-main.432 · Cited by 133
Reading-Strategy Inspired Visual Representation Learning for Text-to-Video Retrieval
Dong, J., Wang, Y., Chen, X., Qu, X., Li, X., He, Y., & Wang, X. (2022) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2022.3150959 · Cited by 89
EgoVLPv2: Egocentric Video-Language Pre-training with Fusion in the Backbone
Pramanick, S., Song, Y., Nag, S., Lin, K. Q., Shah, H., Shou, M. Z., Chellappa, R., & Zhang, P. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00487 · Cited by 106
Luo, H., Ji, L., Shi, B., Huang, H., Duan, N., Li, T., Chen, X., & Zhou, M. (2020) · arXiv (Cornell University) · Cited by 82
Frozen in Time: A Joint Video and Image Encoder for End-to-End Retrieval
Bain, M., Nagrani, A., Varol, G., & Zisserman, A. (2021) · 2021 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00175 · Cited by 76
COTS: Collaborative Two-Stream Vision-Language Pre-Training Model for Cross-Modal Retrieval
Lu, H., Fei, N., Huo, Y., Gao, Y., Lu, Z., & Wen, J.-R. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01524 · Cited by 78
Revealing Single Frame Bias for Video-and-Language Learning
Lei, J., Berg, T. L., & Bansal, M. (2023) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2023.acl-long.29 · Cited by 146
Multi-Modal Cross-Domain Alignment Network for Video Moment Retrieval
Fang, X., Liu, D., Zhou, P., & Hu, Y. (2022) · IEEE transactions on multimedia · doi:10.1109/tmm.2022.3222965 · Cited by 108
VALOR: Vision-Audio-Language Omni-Perception Pretraining Model and Dataset
Liu, J., Chen, S., He, X., Guo, L., Zhu, X., Wang, W., & Tang, J. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3479776 · Cited by 175
Self-citationCompressing Visual-linguistic Model via Knowledge Distillation
Fang, Z., Wang, J., Hu, X., Wang, L., Yang, Y., & Liu, Z. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00146 · Cited by 81
LAVENDER: Unifying Video-Language Understanding as Masked Language Modeling
Li, L., Gan, Z., Lin, K., Lin, C.-C., Liu, Z., Liu, C., & Wang, L. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.02214 · Cited by 90
Self-citationHierarchical Local-Global Transformer for Temporal Sentence Grounding
Fang, X., Liu, D., Zhou, P., Xu, Z., & Li, R. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3309551 · Cited by 77
Object-aware Video-language Pre-training for Retrieval
Wang, A. J., Ge, Y., Cai, G., Yan, R., Lin, X., Shan, Y., Qie, X., & Shou, M. Z. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00331 · Cited by 69
HiTeA: Hierarchical Temporal-Aware Video-Language Pre-training
Ye, Q., Xu, G., Yan, M., Xu, H., Qian, Q., Zhang, J., & Huang, F. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01413 · Cited by 87
Learning Audio-Video Modalities from Image Captions
Nagrani, A., Seo, P. H., Seybold, B., Hauth, A., Manén, S., Sun, C., & Schmid, C. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19781-9_24 · Cited by 82
Multimodality Representation Learning: A Survey on Evolution, Pretraining and Its Applications
Manzoor, M. A., Albarri, S., Xian, Z., Meng, Z., Nakov, P., & Liang, S. (2023) · ACM Transactions on Multimedia Computing Communications and Applications · doi:10.1145/3617833 · Cited by 86
Future Transformer for Long-term Action Anticipation
Gong, D., Lee, J., Kim, M., Ha, S. J., & Cho, M. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00306 · Cited by 67
Enhancing Video-Language Representations With Structural Spatio-Temporal Alignment
Fei, H., Wu, S., Zhang, M., Zhang, M., Chua, T., & Yan, S. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3393452 · Cited by 71
Can I Trust Your Answer? Visually Grounded Video Question Answering
Xiao, J., Yao, A., Li, Y., & Chua, T. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01254 · Cited by 101
VindLU: A Recipe for Effective Video-and-Language Pretraining
Cheng, F., Wang, X., Lei, J., Crandall, D., Bansal, M., & Bertasius, G. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01034 · Cited by 76
From CNNs to Transformers in Multimodal Human Action Recognition: A Survey
Shaikh, M. B., Chai, D., Islam, S. M. S., & Akhtar, N. (2024) · ACM Transactions on Multimedia Computing Communications and Applications · doi:10.1145/3664815 · Cited by 71
Visual Semantic Role Labeling for Video Understanding
Sadhu, A., Gupta, T., Yatskar, M., Nevatia, R., & Kembhavi, A. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.00554 · Cited by 63
Progressive Spatio-Temporal Prototype Matching for Text-Video Retrieval
Li, P., Xie, C.-W., Zhao, L., Xie, H., Ge, J., Zheng, Y., Zhao, D., & Zhang, Y. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00379 · Cited by 62
Learning To Recognize Procedural Activities with Distant Supervision
Lin, X., Petroni, F., Bertasius, G., Rohrbach, M., Chang, S., & Torresani, L. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01348 · Cited by 70
Toward Video Anomaly Retrieval From Video Anomaly Detection: New Benchmarks and Model
Wu, P., Liu, J., He, X., Peng, Y., Wang, P., & Zhang, Y. (2024) · IEEE Transactions on Image Processing · doi:10.1109/tip.2024.3374070 · Cited by 69
Self-citationInstruct-ReID: A Multi-Purpose Person Re-Identification Task with Instructions
He, W., Deng, Y., Tang, S., Chen, Q., Xie, Q., Wang, Y., Bai, L., Zhu, F., Zhao, R., Ouyang, W., et al. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01659 · Cited by 62
VL-LTR: Learning Class-wise Visual-Linguistic Representation for Long-Tailed Visual Recognition
Tian, C., Wang, W., Zhu, X., Dai, J., & Qiao, Y. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19806-9_5 · Cited by 65
VX2TEXT: End-to-End Learning of Video-Based Text Generation From Multimodal Inputs
Lin, X., Bertasius, G., Wang, J., Chang, S., Parikh, D., & Torresani, L. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.00693 · Cited by 58
Large language models meet text-centric multimodal sentiment analysis: a survey
Yang, H., Zhao, Y., Wu, Y., Wang, S., Zheng, T., Zhang, H., Ma, Z., Che, W., Wang, S., Wei, S., et al. (2025) · Science China Information Sciences · doi:10.1007/s11432-024-4593-8 · Cited by 104
Image Difference Captioning with Pre-training and Contrastive Learning
Yao, L., Wang, W., & Jin, Q. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i3.20218 · Cited by 55
Look Before you Speak: Visually Contextualized Utterances
Seo, P. H., Nagrani, A., & Schmid, C. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.01660 · Cited by 57
Shin, A., Ishii, M., & Narihira, T. (2022) · International Journal of Computer Vision · doi:10.1007/s11263-021-01547-8 · Cited by 58
An Empirical Study of End-to-End Video-Language Transformers with Masked Visual Modeling
Fu, T.-J., Li, L., Gan, Z., Lin, K., Wang, W. Y., Wang, L., & Liu, Z. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.02193 · Cited by 70
Self-citationA Multi-Modal Vertical Federated Learning Framework Based on Homomorphic Encryption
Gong, M., Zhang, Y., Gao, Y., Qin, A. K., Wu, Y., Wang, S., & Zhang, Y. (2023) · IEEE Transactions on Information Forensics and Security · doi:10.1109/tifs.2023.3340994 · Cited by 54
VALUE: A Multi-Task Benchmark for Video-and-Language Understanding EvaluationPreprint
Li, L., Lei, J., Gan, Z., Yu, L., Chen, Y.-C., Pillai, R., Cheng, Y., Zhou, L., Wang, X. E., Wang, W. Y., et al. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2106.04632 · Cited by 90
Self-citationCoVR: Learning Composed Video Retrieval from Web Video Captions
Ventura, L., Yang, A., Schmid, C., & Varol, G. (2024) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v38i6.28334 · Cited by 62
CONQUER: Contextual Query-aware Ranking for Video Corpus Moment Retrieval
Hou, Z., Ngo, C., & Chan, W. K. (2021) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3474085.3475281 · Cited by 50
Survey: Transformer based video-language pre-training
Ruan, L., & Jin, Q. (2022) · AI Open · doi:10.1016/j.aiopen.2022.01.001 · Cited by 56
Video description: A comprehensive survey of deep learning approaches
Rafiq, G., Rafiq, M. T., & Choi, G. S. (2023) · Artificial Intelligence Review · doi:10.1007/s10462-023-10414-6 · Cited by 55
Clover: Towards A Unified Video-Language Alignment and Fusion Model
Huang, J., Li, Y., Feng, J., Wu, X., Sun, X., & Ji, R. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01427 · Cited by 59
Towards Visual-Prompt Temporal Answer Grounding in Instructional Video
Shutao Li, A., Li, B., Sun, B., & Weng, Y. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3411045 · Cited by 55
DeCEMBERT: Learning from Noisy Instructional Videos via Dense Captions and Entropy Minimization
Tang, Z., Lei, J., & Bansal, M. (2021) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2021.naacl-main.193 · Cited by 48
Parallel Attention Network with Sequence Matching for Video Grounding
Zhang, H., Sun, A., Jing, W., Zhen, L., Zhou, J. T., & Goh, S. M. R. (2021) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2021.findings-acl.69 · Cited by 61
LocVTP: Video-Text Pre-training for Temporal Localization
Cao, M., Yang, T., Weng, J., Zhang, C., Wang, J., & Zou, Y. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19809-0_3 · Cited by 52
Prompt Switch: Efficient CLIP Adaptation for Text-Video Retrieval
Deng, C., Chen, Q., Qin, P., Chen, D., & Wu, Q. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01434 · Cited by 47
Scaling-up medical vision-and-language representation learning with federated learning
Lu, S., Liu, Z., Liu, T., & Zhou, W. (2023) · Engineering Applications of Artificial Intelligence · doi:10.1016/j.engappai.2023.107037 · Cited by 49
VideoXum: Cross-Modal Visual and Textural Summarization of Videos
Lin, J., Hua, H., Chen, M., Li, Y., Hsiao, J.-H., Ho, C., & Luo, J. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3335875 · Cited by 56
Unsupervised Temporal Video Grounding with Deep Semantic Clustering
Liu, D., Qu, X., Wang, Y., Di, X., Zou, K., Cheng, Y., Xu, Z., & Zhou, P. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i2.20060 · Cited by 51
Self-citationVisual language navigation: a survey and open challenges
Park, S., & Kim, Y. (2022) · Artificial Intelligence Review · doi:10.1007/s10462-022-10174-9 · Cited by 49
Hierarchical Video-Moment Retrieval and Step-Captioning
Zala, A., Cho, J., Kottur, S., Chen, X., Oğuz, B., Mehdad, Y., & Bansal, M. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.02208 · Cited by 57
A Universal Quaternion Hypergraph Network for Multimodal Video Question Answering
Guo, Z., Zhao, J., Jiao, L., Liu, X., & Liu, F. (2021) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2021.3120544 · Cited by 45
A Multimodal Memes Classification: A Survey and Open Research Issues
Afridi, T. H., Alam, A., Khan, M. N., Khan, J., & Lee, Y.-K. (2021) · Lecture notes in networks and systems · doi:10.1007/978-3-030-66840-2_109 · Cited by 47
Memobert: Pre-Training Model with Prompt-Based Learning for Multimodal Emotion Recognition
Zhao, J., Li, R., Jin, Q., Wang, X., & Li, H. (2022) · ICASSP 2022 - 2022 IEEE International Conference on Acoustics, Speech and Signal Processing (ICASSP) · doi:10.1109/icassp43922.2022.9746910 · Cited by 39
EclipSE: Efficient Long-Range Video Retrieval Using Sight and Sound
Lin, Y.-B., Lei, J., Bansal, M., & Bertasius, G. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19830-4_24 · Cited by 46
Audio-Enhanced Text-to-Video Retrieval using Text-Conditioned Feature Alignment
Ibrahimi, S., Sun, X., Wang, P., Garg, A., Sanan, A., & Omar, M. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01107 · Cited by 41
Playing Lottery Tickets with Vision and Language
Gan, Z., Chen, Y.-C., Li, L., Chen, T., Cheng, Y., Wang, S., Liu, J., Wang, L., & Liu, Z. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i1.19945 · Cited by 48
Self-citationConnecting Language and Vision for Natural Language-Based Vehicle Retrieval
Bai, S., Zheng, Z., Wang, X., Lin, J., Zhang, Z., Zhou, C., Yang, H., & Yang, Y. (2021) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw53098.2021.00455 · Cited by 37
A Recurrent Vision-and-Language BERT for NavigationPreprint
Hong, Y., Wu, Q., Qi, Y., Rodríguez-Opazo, C., & Gould, S. J. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2011.13922 · Cited by 38
Search-oriented Micro-video Captioning
Nie, L., Qu, L., Meng, D., Zhang, M., Tian, Q., & Bimbo, A. D. (2022) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3503161.3548180 · Cited by 37
Metadata
- Authors
- Li, L., Chen, Y.-C., Cheng, Y., Gan, Z., Yu, L., & Liu, J.
- Affiliations
- Microsoft (United States) (US)
- Venue
- Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP)
- Published
- 2020
- Pages
- 2046-2065
- OpenAlex
- W3105232955
- Cited by
- 408
- References
- 79
- Citations by year
- 2026: 17 · 2025: 49 · 2024: 67 · 2023: 129 · 2022: 87 · 2021: 52 · 2020: 7
- FWCI
- 21.21
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Human Pose and Action Recognition
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Video Analysis and Summarization
- Keywords
- multimodal representation learning, hierarchical encoder, cross-modal transformer, temporal transformer, video question answering, video retrieval, video captioning, video moment retrieval
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
