

The DOI matches its Crossref record; 79 of the 79 references it cites were found in a registry or an index.
HERO: Hierarchical Encoder for Video+Language Omni-representation Pre-training
Open accessAbstract
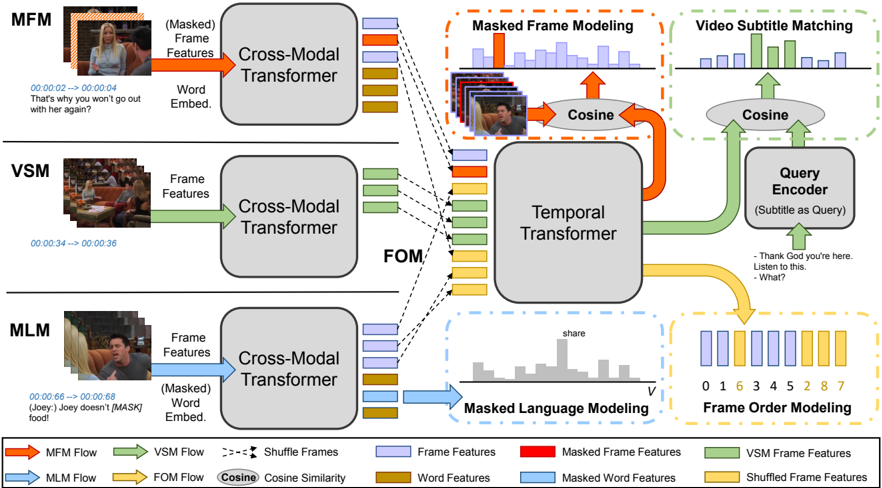
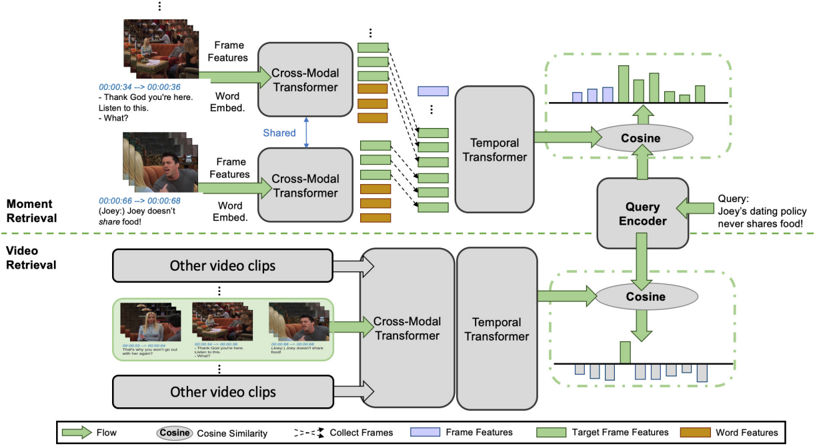
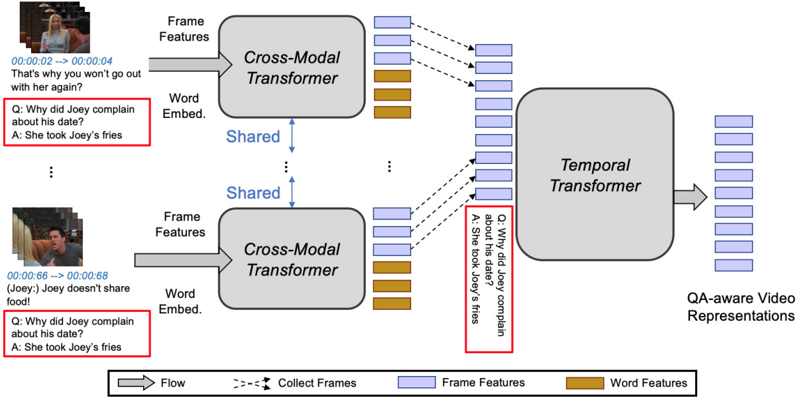
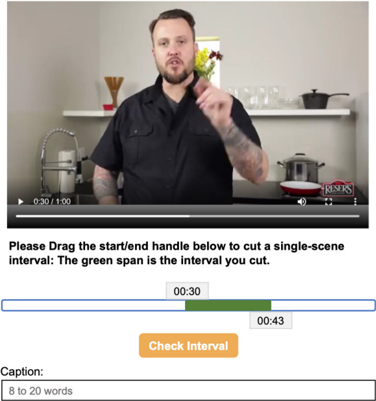
We present HERO, a novel framework for large-scale video+language omnirepresentation learning.HERO encodes multimodal inputs in a hierarchical structure, where local context of a video frame is captured by a Cross-modal Transformer via multimodal fusion, and global video context is captured by a Temporal Transformer.In addition to standard Masked Language Modeling (MLM) and Masked Frame Modeling (MFM) objectives, we design two new pre-training tasks: (i) Video-Subtitle Matching (VSM), where the model predicts both global and local temporal alignment; and (ii) Frame Order Modeling (FOM), where the model predicts the right order of shuffled video frames.HERO is jointly trained on HowTo100M and large-scale TV datasets to gain deep understanding of complex social dynamics with multi-character interactions.Comprehensive experiments demonstrate that HERO achieves new state of the art on multiple benchmarks over Text-based Video/Video-moment Retrieval, Video Question Answering (QA), Video-and-language Inference and Video Captioning tasks across different domains.We also introduce two new challenging benchmarks How2QA and How2R for Video QA and Retrieval, collected from diverse video content over multimodalities. 1
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
The source backs part of the claim, not all of it — or backs it for a different population, condition or comparison.
In the citing paper
“As demonstrated in Figure 2 in [192], the multimodal Transformer models have another architecture taxonomy based on the computational size of the components.”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
Experimental — accuracy not yet measuredIn the citing paper
“One simplifying is processing the visual input in convolution-free manner, e.g., E2E-VLP [271], ViLT [192].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Jakubův, J., Chvalovský, K., Goertzel, Z., et al. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,648
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
ImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333
Self-citationBERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
Decoupled Weight Decay Regularization
Loshchilov, I., & Hutter, F. (2017) · arXiv · doi:10.48550/arxiv.1711.05101 · Cited by 12,522
(2017) · Cited by 11,625
Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
Raffel, C., Shazeer, N., Roberts, A., Lee, K., Narang, S., Matena, M., Zhou, Y., Li, W., & Liu, P. J. (2019) · arXiv · doi:10.48550/arxiv.1910.10683 · Cited by 10,929
(2004) · Cited by 9,718
XLNet: Generalized Autoregressive Pretraining for Language Understanding
Yang, Z., Dai, Z., Yang, Y., Carbonell, J., Salakhutdinov, R., & Le, Q. V. (2019) · arXiv · doi:10.48550/arxiv.1906.08237 · Cited by 6,687
Representation Learning with Contrastive Predictive Coding
Oord, A. V. D., Li, Y., & Vinyals, O. (2018) · arXiv · doi:10.48550/arxiv.1807.03748 · Cited by 6,242
Bottom-Up and Top-Down Attention for Image Captioning and Visual Question Answering
Anderson, P., He, X., Buehler, C., Teney, D., Johnson, M., Gould, S. J., & Zhang, L. (2018) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2018.00636 · Cited by 5,416
Google's Neural Machine Translation System: Bridging the Gap between Human and Machine Translation
Wu, Y., Schuster, M., Chen, Z., Le, Q. V., Norouzi, M., Macherey, W., Krikun, M., Cao, Y., Gao, Q., Macherey, K., et al. (2016) · arXiv · doi:10.48550/arxiv.1609.08144 · Cited by 5,319
The Kinetics Human Action Video DatasetPreprint
Kay, W., Carreira, J., Simonyan, K., Zhang, B., Hillier, C., Vijayanarasimhan, S., Viola, F., Green, T., Back, T., Natsev, P., et al. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1705.06950 · Cited by 5,004
CIDEr: Consensus-based image description evaluation
Vedantam, R., Zitnick, C. L., & Parikh, D. (2015) · 2015 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2015.7299087 · Cited by 4,845
ALBERT: A Lite BERT for Self-supervised Learning of Language Representations
Lan, Z., Chen, M., Goodman, S., Gimpel, K., Sharma, P., & Soricut, R. (2019) · arXiv · doi:10.48550/arxiv.1909.11942 · Cited by 4,308
SlowFast Networks for Video Recognition
Feichtenhofer, C., Fan, H., Malik, J., & He, K. (2019) · 2019 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00630 · Cited by 4,007
A large annotated corpus for learning natural language inference
Bowman, S. R., Angeli, G., Potts, C., & Manning, C. D. (2015) · Proceedings of the 2015 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d15-1075 · Cited by 3,377
A Broad-Coverage Challenge Corpus for Sentence Understanding through Inference
Williams, A., Nangia, N., & Bowman, S. (2018) · Proceedings of the 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long Papers) · doi:10.18653/v1/n18-1101 · Cited by 3,342
LXMERT: Learning Cross-Modality Encoder Representations from Transformers
Tan, H., & Bansal, M. (2019) · Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP) · doi:10.18653/v1/d19-1514 · Cited by 2,319
ViLBERT: Pretraining Task-Agnostic Visiolinguistic Representations for Vision-and-Language Tasks
Lu, J., Batra, D., Parikh, D., & Lee, S. (2019) · arXiv · doi:10.48550/arxiv.1908.02265 · Cited by 2,109
Meteor Universal: Language Specific Translation Evaluation for Any Target Language
Denkowski, M., & Lavie, A. (2014) · WMT@ACL · doi:10.3115/v1/w14-3348 · Cited by 2,108
UNITER: UNiversal Image-TExt Representation Learning
Chen, Y.-C., Li, L., Yu, L., El Kholy, A., Ahmed, F., Gan, Z., Cheng, Y., & Liu, J. (2020) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-58577-8_7 · Cited by 2,055
Self-citationLearning deep representations by mutual information estimation and maximization
Hjelm, R. D., Fedorov, A., Lavoie-Marchildon, S., Grewal, K., Bachman, P., Trischler, A., & Bengio, Y. (2018) · arXiv · doi:10.48550/arxiv.1808.06670 · Cited by 1,991
MSR-VTT: A Large Video Description Dataset for Bridging Video and Language
Xu, J., Mei, T., Yao, T., & Rui, Y. (2016) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2016.571 · Cited by 1,888
Oscar: Object-Semantics Aligned Pre-training for Vision-Language Tasks
Li, X., Yin, X. P., Li, C., Zhang, P., Hu, X., Zhang, L., Wang, L., Hu, H., Li, D., Wei, F., et al. (2020) · Lecture notes in computer science · doi:10.1007/978-3-030-58577-8_8 · Cited by 1,791
Sequence to Sequence -- Video to Text
Venugopalan, S., Rohrbach, M., Donahue, J., Mooney, R. J., Darrell, T., & Saenko, K. (2015) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2015.515 · Cited by 1,448
Dense-Captioning Events in Videos
Krishna, R., Hata, K., Ren, F., Fei-Fei, L., & Niebles, J. C. (2017) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2017.83 · Cited by 1,279
VideoBERT: A Joint Model for Video and Language Representation Learning
Sun, C., Myers, A., Vondrick, C., Murphy, K. P., & Schmid, C. (2019) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00756 · Cited by 1,255
Exploring the Limits of Language ModelingPreprint
Józefowicz, R., Vinyals, O., Schuster, M., Shazeer, N., & Wu, Y. (2016) · arXiv (Cornell University) · doi:10.48550/arxiv.1602.02410 · Cited by 1,238
Unified Language Model Pre-training for Natural Language Understanding and Generation
Dong, L., Yang, N., Wang, W., Wei, F., Liu, X., Wang, Y., Gao, J., Zhou, M., & Hon, H.-W. (2019) · arXiv · doi:10.48550/arxiv.1905.03197 · Cited by 1,225
VisualBERT: A Simple and Performant Baseline for Vision and Language
Li, L. H., Yatskar, M., Yin, D., Hsieh, C.-J., & Chang, K.-W. (2019) · arXiv · doi:10.48550/arxiv.1908.03557 · Cited by 1,198
Self-citationLocalizing Moments in Video with Natural Language
Hendricks, L. A., Wang, O., Shechtman, E., Šivic, J., Darrell, T., & Russell, B. C. (2017) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2017.618 · Cited by 1,034
HowTo100M: Learning a Text-Video Embedding by Watching Hundred Million Narrated Video Clips
Miech, A., Zhukov, D., Alayrac, J.-B., Tapaswi, M., Laptev, I., & Sivic, J. (2019) · 2019 IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00272 · Cited by 986
VL-BERT: Pre-training of Generic Visual-Linguistic Representations
Su, W., Zhu, X., Cao, Y., Li, B., Lu, L., Wei, F., & Dai, J. (2019) · arXiv · doi:10.48550/arxiv.1908.08530 · Cited by 950
TALL: Temporal Activity Localization via Language Query
Gao, J., Sun, C., Yang, Z., & Nevatia, R. (2017) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2017.563 · Cited by 936
Patient Knowledge Distillation for BERT Model Compression
Sun, S., Cheng, Y., Gan, Z., & Liu, J. (2019) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d19-1441 · Cited by 931
Self-citationMAttNet: Modular Attention Network for Referring Expression Comprehension
Yu, L., Lin, Z., Shen, X., Yang, J., Lu, X., Bansal, M., & Berg, T. L. (2018) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2018.00142 · Cited by 876
Self-citationUnified Vision-Language Pre-Training for Image Captioning and VQA
Zhou, L., Palangi, H., Zhang, L., Hu, H., Corso, J., & Gao, J. (2020) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v34i07.7005 · Cited by 864
Unicoder-VL: A Universal Encoder for Vision and Language by Cross-Modal Pre-Training
Li, G., Duan, N., Fang, Y., Gong, M., & Jiang, D. (2020) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v34i07.6795 · Cited by 795
From Recognition to Cognition: Visual Commonsense Reasoning
Zellers, R., Bisk, Y., Farhadi, A., & Choi, Y. (2019) · 2019 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2019.00688 · Cited by 769
Towards Automatic Learning of Procedures From Web Instructional Videos
Zhou, L., Xu, C., & Corso, J. J. (2018) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v32i1.12342 · Cited by 722
Revealing the Dark Secrets of BERT
Kovaleva, O., Romanov, A., Rogers, A., & Rumshisky, A. (2019) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d19-1445 · Cited by 650
MovieQA: Understanding Stories in Movies through Question-Answering
Tapaswi, M., Zhu, Y., Stiefelhagen, R., Torralba, A. B., Urtasun, R., & Fidler, S. (2016) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2016.501 · Cited by 646
End-to-End Learning of Visual Representations From Uncurated Instructional Videos
Miech, A., Alayrac, J.-B., Smaira, L., Laptev, I., Šivic, J., & Zisserman, A. (2020) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr42600.2020.00990 · Cited by 646
Scaling Neural Machine Translation
Ott, M., Edunov, S., Grangier, D., & Auli, M. (2018) · Conference on Machine Translation (WMT) · doi:10.18653/v1/w18-6301 · Cited by 631
End-to-End Dense Video Captioning with Masked Transformer
Zhou, L., Zhou, Y., Corso, J. J., Socher, R., & Xiong, C. (2018) · 2018 IEEE/CVF Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2018.00911 · Cited by 605
Jointly Modeling Embedding and Translation to Bridge Video and Language
Pan, Y., Mei, T., Yao, T., Li, H., & Rui, Y. (2016) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2016.497 · Cited by 572
TVQA: Localized, Compositional Video Question Answering
Lei, J., Yu, L., Bansal, M., & Berg, T. (2018) · Proceedings of the 2018 Conference on Empirical Methods in Natural Language Processing · doi:10.18653/v1/d18-1167 · Cited by 541
Self-citationVaTeX: A Large-Scale, High-Quality Multilingual Dataset for Video-and-Language Research
Wang, X., Wu, J., Chen, J., Li, L., Wang, Y., & Wang, W. Y. (2019) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2019.00468 · Cited by 536
Self-citationTGIF-QA: Toward Spatio-Temporal Reasoning in Visual Question Answering
Jang, Y., Song, Y., Yu, Y., Kim, Y., & Kim, G. (2017) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2017.149 · Cited by 527
Guadarrama, S., Krishnamoorthy, N., Malkarnenkar, G., Venugopalan, S., Mooney, R. J., Darrell, T., & Saenko, K. (2013) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv.2013.337 · Cited by 500
Semantic Compositional Networks for Visual Captioning
Gan, Z., Gan, C., He, X., Pu, Y., Tran, K., Gao, J., Carin, L., & Deng, L. (2017) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2017.127 · Cited by 465
Self-citationQ-BERT: Hessian Based Ultra Low Precision Quantization of BERT
Shen, S., Dong, Z., Ye, J., Ma, L., Yao, Z., Gholami, A., Mahoney, M. W., & Keutzer, K. (2020) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v34i05.6409 · Cited by 437
Pixel-BERT: Aligning Image Pixels with Text by Deep Multi-Modal TransformersPreprint
Huang, Z., Zeng, Z., Liu, B., Fu, D., & Fu, J. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2004.00849 · Cited by 433
ActBERT: Learning Global-Local Video-Text Representations
Zhu, L., & Yang, Y. (2020) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr42600.2020.00877 · Cited by 425
12-in-1: Multi-Task Vision and Language Representation Learning
Lu, J., Goswami, V., Rohrbach, M., Parikh, D., & Lee, S. (2020) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr42600.2020.01045 · Cited by 420
A Joint Sequence Fusion Model for Video Question Answering and Retrieval
Yu, Y., Kim, J.-S., & Kim, G. (2018) · Lecture notes in computer science · doi:10.1007/978-3-030-01234-2_29 · Cited by 358
Large-Scale Adversarial Training for Vision-and-Language Representation LearningPreprint
Gan, Z., Chen, Y.-C., Li, L., Zhu, C., Cheng, Y., & Liu, J. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2006.06195 · Cited by 358
Self-citationVisual Entailment: A Novel Task for Fine-Grained Image UnderstandingPreprint
Xie, N., Lai, F., Doran, D., & Kadav, A. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1901.06706 · Cited by 311
TVR: A Large-Scale Dataset for Video-Subtitle Moment Retrieval
Lei, J., Yu, L., Berg, T. L., & Bansal, M. (2020) · Lecture notes in computer science · doi:10.1007/978-3-030-58589-1_27 · Cited by 287
Self-citationBERT has a Mouth, and It Must Speak: BERT as a Markov Random Field Language ModelPreprint
Wang, A., & Cho, K. (2019) · arXiv (Cornell University) · doi:10.48550/arxiv.1902.04094 · Cited by 234
TVQA+: Spatio-Temporal Grounding for Video Question Answering
Lei, J., Yu, L., Berg, T. L., & Bansal, M. (2020) · Proceedings of the conference - Association for Computational Linguistics. Meeting · doi:10.18653/v1/2020.acl-main.730 · Cited by 225
Self-citationTowards Automatic Learning of Procedures from Web Instructional VideosPreprint
Zhou, L., Xu, C., & Corso, J. J. (2017) · arXiv (Cornell University) · doi:10.48550/arxiv.1703.09788 · Cited by 216
Zhou, L., Kalantidis, Y., Chen, X., Corso, J. J., & Rohrbach, M. (2019) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2019.00674 · Cited by 191
Fusion of Detected Objects in Text for Visual Question Answering
Alberti, C., Ling, J., Collins, M., & Reitter, D. (2019) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/d19-1219 · Cited by 188
UniVL: A Unified Video and Language Pre-Training Model for Multimodal Understanding and GenerationPreprint
Luo, H., Ji, L., Shi, B., Huang, H., Duan, N., Li, T., Li, J., Bharti, T., & Zhou, M. Q. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2002.06353 · Cited by 187
Contrastive Bidirectional Transformer for Temporal Representation Learning
Sun, C., Baradel, F., Murphy, K. P., & Schmid, C. (2019) · Cited by 109
Large-Scale Pretraining for Visual Dialog: A Simple State-of-the-Art Baseline
Murahari, V., Batra, D., Parikh, D., & Das, A. (2020) · Lecture notes in computer science · doi:10.1007/978-3-030-58523-5_20 · Cited by 109
Maharaj, T., Ballas, N., Rohrbach, A., Courville, A. C., & Pal, C. (2017) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr.2017.778 · Cited by 93
Luo, H., Ji, L., Shi, B., Huang, H., Duan, N., Li, T., Chen, X., & Zhou, M. (2020) · arXiv (Cornell University) · Cited by 82
XGPT: Cross-modal Generative Pre-Training for Image Captioning
Xia, Q., Huang, H., Duan, N., Zhang, D., Ji, L., Sui, Z., Cui, E., Bharti, T., & Zhou, M. (2021) · Lecture Notes in Computer Science · doi:10.1007/978-3-030-88480-2_63 · Cited by 70
Violin: A Large-Scale Dataset for Video-and-Language Inference
Liu, J., Chen, W., Cheng, Y., Gan, Z., Yu, L., Yang, Y., & Liu, J. (2020) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr42600.2020.01091 · Cited by 69
Self-citationTemporal Localization of Moments in Video Collections with Natural Language.Preprint
Escorcia, V. A., Soldan, M., Šivic, J., Ghanem, B., & Russell, B. C. (2019) · arXiv (Cornell University) · Cited by 65
Distilling the Knowledge of BERT for Text Generation
Chen, Y.-C., Gan, Z., Cheng, Y., Liu, J., & Liu, J. (2019) · Cited by 22
Self-citationXGPT: Cross-modal Generative Pre-Training for Image CaptioningPreprint
Xia, Q., Huang, H., Duan, N., et al. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2003.01473 · Cited by 20
Research works printed but not linked: 4
- Lisa Anne Hendricks, Oliver Wang, Eli Shechtman, Josef Sivic, Trevor Darrell, and Bryan Russell. 2017b. Localizing moments in video with natural language. In CVPR.
- Myle Ott, Sergey Edunov, David Grangier, and Michael Auli. 2018. Scaling neural machine trans- lation. arXiv preprint arXiv:1806.00187. · arXiv
- Jun Xu, Tao Mei, Ting Yao, and Yong Rui. 2016b. Msr- vtt: A large video description dataset for bridging video and language. CVPR.
- Licheng Yu, Zhe Lin, Xiaohui Shen, Jimei Yang, Xin Lu, Mohit Bansal, and Tamara L Berg. 2018a. Mat- tnet: Modular attention network for referring expres- sion comprehension. In CVPR.
Cited by
Sorted by citations
Is Space-Time Attention All You Need for Video Understanding?
Bertasius, G., Wang, H., & Torresani, L. (2021) · arXiv · doi:10.48550/arxiv.2102.05095 · Cited by 1,663
Multimodal learning with transformers: A survey
Xu, P., Zhu, X., & Clifton, D. A. (2023) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2023.3275156 · Cited by 1,072
Flamingo: a visual language model for few-shot learning
Alayrac, J.-B., Donahue, J., Luc, P., Miech, A., Barr, I., Hasson, Y., Lenc, K., Mensch, A., Millican, K., Reynolds, M., et al. (2022) · Advances in Neural Information Processing Systems 35 · doi:10.52202/068431-1723 · Cited by 966
“In particular, BERT [23] inspired a large body of vision-language work [16, 28, 29, 38, 59, 61, 66, 101, 106, 107, 109, 118, 121, 142, 143, 151].”
BackgroundLess is More: CLIPBERT for Video-and-Language Learning via Sparse Sampling
Lei, J., Li, L., Zhou, L., Gan, Z., Berg, T. L., Bansal, M., & Liu, J. (2021) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr46437.2021.00725 · Cited by 639
Self-citationZhao, F., Zhang, C., & Geng, B. (2024) · ACM Computing Surveys · doi:10.1145/3649447 · Cited by 480
Metadata
- Authors
- Li, L., Chen, Y.-C., Cheng, Y., Gan, Z., Yu, L., & Liu, J.
- Affiliations
- Microsoft (United States) (US)
- Venue
- Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP)
- Published
- 2020
- Pages
- 2046-2065
- OpenAlex
- W3105232955
- Cited by
- 408
- References
- 79
- Citations by year
- 2026: 17 · 2025: 49 · 2024: 67 · 2023: 129 · 2022: 87 · 2021: 52 · 2020: 7
- FWCI
- 21.21
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Human Pose and Action Recognition
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Video Analysis and Summarization
- Keywords
- multimodal representation learning, hierarchical encoder, cross-modal transformer, temporal transformer, video question answering, video retrieval, video captioning, video moment retrieval
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
