

The DOI matches its Crossref record; 79 of the 79 references it cites were found in a registry or an index.
HERO: Hierarchical Encoder for Video+Language Omni-representation Pre-training
Open accessAbstract
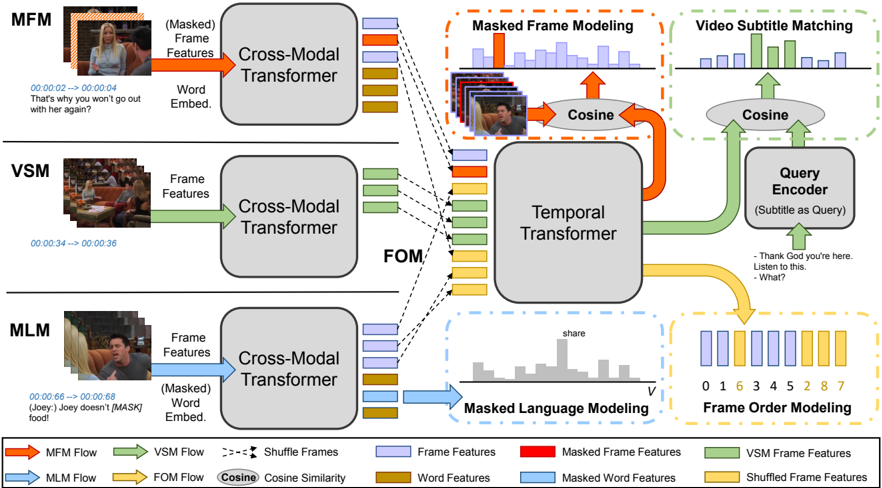
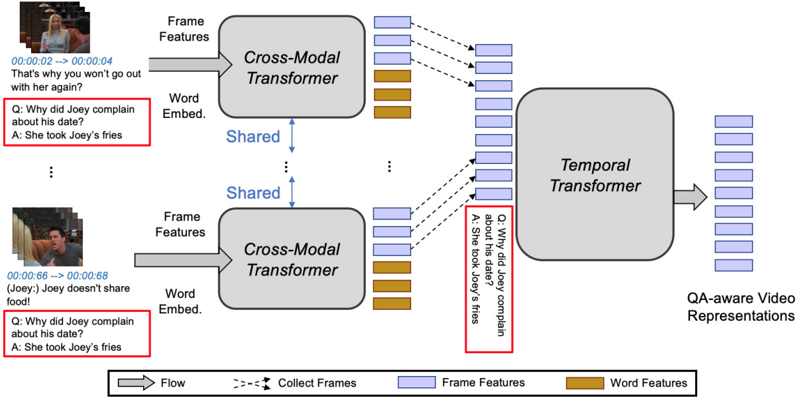
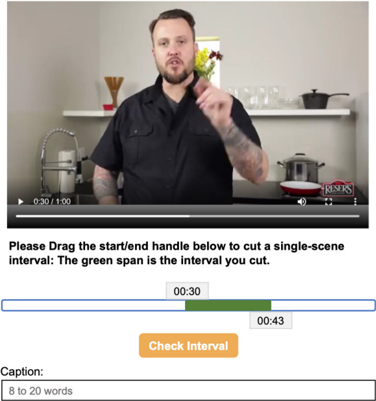
We present HERO, a novel framework for large-scale video+language omnirepresentation learning.HERO encodes multimodal inputs in a hierarchical structure, where local context of a video frame is captured by a Cross-modal Transformer via multimodal fusion, and global video context is captured by a Temporal Transformer.In addition to standard Masked Language Modeling (MLM) and Masked Frame Modeling (MFM) objectives, we design two new pre-training tasks: (i) Video-Subtitle Matching (VSM), where the model predicts both global and local temporal alignment; and (ii) Frame Order Modeling (FOM), where the model predicts the right order of shuffled video frames.HERO is jointly trained on HowTo100M and large-scale TV datasets to gain deep understanding of complex social dynamics with multi-character interactions.Comprehensive experiments demonstrate that HERO achieves new state of the art on multiple benchmarks over Text-based Video/Video-moment Retrieval, Video Question Answering (QA), Video-and-language Inference and Video Captioning tasks across different domains.We also introduce two new challenging benchmarks How2QA and How2R for Video QA and Retrieval, collected from diverse video content over multimodalities. 1
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“As demonstrated in Figure 2 in [192], the multimodal Transformer models have another architecture taxonomy based on the computational size of the components.”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
In the citing paper
“One simplifying is processing the visual input in convolution-free manner, e.g., E2E-VLP [271], ViLT [192].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Jakubův, J., Chvalovský, K., Goertzel, Z., et al. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,648
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
ImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333
Self-citationBERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
Decoupled Weight Decay Regularization
Loshchilov, I., & Hutter, F. (2017) · arXiv · doi:10.48550/arxiv.1711.05101 · Cited by 12,522
(2017) · Cited by 11,625
Research works printed but not linked: 4
- Lisa Anne Hendricks, Oliver Wang, Eli Shechtman, Josef Sivic, Trevor Darrell, and Bryan Russell. 2017b. Localizing moments in video with natural language. In CVPR.
- Myle Ott, Sergey Edunov, David Grangier, and Michael Auli. 2018. Scaling neural machine trans- lation. arXiv preprint arXiv:1806.00187. · arXiv
- Jun Xu, Tao Mei, Ting Yao, and Yong Rui. 2016b. Msr- vtt: A large video description dataset for bridging video and language. CVPR.
- Licheng Yu, Zhe Lin, Xiaohui Shen, Jimei Yang, Xin Lu, Mohit Bansal, and Tamara L Berg. 2018a. Mat- tnet: Modular attention network for referring expres- sion comprehension. In CVPR.
Cited by
Sorted by citations
Items 101–200 of 410
Deep learning for video-text retrieval: a review
Zhu, C., Jia, Q. F., Chen, W. R., Guo, Y., & Liu, Y. (2023) · International Journal of Multimedia Information Retrieval · doi:10.1007/s13735-023-00267-8 · Cited by 47
Sharma, D., Dhiman, C., & Kumar, D. (2023) · Expert Systems with Applications · doi:10.1016/j.eswa.2023.119773 · Cited by 43
Learning Emotion Representations from Verbal and Nonverbal Communication
Zhang, S., Pan, Y., & Wang, J. Z. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01821 · Cited by 42
Procedure-Aware Pretraining for Instructional Video Understanding
Zhou, H., Martín-Martín, R., Kapadia, M., Savarese, S., & Niebles, J. C. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01033 · Cited by 37
HierVL: Learning Hierarchical Video-Language Embeddings
Ashutosh, K., Girdhar, R., Torresani, L., & Grauman, K. L. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.02209 · Cited by 50
Understanding Chinese Video and Language via Contrastive Multimodal Pre-Training
Lei, C., Luo, S., Liu, Y., He, W., Wang, J., Wang, G., Tang, H., Miao, C., & Li, H. (2021) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3474085.3475431 · Cited by 39
Video ReCap: Recursive Captioning of Hour-Long Videos
Islam, M. M., Ho, N., Yang, X., Nagarajan, T., Torresani, L., & Bertasius, G. (2024) · 2024 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr52733.2024.01723 · Cited by 34
EMScore: Evaluating Video Captioning via Coarse-Grained and Fine-Grained Embedding Matching
Shi, Y., Yang, X., Xu, H., Yuan, C., Li, B., Hu, W., & Zha, Z.-J. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01740 · Cited by 38
MILES: Visual BERT Pre-training with Injected Language Semantics for Video-Text Retrieval
Ge, Y., Ge, Y., Liu, X., Wang, J., Wu, J., Shan, Y., Qie, X., & Luo, P. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-19833-5_40 · Cited by 39
Transferring Image-CLIP to Video-Text Retrieval via Temporal Relations
Fang, H., Xiong, P., Xu, L., & Luo, W. (2022) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2022.3227416 · Cited by 33
i-Code: An Integrative and Composable Multimodal Learning Framework
Yang, Z., Fang, Y., Zhu, C., Pryzant, R., Chen, D., Shi, Y., Yi‐chong, X., Qian, Y., Gao, M., Chen, Y., et al. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i9.26290 · Cited by 45
Self-citationMELTR: Meta Loss Transformer for Learning to Fine-tune Video Foundation Models
Ko, D., Choi, J., Choi, H. K., On, K.-W., Roh, B., & Kim, H. J. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01925 · Cited by 38
Joint Searching and Grounding: Multi-Granularity Video Content Retrieval
Chen, Z., Jiang, X., Xu, X., Cao, Z., Mo, Y., & Shen, H. T. (2023) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3581783.3612349 · Cited by 32
Are Vision-Language Transformers Learning Multimodal Representations? A Probing Perspective
Salin, E., Farah, B., Ayache, S., & Favre, B. (2022) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v36i10.21375 · Cited by 37
Learning from Inside: Self-driven Siamese Sampling and Reasoning for Video Question Answering
Yu, W., Zheng, H., Li, M., Ji, L., Wu, L., Xiao, N., & Duan, N. (2021) · neural information processing systems · Cited by 30
JOTR: 3D Joint Contrastive Learning with Transformers for Occluded Human Mesh Recovery
Li, J., Yang, Z., Wang, X., Ma, J., Zhou, C. S., & Yang, Y. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00836 · Cited by 32
QVHighlights: Detecting Moments and Highlights in Videos via Natural Language QueriesPreprint
Lei, J., Berg, T. L., & Bansal, M. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2107.09609 · Cited by 36
Dyadformer: A Multi-modal Transformer for Long-Range Modeling of Dyadic Interactions
Curto, D., Clapés, A., Selva, J., Smeureanu, S., Jacques, J. C. S., Gallardo‐Pujol, D., Guilera, G., Leiva, D., Moeslund, T. B., Escalera, S., et al. (2021) · IEEE International Conference on Computer Vision Workshops · doi:10.1109/iccvw54120.2021.00247 · Cited by 35
SCANet: Scene Complexity Aware Network for Weakly-Supervised Video Moment Retrieval
Yoon, S., Koo, G., Kim, D., & Yoo, C. D. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01249 · Cited by 28
Modeling Motion with Multi-Modal Features for Text-Based Video Segmentation
Zhao, W., Wang, K., Chu, X., Xue, F., Wang, X., & You, Y. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.01144 · Cited by 29
M5Product: Self-harmonized Contrastive Learning for E-commercial Multi-modal Pretraining
Dong, X. M., Zhan, X., Wu, Y., Wei, Y., Kampffmeyer, M., Wei, X.-Y., Lu, M., Wang, Y., & Liang, X. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.02057 · Cited by 36
Learning Procedure-aware Video Representation from Instructional Videos and Their Narrations
Zhong, Y., Yu, L., Bai, Y., Li, S.-W. D., Yan, X., & Li, Y. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01424 · Cited by 37
Self-citationLearning to Answer Visual Questions From Web Videos
Yang, A., Miech, A., Šivic, J., Laptev, I., & Schmid, C. (2022) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2022.3173208 · Cited by 36
Delving into Shape-aware Zero-shot Semantic Segmentation
Liu, X., Tian, B., Wang, Z., Wang, R., Sheng, K., Zhang, B., Zhao, H., & Zhou, G. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00293 · Cited by 27
PIDRo: Parallel Isomeric Attention with Dynamic Routing for Text-Video Retrieval
Guan, P., Pei, R., Shao, B., Liu, J., Li, W., Gu, J., Xu, H., Xu, S., Yan, Y., & Lam, E. Y. M. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01025 · Cited by 25
Self-citationMasking Modalities for Cross-modal Video Retrieval
Gabeur, V., Nagrani, A., Sun, C., Alahari, K., & Schmid, C. (2022) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv51458.2022.00217 · Cited by 27
I2Transformer: Intra- and Inter-Relation Embedding Transformer for TV Show Captioning
Tu, Y., Li, L., Su, L., Gao, S., Yan, C., Zha, Z.-J., Yu, Z., & Huang, Q. (2022) · IEEE Transactions on Image Processing · doi:10.1109/tip.2022.3159472 · Cited by 25
Self-citationZhang, X., Zhao, P., Ji, J., Lu, X., & Yin, Y. (2023) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2023.3294567 · Cited by 26
Adaptive Hierarchical Graph Reasoning with Semantic Coherence for Video-and-Language Inference
Li, J., Tang, S., Zhu, L., Shi, H., Huang, X., Wu, F. Q., Yang, Y., & Zhuang, Y. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00188 · Cited by 24
Selective Query-Guided Debiasing for Video Corpus Moment Retrieval
Yoon, S., Hong, J. W., Yoon, E., Kim, D., Kim, J., Yoon, H. S., & Yoo, C. D. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-20059-5_11 · Cited by 27
CONQUER: Contextual query-aware ranking for video corpus moment retrieval
HOU, Z., Ngo, C., & Chan, W. K. (2021) · Singapore Management University Institutional Knowledge (InK) (Singapore Management University) · Cited by 23
ERM: Energy-Based Refined-Attention Mechanism for Video Question Answering
Zhang, F., Wang, R., Zhou, F., & Luo, Y. (2022) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2022.3212463 · Cited by 23
Hierarchical Semantic Correspondence Networks for Video Paragraph Grounding
Tan, C., Lin, Z., Hu, J., Zheng, W., & Lai, J. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01819 · Cited by 24
A Closer Look at the Robustness of Vision-and-Language Pre-trained ModelsPreprint
Li, L., Gan, Z., & Liu, J. (2020) · arXiv (Cornell University) · doi:10.48550/arxiv.2012.08673 · Cited by 31
Self-citationVideo Moment Retrieval with Hierarchical Contrastive Learning
Zhang, B., Yang, C., Jiang, B., & Zhou, X. (2022) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3503161.3547963 · Cited by 22
Video-Text Representation Learning via Differentiable Weak Temporal Alignment
Ko, D., Choi, J., Ko, J., Noh, S., On, K.-W., Kim, E., & Kim, H. J. (2022) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52688.2022.00496 · Cited by 22
COVID-VTS: Fact Extraction and Verification on Short Video Platforms
Liu, F., Yacoob, Y., & Shrivastava, A. (2023) · Conference of the European Chapter of the Association for Computational Linguistics · doi:10.18653/v1/2023.eacl-main.14 · Cited by 33
Khurana, K., & Deshpande, U. A. (2021) · IEEE Access · doi:10.1109/access.2021.3058248 · Cited by 26
CLIP Meets Video Captioning: Concept-Aware Representation Learning Does Matter
Yang, B., Zhang, T., & Zou, Y. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-18907-4_29 · Cited by 21
NaQ: Leveraging Narrations as Queries to Supervise Episodic Memory
Ramakrishnan, S. K., Al-Halah, Z., & Grauman, K. L. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00647 · Cited by 21
Tem-adapter: Adapting Image-Text Pretraining for Video Question Answer
Chen, G., Liu, X., Wang, G., Zhang, K., Torr, P. H. S., Zhang, X.-P. S., & Tang, Y. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01282 · Cited by 28
A comparative study of language transformers for video question answering
Yang, Z., García, N., Chu, C., Otani, M., Nakashima, Y., & Takemura, H. (2021) · Neurocomputing · doi:10.1016/j.neucom.2021.02.092 · Cited by 21
SViTT: Temporal Learning of Sparse Video-Text Transformers
Li, Y., Min, K., Tripathi, S., & Vasconcelos, N. M. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01814 · Cited by 20
ProTéGé: Untrimmed Pretraining for Video Temporal Grounding by Video Temporal Grounding
Wang, L., Mittal, G. K., Sajeev, S., Yu, Y., Hall, M., Boddeti, V. N., & Chen, M. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.00636 · Cited by 21
Tencent Text-Video Retrieval: Hierarchical Cross-Modal Interactions With Multi-Level Representations
Jiang, J., Min, S., Kong, W., Wang, H., Li, Z., & Liu, W. (2022) · IEEE Access · doi:10.1109/access.2022.3227973 · Cited by 26
End-to-End Pre-Training With Hierarchical Matching and Momentum Contrast for Text-Video Retrieval
Shen, W., Song, J., Zhu, X., Li, G., & Shen, H. T. (2023) · IEEE Transactions on Image Processing · doi:10.1109/tip.2023.3275071 · Cited by 19
Cross-Modality Knowledge Calibration Network for Video Corpus Moment Retrieval
Chen, T., Wang, W., Jiang, Z., Li, R., & Wang, B. (2023) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2023.3316025 · Cited by 19
VLAB: Enhancing Video Language Pretraining by Feature Adapting and Blending
He, X., Chen, S., Ma, F., Huang, Z., Jin, X., Liu, Z., Fu, D., Yang, Y., Liu, J., & Feng, J. (2024) · IEEE Transactions on Multimedia · doi:10.1109/tmm.2024.3521729 · Cited by 30
Self-citationKoala: Key Frame-Conditioned Long Video-LLM
Tan, R., Sun, X., Hu, P., Wang, J.-H., Deilamsalehy, H., Plummer, B. A., Russell, B. C., & Saenko, K. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01289 · Cited by 25
Learning Social Relationship From Videos via Pre-Trained Multimodal Transformer
Teng, Y., Song, C., & Wu, B. (2022) · IEEE Signal Processing Letters · doi:10.1109/lsp.2022.3181849 · Cited by 19
Localizing Moments in Long Video Via Multimodal Guidance
Barrios, W., Soldan, M., Ceballos-Arroyo, A. M., Heilbron, F. C., & Ghanem, B. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01257 · Cited by 20
VL-PET: Vision-and-Language Parameter-Efficient Tuning via Granularity Control
Hu, Z.-Y., Li, Y., Lyu, M. R.-T., & Wang, L. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.00281 · Cited by 20
CoVR-2: Automatic Data Construction for Composed Video Retrieval
Ventura, L., Yang, A., Schmid, C., & Varol, G. (2024) · IEEE Transactions on Pattern Analysis and Machine Intelligence · doi:10.1109/tpami.2024.3463799 · Cited by 31
Learning to Cut by Watching Movies
Pardo, A., Heilbron, F. C., Alcázar, J. L., Thabet, A., & Ghanem, B. (2021) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv48922.2021.00678 · Cited by 19
Video Question Answering with Iterative Video-Text Co-tokenization
Piergiovanni, A., Morton, K., Kuo, W., Ryoo, M. S., & Angelova, A. (2022) · Lecture notes in computer science · doi:10.1007/978-3-031-20059-5_5 · Cited by 18
Foundation Models for Video Understanding: A SurveyPreprint
Madan, N., Møgelmose, A., Modi, R., Rawat, Y. S., & Moeslund, T. B. (2024) · doi:10.36227/techrxiv.171769139.99464428/v1 · Cited by 24
Dual-Modal Attention-Enhanced Text-Video Retrieval with Triplet Partial Margin Contrastive Learning
Jiang, C., Liu, H., Yu, X., Wang, Q., Cheng, Y., Xu, J., Liu, Z., Guo, Q., Chu, W., Yang, M., et al. (2023) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3581783.3612006 · Cited by 17
Self-citationText-Video Retrieval via Multi-Modal Hypergraph Networks
Li, Q., Su, L., Zhao, J., Xia, L., Cai, H., Cheng, S., Tang, H., Wang, J., & Yin, D. Z. (2024) · ACM International Conference on Web Search and Data Mining (WSDM) · doi:10.1145/3616855.3635757 · Cited by 18
Stay in Grid: Improving Video Captioning via Fully Grid-Level Representation
Tang, M., Wang, Z., Zeng, Z., Li, X., & Zhou, L. (2022) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2022.3232634 · Cited by 17
PERCEIVER-VL: Efficient Vision-and-Language Modeling with Iterative Latent Attention
Tang, Z., Cho, J., Lei, J., & Bansal, M. (2023) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv56688.2023.00439 · Cited by 17
Contrastive topic-enhanced network for video captioning
YaWen, Z., Wang, Y., Liao, D., Li, G., Xu, J. H., Man, H., Liu, B., & Xu, X. (2023) · Expert Systems with Applications · doi:10.1016/j.eswa.2023.121601 · Cited by 18
AQuA: Automated Question-Answering in Software Tutorial Videos with Visual Anchors
Yang, S., Vermeulen, J., Fitzmaurice, G. W., & Matejka, J. (2024) · CHI Conference on Human Factors in Computing Systems · doi:10.1145/3613904.3642752 · Cited by 20
EvCap: Element-Aware Video Captioning
Liu, S., Li, A., Zhao, Y., Wang, J., & Wang, Y. (2024) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2024.3399933 · Cited by 20
VideoQA in the Era of LLMs: An Empirical Study
Xiao, J., Huang, N., Qin, H., Li, D., Li, Y., Zhu, F., Tao, Z., Yu, J., Lin, L., Chua, T., et al. (2025) · International Journal of Computer Vision · doi:10.1007/s11263-025-02385-8 · Cited by 25
Video Description: Datasets & Evaluation Metrics
Rafiq, M. T., Rafiq, G., & Choi, G. S. (2021) · IEEE Access · doi:10.1109/access.2021.3108565 · Cited by 16
LSECA: local semantic enhancement and cross aggregation for video-text retrieval
Wang, Z., Zhang, D., & Hu, Z. (2024) · International Journal of Multimedia Information Retrieval · doi:10.1007/s13735-024-00335-7 · Cited by 15
Accommodating Audio Modality in CLIP for Multimodal Processing
Ruan, L., Hu, A., Song, Y., Zhang, L., Zheng, S., & Jin, Q. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i8.26153 · Cited by 15
Werewolf Among Us: Multimodal Resources for Modeling Persuasion Behaviors in Social Deduction Games
Lai, B., Zhang, H., Liu, M., Pariani, A., Ryan, F., Jia, W., Hayati, S. A., Rehg, J. M., & Yang, D. (2023) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2023.findings-acl.411 · Cited by 21
Learning to Ground Instructional Articles in Videos through Narrations
Mavroudi, E., Afouras, T., & Torresani, L. (2023) · IEEE/CVF International Conference on Computer Vision (ICCV) · doi:10.1109/iccv51070.2023.01395 · Cited by 15
Yu, T., Fu, K., Zhang, J., Huang, Q., & Yu, J. (2024) · IEEE Transactions on Image Processing · doi:10.1109/tip.2024.3390984 · Cited by 19
Xie, W., Hu, A., Xie, Q., Chen, J., Wan, R., & Liu, Y. (2025) · Discover Computing · doi:10.1007/s10791-025-09628-9 · Cited by 15
Multi-modal Semantic Inconsistency Detection in Social Media News Posts
McCrae, S., Wang, K., & Zakhor, A. (2022) · Lecture notes in computer science · doi:10.1007/978-3-030-98355-0_28 · Cited by 17
Learning visual language models for video understanding
Yang, A. (2023) · theses.fr (ABES) · doi:10.70675/802872a7z8092z4556za1fdz2c7af45f0e72 · Cited by 26
About Time: Advances, Challenges, and Outlooks of Action Understanding
Stergiou, A., & Poppe, R. W. (2025) · International Journal of Computer Vision · doi:10.1007/s11263-025-02478-4 · Cited by 17
VGNMN: Video-grounded Neural Module Networks for Video-Grounded Dialogue Systems
Le, H., Chen, N. F., & Hoi, S. C. H. (2022) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2022.naacl-main.247 · Cited by 18
Sequence as a Whole: A Unified Framework for Video Action Localization With Long-Range Text Query
Su, Y., Wang, W., Liu, J., Ma, S., & Yang, X. (2023) · IEEE Transactions on Image Processing · doi:10.1109/tip.2023.3243525 · Cited by 14
Self-citationTowards Fast Adaptation of Pretrained Contrastive Models for Multi-channel Video-Language Retrieval
Lin, X., Tiwari, S., Huang, S., Li, M., Shou, M. Z., Ji, H., & Chang, S. (2023) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52729.2023.01426 · Cited by 15
CAD - Contextual Multi-modal Alignment for Dynamic AVQA
Nadeem, A., Hilton, A., Dawes, R., Thomas, G., & Mustafa, A. (2024) · IEEE Winter Conference on Applications of Computer Vision · doi:10.1109/wacv57701.2024.00709 · Cited by 16
Learn to Rectify the Bias of CLIP for Unsupervised Semantic Segmentation
Wang, J., & Kang, G. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.00393 · Cited by 14
Semantically Distributed Robust Optimization for Vision-and-Language Inference
Gokhale, T., Chaudhary, A., Banerjee, P., Baral, C. R., & Yang, Y. (2022) · Findings of the Association for Computational Linguistics: ACL (Findings of ACL) · doi:10.18653/v1/2022.findings-acl.118 · Cited by 15
Overview of the MedVidQA 2022 Shared Task on Medical Video Question-Answering
Gupta, D. K., & Demner‐Fushman, D. (2022) · Workshop on Biomedical Language Processing (BioNLP) · doi:10.18653/v1/2022.bionlp-1.25 · Cited by 14
Multi-modal Dictionary BERT for Cross-modal Video Search in Baidu Advertising
Yu, T., Yang, Y., Li, Y., Liu, L., Sun, M., & Li, P. (2021) · ACM International Conference on Information and Knowledge Management (CIKM) · doi:10.1145/3459637.3481937 · Cited by 13
Multimodal Intent Discovery from Livestream Videos
Maharana, A., Tran, Q., Dernoncourt, F., Yoon, S., Bui, T., Chang, W. H., & Bansal, M. (2022) · Findings of the Association for Computational Linguistics: NAACL · doi:10.18653/v1/2022.findings-naacl.36 · Cited by 13
Modal-specific Pseudo Query Generation for Video Corpus Moment Retrieval
Jung, M., Choi, S., Kim, J. C., Kim, J.-H., & Zhang, B. (2022) · Conference on Empirical Methods in Natural Language Processing (EMNLP) · doi:10.18653/v1/2022.emnlp-main.530 · Cited by 15
Video Corpus Moment Retrieval With Query-Specific Context Learning and Progressive Localization
Zhang, L., Song, P., Duan, Z., Wang, S., Chang, X., & Yang, X. (2025) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2025.3530570 · Cited by 13
Cross-Lingual Cross-Modal Consolidation for Effective Multilingual Video Corpus Moment Retrieval
Liu, J., Yu, T., Peng, H., Sun, M., & Li, P. (2022) · Findings of the Association for Computational Linguistics: NAACL · doi:10.18653/v1/2022.findings-naacl.142 · Cited by 14
Self-citationTG-VQA: Ternary Game of Video Question Answering
Li, H., Jin, P., Cheng, Z., Zhang, S., Chen, K., Wang, Z., Liu, C., & Chen, J. (2023) · International Joint Conference on Artificial Intelligence · doi:10.24963/ijcai.2023/116 · Cited by 13
OMG: Observe Multiple Granularities for Natural Language-Based Vehicle Retrieval
Du, Y., Zhang, B., Ruan, X., Su, F., Zhao, Z., & Chen, H. (2022) · IEEE/CVF Conference on Computer Vision and Pattern Recognition Workshops (CVPRW) · doi:10.1109/cvprw56347.2022.00352 · Cited by 12
Improving Video Corpus Moment Retrieval with Partial Relevance Enhancement
Hou, D., Pang, L., Shen, H., & Cheng, X. (2024) · International Conference on Multimedia Retrieval · doi:10.1145/3652583.3658088 · Cited by 12
ViLA: Efficient Video-Language Alignment for Video Question Answering
Wang, X., Liang, J., Wang, C.-K., Deng, K., Lou, Y., Lin, M. C., & Yang, S. (2024) · Lecture notes in computer science · doi:10.1007/978-3-031-73033-7_11 · Cited by 20
Towards Global Video Scene Segmentation with Context-Aware Transformer
Yang, Y., Huang, Y., Guo, W.-L., Xu, B., & Xia, D. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i3.25426 · Cited by 13
VidLanKD: Improving Language Understanding via Video-Distilled Knowledge TransferPreprint
Tang, Z., Cho, J., Tan, H. X., & Bansal, M. (2021) · arXiv (Cornell University) · doi:10.48550/arxiv.2107.02681 · Cited by 13
Thinking Fast and Slow: Efficient Text-to-Visual Retrieval with Transformers
Miech, A., Alayrac, J.-B., Laptev, I., Sivic, J., & Zisserman, A. (2021) · 2021 IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr46437.2021.00970 · Cited by 149
Enhanced Motion-Text Alignment for Image-to-Video Transfer Learning
Zhang, W., Wan, C., Liu, T., Tian, X., Shen, X., & Ye, J. (2024) · IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings - IEEE Computer Society Conference on Computer Vision and Pattern Recognition/Proceedings · doi:10.1109/cvpr52733.2024.01751 · Cited by 13
Fahad, S. K. A., Zhengkui, D. W., Ng, P. C., Wong, N., Ng, A. B., & See, S. C. W. (2025) · Studies in computational intelligence · doi:10.1007/978-3-031-80334-5_19 · Cited by 13
MuJo: Multimodal Joint Feature Space Learning for Human Activity Recognition
Fritsch, S. G., Oguz, C., Rey, V. F., Ray, L. S. S., Kiefer-Emmanouilidis, M., & Lukowicz, P. (2025) · IEEE International Conference on Pervasive Computing and Communications · doi:10.1109/percom64205.2025.00020 · Cited by 14
Dynamic Multistep Reasoning based on Video Scene Graph for Video Question Answering
Mao, J., Jiang, W., Wang, X., Feng, Z., Lyu, Y., Liu, H., & Yong, Z. (2022) · Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (NAACL-HLT) · doi:10.18653/v1/2022.naacl-main.286 · Cited by 11
Unified QA-aware Knowledge Graph Generation Based on Multi-modal Modeling
Qin, P., Yu, J., Gao, Y. J., Xu, D., Chen, Y., Wu, S., Xu, T., Chen, E., & Hao, Y. (2022) · ACM International Conference on Multimedia (ACM MM) · doi:10.1145/3503161.3551604 · Cited by 11
Self-citationCounterfactual Two-Stage Debiasing For Video Corpus Moment Retrieval
Yoon, S., Hong, J. W., Eom, S., Yoon, H. S., Yoon, E., Kim, D., Kim, J., Kim, C., & Yoo, C. D. (2023) · IEEE International Conference on Acoustics Speech and Signal Processing · doi:10.1109/icassp49357.2023.10095182 · Cited by 12
Video-Text Pre-training with Learned Regions for Retrieval
Yan, R., Shou, M. Z., Ge, Y., Wang, J., Lin, X., Cai, G., & Tang, J. (2023) · Proceedings of the AAAI Conference on Artificial Intelligence · doi:10.1609/aaai.v37i3.25414 · Cited by 29
Metadata
- Authors
- Li, L., Chen, Y.-C., Cheng, Y., Gan, Z., Yu, L., & Liu, J.
- Affiliations
- Microsoft (United States) (US)
- Venue
- Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP)
- Published
- 2020
- Pages
- 2046-2065
- OpenAlex
- W3105232955
- Cited by
- 408
- References
- 79
- Citations by year
- 2026: 17 · 2025: 49 · 2024: 67 · 2023: 129 · 2022: 87 · 2021: 52 · 2020: 7
- FWCI
- 21.21
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Human Pose and Action Recognition
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Video Analysis and Summarization
- Keywords
- multimodal representation learning, hierarchical encoder, cross-modal transformer, temporal transformer, video question answering, video retrieval, video captioning, video moment retrieval
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
