

The DOI matches its Crossref record; 79 of the 79 references it cites were found in a registry or an index.
HERO: Hierarchical Encoder for Video+Language Omni-representation Pre-training
Open accessAbstract
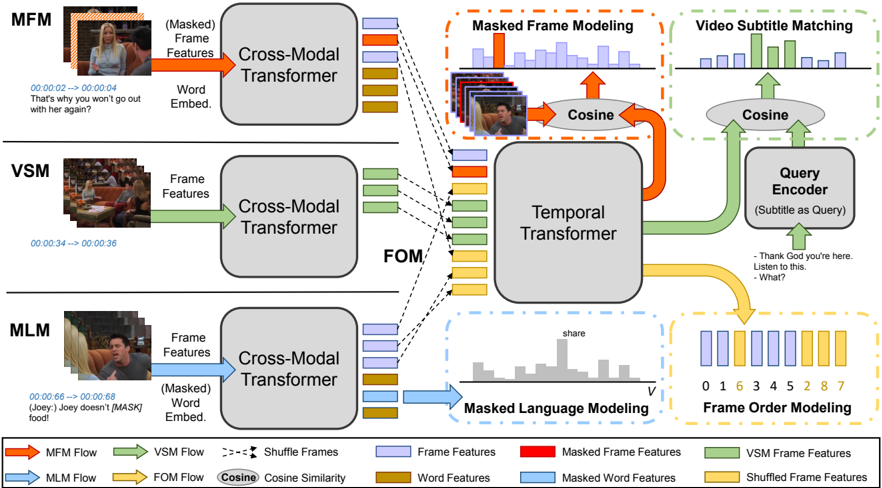
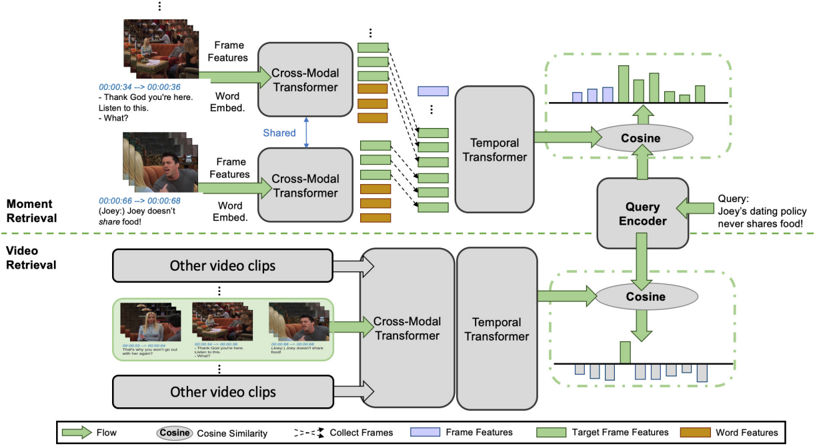
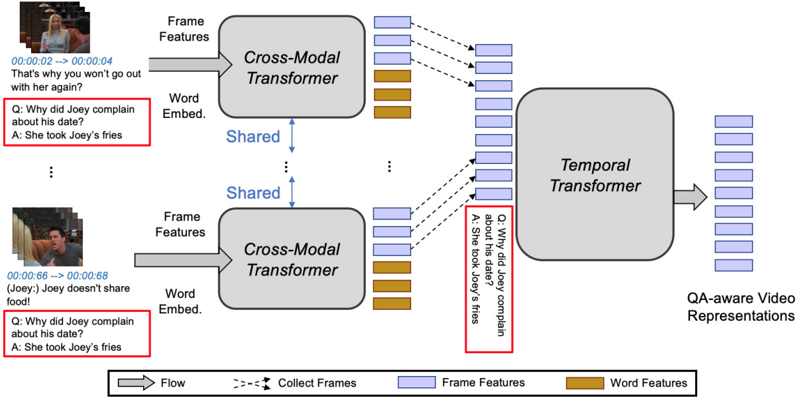
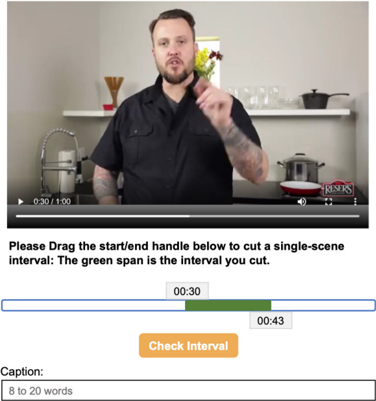
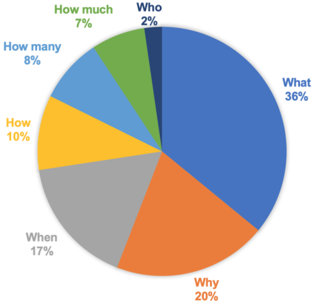
We present HERO, a novel framework for large-scale video+language omnirepresentation learning.HERO encodes multimodal inputs in a hierarchical structure, where local context of a video frame is captured by a Cross-modal Transformer via multimodal fusion, and global video context is captured by a Temporal Transformer.In addition to standard Masked Language Modeling (MLM) and Masked Frame Modeling (MFM) objectives, we design two new pre-training tasks: (i) Video-Subtitle Matching (VSM), where the model predicts both global and local temporal alignment; and (ii) Frame Order Modeling (FOM), where the model predicts the right order of shuffled video frames.HERO is jointly trained on HowTo100M and large-scale TV datasets to gain deep understanding of complex social dynamics with multi-character interactions.Comprehensive experiments demonstrate that HERO achieves new state of the art on multiple benchmarks over Text-based Video/Video-moment Retrieval, Video Question Answering (QA), Video-and-language Inference and Video Captioning tasks across different domains.We also introduce two new challenging benchmarks How2QA and How2R for Video QA and Retrieval, collected from diverse video content over multimodalities. 1
Overview
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Integrity signals
Registry
Cites
Statistics
Figures
Verification
Claims the paper makes
The claims and statistics of this paper haven’t been checked yet.
Run the check — free, no account needed. It reads the open-access text and checks the sources it cites.
Claims other papers make about this one
Each is checked against this paper’s own text: does it say what the citing paper says it does?
In the citing paper
“As demonstrated in Figure 2 in [192], the multimodal Transformer models have another architecture taxonomy based on the computational size of the components.”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
In the citing paper
“One simplifying is processing the visual input in convolution-free manner, e.g., E2E-VLP [271], ViLT [192].”
From Multimodal learning with transformers: A survey (2023) · cites this paper as [192]
Self-check
Percentages, sums and reported differences re-computed from the paper’s own numbers.
The self-check needs the paper’s full text.
Citations
Cites
Deep Residual Learning for Image Recognition
He, K., Zhang, X., Ren, S., & Sun, J. (2016) · 2016 IEEE Conference on Computer Vision and Pattern Recognition (CVPR) · doi:10.1109/cvpr.2016.90 · Cited by 235,474
Vaswani, A., Shazeer, N., Parmar, N., Uszkoreit, J., Jones, L., Gomez, A. N., Kaiser, L., & Polosukhin, I. (2017) · arXiv · doi:10.48550/arxiv.1706.03762 · Cited by 120,404
Jakubův, J., Chvalovský, K., Goertzel, Z., et al. (2023) · DROPS (Schloss Dagstuhl – Leibniz Center for Informatics) · doi:10.4230/lipics.itp.2023.19 · Cited by 76,648
BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2018) · arXiv · doi:10.48550/arxiv.1810.04805 · Cited by 73,173
ImageNet: A large-scale hierarchical image database
Deng, J., Dong, W., Socher, R., Li, L.-J., Li, K., & Fei-Fei, L. (2009) · 2009 IEEE Conference on Computer Vision and Pattern Recognition · doi:10.1109/cvpr.2009.5206848 · Cited by 65,333
Self-citationBERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
Devlin, J., Chang, M.-W., Lee, K., & Toutanova, K. (2019) · Proceedings of the 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies, Volume 1 (Long and Short Papers) · doi:10.18653/v1/n19-1423 · Cited by 54,325
BLEU: a method for automatic evaluation of machine translation
Papineni, K., Roukos, S., Ward, T., & Zhu, W.-J. (2001) · Proceedings of the 40th Annual Meeting on Association for Computational Linguistics - ACL '02 · doi:10.3115/1073083.1073135 · Cited by 21,344
RoBERTa: A Robustly Optimized BERT Pretraining Approach
Liu, Y., Ott, M., Goyal, N., Du, J., Joshi, M., Chen, D., Levy, O., Lewis, M., Zettlemoyer, L., & Stoyanov, V. (2019) · arXiv · doi:10.48550/arxiv.1907.11692 · Cited by 16,515
Decoupled Weight Decay Regularization
Loshchilov, I., & Hutter, F. (2017) · arXiv · doi:10.48550/arxiv.1711.05101 · Cited by 12,522
(2017) · Cited by 11,625
Research works printed but not linked: 4
- Lisa Anne Hendricks, Oliver Wang, Eli Shechtman, Josef Sivic, Trevor Darrell, and Bryan Russell. 2017b. Localizing moments in video with natural language. In CVPR.
- Myle Ott, Sergey Edunov, David Grangier, and Michael Auli. 2018. Scaling neural machine trans- lation. arXiv preprint arXiv:1806.00187. · arXiv
- Jun Xu, Tao Mei, Ting Yao, and Yong Rui. 2016b. Msr- vtt: A large video description dataset for bridging video and language. CVPR.
- Licheng Yu, Zhe Lin, Xiaohui Shen, Jimei Yang, Xin Lu, Mohit Bansal, and Tamara L Berg. 2018a. Mat- tnet: Modular attention network for referring expres- sion comprehension. In CVPR.
Cited by
Sorted by citations
Items 401–410 of 410
Wu, Z., Liu, Z., Chen, A., Zhang, J., Li, R., Ge, H., Wang, Z., Xiao, C., & Liang, C. (2026) · International Journal of Computer Vision · doi:10.1007/s11263-026-02898-w
Video Corpus Moment Retrieval via Decoupled Multimodal Modeling and Unified Localization
Yang, Y., Liu, M., Song, X., Zheng, N., Lü, K., & Guan, W. (2026) · IEEE Transactions on Circuits and Systems for Video Technology · doi:10.1109/tcsvt.2026.3705906
Generation-Augmented Video Corpus Moment Retrieval
Kuai, M., Xiao, Q., Li, J., Peng, J., Liao, L., & Ji, W. (2026) · International ACM SIGIR Conference on Research and Development in Information Retrieval (SIGIR) · doi:10.1145/3805712.3809742 · Cited by 2
Cross-Modal Temporal Alignment for Action Grounding in Videos
Shi, G., Wu, C., Wang, S., Yu, J., Onoda, H., & Liu, J. (2026) · IEEE Access · doi:10.1109/access.2026.3721115
Self-citationLong Story Short: Story-level Video Understanding from 20K Short Films
Ghermi, R., Wang, X., Kalogeiton, V. S., & Laptev, I. (2026) · International Journal of Computer Vision · doi:10.1007/s11263-026-02940-x · Cited by 22
Training-Free Video Corpus Moment Retrieval via Synergistic Collaboration and Adaptive Calibration
Zhao, J., Li, H., Zhang, Y., Wang, W., & Hua, C. (2026) · IEEE Transactions on Image Processing · doi:10.1109/tip.2026.3723243
Rifa, N., & Kabir, M. N. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.7438610
Wavelet-Based Intra-Video Counterfactual Reasoning for Video Question Grounding
Yuan, J., & Wei, W. (2026) · Lecture notes in computer science · doi:10.1007/978-3-032-37098-3_35
Rifa, N., & Kabir, M. N. (2026) · SSRN Electronic Journal · doi:10.2139/ssrn.7442027
Jeong, G., Kang, K.-I., & Kim, H. (2026) · Buildings · doi:10.3390/buildings16214281
Metadata
- Authors
- Li, L., Chen, Y.-C., Cheng, Y., Gan, Z., Yu, L., & Liu, J.
- Affiliations
- Microsoft (United States) (US)
- Venue
- Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP)
- Published
- 2020
- Pages
- 2046-2065
- OpenAlex
- W3105232955
- Cited by
- 408
- References
- 79
- Citations by year
- 2026: 17 · 2025: 49 · 2024: 67 · 2023: 129 · 2022: 87 · 2021: 52 · 2020: 7
- FWCI
- 21.21
- Type
- conference paper
- Language
- en
- Open access
- hybrid
- doi.org
- Licence
- cc-by
- Locations
- Conference on Empirical Methods in Natural Language Processing (EMNLP) (publishedVersion, cc-by)
- arXiv (Cornell University) (submittedVersion)
- arXiv (Cornell University)
- Topics
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Multimodal Machine Learning Applications
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Human Pose and Action Recognition
- Physical Sciences › Computer Science › Computer Vision and Pattern Recognition › Video Analysis and Summarization
- Keywords
- multimodal representation learning, hierarchical encoder, cross-modal transformer, temporal transformer, video question answering, video retrieval, video captioning, video moment retrieval
About these checks
Registry, retraction, Cites and statistics results are computed, not judged, with one exception: a printed reference that no index lists is read once by a model before it counts as a citation error. Claims are extracted by a model and kept only when their quote appears verbatim in the text; each cited source is then checked, with a model’s help, for whether it says what the claim relies on. Those verdicts can be wrong — read the claim’s quote and the cited source before relying on one.
Statistics and arithmetic are recomputed, not judged.
Confidence bands are shown only for fields calibrated on our annotated test set. None is calibrated yet, so no band is shown.
What counts as a claim ›How we measure confidence ›How we check this ›
Are you an author, or do you see a problem with this page? Request a review
